18.1 – Multiple Linear Regression
Introduction
Last time we introduced simple linear regression:
- one independent X variable
- one dependent Y variable.
The linear relationship between Y and X was estimated by the method of Ordinary Least Squares (OLS). OLS minimizes the sum of squared distances between the observed responses,  and responses predicted
 by the line. Simple linear regression is analogous to our one-way ANOVA — one outcome or response variable and one factor or predictor variable (Chapter 12.2).
But the world is complicated and so, our one-way ANOVA was extended to the more general case of two or more predictor (factor) variables (Chapter 14). As you might have guessed by now, we can extend simple regression to include more than one predictor variable. In fact, combining ANOVA and regression gives you the general linear model! And, you should not be surprised that statistics has extended this logic to include not only multiple predictor variables, but also multiple response variables. Multiple response variables falls into a category of statistics called multivariate statistics.
Like multi-way ANOVA, multiple regression is the extension of simple linear regression from one independent predictor variable to include two or more predictors. The benefit of this extension is obvious — our models gain realism. All else being equal, the more predictors, the better the model will be at describing and/or predicting the response. Things are not all equal, of course, and we’ll consider two complications of this basic premise, that more predictors are best; in some cases they are not.
However, before discussing the exceptions or even the complications of a multiple linear regression model, we begin by obtaining estimates of the full model, then introduce aspects of how to evaluate the model. We also introduce and whether a reduced model may be the preferred model.
R code
Multiple regression is easy to do in Rcmdr — recall that we used the general linear model function, lm(), to analyze one-way ANOVA and simple linear regression. In R Commander, we access lm() by
Rcmdr: Statistics → Fit model → Linear model
You may, however, access linear regression through R Commander
We use the same general linear model function for cases of multi-way ANOVA and for multiple regression problems. Simply enter more than one ratio-scale predictor variable and boom!
You now have yourself a multiple regression. You would then proceed to generate the ANOVA table for hypothesis testing
Rcmdr: Models → Hypothesis testing → ANOVA tables
From the output of the regression command, estimates of the coefficients along with standard errors for the estimate and results of t-tests for each coefficient against the respective null hypotheses for each coefficient are also provided. In our discussion of simple linear regression we introduced the components: the intercept, the slope, as well as the concept of model fit, as evidenced by R2, the coefficient of determination. These components exist for the multiple regression problem, too, but now we call the slopes partial regression slopes because there are more than one.
Our full multiple regression model becomes
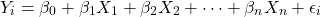
where the coefficients β1, β2, … βn are the partial regression slopes and β0 is the Y-intercept for a model with 1 – n predictor variables. Each coefficient has a null hypothesis, each has a standard error, and therefore, each coefficient can be tested by t-test.
Now, regression, like ANOVA, is an enormous subject and we cannot do it justice in the few days we will devote to it. We can, however, walk you through a fairly typical example. I’ve posted a small data set diabetesCholStatin at the end of this page. Scroll down or click here. View the data set and complete your basic data exploration routine: make scatterplots and box plots. We think (predict) that body size and drug dose cause variation in serum cholesterol levels in adult men. But do both predict cholesterol levels?
Selecting the best model
We have two predictor variables, and we can start to see whether none, one, or both of the predictors contribute to differences in cholesterol levels. In this case, both contribute significantly. The power of multiple regression approaches is that it provides a simultaneous test of a model which may have many explanatory variables deemed appropriate to describe a particular response. More generally, it is sometimes advisable to think more philosophically about how to select a best model.
In model selection, some would invoke Occam’s razor — given a set of explanations, the simplest should be selected — to justify seeking simpler models. There are a number of approaches (forward selection, backward selection, or stepwise selection), and the whole effort of deciding among competing models is complicated with a number of different assumptions, strengths and weaknesses. I refer you to the discussion below, which of course is just a very brief introduction to a very large subject in (bio)statistics!
Let’s get the full regression model
The statistical model is
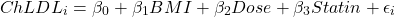
As written in R format, our model is ChLDL ~ BMI + Dose + Statin.
Note 1. BMI is ratio scale and Statin is categorical (two levels: Statin1, Statin2). Dose can be viewed as categorical, with five levels (5, 10, 20, 40, 80 mg), interval scale, or ratio scale. If we are make the assumption that the difference between 5, 10, up to 80 is meaningful, and that the effect of dose is at least proportional if not linear with respect to ChLDL, then we would treat Dose as ratio scale, not interval scale. That’s what we did here.
We can now proceed in R Commander to fit the model.
Rmdr: Statistics → Fit models → Linear model
How the model is inputted into linear model menu is shown in Figure 1.
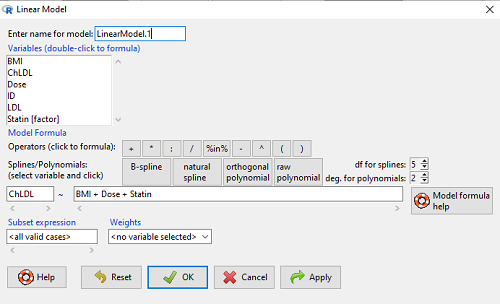
Figure 1. Screenshot of Rcmdr linear model menu with our model elements in place.
The output
summary(LinearModel.1)
Call:
lm(formula = ChLDL ~ BMI + Dose + Statin, data = cholStatins)

Residuals:
    Min      1Q  Median     3Q    Max
-3.7756 -0.5147 -0.0449 0.5038 4.3821

Coefficients:
                      Estimate Std. Error t value Pr(>|t|)
(Intercept)           1.016715   1.178430   0.863 0.39041
BMI                   0.058078   0.047012   1.235 0.21970
Dose                 -0.014197   0.004829  -2.940 0.00411 **
Statin[Statin2]       0.514526   0.262127   1.963 0.05255 .
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 1.31 on 96 degrees of freedom
Multiple R-squared: 0.1231, Adjusted R-squared: 0.09565
F-statistic: 4.49 on 3 and 96 DF, p-value: 0.005407
Question. What are the estimates of the model coefficients (rounded)?
 = intercept = 1.017
 = slope for variable BMI = 0.058
 = slope for variable Dose = -0.014
 = slope for variable Statin = -0.515
Question. Which of the three coefficients were statistically different from their null hypothesis (p-value < 5%)?
Answer: Only coefficient was judged statistically significant at the Type I error level of 5% (p = 0.0041). Of the four null hypotheses we have for the coefficients:
 = 0
 = 0
 = 0; we only reject the null hypothesis for
Dosecoefficient. = 0)
The important take-home concept is about the lack of a direct relationship between the magnitude of the estimate of the coefficient and the likelihood that it will be statistically significant! In absolute value terms  , but was not close to statistical significance (p = 0.220).
We generate a 2D scatterplot and include the regression lines (by group=Statin) to convey the relationship between at least one of the predictors (Fig 2).
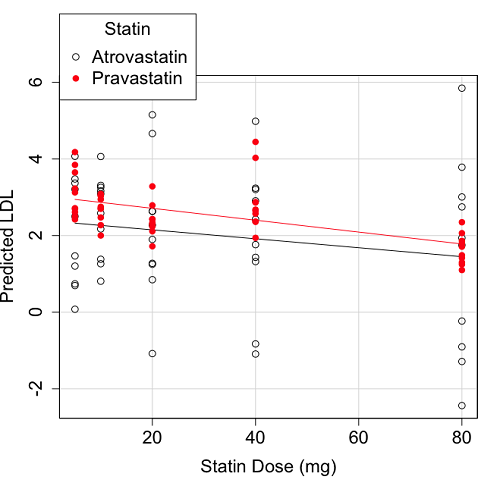
Figure 2. Scatter plot of predicted LDL against dose of a statin drug. Regression lines represent the different statin drugs (Statin1, Statin2).
Question. Based on the graph, can you explain why there will be no statistical differences between levels of the statin drug type, Statin1 (shown open circles) vs. Statin2 (shown closed red circles).
Because we have two predictors (BMI and Statin Dose), you may also elect to use a 3D-scatterplot. Here’s one possible result (Fig 3).
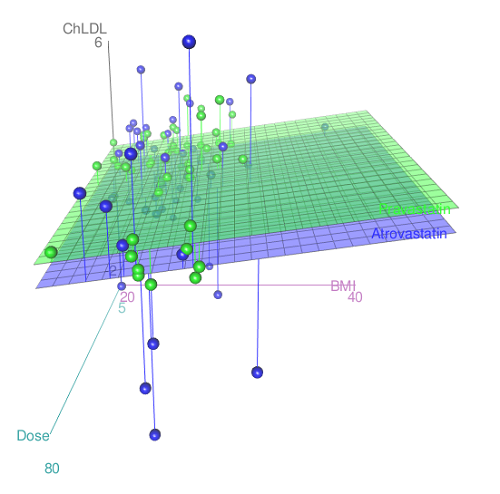
Figure 3. 3D plot of BMI and dose of Statin drugs on change in LDL levels (green Statin2, blue Statin1).
R code for Figure 3.
Graph made in Rcmdr: Graphs → 3D Graph → 3D scatterplot …
scatter3d(ChLDL~BMI+Dose|Statin, data=diabetesCholStatin, fit="linear",
residuals=TRUE, parallel=FALSE, bg="white", axis.scales=TRUE, grid=TRUE,
ellipsoid=FALSE)
Note 2: Figure 3 is a challenging graphic to interpret. I wouldn’t use it because it doesn’t convey a strong message. With some effort we can see the two planes representing mean differences between the two statin drugs across all predictors, but it’s a stretch. No doubt the graph can be improved by changing colors, for example, but I think the 2d plot Figure 2 works better). Alternatively, if the platform allows, you can use animation options to help your reader see the graph elements. Interactive graphics are very promising and, again, unsurprisingly, there are several R packages available. For this example, plot3d() of the package rgl can be used. Figure 4 is one possible version; I saved images and made animated gif.
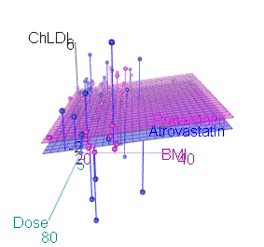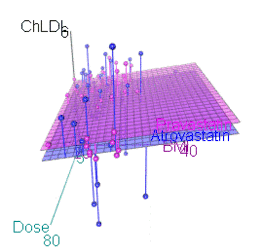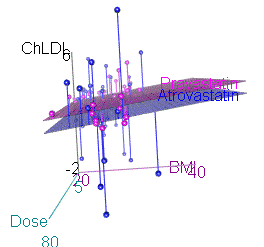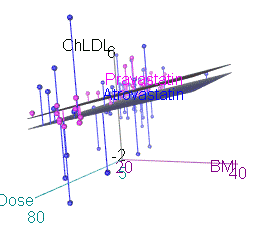
Figure 4. An example of a possible interactive 3D plot; the file embedded in this page is not interactive, just an animation.
Diagnostic plots
While visualization concerns are important, let’s return to the statistics. All evaluations of regression equations should involve an inspection of the residuals. Inspection of the residuals allows you to decide if the regression fits the data; if the fit is adequate, you then proceed to evaluate the statistical significance of the coefficients.
The default diagnostic plots (Fig 5) R provides are available from
Rcmdr: Models → Graphs → Basic diagnostics plots
Four plots are returned
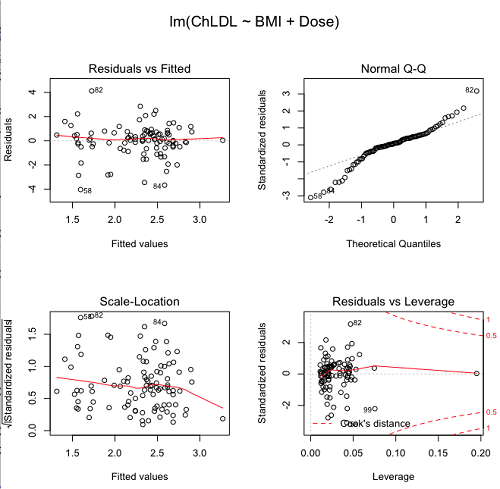
Figure 5. R’s default regression diagnostic plots.
Each of these diagnostic plots in Figure 4 gives you clues about the model fit.
- Plot of residuals vs. fitted helps you identify patterns in the residuals
- Normal Q-Q plot helps you to see if the residuals are approximately normally distributed
- Scale-location plot provides a view of the spread of the residuals
- The residuals vs. leverage plot allows you to identify influential data points.
We introduced these plots in Chapter 17.8 when we discussed fit of simple linear model to data. My conclusion? No obvious trend in residuals, so linear regression is a fit to the data; data not normally distributed Q-Q plot shows S-shape.
Interpreting the diagnostic plots for this problem
The “Normal Q-Q” plot allows us to view our residuals against a normal distribution (the dotted line). Our residuals do no show an ideal distribution: low for the first quartile, about on the line for intermediate values, then high for the 3rd and 4th quartile residuals. If the data were bivariate normal we would see the data fall along a straight line. The “S-shape” suggests log-transformation of the response and or one or more of the predictor variables.
There also seems to be a pattern in residuals vs the predicted (fitted) values. There is a trend of increasing residuals as cholesterol levels increase, which is particularly evident in the “scale-location” plot. Residuals tended to be positive at low and high doses, but negative at intermediate doses. This suggests that the relationship between predictors and cholesterol levels may not be linear, and it demonstrates what statisticians refer to as a monotonic spread of residuals.
The last diagnostic plot looks for individual points that influence, change, or “leverage” the regression — in other words, if a point is removed, does the general pattern change? If so, then the point had “leverage” and thus we need to decide whether or not to include the datum. diagnostic plots Cook’s distance is a measure of the influence of a point in regression. Points with large Cook’s distance values warrant additional checking.
The multicollinearity problem
Statistical model building is a balancing act by the statistician. While simpler models may be easier to interpret and, perhaps, to use, it is a basic truism that the more predictor variables the model includes, the more realistic the statistical model. However, each additional parameter that is added to the statistical model must be independent of all other parameters already in the model. To the extent that this assumption is violated, the problem is termed multicollinearity. If predictor variables are highly correlated, then they are essentially just linear combinations and do not provide independent evidence. For example, one would naturally not include two core body temperature variables in a statistical model on basal metabolic rate, one in degrees Fahrenheit and the other in degrees Celsius, because it is a simple linear conversion between the two units. This would be an example of structural collinearity: the collinearity is because of misspecification of the model variables. In contrast, collinearity among predictor variables may because the data are themselves correlated. For example, if multiple measures of body size are included: weight, height, length of arm, etc., then we would expect these to be correlated, ie, data multicollinearity.
Collinearity in statistical models may have a number of undesirable effects on a multiple regression model. These include
- estimates of coefficients not stable: with collinearity, values of coefficients depend on other variables in the model; if collinear predictors, then the assumption of independent predictor variables is violated.
- precision of the estimates decreases (standard error of estimates increase).
- statistical power decreases.
- p-values for individual coefficients not trust worthy.
Tolerance and Variance Inflation Factor
Absence of multicollinearity is important assumption of multiple regression. A partial test is to calculate product moment correlations among predictor variables. For example, when we calculate the correlation between BMI and Dose for our model, we get r = 0.101 (P = 0.3186), and therefore would tentatively conclude that there was little correlation between our predictor variables.
A number of diagnostic statistics have been developed to test for multicollinearity. Tolerance for a particular independent variable (Xi) is defined as 1 minus the proportion of variance it shares with the other independent variables in the regression analysis (1 − R2i) (O’Brien 2007). Tolerance reports the proportion of total variance explained by adding the Xi–th predictor variable that is unrelated to the other variables in the model. A small value for tolerance indicates multicollinearity — and that the predictor variable is nearly a perfect combination (linear) of the variables already in the model and therefore should be omitted from the model. Because tolerance is defined in relation to the coefficient of determination you can interpret a tolerance score as the unique variance accounted for by a predictor variable.
A second, related diagnostic of multicollinearity is called the Variance Inflation Factor, VIF. VIF is the inverse of tolerance.
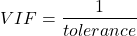
VIF shows how much of the variance of a regression coefficient is increased because of collinearity with the other predictor variables in the model. VIF is easy to interpret: a tolerance of 0.01 has a VIF of 100; a tolerance of 0.1 has a VIF of 10; a tolerance of 0.5 has a VIF of 2, and so on. Thus, small values of tolerance and large values of VIF are taken as evidence of multicollinearity.
Rcmdr: Models → Numerical diagnostics → Variation-inflation factors
vif(RegModel.2)
      BMI     Dose
1.010256 1.010256
A rule of thumb is that if VIF is greater than 5 then there is multicollinearity; with VIF values close to one we would conclude, like our results from the partial correlation estimate above, that there is little evidence for a problem of collinearity between the two predictor variables. They can therefore remain in the model.
Solutions for multicollinearity
If there is substantial multicollinearity then you cannot simply trust the estimates of the coefficients. Assuming that there hasn’t been some kind of coding error on your part, then you may need to find a solution. One solution is to drop one of the predictor variables and redo the regression model. Another option is to run what is called a Principal Components Regression (PCR). One takes the predictor variables and runs a Principal Component Analysis to reduce the number of variables, then the regression is run on the PCA components. By definition, the PCA components are independent of each other. Another option is to use ridge regression approach.
Note 3. Principal Component Analysis (PCA) is a dimensionality reduction technique that finds new uncorrelated variables (principal components) by maximizing variance. Principal Component Regression (PCR) uses PCA as a preprocessing step to create a regression model. The key difference is that PCA is an unsupervised method for data transformation, whereas PCR is a supervised regression technique that uses the components from PCA to predict an outcome. It’s probably not a great idea to use the acronym PCR in our biology reports; easily confused with polymerase chain reaction
Like any diagnostic rule, however, one should not blindly apply a rule of thumb. A VIF of 10 or more may indicate multicollinearity, but it does not necessarily lead to the conclusion that the linear regression model requires that the researcher reduce the number of predictor variables or analyze the problem using a different statistical method to address multicollinearity as the sole criteria of a poor statistical model. Rather, the researcher needs to address all of the other issues about model and parameter estimate stability, including sample size. Unless the collinearity is extreme (like a correlation of 1.0 between predictor variables!), larger sample sizes alone will work in favor of better model stability (by lowering the sample error) (O’Brien 2007).
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- Please explain why the magnitude of the slope is not the key to statistical significance of a slope? Hint: look at the equation of the t-test for statistical significance of the slope.
- Consider the following scenario. A researcher measures his subjects multiple times for blood pressure over several weeks, then plots all of the values over time. In all, the data set consists of thousands of readings. He then proceeds to develop a model to explain blood pressure changes over time. What kind of collinearity is present in his data set? Explain your choice.
- We noted that
Dosecould be viewed as categorical variable. ConvertDoseto factor variable (fDose) and redo the linear model. Compare the summary output and discuss the additional coefficients.- Use Rcmdr: Data → Manage variables in active data set → Convert numeric Variables to Factors to create a new factor variable
fDose. It’s ok to use the numbers as factor levels.
- Use Rcmdr: Data → Manage variables in active data set → Convert numeric Variables to Factors to create a new factor variable
- We flagged the change in LDL as likely to be not normally distributed. Create a log10-transformed variable for
ChLDLand perform the multiple regression again.- Write the new statistical model
- Obtain the regression coefficients — are they statistically significant?
- Run basic diagnostic plots and evaluate for
Quiz Chapter 18.1
Multiple Linear Regression
Data set
| ID | Statin | Dose | BMI | LDL | ChLDL |
|---|---|---|---|---|---|
| 1 | Statin2 | 5 | 19.5 | 3.497 | 2.714778 |
| 2 | Statin1 | 20 | 20.2 | 4.268 | 1.276483 |
| 3 | Statin2 | 40 | 20.3 | 3.989 | 2.677377 |
| 4 | Statin2 | 20 | 20.3 | 3.502 | 2.430618 |
| 5 | Statin2 | 80 | 20.4 | 3.766 | 1.79463 |
| 6 | Statin2 | 20 | 20.6 | 3.44 | 2.234295 |
| 7 | Statin1 | 20 | 20.7 | 3.414 | 2.635305 |
| 8 | Statin1 | 10 | 20.8 | 3.222 | 0.809181 |
| 9 | Statin1 | 10 | 21.1 | 4.04 | 3.259599 |
| 10 | Statin1 | 40 | 21.2 | 4.429 | 1.763997 |
| 11 | Statin1 | 5 | 21.2 | 3.528 | 3.369377 |
| 12 | Statin1 | 40 | 21.5 | 3.01 | -0.827154 |
| 13 | Statin2 | 20 | 21.6 | 3.393 | 2.11172 |
| 14 | Statin1 | 10 | 21.7 | 4.512 | 3.166238 |
| 15 | Statin1 | 80 | 22 | 5.449 | 3.00833 |
| 16 | Statin2 | 10 | 22.2 | 4.03 | 3.05013 |
| 17 | Statin2 | 40 | 22.2 | 3.911 | 2.646034 |
| 18 | Statin2 | 10 | 22.2 | 3.724 | 2.945656 |
| 19 | Statin1 | 5 | 22.2 | 3.238 | 3.209584 |
| 20 | Statin2 | 10 | 22.5 | 4.123 | 3.088763 |
| 21 | Statin1 | 20 | 22.6 | 3.859 | 5.152548 |
| 22 | Statin1 | 10 | 23 | 4.926 | 2.58483 |
| 23 | Statin2 | 20 | 23 | 3.512 | 2.291975 |
| 24 | Statin1 | 5 | 23 | 3.838 | 1.469 |
| 25 | Statin2 | 20 | 23.1 | 3.548 | 2.34079 |
| 26 | Statin1 | 5 | 23.1 | 3.424 | 1.204346 |
| 27 | Statin1 | 40 | 23.2 | 3.709 | 3.238179 |
| 28 | Statin1 | 80 | 23.2 | 4.786 | 2.748643 |
| 29 | Statin1 | 20 | 23.3 | 4.103 | 1.250082 |
| 30 | Statin1 | 40 | 23.4 | 3.341 | 1.432292 |
| 31 | Statin1 | 10 | 23.5 | 3.828 | 1.381755 |
| 32 | Statin2 | 10 | 23.8 | 4.02 | 3.039187 |
| 33 | Statin1 | 20 | 23.8 | 3.942 | 0.848328 |
| 34 | Statin2 | 20 | 23.8 | 2.89 | 1.721163 |
| 35 | Statin1 | 80 | 23.9 | 3.326 | 1.939346 |
| 36 | Statin1 | 10 | 24.1 | 4.071 | 3.090741 |
| 37 | Statin1 | 40 | 24.1 | 4.222 | 1.322305 |
| 38 | Statin2 | 10 | 24.1 | 3.44 | 2.472223 |
| 39 | Statin1 | 5 | 24.2 | 3.507 | 0.076817 |
| 40 | Statin2 | 20 | 24.2 | 3.647 | 2.425758 |
| 41 | Statin2 | 80 | 24.3 | 3.812 | 1.710575 |
| 42 | Statin2 | 40 | 24.3 | 3.305 | 1.940572 |
| 43 | Statin2 | 5 | 24.3 | 3.455 | 2.502214 |
| 44 | Statin2 | 5 | 24.4 | 4.258 | 3.228008 |
| 45 | Statin1 | 5 | 24.4 | 4.16 | 3.477747 |
| 46 | Statin2 | 80 | 24.4 | 4.128 | 2.063247 |
| 47 | Statin1 | 80 | 24.5 | 4.507 | 3.784422 |
| 48 | Statin1 | 5 | 24.5 | 3.553 | 0.695709 |
| 49 | Statin2 | 10 | 24.5 | 3.616 | 2.69987 |
| 50 | Statin2 | 80 | 24.6 | 3.372 | 1.300401 |
| 51 | Statin2 | 80 | 24.6 | 3.667 | 1.418109 |
| 52 | Statin2 | 5 | 24.7 | 3.854 | 3.126671 |
| 53 | Statin1 | 80 | 24.7 | 3.32 | -1.286439 |
| 54 | Statin2 | 5 | 24.7 | 3.756 | 2.423664 |
| 55 | Statin1 | 40 | 24.8 | 4.398 | 2.907473 |
| 56 | Statin2 | 40 | 24.9 | 3.621 | 2.362429 |
| 57 | Statin1 | 10 | 25 | 3.17 | 1.264656 |
| 58 | Statin1 | 80 | 25.1 | 3.424 | -2.436908 |
| 59 | Statin2 | 10 | 25.1 | 3.196 | 2.001465 |
| 60 | Statin2 | 80 | 25.2 | 3.367 | 1.100704 |
| 61 | Statin1 | 80 | 25.2 | 3.067 | -0.23154 |
| 62 | Statin1 | 20 | 25.3 | 3.678 | 4.662866 |
| 63 | Statin2 | 5 | 25.5 | 4.077 | 2.611705 |
| 64 | Statin1 | 20 | 25.5 | 3.678 | 2.633053 |
| 65 | Statin2 | 5 | 25.6 | 4.994 | 4.180082 |
| 66 | Statin1 | 20 | 25.8 | 3.699 | 1.899031 |
| 67 | Statin1 | 10 | 25.9 | 3.507 | 4.063757 |
| 68 | Statin2 | 20 | 25.9 | 3.445 | 2.303761 |
| 69 | Statin1 | 5 | 26 | 4.025 | 2.501427 |
| 70 | Statin1 | 5 | 26.3 | 3.616 | 0.740863 |
| 71 | Statin2 | 40 | 26.4 | 3.937 | 2.573321 |
| 72 | Statin2 | 40 | 26.4 | 3.823 | 2.363839 |
| 73 | Statin1 | 10 | 26.7 | 4.46 | 2.174198 |
| 74 | Statin2 | 5 | 26.7 | 5.03 | 3.845271 |
| 75 | Statin2 | 10 | 26.7 | 3.73 | 2.708896 |
| 76 | Statin2 | 10 | 26.7 | 3.232 | 2.272627 |
| 77 | Statin1 | 80 | 26.8 | 3.693 | 1.751169 |
| 78 | Statin2 | 80 | 27 | 4.108 | 1.86131 |
| 79 | Statin2 | 40 | 27.2 | 5.398 | 4.028977 |
| 80 | Statin2 | 80 | 27.2 | 4.517 | 2.348903 |
| 81 | Statin2 | 20 | 27.3 | 3.901 | 2.790047 |
| 82 | Statin1 | 80 | 27.3 | 5.247 | 5.848545 |
| 83 | Statin2 | 80 | 27.4 | 3.507 | 1.247863 |
| 84 | Statin1 | 20 | 27.4 | 3.807 | -1.079928 |
| 85 | Statin2 | 80 | 27.6 | 3.574 | 1.486789 |
| 86 | Statin1 | 40 | 27.8 | 4.16 | 2.427753 |
| 87 | Statin2 | 20 | 28 | 4.501 | 3.284648 |
| 88 | Statin2 | 5 | 28.1 | 3.621 | 2.699007 |
| 89 | Statin1 | 40 | 28.2 | 3.652 | -1.091256 |
| 90 | Statin2 | 40 | 28.2 | 4.191 | 2.874231 |
| 91 | Statin2 | 40 | 28.4 | 5.791 | 4.445454 |
| 92 | Statin1 | 40 | 28.6 | 4.698 | 3.202874 |
| 93 | Statin1 | 5 | 29 | 4.32 | 4.070753 |
| 94 | Statin2 | 10 | 29.1 | 3.776 | 2.751281 |
| 95 | Statin2 | 5 | 29.2 | 4.703 | 3.64949 |
| 96 | Statin2 | 40 | 29.9 | 4.128 | 2.864691 |
| 97 | Statin1 | 40 | 30.4 | 4.693 | 4.983704 |
| 98 | Statin1 | 20 | 30.4 | 4.123 | 2.273898 |
| 99 | Statin1 | 80 | 30.5 | 3.921 | -0.903438 |
| 100 | Statin1 | 10 | 36.5 | 4.175 | 3.311437 |
Chapter 18 contents
17.3 – Estimation of linear regression coefficients
Introduction
In discussing correlations we made the distinction between inference, testing the statistical significance of the estimate, and the process of getting the estimate of the parameter itself. Estimating parameters is possible for any data set; whether or not the particular model is a good and useful model is another matter. Statisticians speak about the fit of a model… that a model with one or more independent predictor variables explains a substantial amount of the variation in the dependent variable, that it describes the relationship between the predictors and the dependent variable without bias.
Note 1. We introduced the concept of statistical fit in our discussion of Chi-square, goodness of fit, Chapter 9.1.
A number of tools have been developed to assess model fit. For starters, I’ll list just two ways you can approach whether or not a linear model fits your data ore requires some intervention on your part.
Assess fit of a linear model
Recall our R output from the regression of Number of Matings on Body Mass from the bird data set. We used the linear model function.
LinearModel.1 <- lm(Matings ~ Body.Mass, data=bird_matings)
summary(LinearModel.1)
Call: lm(formula = Matings ~ Body.Mass, data = bird_matings)
Residuals:       Min       1Q    Median       3Q      Max
            -2.29237 -1.34322 .-0.03178..1.33792 .2.70763
Coefficients:
             Estimate  Std. Error  t value  Pr(>|t|)
(Intercept)   -8.4746      4.6641   -1.817    0.1026
Body.Mass      0.3623      0.1355    2.673    0.0255 *
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Residual standard error: 1.776 on 9 degrees of freedom
Multiple R-squared: 0.4425, Adjusted R-squared: 0.3806
F-statistic: 7.144 on 1 and 9 DF, p-value: 0.02551
Request R to print the ANOVA table.
Anova(RegModel.1, type="II")
Anova Table (Type II tests)
Response: Matings
            Sum Sq   Df   F value    Pr(>F)
Body.Mass   22.528    1    7.1438   0.02551 *
Residuals   28.381    9
With a little rounding we have the following statistical model
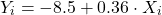
and in English, Number of matings equals Body.mass multiplied by 0.36 then subtract 8.5; the intercept was -8.5, the slope was 0.36.
Note 2. The results of the regression analyses were stored in the object called “LinearModel.1“. This is a nice feature of Rcmdr — it automatically provides an object name for you. Note that with each successive run of the linear model function via Rcmdr that it will change the object name by adding numbers successively. For example, after LinearModel.1 the next run of lm() in Rcmdr will automatically be called “LinearModel.2” and so on. In your own work you may specify the names of the objects directly or allow Rcmdr to do it for you, but do keep track of the object names!
From the R output we see that the estimate of the slope was +0.36, statistically different from zero (p = 0.025). The intercept was -8.5, but not statistically significant (p = 0.103), which means the intercept may be zero.
As a general rule, if you make an estimate of a parameter or coefficient, then you should provide a confidence interval of the form.
estimate + critical value X standard error of the estimate
Note 3. Reminder: Approximate 95% CI can be obtained by + twice the standard error for the coefficient.
For confidence interval of regression slope we have a couple of options in R
Option 1.
confint(LinearModel.1, 'Body.Mass', level=0.95)

               2.5 %    97.5 %
Body.Mass 0.05565899 0.6689173
Option 2.
Goal: Extract the coefficients from the output of the linear model and calculate the approximate SE with nine degrees of freedom. This is the big advantage of saving output from functions as objects. Typically, much more information is about the results are available, and, additionally, can be retrieved for additional use. Extracting coefficients from the objects is the best option, but does come with a learning curve. Let’s get started.
First, what information is available in the linear model output beyond the default information? To find out, use the names() function
names(LinearModel.1)
R output
 [1] "coefficients"  "residuals"     "effects"       "rank"
 [5] "fitted.values" "assign"        "qr"            "df.residual"
 [9] "xlevels"       "call"          "terms"         "model"
Another way is to use the summary() function call.
summary(LinearModel.1)$coefficients
              Estimate Std. Error   t value   Pr(>|t|)
(Intercept) -8.4745763  4.6640856 -1.816986 0.10259256
Body.Mass    0.3622881  0.1355472  2.672781 0.02550595
How can we get just the standard error for the slope? Note that the estimates are reported in a 2X4 matrix like so
| 1,1 | 1,2 | 1,3 | 1,4 |
| 2,1 | 2,2 | 2,3 | 2,4 |
Therefore, to get the standard error for the slope we identify that it is stored in cell 2,2 of the matrix and we write
summary(LinearModel.1)$coefficients[2,2]
which returns
[1] 0.1355472
Let’s use this information to calculate confidence intervals
slp=summary(LinearModel.1)$coefficients[2,1]
slpErrs=summary(LinearModel.1)$coefficients[2,2]
slp + c(-1,1)*slpErrs*qt(0.975, 9)
where qt() is the quantile function for the t distribution and “9” is the degrees of freedom from the regression. Results follow
coef + c(-1,1)*errs*qt(0.975, 9)
[1] 0.05565899 0.66891728
And for the intercept
int=summary(LinearModel.1)$coefficients[1,1]
intErrs=summary(LinearModel.1)$coefficients[1,2]
int + c(-1,1)*intErrs*qt(0.975, 9)
Results
int + c(-1,1)*intErrs*qt(0.975, 9)
[1] -19.025471   2.076318
In conclusion, part of fitting a model includes reporting the estimates of the coefficients (model parameters). And, in general, when estimation is performed, reporting of suitable confidence intervals are expected.
Extract additional statistics from R’s linear model function
The summary() function is used to report the general results from ANOVA and linear model function output in R software, but additional functions can be used to extract the rest of the output, e.g., coefficient of determination. To complete our example of extracting information from the summary() function, we next turn to summary.lm() function to see what is available.
At the R prompt type and submit
summary.lm(LinearModel.1)
returns the following R output
Call:
lm(formula = Matings ~ Body.Mass, data = bird_matings)

Residuals:
     Min       1Q   Median       3Q      Max
-2.29237 -1.34322 -0.03178  1.33792  2.70763

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept)  -8.4746     4.6641  -1.817   0.1026
Body.Mass     0.3623     0.1355   2.673   0.0255 *
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 1.776 on 9 degrees of freedom
Multiple R-squared:  0.4425,    Adjusted R-squared:  0.3806
F-statistic: 7.144 on 1 and 9 DF,  p-value: 0.02551
Looks exactly like the output from summary(). Let’s look at what is available in the summary.lm() function
names(summary.lm(LinearModel.1))
 [1] "call"          "terms"         "residuals"     "coefficients"
 [5] "aliased"       "sigma"         "df"            "r.squared"
 [9] "adj.r.squared" "fstatistic"    "cov.unscaled"
We see some information we got from summary(), e.g., “coefficients”. If we interrogate the name coefficients like so
summary.lm(LinearModel.1)$coefficients
we get
summary.lm(LinearModel.1)$coefficients
              Estimate Std. Error   t value   Pr(>|t|)
(Intercept) -8.4745763  4.6640856 -1.816986 0.10259256
Body.Mass    0.3622881  0.1355472  2.672781 0.02550595
which, again, is a 2X4 matrix (see above)
So to get the standard error for the slope we identify that it is stored in cell 2,2 of the matrix and call it LinearModel.1$coefficients[2,2].
Questions
1. Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
2. What does a small standard error of the slope for a SLR model tell us?
3. For slope, intercept, for just about any statistical estimate, why are we obligated to provide a confidence interval?
Quiz Chapter 17.3
Estimation of linear regression coefficients
Chapter 17 contents
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)
17.1 – Ordinary least squares regression
-
- Introduction
- Example
- Least squares regression explained
- Models used to predict new values
- R code
- How to extract information from an R object
- Regression equations may be useful to predict new observations
- Regression through the origin
- Assumptions of OLS, an introduction
- Questions
- Quiz
- Chapter 17 contents
Introduction
Linear regression is a toolkit for developing linear models of cause and effect between a ratio scale data type, response or dependent variable, often labeled “Y,” and one or more ratio scale data type, predictor or independent variables, X. Like ANOVA, linear regression is a special case of the general linear model. Regression and correlation both test linear hypotheses: we state that the relationship between two variables is linear (the alternative hypothesis) or it is not (the null hypothesis). The difference?
- Correlation is a test of linear association (are variables correlated, we ask?), but are not tests of causation: we do not imply that one variable causes another to vary, even if the correlation between the two variables is large and positive, for example. Correlations are used in statistics on data sets not collected from explicit experimental designs incorporated to test specific hypotheses of cause and effect.
- Linear regression is to cause and effect as correlation is to association. With regression and ANOVA, which again, are special cases of the general linear model (LM), we are indeed making a case for a particular understanding of the cause of variation in a response variable: modeling cause and effect is the goal.
We start our LM model as 
where “~”, tilda, is an operator used by R in formulas to define the relationship between the response variable and the predictor variable(s).
From R Commander we call the linear model function by Statistics → Fit models → Linear model … , which brings up a menu with several options (Fig 1).
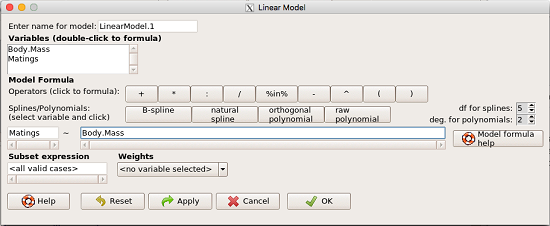
Figure 1. R commander menu interface for linear model.
Our model was
Matings ~ Body.Mass
R commander will keep track of the models created and enter a name for the object. You can, and probably should, change the object name yourself. The example shown in Figure 1 is a simple linear regression, with Body.Mass as the Y variable and Matings the X variable. No other information need be entered and one would simply click OK to begin the analysis.
Example
The purpose of regression is similar to ANOVA. We want a model, a statistical representation to explain the data sample. The model is used to show what causes variation in a response (dependent) variable using one or more predictors (independent variables). In life history theory, mating success is an important trait or characteristic that varies among individuals in a population. For example we may be interested in determining the effect of age (X1) and body size (X2) on mating success for a bird species. We could handle the analysis with ANOVA, but we would lose some information. In a clinical trial, we may predict that increasing Age (X1) and BMI (X2) causes increase blood pressure (Y).
Our causal model looks like
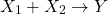
Let’s review the case for ANOVA first.
The response (dependent variable), the number of successful matings for each individual male bird, would be a quantitative (interval scale) variable. (Reminder: You should be able to tell me what kind of analysis you would be doing if the dependent variable was categorical!) If we use ANOVA, then factors have levels. For example, we could have several adult birds differing in age (factor 1) and of different body sizes. Age and body size are quantitative traits, so, in order to use our standard ANOVA, we would have to assign individuals to a few levels. We could group individuals by age (eg, < 6 months, 6 – 10 months, > 12 months) and for body size (eg, small, medium, large). For the second example, we might group the subjects into age classes (20-30, 30-40, etc), and by AMA recommended BMI levels (underweight < 18.5, normal weight 18.5 – 24.9, overweight 25-29.9, obese > 30).
We have not done anything wrong by doing so, but if you are a bit uneasy by this, then your intuition will be rewarded later when we point out that in most cases you are best to leave it as a quantitative trait. We proceed with the test of ANOVA, but we are aware that we’ve lost some information — continuous variables (age, body size, BMI) were converted to categories — and so we suspect (correctly) that we’ve lost some power to reject the null hypothesis. By the way, when you have a “factor” that is a continuous variable, we call it a “covariate.” Factor typically refers to a categorical explanatory (independent) variable.
We might be tempted to use correlation — at least to test if there’s a relationship between Body Mass and Number of Matings. Correlation analysis is used to measure the intensity of association between a pair of variables. Correlation is also used to to test whether the association is greater than that expected by chance alone. We do not express one as causing variation in the other variable, but instead, we ask if the two variables are related (covary). We’ve already talked about some properties of correlation: it ranges from -1 to +1 and the null hypothesis is that the true association between two variables is equal to zero. We will formalize the correlation next time to complete our discussion of the linear relationship between two variables.
But regression is appropriate here because we are indeed making a causal claim: we selected Age and Body Size, and we selected Age and BMI in the second example wish to develop a model so we can predict and maybe even advise.
Least squares regression explained
Regression is part of the general linear model family of tests. If there is one linear predictor variable, then that is a simple linear regression (SLR), also called ordinary least squares (OLS), if there are two or more linear predictor variables, then that is a multiple linear regression (MLR, Chapter 18).
First, consider one predictor variable. We begin by looking at how we might summarize the data by fitting a line to the data; we see that there’s a relationship between mass and mating success in both young and old females (and maybe in older males).
The data set was
Table 1. Our data set of number of matings by male bird by body mass (g).
| Body.Mass | Matings |
|---|---|
| 29 | 0 |
| 29 | 2 |
| 29 | 4 |
| 32 | 4 |
| 32 | 2 |
| 35 | 6 |
| 36 | 3 |
| 38 | 3 |
| 38 | 5 |
| 38 | 8 |
| 40 | 6 |
Note 1: Unfortunately, I’ve lost track where Table 1 data set came from! It’s likely a simulated set inspired by my readings back in 2005.
And a scatterplot of the data (Fig 2)
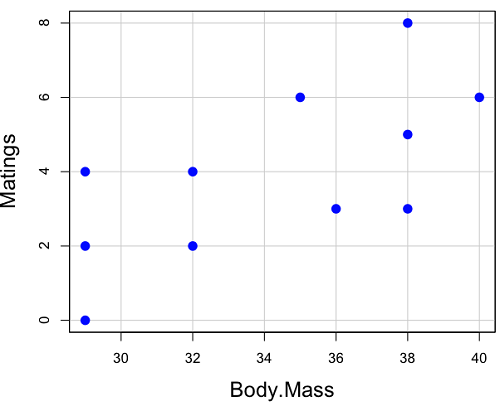
Figure 2. Number of matings by body mass (g) of the male bird.
There’s some scatter, but our eyes tell us that as body size increases, the number of matings also increases. We can go so far as to say that we can predict (imperfectly) that larger birds will have more matings. We fit the best fit line to the data and added the line to our scatterplot (Fig 3). The best fit line meets the requirements that the error about the line is minimized (see below). Thus, we would predict about six matings for a 40 g bird, but only two matings for a 28 g bird. And this is a good feature of regression, prediction, as long as used with some caution.
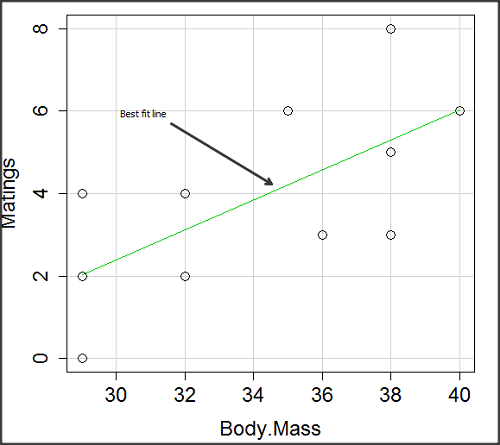
Figure 3. Same data as in Fig 2, but with the “best fit” line.
The prediction works best for the range of data for which the regression model was built. Outside the range of values, we predict with caution.
The simplest linear relationship between two variables is the SLR. This would be the parameter version (population, not samples), where
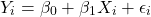
= the Y-intercept coefficient and it is defined as
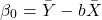
solve for intercept by setting X = 0.
= the regression coefficient (slope)
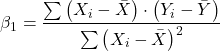
Note 2: The denominator is just our corrected sums of squares that we’ve seen many times before. The numerator is the cross-product and is referred to as the covariance.
ε = the error or “residual”

The residual is an important concept in regression. We briefly discussed “what’s left over,” in ANOVA, where an observation Yi is equal to the population mean plus the factor effect of level i plus the remainder or “error”.
In regression, we speak of residuals as the departure (difference) of an actual Yi (observation) from the predicted Y ( , say “why-hat”).
the linear regression predicts Y
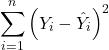
and what remains unexplained by the regression equation is called the residual
There will be as many residuals as there were observations.
But why THIS particular line? We could draw lines anywhere through the points. Well, this line is termed the “best fit“ because it is the only line that minimizes the sum of the squared deviations for all values of Y (the observations) and the predicted . The best fit line minimizes the sum of the squared residuals.
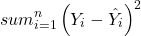
Note 3: More technically we justify the OLS as best fit by saying” Following the Gauss–Markov theorem, OLS estimators are the best linear unbiased estimators (BLUE). Gauss (1821) proved that the least squares method produces unbiased estimates with the smallest variance, a key result for regression analysis, while Markov (1900) rediscovered Gauss’ work and showed the conclusions held under less restrictive conditions.
Thus, like ANOVA, we can account for the total sums of squares (SSTot) as equal to the sums of squares (variation), explained by the regression model, SSreg, plus what’s not explained, what’s left over, the residual sums of squares, SSres, aka SSerror.
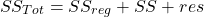
How well does our model explain — fit — our data? We cover this topic in Chapter 17.3 — Estimation of linear regression coefficients, but for now, we introduce  , the coefficient of determination.

ranges from zero (0%), the linear model fails completely to explain the data, to one (100%), the linear model explains perfectly every datum.
Models used to predict new values
Once a line has been estimated, one use is to predict new observations not previously measured!
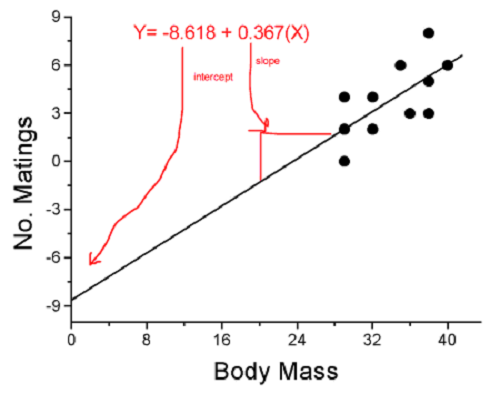
Figure 4. Figure 3 redrawn to extend the line to the Y intercept.
This is an important use of models in statistics: use an equation to fit to some data, then predict Y values from new values of X. To use the equation, simply insert new values of X into the equation, because the slope and intercept are already “known.” Then for any Xi we can determine  (predicted Y value that is on the best fit regression line).
This is what people do when they say
“if you are a certain weight (or BMI) you have this increased risk of heart disease”
“if you have this number of black rats in the forest you will have this many nestlings survive to leave the nest”
“if you have this much run-off pollution into the ocean you have this many corals dying”
“if you add this much enzyme to the solution you will have this much resulting product”.
R Code
We can use the drop down menu in Rcmdr to do the bulk of the work, supplemented with a little R code entered and run from the script window. Scrape data from Table 1 and save to R as bird.matings.
LinearModel.3 <- lm(Matings ~ Body.Mass, data=bird.matings)
summary(LinearModel.3)
Output from R — we’ll pull apart the important parts, color-highlights used to help orient the reader as we go.
Call:
lm(formula = Matings ~ Body.Mass, data = bird.matings)

Residuals:
     Min       1Q   Median      3Q     Max
-2.29237 -1.34322 -0.03178 1.33792 2.70763

Coefficients:
            Estimate Std. Error  t value  Pr(>|t|)
(Intercept)  -8.4746     4.6641   -1.817    0.1026
Body.Mass     0.3623     0.1355    2.673    0.0255 *
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 1.776 on 9 degrees of freedom
Multiple R-squared: 0.4425, Adjusted R-squared: 0.3806
F-statistic: 7.144 on 1 and 9 DF, p-value: 0.02551
What are the values for the coefficients? See Estimate .
Table 2. Coefficient estimates.
| Value | |
 , Y-intercept |
-8.4746 |
 , Slope |
0.3623 |
Get the sum of squares from the ANOVA table
myAOV.full <- anova(LinearModel.3); myAOV.full
Output from R, the ANOVA table
Analysis of Variance Table

Response: Matings
           Df  Sum Sq  Mean Sq  F value     Pr(>F)
Body.Mass   1  22.528  22.5277   7.1438   0.02551 *
Residuals   9  28.381   3.1535
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Looking for , the coefficient of determination? From the R output identify Multiple R-squared. We find 0.4425. Grab the SSreg and SSTot from the ANOVA table and confirm
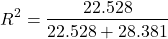
Note 2: The value of increases with each additional predictor variable included in the model, whether statistically significant contributor or not, regardless of whether the association between the predictor is simply due to chance. The Adjusted R-squared is an attempt to correct for this bias.
The residual standard error, RSE, is another model fit statistic.
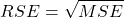
The smaller the residual standard error, the better the model fit to the data. See Residual standard error: 1.776 and MSE = 3.1535 above.
And the “statistical significance?” See Pr(>|t|) .There were tests for each coefficient,  and
 :
Table 3. Coefficient estimates.
| P-value | |
| , Y-intercept |
0.1026 |
| , Slope |
0.0255 |
And, at last, note that p-value, Pr(>F), reported in the Analysis of Variance Table, is the same as the p-value for the slope reported as Pr(>|t|).
Make a prediction:
How many matings expected for a 40 g male?
predict(LinearModel.3, data.frame(Body.Mass=40))
R output
1
6.016949
Answer: we predict 6 matings for a 40g male.
See below for predicting confidence limits.
How to extract information from an R object
We can do more — the lm() returnd a great deal of information about our regression model. Explore all that is available in the objects LinearModel.3 and myAOV.full with the str() command.
Note 3: str() command lets us look at an object created in R. Type ?str or help(str) to bring up the R documentation. Here, we use str() to look at the structure of the objects we created. “Classes” refers to the R programming class attribute inherited by the object. We first used str() in Chapter 8.3.
str(LinearModel.3)
Output from R
List of 12
$ coefficients : Named num [1:2] -8.475 0.362
..- attr(*, "names")= chr [1:2] "(Intercept)" "Body.Mass"
$ residuals : Named num [1:11] -2.0318 -0.0318 1.9682 0.8814 -1.1186 ...
..- attr(*, "names")= chr [1:11] "1" "2" "3" "4" ...
$ effects : Named num [1:11] -12.965 4.746 2.337 1.327 -0.673 ...
..- attr(*, "names")= chr [1:11] "(Intercept)" "Body.Mass" "" "" ...
$ rank : int 2
$ fitted.values: Named num [1:11] 2.03 2.03 2.03 3.12 3.12 ...
..- attr(*, "names")= chr [1:11] "1" "2" "3" "4" ...
$ assign : int [1:2] 0 1
$ qr :List of 5
..$ qr : num [1:11, 1:2] -3.317 0.302 0.302 0.302 0.302 ...
.. ..- attr(*, "dimnames")=List of 2
.. .. ..$ : chr [1:11] "1" "2" "3" "4" ...
.. .. ..$ : chr [1:2] "(Intercept)" "Body.Mass"
.. ..- attr(*, "assign")= int [1:2] 0 1
..$ qraux: num [1:2] 1.3 1.3
..$ pivot: int [1:2] 1 2
..$ tol : num 0.0000001
..$ rank : int 2
..- attr(*, "class")= chr "qr"
$ df.residual : int 9
$ xlevels : Named list()
$ call : language lm(formula = Matings ~ Body.Mass, data = bird_matings)
$ terms :Classes 'terms', 'formula' language Matings ~ Body.Mass
.. ..- attr(*, "variables")= language list(Matings, Body.Mass)
.. ..- attr(*, "factors")= int [1:2, 1] 0 1
.. .. ..- attr(*, "dimnames")=List of 2
.. .. .. ..$ : chr [1:2] "Matings" "Body.Mass"
.. .. .. ..$ : chr "Body.Mass"
.. ..- attr(*, "term.labels")= chr "Body.Mass"
.. ..- attr(*, "order")= int 1
.. ..- attr(*, "intercept")= int 1
.. ..- attr(*, "response")= int 1
.. ..- attr(*, ".Environment")=<environment: R_GlobalEnv>
.. ..- attr(*, "predvars")= language list(Matings, Body.Mass)
.. ..- attr(*, "dataClasses")= Named chr [1:2] "numeric" "numeric"
.. .. ..- attr(*, "names")= chr [1:2] "Matings" "Body.Mass"
$ model :'data.frame': 11 obs. of 2 variables:
..$ Matings : num [1:11] 0 2 4 4 2 6 3 3 5 8 ...
..$ Body.Mass: num [1:11] 29 29 29 32 32 35 36 38 38 38 ...
..- attr(*, "terms")=Classes 'terms', 'formula' language Matings ~ Body.Mass
.. .. ..- attr(*, "variables")= language list(Matings, Body.Mass)
.. .. ..- attr(*, "factors")= int [1:2, 1] 0 1
.. .. .. ..- attr(*, "dimnames")=List of 2
.. .. .. .. ..$ : chr [1:2] "Matings" "Body.Mass"
.. .. .. .. ..$ : chr "Body.Mass"
.. .. ..- attr(*, "term.labels")= chr "Body.Mass"
.. .. ..- attr(*, "order")= int 1
.. .. ..- attr(*, "intercept")= int 1
.. .. ..- attr(*, "response")= int 1
.. .. ..- attr(*, ".Environment")=<environment: R_GlobalEnv>
.. .. ..- attr(*, "predvars")= language list(Matings, Body.Mass)
.. .. ..- attr(*, "dataClasses")= Named chr [1:2] "numeric" "numeric"
.. .. .. ..- attr(*, "names")= chr [1:2] "Matings" "Body.Mass"
- attr(*, "class")= chr "lm"
Yikes! A lot of the output is simply identifying how R handled our data.frame and applied the lm() function.
Note 4: The “how” refers to the particular algorithms used by R. For example, qraux, pivot, and tol refer to arguments used in the QR decomposition of the matrix (derived from our data.frame) used to solve our linear least squares problem.
However, it’s from this command we learn what is available to extract in our object. For example, what were the actual fitted values (, the predicted Y values) from our linear equation? I marked the relevant str() output above in yellow. We call these from the object with the R code
RegModel.1$fitted.values
and R returns
       1        2        3        4        5        6        7        8        9       10       11
2.031780 2.031780 2.031780 3.118644 3.118644 4.205508 4.567797 5.292373 5.292373 5.292373 6.016949
Here’s another look at an object, str(myAOV.full), and how to extract useful values.
Output from R
Classes 'anova' and 'data.frame': 2 obs. of 5 variables:
$ Df : int 1 9
$ Sum Sq : num 22.5 28.4
$ Mean Sq: num 22.53 3.15
$ F value: num 7.14 NA
$ Pr(>F) : num 0.0255 NA
- attr(*, "heading")= chr [1:2] "Analysis of Variance Table\n" "Response: Matings"
Extract the sum of squares: type the object name then $ Sum Sq at the R prompt.
myAOV.full $"Sum Sq"
Output from R
[1] 22.52773 28.38136
Get the residual sum of squares
SSE.myAOV.full <- myAOV.full $"Sum Sq"[2]; SSE.myAOV.full
Output from R
[1] 22.52773
Get the regression sum of squares
SSR.myAOV.full <- myAOV.full $"Sum Sq"[1]; SSR.myAOV.full
Output from R
[1] 50.90909
Now, get the total sums of squares for the model

ssTotal.myAOV.full <- SSE.myAOV.full + SSR.myAOV.full; ssTotal.myAOV.full
Calculate the coefficient of determination
myR_2 <- 1 - (SSE.myAOV.full/(ssTotal.myAOV.full)); myR_2
Output from R
[1] 0.4425091
Which matches what we got before, as it should.
Regression equations may be useful to predict new observations
True. However, you should avoid making estimates beyond the range of the X – values that were used to calculate the best fit regression equation! Why? The answer has to do with the shape of the confidence interval around the regression line.
I’ve drawn an exaggerated confidence interval (CI), for a regression line between an X and a Y variable. Note that the CI is narrow in the middle, but wider at the end. Thus, we have more confidence in predicting new Y values for data that fall within the original data because this is the region where we are most confident.
Calculating the CI for the linear model follows from CI calculations for other estimates. It is a simple concept — both the intercept and slope were estimated with error, so we combine these into a way to generalize our confidence in the regression model as a whole given the error in slope and intercept estimation.
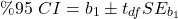
The calculation of confidence interval for the linear regression involves the standard error of the residuals, the sample size, and expressions relating the standard deviation of the predictor variable X — we use the t distribution.
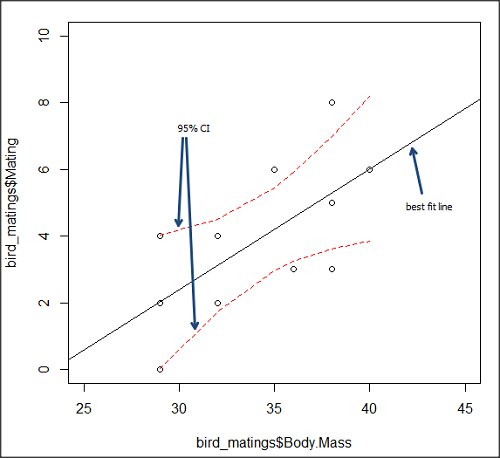
Figure 5. 95% confidence interval about the best fit line.
How I got this graph
plot(bird_matings$Body.Mass,bird_matings$Mating,xlim=c(25,45),ylim=c(0,10))
mylm <- lm(bird_matings$Mating~bird_matings$Body.Mass)
predict(mylm, interval = c("confidence"))
abline(mylm, col = "black")
x<-bird_matings$Body.Mass
lines(x, prd[,2], col= "red", lty=2)
lines(x, prd[,3], col= "red", lty=2)
Nothing wrong with my code, but getting all of this to work in R might best be accomplished by adding another package, a plug-in for Rcmdr called RcmdrPlugin.HH. HH refers to “Heiberger and Holland,” and provides software support for their textbook Statistical Analysis and Data Display, 2nd edition.
Regression through the origin
A regression through the origin in OLS is appropriate when theory dictates that the response must be zero when the predictor is zero, that is, the intercept is known to be exactly 0. In population genetics, for example, if you model pairwise genetic distance as a function of some measure of separation, (eg, time or geographic distance), and the definition of the metric ensures that identical individuals have zero distance, then forcing the regression through the origin can be justified. Doing so reduces parameter estimation to the slope alone and can improve efficiency when the assumption is correct. However, if the true relationship includes a nonzero intercept, constraining it to zero biases the slope.
This choice also affects the coefficient of determination (R²): in a no-intercept model, R² is computed relative to zero rather than the mean of Y, so it is not directly comparable to the standard R² from a model with an intercept and can even appear artificially higher or lower. If the origin constraint is correct, the no-intercept model may show a better (more meaningful) fit; if not, the apparent R² can be misleading despite biased estimates.
R code for regression without the Y-intercept:
noOrigin.model <- lm(formula = Matings ~ 0 + Body.Mass, data = bird.matings)
summary(noOrigin.model)
And the R output:
Call:
lm(formula = Matings ~ 0 + Body.Mass, data = bird.matings)

Residuals:
    Min      1Q  Median      3Q     Max
-3.4112 -1.4406  0.2359  0.9418  3.5301

Coefficients:
          Estimate Std. Error t value Pr(>|t|)
Body.Mass  0.11763    0.01726   6.816 4.65e-05 ***
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1

Residual standard error: 1.97 on 10 degrees of freedom
Multiple R-squared:  0.8229,	Adjusted R-squared:  0.8052
F-statistic: 46.45 on 1 and 10 DF,  p-value: 4.65e-05
Interpretation and comparison between model with and without fit through the origin.
Without an intercept (regression through the origin), the model estimates a slope of 0.1176 (SE = 0.0173, t = 6.82, p = 4.65×10⁻⁵), indicating a strong, statistically significant positive association between Body Mass and the response. Because the intercept is constrained to zero, this slope is effectively forced to account for all variation in Y, which often inflates its magnitude of significance and can bias the estimate if the true relationship does not pass through the origin.
When the intercept was included, the slope increased to 0.3623 (SE = 0.1355, t = 2.67, p = 0.0255), still statistically significant but less so, while the intercept is estimated at –8.47 (SE = 4.66, p = 0.103), which is not significantly different from zero at conventional levels. The change in slope (from 0.12 to 0.36) shows that allowing a nonzero intercept alters the fitted relationship substantially, suggesting that the origin constraint may not be appropriate in this case. Even though the intercept is not statistically significant, its inclusion redistributes variance between intercept and slope, yielding a more reliable slope estimate and a standard R² that is comparable across models, unlike the no-intercept case.
The negative Y-intercept, while statistically justifiable, is also biologically unrealistic, implying a negative number of matings. The statistical justification is simply that the model is used to predict mating success for organisms in the range of body size included in the data set used to make the model — the negative Y-intercept than is interpreted that we are trying to extend the model beyond its range.
In our example with the birds, a biological justification for a non intercept model can be made. For example, mating success is positively associated with body size; therefore, an organism with a hypothetical body size of zero would logically have zero chance of mating success. That said, even when biology suggests the relationship should pass through the origin, it may still be useful to fit a model with an intercept to test that assumption rather than impose it.
Measurement error, in the case of our birds example, chiefly if observed count of matings differs from the true, actual number of matings that occurred, or in a student employing genetic distance, then a number of errors may occur, including sequencing artifacts, alignment bias, or the way genetic distance is computed (eg, corrections for multiple substitutions, cf discussions in Felsenstein 2003, see Legendre and Desdevises 2009 for justifications for through the origin and phylogenetic independent contrasts). As well documented in standard texts on regression and linear models (eg, Introduction to Linear Regression Analysis, by Montgomery et al 2021; An Introduction to Generalized Linear Models, by Dobson and Barnett 2018), measurement error can introduce a small offset, so the estimated intercept serves as a diagnostic for systematic bias. If the intercept is close to zero and not significant, that provides empirical support for the origin constraint; if it is meaningfully different from zero, forcing the regression through the origin would bias the slope and distort inference. Additionally, including the intercept yields a standard R² and residual structure that are comparable across models, helping assess overall model fit before deciding whether the biologically motivated constraint is justified.
Assumptions of OLS, an introduction
We will cover assumptions of Ordinary Least Squares in detail in 17.8, Assumptions and model diagnostics for Simple Linear Regression. For now, briefly, the assumptions for OLS regression include:
- Linear model is appropriate: the data are well described (fit) by a linear model
- Independent values of Y and equal variances. Although there can be more than one Y for any value of X, the Y’s cannot be related to each other (that’s what we mean by independent). Since we allow for multiple Y’s for each X, then we assume that the variances of the range of Ys are equal for each X value (this is similar to our ANOVA assumptions for equal variance by groups).
- Normality. For each X value there is a normal distribution of Ys (think of doing the experiment over and over)
- Error (residuals) are normally distributed with a mean of zero.
Additionally, we assume that measurement of X is done without error (the equivalent, but less restrictive practical application of this assumption is that the error in X is at least negligible compared to the measurements in the dependent variable). Multiple regression makes one more assumption, about the relationship between the predictor variables (the X variables). The assumption is that there is no multicolinearity: the X variables are not related or associated to each other.
In some sense the first assumption is obvious if not trivial — of course a “line” needs to fit the data so why not plow ahead with the OLS regression method, which has desirable statistical properties and let the estimation of slopes, intercept and fit statistics guide us? One of the really good things about statistics is that you can readily test your intuition about a particular method using data simulated to meet, or not to meet, assumptions.
What about assumptions and BLUE? Interestingly, OLS coefficient estimates remain unbiased even if the errors are not normal, as long as other assumptions (like a mean of zero, no correlation, and constant variance) hold. However, the OLS estimators are no longer the “best” linear unbiased estimators (BLUE) because the efficiency property is lost. As we have discussed before, the main consequence is the effects on statistical inference. Without normality, standard errors, t-statistics, confidence intervals, and p-values will be unreliable.
Note 5: The efficiency property means the estimator has the smallest variance among all linear, unbiased estimators. And “unbiased,” again, means the estimator’s expected value is equal to the true parameter value.
Coming up with datasets like these can be tricky for beginners. Thankfully, others have stepped in and provide tools useful for data simulations which greatly facilitate the kinds of testing of assumptions — and more importantly, how assumptions influence our conclusions — statisticians greatly encourage us all to do (see Chatterjee and Firat 2007).
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- Predict new values for number of matings for male birds of 20g and 60g.
- Anscombe’s quartet (Anscombe 1973) is a famous example of this approach and the fictitious data can be used to illustrate the fallacy of relying solely on fit statistics and coefficient estimates.
Here are the data (modified from Anscombe 1973, p. 19) — I leave it to you to discover the message by using linear regression on Anscombe’s data set. Hint: play naïve and generate the appropriate descriptive statistics, make scatterplots for each X, Y set, then run regression statistics, first on each of the X, Y pairs (there were four sets of X, Y pairs).
Anscombe’s quartet
| X | Y1 | Y2 | Y3 | Y4 |
|---|---|---|---|---|
| 10 | 8.04 | 9.14 | 7.46 | 6.58 |
| 8 | 6.95 | 8.14 | 6.77 | 5.76 |
| 13 | 7.58 | 8.74 | 12.74 | 7.71 |
| 9 | 8.81 | 8.77 | 7.11 | 8.84 |
| 11 | 8.33 | 9.26 | 7.81 | 8.47 |
| 14 | 9.96 | 8.10 | 8.84 | 7.04 |
| 6 | 7.24 | 6.13 | 6.08 | 5.25 |
| 4 | 4.26 | 3.10 | 5.39 | 12.50 |
| 12 | 10.84 | 9.13 | 8.15 | 5.56 |
| 7 | 4.82 | 7.26 | 6.42 | 7.91 |
| 5 | 5.68 | 4.74 | 5.73 | 6.89 |
| Mean (±SD) | 7.50 (2.032) | 7.50 (2.032) | 7.50 (2.032) | 7.50 (2.032) |
Quiz Chapter 17.1
Ordinary Least Squares
Chapter 17 contents
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)
17 – Linear Regression
Introduction
Regression is a toolkit for developing models of cause and effect between one ratio scale data type dependent response variables, and one (simple linear regression) or more or more (multiple linear regression) ratio scale data type independent predictor variables. By convention the dependent variable(s) is denoted by Y, the independent variable(s) represented by X1, X2,  Xn for n independent variables. Like ANOVA, linear regression is simply a special case of the general linear model, first introduced in Chapter 12.7.
Components of a statistical model
Regression statistical methods return model estimates of the intercept and slope coefficients, plus statistics of regression fit (eg, R2, aka “R-squared,” the coefficient of determination).
Chapter 17.1 – 17.9 cover the simple linear model
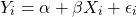
Chapter 18.1 – 18.5 cover the multiple regression linear model
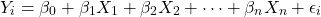
where α or β0 represent the Y-intercept and β or β1, β2, … βn represent the regression slopes.
Regression and correlation test linear hypotheses
We state that the relationship between two variables is linear (the alternative hypothesis) or it is not (the null hypothesis). The difference? Correlation is a test of linear association (are variables correlated, we ask?), imply possible causation, but are not sufficient evidence for causation: we do not imply that one variable causes another to vary, even if the correlation between the two variables is large and positive, for example. Correlations are used in statistics on data sets not collected from explicit experimental designs incorporated to test specific hypotheses of cause and effect.
Linear regression, however, is to cause and effect as correlation is to association. With regression and ANOVA, we are indeed making a case for a particular understanding of the cause of variation in a response variable: modeling cause and effect is the goal. Regression, ANOVA, and other general linear models are designed to permit the statistician to control for the effects of confounding variables provided the causal variables themselves are uncorrelated.
When to use correlation and when to apply linear regression to data set? For two ratio scale variables, one can always apply either approach. Correlation is always appropriate if both variables are measured in the course of the study whereas a regression modeling approach would be implied where one variable was the result of manipulation by the researcher.
Assumptions of linear regression
The key assumption in linear regression is that a straight line indeed is the best fit of the relationship between dependent and independent variables. The additional assumptions of parametric tests (Chapter 13) also hold. In Chapter 18 we conclude with an extension of regression from one to many predictor variables and the special and important topic of correlated predictor variables or multicollinearity.
Build a statistical model, make predictions
In our exploration of linear regression we begin with simple linear regression, also called ordinary least squares regression, starting with one predictor variable. Practical aspects of model diagnostics are presented. Regression may be used to describe or to provide a predictive statistical framework. In Chapter 18 we conclude with an extension of regression from one to many predictor variables. We conclude with a discussion of model selection. Throughout, use of Rcmdr and R have multiple ways to analyze linear regression models are presented; we will continue to emphasize the general linear model approach, but note that use of linear model in Rcmdr provides a number of default features that are conveniently available.
Questions
1. Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
Suggested homework
Homework 11: Simple linear regression.
Quiz
In addition to the quiz on this page, a total of 81 questions among the several subchapters, a mix of true or false and multiple choice question format.
Quiz Chapter 17
Linear Regression
References
Linear regression is a huge topic; references I include are among my favorite on the subject, but are only a small and incomplete sampling. For simplicity, I merged references for Chapter 17 and Chapter 18 into one page at References and suggested readings (Ch17 & 18)
Chapter 17 contains
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)