14.7 – Rcmdr Multiway ANOVA
Introduction
We have been talking about the two-way randomized, balanced, replicated design. Here, we take you step by step through use of R to conduct the multiway ANOVA.
R code: Multiway ANOVA
Rcmdr: Statistics → Means → Multiway ANOVA… we will review this as Option 1
or
Rcmdr: Statistics → Fit Models → Linear model… we will review this as Option 2
In either case, as a reminder, your data set must be stacked worksheet, like the data in this worksheet
Table 1. Data set, example.14.7†
| Diet | Population | Response |
| A | 1 | 4 |
| A | 1 | 6 |
| A | 1 | 5 |
| A | 2 | 5 |
| A | 2 | 8 |
| A | 2 | 9 |
| B | 1 | 12 |
| B | 1 | 15 |
| B | 1 | 11 |
| B | 2 | 5 |
| B | 2 | 7 |
| B | 2 | 8 |
Option 1
Your first option is to use the ANOVA menus via “Means.” This is a perfectly good way to handle a standard two-way, fully-crossed, fixed effects model. However, other designs will not run with this command and R will return a report of errors for ANOVA models that do not conform to the replicated, balanced, crossed design.
Rcmdr: Statistics → Means → Multiway Analysis of variance …
Factors: highlight “Diet” AND “Population”
Response variable: pick one (in this window, all we see is “Response”)
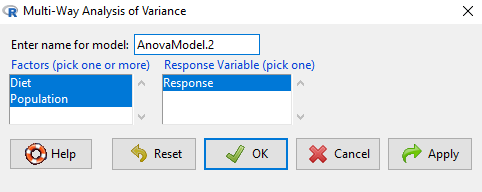
Figure 1. Screenshot Rcmdr multi-way ANOVA.
†Note 1: Don’t forget to convert numeric Population to factor. Assuming Population is part of a data.frame called example.14.7, then example.14.7$Population <- factor(example.14.7$Population).
Interpret the output
AnovaModel.2 <- (lm(Response ~ Diet*Population, data=example.14.7))

Anova(AnovaModel.2)

Anova Table (Type II tests)
Response: Response
                  Sum Sq    Df    F value      Pr(>F)
Diet              36.750     1    12.2500    0.008079 **
Population        10.083     1     3.3611    0.104104
Diet:Population   52.083     1    17.3611    0.003136 **
Residuals         24.000     8
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
tapply(example.14.7 Response, list(Diet=example.14.7 Diet,
+ Population=example.14.7 Population), mean, na.rm=TRUE) # means
Population
Diet 1 2
A 5.00000 7.333333
B 12.66667 6.666667

tapply(example.14.7 Response, list(Diet=example.14.7 Diet,
+ Population=example.14.7 Population), sd, na.rm=TRUE) # std. deviations
Population
Diet 1 2
A 1.000000 2.081666
B 2.081666 1.527525

tapply(example.14.7 Response, list(Diet=example.14.71 Diet,
+ Population=example.14.7 Population), function(x) sum(!is.na(x))) # counts
Population
Diet 1 2
A 3 3
B 3 3
End R output.
Note 2: What is the “Type II tests”? When you fit a model with categorical predictors using lm() or aov(), you test hypothesis for each effect (main effects and interactions). These tests differ depending on how the model partitions the variance among predictors. See Note 2 in Chapter 12.7 for description of Type I, Type II, and Type III sums of squares.
Summary of multi-way ANOVA command
The multi-way ANOVA command returns our ANOVA table plus the adjusted means, along with standard deviations and number of observations (counts). The adjusted means would then be good to put into a chart to present group comparisons following adjustments from the effects of levels within groups.
Rcmdr: Models → Graphs → Predictor effect plots …
Here’s the chart (hint: 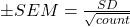 )
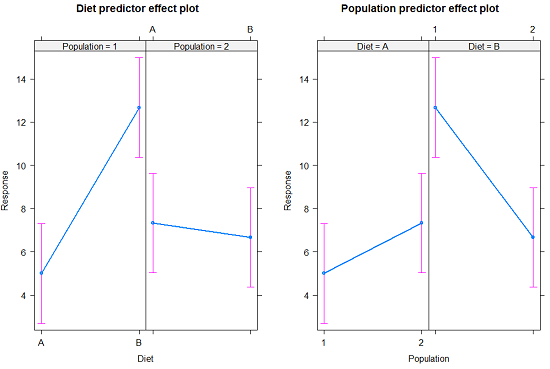
Figure 2. Predictor effect plots, Diet and Population on Response variable.
Option 2
A more general approach is to use the General linear model. This approach can handle the standard 2-way fixed effects ANOVA (above), but any other model as well. The model is Response ~ Diet*Population.
Rcmdr: Statistics → Fit Models → Linear model…
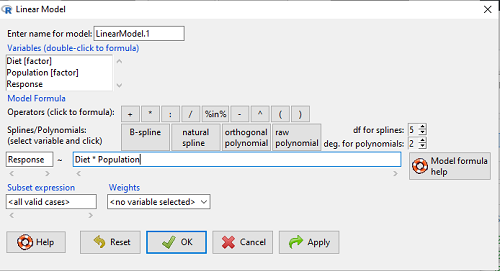
Figure 3. Screenshot Rcmdr linear model menu.
Interpret the output
LinearModel.1 <- lm(Response ~ Diet * Population, data=example.14.7)

summary(LinearModel.1)

Call:
lm(formula = Response ~ Diet * Population, data = example.14.7)

Residuals:
Min 1Q Median 3Q Max
-2.3333 -1.1667 0.1667 1.0833 2.3333

Coefficients:
                        Estimate    Std. Error ..t value .  Pr(>|t|)
(Intercept) .              5.000         1.000 .   5.000    .0.00105 **
Diet[T.B] .                7.667       ..1.414 .   5.421    .0.00063 ***
Population[T.2]           .2.333       ..1.414 .   1.650    .0.13757
Diet[T.B]:Population[T.2] -8.333       ..2.000    -4.167    .0.00314 **
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 1.732 on 8 degrees of freedom
Multiple R-squared: 0.8047, Adjusted R-squared: 0.7315
F-statistic: 10.99 on 3 and 8 DF, p-value: 0.003285
End R output
Lots to sort through, so let’s begin with what is in common between the two approaches, the Multi-way ANOVA command versus the linear model command.
Compare R output from ANOVA and linear model
As a direct output, the linear model option does not provide an ANOVA summary table. Instead of our ANOVA table the linear model returns estimates of coefficients along with t-test results for each coefficient of the model from the lm() command output
Recall that we can get ANOVA tables through the following R commands via Rcmdr.
Rcmdr: Models → Hypothesis tests → ANOVA Table.
Let’s do so for this linear model (accept the default for type of tests = “Type II”).
And the output from lm() stored in the object LinearModel.1 is
Anova(LinearModel.1, type="II")
Anova Table (Type II tests)

Response: Response
                Sum Sq Df F value   Pr(>F)
Diet            36.750  1 12.2500 0.008079 **
Population      10.083  1  3.3611 0.104104
Diet:Population 52.083  1 17.3611 0.003136 **
Residuals       24.000  8
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
End R output
Now, we’re in business, and, using the lm() function, we have the estimates for each model coefficient plus our ANOVA table.
Same answer! Of course. Which to choose, Option 1 or Option 2? Use the lm() options; more flexible, covers more designs than the multiway ANOVA which is strictly for the crossed fully replicated design.
Note 3: Rcmdr uses Anova(), not anova(). anova() is a generic function, part of the base statistics package, and it returns an ANOVA table. Anova() is not a wrapper to anova(), it is a different function, part of the car package. It uses different default methods and different types of sums of squares: Type-II or Type-III analysis-of-variance tables for model objects produced by lm(), glm(), etc. See Note 2 in Chapter 12.7 for description of Type I, Type II, and Type III sums of squares.
Questions
- Write out the two-way model described for the data in Table 1.
- Write the null hypotheses and provide a summary of the statistical significance of the model.
Quiz Chapter 14.7
Rcmdr Multiway ANOVA
Chapter 14 contents
12.7 – Many tests one model
Introduction
In our introduction to parametric tests we so far have covered one and two sample t-tests and now the multiple sample or one-way analysis of variance (ANOVA). In subsequent sections we will cover additional tests, each with their own name. It is time to let you in on a little secret. All of these tests, t-tests, ANOVA, and linear and multiple regression we will work on later in the book belong to one family of statistical models. That model is called the general Linear Model (LM), not to be confused with the Generalized Linear Model (GLM) (Burton et al 1998; Guisan et al 2002). This greatly simplifies our approach to learning how to implement statistical tests in R (or other statistical programs) — you only need to learn one approach: the general Linear Model (LM) function lm().
Brief overview of linear models
With the inventions of correlation, linear regression, t-tests, and analysis of variance in the period between 1890 and 1920, subsequent work led to the realization that these tests (and many others!) were special cases of a general model, the general linear model, or LM. The LM itself is a special case of the generalized linear model, or GLM; among the differences between LM and GLM, in LM, the dependent variable is ratio scale and errors in the response (dependent) variable(s) are assumed to come from a Gaussian (normal) distribution. In contrast, for GLM, the response variable may be categorical or continuous, and error distributions other than normal (Gaussian), may be applied. The GLM user must specify both the error distribution family (eg, Gaussian) and the link function, which specifies the relationship among the response and predictor variables. While we will use the GLM functions when we attempt to model growth functions and calculate EC50 in dose-response problems, we will not cover GLM this semester.
The general Linear Model, LM
In matrix form, the LM can be written as

where  is a matrix of response variables predicted by independent variables contained in matrix
 and weighted by linear coefficients in the vector b. Basically, all of the predictor variables are combined to produce a single linear predictor
 . By adding an error component we have the complete linear model.

In the linear model, the error distribution is assumed to be normally distributed, or “Gaussian.”
R code
The bad news is that LM in R (and in any statistical package, actually) is a fairly involved set of commands; the good news is that once you understand how to use this command, and can work with the Options, you will be able to conduct virtually all of the tests we will use this semester, from two-sample t-tests to multiple linear regression. In the end, all you need is the one Rcmdr command to perform all of these tests.
We begin with a data set, ohia.ch12. Scroll down this page or click here to get the R code.
I found a nice report on a common garden experiment with o`hia (Corn and Hiesey 1973). O`hia (Metrosideros polymorpha) is an endemic, but wide-spread tree in the Hawaiian islands (Fig 1). O`hia exhibits pronounced intraspecific variation: individuals differ from each other. O`hia grows over wide range of environments, from low elevations along the ocean right up the sides of the volcanoes, and takes on many different growth forms, from shrubs to trees. Substantial areas of o`hia trees on the Big Island are dying, attributed to two exotic fungal species of the genus Ceratocystis (Asner et al., 2018).
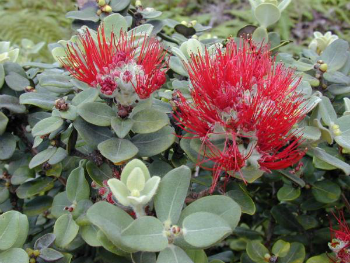
Figure 1. O’hia, Metrosideros polymorpha. Public domain image from Wikipedia.
The Biology. Individuals from distinct populations may differ because the populations differ genetically, or because the environments differ, or, and this is more realistic, both. Phenotypic plasticity is the ability of one genotype to produce more than one phenotype when exposed to different environments. Environmental differences are inevitable when populations are from different geographic areas. Thus, in population comparisons, genetic and environmental differences are confounded. A common garden experiment is a crucial genetic experiment to separate variation in phenotypes, P, among populations into causal genetic or environmental components.
If you recall from your genetics course, 
where G stands for genetic (alleles) differences among individuals and E stands for environmental differences among individuals. In brief, the common garden experiment begins with individuals from the different populations are brought to the same location to control environmental differences. If the individuals sampled from the populations continue to differ despite the common environment, then the original differences between the populations must have a genetic basis, although the actual genetic scenario may be complicated (the short answer is that if “genotype by environment interaction exists, then results from a common garden experiment cannot be generalized back to the natural populations/locations — this will make more sense when we talk about two-way ANOVA). For more about common garden experiments, see de Villemereuil et al (2016). Nuismer and Gandon (2008) discuss statistical aspects of the common garden approach to studying local adaptation of populations and the more powerful “reciprocal translocation” experimental design.
Managing data for linear models
First, your data must be stacked in the worksheet. That means one column is for group labels (independent variable), the other column is for the response (dependent) variable.
If you have not already downloaded the data set, ohia.ch12, do so now. Scroll down this page or click here to get the R code.
Confirm that the worksheet is stacked. If it is not, then you would rearrange your data set using Rcmdr: Data → Active data set → Stack variables in data set…
The data set contains one factor, “Site” with three levels (M-1, 2, 3). M stands for Maui, and collection sites were noted in Figure 2 of Corn and Hiesey (1973). Once the dataset is in Rcmdr, click on View to see the data (Fig 2). There are two response variables, Height (shown in red below) and Width (shown in blue below).
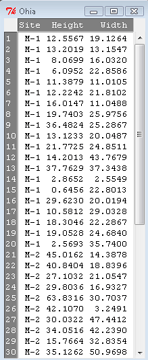
Figure 2. The o`hia dataset as viewed in R Commander.
The data are from Table 5 of Corn and Hiesey 1973. (I simulated data based on their mean/SD reported in Table 5). This was a very cool experiment: they collected o`hia seeds from three elevations on Maui, then grew the seeds in a common garden in Honolulu. Thus, the researchers controlled the environment; what varied, then were the genotypes.
As always, you should look at the data. Box plots are good to compare central tendency (Fig 3).
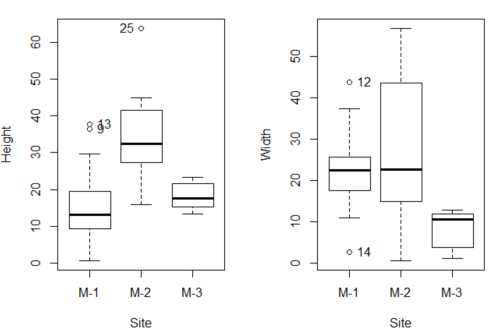
Figure 3. Box plots of growth responses of o`hia seedlings collected from three Maui sites, M-1 (elevation 750 ft), M-2 (elevation 1100 ft), and M-3 (elevation 6600 ft). Data adapted from Table 5 of Corn and Hiersey 1973.
R code to make Figure 4 plots
par(mfrow=c(1,2))
Boxplot(Height ~ Site, data = ohia, id = list(method = "y"))
Boxplot(Width ~ Site, data = ohia, id = list(method = "y"))
This dataset would typically be described as a one-way ANOVA problem. There was one treatment variable (population source) with three levels (M-1, M-2, M-3). From Rcmdr we select the one-way ANOVA: Statistics → Means → One-way ANOVA… and after selecting the Groups (from the Site variable) and the Response variable (eg, Height), we have
AnovaModel.1 <- aov(Height ~ Site, data = ohia.ch12)
summary(AnovaModel.1)
           Df Sum Sq   Mean Sq  F value          Pr(>F)
Site        2   4070    2034.8    22.63 0.000000131 ***
Residuals  47   4227      89.9
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Let us proceed to test the null hypothesis (what was it???) using instead the lm() function. Four steps in all.
Step 1. Rcmdr: Statistics → Fit models → Linear model … (Fig 4).
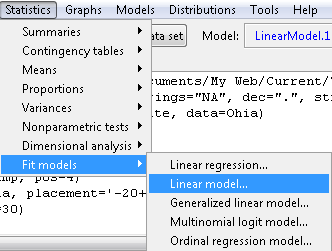
Figure 4. R Commander, select to fit a Linear model.
Step 2. The pop up menu below (Fig 5) follows.
First, What is our response (dependent) variable? What is our predictor (independent) variable? We then input our model. In this case, with only the one predictor variable, Sites, our model formula is simple to enter (Fig 5): Height ~ Site.
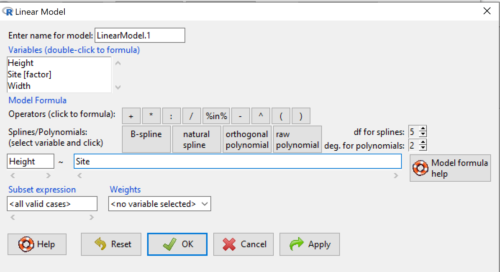
Figure 5. Input linear model formula, Height ~ Site.
Step 3. Click OK to carry out the command.
Here is the R output and the statistical results from the application of the linear model.
LinearModel.1 <- lm(Height ~ Site, data=ohia.ch12)
summary(LinearModel.1)

Call:
lm(formula = Height ~ Site, data = ohia.ch12)

Residuals:
    Min     1Q   Median     3Q     Max
-18.808 -4.761   -1.755  4.758  29.257

Coefficients:
             Estimate  Std. Error  t value      Pr(>|t|)
(Intercept)    15.314       2.121    7.222 0.00000000377 ***
Site[T.M-2]    19.261       2.999    6.423 0.00000006153 ***
Site[T.M-3]     2.924       3.673    0.796          0.43
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Residual standard error: 9.483 on 47 degrees of freedom
Multiple R-squared:  0.4905,	Adjusted R-squared:  0.4688
F-statistic: 22.63 on 2 and 47 DF,  p-value: 0.0000001311
End R output
The linear model has produced a series of estimates of coefficients for the linear model, statistical tests of the significance of each component of the model, and the coefficient of determination, R2, which is a descriptive statistic of how well model fits the data. Instead of our single factor variable for Source Population like in ANOVA we have a series of what are called dummy variables or contrasts between the populations. Thus, there is a coefficient for the difference between M-1 and M-2. “Site[T.M-2]” in the output, between M-1 and M-3, and between M-2 and M-3.
Note 1: Brief description of linear model output; these will be discussed fuller in Chapter 17 and Chapter 18. The residual standard error is a measure of how well a model fits the data. The Adjusted R-squared is calculated by dividing the residual mean square error by the total mean square error. The result is then subtracted from 1.
It also produced our first statistic that assesses how well the model fits the data called the coefficient of determination, R2. An of of 1.0 would indicate that all variation in the data set can be explained by the predictor variable(s) in the model with no residual error remaining. Our value of 49% indicates that nearly 50% of the variation in height of the seedlings grown under common environments are due to the source population (= genetics).
Step 4. But we are not quite there — we want the traditional ANOVA results (recall the ANOVA table).
To get the ANOVA Table we have to ask Rcmdr (and therefore R) to give us this. Select
Rcmdr: Models → Hypothesis tests → ANOVA table … (Fig 6).
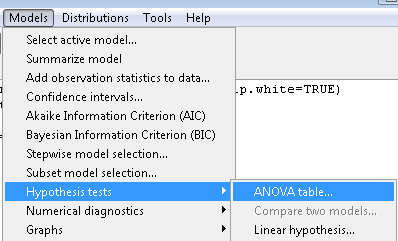
Figure 6. To retrieve an ANOVA table, select Models, Hypothesis tests, then ANOVA table…
Here’s the type of tests for the ANOVA table, select the default (Fig 7).
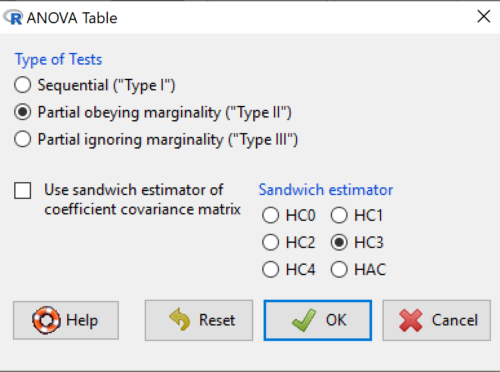
Figure 7. Options for types of tests.
Now, in the future when we work with more complicated experimental designs, we will also need to tell R how to conduct the test. For now, we will accept the default Type II type of test and ignore sandwich estimators. You should confirm that for a one-way ANOVA, Type I and Type II choices give you the same results.
The reason they do is because there is only one factor — when there are more than one factors, and if one or both of the factors are random effects, then Type I, II, and III will give you different answers. We will discuss this more as needed, but see the note below about default choices.
Note 2: Marginal or partial effects are slopes (or first derivatives): they quantify the change in one variable given change in one or more independent variables. Type I tests are sequential: sums of squares are calculated in the order the predictor variables are entered into the model. Type II tests the sums of squares are calculated after adjusting for some of the variables in the model. Type III, every sum of square calculation is adjusted for all other variables in the model. Sandwich estimator refers to algorithms for calculating the structure of errors or residuals remaining after the predictor variables are fitted to the data. The assumption for ordinary least square estimation (See Chapter 17) is that errors across the predictors are equal, ie, equal variances assumption. HC refers to “heteroscedasticity consistent” (Hayes and Chai 2007), which infers fitting of a model does not assume equal error variance across all observations.
By default, Rcmdr makes Type II. In most of the situations we will find ourselves this semester, this is the correct choice.
Below is the output from the ANOVA table request. Confirm that the information is identical to the output from the call to aov() function.
Anova(LinearModel.1, type = "II")
Anova Table (Type II tests)
Response: Height
          Sum Sq  Df   F value        Pr(>F)
Site      4069.7   2    22.626  0.0000001311 ***
Residuals 4226.9  47
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
And the other stuff we got from the linear model command? Ignore for now but make note that this is a hint that regression and ANOVA are special cases of the same model, the linear model.
We do have some more work to do with ANOVA, but this is a good start.
Why use the linear model approach?
Chief among the reasons to use the lm() approach is to emphasize that a model approach is in use. One purpose of developing a model is to provide a formula to predict new values. Prediction from linear models is more fully developed in Chapter 17 and Chapter 18, but for now, we introduce the predict() function with our O`hia example.
myModel <- predict(LinearModel.1, interval = "confidence")
head(myModel, 3)    #print out first 3 rows
#Add the output to the data set
ohiaPred <- data.frame(ohia,myModel)
with(ohiaPred, tapply(fit, list(Site), mean, na.rm = TRUE))   #print out predicted values for the three sites
Output from R
myModel <- predict(LinearModel.1, interval = "confidence")
head(myModel, 3)
       fit      lwr      upr
1 15.31374 11.04775 19.57974
2 15.31374 11.04775 19.57974
3 15.31374 11.04775 19.57974
with(myModel, tapply(fit, list(Site), mean, na.rm = TRUE))
     M-1      M-2      M-3
15.31374 34.57474 18.23796
Questions
1. Revisit ANOVA problems in homework and questions from early parts of this chapter and apply lm() followed by Hypothesis testing (Rcmdr: Models → Hypothesis tests → ANOVA table) approach instead of one-way ANOVA command. Compare results using lm() to results from One-way ANOVA and other ANOVA problems.
Quiz Chapter 12.7
Many tests one model
Data set and R code used in this page
Corn and Hiesey (1973)
| Site | Height | Width |
|---|---|---|
| M-1 | 12.5567 | 19.1264 |
| M-1 | 13.2019 | 13.1547 |
| M-1 | 8.0699 | 16.032 |
| M-1 | 6.0952 | 22.8586 |
| M-1 | 11.3879 | 11.0105 |
| M-1 | 12.2242 | 21.8102 |
| M-1 | 16.0147 | 11.0488 |
| M-1 | 19.7403 | 25.9756 |
| M-1 | 36.4824 | 25.2867 |
| M-1 | 13.1233 | 20.0487 |
| M-1 | 21.7725 | 24.8511 |
| M-1 | 14.2013 | 43.7679 |
| M-1 | 37.7629 | 37.3438 |
| M-1 | 2.8652 | 2.5549 |
| M-1 | 0.6456 | 22.8013 |
| M-1 | 29.623 | 20.0194 |
| M-1 | 10.5812 | 29.0328 |
| M-1 | 18.3046 | 22.2867 |
| M-1 | 19.0528 | 24.684 |
| M-1 | 2.5693 | 35.74 |
| M-2 | 45.0162 | 14.3878 |
| M-2 | 40.8404 | 18.8396 |
| M-2 | 27.1032 | 21.0547 |
| M-2 | 29.8036 | 16.9327 |
| M-2 | 63.8316 | 30.7037 |
| M-2 | 42.107 | 3.2491 |
| M-2 | 30.0322 | 47.4412 |
| M-2 | 34.0516 | 42.239 |
| M-2 | 15.7664 | 32.8354 |
| M-2 | 35.1262 | 50.9698 |
| M-2 | 43.6988 | 19.3897 |
| M-2 | 26.7585 | 13.8168 |
| M-2 | 36.7895 | 0.5817 |
| M-2 | 30.9458 | 53.7757 |
| M-2 | 26.8465 | 15.4137 |
| M-2 | 40.3883 | 9.2161 |
| M-2 | 30.6555 | 56.8456 |
| M-2 | 19.9736 | 44.9411 |
| M-2 | 27.676 | 36.8543 |
| M-2 | 44.084 | 24.3396 |
| M-3 | 15.2646 | 11.4999 |
| M-3 | 19.6745 | 9.7757 |
| M-3 | 23.275 | 12.7825 |
| M-3 | 16.1161 | 2.4065 |
| M-3 | 16.8393 | 1.1253 |
| M-3 | 23.107 | 3.7349 |
| M-3 | 21.5322 | 6.9725 |
| M-3 | 13.4191 | 12.2867 |
| M-3 | 14.7273 | 11.4841 |
| M-3 | 18.4245 | 11.9078 |
Chapter 12 contents
10.3 – Paired t-test
Introduction
Good experiments include controls. Interested in a new treatment for weight loss? Define a control group to compare the weight loss by a group using the new product. In many cases, the best control is the individual.
Consider now a basic experimental design, the randomized crossover trial (Fig 1), introduced in Chapter 2.4.
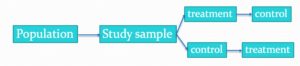
Figure 1. A two group Randomized Crossover Trial.
Subjects randomly selected from population of interest, then again once recruited into one of two treatment arms: arm 1, subjects first receive the experimental treatment, then some time later the subjects receive the control treatment; arm 2, subjects first receive the control treatment, then some time later the subjects receive the experimental treatment. Note the difference between this paired or repeated measures design and the independent sample design (see Chapter 10.1). Repeated measures designs have many advantages; we discuss them further in Chapter 14.6. At the start, repeated measures designs have greater statistical power compared to cross-sectional (independent) sample designs.
Many experiments are designed so that subjects receive all treatments and responses are gauged against the initial values recorded on the subjects. Repeated measures statistical tests, like the paired t-test, are needed however to analyze the data. These types of statistical procedures are similar to the two sample independent t-test that we discussed earlier.
However, there is an important difference between these two types of statistical procedures. For the two independent sample t-test the samples are unpaired: we observed one variable on some individuals assigned to two different groups. These groups might be
- Two locations where we measure plants or animals
- A treatment (or experimental) group with a control group.
- Expression of cytokeratin genes (eg, ΔΔCT, fold-change) from breast cancer patients compared to healthy donor subjects (Andergassen et al 2016).
The point is that samples in one group are not the same samples in the second group.
In the paired t-test we have two groups but the observations in these two groups are paired. Paired means that there is some relationship between one observation in the first sample and one observation in the second sample (every observation in one sample must be paired with one observation in another sample).
For example, weight change in humans before and after a change in diet could be performed as a paired analysis. Each subject’s weight before the diet was “paired” with the same subject’s weight after the diet.
Another example comes from genetics. Siblings or Monozygotic twins or clones, strains or varieties of plants or animals can be Paired in an experiment.
- You can give one of the twins a particular diet, or the plant or animal clones or strains can be raised in a particular environment (nutrient)
- The other twin or plant or animal clone or variety can serve as a type of control by providing a normal diet or normal environment.
Another example is a study of environmental pollution on cancer rates in many different communities.
- The researchers selects pairs of communities with similar characteristics for many socioeconomic factors.
- Each pair of communities differed with respect to the proximity to a known source of pollution: one of the pair was close to a source of pollution and one of the pair was far from a source of pollution.
The purpose of pairing in this example is to attempt to “control” for all the socioeconomic factors that might contribute to cancer but they did not want to directly measure. These other factors should be similar for each member of the pair.
Example: How repeatable is human running performance?
The subheading is misleading — we leave “repeatability” or, do individuals perform consistently to another time (see Chapter 12.3 – Fixed effects, random effects, and agreement). Here, we focus on a different question — we test whether mean performance differs across repeated trials. This may seem a subtle difference, but consistency asks the question if performance, whether it is answering questions on an exam or running times for a race, is stable across trials. Testing the means of first and second trials asks a different question: we test for a trend in performance, which may reflect learning.
Here’s an example in which a measure was taken twice for the same individuals. The data are running speed or pace during 5K race held annually on Oahu for a selected sample of female runners with repeat race times (20 – 29 years old). The race was run annually on Oahu, and the data reported are the pace for the first race and the second race, which occurred a year later (Jamba Juice – Banana Man Chase, Ala Moana Beach Park, data extracted from source, https://timelinehawaii.com).
Table 1. 5K pace times (kph) for 15 women (20 – 29 years)
| ID | First race | Second race |
|---|---|---|
| 1 | 15.28 | 15.61 |
| 2 | 11.22 | 11.19 |
| 3 | 8.80 | 9.14 |
| 4 | 8.88 | 5.46 |
| 5 | 9.81 | 10.50 |
| 6 | 6.12 | 5.69 |
| 7 | 8.31 | 8.71 |
| 8 | 6.26 | 7.42 |
| 9 | 17.16 | 16.41 |
| 10 | 16.23 | 15.82 |
| 11 | 5.90 | 7.12 |
| 12 | 8.31 | 10.48 |
| 13 | 5.93 | 8.64 |
| 14 | 10.54 | 5.99 |
| 15 | 9.53 | 8.69 |
Note 1: We’ll return to this data set in Chapter 15.3
Load the data into R as an unstacked data set. Data available at end of this page or click here.
Begin with description and exploration of the data. Start with histograms to get a sense of the sample distributions (hint: we’re looking to see if the data looks like it could come from a normal distribution, see Chapter 13.3 Assumptions) (Fig 2).
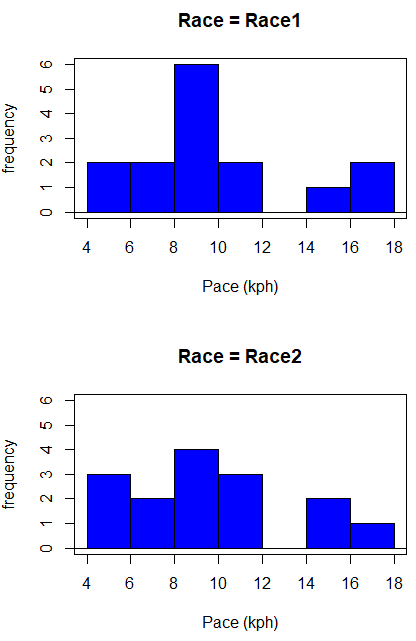
Figure 2. Histograms shows the distribution of 5K running times of 15 women who ran the race twice.
R code (stacked data set, then used defaults R Commander to make the histogram, then modified the code and submitted modified code to make Fig 1)
with(stackExCh10.3, Hist(obs, groups=Race, scale="frequency", breaks="Sturges", col="blue",
xlab="Time (min)", ylab="Frequency")))
Conclusion? The histograms don’t look normally distributed so we keep this in mind as we proceed. (See Chapter 13 – Assumptions of parametric tests for additional information about assumptions.)
A box plot comparing the first and second pace times (Fig 3).
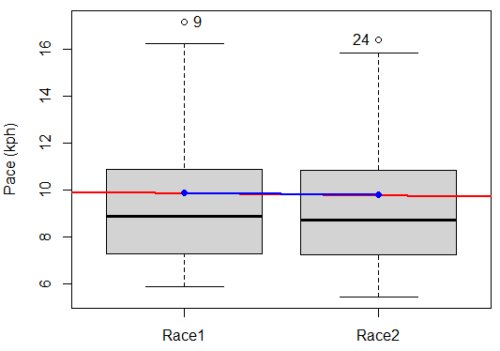
Figure 3. Box plot of race speed (kph) for 15 women 5K in two successive years.
I added a trend line (linear regression, see Chapter 17, red line) and connected the averages (blue line) for visual emphasis — no differences between the means — but note that one wouldn’t do this as part of an analysis (see Chapter 4 discussion).
R code for Fig 2
Boxplot(obs~Race, data=stackExCh10.3, id=list(method="y"), xlab="", ylab="Pace (kph)") #boxplot was made in Rcmdr
abline(lm(obs ~ as.numeric(Race), data=stackExCh10.3), col="red", lwd=2)
means <- tapply(obs, Race, mean)
points(1:2, means, pch=7, col="blue")
lines(1:2, means, col="blue", lwd=2)
The box plot works to show the median difference, but loses the paired information. A nice package called PairedData has several functions that work well with paired data, for example a profile plot (Fig 4). A profile plot is useful for showing an association between paired data.
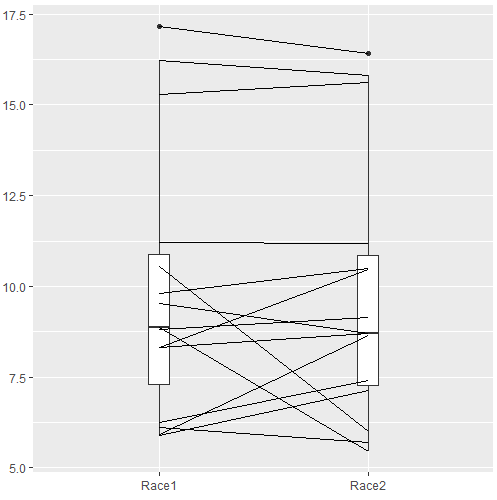
Figure 4. Profile plot, PairedData package.
R commands for Figure 4.
require(PairedData)
attach(example.ch10.3) # remember to attach dataframe so you don't have to call variables like example.ch10.3$Race1
races <- paired(Race1, Race2)
plot(races, type = "profile")
Paired t-test calculation
The paired t-test is a straight-forward extension of the independent sample t-test; the key concept is that the two samples are no longer independent, they are paired. Thus, instead of mean of group 1 minus mean of group two, we test the differences between sample 1 and sample 2 for each paired observation.

- Compute the differences between the Paired Samples (as in tables above)
- Calculate the MEAN difference score,
 : in the previous example = -0.094 kmh
- Calculate the degrees of freedom df = # pairs – 1 = n – 1, where n is the number of pairs
- Calculate the standard error of the mean of d.
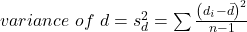
where

- Calculate the test statistic for paired data

- Compare to the Critical Value in Table C. 4 (Appendix Table 2)
- Find the Critical Value = t α (2), df
Try as difference instead of paired
Before you answer, take a look at the box plot of the mean difference between the repeat measures of 5K pace for the 15 women (Fig 5).
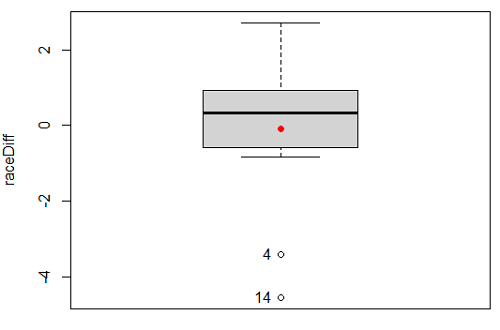
Figure 5. Box plot of differences, Red dotted lines shows the null hypothesis.
Note 2: Figure 5 is appropriate for diagnostics, but not for publication, per our discussions in Chapter 4.
Create a new variable, raceDiff, equal to Race2 minus Race1. Then, use the one sample T-test on raceDiff. I’ll leave you to complete the work (Question 2).
R code
t.test(Race1, Race2, paired = TRUE, alternative = "two.sided")
R output
Paired t-test

data: Race.1 and Race.2
t = 0.19389, df = 14, p-value = 0.849
alternative hypothesis: true difference in means is not equal to 0
95 percent confidence interval:
-0.9491017 1.1377521
sample estimates:
mean of the differences
0.09432517
Rcmdr, paired t-test
Rcmdr: Statistics → Means → Paired t-test…
Note: your two groups must be in two different columns (unstacked!) to run this version of the test.
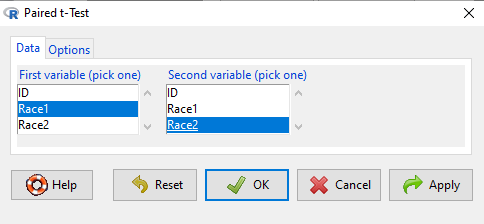
Figure 6. R Commander Paired t-test menu, Rcmdr version 2.7.
After selecting the variables, set null hypothesis after clicking on Options tab (Fig 6).
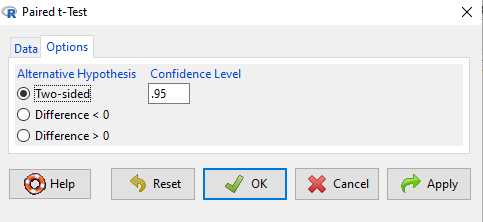
Figure 7. R Commander Paired t-Test options, select null hypothesis.
Click OK to proceed. Results will be the same as the output listed above.
the following text needs to be updated
Interpret the results.
So, what can we conclude about the null hypothesis? Interpret the 95% CI, the T-test statistic, and the P-value.
Do not ignore sample dependence
What if we ignored the repeated measures design and treated the first and second races as independent? The important concept here is to ask, what would have happened if we had done a two independent sample t-test instead?
Let’s run the analysis again, this time incorrectly using the independent sample t-test. We need to manipulate the data set before we do.
Manage your data: Stack the data
This is a good time to share how to Stack data in R. If you look at our active data set, the results of the two trials are in two different columns. In order to run the independent sample t-test we need the data in one column (with a label column).
stackExCh10.3 <- stack(example.ch10.3[, c("Race1","Race2")])
names(stackExCh10.3) <- c("obs", "Race")
Rcmdr: Data → Active data set → Stack variables in data set…
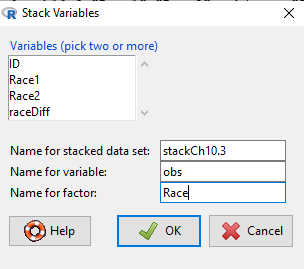
Figure 8. R Commander: Stack worksheet. Select the two variables, Race1 and Race2.
I entered values for name of the new data set, the new variable, and the name for the factor (label) column.
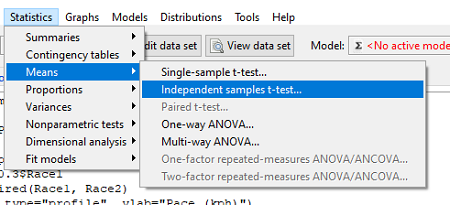
Figure 9. R Commander, select independent sample t-Test …
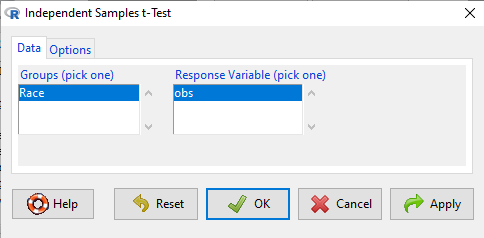
Figure 10. R commander, independent sample t test menu.
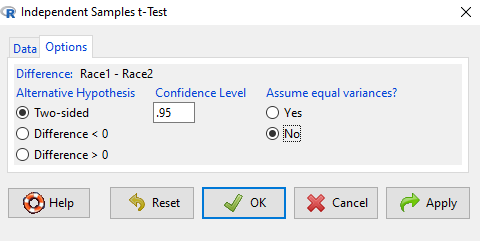
Figure 11. R Commander, select options for independent sample t-Test (assume equal variance).
Here are the results of the independent sample t-test from R.
t.test(obs~Race, alternative='two.sided', conf.level=.95, var.equal=TRUE, + data=stackCh10.3)

Two Sample t-test
data: obs by Race
t = 0.070645, df = 28, p-value = 0.9442
alternative hypothesis: true difference in means is not equal to 0
95 percent confidence interval:
 -2.640719 2.829369
sample estimates:
mean in group Race1 mean in group Race2
 9.886342 9.792017
End R output
In this case, we would have reached the same general conclusion, but the p-values are different. The p-value from the paired t-test was about 0.85 whereas the p-value from the independent sample t-test was higher, nearly 0.95, suggesting little difference between the two trials.
While the general conclusion holds, this time, that there were no statistically significant difference between the means for first and second trials. However, it won’t always work out that way. And besides, if you treated the paired data as independent, you’ve clearly violated one of the assumptions of the test.
Take a look at the degrees of freedom for the two analyses. By ignoring the pairing of samples we gain twice the number of degrees of freedom … that can’t both be right. The way to distinguish between the two is to go back to the experimental units.
Question: What are the sampling units in the case of repeat measures on individuals: the individuals themselves? the pairs of burst speed trials? something else?
it is important to note that the paired t-test is still the best for this situation because it accurately reflects the experiment — individuals were measured twice, therefore the two groups (trial 1 and trial 2) are not independent! Thus, the p-value from the paired t-test correctly reflect our best analyses of the test of the null hypothesis because the correct degrees of freedom were 14 and not 28.
In the case of the independent sample t-test we necessarily make the assumption that the two groups are independent — that is, that they are measured on different sampling units (eg, different individuals or subjects). In statistical terms, that means that you assume that the correlation between trial results is equal to zero. By incorrectly choosing an independent sample test in these repeated measures cases, I would make two null hypotheses: (1) that the means are the same and (2) that the correlation between repeat measures is zero. The problem? The t-test only evaluates the first hypothesis (means).
Questions
- Refer to Figure 6 again and related data set. Were runners faster the second year or the first year running the 5k? What about the points labeled 4 and 14? What was the average difference between first and second races?
- Complete the test of the null hypothesis of no difference between race 1 and race 2 (
raceDiff) with the one sample t-test. Set up a table to compare the test statistic, df, and p-values for results from paired t test, one sample t-test, and independent sample t-test. How do these results compare? - I’ve called the observed value “pace,” but runners would know that pace is actually amount of time per kilometer, not the total time over 5k, which is what I called pace.
- Create a new variable and report average pace for Race1 and Race2.
- Redo the paired analysis, including box plot, on your new variable.
- What is the null hypothesis for your new variable?
- Summarize your results and add to the table you created for question 2.
- Redo the two plots in Figure 2 so that the two histograms are on the sample plot. Instructions and examples were provided in Chapter 4.2.
Quiz Chapter 10.3
Paired t-test
Data set
example.ch10.3 <- read.table(header=TRUE, text = "
ID Race1 Race2
1 15.28 15.61
2 11.22 11.19
3 8.80 9.14
4 8.88 5.46
5 9.81 10.50
6 6.12 5.69
7 8.31 8.71
8 6.26 7.42
9 17.16 16.41
10 16.23 15.82
11 5.90 7.12
12 8.31 10.48
13 5.93 8.64
14 10.54 5.99
15 9.53 8.69
")
Chapter 10 contents
4.1 – Bar (column) charts
Introduction
Bar chart, also called a bar graph, or column chart in many spreadsheet apps (e.g., Google Sheets, Microsoft Excel, Libreoffice Calc — “bar charts” is reserved for horizontal bar plots), are used to compare counts among two or more categories, i.e., an alternative to pie charts (Fig. 1).
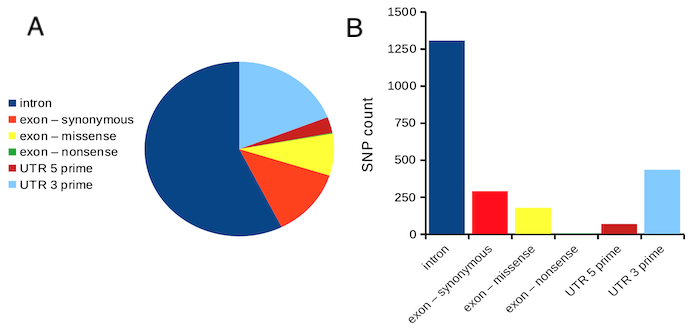
Figure 1. Single nucleotide variants for human gene ACTB by DNA and functional element (data collected 19 May 2022 from NCBI SNP database with Advanced search query). A. Pie chart. Note that slide for “exon – nonsense” is not visible. B. Bar chart – color coded bars to facilitate comparison with pie chart.
Although bar charts are common in the literature (Cumming et al 2007; Streit and Gehlenborg 2014), bar charts may not be a good choice for comparisons of ratio scale data (Streit and Gehlenbor 2014). Bar charts for ratio data are misleading. Parts of the range implied by the bar may never have been observed: the bars of the chart always start at zero. Box (whisker) plots are better for comparisons of ratio scale data and are presented in the next section of this chapter. That said, I will go ahead and present how to create bar charts for both count — generally considered acceptable — and ratio scale data, for which their use is controversial.
Purpose of the bar chart
Like all graphics, a bar chart should tell a story. The purpose of displaying data is to give your readers a quick impression of the general differences among two or more groups of the data. For counts, that’s where the bar chart comes in. The bar chart is preferred over the pie chart because differences are represented by lengths of the bars in the bar chart. Differences among categories in a pie chart are reflected by angles, and it seems that humans are much better at judging lengths than angles.
Bar chart with counts
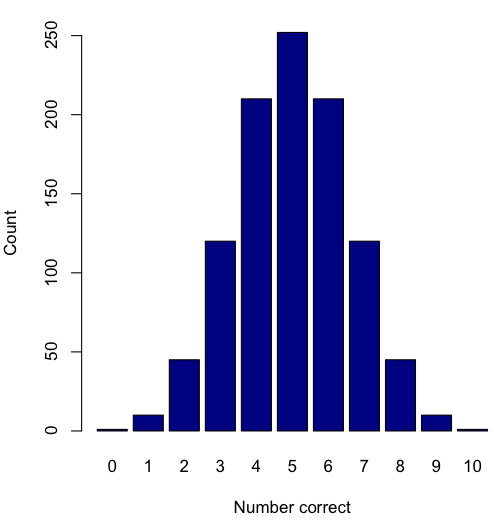
Figure 2. A simple bar chart
myCombo <- seq(0,10, by=1)
myCounts <- choose(10, myCombo)    #combinations
barplot(myCounts, names.arg = myCombo, xlab = "Number correct", ylab = "Count",col = "darkblue")
A stacked bar chart is used to
myCombo <- seq(0,10, by=1)
myCounts <- choose(10, myCombo)    #combinations
barplot(myCounts, names.arg = myCombo, xlab = "Number correct", ylab = "Count",col = "darkblue")
Figure 3. The luxury ship RMS Titanic, which sunk 15 April 1912, More than 1500 souls were lost. Public domain image, Wikipedia. Click image to view full sized image.
Stacked bar chart, data set TitanicSurvival in package carData.
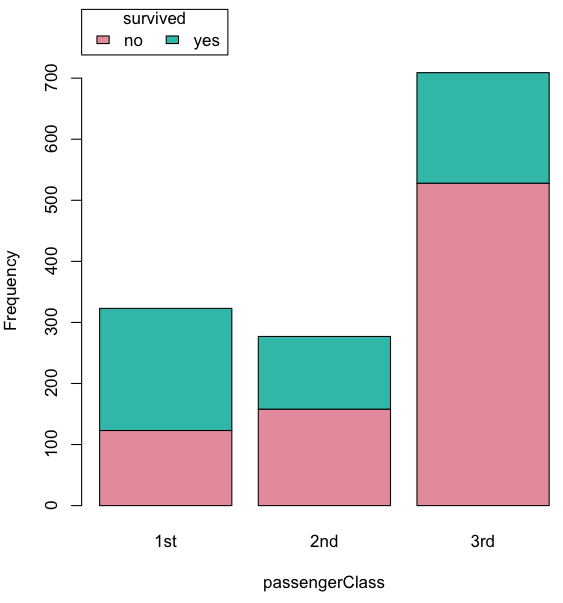
Figure 4. A stacked bar chart, survival Titanic
Barplot(passengerClass, by=survived, style="divided", legend.pos="above", xlab="passengerClass", ylab="Frequency")Bar charts with error bars
Although many data visualization specialists argue against the bar chart — they tend to obscure data — their use is well established. For the familiar bar chart with ratio scale data, the X (horizontal) axis displays the categories of one variable (e.g., location, or treatment group). You plot groups to emphasize comparisons. The Y (vertical) axis then is the mean for each group.
You need error bars with your bar chart to convey variability. A bar chart plus error bars is sometimes called (pejoratively) a dynamite plot. If the mean is displayed, some measure of precision should be (must be?) displayed (Cumming et al 2007). And, as you should recall by now, your choices are standard deviation (Chapter 3.2), standard error of the mean (SEM) (Chapters 3.2, 3.4), or confidence interval (see Chapter 3.4). It is strongly advised, that without a representation of precision, one should not interpret trends or group differences from representations of means (i.e., height of bars) alone.
The bar charts on this page are means plus or minus the standard error of the mean, + SEM. I’m not advocating here for the bar chart — box plots with efforts to show the actual data are better. However, bar charts remain common and may be more familiar to certain audiences. We’ll discuss which choice to make.
Examples
The Copper_rats_PMID3357063 dataset will be used for the next series of graphs (Data set). Refer to Mike’s Workbook for Biostatistics Part07 to review how to import the data.
A portion of the data set is shown below
head(Copper)
         Diet     Body    Heart    Liver
1 Adequate-Cu 320.1381 1.125037 10.259657
2 Adequate-Cu 329.6879 1.158982 9.843295
3 Adequate-Cu 327.9838 1.090374 9.855975
4 Adequate-Cu 334.6669 1.118183 9.942997
5 Adequate-Cu 338.3134 1.172636 9.860971
6 Adequate-Cu 345.4608 1.056183 8.885820
The data set consists of organ weights (heart, liver) from rats fed a diet adequate in copper, deficient in copper, and then a third group who received the adequate diet from perspective of amount of copper, but calorie restricted to match the decreased feeding rates of the rats fed the copper deficient diet. Copper is an essential trace element in our diet. The data set was simulated from descriptive statistics (means, standard deviation, number of subjects) of published data by sampling from a normal distribution. (Table 1, Ovecka et al 1988).
On we go with some graphs.
Note 1: R has many options to create bar charts, and especially ggplot2 can be used to great advantage, but there is a learning curve. One of the great things about R is that folks help each other by sharing code. For example, http://www.cookbook-r.com/Graphs/Plotting_means_and_error_bars_(ggplot2)/
But, I’m still learning about R graphics, and for bar charts with error bars, I find other packages more straight-forward. So, I’ll use this moment to point out that making a good graph is more about the end product then the particular tools. I have been using other tools for years to make my graphics, so I tend to default on these options first. Graphs presented here are mostly from Veusz software program (pronounced “views”). I like it because the software allows me to edit any of the elements of the graph.
Here’s a typical looking bar chart with ratio scale data: means ± SEM. Let’s look at them more critically.
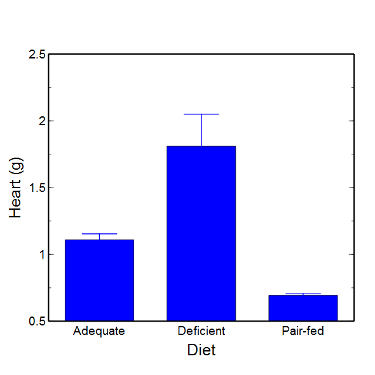
Figure 5. A bar chart with error bars (standard error of the mean).
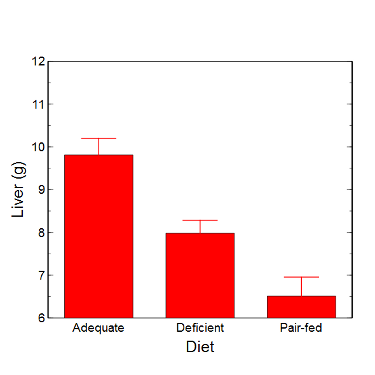
Figure 6. Another bar chart. with standard errors of mean
When making comparisons, make sure the axes have the same scale, or consider putting the graphs together.
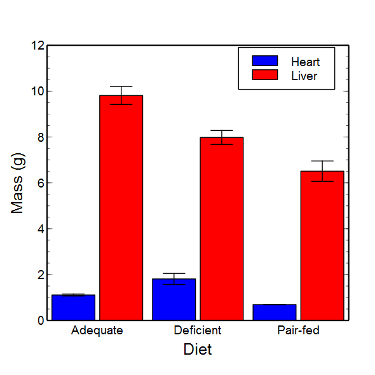
Figure 7. Bar chart that allows for a comparison among levels of a a factor (organs, liver vs. heart).
Analysis note: For variables that covary with body size (for example, on average, tall people generally are heavier too), is how to present (and analyze) the data in such a way that body size is accounted for. Here, the solution was to express organ weight as the ratio of organ weight to body weight for the mice. This may or may not be a good solution, and the answer is too complicated for us now (has to do with a thing called allometric scaling), but I wanted to at least present the issue and show how the graphics can be improved to handle some of these concerns.
Here’s the organ weights again, but taken as ratio of body mass.
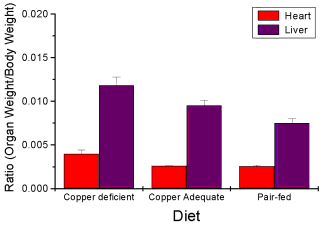
Figure 8. Same chart as in Figure 6, but on ratios.
Note 2. Lets be clear about expectations of you for statistics class. Now, R (and Rcmdr) do lots of graphics, pretty much anything you want, but it is not as friendly as it could be. For BI311 homework, the default graphics available via Rcmdr will generally be adequate for assignments. R and Rcmdr has many bar chart options, but there isn’t a straightforward way to get the error bars, unless you are willing to enter some code to the command line or learn a particular package (like gplots or ggplot2).
How to make a bar chart with error bars in R
Option 1. First, let’s try a work-around. Instead of an error bar option for bar chart menu, Rcmdr provides a plot of means that allows you to plot with error bars. These are equivalent graphs, the “bar chart” and the “plot of means”, though you should favor the bar chart format for publishing.
Rcmdr: Graphs → Plot of means…
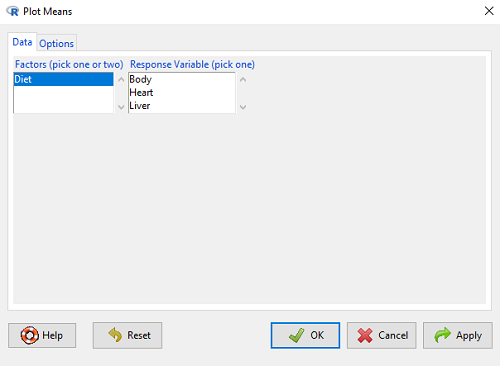
Figure 9. Rcmdr menu popup for Plots Means
Here, Rcmdr takes the data and calculates the mean and your choice of standard errors or deviations, confidence intervals, or no error bars. the resulting graph is below.
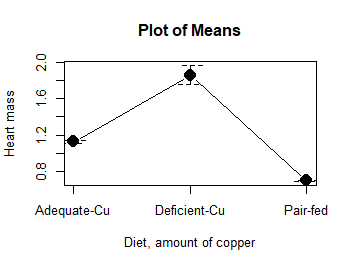
Figure 10. Plot of means
That’s an ugly graph (Fig. 10). Functional, good enough for data exploration and preliminary results, and certainly good enough for a Biostatistics homework or report. Additionally, connecting the dots here is a no-no. It implies that if we had measured categories between “adequate copper” and “deficient copper,” then the points would fall on those lines. That would be a complete guess. So, why did I include the connecting lines? That was the default setting for the command, and it makes the point — think before you click. One argument for connecting points in a graph is that it makes it easier for the reader to visualize trends.
This graph (Fig. 10) is fine for exploring data, but you will want to do better for publication.
Let’s make some better graphs with R
Once you are ready to go beyond the default settings available in Rcmdr, there is tremendous functionality in R for graphics. To access R’s potential, you’ll need to get into the commands a bit. I’m going to continue to try and shield you from the programming aspects of R, but from time to time you really need to see what is possible with R. Graphics is one such area. I use the package gplots, with 23 different graphing functions (type at R prompt ?gplots to call up the manual pages).
gplots should be among the packages on your R installation; if not, then install the package and run library(gplots) to complete the installation. We’ll try the barchart2 function.
But first, we need to get means for each of our groups.
At the R command prompt:
hrtWt <- tapply(Dataset$HeartWt, list(Group=Dataset$Group), mean, na.rm=TRUE) This code extracts means from our HeartWt variable for each Group, then stores the three (in this case, because our data set has 3 groups) in the place holder I had called hrtWt. To verify that the three means are there, type “hrtWt” without the quotes then enter.
You should see
hrtWt Group Cu adequate Cu deficient Pair-fed
               1.200000     1.566667 0.900000
R functions used: tapply, list, mean; na.rm was not needed but would be used to remove all missing values (recall during our import phase we were asked how missing observations were noted in our file; the default is NA).
Next, I want to apply standard error bars
stdDEV <- tapply(Dataset$HeartWt, list(Group=Dataset$Group), sd, na.rm=TRUE)
cil <- hrtWt-(stdDEV/sqrt(3))
ciu <- hrtWt+(stdDEV/sqrt(3))
I used cil and ciu to designate the lower cil and upper ciu values for my ± SEM (standard error of the mean). ciu stands for “confidence interval lower;” ciu stands for “confidence interval upper.”
Finally, here’s the plot command
barplot2(hrtWt, beside = TRUE, main=c("Mice fed different amounts of copper in diet"), col = c("blue", "red", "green"), xlab="Copper in diet", ylab="Heart mass (g)", ylim = c(0, 2), plot.ci=TRUE, ci.l=cil, ci.u=ciu)Now, draw a box around the graphic
box()Whew!
What does your new graph look like? My graph is below (Fig. 11).
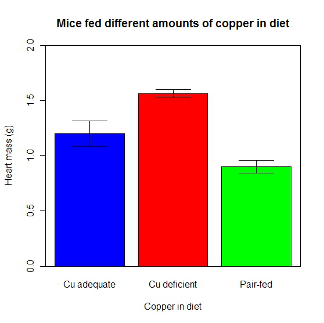
Figure 11. A bar chart using barplot2.
This works and the point is that once the script is written it easy to make small changes as you need in the future to make nice graphs.
If you are impatient like me, I like a GUI option, at least to start crafting the graph. The Rcmdr plugin KMggplot2 provides a good set of tools to make bar charts with error bars. An even better option I think is to use a software package that is designed for graphics, at least simple graphics like a bar chart. I use SciDAVis and Veusz for simple graphs like pie charts and bar charts; much easier to control.
ggplot2 bar charts with error bars
Nevertheless, here’s how to make a bar chart with error bars using ggplot2 (Fig. 11). First, we need to create a statistics summary. The script printed here was modified from scripts at R Graph Cookbook website.
require(plyr)
summarySE <- function(data=NULL, measurevar, groupvars=NULL, na.rm=FALSE,
     conf.interval=.95, .drop=TRUE) {
length2 <- function (x, na.rm=FALSE) {
     if (na.rm) sum(!is.na(x))
     else length(x)
}

#returns a vector with N, mean, and sd
datac <- ddply(data,groupvars, .drop=.drop,
    .fun = function(xx,col){
      c(N=length2(xx[[col]],na.rm=na.rm),
      mean=mean(xx[[col]],na.rm=na.rm),
      sd=sd(xx[[col]],na.rm=na.rm)
     )
    },
    measurevar
   )

#Rename the "mean" column
datac <- rename(datac,c("mean"=measurevar))

#Calculate the standard error of the mean
datac$se <- datac$sd/sqrt(datac$N)

#Get confidence interval
ciMult <- qt(conf.interval/2 + .5, datac$N-1)
datac$ci <- datac$se*ciMult

return(datac)
}
Applying this function to the BMI dataset yields the following output.
sumBMI <- summarySE(BMI, measurevar="BMI", groupvars=c("Sex", "Smoke"));sumBMI

   Sex Smoke   N      BMI       sd        se       ci
1    F    No  23 26.83567 7.610271 1.5868511 3.290928
2    F   Yes  14 25.76133 4.658625 1.2450698 2.689810
3    M    No  10 26.35731 3.363575 1.0636557 2.406156
4    M   Yes  27 26.71879 4.675631 0.8998256 1.849618
Now we are ready to make the bar chart with error bars
ggplot(tgc,aes(x=Smoke,y=BMI,fill=Sex)) +
 geom_bar(position=position_dodge(),stat="identity",color="black") +
 geom_errorbar(aes(ymin=BMI,ymax=BMI+se),width=.2,position=position_dodge(.9))
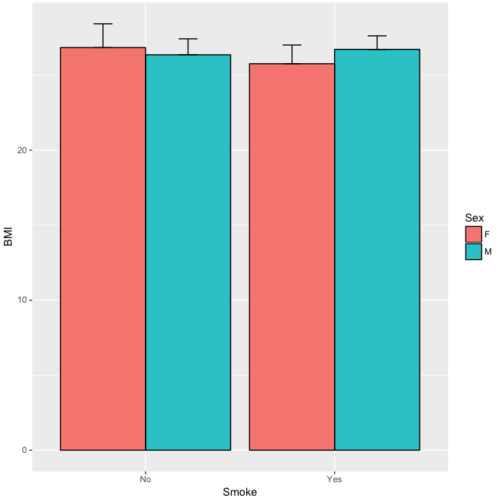
Figure 12. A barchart from ggplot2
Questions
1. Why should you use box plots and not bar charts to display comparisons for a ratio scale variable between categories? Obtain a copy of the article by Streit and Gehlenbor 2014 — it’s free! After reading, summarize the pro and cons for box plots over bar charts with error bars.
2. Enter the following data into R. The data are sulfate levels in water, parts per million.
type = c("Palolo Stream","Chaminade tap water", "Aquafina","Dasani")
sulfateppm =c(11, 14, 5, 12)
try = data.frame(type,sulfateppm)
byWater = tapply(try$sulfateppm,list(Group=try$type),mean)
Make a simple bar chart using the boxplot2 function in gplots package.
3. Change the range of values on the vertical axis to 0, 20
4. Change the color of the bars from gray to blue
5. Add a label to the vertical axis, “Sulfates, ppm” (without the quotes)
6. Add a box around the graph.
Quiz – Chapter 4.1
Bar charts
Data set
| Diet | Body | Heart | Liver |
|---|---|---|---|
| Adequate-Cu | 320.1381 | 1.125037 | 10.259657 |
| Adequate-Cu | 329.6879 | 1.158982 | 9.843295 |
| Adequate-Cu | 327.9838 | 1.090374 | 9.855975 |
| Adequate-Cu | 334.6669 | 1.118183 | 9.942997 |
| Adequate-Cu | 338.3134 | 1.172636 | 9.860971 |
| Adequate-Cu | 345.4608 | 1.056183 | 8.88582 |
| Adequate-Cu | 343.089 | 1.081261 | 10.166647 |
| Adequate-Cu | 328.3403 | 1.111278 | 10.124185 |
| Adequate-Cu | 324.9723 | 1.189194 | 10.158402 |
| Adequate-Cu | 325.2378 | 1.14715 | 9.939521 |
| Deficient-Cu | 195.5052 | 1.90973 | 7.907565 |
| Deficient-Cu | 182.7809 | 1.823672 | 8.430167 |
| Deficient-Cu | 184.3701 | 1.632249 | 7.619104 |
| Deficient-Cu | 193.7867 | 1.831765 | 8.742489 |
| Deficient-Cu | 180.0417 | 1.710367 | 7.975879 |
| Deficient-Cu | 208.5349 | 2.495623 | 8.652445 |
| Deficient-Cu | 182.3048 | 1.262053 | 7.257726 |
| Deficient-Cu | 203.0413 | 2.153639 | 8.081782 |
| Deficient-Cu | 193.3829 | 1.986028 | 7.807328 |
| Deficient-Cu | 195.0523 | 1.76975 | 8.297611 |
| Pair-fed | 211.0858 | 0.6911343 | 6.251177 |
| Pair-fed | 210.4041 | 0.6928067 | 7.696669 |
| Pair-fed | 208.5969 | 0.6911901 | 6.973803 |
| Pair-fed | 209.3333 | 0.7039211 | 6.629303 |
| Pair-fed | 208.8889 | 0.7077486 | 6.038704 |
| Pair-fed | 208.2994 | 0.7004535 | 6.606877 |
| Pair-fed | 209.4524 | 0.6915543 | 6.228888 |
| Pair-fed | 210.2699 | 0.6984497 | 6.638466 |
| Pair-fed | 208.8142 | 0.7214847 | 6.353705 |
| Pair-fed | 209.2977 | 0.6848656 | 6.536642 |