8.2 – The controversy over proper hypothesis testing
Introduction
Over the next several chapters we will introduce and develop an approach to statistical inference, which has been given the title “Null Hypothesis Significance Testing” or NHST.
In outline, NHST proceeds with
- statements of two hypotheses, a null hypothesis, HO, and an alternative hypothesis, HA
- calculate a test statistic comparison of the null hypothesis (assuming some characteristic of data).
- The value of the test statistic is to be compared to a critical value for the test, identified for the assumed probability distribution at associated degrees of freedom for the statistical function, and assigned Type I error rate.
We will expand on these statements later in this chapter, so stay with me here. Basically, the null hypothesis is often a statement like the responses of subjects from the treatment and control groups are the same, eg, no treatment effect. Note that the alternative hypothesis, eg, hypertensive patients receiving hydalazine for six weeks have lower systolic blood pressure than patients receiving a placebo (Campbell et al 2011), would be the scientific hypothesis we are most interested in. But in the Frequentist NHST approach we test the null hypothesis, not the alternative hypothesis. This framework over proper hypothesis testing is the basis of the Bayesian vs Frequentist controversy.
Consider the independent sample t-test (see Chapter 8.5 and 8.6), our first example of a parametric test.

After plugging in the sample means and the standard error for the difference between the means, we calculate t, the test statistic of the t-test. The critical value is treated as a cut-off value in the NHST approach. We have to set our Type I error rate before we start the experiment, and we have available the degrees of freedom for the test, which follows from the sample size. With these in hand, the critical value is found by looking in the t-table of probabilities (or better, use R).
For example, what is the critical value of t-test with 10 degrees of freedom and Type I error of 5%?
In Rcmdr, choose Distributions → Continuous distributions → t distribution → t quantiles… (Fig 1).
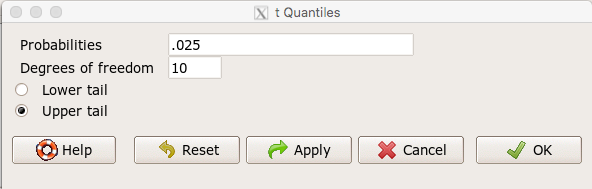
Figure 1. Screenshot t-quantiles Rcmdr menu.
Note we want Type I equal to 5%. Since there are two tails for our test, we divide 5% by two and enter 0.025 and select the Upper tail.
R output
> qt(c(.025), df=10, lower.tail=FALSE)
[1] 2.228139
which is the same thing we would get if we look up on the t-distribution table (Fig 2).
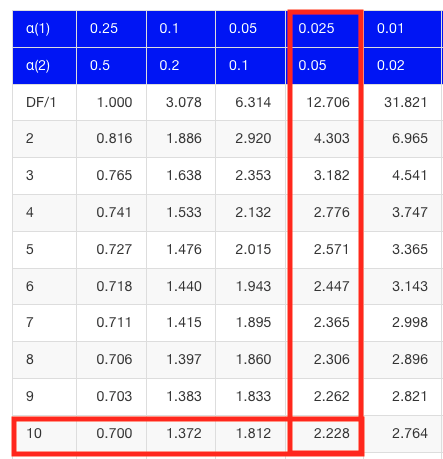
Figure 2. Screenshot of portion of t-table with highlighted (red) critical value for 10 degrees of freedom.
If the test statistic is greater than the critical value, then the conclusion is that the null hypothesis is to be provisionally rejected. We would like to conclude that the alternative hypothesis should favored as best description of the results. However, we cannot — the p-value simply tells us how likely our results would be obtained and if the null hypothesis was true. Confusingly, however, you cannot interpret the p-value as telling you the probability (how likely) that the null hypothesis is true. If however the test statistic is less than the critical value, then the conclusion is that the null hypothesis is to be provisionally accepted.
The test statistic can be assigned a probability or p-value. This p-value is judged to be large or small relative to an a priori error probability level cut off called the Type I error rate. Thus, NHST as presented in this way may be thought of as a decision path — if the test statistic is greater than the critical value, which will necessarily mean that the p value is less than the Type I error rate, then we make one type of conclusion (reject HO). In contrast, if the test statistic is less than the critical value, which will mean that the p-value associated with the test statistic will be greater than the Type I error rate, then we conclude something else about the null hypothesis. The various terms used in this description of NHST were defined in Chapter 8.3.
Sounds confusing, but, you say, OK, what exactly is the controversy? The controversy has to do whether the probability or p-value can be interpreted as evidence for a hypothesis. In one sense, the smaller the p-value, the stronger the case to reject the null hypothesis, right? However, just because the p-value is small — the event is rare — how much evidence do we have that the null hypothesis is true? Not necessarily, and so we can only conclude that the p-value is one part of what we may need for evidence for or against a hypothesis (hint: part of the solution is to consider effect size — introduced in Chapter 9.2 — and the statistical power of the test, see Ch 11). What follows was covered by Goodman (1988) and others. Here’s the problem. Consider tossing a fair coin ten times, with the resulting trial yielding nine out of ten heads (eg, a value of one, with tails equal to zero).
R code
set.seed(938291156)
rbinom(10,1,0.5)
[1] 1 1 1 1 1 1 0 1 1 1
Note 1: To get this result I repeated rbinom() a few times until I saw this rare result. I then used the command get_seed() from mlr3misc package to retrieve current seed of R’s random number generator. Initialize the random seed with the command set.seed().
While rare (binomial probability 0.0098), do we take this as evidence that the coin is not fair? By itself, the p-value provides no information about the alternative hypothesis. More about p-value follows below in sections What’s wrong with the p-value from NHST? and The real meaning and interpretation of P-values.
Statisticians have been aware of limitations of the NHST approach for years (see editorial by Wasserstein et al 2019), but only now is the message getting attention of researchers in the biosciences and other fields. In fact, the New York Times recently had a nice piece by F.D. Flam (“The Odds, Continually Updated,” 29 Sep 2014) on the controversy and the Bayesian alternative. Like most controversies there are strong voices on either side, and it can be difficult as an outsider to know which position to side with (Fig 3).
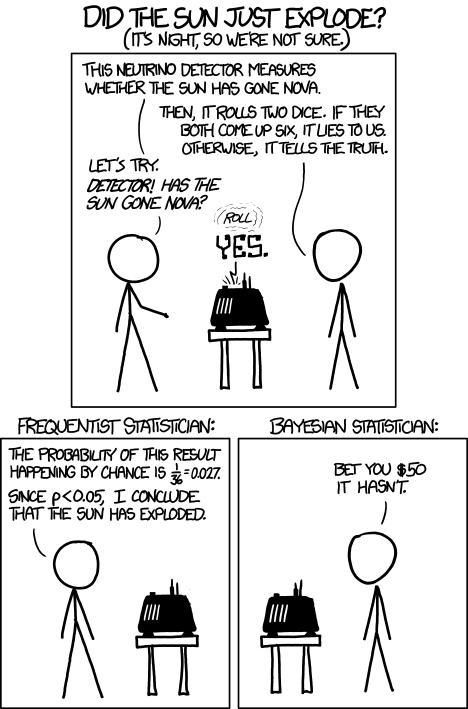
Figure 3. “Frequentists vs. Bayesians,” https://xkcd.com/1132/.
The short answer is — as you go forward do realize that there is a limitation to the frequentist approach and to be on the correct side of the controversy, you need to understand what you can conclude from statistical results. NHST is by far the most commonly used approached in biosciences (eg, out of 49 research articles I checked from four randomly selected issues of 2015 PLoS Biology, 43 used NHST, 2 used a likelihood approach, none used Bayesian statistics). The NHST is also the overwhelming manner in which we teach introductory statistics courses (eg, checking out the various MOOC courses at www.coursera.org, all of the courses related to Basic Statistics or Inferential Statistics are taught primarily from the NHST perspective). However, right from the start I want to emphasize the limits of the NHST approach.
If the purpose of science is to increase knowledge, then the NHST approach by itself is an inadequate framework at best, and in the eyes of some, worthless! Now, I think this latter sentiment is way over the top, but there is a need for us to stop before we begin, in effect, to set the ground rules for what can be interpreted from the NHST approach. The critics of NHST have a very important point, and that needs to be emphasized, but we will also defend use and teaching of this approach so that you are not left with the feeling that somehow this is a waste of time or that you are being cheated from learning the latest knowledge on the subject of statistical inference. The controversy hinges on what probability means.
P-values, statistical power, and replicability of research findings
Science, as a way of knowing how the world works, is the only approach that humans have developed that has been empirically demonstrated to work. Note how I narrowed what science is good for — if we are asking questions about the material world, then science should be your toolkit. Some (eg, Platt 1964), may further argue that there are disciplines in science that have been more successful (eg, molecular biology) than others (eg, evolutionary psychology, cf discussion in Ryle 2006) at advancing our knowledge about the material world. However, to the extent research findings are based solely on statistical results there is reason to believe that many studies in fact have not recovered truth (Ioannidis 2005).
In a review of genomics, it was reported that findings of gene expression differences by many microarray studies were not reproducible (Allison et al 2006). The consensus is that confidence in the findings should hold only for the most abundant gene transcripts of many microarray gene expression profiling studies, a conclusion that undercuts the perceived power of the technology to discover new causes of disease and the basis for individual differences for complex phenotypes. Note that when we write about failure of research reproducibility we are not including cases of alleged fraud (Carlson 2012 on Duke University oncogenomics case), we are instead highlighting that these kinds of studies often lack statistical power; hence, when repeated, the experiments yield different results.
Frequentist and Bayesian Probabilities
Turns out there is a lot of philosophical problems around the idea of “probability,” and three schools of thought. In the Fisherian approach to testing, the researcher devises a null hypothesis, HO, collects the data, then computes a probability (p-value) of the result or outcome of the experiment. If the p-value is small, then this is inferred as little evidence in support of the null hypothesis.
In the Frequentists’ approach, the one we are calling NHST, the researcher devises two hypotheses, the null hypothesis, HO, and an alternative hypothesis, HA. The results are collected from the experiment and, prior to testing, a Type I error rate (α, chance) is defined. The Type I error rate is set to some probability and refers to the chance of rejecting the null hypothesis purely due to random chance. The Frequentist then computes a p-value of result of the experiment and applies a decision criterion: If P-value greater than Type I error rate, then provisionally accept null hypothesis. In both the Fisherian and Frequentist approaches, the probability, again defined at the relative frequency of an event over time, is viewed as a physical, objective and well-defined set of values.
Bayesian approach: based on Bayes conditional probability, one identifies the prior (subjective) probability of an hypothesis, then, adjusts the prior probability (down or up) as new results come in. The adjusted probability is known as posterior probability and it is equal to the likelihood function for the problem. The posterior probability is related to the prior probability and this function can be summarized by the Bayes factor as evidence the evidence against the null hypothesis. And that’s what we want, a metric of our evidence for or against the null hypothesis.
Note 2: A probability distribution function (PDF) is a function of the sample data and returns how likely that particular point will occur in the sample. The distribution is given. The likelihood function approaches this from a different direction. The likelihood function takes the data set as a given and represents how likely are the different parameters for your distribution.
We can calibrate the Bayesian probability to the frequentist p-value (Selke et al 2001; Goodman 2008; Held 2010; Greenland and Poole 2012). Methods to achieve this calibration vary, but the Fagan nomogram Held (2010) proposed is a good tool for us as we go forward. We can calculate our NHST p-value, but then convert the p-value to a Bayes factor by looking at the nomogram. I mention this here not as part of your to do list, but rather as a way past the controversy: the NHST p-value can be interpreted as a Bayesian conditional probability, but they do not test the same hypothesis.
Likelihood
Before we move on there is one more concept to introduce, that of likelihood. We describe a model (an equation) we believe can generate the data we observe. By constructing different models with different parameters (hypotheses), you generate a statistic that yields a likelihood value. If the model fits the data, then the likelihood function has a small value. The basic idea then is to compare related, but different models to see which fits the data better. We will use this approach when comparing linear models when we introduce multiple regression models in Chapter 18.
What’s wrong with the p-value from NHST?
Well, really nothing is “wrong” with the p-value.
Where we tend to get into trouble with the p-value concept is when we try and interpret it. See below, Why is this important to me as a beginning student? The p-value is not evidence for a position, it is a statement about error rates. The p-value from NHST can be viewed as the culmination of a process that is intended to minimize the chance that the statistician makes an error.
In Bayesian terms, the p-value from NHST is the probability that we observe the data (eg, the differences between two sample means), assuming the null hypothesis is true. If we want to interpret the p-value in terms of evidence for a proposition, then we want the conditional error probability.
Sellke et al (2001) provided a calibration of p-values and, assuming that the prior probabilities of the null hypothesis and the alternative hypothesis are equal (that is, that each have a prior probability of 0.5), by using a formula provided by them (equation 3), we can correct our NHST p-value into a probability that can be interpreted as evidence in favor of the interpretation that the null hypothesis is true. In Bayesian terms this is called the posterior probability of the null hypothesis. The formula is

where e is Euler’s number, the base of the natural logarithm (ln), and p is the p-value from the NHST. This calibration works as long as  (Sellke et al 2001).
By convention we set the Type I error at 5% (cf Cohen 1994). How strong of evidence is a p-value near 5% against the null hypothesis being true, again, under the assumption that the prior probability of the null hypothesis being true is 50%? Using the above formula I constructed a plot of the calculated conditional error probability values against p-values (Fig 4).
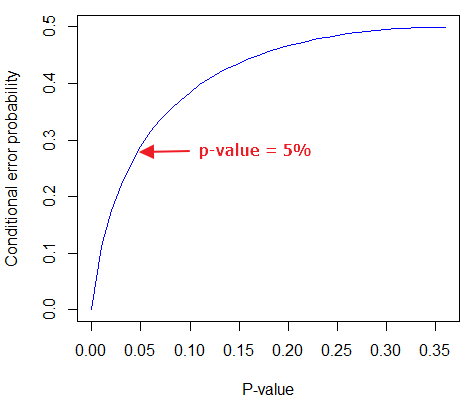
Figure 4. Conditional error probability values plotted against p-values.
As you can see, a p-value of 5% is not strong evidence at just 0.289. Not until p-values are smaller than 0.004 does the conditional error probability value dip below 0.05, suggesting strong evidence against the null hypothesis being true.
R note: For those of you keeping up with the R work, here’s the code for generating this plot. Text after “#” are comments and are not interpreted by R.
At the R prompt type each line
NHSTp = seq(0.00001,0.37,by=0.01)      #create a sequence of numbers between 0.0001 and 0.37 with a step of 0.01
CEP = (1+(-1*exp(1)*NHSTp*log(NHSTp))^-1)^-1    #equation 3 from Sellke et al 2001
plot(NHSTp,CEP,xlab="P-value", ylab="Conditional error probability",type="l",col="blue")
Why is this important to me as a beginning student?
As we go forward I will be making statements about p-values and Type I error rates and null hypotheses and even such things as false positives and false negative. We need to start to grapple with what exactly can be said by p-values in the context of statistical inference, and to recognize that we will sometimes state conclusions that cut some corners when it comes to interpreting p-values. And yet, you (and all consumers of statistics!) are expected to recognize what p-values mean. Always.
The real meaning and interpretation of P-values
This is as good of a time as any to make some clarification about the meaning of p-value and the whole inference concept. Fisher indeed came up with the concept of the p-value, but its use as a decision criterion owes to others and Fisher disagreed strongly with use of the p-value in this way (Fisher 1955; Lehmann 1993).
Here are some common p-value corner-cutting statements to avoid using (after Goodman 2008; Held 2010). P-values are sometimes interpreted, incorrectly, as
Table. Incorrect interpretations of NHST p-values
- the probability of obtaining the observed data under the assumption of no real effect
- an observed type-I error rate
- the false discovery rate, ie, the probability that a significant finding is a “false positive”
- the (posterior) probability of the null hypothesis.
So, if p-values don’t mean any of these things, what does a p-value mean? It means that we begin by assuming that there is no effect of our treatments — the p-value is then the chance we will get as large of a result (our test statistic) and the null hypothesis is true. Note that this definition does not include a statement about evidence of the null hypothesis being true. To get evidence of “truth” we need additional tools, like the Bayes Factor and the correction of the p-value to the conditional error probability (see above). Why not dump all of the NHST and go directly to a Bayesian perspective, as some advise? The single best explanation was embedded in the assumption we made about the prior probability in order to calculate the conditional error probability. We assumed the prior probability was 50%. For many, many experiments, that is simply a guess. The truth is we generally don’t know what the prior probability is. Thus, if this assumption is incorrect, then the justification for the formula by Sellke et al (2001) is weakened, and we are no closer to establishing evidence than before.
The take home message is that it is unlikely that a single experiment will provide strong evidence for the truth. Thus the message is repeat your experiments — and you already knew that! And the Bayesians can tell us that with the addition of more and more data reduces the effect of the particular value of the prior probability on our calculation of the conditional error probability. So, that’s the key to this controversy over the p-value.
Reporting p-values
Estimated p-values can never be zero. Students may come to use software that may return p-values like “0” — I’m looking at you Google Sheets re: default results from CHISQ.TEST() — but again, this does not mean the probability of the result is zero. The software simply reports values to two significant figures and failed to round. Some journals may recommend that 0 should be replaced by p < 0.01 or even < 0.05 inequalities, but the former lacks precision and the latter over-emphasizes the 5% Type I error rate threshold, the “statistical significance” of the result. In general, report p-value to three significant figures and four digits. If a p-value is small, use scientific notation and maintain significant digits. Thus, a p-value of 0.004955794 should be reported as 0.00496 and a p-value of 0.0679 should be reported as 0.0679. Use R’s signif() function, for example p-value reported as 6.334e-05, then
signif(6.334e-05,3)
[1] 6.33e-05
Rounding and significant figures were discussed in Chapter 3.5. See Land and Altman (2015) for guidelines on reporting p-values and other statistical results.
Questions
- Revisit Figure 1 again and consider the following hypothesis — the sun will rise tomorrow.
- If we take the Frequentist position, what would the null hypothesis be?
- If we take the Bayesian approach, identify the prior probability.
- Which approach, Bayesian or Frequentist, is a better approach for testing this hypothesis?
- Consider the pediatrician who, upon receiving a chest X-ray for a child notes the left lung has a large irregular opaque area in the lower quadrant. Based on the X-ray and other patient symptoms, the doctor diagnoses pneumonia and prescribes a broad-spectrum antibiotic. Is the doctor behaving as a Frequentist or a Bayesian?
- With the p-value interpretations listed in the table above in hand, select an article from PLoS Biology, or any of your other favorite research journals, and read how the authors report results of significance testing. Compare the precise wording in the results section against the interpretative phrasing in the discussion section. Do the authors fall into any of the p-value corner-cutting traps?
Quiz Chapter 8.2
The controversy over proper hypothesis testing
Chapter 8 contents
- Introduction
- The null and alternative hypotheses
- The controversy over proper hypothesis testing<.span>
- Sampling distribution and hypothesis testing
- Tails of a test
- One sample t-test
- Confidence limits for the estimate of population mean
- References and suggested readings
8.1 – The null and alternative hypotheses
Introduction
Classical statistical parametric tests — t-test (one sample t-test, independent sample-t-test), analysis of variance (ANOVA), correlation, and linear regression— and nonparametric tests like  (chi-square: goodness of fit and contingency table), share several features that we need to understand. It’s natural to see all the details as if they are specific to each test, but there’s a theme that binds all of the classical statistical inference in order to make claim of “statistical significance.”
- a calculated test statistic
- degrees of freedom associated with the calculation of the test statistic
- a probability value or p-value which is associated with the test statistic, assuming a null hypothesis is “true” in the population from which we sample.
- Recall from our previous discussion (Chapter 8.2) that this is not strictly the interpretation of p-value, but a short-hand for how likely the data fit the null hypothesis. P-value alone can’t tell us about “truth.”
- in the event we reject the null hypothesis, we provisionally accept the alternative hypothesis.
Statistical Inference in the NHST Framework
By inference we mean to imply some formal process by which a conclusion is reached from data analysis of outcomes of an experiment. The process at its best leads to conclusions based on evidence. In statistics, evidence comes about from the careful and reasoned application of statistical procedures and the evaluation of probability (Abelson 1995).
Formally, statistics is rich in inference process (Bzdok et al, 2018). We begin by defining the classical frequentist, aka Neyman-Pearson approach, to inference, which involves the pairing of two kinds of statistical hypotheses: the null hypothesis (HO) and the alternative hypothesis (HA). The null hypothesis assumes that any observed difference between the groups are the results of random chance (introduced in Ch 2.3 – A brief history of (bio)statistics ), where “random chance” implies that outcomes occur without order or pattern (Eagle 2021). Whether we reject or accept the null hypothesis — a short-hand for the more appropriate “provisionally reject” in light of the humility that our results may reflect a rare sampling event — based on the outcome of our statistical inference, the inference is evaluated against a decision criterion (cf discussion in Christiansen 2005), a fixed statistical significance level (Lehmann 1992). Significance level refers to the setting of a p-value threshold before testing is done. The threshold is often set to Type I error of 5% (Cowles & Davis 1982), but researchers should always consider whether this threshold is appropriate for their work (Benjamin et al 2017).
This inference process is referred to as Null Hypothesis Significance Testing, NHST. Additionally, a probability value will be obtained for the test outcome or test statistic value. In the Fisherian likelihood tradition, the magnitude of this statistic value can be associated with a probability value, the p-value, of how likely the result is given the null hypothesis is “true.” (Again, keep in mind that this is not strictly the interpretation of p-value, it’s a short-hand for how likely the data fit the null hypothesis. P-value alone can’t tell us about “truth”, per our discussion, Chapter 8.2.)
Note 1: About reporting p-values, -logP. A Google search will likely reveal “logP,” which is a measure in chemistry. In contrast, “-logP” pertains to how to report p-values in statistics. P-values are traditionally reported as a decimal, like 0.000134, in the closed (set) interval (0,1) — p-values can never be exactly zero or one. The smaller the value, the less the chance our data agree with the null prediction. Small numbers like this can be confusing, particularly if many p-values are reported, like in many genomics works, eg, GWAS studies. In the past, small p-values would be reported as “less than,” eg, < 0.001. This was done in part because of the misleading impression of precision that many significant figures can represent (see discussion in Lang and Altman 2014).
-logP is an alternative, particularly for GWAS studies where the significance level may be much smaller than 5%. Thus, instead of reporting vanishingly small p-values, studies may report the negative log10 p-value, or -logP. Instead of small numbers, large numbers are reported, the larger, the more against the null hypothesis. Thus, our p-value becomes 3.87 -logP.
R code
-1*log(0.000134,10)
[1] 3.872895
Why log10 and not some other base transform? Just that log10 is convenience — powers of 10.
The antilog of 3.87 returns our p-value
> 10^(-1*3.872895)
[1] 0.0001340001
For convenience, a partial p-value -logP transform table
| P-value | -logP |
| 0.1 | 1 |
| 0.01 | 2 |
| 0.001 | 3 |
| 0.0001 | 4 |
On your own, complete the table up to -logP 5 – 10. See Question 7 below.
NHST Workflow
We presented in the introduction to Chapter 8 without discussion a simple flow chart to illustrate the process of decision (Fig 1, Chapter 8). Here, we repeat the flow chart diagram and follow with descriptions of the elements.
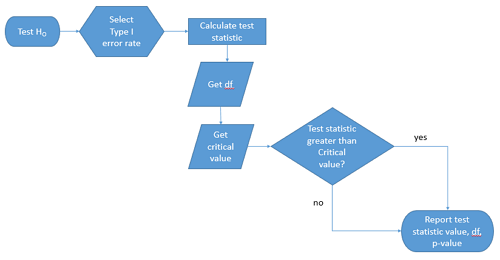
Figure 1. Flow chart of inductive statistical reasoning.
What’s missing from the flow chart is the very necessary caveat that interpretation of the null hypothesis is associated with two kinds of error, Type I error and Type II error. These points and others are discussed in the following sections.
We start with the hypothesis statements. For illustration we discuss hypotheses in terms of comparisons involving just two groups, also called two sample tests. One sample tests in contrast refer to scenarios where you compare a sample statistic to a population value. Extending these concepts to more than two samples is straightforward, but we leave that discussion to Chapters 12 – 18.
Null hypothesis
By far the most common application of the null hypothesis testing paradigm involves the comparisons of different treatment groups on some outcome variable. These kinds of null hypotheses are the subject of Chapters 8 through 12.
The Null hypothesis (HO) is a statement about the comparisons, eg, between a sample statistic and the population, or between two treatment groups. The former is referred to as a one tailed test whereas the latter is called a two-tailed test. The null hypothesis is typically “no statistical difference” between the comparisons.
For example, a one sample, two tailed null hypothesis.

and we read it as “there is no statistical difference between our sample mean and the population mean.” For the more likely case in which no population mean is available, we provide another example, a two sample, two tailed null hypothesis.
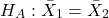
Here, we read the statement as “there is no difference between our two sample means.” Equivalently, we interpret the statement as both sample means estimate the same population mean.
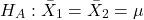
Under the Neyman-Pearson approach to inference we have two hypotheses: the null hypothesis and the alternative hypothesis. The hull hypothesis was defined above.
Note 2: Tails of a test are discussed further in chapter 8.4.
Alternative hypothesis
Alternative hypothesis (HA): If we conclude that the null hypothesis is false, or rather and more precisely, we find that we provisionally fail to reject the null hypothesis, then we provisionally accept the alternative hypothesis. The view then is that something other than random chance has influenced the sample observations. Note that the pairing of null and alternative hypotheses covers all possible outcomes. We do not, however, say that we have evidence for the alternative hypothesis under this statistical regimen (Abelson 1995). We tested the null hypothesis, not the alternative hypothesis. Thus, it is incorrect to write that, having found a statistical difference between two drug treatments, say aspirin and acetaminophen for relief of migraine symptoms, it is not correct to conclude that we have proven the case that acetaminophen improves improves symptoms of migraine sufferers.
For the one sample, two tailed null hypothesis, the alternative hypothesis is

and we read it as “there is a statistical difference between our sample mean and the population mean.” For the two sample, two tailed null hypothesis, the alternative hypothesis would be
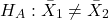
and we read it as “there is a statistical difference between our two sample means.”
Alternative hypothesis often may be the research hypothesis.
It may be helpful to distinguish between technical hypotheses, scientific hypothesis, or the equality of different kinds of treatments. Tests of technical hypotheses include the testing of statistical assumptions like normality assumption (see Chapter 13.3) and homogeneity of variances (Chapter 13.4). The results of inferences about technical hypotheses are used by the statistician to justify selection of parametric statistical tests (Chapter 13). The testing of some scientific hypothesis like whether or not there is a positive link between lifespan and insulin-like growth factor levels in humans (Fontana et al 2008), like the link between lifespan and IGFs in other organisms (Holtzenberger et al 2003), can be further advanced by considering multiple hypotheses and a test of nested hypotheses and evaluated either in Bayesian or likelihood approaches (Chapter 16 and Chapter 17). The advantage of the Bayesian approach is that it returns evidence for or against this hypothesis: if the posterior probability is greater than the prior probability, we can we say that we have evidence for the hypothesis. This is very appealing — the challenge is that the prior probability is inherently subjective (Chapter 6.4), limited by the amount and quality of existing information pertaining to the hypothesis (Prelec 2004).
Note 3: In Bayesian statistics, hypotheses and their parameters are treated as random variables and we can assign them probabilities. The prior probability is your initial belief about the likelihood of an event before adding new data. The posterior probability is the updated probability after new data has been added. Thus, the posterior combines your prior belief with the new information (the likelihood).
In the frequentis approach, the null hypothesis is no difference (no effect); in the Bayesian context, we’d treat this as a point estimate of zero and have to assign it a probability. In the absence of empirical evidence, one option is to set the probability as 50%, equal prior odds. Use of the spike and slab prior is likely a better approach. There’s a lot of work on these points; I refer interested readers to Campbell and Gustafson (2024) for additional readings and discussion.
How to interpret the results of a statistical test.
Any number of statistical tests may be used to calculate the value of the test statistic. For example, a one sample t-test may be used to evaluate the difference between the sample mean and the population mean (Chapter 8.5) or the independent sample t-test may be used to evaluate the difference between means of the control group and the treatment group (Chapter 10). The test statistic is the particular value of the outcome of our evaluation of the hypothesis and it is associated with the p-value. In other words, given the assumption of a particular probability distribution, in this case the t-distribution, we can associate a probability, the p-value, that we observed the particular value of the test statistic and the null hypothesis is true in the reference population.
By convention, we determine statistical significance (Cox 1982; Whitley & Ball 2002) by assigning ahead of time a decision probability called the Type I error rate, often given the symbol α (alpha). The practice is to look up the critical value that corresponds to the outcome of the test with degrees of freedom like your experiment and at the Type I error rate that you selected. The Degrees of Freedom (DF, df, or sometimes noted by the symbol v), are the number of independent pieces of information available to you. Knowing the degrees of freedom is a crucial piece of information for making the correct tests. Each statistical test has a specific formula for obtaining the independent information available for the statistical test. We first were introduced to DF when we calculated the sample variance with the Bessel correction, n – 1, instead of dividing through by n. With the df in hand, the value of the test statistic is compared to the critical value for our null hypothesis. If the test statistic is smaller than the critical value, we fail to reject the null hypothesis. If, however, the test statistic is greater than the critical value, then we provisionally reject the null hypothesis. This critical value comes from a probability distribution appropriate for the kind of sampling and properties of the measurement we are using. In other words, the rejection criterion for the null hypothesis is set to a critical value, which corresponds to a known probability, the Type I error rate.
Before proceeding with yet another interpretation, and hopefully less technical discussion about test statistics and critical values, we need to discuss the two types of statistical errors. The Type I error rate is the statistical error assigned to the probability that we may reject a null hypothesis as a result of our evaluation of our data when in fact in the reference population, the null hypothesis is, in fact, true. In Biology we generally use Type I error α = 0.05 level of significance. We say that the probability of obtaining the observed value AND HO is true is 1 in 20 (5%) if α = 0.05. Put another way, we are willing to reject the Null Hypothesis when there is only a 5% chance that the observations could occur and the Null hypothesis is still true. Our test statistic is associated with the p-value; the critical value is associated with the Type I error rate. If and only if the test statistic value equals the critical value will the p-value equal the Type I error rate.
The second error type associated with hypothesis testing is, β, the Type II statistical error rate. This is the case where we accept or fail to reject a null hypothesis based on our data, but in the reference population, the situation is that indeed, the null hypothesis is actually false. We must also keep in mind that, as we evaluate the p-value relative to the magnitude of the Type I error rate, and if we reject the null hypothesis, we still do not say that we have evidence for the alternative hypothesis.
Thus, we end with a concept that may take you a while to come to terms with — there are four, not two possible outcomes of an experiment.
Outcomes of an experiment
What are the possible outcomes of a comparative experiment\? We have two treatments, one in which subjects are given a treatment and the other, subjects receive a placebo. Subjects are followed and an outcome is measured. We calculate the descriptive statistics aka summary statistics, means, standard deviations, and perhaps other statistics, and then ask whether there is a difference between the statistics for the groups. So, two possible outcomes of the experiment, correct\? If the treatment has no effect, then we would expect the two groups to have roughly the same values for means, etc., in other words, any difference between the groups is due to chance fluctuations in the measurements and not because of any systematic effect due to the treatment received. Conversely, then if there is a difference due to the treatment, we expect to see a large enough difference in the statistics so that we would notice the systematic effect due to the treatment.
Actually, there are four, not two, possible outcomes of an experiment, just as there were four and not two conclusions about the results of a clinical assay. The four possible outcomes of a test of a statistical null hypothesis are illustrated in Table 1.
Table 1. When conducting hypothesis testing, four outcomes are possible.
| HO in the population | |||
| True | False | ||
| Result of statistical test | Reject HO | Type I error with probability equal to
α (alpha) |
Correct decision, with probability equal to
1 – β (1 – beta) |
| Fail to reject the HO | Correct decision with probability equal to
1 – α (1 – alpha) |
Type II error with probability equal to
β (beta) |
|
In the actual population, a thing happens or it doesn’t. The null hypothesis is either true or it is not. But we don’t have access to the reference population, we don’t have a census. In other words, there is truth, but we don’t have access to the truth. We can weight, assigned as a probability or p-value, our decisions by how likely our results are given the assumption that the truth is indeed “no difference.”
If you recall, we’ve seen a table like Table 1 before in our discussion of conditional probability and risk analysis (Chapter 7.3). We made the point that statistical inference and the interpretation of clinical tests are similar (Browner and Newman 1987). From the perspective of ordering a diagnostic test, the proper null hypothesis would be the patient does not have the disease. For your review, here’s that table (Table 2).
Table 2. Interpretations of results of a diagnostic or clinical test.
| Does the person have the disease\? | |||
| Yes | No | ||
| Result of the diagnostic test |
Positive | sensitivity of the test (a) | False positive (b) |
| Negative | False negative (c) | specificity of the test (d) | |
Thus, a positive diagnostic test result is interpreted as rejecting the null hypothesis. If the person actually does not have the disease, then the positive diagnostic test is a false positive.
Questions
- Match the corresponding entries in the two tables. For example, which outcome from the inference/hypothesis table matches specificity of the test \?
- Find three sources on the web for definitions of the p-value. Write out these definitions in your notes and compare them.
- In your own words distinguish between the test statistic and the critical value.
- All of our discussions have been about testing the null hypothesis, about accepting or rejecting, provisionally, the null hypothesis.
- What are the p-values for -logP of 5, 6, 7, 8, 9, and 10 \? Complete the p-value -logP transform table.
- Instead of log10 transform, create a similar table but for negative natural log transform. Which is more convenient? Hint:
log(x, base=exp(1))
Quiz Chapter 8.1
The null and alternate hypothesis
Chapter 8 contents
6.4 – Types of probability
Introduction
By probability, we mean a number that quantifies the uncertainty associated with a particular event or outcome. If an outcome is certain to occur, the probability is equal to 1; if an outcome cannot happen, the probability is equal to zero. Most events we talk about in biology have probability somewhere in between.
A basic understanding, or at least an appreciation for probability is important to your education in biostatistics. Simply put, there is no certainty in biology beyond simple expectations like Benjamin Franklin’s famous quip about “death and taxes…”
Discrete probability
You are probably already familiar with discrete probability. For example, what is the probability that a single toss of a fair coin will result in a “heads?” The outcomes of the coin toss are discrete, categorical, either “heads” or “tails.”
Note 1: Obviously, this statement assumes a few things — coin tossed not in a vacuum, for example. We assume a fair coin — equal chance heads or tails. Fair coins have two sides; tossing a coin we expect “heads” or “tails,” but rarely, some coin types may land and come to rest on edge or side (eg, USA nickels). We still consider the coin toss having binary outcomes, by definition, even though a coin may land on edge about one toss in six thousand (Murray and Teare 1993) because the exception is extremely rare. h/t Dr. Jerry Coyne.
And for ten tosses of the coin? And more cogently, what is the probability that you will toss a coin ten times and get all ten “heads?” While different in tone, these are discrete outcomes. An important concept is independence. Are the multiple events independent? In other words, does the toss of coin on the first attempt affect the toss of the coin on the second attempt and so on up to the tenth toss? At least in principle the repeated tosses are independent so to find the probability you just multiply each event’s probability to get the total.
In contrast, if one or more events are not independent but somehow influence the behavior of the next event, then you add the probabilities for each dependent event. We can do better than simply multiply or add events one at a time; depending on the number of discrete outcomes it is very likely that someone has already calculated all possible outcomes and come up with an equation. In the case of the tossing of two coins this is a binomial equation problem and repeat tosses can be modeled by use of the Bernoulli distribution.
Now, try this on for size. What is the probability that the next child born at Kapiolani Medical Center in Honolulu will be assigned female?
We just described a discrete random variable, which can only take on discrete or “countable” numbers. This distribution of values is the probability mass function. The probability of a one fatal airline accident in a year exactly on 20.1 is practically zero (the area under a point along the curve is zero), so we can get the probability of a range of values around the point as our answer.
Continuous probability
Many events in biology are of degree, not kind. It is kind of awkward to think about it, but for a sample of adult house mice drawn from a population, what is the probability of obtaining a mouse that is 20.0000 grams (g) in weight? Each possible value of body mass for a mouse is considered an event, just like in our example of tossing a coin. But clearly, we don’t expect to get a lot of mice that are exactly 20.0000 g in weight. For variables like body mass, the type of data we collect is continuous, and the probability values need to be rethought along a continuum of possible values and, in turn, how likely each value is for a mouse. Although it is theoretically possible that a mouse could weigh ten pounds, we know by experience that this is impossible. Adult mice weigh between 15 and 50 g or there about.
We just described a continuous random variable, which can take on any value between a specific interval of values. This distribution of values is the probability density function (PDF). The probability of a mouse’s weight falling exactly on 20.1 is practically zero (the area under a point along the curve is zero), so we can get the probability of a range of values around the point as our answer.
In statistical inference, following our measurements of the variables from our sample drawn from a population, we make conclusions with the following kind of caveat: “the mean body mass for this strain of mouse is 20 g.” That is our best estimate of the mean (middle) for the population of mice, more specifically, for the body mass of the mice. Here, the variable body mass is more formally termed a random variable. This implies that there is in fact a true population mean body mass for the mice and that any deviations from that mean are due to chance.
In statistics we don’t settle for a single point estimate of the population mean. You will find most reporting of estimates of random variables is accompanies by a statement like, the mean was 20g with a 95% probability that the true population mean is between 18.9 and 21 g. This is called the 95% confidence interval for the mean and it takes into account how good of an estimate our sample is likely to be relative to the true population value. Not only are we saying that we think the population mean is 20g, but we’re willing to say that we are 95% certain that the true value must be between a lower limit (18.9 g) and and upper limit (21 g). In order to make this kind of statement we have to assume a distribution that will describe the probability of mouse weights. For many reasons we usually assume a normal distribution. Once we make this assumption we can calculate how probable a particular weight is for a mouse.
We introduced how to calculate Confidence Intervals in Chapter 3.4 and will extend this in any chapter that introduces an estimation.
Types of probability
To begin refining our concept of probability, it is sometimes useful to distinguish among kinds of probabilities:
- between theoretical and empirical;
- between subjective and objective.
In most cases, including your statistics book, we would begin our discussion of probability by talking of some probabilities for events we’re familiar with.
- The theoretical probability of heads appearing the next time you flip a fair coin is 1/2 or 50%. As long as we’re talking about a fair coin, the probability of a heads appearing each time you flip the coin remains 50%. We can check this by conducting and experiment: out of 10 tosses, how many heads appear? The answer would be an empirical probability, and we understand the chance in an objective manner (no interpretation needed).
- The theoretical probability that a “5” will appear on the face of a fair dice after a toss is 1/6 or 16.667%. Again, as long as we’re talking about a fair dice, the probability of a “5” appearing each time you roll the dice remains 16.667%.
- The probability that at birth, a human baby’s sex will be male about 1/2 or 50%. This is an empirical probability based on millions of observations. Changes in technology, and ethical standards notwithstanding, the probability will remain the same.
- The probability of the birth of a Downs syndrome baby is 1/800, but increases with age until by age 45, the chance is 1/12. Again, these are empirical and objective.
- The probability of winning the Publisher’s Clearing House Sweepstakes is about 1 in 100 million. This probability is theoretical, it is also objective; however, by adding lots of twists to the game, by having multiple opportunities and by giving the appearance that a person must purchase a magazine, some players perceive their chances as increasing or decreasing by their efforts (=subjective).
R and distributions
R offers access to many named distributions. R generally provides four functions available for each.
density (d):the probability density function (PDF) for continuous distributions or the probability mass function (PMF) for discrete distributions.
probability (p): the cumulative distribution function (CDF), which is the chance (probability) of a random variable being less than or equal to a given value
quantile (q): the quantile function (inverse CDF), which returns the value at a given probability
r: draw random numbers from the specified distribution.
Examples of functions for the normal distribution then, are: dnorm(), pnorm(), qnorm(), and rnorm().
Coding example: Find the PDF for x = 0 in a standard normal distribution. # Find the PDF value for x = 0 in a standard normal distribution (mean=0, sd=1)
dnorm(x = 0, mean = 0, sd = 1)
R output
0.398942280401433
Thus, we conclude the chance that x = 0 is about 40%.
Note 2: Technically it’s not the chance that x is exactly 0 — it refers to the chance that the random variable falls within fractionally small interval around that value. That’s the calculus foundation for probability speaking.
Coding example: Find the probability that for x is equal to -1.2 or less in a standard normal distribution.
pnorm(q = -1.2, mean = 0, sd = 1, lower.tail = TRUE)
R output
0.115069670221708
Thus, we conclude the chance that x is equal to or less than -1.2 is about 11.5%.
Coding example: Assuming normal distribution of test scores, what score will 50% of students score? Find the probability that for x is equal to -1.2 or less in a standard normal distribution.
qnorm(0.5, mean = 75, sd = 10)
R output
75
As expected, at 50% it returns the mean. Now, confirm that the lower 25% and upper 75% are 68.26 and 81.75, respectively.
Last coding example, draw random sample of three scores from the same exam.
rnorm(3, mean = 75, sd = 10)
R output
-
66.0384856946112
-
69.1887923903669
-
77.6342297053815
R Commander: Distributions menus give four options
- Quantiles
- Probabilities
- Plot
- Sampling
Note 3: Looking for more examples? These kinds of problems are common skill-based questions one finds in any statistics course. Homework 3: Distributions & Probability in Mike’s Workbook for Biostatistics offers several additional examples to work through. Additional examples are provided in Chapter 6.5 and Chapter 6.6.
Questions
1. Define and distinguish, with examples
- discrete and continuous probability
- theoretical and empirical probability
- subjective and objective probability
Quiz Chapter 6.4
Types of probability
Chapter 6 contents
- Introduction
- Some preliminaries
- Ratios and proportions
- Combinations and permutations
- Types of probability
- Discrete probability distributions
- Continuous distributions
- Normal distribution and the normal deviate
- Moments
- Chi-square distribution
- t distribution
- F distribution
- References and suggested readings