3.3 – Measures of dispersion
More about summary statistics.
The statistics of data exploration involve calculating estimates of the middle, central tendency, and the variability, or dispersion, about the middle. Statistics about the middle were presented in the previous section, Chapter 3.1. Statistics about measures of dispersion, and how to calculate them in R, are presented in this page. Use of Z score to standardize or normalize scores is introduced. Statistical bias is also introduced.
Describing the middle of the data gives your reader a sense of what was the typical observation for that variable. Next, your reader will want to know something about the variation about the middle value — what was the smallest value observed? What was the largest value observed? Were data widely scattered or clumped about the middle?
Measures of dispersion or variability are descriptive statistics used to answer these kinds of questions. Variability statistics are very important and we will use them throughout the course. A key descriptive statement of your data, how variable?
Note 1: Data is plural = a bunch of points or values; datum is the singular and rarely used.
Examine the two figures below (Fig 1 and Fig 2): the two sample frequency distributions (put data into several groups, from low to high, and membership is counted for each group) have similar central tendencies (mean), but they have different degrees of variability (standard deviation).
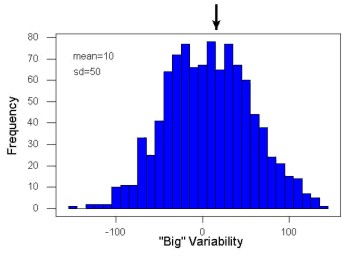
Figure 1. A histogram which displays a sampling of data with a mean of 10 (arrow marks the spot) and standard deviation (sd) of 50 units.
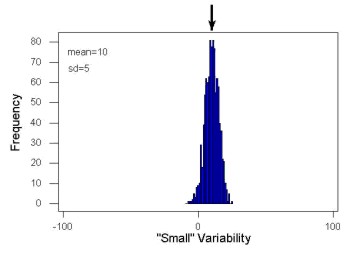
Figure 2. A histogram which displays a sampling of data with the same mean of 10 (arrow marks the spot) displayed in Fig. 1, but with a smaller standard deviation (sd) of 5 units.
Clearly, knowing something about the middle of a data set is only part of the required information we need when we explore a data set; we need measures of dispersion as well. Provided certain assumptions about the frequency of observations hold, estimates of the middle (eg, mean, median) and the dispersion (eg, standard deviation) are adequate to describe the properties of any observed data set.
For measures of dispersion or variability, the most common statistics are: Range, Mean Deviation, Variance, Standard Deviation, and Coefficient of Variation.
The range.
The range is reported as one number, the difference between maximum and minimum values.
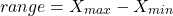
Arrange the data from low to high, subtract the minimum, Xmin, from the maximum, Xmax, value and that’s the range.
For example, the minimum height of a collection of fern trees might be 1 meter whereas the maximum height might be 2.2 meters. Therefore, the range is 1.2 meters (= 2.2 – 1).
The range is useful, but may be misleading (as index of true variability in population) if there is one or more exceptional “outlier” (one individual that has an exceptionally large or small value). I often just report Xmin and Xmax. That’s the way R does it, too.
If you recall, we used the following as an example data set.
x = c(4,4,4,4,5,5,6,6,6,7,7,8,8,8,15)The command for range in R is simply range().
range(x)
[1] 4 15
There is apparently no universally accepted symbol for “range,” so we report the statistic as range = 15 – 4 = 11.
You may run into an interquartile range, which is abbreviated as IQR. It is a trimmed range, which means, like the trimmed mean, it will be robust to outlier observations. To calculate this statistic, divide the data into fourths, termed quartiles. For our example variable, x, we can get the quartiles in R
quantile(x)
  0%  25%  50%  75% 100%
 4.0  4.5  6.0  7.5 15.0
Thus, we see that 25% of the observations are 4.5 (or less), the second quartile is the median, and 75% of the observations are less than 7.5. The IQR is the difference between the first quartile, Q1, and the third quartile, Q3.
The command for obtaining the IQR in R is simply IQR(). Yes. You have to capitalize “IQR” — R is case sensitive; that means IqR is not the same as IQR or iqr.
IQR(x)
[1] 3.5
and we report the statistic as IQR = 3.5. Thus, 75% of the observations are within 3.5 points of the median. The IQR is used in box plots (Chapter 4). Quartiles are special cases of the more general quantile; quantiles divide up the range of values into groups with equal probabilities. For quartiles, four groups at 25% intervals. Other common quantiles include deciles (ten equal groups, 10% intervals) and percentiles (100 groups, 1% intervals).
The mean deviation.
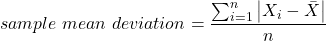
Subtract each observation from the sample mean; each  is called a deviate: some observations will be positive (greater than
 ) and some will be negative (less than ).
Take the absolute value of the deviation and then add up the absolute values of the deviations from the mean. At the end, divide by the sample size, n. Large values for this statistic implies that much of the data is spread out, far from the mean. Small values in turn imply that each observation is close to the mean.
Note 2: The mean deviation will always be positive, which is why we take the absolute. By taking the absolute value of each deviate, then the sum is greater than zero. Now, we rarely use this statistic by itself — but that difference is integral to much of the statistical tests we will use. Look for this difference in other equations!
In R, we can get the mean deviation with the mad() function. At the R prompt, then
mad(x)
[1] 2.9652
Population variance and population standard deviation.
The population variance is appropriate for describing variability about the middle for a census. Again, a census implies every member of the population was measured. Equation of the population variance is
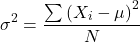
The population standard deviation also describes the variability about the middle, but has the advantage of being in the same units as the quantity (ie, no “squared” term). Equation of the population standard deviation is

Sample variance and sample standard deviation.
The above statements about the population variance and standard deviation hold for the sample statistics. Equation of the sample variance
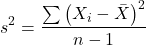
and the equation of the sample standard deviation

Of course, instead of taking the square-root of the sample variance, the sample standard deviation could be calculated directly.
*** QuickLaTeX cannot compile formula:
\begin{align*}s = \sqrt{\frac{\sum \left ( X_{i} - \bar{X} \right )^2}{n-1}\end{align*}

*** Error message:
File ended while scanning use of \align*.
Emergency stop.
n - 1 instead of N. This is Bessel’s correction and we will take a few moments here and in class to show you why this correction makes sense. Bessel’s correction to the sample variance illustrates a basic issue in statistics: when estimating something, we want the estimator (ie, the equation), to be an unbiased value for the population parameter it is intended to estimate.Statistical bias is an important concept in its own right; bias is a problem because it refers to a situation in which an estimator consistently returns a value different from the population parameter for which it is intended to estimate. Thus, the sample mean is said to be an unbiased estimator of the population mean. Here, bias means that the formula will give you a good estimate of the value. This turns out not to be the case for the sample variance if you divide by n instead of n - 1. Now, for very large values of n, this is not much of an issue, but it shows up when n is small. In R you get what you ask for — if you ask for the sample standard deviation, the software will return the correct value; calculators, go to watch out for this — not all of them are good at communicating which standard deviation they are calculating, the population or the sample standard deviation.
Winsorized variances.
Like the trimmed mean and winsorized mean (Ch3.2), we may need to construct a robust estimate of variability less sensitive to extreme outliers. Winsorized refers to procedures to replace extreme values in the sample with a smaller value. As noted in Chapter 3.2, we chose the level ahead of time, eg, 90%. Winsorized values then The winsorized variance is just the sample variance of the winsorized values. winvar() from the WRS2 package.
Making use of the sample standard deviation.
Given an estimate of the mean and an estimate of the standard deviation, one can quickly determine the kinds of observations made and how frequently they are expected to be found in a sample from a population (assuming a particular population distribution). For example, it is common in journal articles for authors to provide a table of summary statistics like the mean and standard deviation to describe characteristics of the study population (aka the reference population), or samples of subjects drawn from the study population (aka the sample population). The CDC provides reports of attributes of for a sample of adults (more than forty thousand) from the USA population (Fryar et al 2018). Table 1 shows a sample of results for height, weight, and waist circumference for men aged 20 – 39 years.
Table 1. Summary statistics mean ( standard deviation) of height, weight, and waist circumference of 20-39 year old men USA.
| Years | Height, inches | Weight, pounds | Waist Circumference, inches |
|---|---|---|---|
| 1999 – 2000 | 69.4 (0.1) | 185.8 (2.0) | 37.1 (0.3) |
| 2007 – 2008 | 69.4 (0.2) | 189.9 (2.1) | 37.6 (0.3) |
| 2015 – 2016 | 69.3 (0.1) | 196.9 (3.1) | 38.7 (0.4) |
We introduced the normal deviate as a way to normalize scores, and which we we will use extensively in our discussion of the normal distribution in Chapter 6.7, as a way to standardize a sample distribution, assuming a normal curve.

For data that are normally distributed, the standard deviation can be used to tell us a lot about the variability of the data:
62.26% of the data will lie between  of
95.46% of the data will lie between  of
99.0% of the data will lie between  of
This is known as the empirical rule, where 68% of the observations will be within one standard deviation, 95% of observations will be within two standard deviations, and 99% of observations will be within three standard deviations.
For example, men aged 20 years in the USA are on average μ = 5 feet 11 inches tall, with a standard deviation of σ = 3 inches. Consider a sample of 1000 men from this population. Assuming a normal distribution, we predict that 623 (62.26%) will be between 5 ft. 8 in. and 6 ft. 2 in. ( ).
Where did the 5 ft. 8 in. and the 6 ft. 2 in. come from /? We add or subtract multiples of standard deviations. Thus, 6 ft. 2 in. = 5 ft. 11 in.  (replace σ = 3) and 5 ft. 8 in. = 5 ft. 11 in.
 (again, replace σ = 3″).
Can generalize to any distribution. Chebyshev’s inequality (or theorem) guarantees that no more than a particular fraction  of observations can be a specified
 standard deviations distance away from the mean ( needs to be greater than 1). Thus, for
 standard deviations, we expect a minimum of 75% of values within (
 ) two standard deviations away from the mean, or for
 , then 89% of values will be within (
 ) three standard deviations from the mean.
Hopefully you are now getting a sense how this knowledge allows you to plan an experiment.
For example, for a sample of 1000 observations of height of men, how many do we expect to be greater than 6 ft. 7 in. tall? Apply the empirical rule and do a little math — 79 inches (6 ft. 7 in) minus 71 inches (the mean) is equal to 8. Divide 8 by 3 (our value of  ) you’ll get 2.66667; so, 6 ft. 7 in. tall is about 2.67 X standard deviations greater than the mean. From Chebyshev’s inequality we have
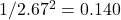 , or 14% of observations less than or greater than the mean (
 ).
Our question asks only about expected number of observations greater than  ; divide 14% in half — we therefore expect about 70 individuals out of 1000 men sampled to be 6 ft. 7 in. or taller. Note we made no assumption about the shape of the distribution. If we assume the sample of observations comes from the normal distribution, then we can apply the Z score: about 4 individuals out of 1000 expected to be from the mean (see R code in Note box). We extend the Z-score work in Chapter 6.7.
Note 4: R code:
round(1000*(pnorm(c(79), mean=71, sd=3,lower.tail=FALSE)),0)
or alternatively
round(1000*(pnorm(c(2.67), mean=0, sd=1,lower.tail=FALSE)),0)
R output
[1] 4
R Commander command
Rcmdr: Distributions → Continuous distributions → Normal distribution → Normal probabilities …, select Upper tail.
Another example, this time with a data set available in R, the diabetic retinopathy data set in the survival package.
data(diabetic, package="survival")
Ages of the 394 subjects ranged from 1 to 58. Mean was 20.8 + 14.81 years. How many out of 100 subjects do we expect greater than 50 years old? With Chebyshev’s inequality we have 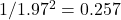 , or 25.7% of observations less than or greater than the mean, so about 13. If we assume normality, then Z score (Upper tail) is 28.5% and we expect 28 subjects older than 50. Checking the data set, only eight subjects were older than 50. Our estimate by Chebyshev’s inequality was closer to the truth. Why /? Take a look at the histogram (Ch4) of the ages (Fig 3).
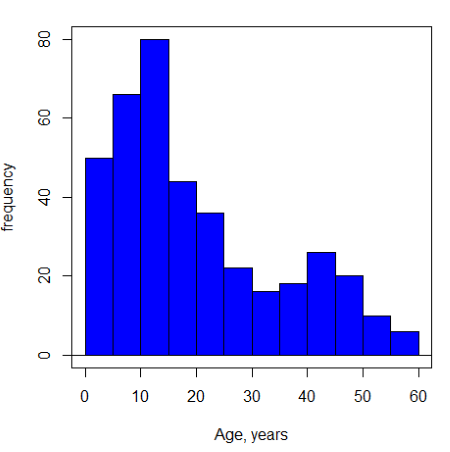
Figure 3. Histogram of ages of subjects in the diabetic retinopathy data set in the survival package.
Doesn’t look like a normal distribution, does it/?.
Z-score or Chebyshev’s inequality, which to use /? Chebyshev’s inequality is more general — it can be used whether the variables is discrete or continuous and without assumption about the distribution. In contrast, the Z score assumes more is known about the variable: random, continuous, drawn from a normally distributed population. Thus, as long as these assumptions hold, the Z score approach will give a better answer. Makes intuitive sense — if we know more, our predictions should be better.
In summary from the above points, and perhaps more formally for our purposes, the standard deviation is a good statistic to describe variability of observations on subjects, it’s integral to the concept of precision of an estimate and is part of any equation for calculating confidence intervals (CI). For any estimated statistic, a good rule of thumb is to always include a confidence interval calculation. We introduced these intervals in our discussion of risk analysis (approximate CI of NNT), and we will return to confidence intervals more formally when we introduce t-tests.
When you hear people talk about “margin of error” in a survey, typically they are referring to the standard deviation — to be more precise, they are referring to a calculation that includes the standard deviation, the standard error and an accounting for confidence in the estimate (see also Chapter 3.5 – Statistics of error).
Corrected Sums of Squares.
Now, take a closer look at the sample variance formula. We see a deviate

The variance is the average of the squared deviations from the mean. Because of the “squared” part, this statistic will always be positive and greater (or typically, equal to) zero. The variance has squared units (eg, if the units were grams, then the variance units are grams2). The sample standard deviation has the same units as the quantity (ie, no “squared” term). The numerator is called a sums of squares, and will be abbreviated as SS. Much like the deviate, will show up frequently as we move forward in statistics (eg, it’s key to understanding ANOVA).
Other standard deviations of means.
Just as we discussed for the arithmetic average, there will be corresponding standard deviations for the other kinds of means. With the geometric mean, one would calculate the standard deviation of the geometric mean, sgm, as
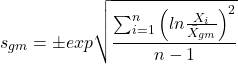
where exp is the exponential function, ln refers to natural logarithm, and  refers to the sample geometric mean.
For the sample harmonic mean, it turns out there isn’t a straight-forward formula, only an approximation (which I will spare you — it involves use of expectations and moments).
Base R, and therefore Rcmdr, doesn’t have built in functions for these, although you could download and install some R packages which do (eg, package NCStats, and the function is geosd() ).
If we run into data types appropriate for the geometric or harmonic means and standard deviations I will point these out; for now, I present these for completeness only.
Coefficient of variation (CV).
An unfortunate property of the standard deviation is that it is related (= “correlated”) to the mean — a fact recognized by Pearson (1896, p 276). Thus, if the mean of a sample of 100 individuals is 5 and variability is about 20%, then the standard deviation is about 1; compare to a sample of 100 individuals with mean = 25 and 20% variability, the standard deviation is about 5. For means ranging from 1 to 100, here’s a plot to show you what I am talking about.
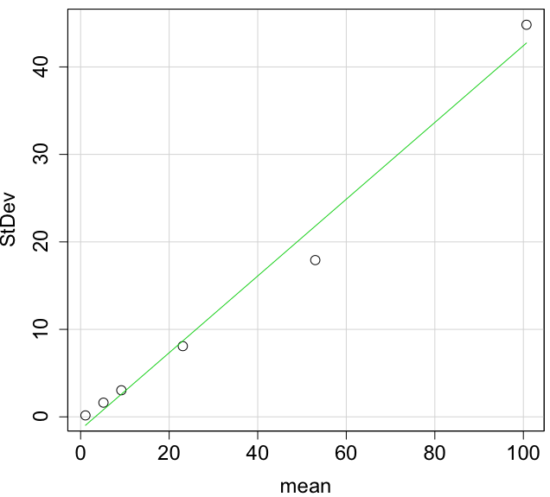
Figure 4. Scatter plot of the standard deviation (StDev) by the mean. Data sets were simulated.
The data presented in the Figure 4 graph were simulated. Is this bias, a correlation between mean and standard deviation, something you’d see in “real” data? Here’s a plot of height in inches at withers for dog breeds (Fig 5). A line is drawn (ordinary linear regression, see Chapter 17) and as you can see, as the mean increases, the variability as indicated by the standard deviation also increases.
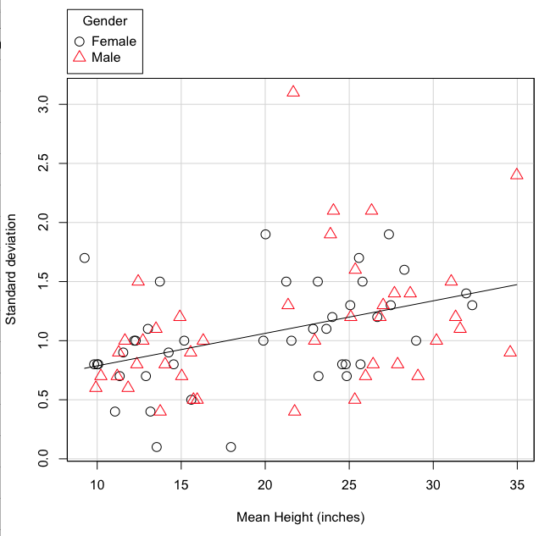
Figure 5. Plot of the standard deviation by the mean for heights of different breeds of dogs.
So, to compare variability estimates among groups when the means also vary, we need a new statistic, the coefficient of variation, abbreviated CV (Pearson 1896). The coefficient of variation is also known as the relative standard deviation, RSD. Many statistics textbooks not aimed at biologists do not provide this estimator (eg, check your statistics book).
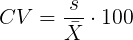
This is simply the standard deviation of the sample divided by the sample mean, then multiplied by 100 to give a percent. The CV is useful when comparing the distributions of different types of data with different means.
Many times, the standard deviation of a distribution will be associated with the mean of the data.
Example. The standard deviation in height of elephants will be larger on the centimeter scale than the standard deviation of the height of mice. However, the amount of variability RELATIVE to the mean may be similar between elephants and mice. The CV might indicate that the relative variability of the two organisms is the same.
The standard deviation will also be influenced by the scale of measurement. If you measure on the mm scale versus the meter scale the magnitude of the SD will change. However, the CV will be the same!
By dividing the standard deviation by the mean you remove the measurement scale dependence of the standard deviation and generally, you also remove the relationship of the standard deviation with the mean. Therefore, CV is useful when comparing the variability of the data from distributions with different means.
One disadvantage is that the CV is only useful for ratio scale data (ie, those with a true zero).
The coefficient of variation is also one of the statistics useful for describing the precision of a measurement. See Chapter 3.4 Estimating parameters.
Standard error of the mean (SEM).
All estimates should be accompanied by a statistic that describes the accuracy of the measure. Combined with the confidence interval (Chapter 3.4), one such statistic is called the standard error of the mean, or SEM for short. For the error associated with calculation of our sample mean, it is defined as the sample standard deviation divided by the square root of n, the sample size.
sem → 
The concept of error for estimates is a crucial concept. All estimates are made with error and for many statistics, a calculation is available to estimate the error (see Chapter 3.4).
Although related to each other, the concepts of sample standard deviation and sample standard error have distinct interpretations in statistics. The standard deviation quantifies the amount of variation of observations from the mean, while the standard error quantifies the difference between the sample mean and the population mean. The standard error will always be smaller than the standard deviation and is best left for reporting accuracy of a measure and statistical inference rather than description.
Questions.
- For a sample data set like
myY <- c(1,1,3,6), you should now be able to calculate, by hand, the
• range
• mean
• median
• mode
• standard deviation
• coefficient of variation - For our example data set,
myX <- c(4,4,4,4,5,6,6,6,7,7,8,8,8,8,8)calculate
• IQR
• sample standard deviation, s
• coefficient of variation - Use the
sample()command in R to draw samples of size 4, 8, and 12 from your example data set stored inmyX. Repeat the calculations from question 4. For examplex4 <- sample(x,4)will randomly select four observations from x, and will store it in the object x4, like so (your numbers probably will differ!)x4 <- sample(x,4); x4 [1] 8 6 8 6 - Repeat the exercise in question 4 again using different samples of 4, 8, and 12. For example, when I repeat sample(
x,4) a second time I getsample(x,4) [1] 8 4 8 6 - For Table 1, determine how many multiples of the standard deviation for observations greater than 95-percentile (eg, determine the observation value for a person who is in the 95-percentile for Height in the different decades, etc.
- Calculate the sample range, IQR, sample standard deviation, and coefficient of variation for the following data sets
• Height in inches of mothers,mom <- c(67, 66.5, 64, 58.5, 68, 66.5) #(data from GaltonFamilies in R package HistData)
and fathers,dad <- c(78.5, 75.5, 75, 75, 74, 74) #(data from GaltonFamilies in R package HistData)
• Carbon dioxide (CO2) readings from Mauna Loa for the month of December for
years <-c (1960, 1965, 1970, 1975, 1980, 1985, 1990, 1995, 2000, 2005, 2010, 2015, 2020)years <-c (1960, 1965, 1970, 1975, 1980, 1985, 1990, 1995, 2000, 2005, 2010, 2015, 2020) #obviously, do not calculate statistics on years; you can use to make a plotco2 <- c(316.19, 319.42, 325.13, 330.62, 338.29, 346.12, 354.41, 360.82, 396.83, 380.31, 389.99, 402.06, 414.26) #(data from Dr. Pieter Tans, NOAA/GML (gml.noaa.gov/ccgg/trends/) and Dr. Ralph Keeling, Scripps Institution of Oceanography (scrippsco2.ucsd.edu/))
• Body mass of Rhinella marina (formerly Bufo marinus) (see Fig. 1),bufo <- c(71.3, 71.4, 74.1, 85.4, 85.4, 86.6, 97.4, 99.6, 107, 115.7, 135.7, 156.2)
Quiz – Chapter 3.3
Measures of dispersion
Chapter 3 contents
2.2 – Why do we use R Software?
- Why R? The case for using R in biostatistics education.
- How to get started with R .
- Why R Commander, why not RStudio? .
- Wait! Why don’t we use Microsoft Excel? .
- Statistics comparisons between R and MS Excel .
- Graphics comparison between R and MS Excel .
- So, you’re telling me I don’t need a spreadsheet application? .
- Still not convinced? .
- Why install R on your computer?.
- Help with R?.
- Questions .
- Quiz .
- Chapter 2 contents.
If this page is TL;DR, and you’re in a rush, then instructions to install R onto your macOS or Windows PC are provided in Install R. To run in the cloud only, see Use R in the cloud.
Why R? The case for using R in biostatistics education.
.
Why do we use R Software? Or put another way: DrD, Why are you making me use R?
Truth? You can use just about any acceptable statistical application to get the work done and achieve the learning objectives we have for beginning biostatistics. However, we will use the R statistical language as our primary statistical software in this course. Part of the justification is that all statistical software applications come with a learning curve, so you’d start at zero regardless of which application I used for the course.
In selecting software for statistics I have several criteria. The software should be:
- if not exactly easy, the software should have a reasonable learning curve
- widely accessible and compatible with
allmost personal computers - well-respected and widely used by professionals
- free software
- open source
- well-supported for the purposes of data analysis and data processing
- really good for making graphics, from the basics to advanced
- capable to handle diverse kinds of statistical tests
R meets all of these criteria. R history began back in 1993 and has always been available as free software under the terms of the Free Software Foundation’s GNU General Public License in source code form. R compiles and runs on a wide variety of UNIX platforms and similar systems, including GNU/LINUX, FreeBSD, and various Linux distros like the popular Ubuntu®, in addition to their more famous Microsoft Windows® and Apple macOS® distributions. To facilitate access to the software, numerous mirror sites are available from sites around the world, with cloud.r-project.org supported by RStudio perhaps the most widely used. From January 2024 to December 2024, more than 8.5 million downloads of base R were made from the RStudio CRAN mirror site (CRAN stands for Comprehensive R Archive Network.
changelog file, which allow one to track numbers of downloads for any package from their mirror site — https://cloud.r-project.org/. Here’s the code and recent counts for downloads of R itself over a four week period .
install.packages("cranlogs")
library(cranlogs)
# How many downloads of base R around start of Fall semester?
 out <- cran_downloads("R", from = "2025-08-01", to = "2025-08-31")
sum(out$count)
R output
[1] 582524
An iterative function returning number of downloads over multiple years is provided at Part05 of Mike’s Workbook for Biostatistics.
R is straightforward to use once you learn how to work with the language, but has a steep learning curve; after all, it’s a programming language. I recommend installing the program onto your computer, but ready to go R is also available at multiple cloud services, including Google CoLab and Posit Cloud. The remainder of this page is directed at users who choose to install R to their computer, although much of the discussion holds regardless of the R environment choice, local or Cloud.
For local installs of R, I also recommend use of the GUI R Commander. Use of R Commander helps with the learning curve, and eventually, your use of code will become second nature. We don’t use RStudio, but as your skills improve, I recommend transitioning to the IDE RStudio; after the initial growing pains are behind you, RStudio likely will be a better solution over R Commander.
This discussion implies learning R programming. However, while we need statistical software to do statistics, students in my BI311 course must keep in mind that learning objectives for a biostatistics course is about the concepts and interpretation of statistics, not just use of the software. In other words, learning how to use R is not the focus of BI311 nor will you likely achieve R programming competency by the end of the semester. I certainly encourage students to strive for competency and I give frequent bonus opportunities to demonstrate coding skills during the semester.
Why R and not some other statistics software?
Thus, you might ask if the purpose of the course isn’t to learn R, why work with R instead of a more familiar app or software, eg, Microsoft Excel® (hereafter simply referred to as Excel), or Google Sheets, or even my favorite open-source office alternative, LibreOffice Calc? Or, perhaps even just one of the many online calculators, if the course learning objective is to “just” learn about statistics?
First, I believe that real data derived from real biology or biomedical problems are essential elements to a first course in biostatistics. That’s not a particularly unique perspective although I don’t have survey results of other statistics instructors to back up the claim. Real problems involve observations on multiple subjects, many variables — large data sets; this alone precludes use of hand calculations and calculators. As a corollary, we will not spend a great deal of time learning the in’s and out’s of the algorithms that form particular statistical tests. Now, do understand that there is a tremendous benefit to understanding statistics by working through the equations, by looking at the algorithms, and there’s no escaping the need for understanding that probability provides the foundation of statistics inference (Chapter 8). Thus, for most of us, the statistical software available to us provides an appropriate framework for applying correct statistical tests to our projects. Therefore, the decision is about which statistical package we should use.
Second, R is perhaps the choice in academia for statistical software. A PUBMED search found more than 1500 citations of R. Visit Robert A. Muenchen’s web page (The popularity of data analysis software, r4stats.com) to see updated statistics on statistical software use. Those of you continuing on to graduate school or to professional schools will find that many of your statistically literate colleagues use R and not one of the commercial programs. While there are many excellent commercial packages (Table 1), and in some cases you can make spreadsheet programs do statistics (typically add-ins are required), all statistical software come with steep learning curves. Thus, part of my selling point to you is that learning to use R is at the cutting-edge in your field and, given that all of the software you could use can have have their challenges, it is best to work with something that will be around and is in wide use, without the burden of a financial investment.
Table 1. A selective list of statistical software.
| Software | Student license? | Limited or full function version | macOS | Windows 11 | Fee* | Academic license type |
|---|---|---|---|---|---|---|
| GraphPad Prism | Subscription, $142 per year | Full | Yes | Yes | $202 | annual subscription |
| JMP | Yes, but with purchase of selected textbook | Limited | Yes | Yes | $100 | monthly subscription |
| Minitab | Subscription, $54.99 per year | Full | Yes | Yes | $1610 | annual subscription |
| IBM SPSS | Rental, $76 per year | Full | Yes | Yes | $260 | annual rental |
| SigmaSTAT | No | NA | No | Yes | $299 | perpetual |
| MySTAT | Yes, free | Limited | No | Yes | NA | |
| SYSTAT | No | NA | No | Yes | $739 | perpetual |
| Stata | Subscription, $94 per year | Full | Yes | Yes | $325 | annual subscription |
see Wikipedia for list of additional software
Third, what about online sites like plot.ly where, for free, you can plot and, in some cases, calculate statistics? What about the web application at Brightstat, which claims to provide an SPSS-like experience online (Stricker 2008)? While it is true that there are many wonderful websites that can perform many of the statistical tests we will use this semester, these sites are not suitable for more than occasional use.
How to get started with R.
.
A few words about my approach to the software in my biostatistics course. I note to students during the semester that our course is not a programming course, but rather, programming skills are acquired along the way. Our focus is how to do statistical analysis, how to design experiments, etc. Coding skills without understanding of the why we’re doing it is not unlike learning to cook by following a great recipe as opposed to learning about the art and science of flavor (NPR Science Friday, March 15, 2024) — the homework is solved but the why we can support our conclusions may be obscure.
We set aside the first couple of class meetings simply to setup student’s Windows PC or Apple macOS computers to do data science; for students with access to Chromebooks or iPad tablets, we need to set them up to run R in the Cloud (eg., Google Colaboratory) — in other words, there’s a lot of pre-work that can present barriers to actual doing statistics in R (or other software). Once we have the environment set up for the students, we utilize a “tell-show-do” approach to learning how to code. The “tell” part includes sharing script; the “do” part is mostly done by students outside of class as part of completing homework.
First work with the language can be frustrating, so I also encourage a “five minute” rule — if it ain’t working, stop. So, by all means when Run through a troubleshooting checklist, but please don’t continue to struggle — the gap is between the instructions and where the student is with the material — it’s a me-as-instructor problem, not a student must work harder problem!
All statistics work follows a similar workflow.
The basic workflow for a data project, using R as the primary statistical programming tool, looks like that illustrated in Figure 1.

Figure 1. A basic workflow with R.
The workflow begins with the assumption that a data set already exists. Getting the data into an R session depends on the source of the data, for example stored in spreadsheet file or from a table on a webpage. Data cleaning and processing of the data may be in order — for small and modest-sized data sets, my own preference is to do most of the data cleaning in my spreadsheet app, but R has full capabilities to handle or “wrangle” data. Next, the raw data should be stored in R session in a data frame object. Once the data frame object is available, exploratory data analysis, including summary statistics and data visualization can proceed. Higher order analytics, including statistical inference and modeling, can then begin.
The R statistical language, accompanied by additional packages to extend its capabilities beyond basic math and statistical functions, provided a complete statistical environment. R is best viewed as a programming language for statistics (data analysis), and data processing. Power users of R learn how to write scripts that do t-tests, ANOVA, regression, etc. The scripts are just lines of code that R understands and it provides the user tremendous control over analysis and inference of data sets. Because of this flexibility and power, however, R can be intimidating at first. So, we’ll start slowly with scripts, introducing just what we need to get started and build from there. We’ll be addressing R issues in more depth over the next several weeks, but for the first week, our goal(s) should be to make sure each of you knows how to start/exit R, how to create and utilize a working directory, and how to use R as a calculator. You obtain your copy of R from the R Project for Statistical Computing, available at https://www.r-project.org. Instructions to install R are provided in Install R. A ten-part tutorial to get started using R is provided in Mike’s Workbook for Biostatistics.
Note 2. A working directory or working folder is something you create on your computer to contain the files and sub-directories of a project. It sets the default location for files you may need to have R read. For example, all of your work for a course (data files, script files, Markdown files), may be stored in a folder called BI311 on your Desktop. For example, on a macOS, the path to the working folder would be
/Users/username/Desktop/BI311
Why R Commander, why not RStudio?
.
We utilize an R package that provides a menu-driven context to much of the typical statistics one needs to do biostatistics. The package is called R Commander (Rcmdr), which provides a graphic user interface or GUI. Rcmdr therefore significantly eases the learning curve for doing statistics with R. We use a package called R Commander, which provides drop down menus for most of the typical kinds of analyses. Rcmdr is in use in many courses across the world (more than 17K downloads in August 2025), and among the other GUI available for R, Rcmdr is among the best supported GUI available for R. R Commander function is extended by plug-ins; as of August 2025, there were 31 plugins that extend Rcmdr’s capabilities. Instructions to install R Commander are provided in Install R Commander.
Note 3. Other options to improve use of R include use of RStudio®, which is an integrated development environment or IDE. RStudio is really nice to use, and, happily, you can run R Commander within RStudio — but with windows popping up outside of the RStudio windowing framework if the default MDI environment to organize is set. (The solution? R Commander runs best when SDI option is selected during RStudio install.) I am also increasingly using shiny apps within the course to help with concept presentation; in the future, I plan to provide a complete shiny app which would allow BI311 students to work interactively with the statistics presented in this text, something like the radiant-rstats project. However, for use in our course, R Commander provides a familiar look as students develop knowledge in the course: simply point and click to access the statistical functions.
Wait! Why don’t we use Excel? My instructor in {insert course here} used Excel…
.
A very reasonable question for you to ask — why don’t we use Microsoft Excel or Google Sheets for statistics? Moreover, it is highly likely that you have gained at least some introduction to descriptive statistics and graphing with spreadsheets in former courses — shouldn’t we learn statistics within a software framework you are already familiar?
After all, “Can’t Microsoft Excel do statistics?” Mostly the answer is, no, not really (Fig 2).
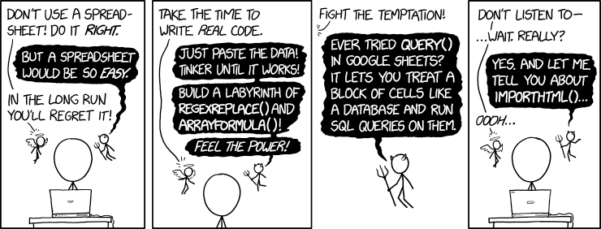
Figure 2. “Spreadsheets,” xkcd.com no. 2180.
MS Excel, Google Sheets, Apple Numbers, and for that matter, Calc, the spreadsheet application in my favorite office app LibreOffice (LibreOffice is a free, open-source alternative to Microsoft Office), can be used to calculate many descriptive statistics. With some effort, these applications can be extended by use of either Analysis ToolPak or Solver Add-ins to do more complicated statistics like regression and analysis of variance, and curve fitting.
Note 4. Perhaps you’re thinking: I’m a data science student — it’s not whether we chose between use of spreadsheet apps or R, we should be using Python, shouldn’t we? DrD — this is an open question, and if you judge the job market as the arbiter, I’d say learn Python over R — if you are primarily aiming for a data science position. However, from the point of view of learning statistics, my vote would be R — far more packages developed to accomplish our tasks, and, at least for this course, we are not teaching coding: our focus is on using statistics to explore (describe) and ask questions about data collected by observation or experimentation.
While we’re on the subject in 2025, it looks like the job market is in Machine Learning, which means R or Python knowledge will be a given, but advantage will go to those who know Alteryx or it’s open source alternative KNIME for data science workflow design — from data collection to model development.
However, use of MS Excel for statistical analysis involves learning a number of commands, syntax, and developing workflows that are neither intuitive nor standard. Some publishers have provided add-ins that are reportedly designed to simplify this process (eg, XLStat, UNISTAT, Real Statistics using Excel). None of these options are free and none are in use in any major way by scientists (see Robert Muenchen’s The popularity of data analysis software). The free add-ins of Analysis ToolPak and Solver may work for you if you own a Windows PC, but only Solver is included for the Mac versions of Excel. MacOS users may download and install StatPlus:MacLE, which is a limited, but free alternative to the Analysis ToolPak add-in; for a complete package a Pro version is available (licenses started at $89, web site: www.analystsoft.com/en/products/statplusmacle/).
An additional caution: you should be aware that there have been reports over the years that algorithms selected by Microsoft for Excel have not always been to industry standards (eg, McCullogh and Wilson 2005). In short, the fit of Excel and other spreadsheet apps for use in statistics is not a simple one. To do the kinds of statistics we will use routinely in class, Excel would need to be modified with add-ins, and the add-ins would be the result of programming by someone. And you would still need to learn how to write the code.
What about graphics? You may like Microsoft Excel’s ability to do graphics. Indeed, Excel, Google Sheets, and LibreOffice Calc can be used to generate many typical kinds of statistical plots. But again, in comparison to R, spreadsheet app graphics are limited and require a deal of effort to generate acceptable plots. I think you’ll be surprised at how straight-forward R is. Here’s an example, first rendered in Microsoft Excel, then in base R. And importantly, the kinds of plots Excel does well at are not necessarily the plots suitable for research publication. For example, Excel allows you to make bar charts easily, but cannot do box plots. Box plots are preferred over bar (column) charts for ratio scale data.
Note 5. base R refers to the core R programming language along with many functions and graphics routines. We extend capabilities of base R by adding packages, like R Commander.
Statistics comparisons between R and MS Excel.
.
About that learning curve. Let’s compare R and MS Excel for basic functions common in data analysis. Similar conclusions hold for comparisons to Google Sheets and LibreOffice Calcs.
Note 6. If you search for variants of this question, you’ll find other’s making the argument that the learning curve for many data science tasks is, perhaps surprisingly, shorter for R than it is for Excel. For example, see Amieroh Abrahams 2023 article at https://www.jumpingrivers.com/blog/comparing-r-excel-data-wrangling/ .
Table 2 lists the observations we can use to conduct comparisons of the applications.
A simple data set
| varA |
|---|
| 12 |
| 14 |
| 20 |
| 25 |
| 28 |
| 29 |
| 32 |
| 34 |
| 35 |
| 39 |
| 47 |
| 47 |
| 50 |
| 53 |
| 54 |
| 71 |
| 79 |
| 87 |
| 89 |
| 96 |
| 105 |
| 122 |
| 130 |
| 132 |
One of the first steps in data analysis is to produce what are called descriptive statistics. Common descriptive statistics are the mean and the sample standard deviation. Let’s compare Excel and R for retrieving these two statistics.
With Excel, to calculate the arithmetic mean of 24 numbers, enter the values into a single column of 24 rows, then enter “=average(A2:A25)“, without the quotes, into a new cell of the spreadsheet. “A2:A25” refers to where data would be contained in column A rows 2 through 25. Typically the first row in a worksheet would contain the name of the variable, eg, “A.” Depending on the significant figures set, the estimate returned by Excel for the mean of A is 59.58333333.
Similarly, to obtain the standard deviation, type =stdev(A2:A25), into a new cell of the spreadsheet. Again, depending on the significant figures set, Excel returns a value of 37.05215674 for the standard deviation of A.
In contrast, to obtain the mean and standard deviation for a variable in an R data set, all you would type at the R prompt (>), or in the script window
Note 7. Always run your code as a script. Entering code at the R prompt means you are working at the command-line interface, and you work one line at a time. This is not an efficient way to interact with R. Instead, I recommend you always create and work from a script document. For beginners, that’s why I recommend R Commander, which includes a script window. Simply type your code in the script window, highlight the code you wish to run, and run by clicking submit button (or Ctrl+R Win11 or Cmd+Enter macOS). When you are ready to move on from R Commander, RStudio is the IDE of choice.
and then submit the code is:
myA <- c(12, 14, 20, 25, 28, 29, 32, 34, 35, 39, 47, 47, 50, 53, 54, 71, 79, 87, 89, 96, 105, 122, 130, 132)where the “c” is a function to combine arguments into a vector and saved to the object myA, followed at the new line by
mean(myA)Hit enter after entering the command) and R returns
[1] 59.58333For the standard deviation, write the R base function sd()
sd(myA)Hit enter after entering the command and R returns
[1] 37.05216It’s not much of a difference, but note that to get the mean (arithmetic average) I typed seven characters in R, but 16 characters in Excel; similarly, for the standard deviation I typed in 5 characters in R, but 13 characters in Excel. That’s a savings of 56% and 62%, respectively. Excel tries to help by using AutoComplete to anticipate what you want to enter, but AutoComplete doesn’t always work properly (eg, see gene name errors generated by use of default Microsoft Excel settings, Ziemann et al 2016).
Note 8. I use spreadsheets all of the time for data entry and data management. Make sure AutoComplete and AutoCorrect options are turned off and these problems are much less.
In conclusion, R is quicker for descriptive statistics.
Graphics comparison between R and MS Excel.
.
MS Excel is often cited for its graphics capabilities (Camões 2016). We can make the familiar scatter plots, bar charts, and pie charts in Excel. These plots and more are easily obtained in R. I won’t elaborate here about graphics, we talk at some length about graphics in Chapter 4. But here’s one example in R.
Let’s plot myB vs myA. We already provided the data for variable A, here’s the data for variable B.
17, 21, 21, 26, 27, 32, 28, 42, 40, 30, 71, 53, 56, 61, 55, 89, 82, 63, 116, 162, 116, 154, 137, 149Don’t recall how to assign a set of numbers to an object, B, in R? See above and look again at how we assigned the numbers to object myA.
To get a simple scatter plot (Fig 3), I may write at the R prompt.
plot(myA,myB)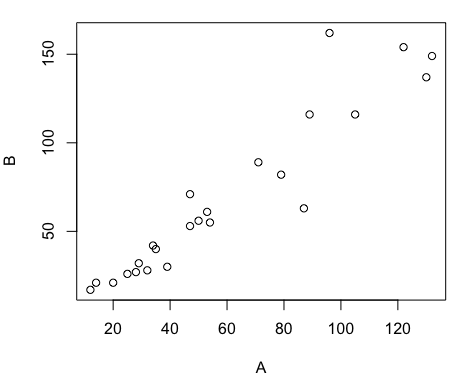
Figure 3. Basic scatter plot made in R, plot(myA,myB).
And here’s the comparable default plot (Fig 4) from Microsoft Excel, Office 365
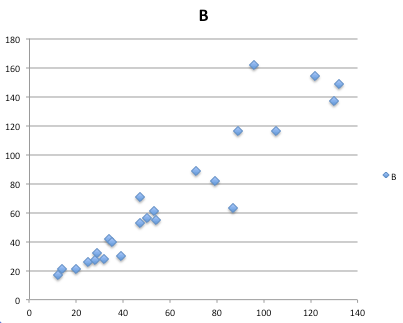
Figure 4. Basic scatterplot made in Microsoft Excel.
Now, both graphs need some work, and to be fair, these are just the defaults. With some effort, you can make an Excel graph look pretty good. But note — the defaults in Excel don’t generate axis labels, while R default plot does. Excel adds a useless title and legend; both need to be removed. Excel also adds grid lines where typically one would not include these in a scientific plot; for example, in the case of scatterplots, grid lines can distract the viewer from the data points and reduce the data-to-ink ratio Tufte 1984).
Count the steps to generate an acceptable scatter plot (Table 3). I’ve also added R Commander (Rcmdr) steps for comparisons (Rcmdr lets you use drop-down menus like Excel or Google Sheets or LibreOffice Calcs).
Table 3. Steps needed to make a simple scatterplot in R, R Commander, or Microsoft Excel.
| Steps | R | Rcmdr | Excel 365 |
| 1 | write the function | Select Graphs | Highlight columns |
| 2 | Select scatterplot | Select from Menu “Insert” | |
| 3 | Select variables | Select scatterplot | |
| 4 | Uncheck options | Select type of scatterplot | |
| 5 | Delete legend | ||
| 6 | Remove grids | ||
| 7 | Insert X-axis label | ||
| 8 | Insert Y-axis label |
Conclusion? R is quicker for routine statistical plots like a scatter plot. And I didn’t even count the steps needed to change MS Excel’s dreadful diamond icon points.
That’s one step in R, four steps in Rcmdr, but eight steps for Microsoft Excel. LibreOffice Calc is a little better at only four steps, but like MS Excel, you’d need to change several components to the graph (Fig 5).
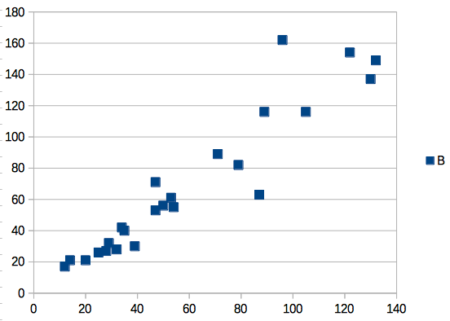
Figure 5. Basic scatterplot made in LibreOffice Calc.
Note 9. In R vernacular, these are referred to as pch, or point characters: pch = 23 returns a blue diamond character; for a blue square like Figure 5, add to the plot() command as
plot(myA,myB, pch = 22)
So, you’re telling me I don’t need a spreadsheet application?
.
No, not at all. We use spreadsheets, and more generally, databases, to store data. Spreadsheets apps are designed to make data entry and data management approachable and efficient. They remain an important tool for researchers (Browman and Woo 2017).
R is not that great of a spreadsheet; packages are available to seamlessly tie your spreadsheet and database data to R via ODBC. We will routinely enter and manipulate data in MS Excel, then import the data into R for analysis.
Spreadsheet apps like MS Excel and Google Sheets (see also LibreOffice Calc) are great at being a spreadsheet program, R is great at being a statistical software program. You should take advantage of what the tools do best.
Still not convinced?
.
R is in use all over the world, by students and professionals alike and if one is going to spend the time to learn how to use a statistics software program, you should learn a standard program, like R.
And it’s not just me. Read about R in this 2009 New York Times piece, “Data analysts captivated by R’s power.” Look who purchased (April 2015) Revolution Analytics, a major player in the development of the R programming language.
Note 10. The answer was Microsoft. For several years Microsoft supported R development via Microsoft Machine Learning Server & Microsoft R Open. However, as of July 2023, this service is no longer available. See Microsoft R application network retirement.
Why install R on your computer?
.
Convenience. Control. Offline.
At the Biology department of Chaminade University, we have installed and maintain R, Rcmdr, and RStudio along with all required packages on our Macbook Pro® Lab computers for your use during class and during optional, proctored biostatistics work sessions. Since 2018, R is increasingly available “in the cloud” (eg, RStudio Cloud), which would mean you could run R in your browser and avoid installation on your computer. You can run significant analysis with R in the cloud via the free Google Colaboratory and CoCalc are now available: I encourage you to look into these platforms. Unfortunately, these services are not quite ready for the classroom. For example, RStudio in the Cloud is free to use on a limited basis, but quickly requires a significant subscription cost with increasing use. Google Colab and GoCalcs require use of Jupyter notebooks, which add yet another layer to the learning curve without focusing on learning statistics. Second, although access to their servers is easy, running simultaneous connections via Chaminade’s single public IP address is likely to lead to problems for us. Third, I want you to use R Commander (Rcmdr) to assist in the learning curve — Rcmdr cannot be run in the Cloud (ie, RStudio in the Cloud, Google Colaboratory, or CoCalc).
Therefore, you are encouraged to install R, Rcmdr, and even RStudio, onto your own computers, in part because of the convenience, but also because R is not generally available to students on campus, ie, only the Biology department’s computers have the up-to-date R software installed.
To get started, go to your Canvas website and view How to install R on your own computer.
An additional benefit to installing a version of R on your computer, you’ll understand more about the software if you take the time to install and if need be, troubleshoot your installation of the software. Moreover, there’s a considerable amount of help out there for R. For example, a simple Google search(keywords: tutorial “install R”), returns more than 700K hits, and more than 40K January 2023 alone (add “after:2023-01-01” to Google search box). In fact, there’s so much out there that you’ll want to sample from several sites and select the voice that works best for you.
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- I listed several spreadsheet apps: Microsoft Excel, Google Sheets, Apple Numbers, LibreOffice Calc. Which of these are free to download and install to your computer? Which are freely available via the Cloud?
- What level of confidence do you have to this statement: I am confident in my ability to use spreadsheet apps for my BI-311 work this semester. Response options:
- Strongly disagree.
- Disagree.
- Agree.
- Strongly agree.
- What level of confidence do you have to this statement: I am confident in my ability to use the R programming software for my BI-311 work this semester. Response options:
- Strongly disagree.
- Disagree.
- Agree.
- Strongly agree.
.
Quiz Chapter 2.2
Why do we use R software?
Chapter 2 contents
.