19.3 — Monte Carlo methods
edits: — under construction —
Introduction
Statistical method that employ Monte Carlo methods use repeated random sampling to estimate properties of a frequency distribution. These distributions may be well-known, e.g., gamma-distribution, normal distribution, or t-distribution, or . The simulation is based on generation of a set of random numbers on the open interval (0,1) — the set of real numbers between zero and one (all numbers greater than 0 and less than 1).
If the set included 0 and 1, then it would be called a closed set, i.e., the set includes the boundary points zero and one.
Markov chain Monte Carlo (MCMC) sampling approach used to solve large scale problems. The Markov chain refers to how the sample is drawn from a specified probability distribution. It can be drawn by discrete time steps (DTMC) or by a continuous process (CTMC). The Markov process is “memoryless:” predictions of future events are derived solely from their present state — the future and past states are independent.
Gibbs sampling is a common MCMC algorithm.
ccc
R code
R’s uniform generator is runif function. Examples of the samples generated over different values (100, 1000, 10000, 100000) with output displayed as histograms (Fig. 1). Note that as sample size increases, the simulated distributions resemble more and more the uniform distribution. Use set.seed() to reproduce the same set and sequence of numbers
require(RcmdrMisc)
par(mfrow = c(2, 2))
myUniformH <- data.frame(runif(100))
with(myUniformH, Hist(runif.100., scale="frequency", ylim=c(0,20), breaks="Sturges", col="red", xlab="100 samples", ylab="Count"))
myUniform1K <- data.frame(runif(1000))
with(myUniform1K, Hist(runif.1000., scale="frequency", ylim=c(0,150), breaks="Sturges", col="green", xlab="1K samples", ylab="Count"))
myUniform10K <- data.frame(runif(10000))
with(myUniform10K, Hist(runif.10000., scale="frequency", ylim=c(0,600), breaks="Sturges", col="lightblue", xlab="10K samples", ylab="Count"))
myUniform100K <- data.frame(runif(100000))
with(myUniform100K, Hist(runif.100000., scale="frequency", ylim=c(0,5000),breaks="Sturges", col="blue", xlab="100K samples", ylab="Count"))
#reset par()
dev.off()
Yes, a nice repeating function would be more elegant code, but we move on. As a suggestion, you should create one! Use sapply() or a basic for loop.
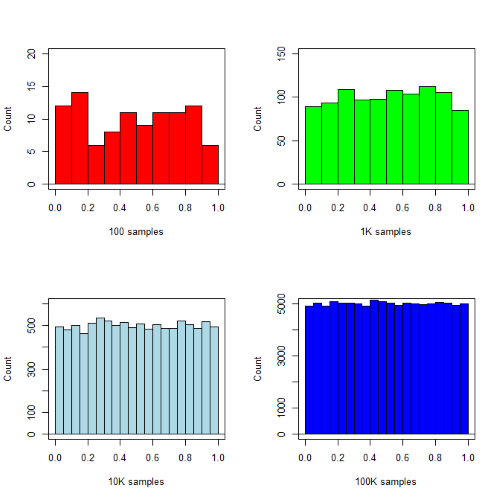
Figure 1. Histograms of runif results with 100, 1K, 10K, and 100K numbers of values to be generated
Looks pretty uniform. A property of random numbers is that history should not influence the future, i.e., no autocorrelation. We can check using the acf() function (Fig. 2).
par(mfrow = c(2, 2))
acf(myUniformH, main="100")
acf(myUniform1K, main="1K")
acf(myUniform10K, main="10K")
acf(myUniform100K, main="100K"
dev.off()
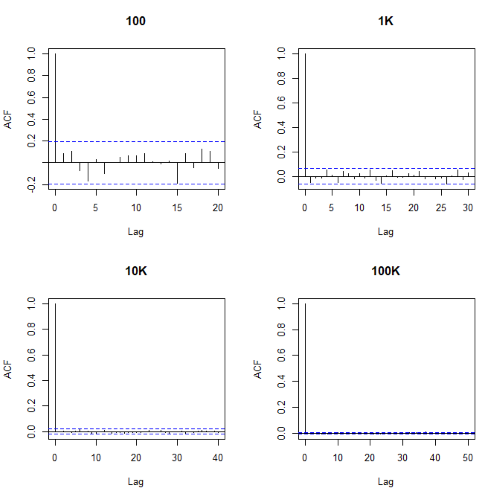
Figure 2. Autocorrelation plots of runif results with 100, 1K, 10K, and 100K numbers of values
Correlations among points are plotted versus lag, where lag refers to the number of points between adjacent points, e.g., lag = 10 reflects the correlation among points 1 and 11, 2 and 12, and so forth. The band defined by two parallel blue dashed lines
Questions
- Use
set.seed(123)and repeatrunif(10)twice. Confirm that the two sets are different (do not set seed) or the same whenset.seedis used. R hint: use functionidentical(x,y), where x and y are the two generated samples. This function tests whether the values and sequence of elements are the same between the two vectors.
Chapter 19 contents
- Introduction
- Jackknife sampling
- Bootstrap sampling
- Monte Carlo methods
- Ch19 References and suggested readings
3.4 – Estimating parameters
Introduction.
What you will find on this page. Definitions for constants, variables, and parameters as used in data analytics. Statistical bias and the concept of unbiased estimators are discussed. The different types of error are introduced along with definitions of accuracy and precision. Statistics used to quantify error are presented in the next section, Chapter 3.4.
Estimating parameters.
Parameters belong to populations; they are fixed but unknown. Parameters are characteristics of populations: the typical average height and weight of five year old children; What is the normal range of values for height and weight of five year old children; average and range of gene expression of TP53 in epithelial lung cells of 50 year old non-smoking humans; etc. Because we generally do not have at our disposal surveys — census — of entire populations for these characteristics, we sample and calculate descriptive statistics for a subset of individuals from populations: these statistics, the mean height, range of height, etc., are variables. We expect average height, range of height, etc., to change, to vary, from sample to sample. A constant, as the word implies, is not variable and remains unchanged.
We estimate parameters (means, variances) from samples of observations from a population. Intuitively then, our estimates are only as good as how representative of the population the sample is. Statistics allows us to be more precise: we can define “how good” our estimates are by asking about, and quantifying, the accuracy and precision of our estimates.
Notwithstanding the notion of “personalized medicine,” our goal in science is to understand cause and effect among sets of observations on samples from a population. We ask, what is the link between lung cancer and smoking? We know that smoking tobacco cigarettes increases risk of cancer, but not everyone who smokes will get cancer (Pesch et al., 2012). Tumorigenic risk is in part mediated by heredity (cf. Trifiletti et al 2017). That’s one way we run into problems in statistics: the biological phenomenon is complicated in ways we are not yet aware of, and thus samples drawn from populations are heterogeneous. Put another way, we think there is one population, but there may be many distinct populations. By chance, repeated samples drawn from the population include individuals with different risk associated with heredity.
As an aside, this is precisely why the concept of personalized medicine is important. Medical researchers have learned that some people with breast cancer respond to treatment with trastuzumab, a monoclonal antibody, but others do not (review in Valabrega et al 2007). Responders have more copies of a gene, copy number variation, for an EGF-like receptor called HER2. In contrast, non-responders to trastuzumab have fewer copies of this receptor (and are said to be HER2-negative in an antibody test for HER2). Thus, we speak about people with breast cancer as if the disease is the same, and from a statistical point of view, we would assume that individuals with breast cancer are of the same population. But they are not — and so the treatment fails for some, but works for others. In this example, we have a mechanism or cause to explain why some do not respond; their breast cancer is not associated with increased copy numbers of HER2. And so in studies with breast cancer, statisticians may account for differences in HER2 status. Note: Fewer than 30% of breast cancer may have over-expression of HER2, (Bilous et al. 2003).
Clearly, HER2 status would be used by statisticians when drawing samples from population, and we would not mistake samples. But, in many other situations we are not aware of any differences and so we assume our samples come from the same population. Note that even with imperfect knowledge about samples, experimental design is intended to help mediate heterogeneous samples. For example, this is why treatment controls need to be used, or case controls are included in studies.
Random assignment to groups also is an attempt to control for unknowns: if random, then all treatment groups will likely include representatives of the numerous co-factors that contribute to risk.
Statisticians have an additional, technical burden: there are often a variety of ways (algorithms) to describe or make inferences about samples, and they are not equally capable of giving us “truth.” Estimates of a parameter are not going to be exactly the true value of the parameter! This is the problem of identifying unbiased ways to estimate parameters. In statistics, bias quantifies whether an algorithm to calculate a particular statistic (e.g., the mean or variance), is consistently too low or too high.
Random sampling.
Random sampling from the population is likely to be our best procedure for obtaining representative samples, but it is not foolproof (we’ll return to situations where random sampling fails to provide adequate samples of populations in Chapter 5.5 Importance of randomization in experimental design). However, a second concern is how to calculate the mean, how to calculate the variance. In the section on Descriptive Statistics (Chapter 3.2), we presented how to calculate the arithmetic mean — the simple average — but also introduced you to other calculations for the middle (e.g., median, geometric mean, harmonic mean). How to know which “middle” is correct?
Statisticians use the concept of bias — the simple arithmetic mean is an unbiased estimator of the population parameter, but a correction needs to be made to the calculation of sample variance to remove bias. Bias implies that the estimator systematically misses the target in some way. Good or “best” parameter estimates are, on average, going to be close to the actual parameter if we collected many samples of the population (this will depend on the sample size and the variability of the data). Earlier we introduced Bessel’s correction to the sample variance, divide the sum of squares by n – 1 and not N as we did for the population variance, so that it is an unbiased estimator of the sample variance. Thus, statisticians have worked out how well their statistical equations work as estimators; concepts of expected values or the expectation are used to evaluate how well an estimator works. In statistics, the expected value of a statistic is calculated by multiplying each of the possible outcomes by the likelihood each outcome will occur and then summing all of those values..
We need to add a bit more to our discussion about measurement and estimation.
Types of error.
To measure is to assign a number to something, a variable. Measurements can have multiple levels, but are of the four data types: nominal, ordinal, interval scale, and ratio scale. Nominal and ordinal types are categorical or qualitative; interval and ratio are continuous or quantitative. Errors in measurement represent differences between what is observed and recorded compared with the true value, i.e., the actual population value. With respect to measurement we distinguish between random errors and systematic errors. Random errors occur by chance, and are thus expected to vary from one measurement instance from another. Random error may lead to measures larger or smaller than the true value. Systematic errors are of a kind that can be attributed to failures of an experimental design or instrument.
Accuracy is reflected in the question: how close to the true value is our measure? Accuracy is distinct from precision, the concept of how clustered together are repeated values for the same measurement. All measurement has associated error, which may be divided into two kinds: random error and systematic error.
We tend to think of error in terms of mistakes, mistakes by us or as failure of the measurement process. However, in biology research, that is too restrictive of a meaning for error. First, experimental error occurs when the estimates derived from the samples — sample mean, sample variance — differ from the population parameters — population mean, population variance. Second, error in biology ranges from mistakes in data collection to real differences among individuals for a characteristic. The latter source, error among individuals, is of course, not a mistake, but rather, it’s the “very spice of life” (Cowper 1845). We’ll leave the study of individual differences, biological error, for later. This section is concerned with error in the sense of mistakes.
Random error includes things like chance error in an instrument leading to different repeat measures of the same thing and to the reality that individual differences exist for most biological traits. We minimize the effects of this kind of error by randomizing: we randomly select samples from populations; we randomly assign samples to treatment groups. Random error can make it hard to differentiate treatment effects. Random error decreases precision, the repeatability of measures. At worse, random error is conservative — it tends to mean we miss group differences, we conclude that the treatment (e.g., aspirin analgesics) has no effect on the condition (e.g., migraines). This kind of error is referred to as a Type II error (Chapter 8).
The experimental design remedy for random error is to increase sample size, a key conclusion drawn from power analysis on experiments, discussed in Chapter 11. The other type of error, systematic error, a type of bias, is more in line with the idea of errors being synonymous with mistakes. Uncalibrated instruments yield incorrect measures. And these kinds of errors lead us to make errors that can be more problematic. An example? Back in the early 1990s when I started research on whole animal metabolic rates (e.g., Dohm et al 1994, Beck et al 1995), we routinely set baseline carbon dioxide, CO2, levels to 0.035% of volume of dry air (350 ppm, parts per million), which reflected ambient levels of CO2 at the time (see Figure 4 in Chapter 4.6).
#NOAA monthly data from Mauna Loa Observatory
co2.1994 <- c(358.22, 358.98, 359.91, 361.32, 361.68, 360.80, 359.39, 357.42, 355.63, 356.09, 357.56, 358.87)
You are probably aware, today, background CO2 have increased considerably even since the 1980s. Data for 2021 (average 420 ppm — reporting just 2 significant figures) are provided below
co2.2021 <- c(415.49, 416.72, 417.61, 419.01, 419.09, 418.93, 416.9, 414.42, 413.26, 413.9, 414.97, 416.67)
source: Global Monitoring Lab, NOAA
Thus, if I naively compared rates of CO2 produced by an animal at rest,  , measured today against the data I gathered back in the 1990s without account for the change in background CO2 in my analysis, I will have committed a systematic error: values of on animals would be systematically higher than values for 1988 when I apply a baseline correction.
Examples of error.
One under-reported cost of next-generation sequencing technologies is that base calls, the process of assigning a nucleotide base to chromatogram peaks has more errors than traditional Sanger-based sequencing methods (Fox et al 2014). In “next-generation-sequencing” (NGS) methods, individual DNA fragments are assigned sequences, whereas Sanger methods took the average sequence of a collection of DNA fragments; thus, in principle, NGS methods should be able to characterize variation of mixtures of sequences in ways not available to traditional sequencing approaches. However, artifacts introduced in sample preparation and PCR amplification lead to base calling errors (Fox et al 2014).
Gene expression levels will differ among tissue types, thus mixed samples from different tissues will misrepresent gene expression levels.
Measurement of energy expenditure, oxygen uptake and carbon dioxide release by an organism, have long been sources of study in ecology and other disciplines. A classic measure is called basal metabolic rate, measured as the rate of oxygen consumption of an endothermic animal, post-absorptive (i.e., not digesting food), at rest but not sleeping, while the animal is contained within a thermal-neutral environment (Blaxter 1989).
Accuracy and precision.
Two properties of measurement are the accuracy of the measure and its precision. Accuracy is defined as the closeness of a measured value to its true value. Precision refers to the closeness of a second measure to the first, to the closeness of a third measure to the first and second, and so on. Precision refers to repeatability of measurement. We suggested use of the coefficient of variation, defined with examples in Chapter 3.2, as a way to quantify precision.
Consider the accuracy and precision of three volumetric pipettors: p1000, which has a nominal range between 100 and 1000 μL (microliters); p200, which has a range between 20 and 200 μL; p100, which has a range between 10 and 100 μL. Which of these three pipettors do you think would have the best accuracy and precision for dispensing 100 μL? We can test pipettors by measuring the mass of distilled water dispensed by the pipettor on an analytical balance. For 100 μL of distilled water at standard temperature and pressure conditions, the mass of the water would be 0.100 grams. The results are shown in the table, and a dot plot is shown in the figure to help us see the numbers.
Table 1. Mass (grams) of 100 μL of distilled water dispensed by three volumetric pipettors*
| p1000 | p200 | p100 | |
| 0.113 | 0.100 | 0.101 | |
| 0.114 | 0.100 | 0.100 | |
| 0.113 | 0.100 | 0.100 | |
| 0.115 | 0.099 | 0.101 | |
| 0.113 | 0.100 | 0.101 | |
| 0.112 | 0.100 | 0.100 | |
| 0.113 | 0.100 | 0.100 | |
| 0.111 | 0.100 | 0.100 | |
| 0.114 | 0.101 | 0.101 | |
| 0.112 | 0.100 | 0.100 | |
| mean: | 0.113 | 0.100 | 0.1004 |
| standard deviation: | 0.0012 | 0.0005 | 0.0005 |
*Temperature 21.5 °C, barometric pressure 76.28 cm mercury (elevation 52 meters). Data presented in Table 1 were not corrected to standard temperature or pressure.
Here is the code for the R run; assuming that you have started R commander, then copy and paste each line into the R Commander script window; if not, enter the script one line at a time in the R console. Recall that the hashtag, #, is used to add comment lines.
Note 1: A reminder: Don’t include the last two rows from Table 1 in your data set; these contain descriptive statistics and are not your data.
#create the variables
p1000 <- c(0.113, 0.114, 0.113, 0.115, 0.113, 0.112, 0.113, 0.111, 0.114, 0.112)
p100 <- c(0.101, 0.1, 0.1, 0.101, 0.101, 0.1, 0.1, 0.1, 0.101, 0.1)
p200 <- c(0.1, 0.1, 0.1, 0.099, 0.1, 0.1, 0.1, 0.1, 0.101, 0.1)
#create a data frame
pipet <- data.frame(p100,p200,p1000)
attach(pipet)
#stack the data
stackPipet <- stack(pipet[, c("p100","p200","p1000")])
#Add variable names
names(stackPipet) <- c("mass", "pipet")
#create the dot plot
with(stackPipet, RcmdrMisc::Dotplot(mass, by=pipet, bin=FALSE))
From Table 1 we see that the means for the p100 and p200 were both close to the target mass of 0.1 g. The mean for the p1000, however, was higher than the target mass of 0.1 g. A dot plot is a good way to display measurements (Fig. 1).
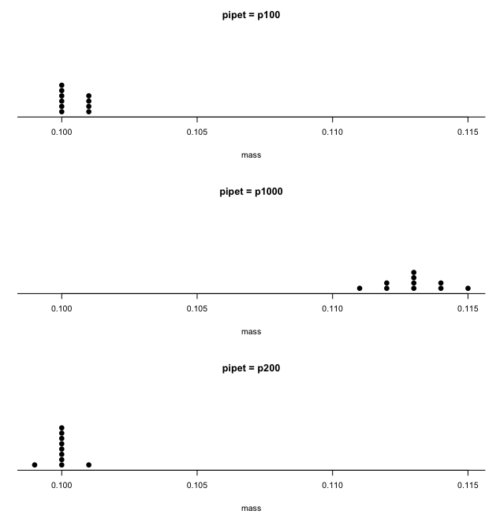
Figure 1. Dot plot of pipet results.
Note 2: Dotplot() is part of the RcmdrMisc package; if you are using the Rcmdr script window (please do!), then the functions in RcmdrMisc are already available and you wouldn’t need to use RcmdrMisc:: (package name plus double-colon operator) to call the Dotplot() function (more properly, referred to as namespaces). Thus, with(stackPipet, Dotplot(mass, by=pipet, bin=FALSE)) would work perfectly well within the Rcmdr script window.
From the dot plot we can quickly see that the p1000 was both inaccurate (the data fall well above the true value), and lacked precision (the values were spread about the mean value). The other two pipettors showed accuracy and looked to be similar in precision, although only two of ten values for the p200 were off target compared to four of ten values for the p100. Thus, we would conclude that the p200 was best at dispensing 100 microliters of water.
In the next chapter we apply statistics to estimate our confidence in this conclusion. In contrast to measurement, estimation implies calculation of a value. In statistics, estimates may be a point, e.g., a value of a collection of data, or an interval, e.g., a confidence interval.
Summary.
This is your first introduction into the concept of experimental design, as defined by statisticians! One of the key tasks for a statistical analyst is to have an appreciation for measurement accuracy and precision as established in the experiment. Precise and accurate measurement levels determine how well questions about the experiment can be answered. At one extreme, if a measure is imprecise, but accurate, then it will be challenging to quantify differences between a control group and a treatment group. At the other extreme, if the measure is precise, but inaccurate, the danger would be differences between the treatment and control group may be more likely, even when the groups are truly not different!
Questions.
- List the types of error in measuring mRNA expression levels on a gene for a sampling of cells from biopsy of normal tissue and a biopsy of a tumor. Assume use of NEXGEN methods for measuring gene expression. Distinguish between technical errors and biological errors.
- If confidence interval are useful for estimating accuracy, what statistic do we call to quantify precision?
Quiz Chapter 3.4
Estimating parameters
Chapter 3 contents
3.2 – Measures of Central Tendency
- Introduction to summary statistics.
- Other “means”.
- How to calculate these other means.
- Do try on your own!.
- Other measures of central tendency.
- Why the median may be a better middle than the mean.
- Scaling and transformation of data.
- R operators.
- Creating objects in R.
- R code calculate central tendency.
- There’s an R package for that.
- Use aggregate() to calculate summary statistics by group.
- Questions.
- Quiz.
- Chapter 3 contents .
Introduction to summary statistics.
For a sample of observations we can begin the summary by identifying the “typical” value. Various statistics are used to describe the middle and collectively these are referred to as measures of central tendency. The mean, the median, and the mode are the most common measures of central tendency. In the situation in which we work with data from a population census, we would calculate population descriptive statistics — not inferential statistics; because we more often work with samples from populations, we report sample descriptive statistics.
First we review the familiar arithmetic mean and introduce the weighted mean. Next we introduce “other means,” which you may not be as familiar with.
Means.
There are several means beyond the simple arithmetic average or mean. Here we review a few. We use this topic also to start introducing standard notation we will use throughout the book.
The population mean, μ (pronounced “mu”) is given by
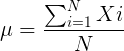
Xi, an observation on the i-th individual
Σ, or “sigma,” which instructs you to add them up (the X’s), from i = 1 (the first observation) to i = N (the last observation).
The sample mean,  , pronounced “eks bar,” of a collection of observations is given by
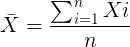
Note 1: Parameters (aka random variables) get Greek letters and sample variables get Roman letters. See Chapter 3.4
Weighted arithmetic mean.
In some cases you may have several samples from the same population. If the sample sizes are the same, you can calculate the average of averages without any fuss — just take all of the sample means and add them up, then divide by the total number of samples. If the sample sizes differ, then you needs to weight (W) each sample mean by its sample size. Simply divide each sample mean by its appropriate sample size, then add all of these up. That is the weighted average.
More generally, we can write
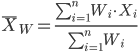
For example, consider a variable containing the following observations, for example, over the course of watching birds gathering at a drinking source (eg, recorded over 20 days, a single 5 minute interval per day), we can count how many times zero, one, two, etc birds are observed.
Table 1. A sample of counts of observations, eg, how many birds
| Observation | Frequency |
|---|---|
| 1 | 0 |
| 2 | 0 |
| 3 | 2 |
| 4 | 4 |
| 5 | 2 |
| 6 | 3 |
| 7 | 2 |
| 8 | 3 |
| 9 | 1 |
The observation “4” was observed four times; the observation “5” was observed twice, and so on for a total of 15 observations.
What is the arithmetic mean of these 15 observations? To solve this, well, you have a couple of choices. You could copy the numbers down as often as they appear and then calculate the mean in the usual way.
Other “means”.
The arithmetic average (illustrated above) is not the only way to estimate the mean.
The trimmed mean, also called the truncated mean, is a useful approach when data is widely dispersed — data spread away from the middle (see Chapter 3.3). Thus, the trimmed mean will be less influenced compared to the arithmetic mean by outlier data points, ie, data far from other data points in the set.
You would use the trimmed mean to describe the middle of a data set in which a plot shows most of the values are clumped together around a middle – and yet you see a few values that are much smaller or much greater. A specified percentage of the smallest and largest values are removed from the data set and then the simple arithmetic mean is calculated for the trimmed data set. For example, given a data set of daily rainfall for different cities, you might wish to remove the driest 5% and wettest 5% of the days in order to better compare the rainfall trends for the cities.
Calculating the trimmed mean is straight-forward in R: use the same built-in function, mean(), but add some options.
Note 2: This is a good time to remind you how to get help with R commands. Do you recall how to get help in R?
At the R prompt type
help(mean) or
?mean
The R Documentation page for mean() will pop up (assuming you allowed R to install help pages as html). Figure 1 shows a screenshot of a portion of the help page for mean()
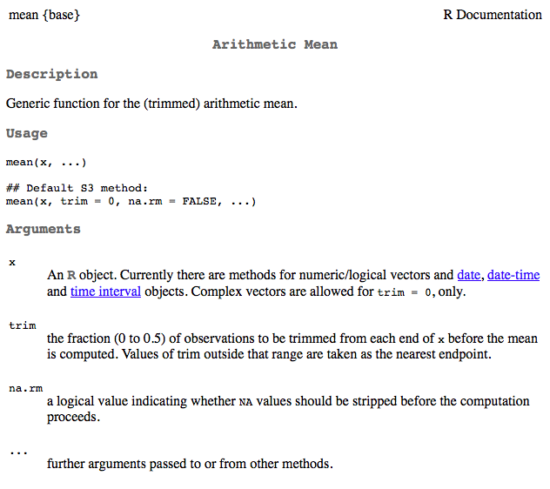
Figure 1. A portion of the R help page about the function mean.
From the help page (Fig 1) we can see that we can specify a trimmed mean by adding options to the mean(x, ...) command. For our x variable defined above, get the trimmed mean after 25% of the data are removed.
mean(x, trim=0.25)[1] 6From the help page we see that the only required option you need to feed the mean command is the name of the variable, in this case, “x” (it can be, of course, any name provided the data are attached). In this case we removed 25% of the values – 12.5% of the smallest values and 12.5% of the largest values – that’s also called the interquartile mean. We use a dot plot to show these trends (Fig 2).
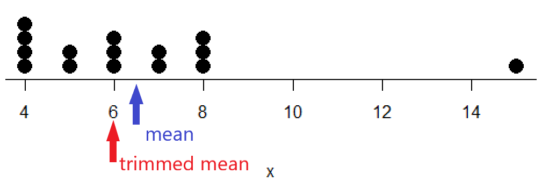
Figure 2. Dot plot of our x variable with locations of the mean (blue) and the trimmed mean (red). The Dotplot(x) function in package RcmdrMisc was used in Rcmdr to make this graphic. Arrows were added by hand. Dotplot() example code presented in Chapter 3.4.
If we recalculate a trimmed mean after dropping 10% of the points, or even 40% of the points, we get the same mean value of 6. The trimmed mean is an example of a robust estimator; it’s resistant to the influence of outliers.
Another useful descriptor of the middle is the geometric mean. The geometric mean is useful for calculating the average of ratios. Geometric mean would be used when you want to compare central tendency for different variables, each differing in scale. For example, gene expression results, reported as fold-changes, for different genes often shows tremendous differences among genes and would be best described by logarithmic scale, not arithmetic scale. Geometric mean expression values would be better choice for central tendency. Other examples are found in economics: for example, calculating compound interest or interest. The geometric mean applies whenever the scale is multiplicative and not additive
The geometric mean is given by the equation
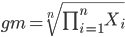
The geometric mean (gm) is equivalent to log-transforming your data, then calculating the arithmetic mean, and transforming the result back (with the antilog exponent.) As you recall, for our simple data set the arithmetic mean was 6.2. The geometric mean for this data was 5.977. Taking the natural log for each of the values from our simple data set, then calculating the arithmetic mean we have 1.788.
The antilog of this value is
exp(1.788)[1] 5.977Another frequently encountered mean is the harmonic mean, which is defined by the equation

Harmonic mean is appropriate for averaging rates. For example, what is the average speed traveled if you travel 30 miles per hour (mph) between point A and B, then on the return trip, your speed was 40 mph? If you think (30 + 40)/2 = 35 mph, then this would be incorrect — after all, the distance covered has not changed, just the time. The harmonic mean returns 34.2 mph. Let
y = c(30,40)The harmonic mean returns 34.2 mph ( see below “How to calculate these other means”)
Both harmonic and geometric means apply for values greater than zero.
How to calculate these “other” means.
In Microsoft Excel, calculate geometric mean via the function GEOMEAN(); calculate harmonic mean via the function HARMEAN().
The base R (and Rcmdr) doesn’t have built in functions for these, although you could download and install some R packages which do (eg, package psych, geometric.mean(variable), harmonic.mean(variable)). It is quicker to just to calculate these by submitting a snippet of code into the script window
For geometric mean of variable “x” at the R prompt type
exp(mean(log(x)))For harmonic mean of variable “x” at the R prompt type
1/mean(1/x)where is the base of the natural logarithm, Euler’s number, and log is the natural logarithm (in R, to get log to other bases you can use log10 for base 10 logarithm or log2 for base 2 logarithm, or log(x, base = n) for any base n of the variable x, and variable is the name of the variable you wish to do the calculations on.
R code: Do try on your own!
Here’s some numbers to try your hand. For example, create a variable containing a few numbers, any numbers. and write it to the variable named z
myZ = c(3,4,6,7,9,11,4)Now, calculate the arithmetic mean, the geometric mean, and the harmonic mean for the variable myZ. You should get Table 4.2)}
Table 2. Comparison of different means for myZ.
| mean | value |
|---|---|
| Arithmetic | 6.285714 |
| Geometric | 5.716403 |
| Harmonic | 5.204936 |
Try three more. In R (or R Commander script window), create three new variables.
varA = c(3,3,3,3)varB = c(1,2,3,12)varC = c(-3,0,1,3)Now, calculate the arithmetic mean, geometric mean, and harmonic mean for each variable.
For the simple arithmetic mean
mean(varA)For the geometric mean, use the formula above
exp(mean(log(varA)))For the harmonic mean, use the formula above
1/mean(1/varA)What did you get?
Other measures of central tendency
Median
The median, which lacks an accepted notation — we’ll go with  , divides a set of observed numbers into two equal halves. Half the observations are above the median, half of the observations are below the median. Arrange data from lowest to highest, take the middle measurement:

odd number of measurements minus the middle value minus even number of measurements minus average of the 2 middle values

Or, more succinctly, we have

To get the median in R type at the R prompt
median(variable)and of course, replace variable with the name of the variable containing the numbers. For our x variable created earlier, the function median returns in R
[1] 6[Note that the median for x was the same as the trimmed mean for x, which is consistent with with our view that the trimmed mean is a robust estimator of the middle of a data set.
Mode
Mode is another way to express the middle and it refers to the most frequent occurring measurement. Use of mode makes most sense for discrete or countable numbers. For a normal distribution, the mean, median and mode will be the same value. Note that a data set may have more than one mode. For example, what is the mode for the variable we created earlier?
myX = c(4,4,4,4,5,5,6,6,6,7,7,8,8,8,15)For this small data set we see that “4” is the most frequent with a count of four occurrences in the set.
Mode would seem like a straightforward function in R. However, it turns out there is not a mode function in the base package.
A little explanation is in order. In R, typing mode at the R prompt like so
mode(myX)returns
[1] "numeric" Not the answer we were expecting. In R, mode command is used to tell you what the mode (ie, way or manner in which some task is accomplished) of storage is for the variables.
In order to get the statistical mode we want, we either hunt down a package that contains mode estimation (eg, install the package DescTools use the Mode function — see below), or we can write a little code.
Note 3: A reminder — what we are attempting is to estimate a statistic. DescTools includes about 80 different statistics functions, including functions to calculate every statistic described in this chapter, chapter 3.3, and most other chapters in this book.
A quick Google search found a number of answers at stackoverflow.com (eg, question 2547402). The simplest response was to use names and max commands like so
temp = table(as.vector(myX))names (temp)[temp==max(temp)]Why the median may be a better middle than the mean
Comparing the two measures of central tendency can tell you without plotting how your data are distributed about the middle. Sample distributions are discussed in Chapter 6.
- When the distribution of the data is symmetric or normally distributed (discussed in Chapter 6.7) then the mean and the median will be about the same value
- When data are right-skewed (a few large values), then the mean will be greater than the median.
- When the data are left-skewed (a few small values), then the mean will be less than the median.
Here’s an illustration (Fig 3). I sampled 100 points from a random normal distribution with mean zero and standard deviation 0ne and another 100 points from a log-normal distribution also with mean zero and standard deviation one. In Figure 3, the histograms (see Chapter 4.2 – Histograms), along with summary statistics (see Note 4). Means are indicated with red arrows and medians are indicated with blue arrows.
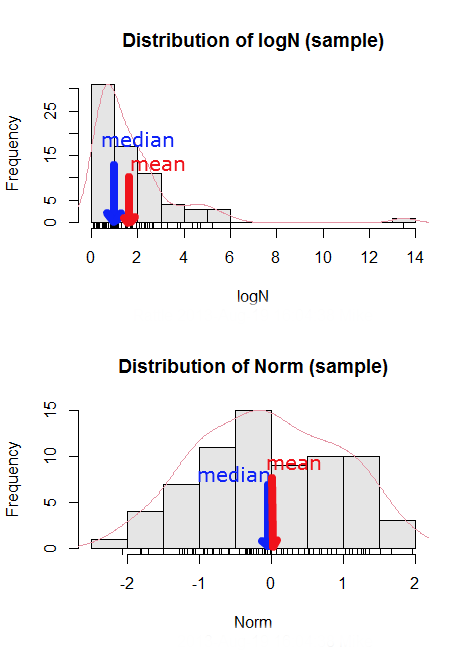
Figure 3. Normal and lognormal distributions with mean (red) and median (blue) noted for comparison.
So the median is a better descriptor or the central tendency of a sample distribution when the distribution is NOT normally distributed.
Note 4: “Summary statistics” refers to reporting of one or more descriptive statistics on a data set. The mean, median, standard deviation, range are common reported statistics. R Commander provides a menu to select from descriptive statistics, returning a table of the estimates. Rcmdr: Statistics → Summaries → Numerical summaries…
Scaling and transformation of data
Sometimes it is useful to standardize your data so that the variables all have the same scale. One algorithm for standardization is called normalization. Normalization implies that you correct the data so that data has a mean, μ, of zero, and a standard deviation, σ, of 1 (unit variance). There are several ways to standardize, each with strengths and limitations. To normalize we use the Z-score equation (see Chapter 6.7 for other uses of Z score).

where Xi is each observation in your data set.
Normalization will make outliers, the few points in a data set that are noticeably different from the central tendency of the rest of the data, smaller and less influential. When you normalize multiple sets of data, then each will have the same mean (0) and variance (unit variance), but the ranges will differ. An example of this is the simple product moment correlation — by standardizing you change the variances for the different variables to have the same unit variance.
As we will see later in class it is also useful to expand or contract the variability of the data or to change the shape of the distribution (if the data is not normally distributed). For example, if you compare individuals of a population for many morphological traits (eg body size, growth rate), the spread of points (called a distribution) will look more like a Poisson distribution (not symmetrical about the mean, a few individuals may be much larger…). This is partly due to the way in which morphological traits are measured. We normally measure body size on a linear scale (inches or centimeters). However, body size is affected by physiological processes that are more related to volume. Therefore, the more appropriate scale of measurement is on a log scale. We can transform the data measured on a linear scale to a log scale. For morphological traits this can produce a distribution that is normally distributed (bell shape). There are many more statistical procedures for data that is normally distributed than there are statistical procedures for Poisson distributions or any other type of distribution. Additional discussion about data transformation is introduced in Chapter 13.3.
You can always uncode or unstandardize your data after performing the statistical procedures and return to the original scale. In fact, when reporting descriptive statistics you should report the untransformed, uncoded data. Moreover, you will find it useful to report means adjusted for other variables (eg, from ANOVA or regression); if the ANOVA or regression equations are performed on transformed or coded data you would want to back calculate to the original scale after applying the ANOVA or regression adjustments. This advise will make more sense after we’ve discussed ANOVA (Chapter 12) and linear regression (Chapter 17).
R operators
The names command can be used to retrieve the names contained in the variable (if text types) or to set the names of the observations, which is what we are using it for here. We set the numbers to text names “4”, “5”, etc. then find the maximum count of named items in the temp table. The double equals operator (==) is used to tell R to find the object that is “equal to” something we specify, in this case, the max value (R Language Definition 2014). Table 3 shows common operators in R.
Table 3. Common arithmetic* and comparison** operators
| Operator | Description |
|---|---|
| ? | help |
| + | plus |
| - | minus |
| * | multiply |
| / | divide |
| : | series |
| > | greater than |
| < | less than |
| >= | greater than or equal to |
| <= | less than or equal to |
| = | left assignment |
| <- | left assignment |
== | equal to |
** To list and get help with use of comparison operators enter at the R prompt
help(Arithmetic)
help(Comparison)
The R package modeest has a number of algorithms for calculating the mode, depending on the kind of data you are working with. After installing the package and its dependencies, type at the R prompt
require(modeest)
mfv(myX)
[1] 4
Creating objects in R
Everything in R is an object (Chambers 2008). We provide many worked examples in Part 07. Working with your own data – Mike’s Workbook for Biostatistics. In brief, create a variable in R by assigning the vector x, either directly at the R prompt or in a script window (Rcmdr, RStudio), like so
myX = c(4,4,4,4,5,5,6,6,6,7,7,8,8,8,15)
The function c(), which stands for combine is used to combine the set of numbers into the object, myX. For small sets like this you may find it convenient to enter the values one by one and let R store it into the vector for you. For R installed on your computer, use the scan() function and your keyboard — scan() doesn’t work consistently in serverless R instances (eg., Google CoLab). Careful! Make sure that you remember to assign the results from scan to a vector.
I’ll create the object tryScan just to distinguish it from x, although I will enter the same values. Until R receives an interrupt signal from you, it will prompt you to enter numbers one row at a time. When you’ve reached the end, use the keyboard shortcut Ctrl + q (Windows) or Cmd + q (macOS) to interrupt keyboard input.
tryScan = scan()
1: 4
2: 4
3: 4
4: 4
5: 5
6: 5
7: 6
8: 6
9: 6
10: 7
11: 7
12: 8
13: 8
14: 8
15: 15
Read 15 items
tryScan
 [1] 4 4 4 4 5 5 6 6 6 7 7 8 8 8 15
The function tryScan is a very useful command, with many options, and can be used for more than keyboard entry. For example, you can paste from your computer’s clipboard a column of numbers from your spreadsheet.
R code calculate central tendency
Once we have the vectormyX, calculate the mean by entering at the R prompt
mean(myX)
and you should get the answer of 6.466667
And of course, you don’t type in the R prompt >, right?
Or, for the better option, create two variables, one containing the list of observed numbers and the second that contains the frequency for each observed number in the series. You would then use the command for weighted mean.
myY = c(4,5,6,7,8,15)
myW = c(4/15, 1/15, 3/15, 2/15, 4/15, 1/15)
Note — you can check that the frequencies sum to 1 by using the sum command like so
sum(myW)
For the weighted mean, the command is
weighted.mean(myY,myW)
and, the answer returned is 6.466667, the same as before.
There’s an R package for that.
We list code examples for all of the statistics described on this page, but as you can imagine, there are packages that include these and other useful functions, or “wrapper functions” that make writing code easier in R. A good example is the DescTools package. One advantage of using a package like DescTools is that it cuts through the need to remember specific commands for basic data exploration. For example, just call the Desc() function to yield several measures of central tendency and dispersion (see Chapter 3.3).
The R code and output follows, along with a plot (Fig 4). The mean and median are highlighted in orange.
Desc(myX)
────────────────────────────────────────────────────────────────────────────────
myX (numeric)

length      n   NAs unique   0s  mean meanCI'
    15     15     0      6    0  6.47    4.92
       100.0%  0.0%        0.0%          8.02

   .05    .10   .25 median  .75   .90     .95
  4.00   4.00  4.50   6.00 7.50  8.00   10.10

range      sd vcoef    mad  IQR  skew    kurt
11.00    2.80  0.43   2.97 3.00  1.72    2.94

  value freq   perc cumfreq cumperc
1     4    4  26.7%       4   26.7%
2     5    2  13.3%       6   40.0%
3     6    3  20.0%       9   60.0%
4     7    2  13.3%      11   73.3%
5     8    3  20.0%      14   93.3%
6    15    1   6.7%      15  100.0%

' 95%-CI (classic)

Figure 4. Histogram, box plot, and cumulative distribution function plot generated by default by Desc() call.
Lots of output! This is a good example of how to explore data — describe the middle (eg, mean and median), but also the variability about the middle (eg, range, standard deviation — sd, mean absolute deviation — mad, coefficient of variation — vcoef), and distribution shape (quantiles — 0.05, 0.25 etc, kurt, skew). The plots — histogram, box plot, and cumulative distribution plots — are explained in Chapter 4.
Use aggregate() to calculate summary statistics by group.
So far, all code presumes need to calculate descriptive statistics one vector at a time. In general, we need summary statistics for more than one group or strata. For example, we may ask, what are the average body temperature readings measured by IR device on different body areas from several subjects (question 8a, Homework 2A: Descriptive statistics in Mike’s Workbook for Biostatistics).
The aggregate() function in R simplifies calculating means by groups by providing a concise and efficient way to apply a summary function (like mean()) to a variable, grouped by one or more other variables. The format for aggregate is
aggregate(x = variable_to_aggregate ~ grouping_variable, FUN = mean, data = your_dataframe)
Questio8a had two levels of body regions, “Forehead” and “Throat.” Assuming the variable is named bodyTemp and the grouping variable is called bodyGroup and stored in the attached data.frame question08a, then the following R code provides the requested summary statistics by groups.
aggregate(bodyTemp ~ bodyGroup, data = question08a,
function(x) c(mean = mean(x)))
Additional statistics can be requested by adding one after the other following mean(x), eg, median = median(x).
Note 5: aggregate() is part of the base R installation. Additional functions are available, including dplyr and data.table packages, which the user is encouraged to explore!
The advantage of use of R Commander, it’s easy to get multiple statistics by groups by following the drop down menus, beginning with Statistics > Summaries > Table of statistics… (Fig 5).

Figure 5. Screenshot R Commander, summary statistics by group.
Questions
- Find the help page in R for the median function. How does the function handle missing values?
- For a simple data set like the following
myY <- c(1,1,3,6)you should now be able to calculate, by hand, the
• mean • median • mode - If the observations for a ratio scale variable are normally (symmetrically) distributed, which statistic of central tendency is best (eg, less sensitive to outlier values)?
- In the
names()command, what do you think the result will be if you replacemaxin the command withmin? - If data are right skewed, what will be the order of the mean, median, and mode?
- Body mass of Rhinella marina (formerly Bufo marinus, Fig 6),
bufo <- c(71.3, 71.4, 74.1, 85.4, 85.4, 86.6, 97.4, 99.6, 107, 115.7, 135.7, 156.2)
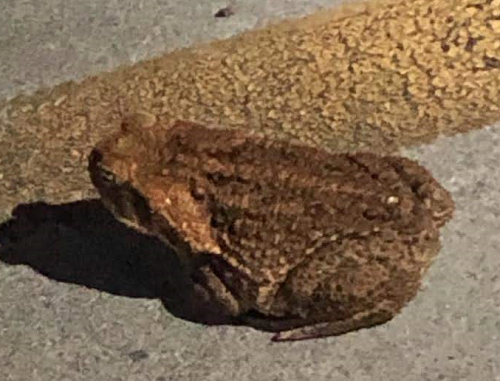
Figure 6. Female Rhinella marina (formerly Bufo marinus), Chaminade University campus. Body length 23.5 cm. Click image to view full sized image.
- Under what circumstances is it appropriate to transform raw data?
- What does “standardize” or “normalize” imply as actions to take with data?
Quiz Chapter 3.2
Measures of Central Tendency
Chapter 3 contents
- Exploring data
- Data types
- Measures of Central Tendency
- Measures of dispersion
- Estimating parameters
- Statistics of error
- References and suggested readings
1.1 – A quick look at R and R Commander
A first look at R.
R is a programming language for statistical computing (Venables et al 2009). R is an interpreted language — when you run (execute) an R program — the R interpreter intercepts and runs the code immediately through its command-line interface, one line at time. Python is another popular interpreted language common in data science. Interpreted languages are in contrast to compiled languages, like C++ and Rust, where program code is sent to a compiler to a machine language application. R is free to use and available via many platforms, from local installations on a person’s laptop to running on cloud servers (Fig 1). 
Figure 1. Choose how you will interact with R: on your computer (Blue box) or in the cloud (Red box). Users of Linux, macOS, and WinPC can either install R to their computer or choose to access R in the cloud (and/or, black arrow).
Before you begin, you have a choice: how do you want to work with R (Fig 1)? In part, the choice depends on your computing device. If you have a desktop or laptop computer, running Linux, Apple macOS, or Microsoft Windows, then R can be installed onto your computer (blue box, Fig 1). If, however, you have a ChromeBook, Apple iPad or iPhone, or any Android Tablet or Smartphone, you would go with the second option (red box, Fig 1).
For those going with installing R to their computer, the second choice is to pick the environment for creating and running scripts and managing file input and output during a session. Working environments for R in the cloud include RStudio and Jupyter Notebooks (eg, Google CoLab) (red box, Fig 1 — see Note 2 below). For installed R, two suggested environments are R Commander and RStudio, an Integrated Development Environment or IDE, RStudio (Fig 1). The choice depends on your needs — an IDE is helpful when you plan to write a lot of code, it’s a comprehensive programming environment, which includes many tools that support writing code from scratch.
For our course at Chaminade University, I recommend R Commander because of the drop-down menu approach to accessing statistical functions in R; R Commander is not a comprehensive environment, but it provides the necessary scripting window along with access to markdown editing. R Commander, Rcmdr, is an R package that provide a graphical user interface or GUI for R. It is based on the tcltk package. R must be installed first before installing the R Commander package. R Commander provides familiar menu functions, like many commercial statistical software. R Commander, like the IDE RStudio, is not necessary for R programming or conducting statistical analysis or even generating reports via markdown. R Commander, however, shrinks the learning curve with R programming basics so that students can focus on learning statistics, which is the chief objective of the Biostatistics course at Chaminade.
The following steps user through use of R and R Commander, from installation to writing and running commands. Mike’s Workbook for Biostatistics has a ten-part tutorial, A quick look at R and R Commander, which I recommend.
Note 1: Getting started? By all means rely on Mike’s Biostatistics Book (Appendix: Install R, Install R Commander, Use R in the cloud) and blogs or other online tutorials to point you in the right direction. You’ll also find many free and online books that may provide the right voice to get you working with R. However, the best way to learn is to go to the source. The R team has provided extensive documentation, all included as part of your installation of R. In R, run the command RShowDoc("doc name"). replace doc name with the name of the R manual or R user guide. For example, the Venables publication is accessed as RShowDoc("R-intro"). Similarly, the manual for installation is RShowDoc("R-admin") and the manual for R data import/export is RShowDoc("R-data").
Install R.
.
Full installation instructions are available at Install R, and for the R Commander package, at Install R Commander. Here, we provide a brief overview of the installation process.
Note 2: The instructions at Mike’s Biostatistics Book assume use of R on a personal computer running updated Microsoft Windows or Apple macOS operating systems. For Linux instructions, eg, Ubuntu distro, see How to install R on Ubuntu 22.04. For Chromebook users, if you can install a Linux subsystem, then you can also install and run R although it’s not a trivial installation. For instructions to install R see Levi’s excellent write up at levente.littvay.hu/chromebook/. (This works best with Intel-based CPUs — see my initial attempts with an inexpensive Chromebook at Install R.)
Another option is to run R in the cloud via service like Google’s Colab or CoCalc hosted by SageMath. Both support Jupyter Notebooks, a “web-based interactive computational environment.” Neither cloud-based service supports use of R Commander (because R Commander interacts with your local hardware). Colab is the route I’d choose if I don’t have access to a local installation of R. See Use R in the cloud for more details.
Download a copy of the R installation file appropriate for your computer from one of the Comprehensive R Archive Network (CRAN) mirror site of the r-project.org. For Hawaii, the most convenient mirror site is provided by the folks at RStudio (https://cloud.r-project.org/. In brief, Windows 11 users download and install the base distribution. MacOS users must first download and install XQuartz (https://Xquartz.org), which provides the X Window System needed by R’s GUI (graphic user interface). Once XQuartz is installed, proceed to install R to your computer. MacOS users — don’t forget to drag the R.app to your Applications folder!
Start R.
.
The following is a minimal look at how to use R and R Commander. Please refer to tutorials at Mike’s Workbook for Biostatistics (R work, part 1 – 10) to learn use of R and R Commander.
We’re just getting started, so the next thing to learn is how to set your working environment for your R sessions. Although we’ll discuss the R environment more as we proceed, it’s a good idea to start with a best practice action common in data science — always create and work from a working folder. This can be a local folder on your computer or pointed to a folder in your cloud storage. On my mac I usually create a folder on the desktop, example BI-311, and point to that as my working folder for a project. Now, we need to point R to use the working folder — we do this at start of each R session (or modify some code R needs during start up to always point to the folder — for now, we leave that for a later exercise).
Once R is installed on your computer, start R as you would any program on your computer. For example, the icon for the R.app as it appears in the dock on a MacBook is shown in Figure 2.
Figure 2. R.app icon shown on a MacBook dock.
To point R to our working folder, there are several options. For now, we’ll go with writing and submitting a simple function in R. Recall that R has a command-line. The R prompt appears on the command line in the RGUI as the greater-than typographical symbol “>” at the beginning of a line (Fig 2). The prompt is returned by R to indicate the interpreter is ready to accept the next line of code.
First, discover where R is pointing to by submitting (type the command exactly as written then select keyboard shortcuts on Windows enter, or on macOS return key) the function getwd() at the prompt.
Note 3: Unfamiliar with keyboard shortcuts? I created a page just for you at Keyboard shortcuts in Mike’s Workbook for Biostatistics.
Ready to
On my MacBook, R returns
> getwd()
[1] "/Users/[username]/Documents"
To point to my working folder, I submit setwd("/Users/[username]/Desktop/BI311". When I run getwd() again, R returns the update
> getwd()
[1] "/Users/[username]/Desktop/BI311"
Note 4: Windows users will recognize that, unlike macOS and Linux, they will need to write paths with the backslash, not the forward slash. This is discussed further in Mike’s Workbook.
[username] is just a placeholder here — no reason to share my actual user name!
Ready to do some work?
R coding practices in this book and in the companion workbook roughly follow guidance outlined in a September 2018 R-Bloggers post, “R Code — Best practices,” by The R Trader. Of note, naming conventions: variables are nouns, variable names are written in lowerCamelCase; functions are verbs, function names are period separated, eg, my.function; script file names all end with .R and are written snake_case.R. Comments, preceded by # and a single space, eg, # A brief comment, are sparingly included in code, but reserved for explanatory sentences in the text. We use <- and not = for assignment statements.
Where discussion requires reference to instructions on use of the R programming language, R code (instructions) the user needs to enter at the R prompt are shown in code blocks.
Courier New font within a “code block.”Until you write your own functions, the general idea is, you enter one set of commands at a time, one line at a time. For example, to create a new variable, curryPoints, containing points scored by the NBA’s Steph Curry during the 2016 playoffs, type the following code at the R prompt (displayed as >, the “greater than” sign)
curryPoints <- c(24,6,40,29,26,28,24,19,31,31,11,18,19).
and to obtain the mean, or arithmetic average, for curryPoints at the R prompt type and enter
.
mean(curryPoints).
Output from R function mean will look like the following
.
[1] 24.42857.
Functions in R, or any other data science programming language, are intended to automate a task.
Note 5: A good data management habit — store the variable as an R object called a data.frame.
df.curryPoints <- data.frame(curryPoints)
The R prompt appears in the RGUI as the greater-than typographical symbol “>” at the beginning of a line (Fig 3). The prompt is returned by R to indicate the interpreter is ready to accept the next line of code.
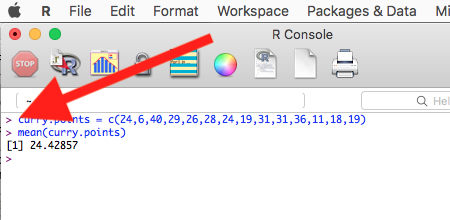
Figure 3. The R GUI on a macOS system; red arrow points to the R prompt.
Note 6: We just demonstrated one of several ways data can be brought into an R session, by creating a data.frame directly from a vector. Other methods include
- Reading a text file from your computer, eg, CSV, by
read.csv() - Importing a spreadsheet (Excel file) from your computer
using readxl::read_excel() - Entering small datasets directly using
read.table()with thetext= argument
Everything that exists is an object.
.
A brief programmer’s note — John M. Chambers, creator of the S programming language and a member of the R-project team, once wrote that sub-header phrase about R and objects. What that means for us: programming objects can be a combination of variables, functions, and data structures. During an R session the user creates and uses objects. The ls() function is a useful R command to list objects in memory. If you have been following along with your own installed R app, then how many objects are currently available in your session of R? Answer by submitting ls(). Hint: the answer should be one object.
A routine task during analysis is to calculate an estimate then use the result in subsequent work. For example, instead of simply printing the result of mean(curryPoints), we can assign the result to an object.
myResult <- mean(curryPoints)
.
To confirm the new object was created, try ls() again. And, of course, there’s no particular reason to use the object name, myResult, I provided! Like any programming language, creating good object names will make your code easier to understand.
When you submit the above code, R returns the prompt, and the result of the function call is not displayed. View the result by submitting the object’s name at the R prompt, in this case, myResult. Alternatively, a simple trick is to string commands on the same line by adding ; (semicolon) at the end of the first command. For example,
myResult <- mean(curryRoints); myResult
.
Objects created during an R session, like curryPoints, are stored in memory within the Global Environment. To remove an object, use the command rm(myVariable). Why remove objects during an R session? If you are attempting multiple tasks in a homework assignment, removing unneeded objects helps maintain a clean and organized workspace, improving code readability and reducing the chance of accidental errors.
Write your code as script.
.
While it is possible to submit code one line at a time, a much better approach is to create and manage code in a script file. A script file is just a text file with one command per line, but potentially containing many lines of code. Script files help automate R sessions. Once the code is ready, the user submits code to R from the script file.
Note 7: Working with scripts eliminates the R prompt, but code is still interpreted one line at a time. The user does not type the prompt in a script file.
Figure 4 shows how to create a new script file via the RGUI menu: File → New script.

Figure 4. Screenshot of drop down menu RGUI, create new script, Windows 11.
The default text editor opens (Fig 5).
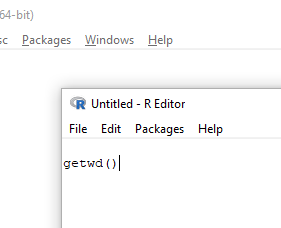
Figure 5. Screenshot of portion of R Script editor, Windows 11. A simple R command is visible.
Submit code by placing cursor at start of the code or, if code consists of multiple lines, select all of the code, then hit keyboard keys Ctrl + R (Windows 11) or for macOS, Cmd + Enter.
I recommend starting with a clean environment, by using rm(list = ls()) at the beginning of a script.
By default, save R script files for reuse with the file extension .R, eg, my_script.R. Because the scripts are just text files you can use other editors that may make coding more enjoyable (see RStudio in particular, but there are many alternatives, some free to use. A good alternative is ESS).
Install R Commander package.
.
By now, you have installed the base package of the R statistical programming language (see for detailed instructions). The base package contains all of the components you would need to create and run data analysis and statistics on sets of data. However, you would quickly run into the need to develop functions, to write your own programs to facilitate your work. One of the great things about R is that a large community of programmers have written and contributed their own code; chances are high that someone has already written a function you would need. These functions are submitted in the form of packages. Throughout the semester we will install several R packages to extend R capabilities. R packages discussed in this book are listed at R packages of the Appendix.
Our first package to install is R Commander, Rcmdr for short. R Commander is a package that adds function to R; it provides a familiar point-and-click interface to R, which allows the user to access functions via a drop-down menu system (Fox 2017). Thus, instead of writing code to run a statistical test, Rcmdr provides a simple menu driven approach to help students select and apply the correct statistical test. R Commander also provides access to Rmarkdown and a menu approach to rendering reports.
install.packages("Rcmdr")
.
In addition, download and install the plugin
install.packages("RcmdrMisc")
See Install R Commander for detailed installation instructions.
Note 8: Plugins are additional software which add function to an existing application.
Start R Commander.
.
After installing Rcmdr, to start R Commander, type library(Rcmdr) at the R prompt and enter to load the library
library(Rcmdr).
On first run of R Commander you may see instructions for installing additional packages needed by R Commander. Accept the defaults and proceed to complete the installation of R Commander. Next time you start R commander the start up will be much faster since the additional packages needed by R Commander will already be present on your computer.
Note that you don’t type the R prompt and, indeed, in R Commander Script window you won’t see the prompt (Fig 6). Instead, you enter code in the R Script window, then click “Submit” button (or Win11: Ctrl+R or for macOS: Cmd+Enter), to send the command to the R interpreter. Results are sent to Output window (Fig 6).
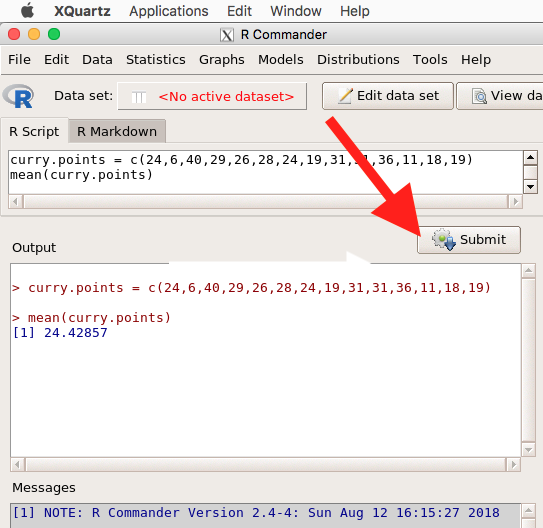
Figure 6. The windows of R Commander, macOS. From bottom to top: Messages, Output, Script (tab, Markdown) Rcmdr ver. 2.4-4.
Figure 6 shows how the R Commander GUI looks on a macOS computer. The look is similar on Microsoft Windows 11 machines (Fig 7).
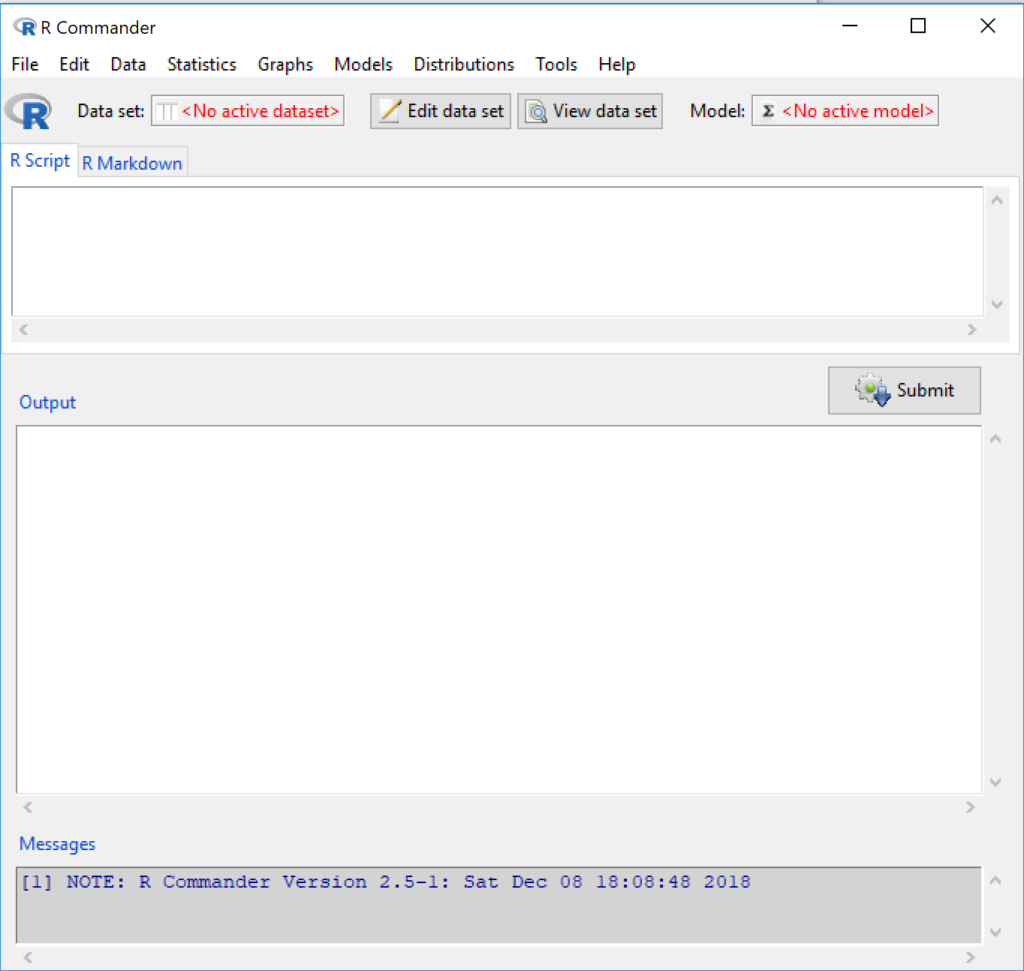
Figure 7. The windows of R Commander, Win11. From bottom to top: Messages, Output, Script (tab, R Markdown) Rcmdr ver. 2.5-1.
We use R Commander because it gives us access to code from drop-down menus, which at least initially, helps learn R (Fox 2005, Fox 2016). Later, you’ll want to write the code yourself, and RStudio provides a nice environment to accomplish your data analysis.
Improve Rcmdr experience.
Windows users: R Commander works best in Windows if SDI option is set. This can be accomplished during R installation (“Startup options” popup, change from default “No” to “Yes” to customize), but you can also change after installing R. Win11 users should change from MDI to SDI — from one big window to separate windows — (see Do explore settings, WinPC see Fig 9; macOS see Fig 10). The downside of SDI is that while multiple Windows may appear during an R session, one or more windows may be hidden by an open window. For example, plots will popup in a new window and may be obscured by the Rcmdr window if full screen. A simple trick to view active windows on Win11 is to use the keyboard shortcut s Alt + Tab to view and cycle between windows. What about SDI and RStudio? RStudio experience will be similar whether MDI (default) or SDI was selected.
macOS users: To improve R Commander performance, turn off Apple’s app nap (see Do explore settings, Figures 6), which should improve a Mac user’s experience with R Commander and other X Window applications.
Complete R setup by installing LaTeX and pandoc for Markdown.
.
LaTeX is a system for document preparation. pandoc is a document converter system. Markdown is a language used to create formatted writing from simple text code. Once these supporting apps are installed, sophisticated reports can be generated from R sessions, by-passing copy and paste methods one might employ. See Install R Commander for instructions to add these apps.
Note 9: If you successfully installed R and are running R Commander, but may be having problems installing pandoc or LaTeX, then this note is for you. While there’s advantages to getting pandoc etc working, it is not essential for BI311 work.
Assuming you have Rcmdr and RcmdrMisc installed, and if you have started Rcmdr and have it up and running, then we can skip pandoc and LaTeX installation and use features of your browser to save to pdf.
R Markdown by default will print to a web page (an html document called RcmdrMarkdown.html) and display it in your default browser. To meet requirements of BI311 — you submit pdf files — we can print the html document generated from “Generate Report” in R Commander to a pdf.
- Chrome browser, right click in the web page, from the popup menu select Print, then change destination to Save as pdf.
- Safari browser, right click then select Print page (or if an option, Save page as pdf), then find at lower left find PDF and option to Save as PDF.
R Markdown.
.
Markdown is a syntax for plain text formatting and is really helpful for generating clean html (web) files. R Commander also helps us with our reporting. R Markdown is provided as a tab (Fig 6, Fig 7). Provided you have also installed pandoc on your computer, you can also convert or “render” the work into other formats including pdf and epub. Unsure if your computer has pandoc installed? If you are unsure than most likely it is not installed. 😁 Rcmdr provides a quick check — go to Tools and if you see Install auxiliary software, then click on it and a link to pandoc website to find and download installation file. You can also confirm install of pandoc by opening a terminal on your computer (eg, search “terminal” on macOS or “cmd” on Win11), then enter pandoc –version at the shell prompt. Figure 8 shows version pandoc is installed on my Win11 HP laptop.
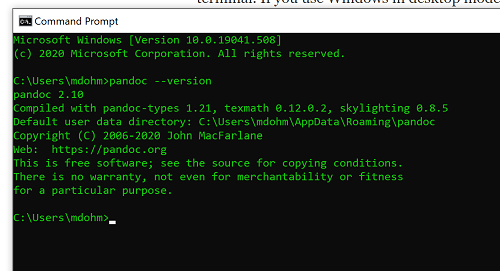
Figure 8. Screenshot of terminal window (cmd) on win11 computer, checking for installed pandoc on a win10 pc.
Enter your R code in the script window, submit your code, and your results (code, output, graphs) are neatly formatted for you by Markdown. Once the Markdown file is created in R Commander, you can then export to an html file for a a web browser, an MS Word document, or other modes.
Do explore settings!
.
After installation, R and R Commander are ready to go. However, students are advised that a few settings may need to be changed to improve performance. For example, on Win11 PCs, R Commander recommends changing from the default MDI (Multiple Document Interface) to SDI (Single Document Interface). Check the SDI button via Edit menu, select GUI preferences menu. Click save, which will make changes to .RProfile, then exit and restart R. Check to make sure the changes have been made (Fig 9).
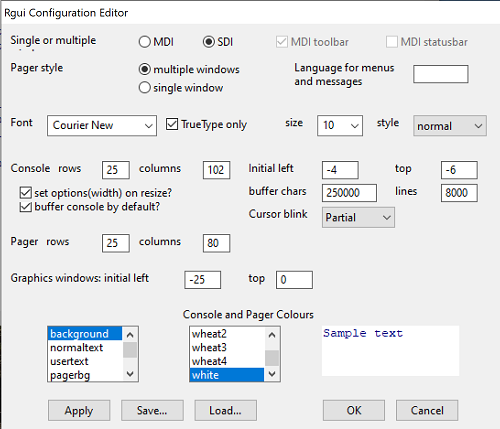
Figure 9. Screenshot of GUI preferences settings after changing from default MDI to SDI, win10
For macOS users, both R and Rcmdr will run better if you turn off Apple’s power saving feature called nap. From Rcmdr go to Tools and select Manage Mac OS X app nap for R.app… (Fig 10).
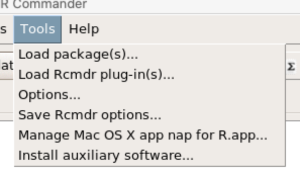
Figure 10. Screenshot Rcmdr Tools popup menu, macOS 10.15.6
A dialog box appears; select off to turn off app nap (Fig 11).
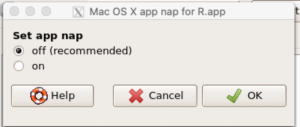
Figure 11. Screenshot Rcmdr Set app nap dialog box, macOS 10.15.6
Exit R Commander.
.
Click on Rcmdr: File → Exit, then choose to exit from just R Commander, or both R Commander and R.
If you exit just R Commander or both R and R Commander, you’ll receive a pop-up request to confirm you want to quit R Commander (click yes), and a second prompt asking if you want to save your script. In general, select yes and then you’ll be able to take up where you left off. Similarly, if asked to save your workspace, choose no. If you save workspace, this creates an .RProfile text file with settings for how R and R Commander will behave the next time you start R. The file will be saved to your current working folder, which R will use the next time R starts. At least while you are getting started, you should avoid creating these .RProfile files.
As long as the current session of R is active, then the library for Rcmdr, as well as any other library loaded during the R session, is in memory. To start R Commander again while R is running, at the R prompt, type and submit
Commander()
Questions.
- Biostatistics students should work through my ten R lessons, A quick look t R and R Commander, available in Mike’s Workbook for Biostatistics.
- Students should also search Internet for R tutorials and R Commander tutorials. Find recent tutorials and work through several of them. We get better when we practice.
Quiz Chapter 1.1
A quick look at R and R Commander
Chapter 1 contents
.
- Getting started
- A quick look at R and R Commander
- Chapter 1 – References