12.6 – ANOVA posthoc tests
Introduction
Tests of the null hypothesis in a one-way ANOVA yields one answer: either you reject the null, or you do not reject the null hypothesis — with the usual caveats about “provisionally reject,” etc (Ch8.2 and Ch8.3). But while there was only one factor (population, drug treatment, etc) in a one-way ANOVA, there are usually many treatments (eg, multiple levels, four different populations, three doses of a drug plus a placebo).
ANOVA plus posthoc tests solves the multiple comparison problem we discussed: you still get your tests of all group differences, but with adjustments to the procedures so that these tests are conducted without suffering the increase in Type I error = the multiple comparison problem. If the null hypothesis is rejected, you may then proceed to posthoc tests among the groups to identify differences without increasing the chance of rejecting the null hypothesis too often.
Consider the following example of four populations scored for some outcome, sim.ch12 (scroll down the page, or click here to get the R code).
Bring the data frame, sim.ch12, into current memory in Rcmdr by selecting the data set. Next, run the one-way ANOVA.
Rcmdr: Statistics → Means → One-way ANOVA…
which brings up the following menu (Fig 1).
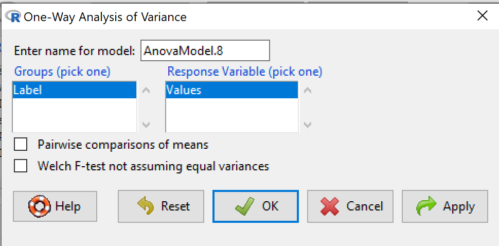
Figure 1. One-way ANOVA menu in R Commander.
Note 1: If you look carefully in Figure 1, you can see model name was AnovaModel.8. There’s nothing sacred about that name, it just means this was the 8th model I had run up to that point. For consistency I renamed all instances of model objects reported in the text as AnovaModel.1 — after all, they were the same model run with different commands. As a reminder, Rcmdr will provide names for models for you; it is better practice to provide model names yourself.
Notice that Rcmdr menu correctly identifies the Factor variable, which contains text labels for each group, and the Response variable, which contains the numerical observations.
Note 2: If your factor is numeric, you’ll first have to tell R that the variable is a factor and hence nominal. this can be accomplished within Rcmdr via the Data → Manage variables… options, or simply submit the command
newName <- as.factor(oldVariable)
Similarly, you may need to change a variable from character to factor. For example, check a variable with class(). If it returns anything but “factor,” then use as.factor() as before.
If your data set contains more variables, then you would need to sort through these and select the correct model (Fig 1).
To get the default Tukey posthoc tests simply check the Pairwise comparisons box and then click OK.
For a test of the null that four groups have the same mean, a publishable ANOVA table would look like Table 1.
Note 3: the ANOVA table is something you put together from the output of R (or other statistical programs). After running one-way ANOVA in Rcmdr, go to Models → Hypothesis tests → ANOVA table…, accept the defaults (marginality, sandwich estimators and are explained in the next chapter 12.7).
Table 1. The ANOVA table
| Df | Mean Square |
F | P† | |
| Label | 3 | 389627 | 76.44 | < 0.0001 |
| Error | 36 | 61167 |
1.108357e-15 to a threshold < 0.0001.Note 4: To automatically replace a small p-value with a threshold cutoff requires conditional formatting, to highlight results by their content. This is a great ability of spreadsheet apps, and, unsurprisingly, R can do this too. For example, the pvalue() function in scales package, which can report p-values rounded to a threshold value.
R code
pvalue(1.108357e-15, accuracy=0.0001, decimal.mark = ".", add_p=TRUE)
Output
[1] "p<0.0001"
h/t norbert at Scripts & Statistics
Here’s the R output for ANOVA
AnovaModel.1 <- aov(Values ~ Label, data = sim.Ch12)
summary(AnovaModel.1)
          Df  Sum Sq Mean Sq  F value     Pr(>F)
Label      3  389627  129876    76.44   1.11e-15 ***
Residuals 36   61167    1699
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
with(sim.Ch12, numSummary(Values, groups = Label, statistics = c("mean", "sd")))
      mean       sd data:n
Pop1 150.3 35.66838 10
Pop2  99.0 43.25634 10
Pop3 130.9 42.36469 10
Pop4 350.7 43.10723 10
End of R output.
When to conduct posthoc tests.
Recall that all we can say is that a difference has been found and we reject the null hypothesis. However, we do not know if group 1 = group 2, but both are different from group 3, or some other combination. So we may want additional tools. We can conduct posthoc tests (also called multiple comparisons tests).
Once a difference has been detected (F test statistic > F critical value, therefore P < 0.05), then posteriori tests, also called unplanned comparisons, can be used to tell which means differ.
There are also cases for which some comparisons were planned ahead of time and these are called a priori or planned comparisons; even though you conduct the tests after the ANOVA, you were always interested in particular comparisons. This is an important distinction: planned comparisons are more powerful, more aligned with what we understand to be the scientific method. An argument — transparency, avoids Type II errors — can be made that if comparisons are planned, and only a few tests are conducted, no correction for “multiple tests” is warranted. Moreover, it is defensible to report all p-values from a hundred tests without correction, acknowledging that if all null hypotheses were “true,” then 5 would be expected to be less than Type I of 5% by chance alone.
Posthoc tests.
ANOVA was introduced by Fisher in 1918, and, as readers know by know, returns whether or not significant differences are present among groups, but no which groups may differ. Unsurprisingly, given the needs of researchers to compare groups, many tests were developed since Fisher’s ANOVA to conduct multiple comparison tests. Collectively, they are often referred to as posthoc tests (Ruxton and Beauchamp 2008).
There are many different flavors of these tests, and R offers several, but I will hold you responsible only for three such comparisons: Tukey’s, Dunnett’s, and Bonferroni (Dunn). These named tests are among the common ones (Table 2, Midway et al 2020), but you should be aware that the problem of multiple comparisons and inflated error rates has received quite a lot of recent attention because the size of data sets has increased in many fields, eg, genome wide-association studies in genetics or data mining in economics or business analytics. A related topic then is the issue of “false positives.” New approaches include Holm-Bonferroni. There are others — it is a regular “cottage industry” in applied statistics to a problem that, while recognized, has not achieved a universal agreed solution. Best we can do is be aware and deal with it and know that the problem is one mostly of big data (eg, microarray and other high-throughput approaches). Equally important, some of these tests are better than others, and some may not be consistent with best practices.
Let’s take a look at these procedures.
Performing multiple comparisons and the one-way ANOVA
Note 5: In order to do most of the posthoc tests you will need to install the multcomp package; after installing the package, load the library(multcomp). Just using the default option from the one-way ANOVA command yields the Tukey’s HSD test.
a. Tukey’s: “honestly (wholly) significant difference test”
Tests 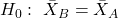 versus
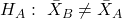 where A and B can be any pairwise combination of two means you wish to compare. Thus, this is likely a case of unplanned comparisons. There are
 comparisons.
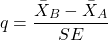
where
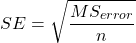
and n is the harmonic mean of the sample sizes of the two groups being compared. If the sample sizes are equal, then the simple arithmetic mean is the same as the harmonic mean.
Note 6: q is like t for when we are testing means from two samples.
- The significance level is the probability of encountering at least one Type I error (probability of rejecting Ho when it is true). This is called the experimentwise (familywise) error rate whereas before we talked about the comparisonwise (individual) error rate.
Three options to get the posthoc test Tukey:
(1) TukeyHSD() function is included in base statistics.
(2) use a function called mcp or in Rcmdr, Tukey is the default option in the one-way ANOVA command. The function mcp is part of the multcomp package, which is included in the Rcmdr package.
(3) specify method = "HSD" in PostHocTest function in DescTools package.
In brief, run the anova first, save the output to an object, then call an appropriate command from a package to conduct the posthoc test.
Rcmdr: Statistics → Means → One-way ANOVA
Check “Pairwise comparisons of means” to get the Tukey’s HSD test (Fig 2).
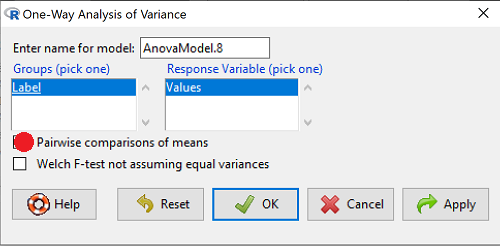
Figure 2. Screenshot Rcmdr menu: Select Tukey posthoc tests with the one-way ANOVA.
Tukey’s honestly significant difference is available without installing additional packages. Simply run
AnovaModel.1 <- aov(formula = Values ~ Label, data = sim.Ch12)
TukeyHSD(AnovaModel.1)
and R output returned is
Tukey multiple comparisons of means
95% family-wise confidence level

Fit: aov(formula = Value ~ Label, data = sim.Ch12)

$Label
           diff        lwr        upr     p adj
Pop2-Pop1 -51.3 -100.94731  -1.652695 0.0406116
Pop3-Pop1 -19.4  -69.04731  30.247305 0.7200796
Pop4-Pop1 200.4  150.75269 250.047305 0.0000000
Pop3-Pop2 31.9   -17.74731  81.547305 0.3232616
Pop4-Pop2 251.7  202.05269 301.347305 0.0000000
Pop4-Pop3 219.8  170.15269 269.447305 0.0000000
Installation of R Commander also includes installation of the multcomp package, which contains several post hoc tests, including Tukey and Dunnett’s tests.
R output follows. There’s a lot, but much of it is repeat information. Take your time, here we go.
.Pairs <- glht(AnovaModel.1, linfct = mcp(Label = "Tukey"))
summary(.Pairs) # pairwise tests
     Simultaneous Tests for General Linear Hypotheses
Multiple Comparisons of Means: Tukey Contrasts
 Fit: aov(formula = Values ~ Label, data = sim.Ch12)

 Linear Hypotheses:
                  Estimate Std. Error t value Pr(>|t|)
 Pop2 - Pop1 == 0   -51.30      18.43  -2.783   0.0405 *
 Pop3 - Pop1 == 0   -19.40      18.43  -1.052   0.7201
 Pop4 - Pop1 == 0   200.40      18.43  10.871   <0.001 ***
 Pop3 - Pop2 == 0    31.90      18.43   1.730   0.3233
 Pop4 - Pop2 == 0   251.70      18.43  13.654   <0.001 ***
 Pop4 - Pop3 == 0   219.80      18.43  11.924   <0.001 ***
 ---
 Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
 (Adjusted p values reported -- single-step method)

 confint(.Pairs) # confidence intervals
      Simultaneous Confidence Intervals

 Multiple Comparisons of Means: Tukey Contrasts

 Fit: aov(formula = Values ~ Label, data = sim.Ch12)

 Quantile = 2.6927
 95% family-wise confidence level

 Linear Hypotheses:
                  Estimate  lwr       upr
 Pop2 - Pop1 == 0  -51.3000 -100.9382   -1.6618
 Pop3 - Pop1 == 0  -19.4000  -69.0382   30.2382
 Pop4 - Pop1 == 0  200.4000  150.7618  250.0382
 Pop3 - Pop2 == 0   31.9000  -17.7382   81.5382
 Pop4 - Pop2 == 0  251.7000  202.0618  301.3382
 Pop4 - Pop3 == 0  219.8000  170.1618  269.4382
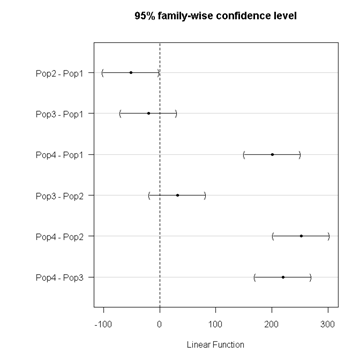
Figure 3. Plot of confidence intervals of Tukey HSD.
R Commander includes a default 95% CI plot (Fig 3). From this graph, you can quickly identify the pairwise comparisons for which 0 (zero, dotted vertical line) is included in the interval, ie, there is no difference between the means (eg, Pop1 is different from Pop4, but Pop1 is not different from Pop3).
b. Dunnett’s Test for comparisons against a control group
- There are situations where we might want to compare our experimental Populations to one control Population or group. Thus, this is likely a case of planned comparisons.
- This is common in medical research where there is a placebo (control pill with no drug) or sham operations (operations where everything but the critical operation is done).
- This is also a common research design in ecological or agricultural research where some animal or plant populations are exposed to an environmental factor (eg, fertilizer, pesticide, pollutant, competitors, herbivores) and other animal or plant populations are not exposed to these environmental factor.
- The difference in the statistical procedure for analyzing this type of research design is that the experimental groups may only be compared to the control group.
- This results in fewer comparisons.
- The formula is the same as for the Tukey’s Multiple Comparison test, except for the calculation of the SE.
Standard Error is changed by multiplying the MSError by 2.
And n is the harmonic mean of the sample sizes of the two groups being compared.
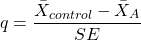
where
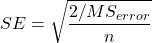
R Commander doesn’t provide a simple way to get Dunnett, but we can get it simply enough if we are willing to write some script. Fortunately (OK, by design!), Rcmdr prints commands.
Look at the Output window from the one-way ANOVA with pairwise comparisons: it provides clues as to how we can modify the mcp command (mcp stands for multiple comparisons).
First, I had run the one-way ANOVA command and noted the model (AnovaModel.3). Second, I wrote the following script, modified from above.
Pairs <- glht(AnovaModel.1, linfct = mcp(Label = c("Pop2 - Pop1 = 0", "Pop3 - Pop1 = 0", "Pop4 - Pop1 = 0")))
where Label was my name for the Factor variable. Note that I specified the comparisons I wanted R to make. When I submit the script, nothing shows up in the Output window because the results are stored in Pairs.
Next, I then need to ask R to provide confidence intervals
confint(Pairs)
R output window
Pairs <- glht(AnovaModel.1, linfct = mcp(Label = c("Pop2 - Pop1 = 0", "Pop3 - Pop1 = 0", "Pop4 - Pop1 = 0")))
confint(Pairs)

Simultaneous Confidence Intervals

 Multiple Comparisons of Means: User-defined Contrasts

 Fit: aov(formula = Values ~ Label, data = sim.Ch12)

 Estimated Quantile = 2.4524
 95% family-wise confidence level

 Linear Hypotheses:
  ...... lwr ....... upr
 Pop2 - Pop1 == 0  .. -51.3000  . -96.5080  ... -6.0920
 Pop3 - Pop1 == 0  .. -19.4000  . -64.6080  ... 25.8080
 Pop4 - Pop1 == 0  .. 200.4000  . 155.1920  .. 245.6080
Look for intervals that include zero, therefore, the group does not differ from the Control group (Pop1). How many groups differed from the Control group?
Alternatively, I may write
Tryme <- glht(AnovaModel.1, linfct = mcp(Label = "Dunnett"))
confint(Tryme)
It’s the same — in fact, the default mcp test is Dunnett’s test.
Tryme <- glht(AnovaModel.1, linfct = mcp(Label = "Dunnett"))
confint(Tryme)

Simultaneous Confidence Intervals

Multiple Comparisons of Means: Dunnett Contrasts

Fit: aov(formula = Values ~ Label, data = sim.Ch12)

Estimated Quantile = 2.4514
95% family-wise confidence level

Linear Hypotheses:
Estimate lwr upr
Pop2 - Pop1 == 0 -51.3000 -96.4895 -6.1105
Pop3 - Pop1 == 0 -19.4000 -64.5895 25.7895
Pop4 - Pop1 == 0 200.4000 155.2105 245.5895
Note 7: Use relevel() command* to set the order of levels in the data set. By default Dunnett procedure in mcp assumes the first level of the factor is the control or reference level. R sorts levels alphabetically, so clearly one option is to always provide a sort-friendly name for the reference level. Naturally, R has you covered if you need to specify a different level as the reference, the relevel() command. For example, instead of Pop1, set reference to Pop2 as follows:
Level
[1] Pop1 Pop2 Pop3 Pop4
Levels: Pop1 Pop2 Pop3 Pop4
Set new order
Level <- relevel(Level, ref = "Pop2"); Level
[1] Pop1 Pop2 Pop3 Pop4
Levels: Pop2 Pop1 Pop3 Pop4
relevel() works only on unordered factors; if you get this error message it just means you need to specify your character variable as a factor. As you may recall, to confirm a character variable is factor
is.factor(Level)
[1] TRUE
If FALSE, then set character variable to factor.
Level <- as.factor(Level)
* Yes, you could change the order any way you want with level(). For example,
Level <- factor(Level, levels = c("Pop2", "Pop4", "Pop1", "Pop3")); Level
returns
[1] Pop1 Pop2 Pop3 Pop4
Levels: Pop2 Pop4 Pop1 Pop3
c. Bonferroni t
The Bonferroni t test is a popular tool for conducting multiple comparisons. This, too, is consistent with an unplanned comparisons approach. The rationale for this particular test is that the MSerror is a good estimate of the pooled variances for all groups in the ANOVA.
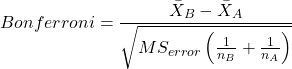
and DF = N – k.
Note 8: In order to achieve a Type I error rate of 5% for all tests, you must divide the 0.05 by the number of comparisons conducted.
Thus, for k = 4 groups,

Here’s a simplified version if you prefer to get all pairwise tests
Use this information then to determine how many total comparisons will be made, then if necessary, use to adjust Type I error rate for one test (the exerimentwise error rate).
For our example, is 0.05/6 = 0.00833. Thus, for a difference between two means to be statistically significant, the P-value must be less than 0.00833.
For Bonferroni, we will use the following script.
- Set up one-way ANOVA model (ours has been saved as AnovaModel.1),
- Collect all pairwise comparisons with the
mcp(~"Tukey")stored in a vector (I called mineWhynot), - and finally, get the Bonferroni adjusted test of the comparisons with the summary command, but add
test = adjusted("bonferroni").
It’s a bit much, but we end up with a very nice output to work with.
Whynot <- glht(AnovaModel.1, linfct = mcp(Label = "Tukey"))
summary(Whynot, test = adjusted("bonferroni"))

 Simultaneous Tests for General Linear Hypotheses

Multiple Comparisons of Means: Tukey Contrasts

Fit: aov(formula = Values ~ Label, data = sim.Ch12)

Linear Hypotheses:
Estimate Std. Error t value Pr(>|t|)
Pop2 - Pop1 == 0 -51.30 18.43 -2.783 0.0512 .
Pop3 - Pop1 == 0 -19.40 18.43 -1.052 1.0000
Pop4 - Pop1 == 0 200.40 18.43 10.871 3.82e-12 ***
Pop3 - Pop2 == 0 31.90 18.43 1.730 0.5527
Pop4 - Pop2 == 0 251.70 18.43 13.654 5.33e-15 ***
Pop4 - Pop3 == 0 219.80 18.43 11.924 2.77e-13 ***
  ---
 Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
 (Adjusted p values reported -- bonferroni method)
Questions
- Be able to define and contrast experiment-wise and family-wise error rates.
- Read and interpret R output
- Refer back to the Tukey HSD output. Among the four populations, which pairwise groups were considered “statistically significant” following use of the Tukey HSD?
- Refer back to the Dunnett’s output. Among the four populations, which population was taken as the control group for comparison?
- Refer back to the Dunnett’s output. Which pairwise groups were considered “statistically significant” from the control group?
- Refer back to the Bonferroni output. Among the four populations, which pairwise groups were considered “statistically significant” following use of the Bonferroni correction?
- Compare and contrast interpretation of results for posthoc comparisons among the four populations based on the three different posthoc methods
- Be able to distinguish when Tukey HSD and Dunnet’s post hoc tests are appropriate.
- Some microarray researchers object to use of Bonferroni correction because it is too “conservative.” In the context of statistical testing, what errors are the researchers talking about when they say the correction is “conservative.”
Quiz Chapter 12.6
ANOVA posthoc tests
Data set used in this page
| Label | Value |
|---|---|
| Pop1 | 105 |
| Pop1 | 132 |
| Pop1 | 156 |
| Pop1 | 198 |
| Pop1 | 120 |
| Pop1 | 196 |
| Pop1 | 175 |
| Pop1 | 180 |
| Pop1 | 136 |
| Pop1 | 105 |
| Pop2 | 100 |
| Pop2 | 65 |
| Pop2 | 60 |
| Pop2 | 125 |
| Pop2 | 80 |
| Pop2 | 140 |
| Pop2 | 50 |
| Pop2 | 180 |
| Pop2 | 60 |
| Pop2 | 130 |
| Pop3 | 130 |
| Pop3 | 95 |
| Pop3 | 100 |
| Pop3 | 124 |
| Pop3 | 120 |
| Pop3 | 180 |
| Pop3 | 80 |
| Pop3 | 210 |
| Pop3 | 100 |
| Pop3 | 170 |
| Pop4 | 310 |
| Pop4 | 302 |
| Pop4 | 406 |
| Pop4 | 325 |
| Pop4 | 298 |
| Pop4 | 412 |
| Pop4 | 385 |
| Pop4 | 329 |
| Pop4 | 375 |
| Pop4 | 365 |
R code # copy the data from the full table to clipboard and paste between the double quotes in text=””)
sim.ch12 <- read.table(header=TRUE, sep=",",text="")

#check the dataframe
head(sim.ch12)
Chapter 12 contents
12.5 – Effect size for ANOVA
Introduction
As noted in the t-test chapter and our discussion of statistical power, an effect size is a measure of the strength of a phenomenon. An effect size calculated from data is a descriptive statistic that indicates how large (or small) the difference is between two or more samples. Effect size measures help to provide context between statistical significance, ie, p-values. Among other uses, effect size measures play an important role in meta-analysis studies biological significance (ie, importance of the measured difference).
Estimation of effect size
eta-squared (η2)

where SSB and SST are from the one-way ANOVA and refer to the sum of squared among (between) groups and the total sum of squares, respectively.  measures the proportion of the variation in the response variable that can be explained by membership in one of the groups.
For example, of 0.15 or 15% is interpreted to mean that just 15% of the variation in the response variable can be attributed to membership in the groups (ie, whether a subject was in control group or treatment group, only 15% of the differences between individuals can be attributed to having received control).
Note 1: η2 is just the unadjusted coefficient of determination, R2.
omega-squared (ω2)
A similar, but “less biased” effect size estimate is given by omega-squared (ω2) (Okada 2013). (The bias comes in because sample estimates were used.) Interpretation of  is the same as : measures the proportion of variation explained by membership in the groups. is given as
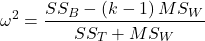
The bias for is more pronounced with small sample size, so omega-squared is preferred. will always be less than or equal to (Okada 2013).
R code
If you have not already done so, please install the package effectsize.
We’ll use the example one-way ANOVA problem from Chapter 12.2. I’ve added the data as example.ch12 and some R script to load the data, scroll to bottom of this page or click on the link).
Get 
First, get the ANOVA model. There are several ways to do this within R (and Rcmdr), the most general is to use the general linear model function, lm(),
#Get the model
AnovaModel.4 <- lm(Difference~Group, data=example.ch12)
#turn it into format that the next command needs
aov_fit <- anova(AnovaModel.4)
#get eta
effectsize(aov_fit)
R output
Parameter | Eta2 (partial) | 9e+01% CI
-----------------------------------------
Group | 0.95 | [0.88, 0.97]
is 0.95 for the Difference group.
Get
R code
omega_squared(aov_fit, partial = FALSE, ci = 0.95)
R output
Parameter | Omega2 | 1e+02% CI
---------------------------------
Group | 0.93 | [0.82, 0.97]
This is a case of a large effect due to group membership. The differences between A, B, and C means account for 93% of the variation. Note that both and  are close; note also that is greater than .
Questions
- In Chapter 7.4 we introduced the concept of number needed to treat, NNT. Discuss the concept of “important differences” between sample means of a control group and a treatment group to NNT.
- This question refers to hypothetical data presented in Chapter 12.2. For the “No difference” group, calculate and . Use the boxplots shown in Figure 1, together with effect size statistics to discuss the relationship between statistical significance (p-value) and important difference.
Quiz Chapter 12.5
Effect size for ANOVA
Data set
example.ch12 <- read.table(header=TRUE, sep=",",text="
Group, No.difference, Difference
A, 12.04822, 11.336161
A, 12.67584, 13.476142
A, 12.99568, 12.961210
A, 12.01745, 11.746712
A, 12.34854, 11.275492
B, 12.17643, 7.167262
B, 12.77201, 5.136788
B, 12.07137, 6.820242
B, 12.94258, 5.318743
B, 12.07670, 7.153992
C, 12.58212, 3.344218
C, 12.69263, 3.792337
C, 12.60226, 2.444438
C, 12.02534, 2.576014
C, 12.60420, 4.575672")
#check the dataframe
head(example.ch12)
Chapter 12 contents
12.4 – ANOVA from “sufficient statistics”
Introduction
By now you should be able to run a one-way ANOVA using R (and R Commander) with ease. As a reminder, You should also be aware that, if you need to, you could use spreadsheet software like Microsoft Excel or LibreOffice Calc to run one way ANOVA on a small data set. Still, there are times when you may need to run a one-way ANOVA on a small data set, and doing so by hand calculator may be just as convenient. What are your available options?
Following the formulas I have given would be one way to calculate ANOVA by hand, but it would be tedious and subject to error. Instead of working with the standard formulas, calculator shortcuts can be derived with a little algebra and this is where I want to draw your attention now. This technique will come in handy in lab classes or other scenarios where you collect some data among a set number of groups and calculate means and standard deviations. The purpose of this posting is to show you how to obtain the necessary statistics to calculate a one-way ANOVA from the available descriptive statistics: means, standard deviations, and sample sizes. In other words, these are the sufficient statistics for one-way ANOVA.
Note 1: In Chapter 11.5, we introduced use of summary statistics, ie, “sufficient statistics,” to calculate the independent sample t-test.
As you recall, a one-way ANOVA yields a single F test of the null hypothesis that all group means are equal. To calculate the F test, you need
- Mean Square Between Groups,

- Mean Squares Within Groups or Error,

F is then calculated as

with degrees of freedom k – 1 for the numerator and N – 1 for the denominator. can also appear as 
We can calculate as
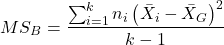
where k is the number of i th groups, ni is the sample size of the ith group,  refers to the overall mean for all of the
 sample means.
Next, for the Error Mean Square, , all we need is the average of the sample variances (the square of the sample standard deviation, s).
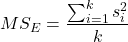
ANOVA from sufficient statistics
Consider an example data set (Table 1) for which only summary statistics are available (mean and standard deviation, sd). The data set is for life span(days) for several inbred strains of laboratory mice from a study (. Sample size for each group was seven mice.
Table 1. Descriptive statistics female life span (days) for ten different inbred strains of mice (Mus domesticus).
| Strains | n | mean | sd |
|---|---|---|---|
| 129S1/SvImJ | 32 | 787.4 | 159.16 |
| A/J | 32 | 630.7 | 130.20 |
| BALB/cByJ | 32 | 734.4 | 154.43 |
| BUB/BnJ | 24 | 611.3 | 218.34 |
| C3H/HeJ | 29 | 724.1 | 131.48 |
| C57BL/6J | 29 | 855.7 | 185.34 |
| CBA/J | 30 | 622.9 | 181.95 |
| FVB/NJ | 26 | 750.3 | 230.11 |
| P/J | 32 | 676.0 | 178.82 |
| SWR/J | 31 | 831.9 | 181.31 |
Data from Yuan et al (2021; https://phenome.jax.org).
Spreadsheet calculations.
You have several options at this point, ranging from using your calculator and the formulas above (don’t forget to square the standard deviation to get the variances!), or you could use Microsoft Excel or LibreOffice Calc and enter the necessary formulas by hand (Table 2). You’ll also find many online calculators for one-way ANOVA by sufficient statistics (eg, https://www.danielsoper.com/statcalc/calculator.aspx?id=43).
Table 2. Spreadsheet with formulas for calculating one-way ANOVA from means and standard deviations from statistics presented in Table 1.
| A | B | C | D | E | F | G | H | I | |
| 1 | Strain | n | Mean | sd | squared | variance | grand mean |
=AVERAGE(C:C) | |
| 2 | 129S1/SvImJ | 32 | 787.4 | 159.16 | =B2*(C2-$I$1)^2 | =D2^2 | dfB | =COUNT(B:B)-1 | |
| 3 | A/J | 32 | 630.7 | 130.2 | =B2*(C3-$I$1)^2 | =D3^2 | dfE | =SUM(B:B)-I2 | |
| 4 | BALB/cByJ | 32 | 734.4 | 154.43 | =B2*(C4-$I$1)^2 | =D4^2 | Msb | =SUM(E:E)/(COUNT(E:E)-1) | |
| 5 | BUB/BnJ | 24 | 611.3 | 218.34 | =B2*(C5-$I$1)^2 | =D5^2 | Mse | =SUM(F:F)/COUNT(F:F) | |
| 6 | C3H/HeJ | 29 | 724.1 | 131.48 | =B2*(C6-$I$1)^2 | =D6^2 | F | =I4/I5 | |
| 7 | C57BL/6J | 29 | 855.7 | 185.34 | =B2*(C7-$I$1)^2 | =D7^2 | P-value | =FDIST(I6,I2,I3) | |
| 8 | CBA/J | 30 | 622.9 | 181.95 | =B2*(C8-$I$1)^2 | =D8^2 | |||
| 9 | FVB/NJ | 26 | 750.3 | 230.11 | =B2*(C9-$I$1)^2 | =D9^2 | |||
| 10 | P/J | 32 | 676.0 | 178.82 | =B2*(C10-$I$1)^2 | =D10^2 | |||
| 11 | SWR/J | 31 | 831.9 | 181.31 | =B2*(C11-$I$1)^2 | =D11^2 |
For this example, you should get the following
MSB = 219899.5
MSE = 31634.1
F = 6.951
P-value = 4.45E-09
Note 2: The number of figures reported for the P-value implies a precision that the data simply do not support. For a report, recommend writing the P-value < 0.001. But note — truncating the p-value diminishes the value to others who may wish to conduct a meta analysis using your work (Chapter 20.15)!
But, R can do it better.
Here’s how. Install the HH package (or RcmdrPlugin.HH for use in Rcmdr) and call the ?aovSufficient function.
Step 1. Install the HH package from a CRAN mirror, eg, cloud.r-project.org, in the usual way.
chooseCRANmirror()
install.packages("HH")
library(HH)
Step 2. Enter the data. Do this in the usual way (eg, from a text file), or enter directly using the read.table command as follows.
MouseData <- read.table(header=TRUE, sep = ",", text= "
Strain, n.size, average, stdev
129S1, 32, 787.4, 159.16
A.J, 32, 630.7, 130.20
BALB.c, 32, 734.4, 154.43
BUB.BnJ, 24, 611.3, 218.34
C3H.HeJ, 29, 724.1, 131.48
C57BL.6J, 29, 855.7, 185.34
CBA.J, 30, 622.9, 181.95
FVB.NJ, 26, 750.3, 230.11
P.J, 32, 676.0, 178.82
SWR.J, 31, 831.9, 181.31")
#Check import
head(MouseData)
End of R input
I know, a little hard to read, but from the MouseData to the end bracket ") before the comment line #Check import, that’s all one command.
Of course, you could copy the data and import the data from your computer’s clipboard in Rcmdr: Data → Import data → from text file, clipboard, or URL…
Note 3: Hint: for field separator, try comma; if that fails, try Tabs
Once the data set is loaded, proceed to Step 3.
Step 3. In our example, sample size was included for each group. Skip to step 4. If, however, the table lacked the sample size information, you can always add a new variable. For example, if we needed to add sample size to the data frame, we would use the repeat element function, rep().
MouseData$n <- rep(7, 10)
If you check the View data set button in Rcmdr, you will see that the command in Step 3 has added a new variable “n” for each of the eleven rows. The function rep() stands for “replicate elements in vectors” and what it did here was enter a value of 7 for each of the ten rows in the data set. Again, this step is not necessary for this example because sample size is already part of the data frame. Proceed to step 4.
Step 4. Run the one way ANOVA using the sufficient statistics and the HH function aovSufficient
MouseData.aov <- aovSufficient(average ~ Strain, data=MouseData)
Step 5. Get the ANOVA table
summary(MouseData.aov)
Here’s the R output
           Df  Sum Sq Mean Sq F value   Pr(>F)
Strain      9 1977732  219748   7.123 2.54e-09 ***
Residuals 287 8853743   30849
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
End R output
To explore other features of the package, type ?aovSufficient at the R prompt (like all R functions, extensive help is generally available for each function in a package).
Meta-analysis and sufficient statistics.
Meta-analysis (see Chapter 20.15 — Meta-analysis), can be performed using sufficient statistics from different tests. Combining sufficient statistics allows for a more precise overall estimate by effectively merging the information from multiple studies, which can be especially useful when individual studies have small sample sizes or lack a unified outcome measure. Common methods include creating summary effect sizes like the standardized mean difference or using p-value combination methods, while ensuring the underlying statistical assumptions are met through goodness-of-fit tests.
Fisher’s method combines the p-values from multiple independent studies into a single overall p-value to test a joint null hypothesis. The method’s test statistic is calculated as the sum of the negative log-transformed p-values. P-values from  number of tests are combined; each p-value,
 , contributes to a variable,
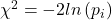 , with
 degrees of freedom. The chi-square distribution is used to evaluate the significance of the Fisher’s method test statistic.
Fisher’s method is available in several R packages (eg,poolr package); here, we’ll just create a simple R code.
Note 4: Not to be confused with Fisher’s exact test, Chapter 9.5.
Limitations: Methods that only use p-values or test statistics may not adequately address the effects of heterogeneity and potential publication bias among studies. Because many older studies do not report effect sizes and confidence intervals, using test statistics or p-values is often the only available method to combine their results.
Example.
One hypothesis about longevity is that the greater the genetic diversity can lead to longer life. The mice in Table 1 were all from inbred mouse strains. By definition, genetic diversity is restricted in inbred mice, compared to outbred strains. Jackson Labs produced a “Diverse Outbred” line of mice, and a few individuals have lived nearly five years, well past the typical 1 – 2 year lifespan of mice (Cohen 2017, Mullis et al 2025). Thus, a natural comparison is to ask: is there a difference in average lifespan between the DO and inbred mouse strains? We’ll run a series of one-sample t-tests against the mean lifespan for the diverse outbred stock of mice, save the p-values, and apply Fisher’s method. While not strictly a meta-analysis, which would draw from multiple studies, this example outlines the basic steps to take given a series of hypothesis of the same kind.
Note 4: Used another R package, BSDA, for a series of one-sample t-tests. DO mean of 794.5 + 262.85 days (n = 192 females), calculated from supplement data in Mullis et al 2025). R code example:
do_avg= 794.5
# dataset MouseData
tsum.test(average[1], stdev[1], n.size[1], mu=do_avg)
Abbreviated R results
t = -0.25235, df = 31, p-value = 0.8024
Repeat for all ten strains from Table 1; p-values were saved to Table 2.
Obviously, a for loop would be appropriate here! The R code extracts p-values from each of the ten tests and saves to p_values object.
p_values <- numeric(length(average))

for (i in 1:length(average)) {
     suppressWarnings({
      test_result <- tsum.test(
      mean.x = average[i],
      s.x = stdev[i],
      n.x = n.size[i],
      mu = do_avg
      )
      p_values[i] <- test_result$p.value
      })
     }

print(p_values)
I’ve wrapped the tsum.test in a suppressWarnings({}) line to prevent multiple, but harmless warnings the code causes. Use of tidyverse would help clean this code up.
The p-values from all ten tests are sorted by strain in Table 2.
Table 2. Results of one sample t-tests inbred strains (Table 1) compared to average lifespan of the J:DO diversity outbred mouse strain from Jackson labs
| Strains | p-value | Strains | p-value | |
| 129S1/SvImJ | 0.8204 | C57BL/6J | 0.08623 | |
| A/J | 5.367e-08 | CBA/J | 1.601e-05 | |
| BALB/cByJ | 0.03527 | FVB/NJ | 0.3368 | |
| BUB/BnJ | 0.0004274 | P/J | 0.0007307 | |
| C3H/HeJ | 0.007479 | SWR/J | 0.2598 |
R-code for Fisher’s method
my_pValues <- c(0.08623, 1.601e-05, 0.3368, 0.0007307, 0.2598)
X_squared <- -2 * sum(log(my_pValues),base = exp(1))
myDf <- 2 * length(my_pValues)
combinedP <- pchisq(X_squared, myDf, lower.tail = FALSE)
result_table <- as.data.frame(rbind(X_squared, myDf, combinedP))
rownames(result_table) <- c("chi_sqr", "df", "P-value")
colnames(result_table) <- c("Value")
print(result_table)
and the R output
                Value
chi_sqr 44.7017431931
     df 16.0000000000
P-value 0.0001541831
With the small p-value, we would reject the null hypothesis of no difference in lifespan among the inbred strains compared to the genetically diverse DO strain of mice.
Limitations of ANOVA from sufficient statistics.
This was pretty easy, so it is worth asking — Why go through the bother of analyzing the raw data, why not just go to the summary statistics and run the calculator formula? First, the chief reason against the calculator formula and use of only sufficient statistics loses information about the individual values and therefore you have no access to the residuals. The residual of an observation is the difference between the original observation and the model prediction. The residuals are important for determining whether the model fits the data well and are, therefore, part of the toolkit that statisticians need to do proper data analysis. We will spend considerable time looking at residual patterns and it is an important aspect of doing statistics correctly.
Secondly, while it is possible to extend this approach to more complicated ANOVA problems like the two-way ANOVA (Cohen 2002), the statistical significance of the interaction term(s) calculated in this way are only approximate (the main effects are OK to interpret). Thus, ANOVA from sufficient statistics has its place when all you have is access to descriptive statistics, but its use is limited and not at all the preferred option for data analysis when the original, raw observations are in hand.
Questions
1. Calculate the one-way ANOVA for body weight of 47 female (F) and 97 male (M) cats (kilograms, dataset cats in MASS R package) from the following summary statistics.
| n | Mean | sd | |
| F | 47 | 2.36 | 0.274 |
| M | 97 | 2.9 | 0.468 |
2. Bonus: Load the cats data set (package MASS, loaded with Rcmdr) and run a one-way ANOVA using the aov() function via Rcmdr. Are the ANOVA from sufficient statistics the same as results from the direct ANOVA calculation? If not, why not.
Quiz Chapter 12.4
ANOVA from “sufficient statistics”
Chapter 12 contents
12.3 – Fixed effects, random effects, and agreement
Introduction
Within discussions of one-way ANOVA models the distinction between two general classes of models needs to be made clear by the researcher. The distinction lies in how the levels of the factor are selected. If the researcher selects the levels, then the model is a Fixed Effects Model, also called a Model I ANOVA. On the other hand, if the levels of the factor were selected by random sampling from all possible levels of the factor, then the model is a Random Effects Model, also called a Model II ANOVA. This page is about such models and I’ll introduce the intraclass correlation coefficient, abbreviated as ICC, as a way to illustrate applications of Model II ANOVA.
Here’s an example to help the distinction. Consider an experiment to see if over the counter painkillers are as good as prescription pain relievers at reducing numbers of migraines over a six week period. The researcher selects Tylenol®, Advil®, Bayer® Aspirin, and Sumatriptan (Imitrex®), the latter an example of a medicine only available by prescription. This is clearly an example of fixed effects; the researcher selected the particular medicines for use.
Random effects, in contrast, implies that the researcher draws up a list of all over the counter pain relievers and draws at random three medicines; the researcher would also randomly select from a list of all available prescription medicines.
Fixed effects are probably the more common experimental approaches. To be complete, there is a third class of ANOVA called a Mixed Model or Model III ANOVA, but this type of model only applies to multidimensional ANOVA (eg, two-way ANOVA or higher), and we reserve our discussion of the Model III until we discuss multidimensional ANOVA (Table 1).
Table 1. ANOVA models
| ANOVA model | Treatments are |
| I | Fixed effects |
| II | Random effects |
| III | Mixed, both fixed & random effects |
Although the calculations for the one-way ANOVA under Model I or Model II are the same, the interpretation of the statistical significance is different between the two.
In Model I ANOVA, any statistical difference applies to the differences among the levels selected, but cannot be generalized back to the population. In contrast, statistical significance of the Factor variable in Model II ANOVA cannot be interpreted as specific differences among the levels of the treatment factor, but instead, apply to the population of levels of the factor. In short, Model I ANOVA results apply only to the study, whereas Model II ANOVA results may be interpreted as general effects, applicable to the population.
This distinction between fixed effects and random effects can be confusing, but it has broad implications for how we interpret our results in the short-term. This conceptual distinction between how the levels of the factor are selected also has general implications for our ability to acquire generalizable knowledge by meta-analysis techniques (Hunter and Schmidt 2000). Often we wish to generalize our results: we can do so only if the levels of the factor were randomly selected in the first place from all possible levels of the factor. In reality, this may not often be the case. It is not difficult to find examples in the published literature in which the experimental design is clearly fixed effects (ie, the researcher selected the treatment levels for a reason), and yet in the discussion of the statistical results, the researcher will lapse into generalizations.
Random Effects Models and agreement
Model II ANOVA is common in settings in which individuals are measured more than once. For example, in behavioral science or in sports science, subjects are typically measured for the response variable more than once over a course of several trials. Another common setting of Model II ANOVA is where more than one raters are judging an event or even a science project. In all of these cases what we are asking is about whether or not the subjects are consistent, in other words, we are asking about the precision of the instrument or measure.
In the assessment of learning by students, for example, different approaches may be tried and the instructor may wish to investigate whether the interventions can explain changes in test scores. To assess instrument validity — an item score from a grading rubric (Goertzen and Klaus 2023), tumor budding as biomarker for colorectal cancer (Bokhorst et al 2020) — agreement or concordance among two or more raters or judges (inter-rater reliability) needs to be established (same citations and references therein). For binomial data, we would be tempted to use the phi coefficient, Is it actually reliable Cohen’s kappa (two judges) or Fleiss Kappa (two or more judges) is a better tool. Phi coefficient and both assessment scores were introduced in Chapter 9.2.
For ratio scale data, agreement among scores of two or more scores from judges There is an enormous number of articles on reliability measures in the social sciences and you should be aware of a classical paper on reliability by Shrout and Fleiss (1979) (see also McGraw and Wong, 1996). Both the ICC and the Pearson product moment correlation, r, which we will introduce in Chapter 16, are measures of strength of linear association between two ratio scale variables (Jinyuan et al 2016). But ICC is more appropriate for association between repeat measures of the same thing, eg, repeat measures of running speed or agreement between judges. In contrast, the product moment correlation can be used to describe association between any two variables, eg, between repeat measures of running speed, but also between say running speed and maximum jumping height. The concept of repeatability of individual behavior or other characteristics is also a common theme in genetics and so you should not be surprised to learn that the concept actually traces to RA Fisher and his invention of ANOVA. Just as in the case of the sociology literature, there are many papers on the use and interpretation of repeatability in the evolutionary biology literature (eg, Lessels and Boag 1987; Boake 1989; Falconer and Mackay 1996; Dohm 2002; Wolak et al 2012).
Agreement and repeatability are Model II (random effects) because the subjects, items, or raters being studied are treated as a random sample from a larger population rather than specific, fixed levels of interest. In reliability studies, subjects are not chosen for their specific characteristics but as representatives of the population variability. The goal is to infer whether a measurement tool works for any future subject or rater, not just the ones tested in the study. These factors are designed to estimate variance components and generalize results beyond the specific sample used. Put another way, the goal of Model II is often to estimate how much variance is due to differences between subjects versus within subjects (repeatability), which requires treating the subject effect as random.
There are many ways to analyze these kinds of data but a good way is to treat this problem as a one-way ANOVA with Random Effects. Thus, the Random Effects model permits the partitioning of the variation in the study into two portions: the amount that is due to differences among the subjects or judges or intervention versus the amount that is due to variation within the subjects themselves. The Factor is the Subjects and the levels of the factor are how ever many subjects are measured twice or more for the response variable.
If the subjects performance is repeatable, then the Mean Square Between (Among) Subjects, , component will be greater than the Mean Square Error component, , of the model. There are many measures of repeatability or reliability, but the intraclass correlation coefficient or ICC is one of the most common. The ICC may be calculated from the Mean Squares gathered from a Random Effects one-way ANOVA. ICC can take any value between zero and one.
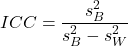
where
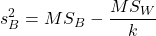
and

B and W refers to the among group (between or among groups mean square) and the within group components of variation (error mean square), respectively, from the ANOVA, MS refers to the Mean Squares, and k is the number of repeat measures for each experimental unit. In this formulation k is assumed to be the same for each subject.
By example, when a collection of sprinters run a race, if they ran it again, would the outcome be the same, or at least predictable? If the race is run over and over again and the runners cross the finish lines at different times each race, then much of the variation in performance times will be due to race differences largely independent of any performance abilities of the runners themselves and the Mean Square Error term will be large and the Between subjects Mean Square will be small. In contrast, if the race order is preserved race after race: Jenny is 1st, Ellen is 2nd, Michael is third, and so on, race after race, then differences in performance are largely due to individual differences. In this case, the Between-subjects Mean Square will be large as will the ICC, whereas the Mean Square for Error will be small, and so will the ICC.
Can the intraclass correlation be negative?
In theory, no. Values for ICC range between zero and one. The familiar Pearson product moment correlation, Chapter 16, takes any value between -1 and +1. However, in practice, negative values for ICC will result if 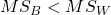 .
In other words, if the within group variability is greater than the among group variability, then negative ICC are possible. The question is whether negative estimates are ever biologically relevant or, simply result of limitations of the estimation procedure. Small ICC values and few repeats increases the risk of negative ICC estimates. Thus, a negative ICC would be “simply a(n) “unfortunate” estimate (Liljequist et al 2019). However, there may be situations in which negative ICC is more than unfortunate. For example, repeatability, a quantitative genetics concept (Falconer and Mackay 1996), can be negative (Nakagawa and Schielzeth 2010).
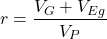
Repeatability reflects the consistency of individual traits over time (or spatially, eg, scales on on a snake), is defined as the ratio of within individual differences and among individuals differences. Thus, within individual variance is attributed to general environmental effects,  , whereas variance among individuals is both genetic and environmental. Scenarios for which repeated measures on the same individual may occur under environmental conditions, termed specific environmental effects or
 by Falconer and Mackay (1996), that negatively affect performance are not hard to imagine — it remains to be determined how common these conditions are and whether or not estimates of repeatability are negative.
ICC Example
I extracted 15 data points from a figure about nitrogen metabolism in kidney patients following treatment with antibiotics (Figure 1, Mitch et al 1977). I used a web application called WebPlot Digitizer (https://apps.automeris.io/wpd/), but you can also accomplish this task within R via the digitize package. I was concerned about how steady my hand was using my laptop’s small touch screen, a problem that very much can be answered by thinking statistically, and taking advantage of the ICC. So, rather than taking just one estimate of each point I repeated the protocol for extracting the points from the figure three times generating a total of three points for each of the 15 data points or 45 points in all. How consistent was I?
Let’s look at the results just for three points, #1, 2, and 3.
In the R script window enter
points = c(1,2,3,1,2,3,1,2,3)
Change points to character so that the ANOVA command will treat the numbers as factor levels.
points = as.character(points)
extracts = c(2.0478, 12.2555, 16.0489, 2.0478, 11.9637, 16.0489, 2.0478, 12.2555, 16.0489)
Make a data frame, assign to an object, eg, “digitizer”
digitizer = data.frame(points, extracts)
The dataset “digitizer” should now be attached and available to you within Rcmdr. Select digitizer data set and proceed with the one-way ANOVA.
Output from oneway ANOVA command
Model.1 <- aov(extracts ~ points, data=digitizer)

 summary(Model.1)
            Df    Sum Sq   Mean Sq  F value     Pr(>F)
points       2 313.38895 156.69448 16562.49 5.9395e-12 ***
Residuals    6   0.05676   0.00946
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

numSummary(extracts , groups = points,
+   statistics=c("mean", "sd"))
         mean           sd data:n
1  2.04780000 0.0000000000      3
2 12.15823333 0.1684708085      3
3 16.04890000 0.0000000000      3
End R output. We need to calculate the ICC
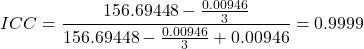
I’d say that’s pretty repeatable and highly precise measurement!
But is it accurate? You should be able to disentangle accuracy from precision based on our previous discussion (Chapter 3.5), but now in the context of a practical way to quantify precision.
ICC calculations in R
We could continue to calculate the ICC by hand, but better to have a function. Here’s a crack at the function to calculate ICC along with a 95% confidence interval.
myICC <- function(m, k, dfN, dfD) {
 testMe <- anova(m)
 MSB <- testMe$"Mean Sq"[1]
 MSE <- testMe$"Mean Sq"[2]
 varB <- MSB - MSE/k
 ICC <- varB/(varB+MSE)
 fval <- qf(c(.025), df1=dfN, df2=dfD, lower.tail=TRUE)
 CI = (k*MSE*fval)/(MSB+MSE*(k-1)*fval)
 LCIR = ICC-CI
 UCIR = ICC+CI
 myList = c(ICC, LCIR, UCIR)
 return(myList)
}
The user supplies the ANOVA model object (eg, Model.1 from our example), k, which is the number of repeats per unit, and degrees of freedom for the among groups comparison (2 in this example), and the error mean square (6 in this case). Our example, run the function
m2ICC = myICC(Model.1, 3, 2,6); m2ICC
and R returns
[1] 0.9999396 0.9999350 0.9999442
with the ICC reported first, 0.9999396, followed by the lower limit (0.9999350) and the upper limit (0.9999442) of the 95% confidence interval.
Instead of writing your own function, several R packages can calculate the intraclass correlation coefficient (ICC) and its variants. These packages include: irr, psy, psych, and rptR. For complex experiments involving multiple predictor variables, these packages are helpful for obtaining the correct ICC calculation (cf Shrout and Fleiss 1979; McGraw and Wong 1996). For the one-way ANOVA it is easier to just extract the information you need from the ANOVA table and run the calculation directly. We do so for a couple of examples.
Example: Are marathon runners consistent more consistent than my commute times?
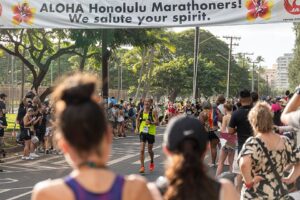
Figure 1.Honolulu Marathon 2024 participant. Image credit: Pdubs.94, licensed under CC BY 4.0 (Creative Commons Attribution 4.0 International License), via Wikipedia.
A marathon is 26 miles, 385 yards (42.195 kilometers) long (World Athletics.org). And yet, tens of thousands of people choose to run in these events. For many, running a marathon is a one-off, the culmination of a personal fitness goal. For others, it’s a passion and a few are simply extraordinary, elite runners who can complete the courses in 2 to 3 hours (Table 3). That’s about 12.5 miles per hour. For comparison, my 20 mile commute on the H1 freeway on Oahu typically takes about 40 minutes to complete, or 27 miles per hour (Table 2, yes, I keep track of my commute times, per Galton’s famous maxim: “Whenever you can, count”).
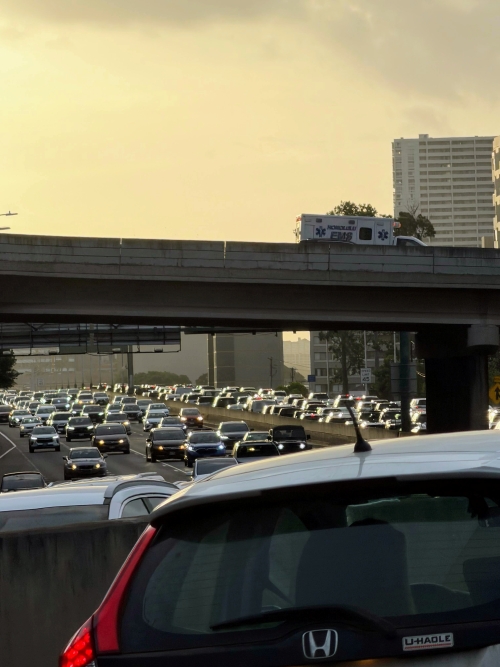
Figure 2. View west along Interstate H-1 (Lunalilo Freeway) at 6:30AM on a weekday, Honolulu, Oahu, Hawaii. Image used with permission, credit: S. Dohm.
Table 2. A sampling of average commute speeds, miles per hour (mph), on the H1 freeway during DrD’s morning commute (distance about 19.3 miles).
| Week | Monday | Tuesday | Wednesday | Thursday | Friday |
|---|---|---|---|---|---|
| 1 | 28.5 | 23.8 | 28.5 | 30.2 | 26.9 |
| 2 | 25.8 | 22.4 | 29.3 | 26.2 | 27.7 |
| 3 | 26.2 | 22.6 | 24.9 | 24.2 | 34.3 |
| 4 | 23.3 | 26.9 | 31.3 | 26.2 | 30.2 |
Try on your own.
Calculate the ICC for my commute speeds.
Run the one-way ANOVA to get the necessary mean squares and input the values into our ICC function. We have
require(psych)
m2ICC = myICC(AnovaModel.1, 4, 4,11); m2ICC
[1] 0.7390535 0.6061784 0.8719286
Repeatability, as estimated by the ICC, was 0.74 (95% CI 0.606, 0.872), for repeat measures of commute times.
We can ask the same about marathon runners — how consistent from race to race are these runners? The following data are race times drawn from a sample of runners who completed the Honolulu Marathon in both 2016 and 2017 in 2 to 3 hours (times recorded in minutes). In other words, are elite runners consistent?
Table 3. Honolulu marathon running times (min) for eleven repeat, elite runners.
| ID | Time |
|---|---|
| P1 | 179.9 |
| P1 | 192.0 |
| P2 | 129.9 |
| P2 | 130.8 |
| P3 | 128.5 |
| P3 | 129.6 |
| P4 | 179.4 |
| P4 | 179.7 |
| P5 | 174.3 |
| P5 | 181.7 |
| P6 | 177.2 |
| P6 | 176.2 |
| P7 | 169.0 |
| P7 | 173.4 |
| P8 | 174.1 |
| P8 | 175.2 |
| P9 | 175.1 |
| P9 | 174.2 |
| P10 | 163.9 |
| P10 | 175.9 |
| P11 | 179.3 |
| P11 | 179.8 |
Stacked worksheet, P refers to person, therefore P1 is person ID 1, P2 is person ID 2, and so on.
After running a one-way ANOVA, here are results for the marathon runners
m2ICC = myICC(Model.1, 2, 10,11); m2ICC
[1] 0.9780464 0.9660059 0.9900868
Repeatability, as estimated by the ICC, was 0.98 (95% CI 0.966, 0.990), for repeat measures of marathon performance. Put more simply, knowing what a runner did in 2016 I would be able to predict their 2017 race performance with high confidence, 98%!
And now, we compare: the runners are more consistent!
Clearly this is an apples-to-oranges comparison, but it gives us a chance to think about how we might make such comparisons. The ICC will change because of differences among individuals. For example, if individuals are not variable, if everyone finishes the race at the same time, then the ICC will be low (or even zero). Because there is no variance to be attributed to individual differences, the proportion of total variance explained by those differences will be being minimal.
Visualizing repeated measures.
Waterfall plot.
If just two measures, then a profile plot will do. We introduced profile plots in the paired t-test chapter (Ch10.3). For more than two repeated measures, a line graph will do (see question 9 below). Another graphic increasingly used is the waterfall plot (waterfall chart), particularly for before and after measures or other comparisons against a baseline. For example, it’s a natural question for our eleven marathon runners — how much did they improve on the second attempt of the same course? Figure 3 shows my effort to provide a visual.
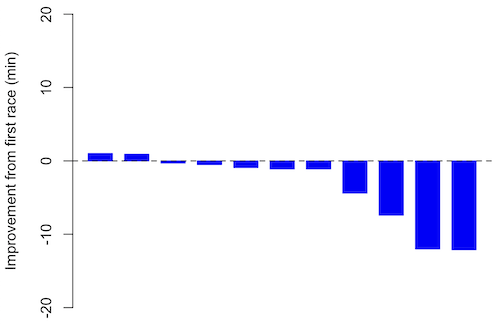
Figure 3. Simple waterfall plot of race improvement for Table 3 data. Dashed horizontal line at zero.
R code
Data wrangling: Create a new variable, eg, race21, by subtracting the first time from the second time. Multiply by -1 so that improvement (faster time in second race) is positive. Finally, apply descending sort so that improvement is on the left and increasingly poorer times are on the right.
df <- data.frame(
ID = rep(paste0("P", 1:11), each = 2),
Time = c(179.9,192.0,
129.9,130.8,
128.5,129.6,
179.4,179.7,
174.3,181.7,
177.2,176.2,
169.0,173.4,
174.1,175.2,
175.1,174.2,
163.9,175.9,
179.3,179.8)
)

# Convert to wide format
df_wide <- reshape(df, idvar = "ID", timevar = "ID",
direction = "wide")

# Extract first and second times manually
time_matrix <- matrix(df$Time, ncol = 2, byrow = TRUE)
colnames(time_matrix) <- c("Time1", "Time2")

# Calculate improvement (second - first)
base21 <- time_matrix[,2] - time_matrix[,1]

# Sort for waterfall display
base21 <- sort(base21, decreasing = TRUE)

# Waterfall plot
barplot(base21, col="blue", border="blue", space=0.5,
ylim=c(-20,20),
ylab="Improvement from first race (min)")
abline(h=0, lty=2)
Interpretation.
From the graph (Fig 3) we see that few of the racers improved their times the second time around — a few had decreased times.
Spaghetti plots.
Spaghetti plots, which display individual trajectories over time or multiple measurements, is a specialized line plot effective for visualizing the consistency of performance. The vertical thickness or spread of a single subject’s line across measurements indicates their level of repeatability. A “flat” line indicates high repeatability, while a volatile, zig-zagging line indicates low repeatability. Spaghetti plots are useful to visualize growth, decline, or stability over time for a single performance measure.
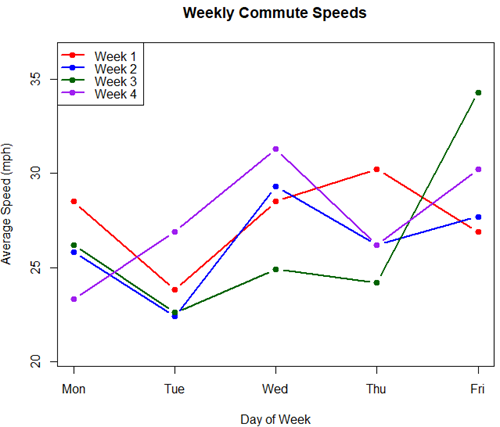
Figure 4. A spaghetti plot of average commute speeds from Table 2 data.
R code
# 1. Enter the data from Table 2.
commute <- data.frame(
Week = 1:4,
Monday = c(28.5, 25.8, 26.2, 23.3),
Tuesday = c(23.8, 22.4, 22.6, 26.9),
Wednesday = c(28.5, 29.3, 24.9, 31.3),
Thursday = c(30.2, 26.2, 24.2, 26.2),
Friday = c(26.9, 27.7, 34.3, 30.2)
)

head(commute)

# 2. Set the X-axis points
days <- 1:5
day_names <- c("Mon", "Tue", "Wed", "Thu", "Fri")

# 3. Create empty plot
# Find range of Y to ensure all data fits
ymin <- min(commute[, 2:6]) - 2
ymax <- max(commute[, 2:6]) + 2

plot(NA, xlim = c(1, 5), ylim = c(ymin, ymax),
xlab = "Day of Week", ylab = "Average Speed (mph)",
main = "Weekly Commute Speeds", xaxt = "n")

# Add X-axis labels
axis(1, at = 1:5, labels = day_names)

# 4. Add lines for each week (spaghetti)
colors <- c("red", "blue", "darkgreen", "purple")
for (i in 1:nrow(commute)) {
# Plot lines
lines(days, commute[i, 2:6], col = colors[i], lwd = 2, type = "b", pch = 19)
}

# 5. Add legend
legend("topleft", legend = paste("Week", 1:4), col = colors, lwd = 2, pch = 19)
Parallel coordinates plots.
Parallel coordinates plot allows each entity to be represented by a unique, continuous line traced across several vertical axes (each representing a different measurement or variable). High repeatability is indicated when a line remains roughly horizontal across all axes, while poor repeatability is visualized as lines that zig-zag or change direction between measurements.
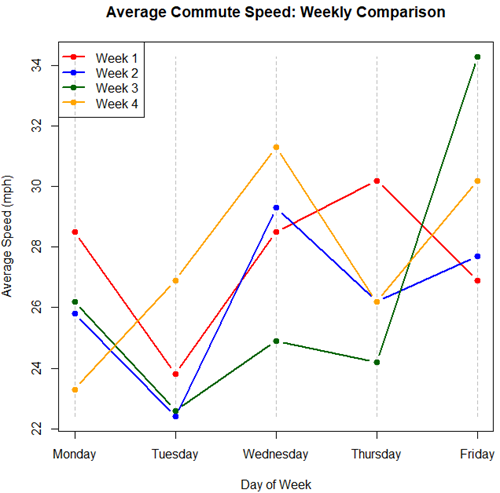
Figure 5. A parallel coordinates plot of average commute speeds from Table 2 data.
Both spaghetti plots and parallel coordinate plots can be used to visualize consistency of performance over multiple measures, but they differ significantly in their handling of data, scale, and context. Spaghetti plots are best for tracking within-subject variability over time, but quickly become a mess — like pasta tossed and sticking to a wall — when subject count increases. Parallel coordinate plots are a multivariate generalization — each line represents an individual’s profile across different tests, eg, accuracy, speed, VO2max.
R code.
# 1. Create the data frame
# see above

# 2. Extract only the numerical commute data for plotting
commute_data <- commute[, 2:6]

# 3. Setup the plot area
# Define range for y-axis
y_range <- range(commute_data)
# Define number of days (5)
num_days <- ncol(commute_data)

# Create empty plot
plot(NA, xlim = c(1, num_days), ylim = y_range,
xaxt = "n", xlab = "Day of Week", ylab = "Average Speed (mph)",
main = "Average Commute Speed: Weekly Comparison")

# Add x-axis labels
axis(1, at = 1:num_days, labels = colnames(commute_data))

# 4. Draw vertical lines for each day
for (i in 1:num_days) {
lines(c(i, i), y_range, col = "grey", lty = 2)
}

# 5. Add lines for each week (repeated measures)
colors <- c("red", "blue", "darkgreen", "orange")
for (i in 1:nrow(commute_data)) {
lines(1:num_days, commute_data[i, ], col = colors[i], lwd = 2, type = "b", pch = 19)
}

# 6. Add legend
legend("topleft", legend = paste("Week", commute$Week), col = colors, lwd = 2, pch = 19)
Heat map.
Heat map quickly identify patterns, such as an individual’s performance improving, degrading, or remaining stable over time. For example, uniform, solid colors across rows (individuals) or columns (time/trials) indicate high consistency, while varied colors indicate poor repeatability.
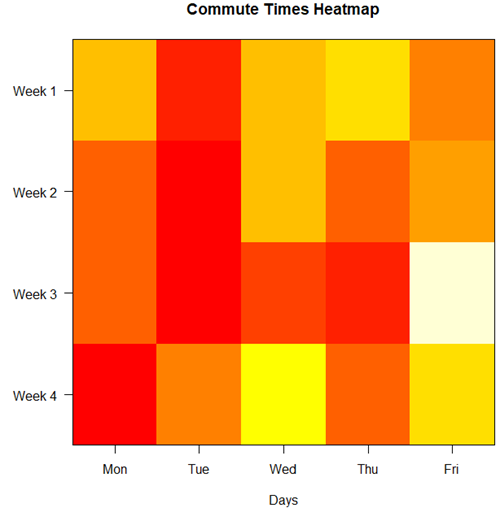
Figure 6. A heat map of the commute speeds data set.
R code.
# 1. Create the data
# Week is excluded from matrix to only include numerical commute times
commute_data <- matrix(c(
28.5, 23.8, 28.5, 30.2, 26.9,
25.8, 22.4, 29.3, 26.2, 27.7,
26.2, 22.6, 24.9, 24.2, 34.3,
23.3, 26.9, 31.3, 26.2, 30.2
), nrow = 4, byrow = TRUE)

# 2. Add row and column names
rownames(commute_data) <- c("Week 1", "Week 2", "Week 3", "Week 4")
colnames(commute_data) <- c("Mon", "Tue", "Wed", "Thu", "Fri")

# 3. Create the heatmap
# Use t() to transpose so weeks are rows and days are columns
# Use rev() on rows to have Week 1 at the top
image_data <- t(apply(commute_data, 2, rev))

# Set up the plotting area (margins for labels)
par(mar = c(5, 6, 4, 2))

# Plot the matrix
# Option 1
image(1:nrow(image_data), 1:ncol(image_data), image_data,
col = heat.colors(12),
axes = FALSE, xlab = "Days", ylab = "",
main = "Commute Times Heatmap")

# Add axes labels
axis(1, at = 1:5, labels = colnames(commute_data))
axis(2, at = 1:4, labels = rev(rownames(commute_data)), las = 1)
box()
Interpretation.
The graphs (Fig 4 – 6) show a lack of trends in consistency of drive speeds. The heat map suggests more consistency on Monday — low speeds (Fig 4 & Fig 5), but that’s a stretch.
An example for you to work, from our Measurement Day
If you recall, we had you calculate length and width measures on shells from samples of gastropod and bivalve species. In the table are repeated measures of shell length, by caliper in mm, for a sample of Conus shells (Fig 7 and Table 4).
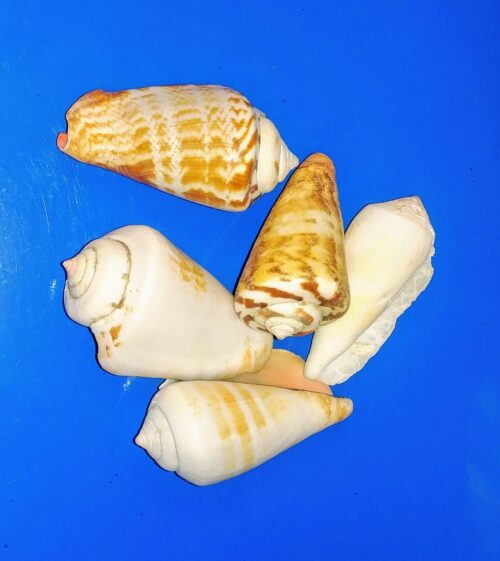
Figure 7. Conus shells, image by M. Dohm.
Repeated measures of the same 12 Conus shells.
Table 4. Unstacked dataset of repeated length measures on 12 shells
| Sample | Measure1 | Measure2 | Measure3 |
|---|---|---|---|
| 1 | 45.74 | 46.44 | 46.79 |
| 2 | 48.79 | 49.41 | 49.67 |
| 3 | 52.79 | 53.45 | 53.36 |
| 4 | 52.74 | 53.14 | 53.14 |
| 5 | 53.25 | 53.45 | 53.15 |
| 6 | 53.25 | 53.64 | 53.65 |
| 7 | 31.18 | 31.59 | 31.44 |
| 8 | 40.73 | 41.03 | 41.11 |
| 9 | 43.18 | 43.23 | 43.2 |
| 10 | 47.1 | 47.64 | 47.64 |
| 11 | 49.53 | 50.32 | 50.24 |
| 12 | 53.96 | 54.5 | 54.56 |
Maximum length from from anterior end to apex with calipers. Repeated measures were conducted blind to shell id, sampling was random over three separate time periods.
Questions
- Consider data in Table 2, Table 3, and Table 4. True or False: The arithmetic mean is an appropriate measure of central tendency. Explain your answer.
- Enter the shell data into R; Best to copy and stack the data in your spreadsheet, then import into R or R Commander. Once imported, don’t forget to change Sample to character, otherwise R will treat Sample as ratio scale data type. Run your one-way ANOVA and calculate the intraclass correlation (ICC) for the dataset. Is the shell length measure repeatable?
- The marathon results in Table 2 are paired data, results of two races run by the same individuals. Make a profile plot for the data (see Ch10.3 for help).
- A profile plot is used to show paired data; for two or more repeat measures, use a line graph instead.
A. Produce a line graph for data in Table 4. The line graph is an option in R Commander (Rcmdr: Graphs Line graph…), and can be generated with the following simple R code:
lineplot(Sample, Measure1, Measure2, Measure3)
B. What trends, if any, do you see? Report your observations.
C. Make another line plot for data in Table 2. Report any trend and include your observations.
Quiz Chapter 12.3
Fixed effects, random effects, and agreement
Chapter 12 contents
- Introduction
- The need for ANOVA
- One way ANOVA
- Fixed effects, random effects, and agreement
- ANOVA from “sufficient statistics”
- Effect size for ANOVA
- ANOVA posthoc tests
- Many tests one model
- References and suggested readings
12.2 – One way ANOVA
Introduction
In ANalysis Of VAriance, or ANOVA for short, we likewise have tools to test the null hypothesis of no difference between between categorical independent variables — often called factors when there’s just a few levels to keep track of — and a single, dependent response variable. But now, the response variable is quantitative, not qualitative like the  tests.
Analysis of variance, ANOVA, is such an important statistical test in biology that we will take the time to “build it” from scratch. We begin by reminding you of where you’ve been with the material.
We already saw an example of this null hypothesis. When there’s only one factor (but with two or more levels), we call the analysis of means and “one-way ANOVA.” In the independent sample t-test, we tested whether two groups had the same mean. We made the connection between the confidence interval of the difference between the sample means and whether or not it includes zero (ie, no difference between the means). In ANOVA, we extend this idea to a test of whether two or more groups have the same mean. In fact, if you perform an ANOVA on only two groups, you will get the exact same answer as the independent two-sample t-test, although they use different distributions of critical values (t for the t-test, F for the ANOVA — a nice little fact for you square the t-test statistic, you’ll get the F-test statistic:  ).
Let’s say we have an experiment where we’ve looked at the effect of different three different calorie levels on weight change in middle-aged men.
I’ve created a simulated dataset which we will use in our ANOVA discussions. The data set is available at the end of this page (scroll down or click here).
We might graph the mean weight changes ( SEM); Below are two possible outcomes of our experiment (Fig 1).
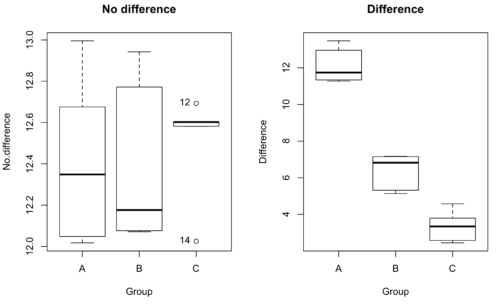
Figure 1. Hypothetical results of an experiment, box plots. Left, no difference among groups; Right, large differences among groups.
As statisticians and scientists, we would first calculate an overall or grand mean for the entire sample of observations; we know this as the sample mean whose symbol is  . But this overall mean is made up of the average of the sample means. If the null hypothesis is true, then the all of the sample means all estimate the overall mean. Put another way, being a member of a treatment group doesn’t matter, ie, there is no systematic effect, all differences among subjects are due to random chance.
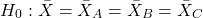
The hypotheses among are three groups or treatment levels then are:
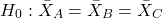
Null that there are no differences among the group means. And the alternative hypotheses include any (or all) of the following possibilities
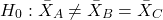
or maybe
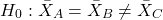
or… have we covered all possible alternate outcomes among three groups?
In either case, we could use one-way ANOVA to test for “statistically significant differences.”
Three important terms you’ll need for one-way ANOVA
FACTOR: We have one factor of interest. For example, a factor of interest might be
- Diet fed to hypertensive subjects (men and women)
- Distribution of coral reef sea cucumber species in archipelagos
- Antibiotic drug therapy for adolescents with Acne vulgaris (click see Webster 2002 for review).
Note 1: Character vs factor. In R programming, while it is true that a treatment variable can be a character vector like Gender*, such vectors are handled by R as string. In contrast, by claiming Gender as a factor, R handles the variable as a nominal data type. Hence, ANOVA and other GLM functions expect any treatment variable to be declared as a factor:
Gender <- c("Gender non-conforming", "Men", "Non-binary", "Transgender", "Women", "Declined"); Gender
[1] "Gender non-conforming" "Men" "Non-binary" "Transgender"
[5] "Women" "Declined"
# it’s a string vector, not a factor
is.factor(Gender)
[1] FALSE
Change string vector to a factor.
Gender <- as.factor(Gender); is.factor(Gender) [1] TRUE
* For discussions of ethics of language inclusivity and whether or not such information should be gathered, see Henrickson et al 2020.
LEVELS: We can have multiple levels (2 or more) within the single factor. Some examples of levels for the Factors listed:
- Three diets (DASH), diet rich in fruits & vegetables, control diet)
- Five archipelagos (Hawaiian Islands, Line Islands, Marshal Islands, Bonin Islands, and Ryukyu Islands)
- Five antibiotics (ciprofloxacin, cotrimoxazole, erythromycin, doxycycline, minocycline).
RESPONSE: There is one outcome or measurement variable. This variable must be quantitative (ie, on the ratio or interval scale). Continuing our examples then
- Reduction in systolic pressure
- Numbers of individual sea cucumbers in a plot
- number of microcomedo.
Note 2: A comedo is a clogged pore in the skin; a microcomedo refers to the small plug. Yes, I had to look that up, too.
The response variable can be just about anything we can measure, but because ANOVA is a parametric test, the response variable must be normally distributed!
Note on experimental design
As we discuss ANOVA, keep in mind we are talking about analyzing results from an experiment. Understanding statistics, and in particular ANOVA, informs how to plan an experiment. The basic experimental design is called a completely randomized experimental design, or CDR, where treatments are assigned to experimental units at random.
In this experimental design, subjects (experimental units) must be randomly assigned to each of these levels of the factor. That is, each individual should have had the same probability of being found in any one of the levels of the factor. The design is complete because randomization is conducted for all levels, all factors.
Thinking about how you would describe an experiment with three levels of some treatment, we would have
Table 1. Summary statistics of three levels for some ratio scale response variable.
| Level 1 |
sample mean1 |
sample standard deviation1 |
| Level 2 |
sample mean2 |
sample standard deviation2 |
| Level 3 |
sample mean3 |
sample standard deviation3 |


Note 3: Table 1 is the basis for creating the box plots in Figure 1.
ANOVA sources of variation
ANOVA works by partitioning total variability about the means (the grand mean, the group means). We will discuss the multiple samples and how the ANOVA works in terms of the sources of variation. There are two “sources” of variation that can occur:
- Within Group Variation
- Among Groups Variation
So let’s look first at the variability within groups, also called the Within Group Variation.
Consider and experiment to see if DASH diet reduces systolic blood pressure in USA middle-aged men and women with hypertension (Moore et al 2001). After eight weeks we have
We get the corrected sum of squares, SS, for within group

and the degrees of freedom, DF, for within groups
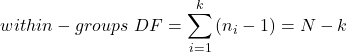
where i is the identity of the groups,  is the individual observations within group i, is the group i mean, ni is the sample size within each group, N is the total sample size of all subjects for all groups, and k is the number of groups.
Importantly, this value is also referred to as “error sums of squares” in ANOVA. It’s importance is as follows — In our example, the within group variability would be zero if and only if all subjects within the same diet lost exactly the same amount of weight. This is hardly ever the case of course in a real experiment. Because there are almost always some other unknown factors or measurement error that affect the response variable, there will be some unknown variation among individuals who received the same treatment (within the same group). Thus, the error variance will generally be larger than zero.
The first point to consider: your ANOVA will never result in statistical differences among the groups if the error variance is greater than the second type of variability, the variability between groups.
The second type of variability in ANOVA is that due to the groups or treatments. Individuals given a calorie-restricted diet will lose some weight; individuals allowed to eat a calorie-rich diet likely will gain weight, therefore there will be variability (a difference) due to the treatment. So we can calculate the variability among groups. We get the corrected sum of squares for among groups
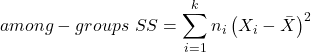
and the degrees of freedom for among groups
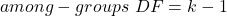
where i is the identity of the groups, is the grand mean as defined in Measures of Central Tendency (Chapter 3.1), is the group i mean, ni is the sample size within each group, N is the total sample size of all subjects for all groups, and k is the number of groups.
The sums of squares here is simply subtracting the mean of each population from the overall mean.
- If the Factor is not important in explaining the variation among individuals then all the population means will be similar and the sums of squares among populations would be small.
- If the Factor is important in explaining some of the variation among the individuals then all the population means will NOT be the same and the sums of squares among populations would be large.
Finally, we can identify the total variation in the entire experiment. We have the total sum of squares.
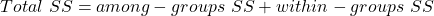
Thus, the insight of ANOVA is that variation in the dataset may be attributed to a portion explained by differences among the groups and differences among individual observations within each group. The inference comes from recognizing that if the among group effect is greater than the within group effect, then there will be a difference due to the treatment levels.
Mean squares
To decide whether the variation associated with the among group differences are greater than the within group variation, we calculate ratios of the sums of squares. These are called Mean Squares or MS for short. The ratio of the Mean Squares is called F, the test statistic for ANOVA.
For the one-way ANOVA we will have two Mean Squares and one F, tested with degrees of freedom for both the numerator  , and denominator
 ).
The Mean Square for (among) groups is
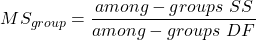
The Mean Square for error is
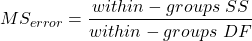
And finally, the value for F, the test statistic for ANOVA, is
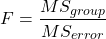
Worked example with R
A factor with three levels, A, B, and C
group <- c("A", "A", "A", "B", "B", "B", "C", "C", "C")
and their responses, simulated
response <- c(10.8, 11.8, 12.8, 6.5, 7, 8, 3.8, 2.8, 3)
We create a data frame
all <- data.frame(group, response)
Of course, you could place the data into a worksheet and then import the worksheet into R. Regardless, we now have our dataset.
Now, call the ANOVA function, aov, and assign the results to an object (eg, Model.1)
Model.1 <- aov(response ~ group, data=all)
Now, visualize the ANOVA table
summary(Model.1)
and the output from R, the ANOVA table, is shown below
Note 4: Rcmdr: Statistics → Means → One-way ANOVA… see figures 2 and 3 below
Table 2. Output from aov() command, the ANOVA table, for the “Difference” outcome variable.
           Df   Sum Sq    Mean Sq   F value       Pr(>F)
group       2   111.16      55.58     89.49    0.0000341 ***
Residuals   6     3.73       0.62
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Let’s take the ANOVA table one row at a time
- The first row has subject headers defining the columns.
- The second row of the table “groups” contains statistics due to group, and provides the comparisons among groups.
- The third row, “Residuals” is the error, or the differences within groups.
Moving across the columns, then, for each row, we have in turn,
- the degrees of freedom (there were 3 groups, therefore 2 DF for group),
- the Sums of Squares, the Mean Squares,
- the value of F, and finally,
- the P-value.
R provides a helpful guide on the last line of the ANOVA summary table, the “Signif[icance] codes,” which highlights the magnitude of the P-value.
Note 5: On the use of “error” and “residuals.” Error refers to the difference between an observed value and the true population value. Residual is the difference between an observed value and a value predicted by a model. In ANOVA, the “error variance” or “residual variance” is the variation within groups unexplained by the tested factor. It is what remains after the effects of the model are accounted for.
What to report? ANOVA problems can be much more complicated than the simple one-way ANOVA introduced here. For complex ANOVA problems, report the ANOVA table itself! But for the one-way ANOVA it would be sufficient to report the test statistic, the degrees of freedom, and the p-value, as we have in previous chapters (eg, t-test, chi-square, etc.). Thus, we would report:
F = 89.49, df = 2 and 6, p = 0.0000341
where F = 89.49 is the test statistic, df = 2 (degrees of freedom for the among group mean square) and 6 (degrees of freedom for the within group mean square), and p = 0.0000341 is the p-value.
In Rcmdr, the appropriate command for the one-way ANOVA is simply
Rcmdr: Statistics → Means
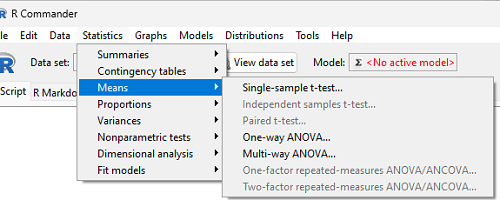
Figure 2. Screenshot Rcmdr select one-way ANOVA.
which brings up a simple dialog. R Commander anticipates factor (Groups) and Response variable. Optional, choose Pairwise comparisons of means for post-hoc test (Tukey’s) and, if you do not want to assume equal variances (see Chapter 13), select Welch F-test.
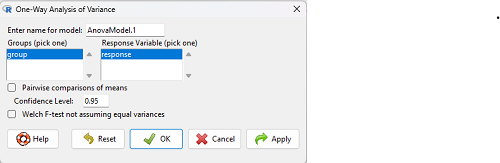
Figure 3. Screenshot Rcmdr select one-way ANOVA options.
Questions
1. Review the example ANOVA Table and confirm the following
- How many levels of the treatment were there?
- How many sampling units were there?
- Confirm the calculation of
 and using the formulas contained in the text.
- Confirm the calculation of F using the formula contained in the text.
- The degrees of freedom for the F statistic in this example were 2 and 6 (F2,6). Assuming a two-tailed test with Type I error rate of 5%, What is the critical value of the F distribution (see Appendix 20.4)
2. Repeat the one-way ANOVA using the simulated data, but this time, calculate the ANOVA problem for the “No.difference” response variable.
3. Leaf lengths from three strains of Arabidopsis thaliana plants grown in common garden are shown in Fig 2. Data are provided for you in the following R script.
arabid <- c("wt","wt","wt","AS1","AS1","AS1","AS2","AS2","AS2")
leaf <- c(4.909,5.736,5.108,6.956,5.809,6.888,4.768,4.209,4.065)
leaves <- data.frame(arabid,leaf)
- Write out a null and alternative hypotheses
- Conduct a test of the null hypothesis by one-way ANOVA
- Report the value of the test statistic, the degrees of freedom, and the P-value
- Do you accept or reject the null hypothesis? Explain your choice.
Figure 4. Box plot of lengths of leaves of a 10-day old plant from on of three strains of Arabidopsis thaliana.
4. Return to your answer to question 7 from Chapter 12.1 and review your answer and modify as appropriate to correct your language to that presented here about factors and levels.
5. Conduct the one-way ANOVA test on the Comet assay data presented question 7 from Chapter 12.1. Data are copied for your convenience to end of this page. Obtain the ANOVA table and report the value of the test statistics, degrees of freedom, and p-value.
a. Based on the ANOVA results, do you accept or reject the null hypothesis? Explain your choice.
Quiz Chapter 12.2
One-way ANOVA
Data used in this page
Difference, no difference
Table 12.2 Difference or No Difference
| Group | No.difference | Difference |
|---|---|---|
| A | 12.04822 | 11.336161 |
| A | 12.67584 | 13.476142 |
| A | 12.99568 | 12.96121 |
| A | 12.01745 | 11.746712 |
| A | 12.34854 | 11.275492 |
| B | 12.17643 | 7.167262 |
| B | 12.77201 | 5.136788 |
| B | 12.07137 | 6.820242 |
| B | 12.94258 | 5.318743 |
| B | 12.0767 | 7.153992 |
| C | 12.58212 | 3.344218 |
| C | 12.69263 | 3.792337 |
| C | 12.60226 | 2.444438 |
| C | 12.02534 | 2.576014 |
| C | 12.6042 | 4.575672 |
Comet assay, antioxidant properties of tea
Data presented in Chapter 12.1
Chapter 12 contents
12.1 – The need for ANOVA
Introduction
Moving from an experiment with two groups to multiple groups is deceptively simple: we move from one comparison to multiple comparisons. Consider an experiment in which we have randomly assigned patients to receive one of three doses of a statin drug (lower cholesterol), including a placebo (eg, Tobert and Newman 2015). Thus, we have three groups or levels of a single treatment factor and we’ll want to test the null hypothesis that the group (level) means are all equal as opposed to the alternative hypothesis in which one or more of the group means, eg, group A, Group B, group C, are different.
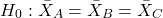
The correct procedure is to analyze multiple levels of a single treatment with a one-way analysis of variance followed by a suitable post-hoc (“after this”) test. Two common post-hoc tests are Tukey’s range test (aka Tukey’s HSD [honestly significant difference] test), which is for all pairwise comparisons, or the Dunnett’s test, which compares groups against the control group. Post-hoc tests are discussed in Chapter 12.6.
Note. To get the number of pairwise comparisons  of observations, let
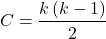
for more on pairwise comparisons, see 10.1 – Compare two independent sample means
For our three group experiment, how many pairwise comparisons can be tested? Therefore,  , and we have
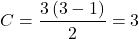
Thus, for our three groups, A, B, and C, there are three possible pairwise comparisons.
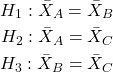
How many pairwise comparisons for a four group experiment? Check your work, you should get  .
The multiple comparison problem
Let’s say that we’re stubborn. We could do many single two-sample t-tests — certainly, your statistical software won’t stop you — this is a situation that calls for statistical reasoning. Here’s why we should not: we will increase the probability of rejecting a null hypothesis when the null hypothesis is true (eg, discussion in Jafari and Ansari-Pour 2019). That is, the chance we will commit a Type I error increases if we do not account for the lack of independence in these sets of pairwise tests evaluated by t-tests. This is multiplicity or the multiple comparison problem.
Review: when we perform a two-sample t-test we are willing to reject a true null hypothesis 5% of the time. This is what is meant by setting the critical probability value (alpha) = 0.05. By “willing” we mean that we know that our conclusions could be wrong because we ar3 working with samples, not the entire population. (Of course at the time, we have no way of actually knowing WHEN we are wrong, but we do want to know how likely we could be wrong!) However, if we compare three population means we have three separate null hypotheses.
HO: one or more of the means are different.
But if we conduct these as separate independent sample t-tests, then we are implicitly making the following null hypothesis statements:
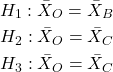
Thus, we have a 5% chance of being wrong for the first hypothesis and/or a 5% chance of being wrong for the second hypothesis and/or a 5% chance of being wrong for the third hypotheses. The chance that we will be wrong for at least one of these hypotheses must now be greater than 5%.
For three separate hypotheses there is a 14% chance of being wrong when we have the probability value for each individual t-test set at α = 0.05. How did we get this result? The point is that these tests are not independent, they are done on the same data set, therefore you can’t simply apply the multiplication probability rule.
Here’s how to figure this: for the set of three hypotheses, the probability of incorrectly rejecting at least one of the null hypotheses is
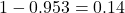
So, for three t-tests on the same experiment, the Type I error overall tests (experiment-wise) is actually 14% not 5%. It gets worse as the number of combinations (groups and therefore hypotheses) increases. For four groups, Type I error is actually
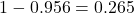
That’s 26.5%, not 5%.
If we have just five populations means to compare the probability of rejecting a null hypothesis when it is true climbs to 60%! How did this happen? The probability or correctly rejecting all of them is now
So, the probability of incorrectly rejecting one test (Type I error) is now
instead of the 5% we think we are testing.
The key argument for why you must use ANOVA to analyze multiple samples instead of a combination of t-tests!! ANOVA guarantees that the overall error rate is the specified 5%.
Why is the Type I error not 5% for each test? Because we conducted ONE experiment, we can conduct only ONE test (we could be right, we could be wrong 5% of the time). If we conduct the experiment over again, on new subjects, each time resulting in new and therefore independent data sets, then Type I error = 5% for each of these independent experiments.
Now, I hope I have introduced you to the issue of Type I error at the level of a single comparison and the idea of an experiment, holding Type I error-rates at 5% across all hypotheses to be evaluated in an experiment. You may wonder why anyone would make this mistake now. Actually, people make this “mistake” all the time and in some fields like evaluating gene expression for microarray data, this error was the norm, not the exception (see for example discussion of this in Jeanmougin et al 2010).
To conclude, if one does multiple tests on the same experiment, whether it is t-tests or some other test for that matter, then our subsequent tests are related. This is what we mean by independence in statistics — and there are many ways that nonindependence may occur in experimental research. For example, we introduced the concept of pseudoreplication, when observations are treated as if they are independent, but they are not (see Chapter 5.2). The “multiple comparison problem” specifically refers to the lack of independence when all the data set from a single experiment is parsed into lots of separate tests. Philosophically, there must be a logical penalty — and that is reflected in the increase in Type I error.
Clearly something must be done about this!
Corrections to account for the multiple comparisons problem
The family-wise (aka experiment-wise) error rate for multiple comparisons is kept at 5%, and each individual-wise comparison is compared against a more strict (ie, smaller Type I error rate). Put another way, the family-wise error rate is the chance of a number of false positives: making a mistake when we consider many tests simultaneously. The simplest correction for the individual-wise error rate is the Bonferroni correction: test each individual comparison at Type I error equal to  , where C is the number of comparisons. The Šidák correction,
 , and the Holm-Bonferroni method are alternatives with reportedly better statistical properties (eg, reduced Type II error rates; Ludbrook 1998, Sauder and DeMars 2019).
ANOVA is a solution
One possible solution for getting the correct experiment-wise error rate: adjust for differences in probability for multiple comparisons with the t-test. We used post-hoc tests presented above: you could evaluate the tests after accounting for the change in Type I error. This is what is done in many cases. For example, in genomics. In the early days of gene expression profiling by microarray, it was common to see researchers conduct t-tests for each gene. Since microarrays can have thousands of genes represented on the chip, then these researchers were conducting thousands of t-tests, arranging the t-tests by P-value and counting the number of P-values less than 5% and declaring that the differences were statistically significant.
This error didn’t stand long, and there are now many options available to researchers to handle the “multiple comparisons” problem (some probably better than others, research on this very much an ongoing endeavor in biostatistics). The Bonferroni correction was an available solution, largely replaced by the Holm (aka Holm-Bonferroni) method (Holm 1979). Recall that the Bonferroni correction judged individual p-values statistically significant only if they were less than , where, again, α is the family-wise error rate (eg, α = 5%) and C was the number of comparisons. The Holm method orders the C p-values from lowest to highest rank. The method then evaluates lowest p-value, if less than , then reject hypothesis for that comparison. Proceed to next p-value, if less than , then reject hypothesis for that comparison, and so on until no more comparisons are less than .
A MUCH better alternative is to perform a single analysis that takes the multiple-comparisons problem into account: Single Factor ANOVA, also called the one-way ANOVA, plus the post-hoc tests with error correction. We introduce one-way ANOVA in the next section. Post-hoc tests are discussed in Chapter 12.6.
Questions
- You should be able to define and distinguish how Bonferoni correction, Dunnett’s test, and Tukey’s test methods protect against inflation of Type I error.
- What will be the experiment-wise error rate for an experiment in which there are only two treatment groups?
- Experiment-wise error rate may also be called _______________ error rate.
- List and compare the three described posthoc approaches to correct for multiple comparison problem,
- Glycophosphate-tolerant soybean is the number one GMO (genetically modified organism) crop plant worldwide. Glycophosphate is the chief active ingredient in Roundup, the most widely used herbicide. A recent paper examined “food quality” of the nutrient and elemental composition of plants drawn from fields which grow soy by organic methods (no herbicides or pesticides) and GMO plants subject to herbicides and pesticides. A total of 28 individual t-tests were used to compare the treatment groups for different levels of nutrients and elements (eg, vitamins, amino acids, etc.,); the authors concluded that 10 of these t-tests were statistically significant at Type I error rate of 5%. Discuss the approach to statistical inference by the authors of this report; include correct use of the terms experiment-wise and individual-wise in your response and suggest an alternative testing approach if it is appropriate in your view.
- In Chapter 4.2 we introduced a data set from an experiment. The experiment looked at DNA damage quantified by measuring qualities in a Comet Assay including the Tail length, the percent of DNA in the tail, and olive moment. The data set is copied to end of this page. In the next chapter I’ll ask you to conduct the ANOVA on this experiment. For now, answer the following questions.
a. What is the response variable? Defend your choice(s).
b. Why is this an ANOVA problem? Include as part of your explanation a statement of the null hypothesis.
Quiz Chapter 12.1
The need for ANOVA
Data used in this page
comet assay dataset
| Treatment | Tail | TailPercent | OliveMoment* |
|---|---|---|---|
| Copper-Hazel | 10 | 9.7732 | 2.1501 |
| Copper-Hazel | 6 | 4.8381 | 0.9676 |
| Copper-Hazel | 6 | 3.981 | 0.836 |
| Copper-Hazel | 16 | 12.0911 | 2.9019 |
| Copper-Hazel | 20 | 15.3543 | 3.9921 |
| Copper-Hazel | 33 | 33.5207 | 10.7266 |
| Copper-Hazel | 13 | 13.0936 | 2.8806 |
| Copper-Hazel | 17 | 26.8697 | 4.5679 |
| Copper-Hazel | 30 | 53.8844 | 10.238 |
| Copper-Hazel | 19 | 14.983 | 3.7458 |
| Copper | 11 | 10.5293 | 2.1059 |
| Copper | 13 | 12.5298 | 2.506 |
| Copper | 27 | 38.7357 | 6.9724 |
| Copper | 10 | 10.0238 | 1.9045 |
| Copper | 12 | 12.8428 | 2.5686 |
| Copper | 22 | 32.9746 | 5.2759 |
| Copper | 14 | 13.7666 | 2.6157 |
| Copper | 15 | 18.2663 | 3.8359 |
| Copper | 7 | 10.2393 | 1.9455 |
| Copper | 29 | 22.6612 | 7.9314 |
| Hazel | 8 | 5.6897 | 1.3086 |
| Hazel | 15 | 23.3931 | 2.8072 |
| Hazel | 5 | 2.7021 | 0.5674 |
| Hazel | 16 | 22.519 | 3.1527 |
| Hazel | 3 | 1.9354 | 0.271 |
| Hazel | 10 | 5.6947 | 1.3098 |
| Hazel | 2 | 1.4199 | 0.2272 |
| Hazel | 20 | 29.9353 | 4.4903 |
| Hazel | 6 | 3.357 | 0.6714 |
| Hazel | 3 | 1.2528 | 0.2506 |
Tail refers to length of the comet tail, TailPercent is percent DNA damage in tail, and OliveMoment refers to Olive's (1990), defined as the fraction of DNA in the tail multiplied by tail length
Chapter 12 contents
3.4 – Estimating parameters
Introduction.
What you will find on this page. Definitions for constants, variables, and parameters as used in data analytics. Statistical bias and the concept of unbiased estimators are discussed. The different types of error are introduced along with definitions of accuracy and precision. Statistics used to quantify error are presented in the next section, Chapter 3.4.
Estimating parameters.
Parameters belong to populations; they are fixed but unknown. Parameters are characteristics of populations: the typical average height and weight of five year old children; What is the normal range of values for height and weight of five year old children; average and range of gene expression of TP53 in epithelial lung cells of 50 year old non-smoking humans; etc. Because we generally do not have at our disposal surveys — census — of entire populations for these characteristics, we sample and calculate descriptive statistics for a subset of individuals from populations: these statistics, the mean height, range of height, etc., are variables. We expect average height, range of height, etc., to change, to vary, from sample to sample. A constant, as the word implies, is not variable and remains unchanged.
We estimate parameters (means, variances) from samples of observations from a population. Intuitively then, our estimates are only as good as how representative of the population the sample is. Statistics allows us to be more precise: we can define “how good” our estimates are by asking about, and quantifying, the accuracy and precision of our estimates.
Notwithstanding the notion of “personalized medicine,” our goal in science is to understand cause and effect among sets of observations on samples from a population. We ask, what is the link between lung cancer and smoking? We know that smoking tobacco cigarettes increases risk of cancer, but not everyone who smokes will get cancer (Pesch et al., 2012). Tumorigenic risk is in part mediated by heredity (cf. Trifiletti et al 2017). That’s one way we run into problems in statistics: the biological phenomenon is complicated in ways we are not yet aware of, and thus samples drawn from populations are heterogeneous. Put another way, we think there is one population, but there may be many distinct populations. By chance, repeated samples drawn from the population include individuals with different risk associated with heredity.
As an aside, this is precisely why the concept of personalized medicine is important. Medical researchers have learned that some people with breast cancer respond to treatment with trastuzumab, a monoclonal antibody, but others do not (review in Valabrega et al 2007). Responders have more copies of a gene, copy number variation, for an EGF-like receptor called HER2. In contrast, non-responders to trastuzumab have fewer copies of this receptor (and are said to be HER2-negative in an antibody test for HER2). Thus, we speak about people with breast cancer as if the disease is the same, and from a statistical point of view, we would assume that individuals with breast cancer are of the same population. But they are not — and so the treatment fails for some, but works for others. In this example, we have a mechanism or cause to explain why some do not respond; their breast cancer is not associated with increased copy numbers of HER2. And so in studies with breast cancer, statisticians may account for differences in HER2 status. Note: Fewer than 30% of breast cancer may have over-expression of HER2, (Bilous et al. 2003).
Clearly, HER2 status would be used by statisticians when drawing samples from population, and we would not mistake samples. But, in many other situations we are not aware of any differences and so we assume our samples come from the same population. Note that even with imperfect knowledge about samples, experimental design is intended to help mediate heterogeneous samples. For example, this is why treatment controls need to be used, or case controls are included in studies.
Random assignment to groups also is an attempt to control for unknowns: if random, then all treatment groups will likely include representatives of the numerous co-factors that contribute to risk.
Statisticians have an additional, technical burden: there are often a variety of ways (algorithms) to describe or make inferences about samples, and they are not equally capable of giving us “truth.” Estimates of a parameter are not going to be exactly the true value of the parameter! This is the problem of identifying unbiased ways to estimate parameters. In statistics, bias quantifies whether an algorithm to calculate a particular statistic (e.g., the mean or variance), is consistently too low or too high.
Random sampling.
Random sampling from the population is likely to be our best procedure for obtaining representative samples, but it is not foolproof (we’ll return to situations where random sampling fails to provide adequate samples of populations in Chapter 5.5 Importance of randomization in experimental design). However, a second concern is how to calculate the mean, how to calculate the variance. In the section on Descriptive Statistics (Chapter 3.2), we presented how to calculate the arithmetic mean — the simple average — but also introduced you to other calculations for the middle (e.g., median, geometric mean, harmonic mean). How to know which “middle” is correct?
Statisticians use the concept of bias — the simple arithmetic mean is an unbiased estimator of the population parameter, but a correction needs to be made to the calculation of sample variance to remove bias. Bias implies that the estimator systematically misses the target in some way. Good or “best” parameter estimates are, on average, going to be close to the actual parameter if we collected many samples of the population (this will depend on the sample size and the variability of the data). Earlier we introduced Bessel’s correction to the sample variance, divide the sum of squares by n – 1 and not N as we did for the population variance, so that it is an unbiased estimator of the sample variance. Thus, statisticians have worked out how well their statistical equations work as estimators; concepts of expected values or the expectation are used to evaluate how well an estimator works. In statistics, the expected value of a statistic is calculated by multiplying each of the possible outcomes by the likelihood each outcome will occur and then summing all of those values..
We need to add a bit more to our discussion about measurement and estimation.
Types of error.
To measure is to assign a number to something, a variable. Measurements can have multiple levels, but are of the four data types: nominal, ordinal, interval scale, and ratio scale. Nominal and ordinal types are categorical or qualitative; interval and ratio are continuous or quantitative. Errors in measurement represent differences between what is observed and recorded compared with the true value, i.e., the actual population value. With respect to measurement we distinguish between random errors and systematic errors. Random errors occur by chance, and are thus expected to vary from one measurement instance from another. Random error may lead to measures larger or smaller than the true value. Systematic errors are of a kind that can be attributed to failures of an experimental design or instrument.
Accuracy is reflected in the question: how close to the true value is our measure? Accuracy is distinct from precision, the concept of how clustered together are repeated values for the same measurement. All measurement has associated error, which may be divided into two kinds: random error and systematic error.
We tend to think of error in terms of mistakes, mistakes by us or as failure of the measurement process. However, in biology research, that is too restrictive of a meaning for error. First, experimental error occurs when the estimates derived from the samples — sample mean, sample variance — differ from the population parameters — population mean, population variance. Second, error in biology ranges from mistakes in data collection to real differences among individuals for a characteristic. The latter source, error among individuals, is of course, not a mistake, but rather, it’s the “very spice of life” (Cowper 1845). We’ll leave the study of individual differences, biological error, for later. This section is concerned with error in the sense of mistakes.
Random error includes things like chance error in an instrument leading to different repeat measures of the same thing and to the reality that individual differences exist for most biological traits. We minimize the effects of this kind of error by randomizing: we randomly select samples from populations; we randomly assign samples to treatment groups. Random error can make it hard to differentiate treatment effects. Random error decreases precision, the repeatability of measures. At worse, random error is conservative — it tends to mean we miss group differences, we conclude that the treatment (e.g., aspirin analgesics) has no effect on the condition (e.g., migraines). This kind of error is referred to as a Type II error (Chapter 8).
The experimental design remedy for random error is to increase sample size, a key conclusion drawn from power analysis on experiments, discussed in Chapter 11. The other type of error, systematic error, a type of bias, is more in line with the idea of errors being synonymous with mistakes. Uncalibrated instruments yield incorrect measures. And these kinds of errors lead us to make errors that can be more problematic. An example? Back in the early 1990s when I started research on whole animal metabolic rates (e.g., Dohm et al 1994, Beck et al 1995), we routinely set baseline carbon dioxide, CO2, levels to 0.035% of volume of dry air (350 ppm, parts per million), which reflected ambient levels of CO2 at the time (see Figure 4 in Chapter 4.6).
#NOAA monthly data from Mauna Loa Observatory
co2.1994 <- c(358.22, 358.98, 359.91, 361.32, 361.68, 360.80, 359.39, 357.42, 355.63, 356.09, 357.56, 358.87)
You are probably aware, today, background CO2 have increased considerably even since the 1980s. Data for 2021 (average 420 ppm — reporting just 2 significant figures) are provided below
co2.2021 <- c(415.49, 416.72, 417.61, 419.01, 419.09, 418.93, 416.9, 414.42, 413.26, 413.9, 414.97, 416.67)
source: Global Monitoring Lab, NOAA
Thus, if I naively compared rates of CO2 produced by an animal at rest,  , measured today against the data I gathered back in the 1990s without account for the change in background CO2 in my analysis, I will have committed a systematic error: values of on animals would be systematically higher than values for 1988 when I apply a baseline correction.
Examples of error.
One under-reported cost of next-generation sequencing technologies is that base calls, the process of assigning a nucleotide base to chromatogram peaks has more errors than traditional Sanger-based sequencing methods (Fox et al 2014). In “next-generation-sequencing” (NGS) methods, individual DNA fragments are assigned sequences, whereas Sanger methods took the average sequence of a collection of DNA fragments; thus, in principle, NGS methods should be able to characterize variation of mixtures of sequences in ways not available to traditional sequencing approaches. However, artifacts introduced in sample preparation and PCR amplification lead to base calling errors (Fox et al 2014).
Gene expression levels will differ among tissue types, thus mixed samples from different tissues will misrepresent gene expression levels.
Measurement of energy expenditure, oxygen uptake and carbon dioxide release by an organism, have long been sources of study in ecology and other disciplines. A classic measure is called basal metabolic rate, measured as the rate of oxygen consumption of an endothermic animal, post-absorptive (i.e., not digesting food), at rest but not sleeping, while the animal is contained within a thermal-neutral environment (Blaxter 1989).
Accuracy and precision.
Two properties of measurement are the accuracy of the measure and its precision. Accuracy is defined as the closeness of a measured value to its true value. Precision refers to the closeness of a second measure to the first, to the closeness of a third measure to the first and second, and so on. Precision refers to repeatability of measurement. We suggested use of the coefficient of variation, defined with examples in Chapter 3.2, as a way to quantify precision.
Consider the accuracy and precision of three volumetric pipettors: p1000, which has a nominal range between 100 and 1000 μL (microliters); p200, which has a range between 20 and 200 μL; p100, which has a range between 10 and 100 μL. Which of these three pipettors do you think would have the best accuracy and precision for dispensing 100 μL? We can test pipettors by measuring the mass of distilled water dispensed by the pipettor on an analytical balance. For 100 μL of distilled water at standard temperature and pressure conditions, the mass of the water would be 0.100 grams. The results are shown in the table, and a dot plot is shown in the figure to help us see the numbers.
Table 1. Mass (grams) of 100 μL of distilled water dispensed by three volumetric pipettors*
| p1000 | p200 | p100 | |
| 0.113 | 0.100 | 0.101 | |
| 0.114 | 0.100 | 0.100 | |
| 0.113 | 0.100 | 0.100 | |
| 0.115 | 0.099 | 0.101 | |
| 0.113 | 0.100 | 0.101 | |
| 0.112 | 0.100 | 0.100 | |
| 0.113 | 0.100 | 0.100 | |
| 0.111 | 0.100 | 0.100 | |
| 0.114 | 0.101 | 0.101 | |
| 0.112 | 0.100 | 0.100 | |
| mean: | 0.113 | 0.100 | 0.1004 |
| standard deviation: | 0.0012 | 0.0005 | 0.0005 |
*Temperature 21.5 °C, barometric pressure 76.28 cm mercury (elevation 52 meters). Data presented in Table 1 were not corrected to standard temperature or pressure.
Here is the code for the R run; assuming that you have started R commander, then copy and paste each line into the R Commander script window; if not, enter the script one line at a time in the R console. Recall that the hashtag, #, is used to add comment lines.
Note 1: A reminder: Don’t include the last two rows from Table 1 in your data set; these contain descriptive statistics and are not your data.
#create the variables
p1000 <- c(0.113, 0.114, 0.113, 0.115, 0.113, 0.112, 0.113, 0.111, 0.114, 0.112)
p100 <- c(0.101, 0.1, 0.1, 0.101, 0.101, 0.1, 0.1, 0.1, 0.101, 0.1)
p200 <- c(0.1, 0.1, 0.1, 0.099, 0.1, 0.1, 0.1, 0.1, 0.101, 0.1)
#create a data frame
pipet <- data.frame(p100,p200,p1000)
attach(pipet)
#stack the data
stackPipet <- stack(pipet[, c("p100","p200","p1000")])
#Add variable names
names(stackPipet) <- c("mass", "pipet")
#create the dot plot
with(stackPipet, RcmdrMisc::Dotplot(mass, by=pipet, bin=FALSE))
From Table 1 we see that the means for the p100 and p200 were both close to the target mass of 0.1 g. The mean for the p1000, however, was higher than the target mass of 0.1 g. A dot plot is a good way to display measurements (Fig. 1).
Figure 1. Dot plot of pipet results.
Note 2: Dotplot() is part of the RcmdrMisc package; if you are using the Rcmdr script window (please do!), then the functions in RcmdrMisc are already available and you wouldn’t need to use RcmdrMisc:: (package name plus double-colon operator) to call the Dotplot() function (more properly, referred to as namespaces). Thus, with(stackPipet, Dotplot(mass, by=pipet, bin=FALSE)) would work perfectly well within the Rcmdr script window.
From the dot plot we can quickly see that the p1000 was both inaccurate (the data fall well above the true value), and lacked precision (the values were spread about the mean value). The other two pipettors showed accuracy and looked to be similar in precision, although only two of ten values for the p200 were off target compared to four of ten values for the p100. Thus, we would conclude that the p200 was best at dispensing 100 microliters of water.
In the next chapter we apply statistics to estimate our confidence in this conclusion. In contrast to measurement, estimation implies calculation of a value. In statistics, estimates may be a point, e.g., a value of a collection of data, or an interval, e.g., a confidence interval.
Summary.
This is your first introduction into the concept of experimental design, as defined by statisticians! One of the key tasks for a statistical analyst is to have an appreciation for measurement accuracy and precision as established in the experiment. Precise and accurate measurement levels determine how well questions about the experiment can be answered. At one extreme, if a measure is imprecise, but accurate, then it will be challenging to quantify differences between a control group and a treatment group. At the other extreme, if the measure is precise, but inaccurate, the danger would be differences between the treatment and control group may be more likely, even when the groups are truly not different!
Questions.
- List the types of error in measuring mRNA expression levels on a gene for a sampling of cells from biopsy of normal tissue and a biopsy of a tumor. Assume use of NEXGEN methods for measuring gene expression. Distinguish between technical errors and biological errors.
- If confidence interval are useful for estimating accuracy, what statistic do we call to quantify precision?
Quiz Chapter 3.4
Estimating parameters
Chapter 3 contents
6.2 – Ratios and probabilities
Introduction
One common objective of a research project is comparison between quantities: one effective way to communicate a comparison is to construct a ratio. Ratios provide a standardized way to compare different data sets. The purpose of this page is introduce the wealth of types of ratios used for quantification of comparisons, from indexes to ratios.
Let’s review our definitions again. An event is some occurrence. As you know, a ratio is one number, the numerator, divided by another called the denominator. A proportion is a ratio where the numerator is a part of the whole. A rate is a ratio of the frequency of an event during a certain period of time. A rate may or may not be a proportion, and a ratio need not be a proportion, but proportions and rates are all kinds of ratios. If we combine ratios, proportions, and/or rates, we construct an index.
Ratios
Yes, data analysis can be complicated, but we start with this basic idea. Much of the statistics is based on frequency measures, eg, ratios, rates, proportions, indexes, and scales.
Ratios are the association between two numbers, one random variable divided by another. Ratios are used as descriptors and the numerator and denominator do not need to be of the same kind. Business and economics are full of ratios. For example, return on investment (ROI), eg, earnings equals net income divided by number of shares outstanding, the Price-Earnings, or P/E ratio, is the ratio of the price of a stock to the earnings per stock, as well as many others are used to summarize performance of a business, and to compare performance of one business against another.
Note 1: ROI also stands for region of interest — a sample in a data set identified by the analyst for a particular interest. Often refers to a specific area in an image.
Ratios are deceptively convenient way to standardize a variable for comparisons, ie, how many times one number contains another. For example, when estimating bird counts for different areas, or different birding effort (intensity, time searched), we may correct counts by accounting for area in which counts were made or the total time spent counting, for a per-unit ratio (Liermann et al 2004).
Practice: There were 1,326 day undergraduate students enrolled in 2014 at Chaminade University of Honolulu and the Sullivan Library added 8469 new items (ebooks, journals, etc,) to its collection during 2014. What is the ratio of new items per student?
Data collected from Chaminade University website at www.chaminade.edu on 3 July 2014.
Practice: For another example, what is ratio of annual institutional aid a student at Chaminade University may expect to receive compared to a student at Hawaii Pacific University?
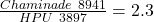
Thus, in 2014, Chaminade offered more than twice the institutional aid to its students then does HPU (both institutions are private universities, data from retrieved on 3 July 2014 from www.cappex.com).
Relative change, Fold-change and orders of magnitude
It’s common practice to report on the amount of change between two quantities recorded over time. Relative change (often percentage) describes change relative to an initial value. Relative change in root length b
To make percent increase (decrease), simply multiple 100%.
(1) 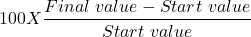
The ratio between two quantities, eg, to compare mRNA expression levels of genes from organisms exposed to different conditions, researchers may report fold-change. Fold change is often reported as log base 2 change.
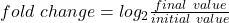
Why log base 2? Symmetry and ease of reporting. A doubling becomes +1 and a halving becomes -1. Without log transformation, doubling is +2, but having is +0.5.
Relative change is useful for reporting percent changes, fold change for ratios, although if the change is small in amount, then relative change can be misleading, eg, value goes from five to ten, then the relative change is 100%, but effectively, a very small change in absolute units. Similarly, fold change becomes a large, but likely meaningless comparison, if the denominator is close to zero.
An example of calculation of fold change. Rates of the expression from cells exposed to heavy metal divided by expression under basal conditions. Gene expression under different treatments may be evaluated by calculating fold-change as the log base2 of the ratio of expression of a gene for one treatment divided by expression of same gene from control conditions. Copper is an essential trace element, but excess exposure to copper is known to damage human health, including chronic obstructive pulmonary disease. One proposed mechanism is that cell injury promotes an epithelial-to-mesenchymal shift. In a pilot study (N.I.H. INBRE P20RR016467), we investigated gene expression changes by quantitative real-time polymerase chain reaction (qPCR) in a rat lung Type II alveolar cell line exposed to copper sulfate compared to unexposed cells. Record cycle threshold values, CT, for each gene, where CT is number of cycles required for the fluorescent signal to exceed background levels; CT is inversely proportional to amount of cDNA (mRNA) in the sample. Genes investigated were ECAD, FOXC2, NCAD, SMAD, SNAI1, TWIST, and VIM, with ATCB as reference gene. ECAD expression is marker of epithelial cells, whereas FOXC2, NCAD, SNAI1, TWIST, and VIM expression marker of mesenchymal cells. After calculating  values, geometric means of normalized values of three replicates each are shown in Table 1.
Note 2: The  is a relative change quantification that relates the PCR signal of the normalized gene of interest (GOI) transcript in a treatment group to another sample, eg, an untreated control. is now a widely applied method to analyze the relative changes in gene expression from real-time quantitative PCR experiments (relevant papers on the analysis method, Livak and Schmittgen (2001) and Schmittgen and Livak (2008) have been cited more than 230K times, Pubmed 2026. See also Rao et al (2013).)
Log-transform, introduced in Ch03.2, was used because gene expression levels vary widely on the original scale and any log-transform will reduce the variability. log-base 2 specifically was used for fold-change in particular because it is easy to interpret (eg, see discussion in Bergemann and Wilson 2011 and Corliss et al 2024), and provides symmetry (all log-transforms provide this symmetry). For example, log(1/2, 2) returns -1, while log(2/1, 2) returns +1. Thus, base 2, we see a decrease by half or doubling of original scale is a fold change of  . In contrast,
log(1/2, 10) returns -0.301, while log(2/1, 10) returns +0.301 — which is perfectly accurate, but deceptive to interpret.
log-base 2 is commonly employed to calculate the number of bits — binary digits — for a given number of values. For example, 8 bits (0 – 7), then log2(8-1), and R returns 2.807355. Round, add 1, and the number of bits is3. Related R code, if want to calculate and print te binary representation of of a number, eg, 8, try
myBits <- intToBits(8)
paste(as.character(myBits),collapse="")
On a more casual note, log-base 2 is useful to calculate number of rounds for a single-elimination playoff tournament, eg, NCAA men’s and women’s basketball tournament or March Madness (NCAA). As of 2025, 60 teams are invited, plus the four winning teams from four play-in games, for a total of 64 teams. The number of rounds is log2(64) and R returns 6. These six are referred to as First Round, Second Round, Sweet Sixteen, Elite Eight, Final Four, and the Championship Game. The play-in games are referred to as the”First Four.” The function draw_bracket() of R package SwimmeR can be used to plot a simple playoff bracket.
Table 1. Mean and fold change of gene expression values from qPCR for several genes from a rat lung cell line.*
| Control | Copper-sulfate | Fold change | |
| ECAD | 34.6 | 35.7 | 0.6 |
| NCAD | 28.5 | 24.0 | 27.2 |
| SMAD | 29.5 | 25.0 | 28.2 |
| SNAI1 | 25.5 | 28.1 | 0.2 |
| FOXC2 | 27.6 | 27.0 | 1.9 |
| VIM | 23.1 | 16.4 | 134.4 |
| TWIST | 25.1 | 22.9 | 5.6 |
* INBRE funding, P20RR016467.
At face value, following four hour exposure to copper sulfate in media, some evidence that the epithelial cell line adopted gene expression profile of mesenchyme-like cells. However, weakness of fold-change is clear from Table 1: the quantity is sensitive to small values. ECAD expression in the cell line is low, thus high numbers of PCR cycles (mean = 36) and treated cells not much fewer (mean = 34.4).
Note 3: Calculation of is included. Geomean CT were
| Control | CuSO4 | |
| ACTB | 32.2 | 32.5 |
| NCAD | 28.5 | 24.0 |
For control cells, 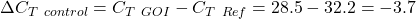
For treatment cells, 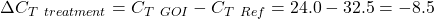
and 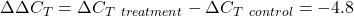
log2, 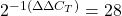
table value differs by rounding
Orders of magnitude
In addition to fold change, order of magnitude is another common way to compare quantities. While fold change returns the multiplier between two numbers, order of magnitude generally refers to differences in multiples of ten, logarithmic.
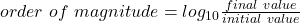
Thus, a difference of one order of magnitude is the number multiplied by 101, three orders of magnitude is the number multiplied by 103, and so on. A change from 10 to 100 is a one order of magnitude increase; the same change, 10 to 100, is a ten-fold change. It’s a difference of scale. If a person’s salary increases by 3%, from $49K to $50,470, reporting this as an “order of magnitude” increase is nonsensical as a communication device (magnitude of change is just 0.01). By contrast, fold change for the same increase would be 1.03 — also indicative of a negligible increase, but a cleaner representation.
Rates
Rates are a class of ratios in which the denominator is some measure of time. For example, the four year graduation rate of some Hawaii universities are shown in Table 2.
Table 2. Percent students graduation with bachelor’s degrees within four years or six years (cohort 2014, data source NCES.ed.gov)
| School | Private/Public | Four-year, Percent graduation |
Six-year, Percent graduation |
| Chaminade University | Private (non-profit) | 43 | 58 |
| Hawaii Pacific University | Private (non-profit) | 31 | 46 |
| University of Hawaii – Hilo | Public | 15 | 38 |
| University of Hawaii – Manoa | Public | 35 | 62 |
| University of Hawaii – West Oahu | Public | 16 | 39 |
| University of Phoenix | Private (for profit) | 0 | 19 |
Examples of rates
Rates are common in biology. To name just a few
- Basal metabolic rate (BMR), often measured by indirect calorimetry, reported in units kiloJoules per hour.
- Birth rates and mortality (death) rates, components of population growth rate.
- Extinction rate, how often over a given time species go extinct.
- Growth rate, which may refer to growth of the individual (somatic growth rate), or increase of number of individuals in a population per unit time.
- Molecular clock hypothesis, rate of amino acid (protein) or nucleotide (DNA) substitution is approximately constant per year over evolutionary time.
- Mutation rate, frequency of new mutations in a DNA sequence of an organism over time.
- Photosynthetic rate, convert light energy into chemical energy.
- Phred quality score, error rates of incorrectly called nucleotide bases by the sequencer.
Proportions
Proportions are also ratios, but they are used to describe one part to the whole. For example, 902 women (self-reported) day undergraduate students enrolled in 2014 at Chaminade University in Honolulu, Hawaii.
Practice: Given that the total enrollment for Chaminade in 2014 was of 1,326, calculate the proportion of female students to the total student body.

More practice: A common statistic in agriculture is germination percentage, count the number of seeds that sprout over a period of time divided by total number of seeds planted multiplied by 100. Figure 1 shows an example of a germination trial for five tomato seeds. Seed in position 3 (left to right 1 – 5) failed to germinate, whereas the other four seeds display range of seedling growth. (A seed coat is observed next to plant 2.)
Figure 1. Example planting of five tomato seeds, day 5, on agar Petri dish (M. Dohm).
Observations conducted over 10 days. Germination defined as evidence of radicle by day 10. Data collected by student for biostatistics project. A random sample of results from three plates is presented in Table 3.
Table 3. Germination of tomato seeds on agar Petri dishes.
| Plate* | 1 | 2 | 3 | 4 | 5 |
| 18 | Yes | No | Yes | Yes | Yes |
| 13 | Yes | Yes | Yes | No | Yes |
| 20 | No | Yes | Yes | Yes | Yes |
* Random sample of three plates drawn from among 30 plates.
We calculate the percent germination for the 15 seeds planted as

Thus, for the sample of plates the germination percent was 80%, which, coincidently, is the same result if germination percent was calculated for the five seeds displayed in Figure 1.
Beginning in Chapter 7 – Probability, Risk Analysis, we introduce and use a number of proportions, for example incidence and prevalence are proportions, as is PPV — positive predictive value. Sensitivity and specificity are both proportions and also qualified as indexes.
Comparing proportions
In some cases you may wish to compare two proportions or two ratios. The hypothesis tested is the difference between the two ratios, and the test is if the confidence interval of the difference includes zero. If it does, then we would conclude there is no statistical difference between the two proportions. In R, use the prop.test function. For example, 63 women were on team sport rosters at Chaminade in 2014, a proportion of 59% of all student athletes (n = 106). Recall from the example above that women were 68% of all students at Chaminade University. Title IX compliance requires that a university “maintain policies, practices and programs that do not discriminate against anyone on the basis of gender” (NCAA, INCLUSION AND BELONGING Championing Women in Sports). In terms of athletic programs, then, universities are required to provide participation opportunities for women and men that are substantially proportionate to their respective rates of enrollment of full-time undergraduate students.
Consider Chaminade University: Is there a statistical difference between proportion of women athletes and their proportion of total enrollment? We introduce statistical inference in Chapter 8, but for now, this is a test of the null hypothesis that the difference between the two proportions is zero.
At the R prompt type (remember, anything after the # sign is a comment and ignored by R).
women = c(62,902)  #where 62 is the number of women athletes and 902 is the number of women students
students = c(106,1326)  #106 is the number of student athletes and 1326 is all students
prop.test(women,students)  #the default is a two-tailed test, ie, no group differences
And R returns
2-sample test for equality of proportions with continuity correction
 data: women out of students
X-squared = 3.6331, df = 1, p-value = 0.05664
alternative hypothesis: two.sided
95 percent confidence interval:
 -0.197532407 0.006861073
sample estimates:
 prop 1 prop 2
0.5849057 0.6802413
What is the conclusion of the test?
When you compare two groups, you’re asking whether the two groups are equal (the null hypothesis). Mathematically, that’s the same as saying the difference between the two groups is equal to zero.
First check the lower and upper limits of the confidence interval. A confidence interval is one way to report a range of plausible values for an estimate (see Ch 7.6 – Confidence intervals). It’s called a confidence interval because a probability is assigned to the range of values; a 95% confidence interval is interpreted as we’re 95% certain the true population value is somewhere between the reported limits. For our Chaminade University Title IX question, recall that we are asking whether the value of zero is included. The lower limit was -0.1975 and some change; the upper limit was 0.0068 and some change. Thus, zero is included and we would conclude that there was no statistical difference between the two proportions.
The second relevant output to look at is the p-value, or probability value. If the p-value is less than 5%, we typically reject the tested hypothesis. We will talk more about p-values and their relationship to inference testing in Chapter 8; for now, pay attention to the confidence interval (introduced in Chapter 3.4); if zero is included, then we conclude no substantial differences between the two proportions.
Indexes
Indexes are composite statistics that combine indicators. They condense complex diagnostic performance data into a single, universally understood numerical indicator.
Indexes are common in biology, and well-known business and economics indexes are reported on every day, eg, Dow Jones Industrial average combines stock prices from 30 companies listed on the New York Stock Exchange and the CPI, or Consumer Protection Index, constructed by the US Bureau of Labor Statistics from a “market basket of consumer goods and services, used by the government and other institutions to track inflation. The CPI itself is made up of numerous indexes to account for regional price differences and other factors.
Some indexes presented in this book include
- Grade point average
- Body Mass Index (BMI)
- Comet assay indexes (tail intensity, tail length, tail moment) are used to assess DNA damage among organisms exposed to environmental contaminants (eg, Mincarelli et al., 2019).
- Encephalization index, ratio of brain to body weight among species. Used to compare cognitive abilities.
- Sensitivity, specificity, NNT — number needed to treat, odds-ratio and RRR and related. See Chapter 7.1 – Probability, Risk Analysis.
- Species diversity indexes, measures of species richness and abundance. See Chapter 20.8.
Scales
Agreement scales for surveys, eg, Likert scale or sliding scale (Sullivan and Artino 2013). For example, after learning about Theranos, students were asked:
How serious is this violation in your opinion?
| Not serious
0 |
Slightly serious
0 |
Moderately serious
2 |
Serious
4 |
Very serious
19 |
a 5-point scale.
Although an intuitive measure, how fast can an individual run, challenging to determine whether individual’s performance is at physiological maximum. Particularly for measures of performance capacity that involves behavior (motivation), may apply a race quality scale (eg., binary scale “good” or “bad” Husak et al 2006).
These examples reflect ordinal scales. Many of the nonparametric tests discussed in Chapter 15 are suitable for analysis of scales.
Limitations of ratios
Although the indexes may be easy to communicate, statistically, indexes have many drawbacks. Chief among these, variation in ratios may be due to change in numerator or denominator. Ratios and any index calculated by combining ratios seem simple enough, but have complicated statistical properties. Over the years, several authors have made critical suggestions for use of ratios and indexes. Some key references are Packard and Boardman (1988), Jasienski and Oikos (1999), Nee et al (2005), and Karp et al (2012). For example, ratios, computing trait value by body weight, are often used to compare some trait among individuals or species that differ in body size. However, this normalization attempt only removes the covariation between size and the trait if there is a 1:1 relationship between size and the trait. More typically, relationship between the trait and body size is allometric, ie, the slope is not equal to one. Thus, ratio will over-correct for large size and under-correct for small size. The proper solution is to conduct the comparison as part of an analysis of covariance (ANCOVA, see Chapter 17.6).
Example
Which is the safer mode of travel: car or airplane?
The following discussion covers travel safety in the United States of America for a typical year, 2000*.
Note 4: *The following discussion excludes the 241 airline passenger deaths associated to the terrorist attacks of September 11 2001 in the USA; the NTSB also “…exclude(s illegal acts) for the purpose of accident rate computation. It also does not include considerations of 2020-2021 and effects of the COVID-19 pandemic on numbers of flights. The purpose of this discussion is not to convince you about the safety of modes of travel. Moreover, the following analysis is not necessarily the proper way to frame or analyze risk, but, rather, the purpose of this discussion is to highlight the impact of assumptions on estimating risk.
Between 2000 and 2023, there were 779 deaths associated with accidents of major air carriers in the USA. Year 2009 was the last multiple-casualty crash of a major U.S. carrier (Colgan Air Flight 3407); between 2010 and 2021, two fatal accidents, two fatalities were reported.
We’ve all heard the claim that it’s much safer to fly with a major airline than it is to travel by car (eg, Flying is getting scary. But is it still safe? CNN June 20, 2024). There are a variety of arguments, but one statistical argument goes as follows. In 2000 in the United States, 638,902,993 persons traveled by major air carrier, whereas there were 190,625,023 licensed drivers. In 2000, 92 persons died in air travel (again, major carriers only), whereas 37,526 persons died in vehicle crashes (includes drivers and passengers). Thus, the risk of dying in air travel is given as the proportion  , or 1.44e-07 (0.000014%), whereas the comparable proportion for death by motor vehicle is
 , or 1.97e-04 (0.0197%).
In other words, we can expect one death (actually 1.4) for every ten million airline passengers, but 20 deaths (actually 19.7) for every one hundred thousand licensed drivers. Thus, flying is a thousand times safer than driving (actual result 1,367 times; divide the rate of motor vehicle-caused deaths for licensed drivers by the rate for airlines). Proportions are hard to compare sometimes, especially when the per capita numbers differ (ten million vs. 100,000 in this case).
We can put the numbers onto a probability tree and get a sense of what we are looking at (Fig 2).
Figure 2. A probability tree to help visualize comparison of deaths (“yes”) by car travel and by airline travel in the United States for the year 2000.
Comparing rates and proportions
Without going into the details, we will do so in Chapter 9 Inferences on Categorical Data, comparing two rates is a chi-square, χ2, contingency table type of problem. More specifically, however, it is a binomial problem (Chapter 3.1, Chapter 6.5); there are two outcomes, death or no death, and we can describe how likely the event is to occur as a proportion. Because the numbers are large, we can use rely on the normal distribution for comparing the two proportions. We’ll explain this more in the next chapters, but for now it may be enough to present the equation for the comparison of two proportions under the assumption of normality, proportion z test.
and the null hypothesis (see Chapter 8) tested as that the two proportions are equal. This may be written as
H0 : p1-p2=0
We can assign statistical significance to the differences in events for the two modes of travel under this set of assumptions. Rcmdr has a nice menu-driven system for comparing proportions, but for now I will simply list the R commands.
At the R prompt type each line then submit the command.
total = 100000000
prop.test(c(19700,14),c(total,total)))
And the R output
prop.test(c(19700,14),c(total,total))

    2-sample test for equality of proportions with continuity
    correction

data:  c(19700, 14) out of c(total, total)
X-squared = 19658, df = 1, p-value < 2.2e-16
alternative hypothesis: two.sided
95 percent confidence interval:
 0.0001940984 0.0001996216
sample estimates:
  prop 1   prop 2
1.97e-04 1.40e-07
There’s a bit to unpack here. R is consistent; when it reports results of a statistical test, it typically returns the value of the test statistic (χ2 = 19658), the degrees of freedom for the test (df = 1), and the p-value (< 2.2e-16).
prop.test() were calculated by the Wilson Score method not the Wald method. While both are parametric tests and therefore sensitive to departures from normality (see Chapter 13.3), formulation of Wilson score method makes fewer assumptions (involving approximations of the population proportions) and therefore is considered more accurate.By convention in statistics, if a p-value, where “p” stands for probability, is less than 5%, we would say that our results are statistically significant from the null hypothesis. Looks pretty convincing to me, the difference of 19,700 deaths compared to 14 deaths is clearly different by any criterion and by the results of the statistical test, the p-value is several orders of magnitude smaller than 5%.
Safer to fly. By far, not even close. And similar conclusions would be reached if we compare different years, or averages over many years, or if we used a different way to express the amount of travel (eg, miles/year) by these modes of transportation.
Are you convinced, really? Is it safer to fly?
Let’s try a little statistical reasoning — what assumptions did I make to do these calculations? We recognize immediately that many more people travel by car: that there are way more cars being driven then there are airline planes being flown. The question then is, have we properly adjusted for this difference? Here are a few considerations. My source for the numbers is the NTS 2001 book published by the U.S. Department of Transportation (U.S. Department of Transportation). We are conducting a risk analysis, and the first step is to make sure that we are comparing “apples with apples.” Here are two alternative solutions that at least compare, “Red Delicious” apples with “Macintosh” apples.
Option 1. There are many, many more licensed drivers than there are licensed commercial airline pilots. The standard comparison offered in the background above compared deaths per licensed car driver, but a different metric for air travel, the rate per passenger. This isn’t as bad of a comparison as it may seem — after all, the majority of deaths in car accidents are of the driver themselves. But it isn’t that hard to make the direct comparison — just find out how many commercial pilots there are — a direct comparison with licensed car drivers (stated above as 190,625,023). From the FAA we see that in 2009 there were 125,738 persons with commercial certificates. Since there are only 20 major airline carriers in the United States now (a few more were active in 2000, but we’ll put this aside), the number of licenses is an over estimate of the actual number we want — how many pilots of commercial airlines — but lets use this number for starters — after all, just because a person has a drivers license doesn’t mean they drive or ride in a car.
Number of deaths/yr: Let’s use 2000 data, a typical year prior to 9/11 (and excluding the Covid-19 pandemic). Airlines: 92 deaths; motor vehicles (includes passenger cars, trucks, etc, but not motorcycles): 37,526 deaths (drivers = 25,567; passengers = 10,695; 86 others).
Which mode of travel is riskier? I get a rate a rate of 7.3 X 10⁻⁴ deaths per commercial pilot, or
92125738
compared to a rate for car drivers of 1.97 X 10⁻⁴ deaths.
To summarize what we have so far, I get a result that suggests car travel is almost four times safer
7.3 x 10-41.97 x 10-4→7.31.97 = 3.7
then traveling by commercial airliner. In whole numbers, these results translate to seven deaths for every 10,000 commercial pilots compared to two deaths for every 10,000 licensed car drivers (Fig 3).
Figure 3. Comparing totals of deaths adjusted by numbers of licensed drivers and by licensed commercial airline pilots in the United States.
R work follows. Enter and submit each command on a separate line in the script window
total = 10000
prop.test(c(2,7),c(total,total))
And the R output
prop.test(c(2,7),c(total,total))

    2-sample test for equality of proportions with continuity
    correction

data:  c(2, 7) out of c(total, total)
X-squared = 1.7786, df = 1, p-value = 0.1823
alternative hypothesis: two.sided
95 percent confidence interval:
 -0.001187816  0.000187816
sample estimates:
prop 1 prop 2
 2e-04  7e-04
What’s happened? The p-value (0.1823) is not less than 5% and so we would conclude under this scenario that there is no difference between the proportions of deaths between the two modes of travel. Let’s keep going.
Option 2. There are many, many more cars on the road then there are airplanes flying commercial passengers. The standard comparison offered in the background information above identified death rates per individual driver, but used a different metric for airline travelers (number of deaths per passenger), which confuses individuals with travelers: what we need is the number of individuals that traveled by airliner, not the total number of passengers (which is many times higher, because of repeat flyers). How can we make a fair comparison for the two modes of travel? Most people never fly whereas most people drive (or ride in a car) frequently in the United States. To me, risk of travel might be better expressed in terms of a per trip rate. I want to know, what are my chances of dying each time I get into my car versus each time I fly on a commercial jet in the United States?
Number of trips/yr. For airlines, I use the number of departures (2000 = 8,951,773). But for cars, we need to decide how to get a similar number. It’s not available directly from the DOT (and would be difficult to get — studies with randomly selected drivers can yield as many as 5 trips per day for licensed drivers). I took the number of licensed drivers and bound the problem — at the low end, let’s say that only 2 trips per week (eg, 50 weeks) are taken by licensed drivers (100 trips); at the upper end, let’s take 2 trips per day per week, or 500 trips/year. Thus, at the low end, we have 1.91 X10¹⁰ trips per year; at the upper end, 9.53 X 10¹⁰ trips per year.
Which mode of travel is riskier? Using the number of deaths/yr listed above in Option 1, I get a rate of 1.03 X 10⁻⁵ deaths/trip for air carriers
928.95 x 10⁶
compared to a rate of 1.97 X 10⁻⁶ deaths/trip for cars (lower bound) or 3.9 X 10⁻⁷ deaths/trip for cars (upper bound). Here’s what the numbers look for in a tree (taking the lower number of trips per year for cars, Fig 4).
Figure 4. Comparing totals of deaths adjusted by numbers of car trips and by numbers of airline trips in the United States.
R work follow
total = 10000000
prop.test(c(20,103),c(total,total))
And the R output
prop.test(c(20,103),c(total,total))

    2-sample test for equality of proportions with continuity
    correction

data:  c(20, 103) out of c(total, total)
X-squared = 54.667, df = 1, p-value = 1.428e-13
alternative hypothesis: two.sided
95 percent confidence interval:
 -1.057370e-05 -6.026305e-06
sample estimates:
  prop 1   prop 2
2.00e-06 1.03e-05
Now we have another really small p-value (1.428e-13), which suggests a statistically significant difference between the modes of air travel, but the difference in deaths is switched. I now have a result that suggests car travel is much safer than traveling with a commercial airliner! These calculations suggest that you are as much as 26 (upper bounds, five times for lower bounds) times more likely to die from a plane crash then you are behind the wheel. In whole numbers, these results indicate one death for every 100,000 airline flights compared to 1 death for every 500,000 (lower estimate) or 2,500,000 car trips!
Do I have it right and the standard answer is wrong? As Lee Corso used to say on ESPN’s College GameDay program, “Not so fast, my friend!” (Wikipedia). Mark Twain was right to hold the skeptic’s view. Begin by listing the assumptions and by checking the logic of the comparisons (there are still holes in my logic!!). For one, if I am considering my risk of dying by mode of travel, it is far more likely that I will be in a car accident than I will an airline accident, simply because I don’t travel by airline that much. When we consider lifetime risk, we can see why the assertion that it is “safer to fly than drive” is true — we’re far more likely to belong to one of the reference populations involving automobiles (eg, those who drive frequently, for many years) than we are to be among the frequent flyers reference populations.
Questions
1. Review and provide your own examples for
- index
- rate
- ratio
- proportion
3. Like travel safety, we are often confronted by risk comparisons like the following: Which animal is more deadly to humans, dogs or sharks? Between the two, which lead to more hospitalizations in the United States? Work through your assumptions and use results from the International Shark Attack file.
- If a person lives in Nebraska, and never visits the ocean, how does a “shark attack” risk analysis apply? Is it a fair comparison to make between dog attacks and shark attacks? Why or why not.
4. Go to cappex.com/colleges and update institutional (gift) aid offered by Chaminade and HPU. Compare to University of Hawaii-Manoa.
5. Calculate percent increase for
- Annual atmospheric CO2 1980 and 2024.
Quiz Chapter 6.2
Ratios and probabilities
Chapter 6 content
- Introduction
- Some preliminaries
- Ratios and probabilities
- Combinations and permutations
- Types of probability
- Discrete probability distributions
- Continuous distributions
- Normal distribution and the normal deviate (Z)
- Moments
- Chi-square distribution
- t distribution
- F distribution
- References and suggested readings
11.4 – Two sample effect size
Introduction
An effect size is a measure of the strength of the difference between two samples. Effect size tells us the practical importance of a result, say, the difference in outcome between a control group and the treatment group. A combined effect size is a common goal of any meta-analysis (Chapter 20.15).
Note 1: To calculate a combined effect size in meta-analysis, pool individual study effect sizes into a single summary effect. If sample size differs widely across the studies, use a weighted average. Thus, studies with more precision get more weight.
By including effect sizes, this complement inferential statistics such as p-values. Importantly, effect size moves us beyond “significant” or “not significant.” Significance tells us a difference is likely between the groups, but offers no information about the practicality of the observed difference. After all, large studies inherently have more statistical power, which, by definition implicates even small differences can be statistically significant.
In statistics there are many estimates of effect size: for categorical data, odds ratio and relative risk between exposed and unexposed groups; for quantitative data, correlation, regression slope are effect size measures, in addition to the difference between group means. For differences in means between groups, Cohen’s d (and Hedge’s g) are common statistics. In ANOVA, eta-squared ( ) and omega-squared (
 ), summarizes the proportion of total variance in the dependent variable explained by the independent variables while
 the coefficient of determination, represents the proportion of variance in the outcome explained by the predictors. Advice and help for understanding “effect size” is an enormously popular topic — nearly 3 million hits in Google Scholar and about forty-five thousand papers in Pubmed. Two highly cited papers are those by Durlak (2009) and Ferguson (2009).
The effect size statistic, Cohen’s d, is calculated by subtracting one sample mean from the other and dividing by the pooled standard deviation.
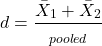
where spooled is the pooled standard deviation for the two sample means.
Hedge’s d, which uses the spooled is the pooled standard deviation for the two sample means instead of the pooled population standard deviation, is written as
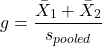
The  used in d is from an equation for pooled standard deviation was provided in Chapter 3.3, but we’ll give it again here.
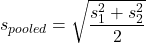
An alternative version of Cohen’s d is available for the t-test test statistic value

A d of one (1) indicates the effect size is equal to one standard deviation; a d of two (2) indicates the effect size between two sample means is equal to two standard deviations, and so on.
The variance of Cohen’s d,  , can be estimated as
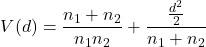
Hedges’ g (Hedges 1981), which includes a Bessel’s correction for bias in small samples, includes “ in the denominator of the pooled standard deviation calculation.
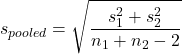
The “-2” forces the pooled variance to be larger — that makes g more conservative than d, which is of use for small sample studies.
A simple modification converts d to g. Multiple d by a small-sample size correction factor J (Durlak 2009):
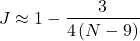
Note 2: Fall 2025 update: this section is actively being modified to better reflect what Cohen, Hedges, and others actually meant. In particular, formulas presented here should be considered as provisional awaiting confirmation and improvements to better reflect historical definitions and modern implementations.
What makes a large effect size?
Cohen cautiously suggested that values of d can be interpreted as
0.2 – small effect size
0.5 – medium effect size
0.8 – large effect size
That is, if the two group means don’t differ by much more than 0.2 standard deviations, than the magnitude of the treatment effect is small and unlikely to be biologically important, whereas a d = 0.8 or more would indicate a difference of 0.8 standard deviations between the sample means and, thus, likely to be an important treatment effect. Cohen (1992) provided these guidelines based on the following argument. The small effect 0.2 comes from the idea that it is much worse to conclude there is an effect when in fact there is no effect of the treatment rather than the converse (conclude no effect when there is an effect). The ratio of the Type II error (0.2) divided by the Type I error (0.05) gives us the penalty of 4. Similarly, for a moderate effect,  equals 10. Clearly, these are only guidelines (see Lakens 2013).
Examples
The difference in average body size between six week old females of two strains of lab mice is 0.4 g (Table 1), and increases to 1.38 g by 16 weeks (Table 2).
Table 1. Average body weights of 6 week old female mice of two different inbred strains.†
| Strain | |
s |
| C57BL/6J | 18.5 | 0.9 |
| CBA/J | 18.1 | 1.27 |
†Source: Jackson Laboratories: C57BL/6J; CBA/J
Table 2. Average body weights of 16 week old female mice of two different inbred strains.†
| Strain | |
s |
| C57BL/6J | 23.9 | 2.3 |
| CBA/J | 25.38 | 3.76 |
†Source: Jackson Laboratories: C57BL/6J; CBA/J
The descriptive statistics are based on weights of 360 individuals in each strain (Jackson Labs).
The differences are both statistically significant from a independent t-test, i.e., p-value less than 0.05. I’ll show you how to calculate independent t-test given summary statistics (means, standard deviations), for Table 1 data, then will ask you to do this on your own in Questions.
Write an R script, example data from Table 1
sdd1 = 0.9
var1 = sdd1^2
sdd2 = 1.27
var2 = sdd2^2
mean1 = 18.5
mean2 = 18.1
n1 = 360
n2 = 360
dff = n1+n2-2
pooledSD <-sqrt((var1+var2)/2)
pooledSEM <-sqrt(var1/n1 + var2/n2); pooledSEM
tdiff<-(mean1-mean2)/pooledSEM; tdiff
pt(tdiff, df=dff, lower.tail=FALSE)
#get two-tailed p-value
2*0.0000006675956
#get cohen's d
2*tdiff/sqrt(dff)
Results from the calculations we report (value of the test statistic, degrees of freedom, p-value), and the effect size, then are
t = 4.875773, df = 718, p-value = 0.0000006675956
cohen's d = 0.364
Now, I’m from the school of “don’t reinvent the wheel” or “someone has already solved your problems” (Freeman et al 2008), when it comes to coding problems. And, as you would expect, of course someone has written a function to calculate the t-test given summary statistics. In addition to base R and the pwr package (see Chapter 11.5), the package BSDA contains several nice functions for power calculations.
To follow this example, install BSDA, then run the following code
require(BSDA)
tsum.test(mean1, sdd1, n1, mean2, sdd2, n2, alternative = "two.sided", mu = 0, var.equal = TRUE, conf.level = 0.95)
R output
Standard Two-Sample t-Test

data: Summarized x and y
t = 4.8758, df = 718, p-value = 0.000001335
alternative hypothesis: true difference in means is not equal to 0
95 percent confidence interval:
0.2389364 0.5610636
sample estimates:
mean of x mean of y
18.5 18.1
Similarly, Cohen’s d is available from a package called effsize.
Note 3: One reason to “re-invent the wheel,” I only needed the one function; the BSDA package contains more 330 different objects/functions. A simple way to check how many objects in a package, eg, BSDA, run
ls("package:BSDA")
BSDA stands for “Basic Statistics and Data Analysis,” and was intended to accompany the 2002 book of the same title by Larry Kitchens.
And of course, if using some else’s code, give proper citation!
Questions
- We needed an equation to calculate pooled standard error of the mean (
pooledSEMin the R code). Read the code and write the equation used to calculate the pooled SEM. - Calculate the t-test and the effect size for the Table 1 data, but at three smaller sample sizes. Change from 360 for n1 = n2 = 20, repeat for n1 = n2 = 50, and finally, repeat for n1 = n2 = 100. Use your own code, or use the
tsum.testfunction from theBSDApackage. - Calculate Cohen’s effect size d for each new calculation based on different sample size.
- Create a table to report the p-values from the t-tests, the effect size, for each of the four n1 = n2 = (20, 50, 100, 360).
- True or false. The mean difference between sample means remains unaffected by sample size.
- True or false. The effect size between sample means remains unaffected by sample size.
- Based on comparisons in your table, what can you conclude about p-value and “statistical significance?” About effect size?
- Repeat questions 2 – 7 for Table 2.
Quiz Chapter 11.4
Two sample effect size
Chapter 11 contents
11.5 – Power analysis in R
Introduction
In R, you can estimate the
- Statistical power — how probable are you to correctly reject the null hypothesis
- Sample size — how many samples or observations must we get to have a reasonable chance to correctly reject a null hypothesis
- Effect size (minimum difference) — how different are the two samples?
Power analysis is recommended before conducting an experiment, but it is also valuable after an experiment.
Base R and pwr package
In Chapter 11.4 we presented functions from BSDA package. R (but not Rcmdr — see the EZR plugin described below) provides all of the basic power analysis we would need for t-tests, one-way ANOVA, etc. as part of the base installation (Everitt and Hothorn 2007). However, the package pwr, provides a more comprehensive package for power analysis. Load and install the R package pwr.
For example, to determine the number of samples for an independent sample t-test (two-tailed), the function is pwr.t.test().
pwr.t.test(n = NULL, d = NULL, sig.level = 0.05, power = NULL, type = c("two.sample", "one.sample", "paired"), alternative = c("two.sided", "less","greater"))
Table 1. Components of pwr.t.test().
| n | Number of observations (per sample) |
| d | Effect size |
| sig.level | Significance level (Type I error probability) |
| power | Power of test (1 minus Type II error probability) |
| type | Type of t test : one- two- or paired-samples |
| alternative | a character string specifying the alternative hypothesis, must be one of “two.sided” (default), “greater” or “less |
The basic question is, how many samples (observations) do I need for each group (k) at Type I error of 5% and type II error of 95%?
To run the test, you fill in all of the “NULL” except the one you wanted solved (ie, leave n = NULL).
For an effect size of 0.2, Type I error (significance level) of 5%, and 95% power, how many observations per group do we need for our study?
pwr.t.test(n = NULL, d =0.2, sig.level = 0.05, power = 0.95, type = c("two.sample"), alternative = c("two.sided"))
Two-sample t test power calculation
n = 650.6974
d = 0.2
sig.level = 0.05 power = 0.95 alternative = two.sided
note: n is number “n” in each group
Wow!
The R pwr package is not as convenient as it could be (have to load and run R scripts): for intro level, try one of the many online sites. Here is a website which can help with power analysis based on a variety of situations. The programs are java-coded. http://www.stat.uiowa.edu/~rlenth/Power/index.html
Note 1: You see what I just did? I “complained” about a free program’s performance! Don’t do that — what I mean by this is that there’s a learning curve with the pwr package, and there are other options to explore outside of the R programming world.
Power analysis with the EZR Rcmdr plugin
The EZR plugin for R Commander provides some facilities to do power analysis (Kanda 2013). First, download and install the RcmdrPlugin.EZR package. The EZR plugin for Rcmdr, RcmdrPlugin.EZR, provides an interface to explore power analyses, along with many other statistical functions (Kanda 2013). After loading the plugin to Rcmdr, additional drop down options are added to the menu bar (Fig 1).
Figure 1. Screenshot of Rcmdr menu bar with (A) and without (B) the EZR plugin.
I’ll demonstrate use of the plugin, but I recommend that you use pwr.t.test() instead. Although EZR uses a drop-down menu system it has many more functions than we need to solve this simple exercise. Thus, EZR is not any easier to apply for what we need here. That said, off we go.
Worked example
Consider a simple data set, wheel running performance in 24-hours for three strains of mice.
Table 2. Wheel running performance in 24-hours for three strains of mice.
| Mouse strain | Average | Standard deviation | n |
| AKR | 395 | 169.7 | 20 |
| CBA | 855 | 77.8 | 20 |
| C57BL/10 | 1135 | 63.6 | 20 |
Consider two groups of mice, AKR vs CBA for wheel running performance. How many samples needed to show a statistical difference for ?
Calculate the pooled standard deviation and calculate a difference between the means (the effect size) for which you wish to say is statistically different. For this example, 132.0 and 460, respectively. With EZR plugin installed and active in R Commander (Fig 2), select
Rcmdr: Statistical analysis → Calculate sample size → Calculate sample size for comparison between two means
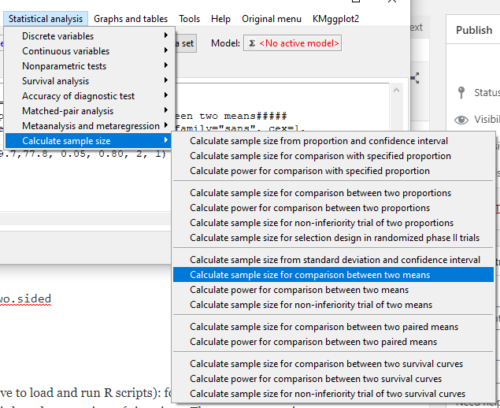
Figure 2. Screenshot of Rcmdr EZR plugin menu.
Select Calculate sample size for comparison between two means, enter the effect size (difference in sample means), standard deviation in each group (or a single value for pooled standard deviation) (Fig 3).
Figure 3. Screenshot of EZR Menu to obtain sample size for the comparison between two (sample) means.
R output from EZR Calculate sample size for comparison between two means
Assumptions
Difference in means 460
Standard deviation 132
Alpha 0.05
two-sided
Power 0.8
N2/N1 1

Required sample size Estimated
N1 2
N2 2
Questions
Recall lizard body mass data set from Chapter 10.1
Geckos <- c(3.186, 2.427, 4.031, 1.995)
Anoles <- c(5.515, 5.659, 6.739, 3.184)
Enter the data into an R data.frame, carry out the independent sample t-test, then
- Calculate power for the comparison between the two means
- Calculate sample size needed to achieve 95% power.
Quiz Chapter 11.5
Power analysis in R