17.1 – Ordinary least squares regression
-
- Introduction
- Example
- Least squares regression explained
- Models used to predict new values
- R code
- How to extract information from an R object
- Regression equations may be useful to predict new observations
- Regression through the origin
- Assumptions of OLS, an introduction
- Questions
- Quiz
- Chapter 17 contents
Introduction
Linear regression is a toolkit for developing linear models of cause and effect between a ratio scale data type, response or dependent variable, often labeled “Y,” and one or more ratio scale data type, predictor or independent variables, X. Like ANOVA, linear regression is a special case of the general linear model. Regression and correlation both test linear hypotheses: we state that the relationship between two variables is linear (the alternative hypothesis) or it is not (the null hypothesis). The difference?
- Correlation is a test of linear association (are variables correlated, we ask?), but are not tests of causation: we do not imply that one variable causes another to vary, even if the correlation between the two variables is large and positive, for example. Correlations are used in statistics on data sets not collected from explicit experimental designs incorporated to test specific hypotheses of cause and effect.
- Linear regression is to cause and effect as correlation is to association. With regression and ANOVA, which again, are special cases of the general linear model (LM), we are indeed making a case for a particular understanding of the cause of variation in a response variable: modeling cause and effect is the goal.
We start our LM model as 
where “~”, tilda, is an operator used by R in formulas to define the relationship between the response variable and the predictor variable(s).
From R Commander we call the linear model function by Statistics → Fit models → Linear model … , which brings up a menu with several options (Fig 1).
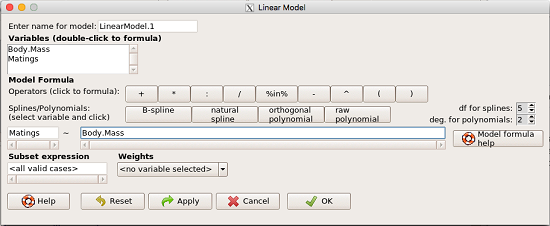
Figure 1. R commander menu interface for linear model.
Our model was
Matings ~ Body.Mass
R commander will keep track of the models created and enter a name for the object. You can, and probably should, change the object name yourself. The example shown in Figure 1 is a simple linear regression, with Body.Mass as the Y variable and Matings the X variable. No other information need be entered and one would simply click OK to begin the analysis.
Example
The purpose of regression is similar to ANOVA. We want a model, a statistical representation to explain the data sample. The model is used to show what causes variation in a response (dependent) variable using one or more predictors (independent variables). In life history theory, mating success is an important trait or characteristic that varies among individuals in a population. For example we may be interested in determining the effect of age (X1) and body size (X2) on mating success for a bird species. We could handle the analysis with ANOVA, but we would lose some information. In a clinical trial, we may predict that increasing Age (X1) and BMI (X2) causes increase blood pressure (Y).
Our causal model looks like
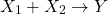
Let’s review the case for ANOVA first.
The response (dependent variable), the number of successful matings for each individual male bird, would be a quantitative (interval scale) variable. (Reminder: You should be able to tell me what kind of analysis you would be doing if the dependent variable was categorical!) If we use ANOVA, then factors have levels. For example, we could have several adult birds differing in age (factor 1) and of different body sizes. Age and body size are quantitative traits, so, in order to use our standard ANOVA, we would have to assign individuals to a few levels. We could group individuals by age (eg, < 6 months, 6 – 10 months, > 12 months) and for body size (eg, small, medium, large). For the second example, we might group the subjects into age classes (20-30, 30-40, etc), and by AMA recommended BMI levels (underweight < 18.5, normal weight 18.5 – 24.9, overweight 25-29.9, obese > 30).
We have not done anything wrong by doing so, but if you are a bit uneasy by this, then your intuition will be rewarded later when we point out that in most cases you are best to leave it as a quantitative trait. We proceed with the test of ANOVA, but we are aware that we’ve lost some information — continuous variables (age, body size, BMI) were converted to categories — and so we suspect (correctly) that we’ve lost some power to reject the null hypothesis. By the way, when you have a “factor” that is a continuous variable, we call it a “covariate.” Factor typically refers to a categorical explanatory (independent) variable.
We might be tempted to use correlation — at least to test if there’s a relationship between Body Mass and Number of Matings. Correlation analysis is used to measure the intensity of association between a pair of variables. Correlation is also used to to test whether the association is greater than that expected by chance alone. We do not express one as causing variation in the other variable, but instead, we ask if the two variables are related (covary). We’ve already talked about some properties of correlation: it ranges from -1 to +1 and the null hypothesis is that the true association between two variables is equal to zero. We will formalize the correlation next time to complete our discussion of the linear relationship between two variables.
But regression is appropriate here because we are indeed making a causal claim: we selected Age and Body Size, and we selected Age and BMI in the second example wish to develop a model so we can predict and maybe even advise.
Least squares regression explained
Regression is part of the general linear model family of tests. If there is one linear predictor variable, then that is a simple linear regression (SLR), also called ordinary least squares (OLS), if there are two or more linear predictor variables, then that is a multiple linear regression (MLR, Chapter 18).
First, consider one predictor variable. We begin by looking at how we might summarize the data by fitting a line to the data; we see that there’s a relationship between mass and mating success in both young and old females (and maybe in older males).
The data set was
Table 1. Our data set of number of matings by male bird by body mass (g).
| Body.Mass | Matings |
|---|---|
| 29 | 0 |
| 29 | 2 |
| 29 | 4 |
| 32 | 4 |
| 32 | 2 |
| 35 | 6 |
| 36 | 3 |
| 38 | 3 |
| 38 | 5 |
| 38 | 8 |
| 40 | 6 |
Note 1: Unfortunately, I’ve lost track where Table 1 data set came from! It’s likely a simulated set inspired by my readings back in 2005.
And a scatterplot of the data (Fig 2)
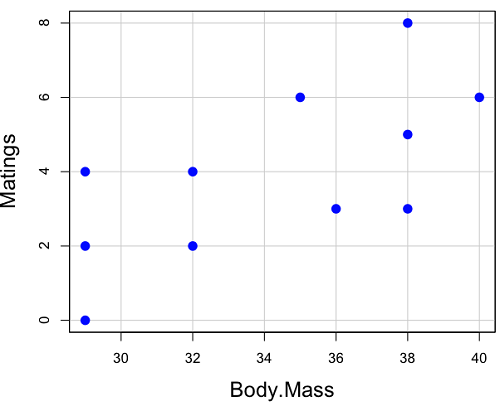
Figure 2. Number of matings by body mass (g) of the male bird.
There’s some scatter, but our eyes tell us that as body size increases, the number of matings also increases. We can go so far as to say that we can predict (imperfectly) that larger birds will have more matings. We fit the best fit line to the data and added the line to our scatterplot (Fig 3). The best fit line meets the requirements that the error about the line is minimized (see below). Thus, we would predict about six matings for a 40 g bird, but only two matings for a 28 g bird. And this is a good feature of regression, prediction, as long as used with some caution.
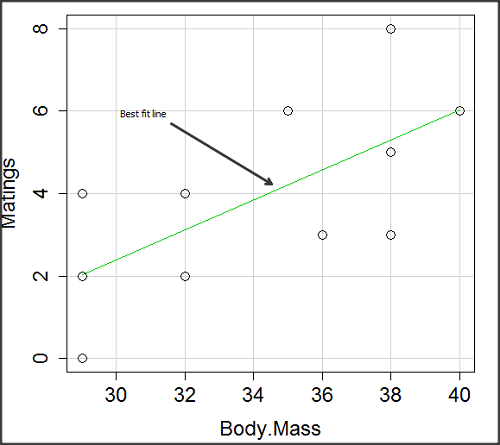
Figure 3. Same data as in Fig 2, but with the “best fit” line.
The prediction works best for the range of data for which the regression model was built. Outside the range of values, we predict with caution.
The simplest linear relationship between two variables is the SLR. This would be the parameter version (population, not samples), where
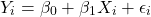
 = the Y-intercept coefficient and it is defined as
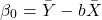
solve for intercept by setting X = 0.
 = the regression coefficient (slope)
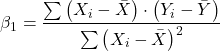
Note 2: The denominator is just our corrected sums of squares that we’ve seen many times before. The numerator is the cross-product and is referred to as the covariance.
ε = the error or “residual”

The residual is an important concept in regression. We briefly discussed “what’s left over,” in ANOVA, where an observation Yi is equal to the population mean plus the factor effect of level i plus the remainder or “error”.
In regression, we speak of residuals as the departure (difference) of an actual Yi (observation) from the predicted Y ( , say “why-hat”).
the linear regression predicts Y
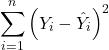
and what remains unexplained by the regression equation is called the residual
There will be as many residuals as there were observations.
But why THIS particular line? We could draw lines anywhere through the points. Well, this line is termed the “best fit“ because it is the only line that minimizes the sum of the squared deviations for all values of Y (the observations) and the predicted . The best fit line minimizes the sum of the squared residuals.
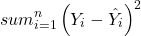
Note 3: More technically we justify the OLS as best fit by saying” Following the Gauss–Markov theorem, OLS estimators are the best linear unbiased estimators (BLUE). Gauss (1821) proved that the least squares method produces unbiased estimates with the smallest variance, a key result for regression analysis, while Markov (1900) rediscovered Gauss’ work and showed the conclusions held under less restrictive conditions.
Thus, like ANOVA, we can account for the total sums of squares (SSTot) as equal to the sums of squares (variation), explained by the regression model, SSreg, plus what’s not explained, what’s left over, the residual sums of squares, SSres, aka SSerror.
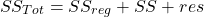
How well does our model explain — fit — our data? We cover this topic in Chapter 17.3 — Estimation of linear regression coefficients, but for now, we introduce  , the coefficient of determination.

ranges from zero (0%), the linear model fails completely to explain the data, to one (100%), the linear model explains perfectly every datum.
Models used to predict new values
Once a line has been estimated, one use is to predict new observations not previously measured!
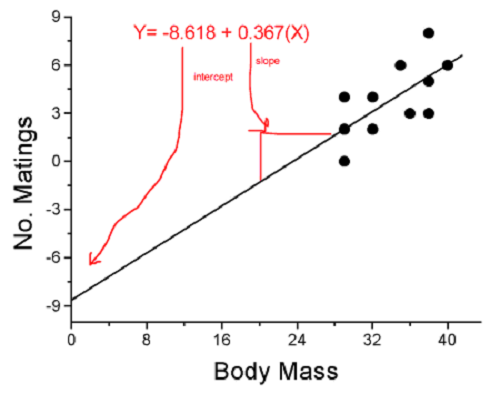
Figure 4. Figure 3 redrawn to extend the line to the Y intercept.
This is an important use of models in statistics: use an equation to fit to some data, then predict Y values from new values of X. To use the equation, simply insert new values of X into the equation, because the slope and intercept are already “known.” Then for any Xi we can determine  (predicted Y value that is on the best fit regression line).
This is what people do when they say
“if you are a certain weight (or BMI) you have this increased risk of heart disease”
“if you have this number of black rats in the forest you will have this many nestlings survive to leave the nest”
“if you have this much run-off pollution into the ocean you have this many corals dying”
“if you add this much enzyme to the solution you will have this much resulting product”.
R Code
We can use the drop down menu in Rcmdr to do the bulk of the work, supplemented with a little R code entered and run from the script window. Scrape data from Table 1 and save to R as bird.matings.
LinearModel.3 <- lm(Matings ~ Body.Mass, data=bird.matings)
summary(LinearModel.3)
Output from R — we’ll pull apart the important parts, color-highlights used to help orient the reader as we go.
Call:
lm(formula = Matings ~ Body.Mass, data = bird.matings)

Residuals:
     Min       1Q   Median      3Q     Max
-2.29237 -1.34322 -0.03178 1.33792 2.70763

Coefficients:
            Estimate Std. Error  t value  Pr(>|t|)
(Intercept)  -8.4746     4.6641   -1.817    0.1026
Body.Mass     0.3623     0.1355    2.673    0.0255 *
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 1.776 on 9 degrees of freedom
Multiple R-squared: 0.4425, Adjusted R-squared: 0.3806
F-statistic: 7.144 on 1 and 9 DF, p-value: 0.02551
What are the values for the coefficients? See Estimate .
Table 2. Coefficient estimates.
| Value | |
 , Y-intercept |
-8.4746 |
 , Slope |
0.3623 |
Get the sum of squares from the ANOVA table
myAOV.full <- anova(LinearModel.3); myAOV.full
Output from R, the ANOVA table
Analysis of Variance Table

Response: Matings
           Df  Sum Sq  Mean Sq  F value     Pr(>F)
Body.Mass   1  22.528  22.5277   7.1438   0.02551 *
Residuals   9  28.381   3.1535
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Looking for , the coefficient of determination? From the R output identify Multiple R-squared. We find 0.4425. Grab the SSreg and SSTot from the ANOVA table and confirm
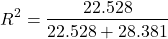
Note 2: The value of increases with each additional predictor variable included in the model, whether statistically significant contributor or not, regardless of whether the association between the predictor is simply due to chance. The Adjusted R-squared is an attempt to correct for this bias.
The residual standard error, RSE, is another model fit statistic.
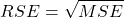
The smaller the residual standard error, the better the model fit to the data. See Residual standard error: 1.776 and MSE = 3.1535 above.
And the “statistical significance?” See Pr(>|t|) .There were tests for each coefficient,  and
 :
Table 3. Coefficient estimates.
| P-value | |
| , Y-intercept |
0.1026 |
| , Slope |
0.0255 |
And, at last, note that p-value, Pr(>F), reported in the Analysis of Variance Table, is the same as the p-value for the slope reported as Pr(>|t|).
Make a prediction:
How many matings expected for a 40 g male?
predict(LinearModel.3, data.frame(Body.Mass=40))
R output
1
6.016949
Answer: we predict 6 matings for a 40g male.
See below for predicting confidence limits.
How to extract information from an R object
We can do more — the lm() returnd a great deal of information about our regression model. Explore all that is available in the objects LinearModel.3 and myAOV.full with the str() command.
Note 3: str() command lets us look at an object created in R. Type ?str or help(str) to bring up the R documentation. Here, we use str() to look at the structure of the objects we created. “Classes” refers to the R programming class attribute inherited by the object. We first used str() in Chapter 8.3.
str(LinearModel.3)
Output from R
List of 12
$ coefficients : Named num [1:2] -8.475 0.362
..- attr(*, "names")= chr [1:2] "(Intercept)" "Body.Mass"
$ residuals : Named num [1:11] -2.0318 -0.0318 1.9682 0.8814 -1.1186 ...
..- attr(*, "names")= chr [1:11] "1" "2" "3" "4" ...
$ effects : Named num [1:11] -12.965 4.746 2.337 1.327 -0.673 ...
..- attr(*, "names")= chr [1:11] "(Intercept)" "Body.Mass" "" "" ...
$ rank : int 2
$ fitted.values: Named num [1:11] 2.03 2.03 2.03 3.12 3.12 ...
..- attr(*, "names")= chr [1:11] "1" "2" "3" "4" ...
$ assign : int [1:2] 0 1
$ qr :List of 5
..$ qr : num [1:11, 1:2] -3.317 0.302 0.302 0.302 0.302 ...
.. ..- attr(*, "dimnames")=List of 2
.. .. ..$ : chr [1:11] "1" "2" "3" "4" ...
.. .. ..$ : chr [1:2] "(Intercept)" "Body.Mass"
.. ..- attr(*, "assign")= int [1:2] 0 1
..$ qraux: num [1:2] 1.3 1.3
..$ pivot: int [1:2] 1 2
..$ tol : num 0.0000001
..$ rank : int 2
..- attr(*, "class")= chr "qr"
$ df.residual : int 9
$ xlevels : Named list()
$ call : language lm(formula = Matings ~ Body.Mass, data = bird_matings)
$ terms :Classes 'terms', 'formula' language Matings ~ Body.Mass
.. ..- attr(*, "variables")= language list(Matings, Body.Mass)
.. ..- attr(*, "factors")= int [1:2, 1] 0 1
.. .. ..- attr(*, "dimnames")=List of 2
.. .. .. ..$ : chr [1:2] "Matings" "Body.Mass"
.. .. .. ..$ : chr "Body.Mass"
.. ..- attr(*, "term.labels")= chr "Body.Mass"
.. ..- attr(*, "order")= int 1
.. ..- attr(*, "intercept")= int 1
.. ..- attr(*, "response")= int 1
.. ..- attr(*, ".Environment")=<environment: R_GlobalEnv>
.. ..- attr(*, "predvars")= language list(Matings, Body.Mass)
.. ..- attr(*, "dataClasses")= Named chr [1:2] "numeric" "numeric"
.. .. ..- attr(*, "names")= chr [1:2] "Matings" "Body.Mass"
$ model :'data.frame': 11 obs. of 2 variables:
..$ Matings : num [1:11] 0 2 4 4 2 6 3 3 5 8 ...
..$ Body.Mass: num [1:11] 29 29 29 32 32 35 36 38 38 38 ...
..- attr(*, "terms")=Classes 'terms', 'formula' language Matings ~ Body.Mass
.. .. ..- attr(*, "variables")= language list(Matings, Body.Mass)
.. .. ..- attr(*, "factors")= int [1:2, 1] 0 1
.. .. .. ..- attr(*, "dimnames")=List of 2
.. .. .. .. ..$ : chr [1:2] "Matings" "Body.Mass"
.. .. .. .. ..$ : chr "Body.Mass"
.. .. ..- attr(*, "term.labels")= chr "Body.Mass"
.. .. ..- attr(*, "order")= int 1
.. .. ..- attr(*, "intercept")= int 1
.. .. ..- attr(*, "response")= int 1
.. .. ..- attr(*, ".Environment")=<environment: R_GlobalEnv>
.. .. ..- attr(*, "predvars")= language list(Matings, Body.Mass)
.. .. ..- attr(*, "dataClasses")= Named chr [1:2] "numeric" "numeric"
.. .. .. ..- attr(*, "names")= chr [1:2] "Matings" "Body.Mass"
- attr(*, "class")= chr "lm"
Yikes! A lot of the output is simply identifying how R handled our data.frame and applied the lm() function.
Note 4: The “how” refers to the particular algorithms used by R. For example, qraux, pivot, and tol refer to arguments used in the QR decomposition of the matrix (derived from our data.frame) used to solve our linear least squares problem.
However, it’s from this command we learn what is available to extract in our object. For example, what were the actual fitted values (, the predicted Y values) from our linear equation? I marked the relevant str() output above in yellow. We call these from the object with the R code
RegModel.1$fitted.values
and R returns
       1        2        3        4        5        6        7        8        9       10       11
2.031780 2.031780 2.031780 3.118644 3.118644 4.205508 4.567797 5.292373 5.292373 5.292373 6.016949
Here’s another look at an object, str(myAOV.full), and how to extract useful values.
Output from R
Classes 'anova' and 'data.frame': 2 obs. of 5 variables:
$ Df : int 1 9
$ Sum Sq : num 22.5 28.4
$ Mean Sq: num 22.53 3.15
$ F value: num 7.14 NA
$ Pr(>F) : num 0.0255 NA
- attr(*, "heading")= chr [1:2] "Analysis of Variance Table\n" "Response: Matings"
Extract the sum of squares: type the object name then $ Sum Sq at the R prompt.
myAOV.full $"Sum Sq"
Output from R
[1] 22.52773 28.38136
Get the residual sum of squares
SSE.myAOV.full <- myAOV.full $"Sum Sq"[2]; SSE.myAOV.full
Output from R
[1] 22.52773
Get the regression sum of squares
SSR.myAOV.full <- myAOV.full $"Sum Sq"[1]; SSR.myAOV.full
Output from R
[1] 50.90909
Now, get the total sums of squares for the model

ssTotal.myAOV.full <- SSE.myAOV.full + SSR.myAOV.full; ssTotal.myAOV.full
Calculate the coefficient of determination
myR_2 <- 1 - (SSE.myAOV.full/(ssTotal.myAOV.full)); myR_2
Output from R
[1] 0.4425091
Which matches what we got before, as it should.
Regression equations may be useful to predict new observations
True. However, you should avoid making estimates beyond the range of the X – values that were used to calculate the best fit regression equation! Why? The answer has to do with the shape of the confidence interval around the regression line.
I’ve drawn an exaggerated confidence interval (CI), for a regression line between an X and a Y variable. Note that the CI is narrow in the middle, but wider at the end. Thus, we have more confidence in predicting new Y values for data that fall within the original data because this is the region where we are most confident.
Calculating the CI for the linear model follows from CI calculations for other estimates. It is a simple concept — both the intercept and slope were estimated with error, so we combine these into a way to generalize our confidence in the regression model as a whole given the error in slope and intercept estimation.
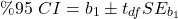
The calculation of confidence interval for the linear regression involves the standard error of the residuals, the sample size, and expressions relating the standard deviation of the predictor variable X — we use the t distribution.
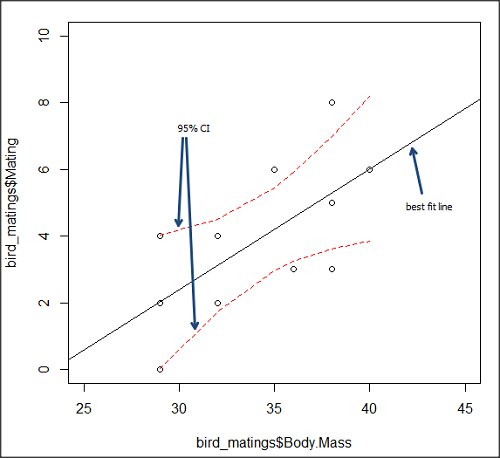
Figure 5. 95% confidence interval about the best fit line.
How I got this graph
plot(bird_matings$Body.Mass,bird_matings$Mating,xlim=c(25,45),ylim=c(0,10))
mylm <- lm(bird_matings$Mating~bird_matings$Body.Mass)
predict(mylm, interval = c("confidence"))
abline(mylm, col = "black")
x<-bird_matings$Body.Mass
lines(x, prd[,2], col= "red", lty=2)
lines(x, prd[,3], col= "red", lty=2)
Nothing wrong with my code, but getting all of this to work in R might best be accomplished by adding another package, a plug-in for Rcmdr called RcmdrPlugin.HH. HH refers to “Heiberger and Holland,” and provides software support for their textbook Statistical Analysis and Data Display, 2nd edition.
Regression through the origin
A regression through the origin in OLS is appropriate when theory dictates that the response must be zero when the predictor is zero, that is, the intercept is known to be exactly 0. In population genetics, for example, if you model pairwise genetic distance as a function of some measure of separation, (eg, time or geographic distance), and the definition of the metric ensures that identical individuals have zero distance, then forcing the regression through the origin can be justified. Doing so reduces parameter estimation to the slope alone and can improve efficiency when the assumption is correct. However, if the true relationship includes a nonzero intercept, constraining it to zero biases the slope.
This choice also affects the coefficient of determination (R²): in a no-intercept model, R² is computed relative to zero rather than the mean of Y, so it is not directly comparable to the standard R² from a model with an intercept and can even appear artificially higher or lower. If the origin constraint is correct, the no-intercept model may show a better (more meaningful) fit; if not, the apparent R² can be misleading despite biased estimates.
R code for regression without the Y-intercept:
noOrigin.model <- lm(formula = Matings ~ 0 + Body.Mass, data = bird.matings)
summary(noOrigin.model)
And the R output:
Call:
lm(formula = Matings ~ 0 + Body.Mass, data = bird.matings)

Residuals:
    Min      1Q  Median      3Q     Max
-3.4112 -1.4406  0.2359  0.9418  3.5301

Coefficients:
          Estimate Std. Error t value Pr(>|t|)
Body.Mass  0.11763    0.01726   6.816 4.65e-05 ***
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1

Residual standard error: 1.97 on 10 degrees of freedom
Multiple R-squared:  0.8229,	Adjusted R-squared:  0.8052
F-statistic: 46.45 on 1 and 10 DF,  p-value: 4.65e-05
Interpretation and comparison between model with and without fit through the origin.
Without an intercept (regression through the origin), the model estimates a slope of 0.1176 (SE = 0.0173, t = 6.82, p = 4.65×10⁻⁵), indicating a strong, statistically significant positive association between Body Mass and the response. Because the intercept is constrained to zero, this slope is effectively forced to account for all variation in Y, which often inflates its magnitude of significance and can bias the estimate if the true relationship does not pass through the origin.
When the intercept was included, the slope increased to 0.3623 (SE = 0.1355, t = 2.67, p = 0.0255), still statistically significant but less so, while the intercept is estimated at –8.47 (SE = 4.66, p = 0.103), which is not significantly different from zero at conventional levels. The change in slope (from 0.12 to 0.36) shows that allowing a nonzero intercept alters the fitted relationship substantially, suggesting that the origin constraint may not be appropriate in this case. Even though the intercept is not statistically significant, its inclusion redistributes variance between intercept and slope, yielding a more reliable slope estimate and a standard R² that is comparable across models, unlike the no-intercept case.
The negative Y-intercept, while statistically justifiable, is also biologically unrealistic, implying a negative number of matings. The statistical justification is simply that the model is used to predict mating success for organisms in the range of body size included in the data set used to make the model — the negative Y-intercept than is interpreted that we are trying to extend the model beyond its range.
In our example with the birds, a biological justification for a non intercept model can be made. For example, mating success is positively associated with body size; therefore, an organism with a hypothetical body size of zero would logically have zero chance of mating success. That said, even when biology suggests the relationship should pass through the origin, it may still be useful to fit a model with an intercept to test that assumption rather than impose it.
Measurement error, in the case of our birds example, chiefly if observed count of matings differs from the true, actual number of matings that occurred, or in a student employing genetic distance, then a number of errors may occur, including sequencing artifacts, alignment bias, or the way genetic distance is computed (eg, corrections for multiple substitutions, cf discussions in Felsenstein 2003, see Legendre and Desdevises 2009 for justifications for through the origin and phylogenetic independent contrasts). As well documented in standard texts on regression and linear models (eg, Introduction to Linear Regression Analysis, by Montgomery et al 2021; An Introduction to Generalized Linear Models, by Dobson and Barnett 2018), measurement error can introduce a small offset, so the estimated intercept serves as a diagnostic for systematic bias. If the intercept is close to zero and not significant, that provides empirical support for the origin constraint; if it is meaningfully different from zero, forcing the regression through the origin would bias the slope and distort inference. Additionally, including the intercept yields a standard R² and residual structure that are comparable across models, helping assess overall model fit before deciding whether the biologically motivated constraint is justified.
Assumptions of OLS, an introduction
We will cover assumptions of Ordinary Least Squares in detail in 17.8, Assumptions and model diagnostics for Simple Linear Regression. For now, briefly, the assumptions for OLS regression include:
- Linear model is appropriate: the data are well described (fit) by a linear model
- Independent values of Y and equal variances. Although there can be more than one Y for any value of X, the Y’s cannot be related to each other (that’s what we mean by independent). Since we allow for multiple Y’s for each X, then we assume that the variances of the range of Ys are equal for each X value (this is similar to our ANOVA assumptions for equal variance by groups).
- Normality. For each X value there is a normal distribution of Ys (think of doing the experiment over and over)
- Error (residuals) are normally distributed with a mean of zero.
Additionally, we assume that measurement of X is done without error (the equivalent, but less restrictive practical application of this assumption is that the error in X is at least negligible compared to the measurements in the dependent variable). Multiple regression makes one more assumption, about the relationship between the predictor variables (the X variables). The assumption is that there is no multicolinearity: the X variables are not related or associated to each other.
In some sense the first assumption is obvious if not trivial — of course a “line” needs to fit the data so why not plow ahead with the OLS regression method, which has desirable statistical properties and let the estimation of slopes, intercept and fit statistics guide us? One of the really good things about statistics is that you can readily test your intuition about a particular method using data simulated to meet, or not to meet, assumptions.
What about assumptions and BLUE? Interestingly, OLS coefficient estimates remain unbiased even if the errors are not normal, as long as other assumptions (like a mean of zero, no correlation, and constant variance) hold. However, the OLS estimators are no longer the “best” linear unbiased estimators (BLUE) because the efficiency property is lost. As we have discussed before, the main consequence is the effects on statistical inference. Without normality, standard errors, t-statistics, confidence intervals, and p-values will be unreliable.
Note 5: The efficiency property means the estimator has the smallest variance among all linear, unbiased estimators. And “unbiased,” again, means the estimator’s expected value is equal to the true parameter value.
Coming up with datasets like these can be tricky for beginners. Thankfully, others have stepped in and provide tools useful for data simulations which greatly facilitate the kinds of testing of assumptions — and more importantly, how assumptions influence our conclusions — statisticians greatly encourage us all to do (see Chatterjee and Firat 2007).
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- Predict new values for number of matings for male birds of 20g and 60g.
- Anscombe’s quartet (Anscombe 1973) is a famous example of this approach and the fictitious data can be used to illustrate the fallacy of relying solely on fit statistics and coefficient estimates.
Here are the data (modified from Anscombe 1973, p. 19) — I leave it to you to discover the message by using linear regression on Anscombe’s data set. Hint: play naïve and generate the appropriate descriptive statistics, make scatterplots for each X, Y set, then run regression statistics, first on each of the X, Y pairs (there were four sets of X, Y pairs).
Anscombe’s quartet
| X | Y1 | Y2 | Y3 | Y4 |
|---|---|---|---|---|
| 10 | 8.04 | 9.14 | 7.46 | 6.58 |
| 8 | 6.95 | 8.14 | 6.77 | 5.76 |
| 13 | 7.58 | 8.74 | 12.74 | 7.71 |
| 9 | 8.81 | 8.77 | 7.11 | 8.84 |
| 11 | 8.33 | 9.26 | 7.81 | 8.47 |
| 14 | 9.96 | 8.10 | 8.84 | 7.04 |
| 6 | 7.24 | 6.13 | 6.08 | 5.25 |
| 4 | 4.26 | 3.10 | 5.39 | 12.50 |
| 12 | 10.84 | 9.13 | 8.15 | 5.56 |
| 7 | 4.82 | 7.26 | 6.42 | 7.91 |
| 5 | 5.68 | 4.74 | 5.73 | 6.89 |
| Mean (±SD) | 7.50 (2.032) | 7.50 (2.032) | 7.50 (2.032) | 7.50 (2.032) |
Quiz Chapter 17.1
Ordinary Least Squares
Chapter 17 contents
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)
9.6 – McNemar’s test
Introduction
There are a number of scenarios in which subjects are paired or matched as part of the experimental design in order to control for confounding variables — a matched pair case-control. Subjects may be matched by age, or other criteria, or the observations are repeat measures of the same subjects (eg, left hand vs. right hand). One member of each pair is then randomly assigned to a treatment, the remaining pair member then assigned to the other treatment group. This scenario should remind you of our standard contingency table problem, but instead of a random collection of subjects assigned to treatments, the data are paired nominal. Thus, paired means that experimental (sampling) units are not independent, which if ignored violates an assumption required to employ the  test. We use McNemar’s test instead.
The possible results of such a design include just two outcomes: the pairs have the same outcome (agree, concordant) or the pairs have different outcomes (disagree, discordant).
McNemar’s solution was to consider only the discordant pairs. Consider two kinds of tests or assays for a condition, and the doctor receives the results of both tests. Our familiar two-by-two table results, and in this scenario may be called a confusion table — after all, there is truth and agreement along the diagonal including cells a and d are agreement between the two methods, whereas the off diagonal cells c and b are “confusion,” the two methods disagree.
Table 1. The familiar 2X2 table, now used to display agreement between two different testing procedures.
| Test 2 | ||||
| Positive | Negative | Row total | ||
| Test 1 | Positive | a | b | a+b |
| Negative | c | d | c+d | |
| Column total | a+c | b+d | n | |
Null hypothesis is that marginal proportions are equal

then McNemar’s test is given by
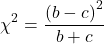
and the test has one degree of freedom.
If one of the cells is low, then a continuity correction would be applied (Edwards 1948, cited in Fagerland et al 2013). With this correction the equation becomes
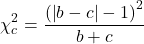
If either b or c is small, then the McNemar’s test statistic does not approximate a distribution very well, so there is a binomial version that you would use (Cochran’s Q test); used in cases where there are three or more matched sets and is common in meta-analysis (Kulinskaya and Dollinger 2015).
R code
Example data: Approval ratings for President Trump at two important markers during the Covid-19 pandemic: April 2020, deaths passed 10,000 persons in the US; in October 2020, it was reported that President Trump tested positive for SAR-COV2 and was admitted to Walter Reed National Military Medical Center (admitted 3 Oct, released 5 Oct). Surveys were conducted by YouGov (April, sponsored by The Economist; October, sponsored by Yahoo News; data extracted from How Americans View Biden’s Response To The Coronavirus Crisis)
Table 2. Approval ratings for President Trump at two important markers during the Covid-19 pandemic, data from YouGov survey.
| Approve | Disapprove | |
| April survey | 720 | 705 |
| October survey | 645 | 812 |
Enter the data as a matrix (note this would be a general approach for the contingency table problems, too, instead of entering via Rcmdr menu). The discordant pairs are b = 645 and c = 705
covid19 <- matrix(c(720, 645, 705, 812), nrow = 2, dimnames = list("April survey" = c("Approve", "Disapprove"), "October survey" = c("Approve", "Disapprove")))

 covid19
                      October survey
April survey       Approve   Disapprove
         Approve       720          705
      Disapprove       645          812
Uncorrected
mcnemar.test(covid19, correct=FALSE)

McNemar's Chi-squared test

data: covid19
McNemar's chi-squared = 2.6667, df = 1, p-value = 0.1025
Correction applied
mcnemar.test(covid19, correct=TRUE)

McNemar's Chi-squared test with continuity correction

data: covid19
McNemar's chi-squared = 2.5785, df = 1, p-value = 0.1083
Conclusions?
No change in approval ratings. The correction for small sample size had little effect on p-value, unsurprisingly, given that the surveys included 1500 (April) and 1504 (October) persons.
Unconditional paired tests
McNemar’s solution considers only the discordant pairs; it’s a conditional test. The downside of these tests is that the concordant pairs are not considered. Thus, by in effect tossing out some portion of the experimental results, it shouldn’t surprise you that the statistical power of the test is reduced (see Chapter 11). Thus, McNemar’s test may no longer be the best choice. Alternative unconditional tests have been proposed, and the mid-P alternative shows promise (Routledge 1994; Fagerland et al 2013). The mid-P value is calculated as the standard p-value for a test statistic minus one half the difference between the standard p-value and the next lowest possible p-value. McNemar’s mid-p test is available in package contingencytables. Try with example data set in Fagerland et al 2013 (Table 1).
#create a 2x2 matrix
bentur <- rbind(c(1, 1), c(7, 12))
First run McNemar’s test without correction for small sample size.
mcnemar.test(bentur, correct=FALSE)
R output follows
McNemar's Chi-squared test

data: bentur
McNemar's chi-squared = 4.5, df = 1, p-value = 0.03389
Next, run McNemar’s test with correction for small sample size.
mcnemar.test(bentur, correct=TRUE)
R output follows
McNemar's Chi-squared test with continuity correction

data: bentur
McNemar's chi-squared = 3.125, df = 1, p-value = 0.0771
Last, run min-p version of McNemar’s test.
McNemar_midP_test_paired_2x2(bentur)
R output
[1] The McNemar mid-P test: P = 0.039063
See also mcnemarExactDP function in exact2x2 package. Without explanation, here’s the R code and results
mcnemarExactDP(n = sum(bentur), m= bentur[1,2] + bentur[2,1], x = bentur[1,2])

      Exact McNemar Test (with central confidence intervals)

data: n=sum(bentur) m=bentur[1, 2] + bentur[2, 1] x=bentur[1, 2]
n = 21, m = 8, x = 1, p-value = 0.07031
alternative hypothesis: true difference in proportions is not equal to 0
95 percent confidence interval:
 -0.54549962 0.02044939
sample estimates:
       x/n    (m-x)/n  difference
0.04761905 0.33333333 -0.28571429
Alternatively, use wrapper function mnemar.exact().
mcnemar.exact(bentur)
R output
Exact McNemar test (with central confidence intervals)

data: bentur
b = 1, c = 7, p-value = 0.07031
alternative hypothesis: true odds ratio is not equal to 1
95 percent confidence interval:
 0.003169739 1.111975554
sample estimates:
odds ratio
 0.1428571
Note the alternative hypothesis: p-value is two-tailed.
Quiz Chapter 9.6
McNemar's test
Questions
1. Apply McNemar’s test and mid-P exact test to CDC example
| Controls | |||
| Cases | Exposed | Not exposed | |
| Exposed | 58 | 89 | |
| Not exposed | 32 | 95 | |
Chapter 9 contents
9.3 – Yates continuity correction
Introduction
Yates continuity correction: Most statistical textbooks at this point will note that critical values in their table (or any chi-square table for that matter) are approximate, but don’t say why. We’ll make the same directive — you may need to make a correction to the for low sample numbers. It’s not a secret, so here’s why.
We need to address a quirk of the test: the chi-square distribution is a continuous function (if you plotted it, all possible values between, say, 4 and 3 are possible). But the calculated statistics we get are discrete. In our HIV-HG co-infection problem from the previous subchapter, we got what appears to be an exact answer for P, but it is actually an approximation.
We’re really not evaluating our test statistic at the alpha levels we set out. This limitation of the goodness of fit statistic can be of some consequence — increases our chance to commit a Type I error — unless we make a slight correction for this discontinuity. The good news is that the does just fine for most df, but we do get concerned with it’s performance at df = 1 and for small samples.
Therefore, the advice is to use a correction if your calculated is close to the critical value for rejection/acceptance of the null hypothesis and you have only one df. Use the Yate’s continuity correction to standard calculation,  .
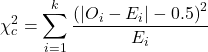
For the 2×2 table (Table 1), we can rewrite Yates correction
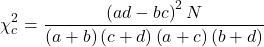
Our concern is this: without the correction, Pearson’s test statistic will be biased (eg, the test statistic will be larger than it “really” is), so we’ll end up rejecting the null hypothesis when we shouldn’t (that’s a Type I error). This becomes an issue for us when p-value is close to 5%, the nominal rejection level: what if p-value is 0.051? Or 0.049? How confident are we in concluding accept or reject null hypothesis, respectively?
I gave you three examples of goodness of fit and one contingency table example. You should be able to tell me which of these analyses it would be appropriate to apply to correction.
More about continuity corrections
Yates suggested his correction to Pearson’s back in 1934. Unsurprisingly, new approaches have been suggested (eg, discussion in Agresti 2001). For example, Nicola Serra (Serra 2018; Serra et al 2019) introduced
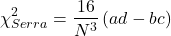
Serra reported favorable performance when sample size was small and the expected value in any cell was 5 or less.
R code
When you submit a 2X2 table with one or more cells less than five, you could elect to use a Fisher exact test, briefly introduced here (see section 9.5 for additional development), or, you may apply the Yates correction. Here’s some code to make this work in R.
Let’s say the problem looks like Table 1.
Table 1. Example 2X2 table with one cell with low frequency.
| Yes | No | |
| A | 8 | 12 |
| B | 3 | 22 |
At the R prompt type the following
library(abind, pos=15)
#abind allows you to combine matrices into single arrays
.Table <- matrix(c(8,12,3,22), 2, 2, byrow=TRUE)
rownames(.Table) <- c('A', 'B')
colnames(.Table) <- c('Yes', 'No') # when you submit, R replies with the following table
.Table  # Counts
 Yes No
A  8 12
B  3 22
Here’s the command; the default is no Yates correction (ie, correct=FALSE); to apply the Yates correction, set correct=TRUE.
.Test <- chisq.test(.Table, correct=TRUE)
Output from R follows
.Test
    Pearson's Chi-squared test with Yates' continuity correction
data:  .Table
X-squared = 3.3224, df = 1, p-value = 0.06834
Compare without the Yates correction
.Test <- chisq.test(.Table, correct=FALSE)
.Test
    Pearson's Chi-squared test
data:  .Table
X-squared = 4.7166, df = 1, p-value = 0.02987
Note that we would reach different conclusions! If we ignored the potential bias of the un-corrected we would be tempted to reject the null hypothesis, when in fact, the better answer is not to reject because Yates-corrected p-value is greater than 5%.
Just to complete the work, what does the Fisher Exact test results look like (see section 9.5)?
fisher.test(.Table)
    Fisher's Exact Test for Count Data
data:  .Table
p-value = 0.04086
alternative hypothesis: true odds ratio is not equal to 1
95 percent confidence interval:
0.9130455 32.8057866
sample estimates:
odds ratio
  4.708908
Which to use? The Fisher exact test is just that, an exact test of the hypothesis. All possible outcomes are evaluated and we interpret the results as likely as p=0.04086 if there is actually no association between the treatment (A vs B) and the outcome (Yes/No) (see section 9.5).
Questions
- With respect to interpreting results from a test for small samples, why use the Yates continuity correction?
- Try your hand at the following four contingency tables (a – d). Calculate the test, with and without the Yates correction. Make note of the p-value from each and note any trends.
(a)
| Yes | No | |
| A | 18 | 6 |
| B | 3 | 8 |
(b)
| Yes | No | |
| A | 10 | 12 |
| B | 3 | 14 |
(c)
| Yes | No | |
| A | 5 | 12 |
| B | 12 | 18 |
(d)
| Yes | No | |
| A | 8 | 12 |
| B | 3 | 3 |
3. Ch09.1, Question 1 provided an example of a count from a small bag of M&Ms. Apply the Yates correction to obtain a better estimate of p-value for the problem. The data were four blue, two brown, one green, three orange, four red, and two yellow candies.
- Construct a table and compare p-values obtained with and without the Yates correction. Note any trend in p-value
Quiz Chapter 9.3
Yates continuity correction
Chapter 9 contents
9.2 – Chi-square contingency tables
 from a, b, c, and d 2X2 table format formula
 effect size
Introduction
This page covers a lot of ground to extend our discussion of implementations of the chi-square test to experimental data and introduces several related statistics, including a correlation coefficient for categorical data and an introduction to agreement and reliability measurement statistics.
We begin with contingency tables.
We just completed a discussion about goodness of fit tests, inferences on categorical traits for which a theoretical distribution or expectation is available. We offered Mendelian ratios as an example in which theory provides clear-cut expectations for the distribution of phenotypes in the F2 offspring generation. This is an extrinsic model — theory external to the study guides in the calculation of expected values — and it reflects a common analytical task in epidemiology.
But for many other kinds of categorical outcomes, no theory is available. Today, most of us accept the link between tobacco cigarette smoking and lung cancer. The evidence for this link was reported in many studies, some better designed than others.
Consider the famous Doll and Hill (1950) report on smoking and lung cancer. They reported (Table IV Doll and Hill 1950), for men with lung cancer, only two out of 649 were non-smokers. In comparison, 27 case-control patients (ie, patients in the hospital but with other ailments, not lung cancer) were nonsmokers, but 622 were smokers (Table 1).
Table 1. Doll and Hill (1950).
| Smokers | Non-smokers | |
| Lung cancer | 647 | 2 |
| Case controls, no lung cancer | 622 | 27 |
A more recent example from the study of the efficacy of St John’s Wort (Hypericum perforatum) as a treatment for major depression (Shelton et al 2001, Apaydin et al. 2016). Of patients who received St. John’s Wort over 8 weeks, 14 were deemed improved while 98 did not improve. In contrast 5 patients who received the placebo were deemed improved while 102 did not improve (Table 2).
Table 2. St. John’s Wort and depression
| Improved | Not improved | |
| St. John’s Wort | 14 | 98 |
| Placebo | 5 | 102 |
Note 1: The St. John’s Wort problem is precisely a the time to remind any reader of Mike’s Biostatistics Book: under no circumstances is medical advice implied from my presentation. From the National Center for Complementary and Integrative Medicine: “It has been clearly shown that St. John’s wort can interact in dangerous, sometimes life-threatening ways with a variety of medicines.”
These kinds of problems are direct extensions of our risk analysis work in Chapter 7. Now, instead of simply describing the differences between case and control groups by Relative Risk Reduction or odds ratios, we instruct how to do inference on the risk analysis problems.
Thus, faced with absence of coherent theory as guide, the data themselves can be used (intrinsic model), and at least for now, we can employ the test.
Note 2: The preferred analysis is to use a logistic regression approach, Chapter 18.3, because additional covariates can be included in the model.
In this lesson we will learn how to extend the analyses of categorical data to cases where we do not have a prior expectation — we use the data to generate the tests of hypotheses. This would be an intrinsic model. One of the most common two-variable categorical analysis involves 2X2 contingency tables. We may have one variable that is the treatment variable and the second variable is the outcome variable. Some examples provided in Table 3.
Table 3. Some examples of treatment and outcome variables suitable for contingency table analysis.
| Treatment Variable and Levels | Outcome Variable(s) | Reference |
| Lead exposure
Levels: Low, Medium, High |
Intelligence and development | Bellinger et al 1987 |
| Wood preservatives
Levels: Borates vs. Chromated Copper Arsenate |
Effectiveness as fungicide | Hrastnik et al 2013 |
| Antidepressants
Levels: St. John’s Wort, conventional antidepressants, placebo |
Depression relief | Linde et al 2008 |
| Coral reefs
Levels: Protected vs Unprotected |
Fish community structure | Guidetti 2006 |
| Aspirin therapy
Levels: low dose vs none |
Cancer incidence in women | Cook et al 2013 |
| Aspirin therapy
Levels: low dose vs none |
Cancer mortality in women | Cook et al 2013 |
Table 4 were examples of published studies returned from a quick PubMed search; there are many examples (meta-analysis opportunities!). However, while they all can be analyzed by contingency tables analysis, they are not exactly the same. In some cases, the treatments are fixed effects, where the researcher selects the levels of the treatments (see Ch12.3 and Ch14.3 for discussion about fixed vs random effects in experimental design).
In other cases, each of these treatment variables need not be actual treatments (in the sense that an experiment was conducted), but it may be easier to think about these as types of experiments. These types of experiments can be distinguished by how the sampling from the reference population were conducted. Before we move on to our main purpose, to discuss how to calculate contingency tables, I wanted to provide some experimental design context by introducing two kinds of sampling (Chapter 5.5).
Our first kind of sampling scheme is called unrestricted sampling. In unrestricted sampling, you collect as many subjects (observations) as possible, then assign subjects to groups. A common approach would be to sample with a grand total in mind; for example, your grant is limited and so you only have enough money to make 1000 copies of your survey and you therefore approach 1000 people. If you categorize the subjects into just two categories (eg, Liberal, Conservative), then you have a binomial sample. If instead you classify the subjects a number of variables, eg, Liberal or Conservative, Education levels, income levels, homeowners or renters, etc., then this approach is called multinomial sampling. The point in either case is that you have just utilized a multinomial sampling approach. The aim is to classify your subjects to their appropriate groups after you have collected the sample.
Logically what must follow unrestricted sampling would be restricted sampling. Sampling would be conducted with one set of “marginal totals” fixed. Margins refers to either the row totals or to the column totals. The sampling scheme is referred to as compound multinomial. The important distinction from the other two types is that the number of individuals in one of the categories is fixed ahead of time. For example, in order to determine if smoking influences respiratory health, you approach as many people as possible to obtain 100 smokers.
The contingency table analysis
We introduced the 2×2 contingency table (Table 4) in Chapter 7.
Table 4. 2X2 contingency table
| Outcome |
|||
| Exposure or Treatment group | Yes | No | Marginal total |
| Exposure (Treatment) | a | b | Row1 = a + b |
| Nonexposure (Control) | c | d | Row2 = c + d |
| Marginal total | Column1 = a + c |
Column2 = a + c |
N |
Contingency tables are all of the form (Table 5)
Table 5. Basic format of a 2X2 table
| Outcome 1 | Outcome 2 | |
| Treatment 1 | Yes | No |
| Treatment 2 | Yes | No |
Regardless of how the sampling occurred, the analysis of the contingency table is the same; mechanically, we have a chi-square type of problem. In both contingency table and the “goodness of fit” Chi-Square analyses the data types are discrete categories. The difference between GOF and contingency table problems is that we have no theory or external model to tell us about what to expect. Thus, we calculate expected values and the degrees of freedom differently in contingency table problems. To learn about how to perform contingency tables we will work through an example, first the long way, and then using a formula and the a, b, c, and d 2X2 table format. Of course, R can easily do contingency tables calculations for us.
Doctors noticed that a new form of Hepatitis (HG, now referred to as GB virus C), was common in some HIV+ populations (Xiang et al 2001). Accompanying the co-infection, doctors also observed an inverse relationship between HG loads and HIV viral loads: patients with high HG titers often had low HIV levels. Thus, the question was whether co-infection alters the outcome of patients with HIV — do HIV patients co-infected with this HG progress to AIDS and mortality at rates different from non-infected HIV patients? I’ve represented the Xiang et al (2001) data in Table 6.
Table 6. Progression of AIDS for patients co-infected with HG [GB virus C], Xiang et al data (2001)
| Lived | Died | Row totals | |
| HG+ | 103 | 41 | 144 |
| HG- | 95 | 123 | 218 |
| Column totals | 198 | 164 | 362 |
Note 3: HG virus is no longer called a hepatitis virus, but instead is referred to as GB virus C, which, like hepatitis viruses, is in the Flaviviridae virus family. For more about the GB virus C, see review article by Bhattarai and Stapleton (2012).
Our question was: Do HIV patients co-infected with this HG progress to AIDS and mortality at rates different from non-infected HIV patients? A typical approach to analyze such data sets is to view the data as discrete categories and analyze with a contingency table. So we proceed.
Setup the table for analysis
Rules of contingency tables (see Kroonenberg and Verbeek 2018). What follows is a detailed walk through setting up and interpreting a 2X2 table. Note that I maintain our a, b, c, d cell order, with row 1 referencing subjects exposed or part of treatment group and row 2 referencing subjects not exposed (or part of the control group), as introduced in Chapter 7.
The Hepatitis G data from Xiang et al 2001 data, arranged in 2X2 format (Table 7).
Table 7. Format of 2X2 table Xiang et al (2001) dataset.
| Lived | Died | Row totals | |
| HG+ | a | b | a + b |
| HG- | c | d | c + d |
| Column totals | a + c | b + d | N |
The data are placed into the cells labeled a, b, c, and d.
Cell a : The number of HIV+ individuals infected with HG that lived beyond the end of the study.
Cell b : The number of HIV+ individuals infected with HG that died during the study.
Cell c : The number of HIV+ individuals not infected with HG that lived.
Cell d : The number of HIV+ individuals not infected with HG that died.
This is a contingency table because the probability of living or dying for these patients may have been contingent on coinfection with hepatitis G.
State the examined hypotheses
HO: There is NO association between the probability of living and coinfection with hepatitis G.
For a contingency table this means that there should be the same proportion of individuals with and without hepatitis G that either lived or died (1:1:1:1).
Now, compute the Expected Values in the Four cells (a, b, c, d)
- Calculate the Expected Proportion of Individuals that lived in Entire Sample:
Column 1 Total / Total = Expected Proportion of those that lived beyond the study. - Calculate Expected Proportion of Individuals that died in Entire Sample:
Column 2 Total / Total = Expected Proportion that died during the study. - Calculate the Expected Proportion of Individuals that lived and were HG+
Expected Proportion of living (step 1 above) x Row 1 Total = Expected For Cell A. - Calculate the Expected Proportion of Individuals that died and were HG+
Expected Proportion died x Row 1 Total = Expected For Cell B - Calculate the Expected Proportion of surviving individuals that were HG-
Expected Proportion lived x Row 2 Total = Expected For Cell C - Calculate the Expected Proportion of individuals that died that were HG-
Expected Proportion that died x Row 2 Total = Expected For Cell D
Yes, this can get a bit repetitive! But, we are now done — remember, we’re working through this to review how the intrinsic model is applied to obtain expected values.
To summarize what we’ve done so far, we now have
Observations arranged in a 2X2 table
Calculated the expected proportions, ie, the Expected values under the Null Hypothesis.
Now, we proceed to conduct the chi-square test of the null hypothesis — The observed values may differ from these expected values, meaning that the Null Hypothesis is False.
Table 8. Copy Table 6 data set
| Lived | Died | Row totals | |
| HG+ | 103 | 41 | 144 |
| HG- | 95 | 123 | 218 |
| Column totals | 198 | 164 | 362 |
Get the Expected Values
- Calculate the Expected Proportion of Individuals that lived in Entire Sample:
Column 1 Total (198) / Total (362) = 0.5470 - Calculate Expected Proportion of Individuals that died in Entire Sample:
Column 2 Total (164) / Total (362) = 0.4530 - Calculate the Expected Proportion of Individuals that lived and were HG+
Expected Proportion of living (0.547) x Row 1 Total (218) = Cell A = 119.25 - Calculate the Expected Proportion of Individuals that died and were HG+
Expected Proportion died (0.453) x Row 1 Total (218) = Cell B = 98.75. - Calculate the Expected Proportion of surviving individuals that were HG-
Expected Proportion lived (0.547) x Row 2 Total (144) = Cell C = 78.768 - Calculate the Expected Proportion of individuals that died that were HG-
Expected Proportion that died 0(.453) X Row 2 Total = Cell D = 65.232
Thus, we have (Table 9)
Table 9. Expected values for Xiang et al (2001) data set (Table 6 and Table 8)
| Lived | Died | Row totals | |
| HG+ | 78.768 | 65.232 | 144 |
| HG- | 119.25 | 98.75 | 218 |
| Column totals | 198 | 164 | 362 |
Now we are ready to calculate the Chi-Square Value
Recall the formula for the chi-square test
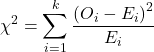
Table 10. Worked contingency table for Xiang et al (2001) data set (Table 6 and Table 8)
| Cell |  |
|
| a | (103 – 87.768)2 = 78.768 | 7.4547 |
| b | (41 – 65.232)2 = 65.232 | 9.002 |
| c | (95 – 119.25)2 = 119.25 | 4.93134 |
| d | (123 – 98.75)2 = 98.75 | 5.95506 |
 |
27.3452 |
Adding all the parts we have the chi-square test statistic 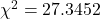 . To proceed with the inference, we test using the chi-square distribution.
Determine the Critical Value of  test and evaluate the null hypothesis
Now recall that we can get the critical value of this test in one of two (related!) ways. One, we could run this through our statistical software and get the p-value, the probability of our result and the null hypothesis is true. Second, we look up the critical value from an appropriate statistical table. Here, we present option 2.
We need the Type I error rate α and calculate the degrees of freedom for the problem. By convention, we set α = 0.05. Degrees of freedom for contingency table is calculated as
Degrees of Freedom = (# rows – 1) x (# columns – 1)
and for our example → DF = (2 – 1) x (2 – 1) = 1.
Note. How did we get the 1 degree of freedom? Aren’t there 4 categories and shouldn’t we therefore have k – 1 = 3 df? We do have four categories, yes, but the categories are not independent. We need to take this into account when we evaluate the test and this lack of independence is accounted for by the loss of degrees of freedom.
What exactly is not independent about our study?
-
- The total number of observations is set in advance from the data collection.
- We also have the column and row totals set in advance. The number of HIV individuals with or without Hepatitis G infection was determined at the beginning of the experiment. The number of individuals that lived or died was also determined before we we conducted the test.
- Then the first cell (let us make that cell A) can still vary anywhere from 0 to N i (sample size of the first drug).
- Once the first cell (A) is determined then the next cell in that row (B) will have to add up to N i.
- Also the other cell in the same column as the first cell (C) must add up to the Column 1 Total.
- Lastly, the last cell (D) must have the Row 1 Total add up to the correct number.
All this translates into there being only one cell that is FREE TO VARY, hence, only one degree of freedom.
Get the Critical Value from a chi-square distribution table: For our example, look up the critical value for DF = 1, α = 0.05, you should get 3.841. The 3.841 is the value of the chi-square we would expect at 5% and the null hypothesis is in fact true condition in the population.
Once we obtain the critical value we simply use the previous statement regarding the probability of the Null Hypothesis being TRUE. We Reject the Null Hypothesis when the calculated test statistic is greater than the Critical Value. We Accept the Null Hypothesis when the calculated is less than the Critical Value. In our example we got 27.3452 for our calculated test statistic, thus we reject the null hypothesis and conclude, that, at least for the sample in this study, there was an association between the probability of patients living past the study period and the presence of hepatitis G.
from a, b, c, and d 2X2 table format formula
If a hand calculation is required, a simpler formula to use is
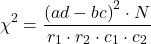
where N is the sum of all observations in the table, r1 and r2 are the marginal row totals, and c1 and c2 are the marginal column totals from the 2×2 contingency table (eg, Table 4). If you are tempted to try this in a spreadsheet, and assuming your entries for a, b, c, d, and N look like Table 11, then a straightforward interpretation requires referencing five spreadsheet cells no less than 13 times! Not to mention a separate call to the distribution to calculate the p-value (one tailed test).
Note 4: This formulation was provided as equation 1 in Yates 1984 (referred to in Serra 2018), but is likely found in the earlier papers on dating back to Pearson.
Table 11. Example spreadsheet with formulas for odds ratio (OR), Pearson’s , and p-value from distribution.
| A | B | C | D | E | F | G | |
| 1 | |||||||
| 2 | a | 103 | OR | =( 2*5)/(3*4) |
|||
| 3 | b | 41 | |||||
| 4 | c | 95 | |||||
| 5 | d | 123 | chisq, p | =(((2*5-3*4)^2)*6)/ (SUM( 2:3)*SUM(4:5)*SUM( 2,4)*SUM(3,5)) |
=CHIDIST(F5,1) | ||
| 6 | N | 632 |
Now, let’s see how easy this is to do in R.
effect size
Inference on hypotheses about association, there’s statistical significance — evaluate p-value compared to Type I error, eg, 5% — and then there’s biological importance, the strength of the association. The concept of effect size is an attempt to communicate the likely importance of a result. Several statistics are available to communicate effect size: for that’s φ, phi for the φ (phi) coefficient.

where N is the total. Phi for our example is
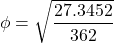
R code
sqrt(27.3452/362)
and R returns
[1] 0.274844
Effect size statistics typically range from 0 to 1; Cohen (1992) suggested the following interpretation
Table 12. Cohen’s interpretation of d values.
| Effect size | Interpretation |
| < 0.2 | Small, weak effect |
| 0.5 | Moderate effect |
| > 0.8 | Large effect |
For our example,  effect size of the association between co-infection with GB virus C and mortality was weak in the patients with HIV infection. The function
phi() in psych package will calculate phi coefficient from a 2X2 table.
Agreement, kappa, and inter-rater reliability
I imagine by now you have made the leap — can we use the contingency table to assess agreement between (inter-) two judges (raters) who evaluate the same object? A naive approach would be to calculate simple agreement, the percent of objects in the list of items evaluated for which both judges agree (concur). For a binomial Yes or No, then agreement (concordance) occurs when both judges report “Yes,” or both report “No,” displayed on the main diagonal of the 2X2 table. The other possible combinations (Yes vs No and No vs Yes) are disagreement (discordance) and would be displayed on the off-diagonal of the 2X2 matrix.
Unfortunately, simple agreement, while intuitive, cannot discriminate between true agreement and agreement by chance. Cohen’s kappa (Cohen 1960, McHugh 2012) is used to assess agreement, aka inter-rater reliability, for binomial and nominal data types for two judges (raters). Cohen’s 1960 paper has been enormously impactful, with more than 53K citations (Google Scholar, Fall 2024), and spawned a number of additional measures of agreement, eg, weighted kappa for more than binomial levels, Fleiss kappa for three or more raters, ICC for ratio scale, discussed in Ch12.3). It’s beyond the scope of this text to review the context of such terms as agreement, and reliability, for just two terms used to evaluate results from two independent observers of the “same” event or object, and leave that to the reader to confirm how to report such endeavors.
Off we go. Cohen’s kappa is defined as

where po is the proportion in agreement and pc is proportion of agreement expected by chance. Essentially, then, interpretable kappa values fall between 0 and 1 (0% to 100%); negative kappa estimates are possible. Cohen (1960) noted that for kappa to equal 1, the off diagonal elements would all have to be zero.
Cohen provided an estimate of the standard error for kappa as
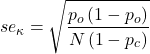
and 95% confidence intervals are then  .
Here, we review calculation of simple agreement and Cohen’s kappa, with just the two levels. Both simple agreement and Cohen’s kappa (κ), are available in R via the icc package. Cohen’s kappa is also available in the psych package, with the cohen.kappa() function providing a confidence interval estimate directly.
Note 5: Base R includes the function kappa(), but that returns an estimate for the condition number of the matrix, or how close to singular the matrix solution may be, ie, determinant is zero and its inverse is unavailable.
Use of both is illustrated here with a simulated coin toss example modified from a nice 2018 summary of Cohen’s kappa at r-bloggers. The R code
library(irr)
# simulate some data
N = 24
flips1 <- rbinom(n = N, size = 1, prob = 0.5)
flips2 <- rbinom(n = N, size = 1, prob = 0.5)
coins<-cbind(flips1, flips2)
Confirm the data set.
head(coins)
flips1 flips2
[1,] 0 1
[2,] 1 0
[3,] 1 0
[4,] 1 1
[5,] 0 0
[6,] 1 0
and create a 2X2 table.
I stacked the data
head(StackedCoin)
Side Coins    HT
1 0 flips1 tails
2 1 flips1 heads
3 1 flips1 heads
4 1 flips1 heads
5 0 flips1 tails
6 1 flips1 heads
then created a simple 2×2 table (see Note 6 below for a simple explanation for why “.Table” as a named object).
.Table <- xtabs(~Coins+HT, data=StackedCoin)
Table 13. coins as 2X2 table.
| tails | heads | |
| flips1 | 10 | 14 |
| flips2 | 14 | 10 |
We can calculate the phi coefficient for Table 13.
phi(.Table, digits = 3)
[1] -0.167
and would conclude no correlation between the two sets of coin tosses.
Now, agreement statistics. Both agree() and kappa2() expect an unstacked (wide) data format. It’s not necessary, but we’ll call a value of 1 as “heads up” and a value of 0 as “tails up” of the tossed coin.
Next, simple agreement.
agree(coins, tolerance=0)
R returns
Subjects = 24
Raters = 2
%-agree = 41.7
Now, a proper agreement statistic.
kappa2(coins)
and R returns
Subjects = 24
Kappa = -0.135
z = -0.7
p-value = 0.484
Results with psych:cohen.kappa, which provides the 95% confidence interval as default output.
Cohen Kappa and Weighted Kappa correlation coefficients and confidence boundaries
                 lower estimate upper
unweighted kappa -0.51    -0.14  0.24
weighted kappa   -0.51    -0.14  0.24
Number of subjects = 24
By chance, the two independent toss of 24 coins had 10 rows of “agreement” (H:H or T:T), simply due to chance. However, results of kappa find no agreement between the two sets of coin tosses.
In summary, we see that simple agreement and the kappa statistic don’t return similar results. Percent agreement reported 41%, whereas kappa was zero. We know percent agreement can’t reflect anything in the coin toss case because each toss is independent from the next. We’ll have you explore repeated trials of coin tosses to help convince you that simple agreement is not a reliable measure of agreement (see question 6 below).
Interpreting agreement values is not straightforward, and some argue agreement statistics should be avoided in favor of disagreement measures (for example, see discussion in Pontius and Millones 2011). Cohen suggested (Table 14)
Table 14. Landis and Koch’s (1977) interpretation of Cohen’s kappa.
| Cohen’s kappa | Agreement? |
| < 0 | none |
| 0.01 — 0.20 | slight |
| 0.21 — 0.40 | fair |
| 0.41 — 0.60 | moderate |
| 0.61 — 0.80 | substantial |
| 0.81 — 1 | nearly perfect |
Note 6: Wikipedia page for Cohen’s kappa suggests that this interpretation began with the Landis and Koch 1997 paper in the journal Biometrics. I haven’t confirmed this — regardless, this paper is also highly influential, with more than 89K citations (Fall 2024).
Even a cursory look at Table 14 should lead to questions about scenarios in which a range of agreement “substantial” would provide little comfort about the agreement between the judges or the reliability of the instrument used, for example forensic cases or histology of tissue biopsies.
Contingency table analyses in Rcmdr
Assuming you have already summarized the data, you can enter the data directly in the Rcmdr contingency table form. If your data are not summarized, then you would use Rcmdr's Two-way table… for this. We will proceed under the assumption that you have already obtained the frequencies for each cell in the table.
Rcmdr: Statistics → Contingency tables → Enter and analyze two-way table…
Here you can tell R how many rows and how many columns (Fig 1).
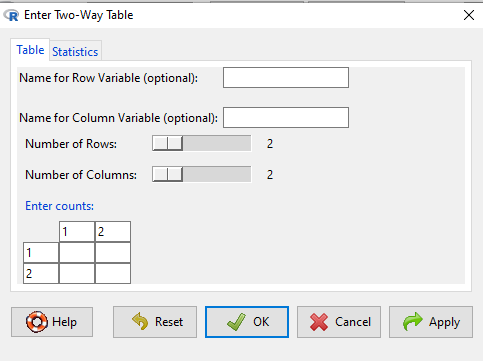
Figure 1. Screenshot R Commander menu for 2X2 data entry with counts.
The default is a 2X2 table. For larger tables, use the sliders to increase the number of rows, columns, or both.
Next, enter the counts. You can edit every cell in this table, including the headers. In the next panel, I will show you the data entry and options. The actual calculation of the test statistic is done when you select the “Chi-square test of independence” check-box (Fig 2).
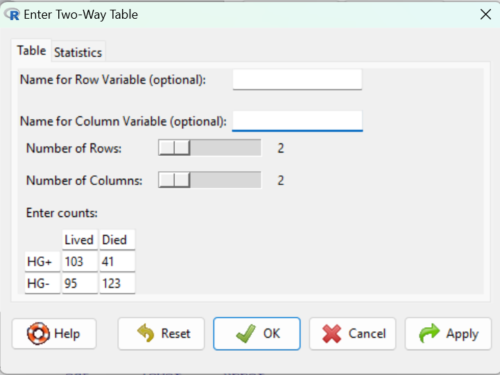
Figure 2. Display of Xiang et al data entered into R Commander menu.
After entering the data, click on the Statistics tab (Fig 3).
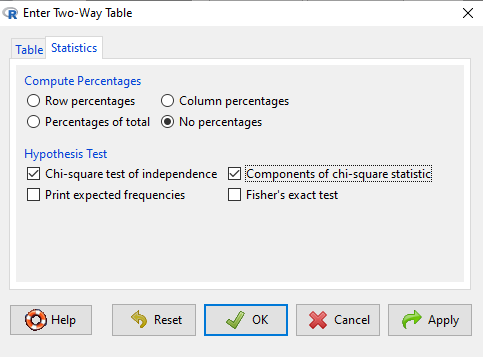
Figure 3. Screenshot Statistics options for contingency table.
If you also select “Components of chi-square statistic” option, then R will show you the contributions of each cell (O-E) towards the chi-square test statistic value. This is helpful to determine if rejection of the null is due to a subset of the categories, and it also forms the basis of the heterogeneity tests, a subject we will pick up in the next section.
Here’s the R output from R Commander. Note the “2, 2, byrow=TRUE” instructions (check out R help to confirm what
.Table <- matrix(c(103,41,95,123), 2, 2, byrow=TRUE)
dimnames(.Table) <- list("rows"=c("HG+", "HG-"), "columns"=c("Lived", "Died"))

.Table # Counts
     columns
rows Lived Died
 HG+   103   41
 HG-   95   123

.Test <- chisq.test(.Table, correct=FALSE)
.Test

Pearson's Chi-squared test

data: .Table
X-squared = 27.339, df = 1, p-value = 0.0000001708

round(.Test$residuals^2, 2) # Chi-square Components
    columns
rows Lived Died
HG+   7.46 9.00
HG-   4.93 5.95

remove(.Test)
remove(.Table)
end R output.
Note 7: R Commander often cleans up after itself by removing objects like .Test and .Table. This is not necessary for the code to work, but does make it easier for you to go back and modify the code without worrying about confusing objects.
Lots of output, take a deep breath and remember… The minimum output we need to look at is… (Table 15)?
Table 15. Minimally expected outcome for report from a statistical test.
| Value of the test statistic | 27.339 |
| Degrees of freedom | 1 |
| p-value | 0.0000001708 |
We can see that the p-value 1.7-7 is much less than Type 1 α = 0.05, thus, by our decision criterion we reject the null hypothesis (provisionally of course, as science goes).
Note 7: Simple enough to get R to report numbers as you need. For example, R code
myNumber = 0.0000001708
format(myNumber, scientific = TRUE, digits=2)
returns
[1] "1.7e-07"
Questions
- Instead of R Commander, try the contingency table problem in R directly.
myData <- matrix(c(103,41,95,123))
chisq.test(myData)
Is this the correct
contingency table analysis? Why or why not? - For many years National Football League games that ended in ties went to “sudden death,” where the winner was determined by the first score in the extra period of play, regardless of whether or not the other team got an opportunity to possess the ball on offense. Thus, in more than 100 games (140), the team that won the coin toss and therefore got the ball first in overtime, won the game following either a kicked field goal or after a touchdown was scored. In 337 other games under this system, the outcome was not determined by who got the ball first. Many complained that the “sudden death” format was unfair and in 2013 the NFL changed its overtime rules. Beginning 2014 season, both teams got a chance to possess the ball in overtime, unless the team that won the coin toss also went on to score a touchdown at which time that team would be declared the winner. In this new era of over-time rules ten teams that won the coin toss went on to score a touchdown in their first possession and therefore win the game, whereas in 54 other overtime games, the outcome was decided after both teams had a chance on offense (data as of 1 December 2015). These data may be summarized in the table
First possession win? Yes No Coin flip years 140 337 New era 10 54 A. What is the null hypothesis?
B. Which is more appropriate: to calculate an odds ratio or to calculate an RRR?
C. This is a contingency table problem. Explain why
D. Conduct the test of the null hypothesis.
E. What is the value of the test statistic? Degrees of freedom? P-value?
F. Evaluate the results of your analysis — do you accept or reject the null hypothesis? - Return to the Doll and Hill (1950) data: 2 men with lung cancer were nonsmokers, 647 men with lung cancer were cigarette smokers. In comparison, 27 case-control patients (ie, patients in the hospital but with other ailments, not lung cancer) were nonsmokers, but 622 were cigarette smokers.
A. What is the null hypothesis?
B. Which is more appropriate: to calculate an odds ratio or to calculate an RRR?
C. This is a contingency table problem. Explain why
D. Conduct the test of the null hypothesis.
E. What is the value of the test statistic? Degrees of freedom? P-value?
F. Evaluate the results of your analysis — do you accept or reject the null hypothesis? - A more recent example from the study of the efficacy of St John’s Wort as a treatment for major depression (Shelton et al 2001). Of patients who received St. John’s Wort over 8 weeks, 14 were deemed improved while 98 did not improve. In contrast 5 patients who received the placebo were deemed improved while 102 did not improve.
A. What is the null hypothesis?
B. Which is more appropriate: to calculate an odds ratio or to calculate an RRR?
C. This is a contingency table problem. Explain why
D. Conduct the test of the null hypothesis.
E. What is the value of the test statistic? Degrees of freedom? P-value?
F. Evaluate the results of your analysis — do you accept or reject the null hypothesis? - Return to the coin toss simulation and repeat comparisons between simple agreement and Cohen’s kappa for different values of N. Do you see any trend(s) for the two measures as sample size increases or decreases?
- Repeat the coin toss simulation for N = 24 up to five times, each time calculate simple agreement and Cohen’s kappa. Provide a table of your five results plus the example, and generalize simple agreement vs Cohen’s kappa as a reliable measure of agreement. Hint: you may want to use Descriptive statistics to help make your case.
Quiz Chapter 9.2
Chi-square contingency tables
Chapter 9 contents
7.1 – Epidemiology definitions
Introduction
This subchapter may lack for drama, but let’s start by providing a list of key terms with definitions as you start our introduction to epidemiology. More definitions will follow in the sections as well.
Definitions
Absolute risk: The probability that a specified event will occur in a specified population. See Ch07.4 – Epidemiology: Relative risk and absolute risk, explained.
Absolute risk reduction (ARR): the decrease in risk of an event in an exposed (treatment) group compared to an unexposed (control) group. Also called the risk difference. 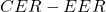 , see Contingency table. See Ch07.4 – Epidemiology: Relative risk and absolute risk, explained.
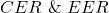 : Control Event Rate and Experimental Event Rate. In observational studies, transition from “control” and “experimental” to exposure terms. For example, prospective or retrospective cohort studies,
 is Exposed Event Rate and its partner
 , Unexposed Event Rate. Equivalently, you will encounter
 for Incidence in the Exposed and
 forIncidence in the Unexposed. For Case-Control studies, where the direct event (incidence) rates over time are unavailable, then becomes Exposure Rate in Cases — the proportion of people with the condition who were exposed to the risk factor and
 is now Exposure Rate in Controls.
Contingency table, also called cross tabulation or crosstab, is a display of counts of variables in a matrix format. We briefly introduced the contingency table in Chapter 5.1. In epidemiology, rows of contingency table represent treatment or exposure groups, columns represent outcomes.
Table 1. A 2 X 2 contingency table
| Outcome | ||
| Yes | No | |
| Treatment or exposed group | a | b |
| Control or nonexposed group | c | d |
The 2X2 contingency table is referred to frequently in this chapter and again in Chapter 9.
R code
a = 4; b = 46; c = 5; d = 45

Table1 <- matrix(c(a,b,c,d), 2, 2, byrow=TRUE, dimnames = list(c("Treatment", "Control"), c("Yes", "No"))); Table1
R output
          Yes  No
Treatment   4  46
Control     5  45
In statistical classification, a field dedicated to establishing algorithms for correctly identifying and predicting classes of data, eg, correct disease diagnosis or , the 2X2 contingency table is often called a confusion or error matrix (Greene 2003). Machine learning methods are often built on developments from statistical classification findings (Michie et al 1995). We expand on contingency tables in Chapter 7.4 and Chapter 9.2.
Note 1: First discussed in Chapter 5.1, by convention, the standard format for an epidemiological 2×2 contingency table organizes exposure on the rows and disease outcome on the columns as follows:
- Rows (Exposure): The top row represents Exposed / Treatment (Yes), and the bottom row represents Non-exposed / Control (No).
- Columns (Outcome): The left column represents Disease / Case (Yes), and the right column represents No Disease / Control (No). See Chapter 7.
Control event rate (CER): How often an event occurs in the control group.  , see Contingency table.
Diagnosis: identification of the nature of a disease or condition.
Event: From probability theory, an event is a set of one or more outcomes to which a probability is assigned to each outcome.
Experimental event rate (EER): How often an event occurs in the treatment group.  , see Contingency table.
Exposure risk: the potential for harm from contact with or vulnerability to a hazard or risk factor.
Hazard: anything that can cause harm.
Incidence: the number of newly diagnosed individuals in a population having a condition, disease or other characteristic. Compare to prevalence.
Likelihood: In every-day English, the term likelihood and probability mean the same thing — the chance that an event will occur. In statistics, however, probability refers to possible outcomes in the future — a prediction for an event to occur, whereas likelihood is associated with the possible explanation (hypothesis) for the outcome that has already occurred, the past. Put another way, likelihood quantifies how likely is the data we observe, given the hypothesis (cf. excellent discussion by Gallistel 2015)? We will look at likelihood methods in practice in subsequent chapters.
Negative predictive value of a test (NPV), defined as the probability that a negative test result identifies a person who truly does not have the disease. Calculated as the total number of individuals without the disease divided by the total that tested negative. 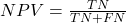
Number needed to treat (NNT): the inverse of the absolute risk reduction. 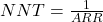 . See Ch07.4 – Epidemiology: Relative risk and absolute risk, explained.
Odds, the ratio (OR) of two probabilities: the probability of getting a one on throwing a dice is  , the probability of not getting a one is
 , therefore the odds of getting a one are 1 to 5.
 . See Ch07.5 – Odds ratio.
Outcome, the single result from a random experiment. For example, result of a single coin toss is “heads.” Results of a birth, the outcome is the child born is a singleton, single birth.
Per capita rate, Latin phrase, for each head, meaning per person.
Positive predictive value of a test (PPV), defined as the probability that a positive test result identifies a person who truly has the disease. Calculated as the total number of individuals with the disease divided by the total that tested positive. 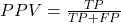
Posttest probability refers to the probability that the patient has the disease after the results of the test are known.
Pretest probability is the prevalence of the disease, ie, the chance that the a randomly selected person from the population has the disease.
Prevalence: The proportion of individuals in a population having a condition, disease, or characteristic. Compare to incidence.
Probability, defined in Chapter 6.1.
Prognosis, how a disease plays out.
Relative risk: Ratio of the risk of an event among those exposed to the risk factor to the risk among those not exposed to the risk factor. See Ch07.4 – Epidemiology: Relative risk and absolute risk, explained.
Relative risk reduction (RRR): is a measure calculated by dividing the absolute risk reduction by the control event rate. See Ch07.4 – Epidemiology: Relative risk and absolute risk, explained.
Risk: Probability of an event. Risk is not restricted to just bad events, but refers to the uncertainty of a particular event (eg, the risk that a child will be born male seems a melodramatic statement, but it is accurate as far as this definition goes).
Therapy, treatment intended to treat, relieve, or cure a disorder of condition.
Questions
- Compare and contrast ARR and RRR.
- What’s the difference between event, hazard, and risk?
- What’s the difference between incidence and prevalence?
- What’s the difference between diagnosis and prognosis?
- What’s the implication of a NNT greater than 100 in terms of the utility of a proposed therapy or treatment?
Quiz
Quiz Chapter 7.1
Epidemiology definitions
Chapter 7 contents
- Introduction
- Epidemiology definitions
- Epidemiology basics
- Conditional Probability and Evidence Based Medicine
- Epidemiology: Relative risk and absolute risk, explained
- Odds ratio
- Confidence intervals
- References and suggested readings
4.4 – Mosaic plots
Introduction
Mosaic plots are used to display associations among categorical variables, eg, from a contingency table analysis. Mosaic plots and tree plots (next chapter) are used to show part-to-whole associations or to show whether or not results are consistent across sub-groups (Ballarini et al 2020). Mosaic plots, a type of visual grid, are simple versions of heat maps (next chapter). Like stacked bar charts, the wdth of each column shows the size of each group, the height of any boxes within the columns shows the size of the sub-groups. Used appropriately, mosaic plots may be useful to show relationships. However, like pie-charts and bar charts, care needs to be taken to avoid their over use; the mosiac plot works for a few categories, but quickly loses clarity as numbers of categories increase. As an alternative, particularly if intended for a general audience, icon arrays, aka waffle plots, may be a better choice (see discussion in Garcia-Retamero et al 2013).
In addition to the function mosaicplot() in the base R package, there are a number of packages in R that will allow you to make these kinds of plots; depending on the analyses we are doing we may use any one of three Rcmdr plugins: RcmdrPlugin.mosaic (depreciated), RcmdrPlugin.KMggplot2, or RcmdrPlugin.EBM.
Example data
Table 1. Records of American and National Leagues baseball teams at home and away midway during 2016 season
| No | Yes | |
|---|---|---|
| AL | 10 | 5 |
| NL | 7 | 8 |
The configuration of major league baseball (MLB) parks differ from city to city. For example, Boston’s American League (AL) Fenway Park has the 30-feet tall “Green Monster” fence in left field and a short distance of only 302 feet along the foul line to right field fence. For comparison, Globe Life Park in Arlington, TX the distance along the foul lines left field (332 feet) and right field (325 feet). So, it suggests that teams may benefit from playing 81 games at their home stadium. To test this hypothesis I selected Win-Loss records of the 30 teams at the midway point of the 2016 season. Data are shown in the Table 1.
mosaicplot() in R base
The function mosaicplot() is included in the base install of R. The following code is one way to directly enter contingency table data like that from Table 1.
myMatrix <- matrix(c(10,  5,  7,  8),  nrow = 2, ncol = 2, byrow = TRUE)
dimnames(myMatrix) <- list(c("AL", "NL"), c("No","Yes"))
myTable <- as.table(myMatrix); myTable
mosaicplot(myTable, color=2:3)
The simple plot is shown in Figure 1. color = “2” is red, color = “3” is green.
Figure 1. Mosaic plot made with basic function mosaicplot().
mosaic plot from EBM plugin
A good option in Rcmdr is to use the “evidence-based-medicine” or “EBM” plug-in for Rcmdr (RcmdrPlugin.EBM). This plugin generates a real nice mosaic plot for 2 X 2 tables.
After loading the EBM plugin, restart Rcmdr, then select EBM from the menu bar and choose to “Enter two-way table…”
Figure 2. First steps to make mosaic plot in R Commander EBM plug-in.
Complete the data entry for the table as shown in the image below. After entering the values, click the OK button.
Figure 3. Next steps to make mosaic plot in R Commander EBM plug-in.
Along with the requested statistics a mosaic plot will appear in a pop-up window.
Figure 4. Mosaic plot made from R Commander EBMplug-in
mosaic-like plot KMggplot2 plugin
The KMggplot2 plugin for Rcmdr will also generate a mosaic-like plot. After loading the KMggplot2 plugin, restart Rcmdr, then load a data set with the table (e.g., MLB data in Table 1). Next, from within the KMggplot2 menu select, “Bar chart for discrete variables…”
Figure 5. First steps to make mosaic plot in R Commander KMggplot2 plug-in.
From the bar chart context menu make your selections. Note that this function has many options for formatting, so play around with these to make the graph the way you prefer.
Figure 6. Next steps to make mosaic plot in R Commander KMggplot2 plug-in.
And here is the resulting mosaic-like plot from KMggplot2.
Figure 7. Mosaic-like plot made from R Commander KMggplot2 plug-in.
Questions
1. Most US states have laws that dictate pre-employment drug testing for job candidates; Interestingly, states are increasingly legalizing marijuana use. Data for states plus District of Columbia are presented in the table. Make a mosaic plot of the table.
Table 2. Marijuana use is US states, legal or not legal
| Marijuana-use legal | Marijuana-use not legal | |
|---|---|---|
| Yes | 19 | 12 |
| No | 14 | 6 |
Data adopted from https://www.paycor.com/resource-center/pre-employment-drug-testing-laws-by-state
Quiz Chapter 4.4
Mosaic plots
Depreciated material
As of summer 2020, Rcmdrplugin.mosaic is depreciated. While you can install the archived version, it is not recommended. Therefore, this material is left as is but for information purposes only. For a simple mosaic plot in Rcmdr I recommend working with the RcmdrPlugin.EBM.
Download the RcmdrPlugin.mosaic package, start Rcmdr, then navigate to Tools and choose Load Rcmdr plug-in(s).… Select Rcmdrplugin.mosaic (Fig. 8), then restart Rcmdr (Fig. 9). The plugin adds mosaic plot to the regular Graphics menu of Rcmdr.
Figure 8. Screenshot of popup menu from Rcmdr with mosaic plugin selected.
Figure 9. After clicking OK (Fig 8), click Yes to restart Rcmdr. The plugin will then be available.
Load a data set with 2X2 arranged data, or create the variables yourself (Yikes, 30 rows!). The mosaic plugin requires that you submit data in a table format. We can check whether our data are currently in that format. At the R prompt type
is.table(MLB)
And R will return
[1] FALSE
(To be complete, confirm that the data set is a data.frame: is.data.frame(MLB).)
You will need a table before proceeding with the mosaic plug-in. then create a table using a command like the one shown below.
MLBTable <- xtabs(~League+HomeWin, data=MLB)
Once the table is ready, select “mosaic or assoc plot” from the Rcmdr Graphics menu (Fig. 10)
Figure 10. How to access the mosaic plot in R Commander.
A small window will pop up that will allow you to select the table of data you just created (Fig. 11). Note that you may need to hunt around your desktop to find this menu! Select the table (in this example, “MLBTable), then click on “Create plot” button.
Figure 11. Screenshot of popup menu in mosaic plugin in R Commander.
R Note: The popup from the mosaic menu shown in Fig. 11 will also display the data.frame MLB. If you mistakenly select the dataframe MLB, you’ll get an error message in Rcmdr (Fig. 12). The plugin behaves erratically if you select MLB: On my computer, the function hangs and requires restarting R.
Figure 12. Error message as result of selecting a dataframe for use in mosaic plugin.
After you select the table, two additional windows will pop up: on the left (Fig. 13) is the context menu to change characteristics of the mosaic plot; on the right (not shown) will be a mosaic plot itself in default grey scale colors.
Figure 13. Options for the mosaic plot
At a minimum, change the plot from grey scale to a colorized version by checking the box next to the “Colorize last variable” option. The new plot is shown in Figure 14.
Figure 14. Our new mosaic plot.
OK. Take a moment and look at the plot. What conclusions can be made about our hypothesis — are there any differences between the leagues for home versus road Wins-Loss records?
By default the mosaic command copies the command to the R window. You can change the graph by taking advantage of the options in the brewer palette. Here’s the command for the mosaic image above.
mosaic(structable(MLBTable), highlighting=2, highlighting_fill=brewer.pal.ext(2,"RdYlGn"))
Change the options in the brackets following “brewer.pal.ext.” For example, replace RdYlGn with Blues to make a plot that looks like the following
Figure 15. Mosaic plot with changed color scheme.
The colors are selected from the Rcolorbrewer package. For more, see this blog for starters.
Chapter 4 contents
- Graphs and tables (How to report statistics)
- Bar (column) charts
- Histograms
- Box plot
- Mosaic plots
- Scatter plots
- Add a second Y axis
- Q-Q plot
- Ternary plots
- Heat maps
- Graph software
- References and suggested readings