17.6 – ANCOVA – analysis of covariance
Introduction
Analysis of covariance (ANCOVA) is intended to help with analysis of designs with categorical treatment variables on some response (dependent) variable, but a known confounding variable is also present. Thus, the researcher is also likely to know of additional ratio scale variables that covary with the response variable and, moreover, must be included in the experimental design in some way.
Take for example the well-known relationship between body size and whole-animal metabolic rate as measured by rates of carbon dioxide production or rates of oxygen consumption for aerobic organisms. We may be interested in how addition or blocking of stress hormones affects resting metabolism; we may be interested in comparing men and women for activity metabolism, and so on. We’d like to know if the regressions were the same (eg, metabolic rate covaried with body mass in the same way — that is, the slope of the relationship was the same).
This situation arises frequently in biology. For example, we might want to know if male and female birds have different mean field metabolic rates, in which case we might be tempted to use a one-way ANOVA or t-test (since one factor with two levels). However, if males and females also differ for body size, then any differences we might see in metabolic rate could be due to differences in metabolic rate are confounded by differences in the covariable body size. We already discussed one approach to correction: calculate a ratio. Thus, a logical approach to correcting or normalizing for the covariation would be to divide body mass (units of kilograms) into metabolic rate (eg, volume of oxygen, O2, consumed), and make comparisons, say, among different species, on mass-specific trait ( ). However, because the regression between mass and metabolic rate is allometric, i.e., not equal to one, the ratio does not, in fact normalize for body mass. We made this point in Chapter 6.2, and remarked that analysis of covariance ANCOVA was a solution.
ANCOVA allows you to test for mean differences in traits like metabolic rate between two or more groups, but only after first accounting for covariation due to another variable (eg, body size). However, ANCOVA makes the assumption that relationship between the covariable and the response variable is the same in the two groups. This is the same as saying that the regression slopes are the same. We discussed how to use t-test to test hypothesis of equal slopes between regression models in Chapter 17.5, but a more elegant way is to include this in your model.
Example
We return to our sample of 13 tadpoles (Rana pipiens), hatched in the laboratory. I’ve repeated the data set in this page, scroll or click here.
Our linear model was 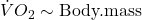 and a scatterplot of the data set is shown in Figure 1 (a repeat of Figure 3 from Chapter 17.5, but now points identified to developmental group).
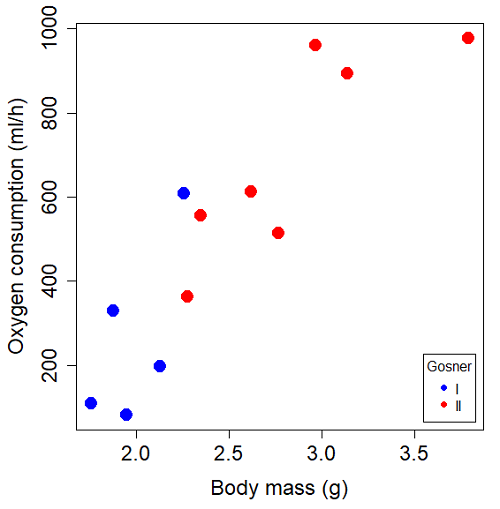
Figure 1. Scatterplot of oxygen consumption by R. pipiens tadpoles vs body mass (g) by developmental group (Gosner stages I or II).
The project looked at whether metabolism as measured by oxygen consumption was consistent across two developmental stages. Metamorphosis in frogs and other amphibians represents profound reorganization of the organism as the tadpole moves from water to air. Thus, we would predict some cost as evidenced by change in metabolism associated with later stages of development. Figure 2 shows a box plot of tadpole oxygen consumption by Gosner (1960) developmental stage (Figure 2 is a repeat of Figure 4 Chapter 17.5).
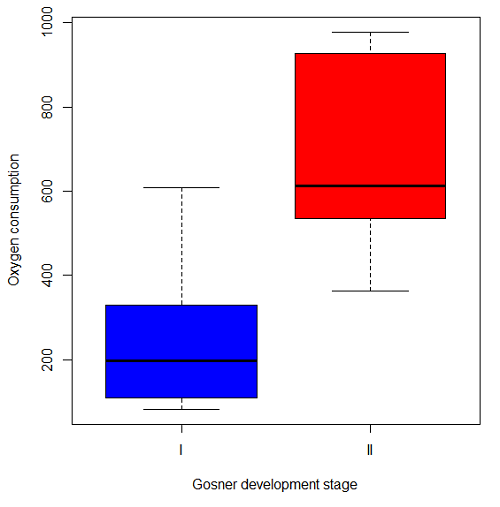
Figure 2. Copy of Figure 4, Chapter 17.5; boxplot of oxygen consumption of R. pipiens tadpoles by Gosner developmental stages.
Looking at Figure 2 we see a trend consistent with our prediction; developmental stage may be associated with increased metabolism. However, older tadpoles also tend to be larger, and the plot in Figure 2 does not account for that. Thus, body mass is a confounding variable in this example. There are several options for analysis here (eg, ANCOVA), but one way to view this is to compare the slopes for the two developmental stages. While this test does not compare the means, it does ask a related question: is there evidence of change in rate of oxygen consumption relative to body size between the two developmental stages? The assumption that the slopes are equal is a necessary step for conducting the ANCOVA.
So, divide the data set (Table 1) into two groups by developmental stage (12 tadpoles could be assigned to one of two developmental stages; one was at a lower Gosner stage than the others and so is dropped from the subset.
Table 1.  and
 of 12 R. pipiens tadpole larvae by Gosner developmental stage.
Gosner stage I
|
|
| 1.76 | 109.41 |
| 1.88 | 329.06 |
| 1.95 | 82.35 |
| 2.13 | 198 |
| 2.26 | 607.7 |
Gosner stage II
| Body mass | |
| 2.28 | 362.71 |
| 2.35 | 556.6 |
| 2.62 | 612.93 |
| 2.77 | 514.02 |
| 2.97 | 961.01 |
| 3.14 | 892.41 |
| 3.79 | 976.97 |
The slopes and standard errors we obtained in Chapter 17.5 were
| Gosner Stage I | Gosner stage II | |
| slope | 750.0 | 399.9 |
| standard error of slope | 444.6 | 111.2 |
Make a plot (Figure 3).
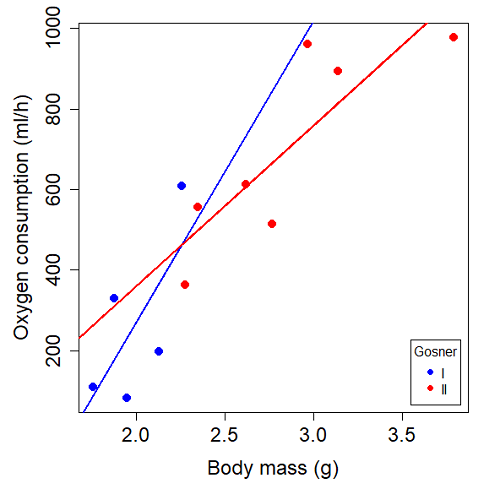
Figure 3. Scatterplot with best-fit regression lines of by for Gosner State I (closed circle, solid line) and Gosner Stage II (open circle, dashed line) R. pipiens tadpoles.
R code for plot in Figure 3.
#Used Rcmdr scatterplot(), then modified code
scatterplot(VO2~Body.mass | Gosner, regLine=FALSE, smooth=FALSE,
boxplots=FALSE, xlab="Body mass (g)", ylab="Oxygen consumption (ml/h)",
main="", cex=1.4, cex.axis=1.5, cex.lab=1.5, pch=c(19,19), by.groups=TRUE,
col=c("blue","red"), grid=FALSE,
legend=list(coords="bottomright"), data=Tadpoles)
#Get regression equations for groups, subset by Gosner
abline(lm(VO2~Body.mass, data=Stage01), lty=1, lwd=2, col="blue")
abline(lm(VO2~Body.mass, data=Stage02), lty=1, lwd=2, col="red")
Returning to the important question, are the two slopes statistically indistinguishable (Ho: bI = bII), where bI is the slope for the Gosner Stage I subset and bII is the slope for the Gosner Stage II subset? We look at the plot, and since the lines cross, we tend to see a difference. Of course, we need to consider that our perception of slope differences may simply be chance, especially because the sample size is small. Proceed to test.
R code
The ANCOVA is a new ANOVA model where the factor variables are adjusted or corrected for the effects of the continuous variable.
R code for ANCOVA example, crossed or interaction model.
tadpole.1 <- lm(VO2 ~ Body.mass*Gosner, data=example.Tadpole)
summary(tadpole.1)
Anova(tadpole.1, type="II")
Output
summary(tadpole.1)

Call:
lm(formula = VO2 ~ Body.mass * Gosner, data = example.Tadpole)

Residuals:
    Min      1Q   Median      3Q      Max
-167.80 -117.93    13.81   94.66   214.65

Coefficients:
                       Estimate   Std. Error   t value    Pr(>|t|)
(Intercept)             -1231.6       783.0     -1.573    0.1544
Body.mass                 750.0       390.7      1.919    0.0912 .
Gosner[T.II]              790.4       859.2      0.920    0.3845
Body.mass:Gosner[T.II]   -350.1       409.5     -0.855    0.4174
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 155.8 on 8 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.821, Adjusted R-squared: 0.7539
F-statistic: 12.23 on 3 and 8 DF, p-value: 0.002336
The coefficients for the first factor (GII) and then the differences in the coefficient for the second factor. You can just add the second coefficient to the first so they’re on the same scale.
Anova Table (Type II tests)

Response: VO2
                  Sum Sq   Df    F value     Pr(>F)
Body.mass         330046    1    13.6030   0.006146 **
Gosner              5630    1     0.2321   0.642908
Body.mass:Gosner   17736    1     0.7310   0.417423
Residuals 194102 8
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Suggests interaction is not significant, i.e., the slopes are not different.
We can then proceed to check to see if the intercepts are different, now that we’ve confirmed no significant difference in slope.
R code for ANCOVA as additive model
tadpole.2 <- lm(VO2 ~ Body.mass + Gosner, data=example.Tadpole)
summary(tadpole.2)
Anova(tadpole.2, type="II")
Output
> summary(tadpole.2)

Call:
lm(formula = VO2 ~ Body.mass + Gosner, data = example.Tadpole)

Residuals:
    Min       1Q    Median      3Q      Max
-163.12  -125.53    -20.27   83.71   228.56

Coefficients:
                   Estimate   Std. Error     t value    Pr(>|t|)
(Intercept)         -595.37       239.87      -2.482     0.03487 *
Body.mass            431.20       115.15       3.745     0.00459 **
Gosner[T.II]          64.96       132.83       0.489     0.63648
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 153.4 on 9 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.8047, Adjusted R-squared: 0.7613
F-statistic: 18.54 on 2 and 9 DF, p-value: 0.0006432

Anova(tadpole.2, type="II")
Anova Table (Type II tests)

Response: VO2
              Sum Sq    Df    F value      Pr(>F)
Body.mass     330046     1    14.0221   0.004593 **
Gosner          5630     1     0.2392   0.636482
Residuals     211839     9
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Note 1. There is no test of interaction in the added model. This model would be appropriate IF the slopes are equal.
Instead of the interaction, or as added, try a nested model, with body mass nested within stage.
tadpole.3 <- lm(VO2 ~ Body.mass/Gosner, data=example.Tadpole)

summary(tadpole.3)

Call:
lm(formula = VO2 ~ Body.mass/Gosner, data = example.Tadpole)

Residuals:
    Min       1Q    Median      3Q      Max
-168.66  -131.14    -20.28   90.33   225.36

Coefficients:
                 Estimate      Std. Error    t value Pr(>|t|)
(Intercept)           -575.10      319.51     -1.800   0.1054
Body.mass              423.65      162.50      2.607   0.0284 *
Body.mass:Gosner[T.II]  21.95       63.73      0.344   0.7384
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 154.4 on 9 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.8021, Adjusted R-squared: 0.7581
F-statistic: 18.24 on 2 and 9 DF, p-value: 0.0006823
Gets the true coefficient (nested lm() version).
The two test different hypotheses.
lm(VO2 ~ Body.mass * Gosner) tests whether or not the regression has a nonzero slope.
lm(VO2 ~ Body.mass */Gosner) test whether or not the slopes and intercepts from different factors are statistically significant.
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- An OLS approach was used for the analysis of tadpole oxygen consumption body mass. Consider the RMA approach — would that be a more appropriate regression model? Explain why or why not.
- Consider an experiment in which you plan to administer a treatment that has a carry-over effect. For example, Compare and contrast “crossed” and “nested” designs.
- True or False. The nested design option for the ANCOVA assumes the slopes for the two groups of tadpoles for the regression line of by are equal. Explain your choice.
- Metabolic rates like oxygen consumption over time are well-known examples of allometric relationships. That is, many biological variables (eg, is related as aMb, where M is body mass, slope b is scaling exponent), and best evaluated on log-log scale. Repeat the analysis above on log10-transformed and for
- crossed design (eg, tadpole.1 model)
- added design (eg, tadpole.2 model)
- nested design (eg, tadpole.3 model)
- Create the plot and add the fitted lines from crossed design to the plot.
Note 2. About log-transform of a variable. The most straight-forward tact is to create two new variables. For example,
lgVO2 <- log10(VO2)
Another option is to transform the variables within the call to lm() function. For example, try
lm(log10(VO2) ~ log10(Body.mass ), data=example.Tadpole)
Hint: don’t forget to attach your data set to avoid having to call the variable as, for example, example.Tadpole$VO2
Quiz Chapter 17.6
ANCOVA - analysis of covariance
Data sets
Oxygen consumption,  , of Anuran tadpoles, dataset=
example.Tadpole
| Gosner | Body mass | VO2 |
|---|---|---|
| NA | 1.46 | 170.91 |
| I | 1.76 | 109.41 |
| I | 1.88 | 329.06 |
| I | 1.95 | 82.35 |
| I | 2.13 | 198 |
| II | 2.28 | 362.71 |
| I | 2.26 | 607.7 |
| II | 2.35 | 556.6 |
| II | 2.62 | 612.93 |
| II | 2.77 | 514.02 |
| II | 2.97 | 961.01 |
| II | 3.14 | 892.41 |
Gosner refers to Gosner (1960), who developed a criteria for judging metamorphosis staging.
Chapter 17 contents
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – Analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)
17.7 – Regression model fit
Introduction
In Chapter 17.5 and 17.6 we introduced the example of tadpoles body size and oxygen consumption. We ran a simple linear regression, with the following output from R
RegModel.1 <- lm(VO2~Body.mass, data=example.Tadpole)

summary(RegModel.1)

Call:
lm(formula = VO2 ~ Body.mass, data = example.Tadpole)

Residuals:
    Min      1Q    Median       3Q       Max
-202.26 -126.35     30.20    94.01    222.55

Coefficients:
                Estimate     Std. Error    t value    Pr(>|t|)
(Intercept)      -583.05         163.97     -3.556     0.00451 **
Body.mass         444.95          65.89      6.753   0.0000314 ***
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 145.3 on 11 degrees of freedom
Multiple R-squared: 0.8057, Adjusted R-squared: 0.788
F-statistic: 45.61 on 1 and 11 DF, p-value: 0.00003144
You should be able to pick out the estimates of slope and intercept from the table (intercept was -583 and slope was 445). Additionally, as part of your interpretation of the model, you should be able to report how much variation in VO2 was explained by tadpole body mass (coefficient of determination,  , was 0.81, which means about 81% of variation in oxygen consumption by tadpoles is explained by knowing the body mass of the tadpole.
What’s left to do? We need to evaluate how well our model fits the data, i.e., we evaluate regression model fit. By fit we mean, how well does our model agree to the raw data? A poor fit and the model predictions are far from the raw data; a good fit, the model accurately predicts the raw data. In other words, if we draw a line through the raw data, a good fit line crosses through most of the points — a poor fit the line rarely passes through the cloud of points.
How to judge fit? This we can do by evaluating the error components relative to the portion of the model that explains the data. Additionally, we can perform a number of diagnostics of the model relative to the assumptions we made to perform linear regression. These diagnostics form the subject of Chapter 17.8. Here, we ask how well does the model,
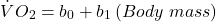
fit the data?
Model fit statistics
The second part of fitting a model is to report how well the model fits the data. The next sections apply to this aspect of model fitting. The first area to focus on is the magnitude of the residuals: the greater the spread of residuals, the less well a fitted line explains the data.
In addition to the output from lm() function, which focuses on the coefficients, we typically generate the ANOVA table also.
Anova(RegModel.1, type="II")
Anova Table (Type II tests)

Response: VO2
                Sum Sq   Df    F value       Pr(>F)
Body.mass       962870    1     45.605   0.00003144 ***
Residuals       232245   11
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Standard error of regression
S, the Residual Standard Error (aka Standard error of regression), is an overall measure to indicate the accuracy of the fitted line: it tells us how good the regression is in predicting the dependence of response variable on the independent variable. A large value for S indicates a poor fit. One equation for S is given by
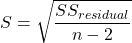
In the above example, S = 145.3 (underlined, bold in regression output above). We can see how if  is large, S will be large indicating poor fit of the linear model to the data. However, by itself S is not of much value as a diagnostic as it is difficult to know what to make of 145.3, for example. Is this a large value for S? Is it small? We don’t have any context to judge S, so additional diagnostics have been developed.
Coefficient of determination
, the coefficient of determination, is also used to describe model fit. can take on values between 0 and 1 (0% to 100%). A good model fit has a high value. In our example above,  or 80.57%. One equation for is given by
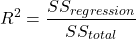
A value of close to 1 means that the regression “explains” nearly all of the variation in the response variable, and would indicate the model is a good fit to the data. As we mentioned in Chapter 17.2, the coefficient of determination, , is the squared value of r, the product moment correlation.
Adjusted R-squared
Before moving on we need to remark on the difference between and adjusted . For Simple Linear Regression there is but one predictor variable, X; for multiple regression there can be many additional predictor variables. Without some correction, will increase with each additional predictor variables. This doesn’t mean the model is more useful, however, and in particular, one cannot compare between models with different numbers of predictors. Therefore, an adjustment is used so that the coefficient of determination remains a useful way to assess how reliable a model is and to permit comparisons of models. Thus, we have the Adjusted  , which is calculated as
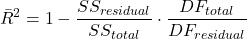
In our example above, Adjusted R 2 = 0.3806 or 38.06%.
Which should you report? Adjusted ,because it is independent of the number of parameters in the model.
Both and S are useful for regression diagnostics, a topic which we will discuss next (Chapter 17.8).
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- As you may know, the US census is used to reapportion congress and also to determine the number of electoral college votes. In honor of the election for US President that’s just days away, in the next series of questions in this Chapter and subsequent sections of Chapter 17 and 18, I’ll ask you to conduct a regression analysis on the electoral college. For starters, make the regression of Electoral votes on 2010 census population. (Ignore for now the other columns, just focus on POP_2019 and Electoral.) Report the
- regression coefficients (slope, intercept)
- percent of the variation in electoral college votes explained by the regression ( ).
- Make a scatterplot and add the regression line to the plot
Quiz Chapter 17.7
Regression model fit
Data set
USA population year 2010 and year 2019 with Electoral College counts
| State | Region | Division | POP_2010 | POP_2019 | Electoral |
|---|---|---|---|---|---|
| Alabama | South | East South Central | 4779736 | 4903185 | 9 |
| Alaska | West | Pacific | 710231 | 731545 | 3 |
| Arizona | West | Mountain | 6392017 | 7278717 | 11 |
| Arkansas | South | West South Central | 2915918 | 3017804 | 6 |
| California | West | Pacific | 37253956 | 39512223 | 55 |
| Colorado | West | Mountain | 5029196 | 5758736 | 9 |
| Connecticut | Northeast | New England | 3574097 | 3565287 | 7 |
| Delaware | South | South Atlantic | 897934 | 982895 | 3 |
| District of Columbia | South | South Atlantic | 601723 | 705749 | 3 |
| Florida | South | South Atlantic | 18801310 | 21477737 | 29 |
| Georgia | South | South Atlantic | 9687653 | 10617423 | 16 |
| Hawaii | West | Pacific | 1360301 | 1415872 | 4 |
| Idaho | West | Mountain | 1567582 | 1787065 | 4 |
| Illinois | Midwest | East North Central | 12830632 | 12671821 | 20 |
| Indiana | Midwest | East North Central | 6483802 | 6732219 | 11 |
| Iowa | Midwest | West North Central | 3046355 | 3155070 | 6 |
| Kansas | Midwest | West North Central | 2853118 | 2913314 | 6 |
| Kentucky | South | East South Central | 4339367 | 4467673 | 8 |
| Louisiana | South | West South Central | 4533372 | 4648794 | 8 |
| Maine | Northeast | New England | 1328361 | 1344212 | 4 |
| Maryland | South | South Atlantic | 5773552 | 6045680 | 10 |
| Massachusetts | Northeast | New England | 6547629 | 6892503 | 11 |
| Michigan | Midwest | East North Central | 9883640 | 9883635 | 16 |
| Minnesota | Midwest | West North Central | 5303925 | 5639632 | 10 |
| Mississippi | South | East South Central | 2967297 | 2976149 | 6 |
| Missouri | Midwest | West North Central | 5988927 | 6137428 | 10 |
| Montana | West | Mountain | 989415 | 1068778 | 3 |
| Nebraska | Midwest | West North Central | 1826341 | 1934408 | 5 |
| Nevada | West | Mountain | 2700551 | 3080156 | 6 |
| New Hampshire | Northeast | New England | 1316470 | 1359711 | 4 |
| New Jersey | Northeast | Mid-Atlantic | 8791894 | 8882190 | 14 |
| New Mexico | West | Mountain | 2059179 | 2096829 | 5 |
| New York | Northeast | Mid-Atlantic | 19378102 | 19453561 | 29 |
| North Carolina | South | South Atlantic | 9535483 | 10488084 | 15 |
| North Dakota | Midwest | West North Central | 672591 | 762062 | 3 |
| Ohio | Midwest | East North Central | 11536504 | 11689100 | 18 |
| Oklahoma | South | West South Central | 3751351 | 3956971 | 7 |
| Oregon | West | Pacific | 3831074 | 4217737 | 7 |
| Pennsylvania | Northeast | Mid-Atlantic | 12702379 | 12801989 | 20 |
| Rhode Island | Northeast | New-England | 1052567 | 1059361 | 4 |
| South Carolina | South | South-Atlantic | 4625364 | 5148714 | 9 |
| South Dakota | Midwest | West-North-Central | 814180 | 884659 | 3 |
| Tennessee | South | East-South-Central | 6346105 | 6829174 | 11 |
| Texas | South | West-South-Central | 25145561 | 28995881 | 38 |
| Utah | West | Mountain | 2763885 | 3205958 | 6 |
| Vermont | Northeast | New-England | 625741 | 623989 | 3 |
| Virginia | South | South-Atlantic | 8001024 | 8535519 | 13 |
| Washington | West | Pacific | 6724540 | 7614893 | 12 |
| West Virginia | South | South-Atlantic | 1852994 | 1792147 | 5 |
| Wisconsin | Midwest | East-North-Central | 5686986 | 5822434 | 10 |
| Wyoming | West | Mountain | 563626 | 578759 | 3 |
Chapter 17 contents
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – Analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)
17.3 – Estimation of linear regression coefficients
Introduction
In discussing correlations we made the distinction between inference, testing the statistical significance of the estimate, and the process of getting the estimate of the parameter itself. Estimating parameters is possible for any data set; whether or not the particular model is a good and useful model is another matter. Statisticians speak about the fit of a model… that a model with one or more independent predictor variables explains a substantial amount of the variation in the dependent variable, that it describes the relationship between the predictors and the dependent variable without bias.
Note 1. We introduced the concept of statistical fit in our discussion of Chi-square, goodness of fit, Chapter 9.1.
A number of tools have been developed to assess model fit. For starters, I’ll list just two ways you can approach whether or not a linear model fits your data ore requires some intervention on your part.
Assess fit of a linear model
Recall our R output from the regression of Number of Matings on Body Mass from the bird data set. We used the linear model function.
LinearModel.1 <- lm(Matings ~ Body.Mass, data=bird_matings)
summary(LinearModel.1)
Call: lm(formula = Matings ~ Body.Mass, data = bird_matings)
Residuals:       Min       1Q    Median       3Q      Max
            -2.29237 -1.34322 .-0.03178..1.33792 .2.70763
Coefficients:
             Estimate  Std. Error  t value  Pr(>|t|)
(Intercept)   -8.4746      4.6641   -1.817    0.1026
Body.Mass      0.3623      0.1355    2.673    0.0255 *
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Residual standard error: 1.776 on 9 degrees of freedom
Multiple R-squared: 0.4425, Adjusted R-squared: 0.3806
F-statistic: 7.144 on 1 and 9 DF, p-value: 0.02551
Request R to print the ANOVA table.
Anova(RegModel.1, type="II")
Anova Table (Type II tests)
Response: Matings
            Sum Sq   Df   F value    Pr(>F)
Body.Mass   22.528    1    7.1438   0.02551 *
Residuals   28.381    9
With a little rounding we have the following statistical model
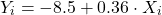
and in English, Number of matings equals Body.mass multiplied by 0.36 then subtract 8.5; the intercept was -8.5, the slope was 0.36.
Note 2. The results of the regression analyses were stored in the object called “LinearModel.1“. This is a nice feature of Rcmdr — it automatically provides an object name for you. Note that with each successive run of the linear model function via Rcmdr that it will change the object name by adding numbers successively. For example, after LinearModel.1 the next run of lm() in Rcmdr will automatically be called “LinearModel.2” and so on. In your own work you may specify the names of the objects directly or allow Rcmdr to do it for you, but do keep track of the object names!
From the R output we see that the estimate of the slope was +0.36, statistically different from zero (p = 0.025). The intercept was -8.5, but not statistically significant (p = 0.103), which means the intercept may be zero.
As a general rule, if you make an estimate of a parameter or coefficient, then you should provide a confidence interval of the form.
estimate + critical value X standard error of the estimate
Note 3. Reminder: Approximate 95% CI can be obtained by + twice the standard error for the coefficient.
For confidence interval of regression slope we have a couple of options in R
Option 1.
confint(LinearModel.1, 'Body.Mass', level=0.95)

               2.5 %    97.5 %
Body.Mass 0.05565899 0.6689173
Option 2.
Goal: Extract the coefficients from the output of the linear model and calculate the approximate SE with nine degrees of freedom. This is the big advantage of saving output from functions as objects. Typically, much more information is about the results are available, and, additionally, can be retrieved for additional use. Extracting coefficients from the objects is the best option, but does come with a learning curve. Let’s get started.
First, what information is available in the linear model output beyond the default information? To find out, use the names() function
names(LinearModel.1)
R output
 [1] "coefficients"  "residuals"     "effects"       "rank"
 [5] "fitted.values" "assign"        "qr"            "df.residual"
 [9] "xlevels"       "call"          "terms"         "model"
Another way is to use the summary() function call.
summary(LinearModel.1)$coefficients
              Estimate Std. Error   t value   Pr(>|t|)
(Intercept) -8.4745763  4.6640856 -1.816986 0.10259256
Body.Mass    0.3622881  0.1355472  2.672781 0.02550595
How can we get just the standard error for the slope? Note that the estimates are reported in a 2X4 matrix like so
| 1,1 | 1,2 | 1,3 | 1,4 |
| 2,1 | 2,2 | 2,3 | 2,4 |
Therefore, to get the standard error for the slope we identify that it is stored in cell 2,2 of the matrix and we write
summary(LinearModel.1)$coefficients[2,2]
which returns
[1] 0.1355472
Let’s use this information to calculate confidence intervals
slp=summary(LinearModel.1)$coefficients[2,1]
slpErrs=summary(LinearModel.1)$coefficients[2,2]
slp + c(-1,1)*slpErrs*qt(0.975, 9)
where qt() is the quantile function for the t distribution and “9” is the degrees of freedom from the regression. Results follow
coef + c(-1,1)*errs*qt(0.975, 9)
[1] 0.05565899 0.66891728
And for the intercept
int=summary(LinearModel.1)$coefficients[1,1]
intErrs=summary(LinearModel.1)$coefficients[1,2]
int + c(-1,1)*intErrs*qt(0.975, 9)
Results
int + c(-1,1)*intErrs*qt(0.975, 9)
[1] -19.025471   2.076318
In conclusion, part of fitting a model includes reporting the estimates of the coefficients (model parameters). And, in general, when estimation is performed, reporting of suitable confidence intervals are expected.
Extract additional statistics from R’s linear model function
The summary() function is used to report the general results from ANOVA and linear model function output in R software, but additional functions can be used to extract the rest of the output, e.g., coefficient of determination. To complete our example of extracting information from the summary() function, we next turn to summary.lm() function to see what is available.
At the R prompt type and submit
summary.lm(LinearModel.1)
returns the following R output
Call:
lm(formula = Matings ~ Body.Mass, data = bird_matings)

Residuals:
     Min       1Q   Median       3Q      Max
-2.29237 -1.34322 -0.03178  1.33792  2.70763

Coefficients:
            Estimate Std. Error t value Pr(>|t|)
(Intercept)  -8.4746     4.6641  -1.817   0.1026
Body.Mass     0.3623     0.1355   2.673   0.0255 *
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 1.776 on 9 degrees of freedom
Multiple R-squared:  0.4425,    Adjusted R-squared:  0.3806
F-statistic: 7.144 on 1 and 9 DF,  p-value: 0.02551
Looks exactly like the output from summary(). Let’s look at what is available in the summary.lm() function
names(summary.lm(LinearModel.1))
 [1] "call"          "terms"         "residuals"     "coefficients"
 [5] "aliased"       "sigma"         "df"            "r.squared"
 [9] "adj.r.squared" "fstatistic"    "cov.unscaled"
We see some information we got from summary(), e.g., “coefficients”. If we interrogate the name coefficients like so
summary.lm(LinearModel.1)$coefficients
we get
summary.lm(LinearModel.1)$coefficients
              Estimate Std. Error   t value   Pr(>|t|)
(Intercept) -8.4745763  4.6640856 -1.816986 0.10259256
Body.Mass    0.3622881  0.1355472  2.672781 0.02550595
which, again, is a 2X4 matrix (see above)
So to get the standard error for the slope we identify that it is stored in cell 2,2 of the matrix and call it LinearModel.1$coefficients[2,2].
Questions
1. Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
2. What does a small standard error of the slope for a SLR model tell us?
3. For slope, intercept, for just about any statistical estimate, why are we obligated to provide a confidence interval?
Quiz Chapter 17.3
Estimation of linear regression coefficients
Chapter 17 contents
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)
17.1 – Ordinary least squares regression
-
- Introduction
- Example
- Least squares regression explained
- Models used to predict new values
- R code
- How to extract information from an R object
- Regression equations may be useful to predict new observations
- Regression through the origin
- Assumptions of OLS, an introduction
- Questions
- Quiz
- Chapter 17 contents
Introduction
Linear regression is a toolkit for developing linear models of cause and effect between a ratio scale data type, response or dependent variable, often labeled “Y,” and one or more ratio scale data type, predictor or independent variables, X. Like ANOVA, linear regression is a special case of the general linear model. Regression and correlation both test linear hypotheses: we state that the relationship between two variables is linear (the alternative hypothesis) or it is not (the null hypothesis). The difference?
- Correlation is a test of linear association (are variables correlated, we ask?), but are not tests of causation: we do not imply that one variable causes another to vary, even if the correlation between the two variables is large and positive, for example. Correlations are used in statistics on data sets not collected from explicit experimental designs incorporated to test specific hypotheses of cause and effect.
- Linear regression is to cause and effect as correlation is to association. With regression and ANOVA, which again, are special cases of the general linear model (LM), we are indeed making a case for a particular understanding of the cause of variation in a response variable: modeling cause and effect is the goal.
We start our LM model as 
where “~”, tilda, is an operator used by R in formulas to define the relationship between the response variable and the predictor variable(s).
From R Commander we call the linear model function by Statistics → Fit models → Linear model … , which brings up a menu with several options (Fig 1).
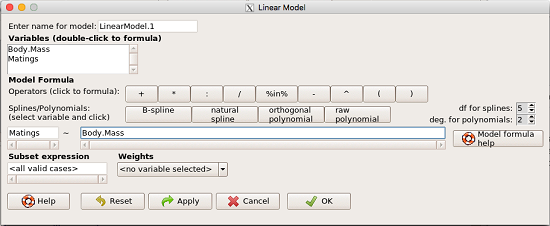
Figure 1. R commander menu interface for linear model.
Our model was
Matings ~ Body.Mass
R commander will keep track of the models created and enter a name for the object. You can, and probably should, change the object name yourself. The example shown in Figure 1 is a simple linear regression, with Body.Mass as the Y variable and Matings the X variable. No other information need be entered and one would simply click OK to begin the analysis.
Example
The purpose of regression is similar to ANOVA. We want a model, a statistical representation to explain the data sample. The model is used to show what causes variation in a response (dependent) variable using one or more predictors (independent variables). In life history theory, mating success is an important trait or characteristic that varies among individuals in a population. For example we may be interested in determining the effect of age (X1) and body size (X2) on mating success for a bird species. We could handle the analysis with ANOVA, but we would lose some information. In a clinical trial, we may predict that increasing Age (X1) and BMI (X2) causes increase blood pressure (Y).
Our causal model looks like
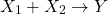
Let’s review the case for ANOVA first.
The response (dependent variable), the number of successful matings for each individual male bird, would be a quantitative (interval scale) variable. (Reminder: You should be able to tell me what kind of analysis you would be doing if the dependent variable was categorical!) If we use ANOVA, then factors have levels. For example, we could have several adult birds differing in age (factor 1) and of different body sizes. Age and body size are quantitative traits, so, in order to use our standard ANOVA, we would have to assign individuals to a few levels. We could group individuals by age (eg, < 6 months, 6 – 10 months, > 12 months) and for body size (eg, small, medium, large). For the second example, we might group the subjects into age classes (20-30, 30-40, etc), and by AMA recommended BMI levels (underweight < 18.5, normal weight 18.5 – 24.9, overweight 25-29.9, obese > 30).
We have not done anything wrong by doing so, but if you are a bit uneasy by this, then your intuition will be rewarded later when we point out that in most cases you are best to leave it as a quantitative trait. We proceed with the test of ANOVA, but we are aware that we’ve lost some information — continuous variables (age, body size, BMI) were converted to categories — and so we suspect (correctly) that we’ve lost some power to reject the null hypothesis. By the way, when you have a “factor” that is a continuous variable, we call it a “covariate.” Factor typically refers to a categorical explanatory (independent) variable.
We might be tempted to use correlation — at least to test if there’s a relationship between Body Mass and Number of Matings. Correlation analysis is used to measure the intensity of association between a pair of variables. Correlation is also used to to test whether the association is greater than that expected by chance alone. We do not express one as causing variation in the other variable, but instead, we ask if the two variables are related (covary). We’ve already talked about some properties of correlation: it ranges from -1 to +1 and the null hypothesis is that the true association between two variables is equal to zero. We will formalize the correlation next time to complete our discussion of the linear relationship between two variables.
But regression is appropriate here because we are indeed making a causal claim: we selected Age and Body Size, and we selected Age and BMI in the second example wish to develop a model so we can predict and maybe even advise.
Least squares regression explained
Regression is part of the general linear model family of tests. If there is one linear predictor variable, then that is a simple linear regression (SLR), also called ordinary least squares (OLS), if there are two or more linear predictor variables, then that is a multiple linear regression (MLR, Chapter 18).
First, consider one predictor variable. We begin by looking at how we might summarize the data by fitting a line to the data; we see that there’s a relationship between mass and mating success in both young and old females (and maybe in older males).
The data set was
Table 1. Our data set of number of matings by male bird by body mass (g).
| Body.Mass | Matings |
|---|---|
| 29 | 0 |
| 29 | 2 |
| 29 | 4 |
| 32 | 4 |
| 32 | 2 |
| 35 | 6 |
| 36 | 3 |
| 38 | 3 |
| 38 | 5 |
| 38 | 8 |
| 40 | 6 |
Note 1: Unfortunately, I’ve lost track where Table 1 data set came from! It’s likely a simulated set inspired by my readings back in 2005.
And a scatterplot of the data (Fig 2)
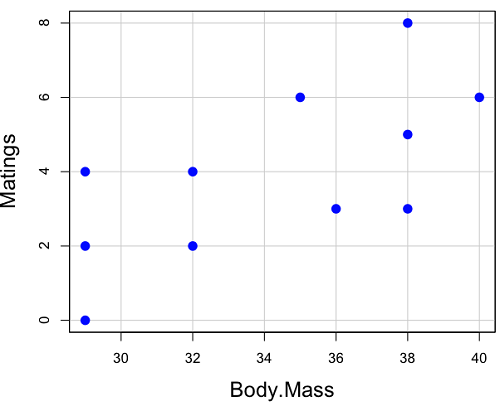
Figure 2. Number of matings by body mass (g) of the male bird.
There’s some scatter, but our eyes tell us that as body size increases, the number of matings also increases. We can go so far as to say that we can predict (imperfectly) that larger birds will have more matings. We fit the best fit line to the data and added the line to our scatterplot (Fig 3). The best fit line meets the requirements that the error about the line is minimized (see below). Thus, we would predict about six matings for a 40 g bird, but only two matings for a 28 g bird. And this is a good feature of regression, prediction, as long as used with some caution.
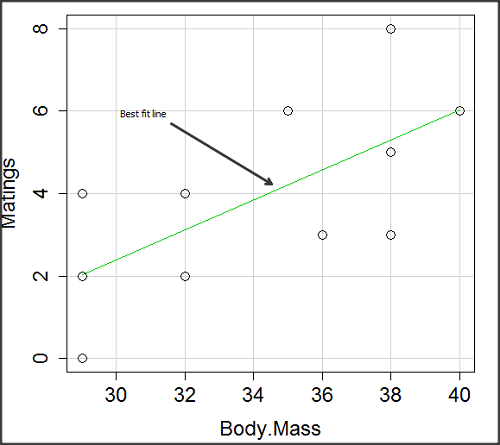
Figure 3. Same data as in Fig 2, but with the “best fit” line.
The prediction works best for the range of data for which the regression model was built. Outside the range of values, we predict with caution.
The simplest linear relationship between two variables is the SLR. This would be the parameter version (population, not samples), where
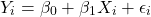
 = the Y-intercept coefficient and it is defined as
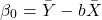
solve for intercept by setting X = 0.
 = the regression coefficient (slope)
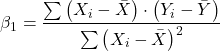
Note 2: The denominator is just our corrected sums of squares that we’ve seen many times before. The numerator is the cross-product and is referred to as the covariance.
ε = the error or “residual”

The residual is an important concept in regression. We briefly discussed “what’s left over,” in ANOVA, where an observation Yi is equal to the population mean plus the factor effect of level i plus the remainder or “error”.
In regression, we speak of residuals as the departure (difference) of an actual Yi (observation) from the predicted Y ( , say “why-hat”).
the linear regression predicts Y
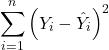
and what remains unexplained by the regression equation is called the residual
There will be as many residuals as there were observations.
But why THIS particular line? We could draw lines anywhere through the points. Well, this line is termed the “best fit“ because it is the only line that minimizes the sum of the squared deviations for all values of Y (the observations) and the predicted . The best fit line minimizes the sum of the squared residuals.
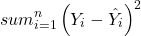
Note 3: More technically we justify the OLS as best fit by saying” Following the Gauss–Markov theorem, OLS estimators are the best linear unbiased estimators (BLUE). Gauss (1821) proved that the least squares method produces unbiased estimates with the smallest variance, a key result for regression analysis, while Markov (1900) rediscovered Gauss’ work and showed the conclusions held under less restrictive conditions.
Thus, like ANOVA, we can account for the total sums of squares (SSTot) as equal to the sums of squares (variation), explained by the regression model, SSreg, plus what’s not explained, what’s left over, the residual sums of squares, SSres, aka SSerror.
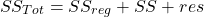
How well does our model explain — fit — our data? We cover this topic in Chapter 17.3 — Estimation of linear regression coefficients, but for now, we introduce , the coefficient of determination.

ranges from zero (0%), the linear model fails completely to explain the data, to one (100%), the linear model explains perfectly every datum.
Models used to predict new values
Once a line has been estimated, one use is to predict new observations not previously measured!
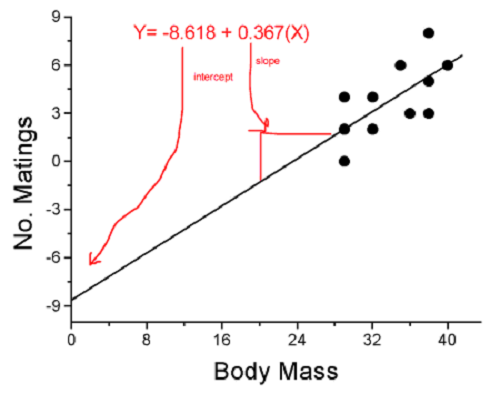
Figure 4. Figure 3 redrawn to extend the line to the Y intercept.
This is an important use of models in statistics: use an equation to fit to some data, then predict Y values from new values of X. To use the equation, simply insert new values of X into the equation, because the slope and intercept are already “known.” Then for any Xi we can determine  (predicted Y value that is on the best fit regression line).
This is what people do when they say
“if you are a certain weight (or BMI) you have this increased risk of heart disease”
“if you have this number of black rats in the forest you will have this many nestlings survive to leave the nest”
“if you have this much run-off pollution into the ocean you have this many corals dying”
“if you add this much enzyme to the solution you will have this much resulting product”.
R Code
We can use the drop down menu in Rcmdr to do the bulk of the work, supplemented with a little R code entered and run from the script window. Scrape data from Table 1 and save to R as bird.matings.
LinearModel.3 <- lm(Matings ~ Body.Mass, data=bird.matings)
summary(LinearModel.3)
Output from R — we’ll pull apart the important parts, color-highlights used to help orient the reader as we go.
Call:
lm(formula = Matings ~ Body.Mass, data = bird.matings)

Residuals:
     Min       1Q   Median      3Q     Max
-2.29237 -1.34322 -0.03178 1.33792 2.70763

Coefficients:
            Estimate Std. Error  t value  Pr(>|t|)
(Intercept)  -8.4746     4.6641   -1.817    0.1026
Body.Mass     0.3623     0.1355    2.673    0.0255 *
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 1.776 on 9 degrees of freedom
Multiple R-squared: 0.4425, Adjusted R-squared: 0.3806
F-statistic: 7.144 on 1 and 9 DF, p-value: 0.02551
What are the values for the coefficients? See Estimate .
Table 2. Coefficient estimates.
| Value | |
 , Y-intercept |
-8.4746 |
 , Slope |
0.3623 |
Get the sum of squares from the ANOVA table
myAOV.full <- anova(LinearModel.3); myAOV.full
Output from R, the ANOVA table
Analysis of Variance Table

Response: Matings
           Df  Sum Sq  Mean Sq  F value     Pr(>F)
Body.Mass   1  22.528  22.5277   7.1438   0.02551 *
Residuals   9  28.381   3.1535
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Looking for , the coefficient of determination? From the R output identify Multiple R-squared. We find 0.4425. Grab the SSreg and SSTot from the ANOVA table and confirm
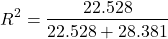
Note 2: The value of increases with each additional predictor variable included in the model, whether statistically significant contributor or not, regardless of whether the association between the predictor is simply due to chance. The Adjusted R-squared is an attempt to correct for this bias.
The residual standard error, RSE, is another model fit statistic.
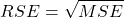
The smaller the residual standard error, the better the model fit to the data. See Residual standard error: 1.776 and MSE = 3.1535 above.
And the “statistical significance?” See Pr(>|t|) .There were tests for each coefficient,  and
 :
Table 3. Coefficient estimates.
| P-value | |
| , Y-intercept |
0.1026 |
| , Slope |
0.0255 |
And, at last, note that p-value, Pr(>F), reported in the Analysis of Variance Table, is the same as the p-value for the slope reported as Pr(>|t|).
Make a prediction:
How many matings expected for a 40 g male?
predict(LinearModel.3, data.frame(Body.Mass=40))
R output
1
6.016949
Answer: we predict 6 matings for a 40g male.
See below for predicting confidence limits.
How to extract information from an R object
We can do more — the lm() returnd a great deal of information about our regression model. Explore all that is available in the objects LinearModel.3 and myAOV.full with the str() command.
Note 3: str() command lets us look at an object created in R. Type ?str or help(str) to bring up the R documentation. Here, we use str() to look at the structure of the objects we created. “Classes” refers to the R programming class attribute inherited by the object. We first used str() in Chapter 8.3.
str(LinearModel.3)
Output from R
List of 12
$ coefficients : Named num [1:2] -8.475 0.362
..- attr(*, "names")= chr [1:2] "(Intercept)" "Body.Mass"
$ residuals : Named num [1:11] -2.0318 -0.0318 1.9682 0.8814 -1.1186 ...
..- attr(*, "names")= chr [1:11] "1" "2" "3" "4" ...
$ effects : Named num [1:11] -12.965 4.746 2.337 1.327 -0.673 ...
..- attr(*, "names")= chr [1:11] "(Intercept)" "Body.Mass" "" "" ...
$ rank : int 2
$ fitted.values: Named num [1:11] 2.03 2.03 2.03 3.12 3.12 ...
..- attr(*, "names")= chr [1:11] "1" "2" "3" "4" ...
$ assign : int [1:2] 0 1
$ qr :List of 5
..$ qr : num [1:11, 1:2] -3.317 0.302 0.302 0.302 0.302 ...
.. ..- attr(*, "dimnames")=List of 2
.. .. ..$ : chr [1:11] "1" "2" "3" "4" ...
.. .. ..$ : chr [1:2] "(Intercept)" "Body.Mass"
.. ..- attr(*, "assign")= int [1:2] 0 1
..$ qraux: num [1:2] 1.3 1.3
..$ pivot: int [1:2] 1 2
..$ tol : num 0.0000001
..$ rank : int 2
..- attr(*, "class")= chr "qr"
$ df.residual : int 9
$ xlevels : Named list()
$ call : language lm(formula = Matings ~ Body.Mass, data = bird_matings)
$ terms :Classes 'terms', 'formula' language Matings ~ Body.Mass
.. ..- attr(*, "variables")= language list(Matings, Body.Mass)
.. ..- attr(*, "factors")= int [1:2, 1] 0 1
.. .. ..- attr(*, "dimnames")=List of 2
.. .. .. ..$ : chr [1:2] "Matings" "Body.Mass"
.. .. .. ..$ : chr "Body.Mass"
.. ..- attr(*, "term.labels")= chr "Body.Mass"
.. ..- attr(*, "order")= int 1
.. ..- attr(*, "intercept")= int 1
.. ..- attr(*, "response")= int 1
.. ..- attr(*, ".Environment")=<environment: R_GlobalEnv>
.. ..- attr(*, "predvars")= language list(Matings, Body.Mass)
.. ..- attr(*, "dataClasses")= Named chr [1:2] "numeric" "numeric"
.. .. ..- attr(*, "names")= chr [1:2] "Matings" "Body.Mass"
$ model :'data.frame': 11 obs. of 2 variables:
..$ Matings : num [1:11] 0 2 4 4 2 6 3 3 5 8 ...
..$ Body.Mass: num [1:11] 29 29 29 32 32 35 36 38 38 38 ...
..- attr(*, "terms")=Classes 'terms', 'formula' language Matings ~ Body.Mass
.. .. ..- attr(*, "variables")= language list(Matings, Body.Mass)
.. .. ..- attr(*, "factors")= int [1:2, 1] 0 1
.. .. .. ..- attr(*, "dimnames")=List of 2
.. .. .. .. ..$ : chr [1:2] "Matings" "Body.Mass"
.. .. .. .. ..$ : chr "Body.Mass"
.. .. ..- attr(*, "term.labels")= chr "Body.Mass"
.. .. ..- attr(*, "order")= int 1
.. .. ..- attr(*, "intercept")= int 1
.. .. ..- attr(*, "response")= int 1
.. .. ..- attr(*, ".Environment")=<environment: R_GlobalEnv>
.. .. ..- attr(*, "predvars")= language list(Matings, Body.Mass)
.. .. ..- attr(*, "dataClasses")= Named chr [1:2] "numeric" "numeric"
.. .. .. ..- attr(*, "names")= chr [1:2] "Matings" "Body.Mass"
- attr(*, "class")= chr "lm"
Yikes! A lot of the output is simply identifying how R handled our data.frame and applied the lm() function.
Note 4: The “how” refers to the particular algorithms used by R. For example, qraux, pivot, and tol refer to arguments used in the QR decomposition of the matrix (derived from our data.frame) used to solve our linear least squares problem.
However, it’s from this command we learn what is available to extract in our object. For example, what were the actual fitted values (, the predicted Y values) from our linear equation? I marked the relevant str() output above in yellow. We call these from the object with the R code
RegModel.1$fitted.values
and R returns
       1        2        3        4        5        6        7        8        9       10       11
2.031780 2.031780 2.031780 3.118644 3.118644 4.205508 4.567797 5.292373 5.292373 5.292373 6.016949
Here’s another look at an object, str(myAOV.full), and how to extract useful values.
Output from R
Classes 'anova' and 'data.frame': 2 obs. of 5 variables:
$ Df : int 1 9
$ Sum Sq : num 22.5 28.4
$ Mean Sq: num 22.53 3.15
$ F value: num 7.14 NA
$ Pr(>F) : num 0.0255 NA
- attr(*, "heading")= chr [1:2] "Analysis of Variance Table\n" "Response: Matings"
Extract the sum of squares: type the object name then $ Sum Sq at the R prompt.
myAOV.full $"Sum Sq"
Output from R
[1] 22.52773 28.38136
Get the residual sum of squares
SSE.myAOV.full <- myAOV.full $"Sum Sq"[2]; SSE.myAOV.full
Output from R
[1] 22.52773
Get the regression sum of squares
SSR.myAOV.full <- myAOV.full $"Sum Sq"[1]; SSR.myAOV.full
Output from R
[1] 50.90909
Now, get the total sums of squares for the model

ssTotal.myAOV.full <- SSE.myAOV.full + SSR.myAOV.full; ssTotal.myAOV.full
Calculate the coefficient of determination
myR_2 <- 1 - (SSE.myAOV.full/(ssTotal.myAOV.full)); myR_2
Output from R
[1] 0.4425091
Which matches what we got before, as it should.
Regression equations may be useful to predict new observations
True. However, you should avoid making estimates beyond the range of the X – values that were used to calculate the best fit regression equation! Why? The answer has to do with the shape of the confidence interval around the regression line.
I’ve drawn an exaggerated confidence interval (CI), for a regression line between an X and a Y variable. Note that the CI is narrow in the middle, but wider at the end. Thus, we have more confidence in predicting new Y values for data that fall within the original data because this is the region where we are most confident.
Calculating the CI for the linear model follows from CI calculations for other estimates. It is a simple concept — both the intercept and slope were estimated with error, so we combine these into a way to generalize our confidence in the regression model as a whole given the error in slope and intercept estimation.
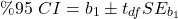
The calculation of confidence interval for the linear regression involves the standard error of the residuals, the sample size, and expressions relating the standard deviation of the predictor variable X — we use the t distribution.
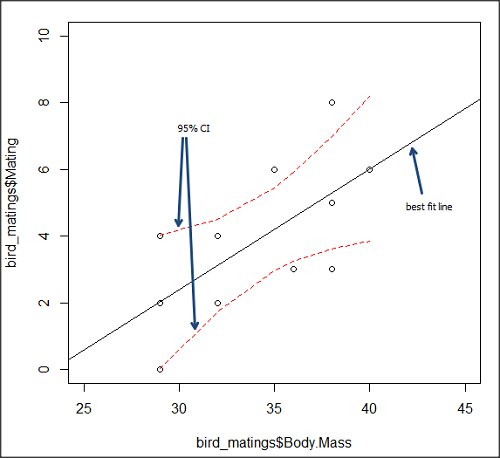
Figure 5. 95% confidence interval about the best fit line.
How I got this graph
plot(bird_matings$Body.Mass,bird_matings$Mating,xlim=c(25,45),ylim=c(0,10))
mylm <- lm(bird_matings$Mating~bird_matings$Body.Mass)
predict(mylm, interval = c("confidence"))
abline(mylm, col = "black")
x<-bird_matings$Body.Mass
lines(x, prd[,2], col= "red", lty=2)
lines(x, prd[,3], col= "red", lty=2)
Nothing wrong with my code, but getting all of this to work in R might best be accomplished by adding another package, a plug-in for Rcmdr called RcmdrPlugin.HH. HH refers to “Heiberger and Holland,” and provides software support for their textbook Statistical Analysis and Data Display, 2nd edition.
Regression through the origin
A regression through the origin in OLS is appropriate when theory dictates that the response must be zero when the predictor is zero, that is, the intercept is known to be exactly 0. In population genetics, for example, if you model pairwise genetic distance as a function of some measure of separation, (eg, time or geographic distance), and the definition of the metric ensures that identical individuals have zero distance, then forcing the regression through the origin can be justified. Doing so reduces parameter estimation to the slope alone and can improve efficiency when the assumption is correct. However, if the true relationship includes a nonzero intercept, constraining it to zero biases the slope.
This choice also affects the coefficient of determination (R²): in a no-intercept model, R² is computed relative to zero rather than the mean of Y, so it is not directly comparable to the standard R² from a model with an intercept and can even appear artificially higher or lower. If the origin constraint is correct, the no-intercept model may show a better (more meaningful) fit; if not, the apparent R² can be misleading despite biased estimates.
R code for regression without the Y-intercept:
noOrigin.model <- lm(formula = Matings ~ 0 + Body.Mass, data = bird.matings)
summary(noOrigin.model)
And the R output:
Call:
lm(formula = Matings ~ 0 + Body.Mass, data = bird.matings)

Residuals:
    Min      1Q  Median      3Q     Max
-3.4112 -1.4406  0.2359  0.9418  3.5301

Coefficients:
          Estimate Std. Error t value Pr(>|t|)
Body.Mass  0.11763    0.01726   6.816 4.65e-05 ***
---
Signif. codes:  0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1

Residual standard error: 1.97 on 10 degrees of freedom
Multiple R-squared:  0.8229,	Adjusted R-squared:  0.8052
F-statistic: 46.45 on 1 and 10 DF,  p-value: 4.65e-05
Interpretation and comparison between model with and without fit through the origin.
Without an intercept (regression through the origin), the model estimates a slope of 0.1176 (SE = 0.0173, t = 6.82, p = 4.65×10⁻⁵), indicating a strong, statistically significant positive association between Body Mass and the response. Because the intercept is constrained to zero, this slope is effectively forced to account for all variation in Y, which often inflates its magnitude of significance and can bias the estimate if the true relationship does not pass through the origin.
When the intercept was included, the slope increased to 0.3623 (SE = 0.1355, t = 2.67, p = 0.0255), still statistically significant but less so, while the intercept is estimated at –8.47 (SE = 4.66, p = 0.103), which is not significantly different from zero at conventional levels. The change in slope (from 0.12 to 0.36) shows that allowing a nonzero intercept alters the fitted relationship substantially, suggesting that the origin constraint may not be appropriate in this case. Even though the intercept is not statistically significant, its inclusion redistributes variance between intercept and slope, yielding a more reliable slope estimate and a standard R² that is comparable across models, unlike the no-intercept case.
The negative Y-intercept, while statistically justifiable, is also biologically unrealistic, implying a negative number of matings. The statistical justification is simply that the model is used to predict mating success for organisms in the range of body size included in the data set used to make the model — the negative Y-intercept than is interpreted that we are trying to extend the model beyond its range.
In our example with the birds, a biological justification for a non intercept model can be made. For example, mating success is positively associated with body size; therefore, an organism with a hypothetical body size of zero would logically have zero chance of mating success. That said, even when biology suggests the relationship should pass through the origin, it may still be useful to fit a model with an intercept to test that assumption rather than impose it.
Measurement error, in the case of our birds example, chiefly if observed count of matings differs from the true, actual number of matings that occurred, or in a student employing genetic distance, then a number of errors may occur, including sequencing artifacts, alignment bias, or the way genetic distance is computed (eg, corrections for multiple substitutions, cf discussions in Felsenstein 2003, see Legendre and Desdevises 2009 for justifications for through the origin and phylogenetic independent contrasts). As well documented in standard texts on regression and linear models (eg, Introduction to Linear Regression Analysis, by Montgomery et al 2021; An Introduction to Generalized Linear Models, by Dobson and Barnett 2018), measurement error can introduce a small offset, so the estimated intercept serves as a diagnostic for systematic bias. If the intercept is close to zero and not significant, that provides empirical support for the origin constraint; if it is meaningfully different from zero, forcing the regression through the origin would bias the slope and distort inference. Additionally, including the intercept yields a standard R² and residual structure that are comparable across models, helping assess overall model fit before deciding whether the biologically motivated constraint is justified.
Assumptions of OLS, an introduction
We will cover assumptions of Ordinary Least Squares in detail in 17.8, Assumptions and model diagnostics for Simple Linear Regression. For now, briefly, the assumptions for OLS regression include:
- Linear model is appropriate: the data are well described (fit) by a linear model
- Independent values of Y and equal variances. Although there can be more than one Y for any value of X, the Y’s cannot be related to each other (that’s what we mean by independent). Since we allow for multiple Y’s for each X, then we assume that the variances of the range of Ys are equal for each X value (this is similar to our ANOVA assumptions for equal variance by groups).
- Normality. For each X value there is a normal distribution of Ys (think of doing the experiment over and over)
- Error (residuals) are normally distributed with a mean of zero.
Additionally, we assume that measurement of X is done without error (the equivalent, but less restrictive practical application of this assumption is that the error in X is at least negligible compared to the measurements in the dependent variable). Multiple regression makes one more assumption, about the relationship between the predictor variables (the X variables). The assumption is that there is no multicolinearity: the X variables are not related or associated to each other.
In some sense the first assumption is obvious if not trivial — of course a “line” needs to fit the data so why not plow ahead with the OLS regression method, which has desirable statistical properties and let the estimation of slopes, intercept and fit statistics guide us? One of the really good things about statistics is that you can readily test your intuition about a particular method using data simulated to meet, or not to meet, assumptions.
What about assumptions and BLUE? Interestingly, OLS coefficient estimates remain unbiased even if the errors are not normal, as long as other assumptions (like a mean of zero, no correlation, and constant variance) hold. However, the OLS estimators are no longer the “best” linear unbiased estimators (BLUE) because the efficiency property is lost. As we have discussed before, the main consequence is the effects on statistical inference. Without normality, standard errors, t-statistics, confidence intervals, and p-values will be unreliable.
Note 5: The efficiency property means the estimator has the smallest variance among all linear, unbiased estimators. And “unbiased,” again, means the estimator’s expected value is equal to the true parameter value.
Coming up with datasets like these can be tricky for beginners. Thankfully, others have stepped in and provide tools useful for data simulations which greatly facilitate the kinds of testing of assumptions — and more importantly, how assumptions influence our conclusions — statisticians greatly encourage us all to do (see Chatterjee and Firat 2007).
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- Predict new values for number of matings for male birds of 20g and 60g.
- Anscombe’s quartet (Anscombe 1973) is a famous example of this approach and the fictitious data can be used to illustrate the fallacy of relying solely on fit statistics and coefficient estimates.
Here are the data (modified from Anscombe 1973, p. 19) — I leave it to you to discover the message by using linear regression on Anscombe’s data set. Hint: play naïve and generate the appropriate descriptive statistics, make scatterplots for each X, Y set, then run regression statistics, first on each of the X, Y pairs (there were four sets of X, Y pairs).
Anscombe’s quartet
| X | Y1 | Y2 | Y3 | Y4 |
|---|---|---|---|---|
| 10 | 8.04 | 9.14 | 7.46 | 6.58 |
| 8 | 6.95 | 8.14 | 6.77 | 5.76 |
| 13 | 7.58 | 8.74 | 12.74 | 7.71 |
| 9 | 8.81 | 8.77 | 7.11 | 8.84 |
| 11 | 8.33 | 9.26 | 7.81 | 8.47 |
| 14 | 9.96 | 8.10 | 8.84 | 7.04 |
| 6 | 7.24 | 6.13 | 6.08 | 5.25 |
| 4 | 4.26 | 3.10 | 5.39 | 12.50 |
| 12 | 10.84 | 9.13 | 8.15 | 5.56 |
| 7 | 4.82 | 7.26 | 6.42 | 7.91 |
| 5 | 5.68 | 4.74 | 5.73 | 6.89 |
| Mean (±SD) | 7.50 (2.032) | 7.50 (2.032) | 7.50 (2.032) | 7.50 (2.032) |
Quiz Chapter 17.1
Ordinary Least Squares
Chapter 17 contents
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)
16.2 – Causation and Partial correlation
Introduction
Science driven by statistical inference and model building is largely motivated by the the drive to identify pathways of cause and effect linking events and phenomena observed all around us. (We first defined cause and effect in Chapter 2.4) The history of philosophy, from the works of Ancient Greece, China, Middle East and so on is rich in the language of cause and effect. From these traditions we have a number of ways to think of cause and effect, but for us it will be enough to review the logical distinction among three kinds of cause-effect associations:
- Necessary cause
- Sufficient cause
- Contributory cause
Here’s how the logic works. If A is a necessary cause of B, then the mere fact that B is present implies that A must also be present. However, that the presence of A does not imply that B will occur. If A is a sufficient cause of B, then the presence of A necessarily implies the presence of B. However, another cause C may alternatively cause B. Enter the contributory or related cause: A cause may be contributory if the presumed cause A (1) occurs before the effect B, and (2) changing A also changes B. A contributory cause does not need to be necessary nor must it be sufficient; contributory causes play a role in cause and effect.
Thus, following this long tradition of thinking about causality we have the mantra, “Correlation does not imply causation.” The exact phrase was written as early as emphasized by Karl Pearson who invented the statistic back in the late 1800s. This well-worn slogan deserves to be on T-shirts and bumper stickers*, and perhaps to be viewed as the single most important concept you can take from a course in philosophy/statistics. But in practice, we will always be tempted to stray from this guidance. The developments in genome-wide-association studies, or GWAS, are designed to look for correlations, as evidenced by statistical linkage analysis, between variation at one DNA base pair and presence/absence of disease or condition in humans and animal models. These are costly studies to do and in the end, the results are just that, evidence of associations (correlations), not proof of genetic cause and effect. We are less likely to be swayed by a correlation that is weak, but what about correlations that are large, even close to one? Is not the implication of high, statistically significant correlation evidence of causation? No, necessary, but not sufficient.
Note 1. A helpful review on causation in epidemiology is available from Parascandola and Weed (2001); see also Kleinberg and Hripcsak (2011). For more on “correlation does not imply causation”, try the Wikipedia entry. Obviously, researchers who engage in genome wide association studies are aware of these issues: see for example discussion by Hu et al (2018) on causal inference and GWAS.
Causal inference (Pearl 2009; Pearl and Mackenzie 2018), in brief, employs a model to explain the association between dependent and multiple, likely interrelated candidate causal variable, which is then subject to testing — is the model stable when the predictor variables are manipulated, when additional connections are considered (eg, predictor variable 1 covaries with one or more other predictor variables in the model). Wright’s path analysis, now included as one approach to Structural Equation Modeling, is used to relate equations (models) of variation in observed variables attributed to direct and indirect effects from predictor variables.
* And yes, a quick Google search reveals lots of bumper stickers and T-shirts available with the causation  sentiment.
Spurious correlations
Correlation estimates should be viewed as hypotheses in the scientific sense of the meaning of hypotheses for putative cause-effect pairings. To drive the point home, explore the web site “Spurious Correlations” at https://www.tylervigen.com/spurious-correlations , which allows you to generate X-Y plots and estimate correlations among many different variables. Some of my favorite correlations from “Spurious Correlations” include (Table 1):
Table 1. Spurious correlations, https://www.tylervigen.com/spurious-correlations
| First variable | Second variable | Correlation |
| Divorce rate in Maine, USA | Per capita USA consumption of margarine | +0.993 |
| Honey producing bee colonies USA | Juvenile arrests for marijuana possession | -0.933 |
| Per capita USA consumption of mozzarella cheese | Civil engineering PhD awarded USA | +0.959 |
| Total number of ABA lawyers USA | Cost of red delicious apples | +0.879 |
These are some pretty strong correlations (cf. effect size discussion, Ch11.4 and 16.1), about as close to +1 as you can get. But really, do you think the amount of cheese that is consumed in the USA has anything to do with the number of PhD degrees awarded in engineering or that apple prices are largely set by the number of lawyers in the USA? Cause and effect implies there must also be some plausible mechanism, not just a strong correlation.
But that does NOT ALSO mean that a high correlation is meaningless. The primary reason a correlation cannot tell about causation is because of the problem (potentially) of an UNMEASURED variable (a confounding variable) being the real driving force (Fig 1).
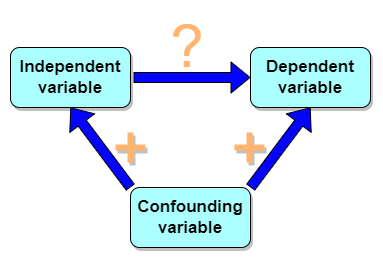
Figure 1. Unmeasured confounding variables influence association between independent and dependent variables, the characters or traits we are interested in.
Here’s a plot of running times for the best, fastest men and women runners for the 100-meter sprint. Running times over 100 meters of top athletes since the 1920s. The data are collated for you and presented at end of this page (scroll or click here).
Here’s a scatterplot (Fig 2).
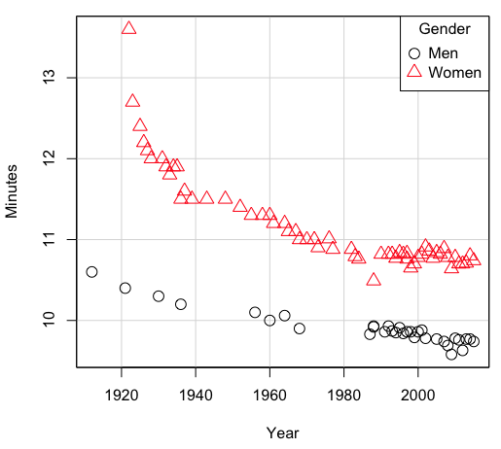
Figure 2. Running times over 100 meters of top athletes since the 1920s.
There’s clearly a negative correlation between years and running times. Is the rate of improvement in running times the same for men and women? Is the improvement linear? What, if any, are the possible confounding variables? Height? weight? Biomechanical differences? Society? Training? Genetics? … Performance enhancing drugs…?
If we measure potential confounding factors, we may be able to determine the strength of correlation between two variables that share variation with a third variable.
The partial correlation
There are several ways to work this problem. The partial correlation is a useful way to handle this problem, i.e., where a measured third variable is positively correlated with the two variable you are interested in.
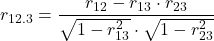
Without formal mathematical proof presented, r12.3 is the correlation between variables 1 and 2 INDEPENDENT of any covariation with variable 3.
For our running data set, we have the correlation between women’s time for 100m over 9 decades, (r13 = -0.876), between men’s time for 100m over 9 decades (r23 = -0.952), and finally, the correlation we’re interested in, whether men’s and women’s times are correlated (r12 = +0.71). When we use the partial correlation, however, I get r12.3 = -0.819… much less than 0 and significantly different from zero. In other words, men’s and women’s times are not positively correlated independent of the correlation both share with the passage of time (decades)! The interpretation is that men are getting faster at a rate faster than women.
In conclusion, keep your head about you when you are doing analyses. You may not have the skills or knowledge to handle some problems (partial correlation), but you can think simply — why are two variables correlated? One causes the other to increase (or decrease) OR the two are both correlated with another variable.
Testing the partial correlation
Like our simple correlation, the partial correlation may be tested by a t-test, although modified to account for the number of pairwise correlations (Wetzels and Wagenmakers 2012). The equation for the t test statistic is now
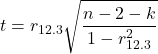
with k equal to the number of pairwise correlations and n – 2 – k degrees of freedom.
Examples
Lead exposure and low birth weigh. The data set is numbers of low birth weight births (< 2,500 g regardless of gestational age) and numbers of children with high levels of lead (10 or more micrograms of lead in a deciliter of blood) measured from their blood. Data used for 42 cities and towns of Rhode Island, United States of America (data at end of this page, scroll or click here to access the data).
A scatterplot of number of children with high lead is shown below (Fig 3).
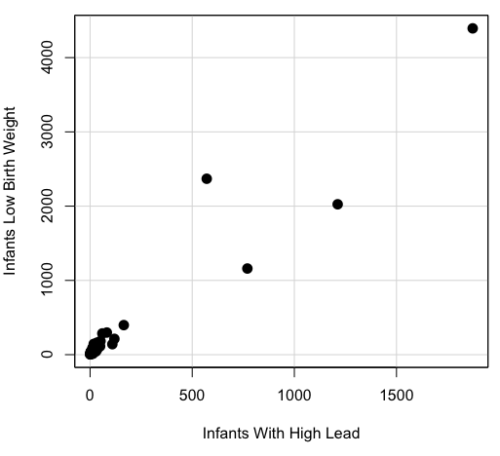
Figure 3. Scatterplot birth weight by lead exposure.
The product moment correlation was r = 0.961, t = 21.862, df = 40, p < 2.2e-16. So, at first blush looking at the scatterplot and the correlation coefficient, we conclude that there is a significant relationship between lead and low birth weight, right?
However, by the description of the data you should recall that counts were reported, not rates (eg, per 100,000 people). Clearly, population size varies among the cities and towns of Rhode Island. West Greenwich had 5085 people whereas Providence had 173,618. We should suspect that there is also a positive correlation between number of children born with low birth weight and numbers of children with high levels of lead. Indeed there are.
Correlation between Low Birth Weight and Population, r = 0.982
Correlation between High Lead levels and Population, r = 0.891
The question becomes, after removing the covariation with population size is there a linear association between high lead and low birth weight? One option is to calculate the partial correlation. To get partial correlations in Rcmdr, select
Statistics → Summaries → Correlation matrix
then select “partial” and select all three variables (select + Ctrl key; (Windows or macOS) (Fig 4).
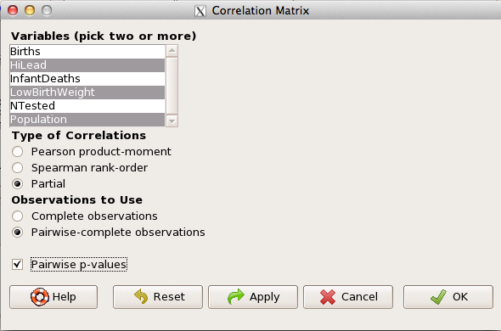
Figure 4. Screenshot Rcmdr partial correlation menu
Results are shown below.
partial.cor(leadBirthWeight[,c("HiLead","LowBirthWeight","Population")], tests=TRUE, use="complete")

Partial correlations:
                 HiLead LowBirthWeight Population
HiLead          0.00000        0.99181   -0.97804
LowBirthWeight  0.99181        0.00000    0.99616
Population     -0.97804        0.99616    0.00000
Thus, after removing the covariation we conclude there is indeed a strong correlation between lead and low birth weights.
Note 2. Some verbiage about correlation tables (matrices). The matrix is symmetric and the information is repeated. I highlighted the diagonal in green. The upper triangle (red) is identical to the lower triangle (blue). When you publish such matrices, don’t publish both the upper and lower triangles; it’s also not necessary to publish the on-diagonal numbers, which are generally not of interest. Thus, the publishable matrix would be
Partial correlations:
                LowBirthWeight Population
HiLead                 0.99181   -0.97804
LowBirthWeight                    0.99616
Another example
Do Democrats prefer cats? The question I was interested in, Do liberals really prefer cats, was inspired by a Time magazine 18 February 2014 article. I collated data on a separate but related question: Do states with more registered Democrats have more cat owners? The data set was compiled from three sources: 2010 USA Census, a 2011 Gallup poll about religious preferences, and from a data book on survey results of USA pet owners (data at end of this page, scroll or click here to access the data).
Note 3: This type of data set involves questions about groups, not individuals. We have access to aggregate statistics for groups (city, county, state, region), but not individuals. Thus, our conclusions are about groups and cannot be used to predict individual behavior, eg, knowing a person votes Green Party does not mean they necessarily share their home with a cat). See ecological fallacy.
This data set also demonstrates use of transformations of the data to improve fit of the data to statistical assumptions (normality, homoscedacity).
The variables, and their definitions, were:
ASDEMS = DEMOCRATS. Democrat advantage: the difference in registered Democrats compared to registered Republicans as a percentage; to improve the distribution qualities the arcsine transform was applied..
ASRELIG = RELIGION. Percent Religious from a Gallup poll who reported that Religion was “Very Important” to them. Also arcsine-transformed to improve normality and homoescedasticity (there you go, throwing $3 words around 🤠 ).
LGCAT = Number of pet cats, log10-transformed, estimated for USA states by survey, except Alaska and Hawaiʻi (not included in the survey by the American Veterinary Association).
LGDOG = Estimated number of pet dogs, log10-transformed for states, except Alaska and Hawaiʻi (not included in the survey by the American Veterinary Association).
LGIPC = Per capita income, log10-transformed.
LGPOP = Population size of each state, log10 transformed.
As always, begin with data exploration. All of the variables were right-skewed, so I applied data transformation functions as appropriate: log10 for the quantitative data and arc sine transform for the frequency variables. Because Democrat Advantage and Percent Religious variables were in percentages, the values were first divided by 100 to make frequencies, then the R function asin() was applied. All analyses were conducted on the transformed data, therefore conclusions apply to the transformed data.
Note 4: As we’ve discussed before, to relate the results to the original scales, back transformations would need to be run on any predictions. Back transformation for log10 would be power of ten; for the arcsine-transform the inverse of the arcsine would be used.
A scatter plot matrix (KMggplo2) plus histograms of the variables along the diagonals shows the results of the transforms and hints at the associations among the variables. A graphic like this one is called a trellis plot; a layout of smaller plots in a grid with the same (preferred) or at least similar axes. Trellis plots (Fig 5) are useful for finding the structure and patterns in complex data. Scanning across a row shows relationships between one variable with all of the others. For example, the first row Y-axis is for the ASDEMS variable; from left to right along the row we have, after the histogram, what look to be weak associations between ASDEMS and ASRELIG, LGCAT, LGDOG, and LGDOG.
Figure 5. Trellis plot, correlations among variables.
A matrix of partial correlations was produced from the Rcmdr correlation call. Thus, to pick just one partial correlation, the association between DEMOCRATS and RELIGION (reported as “very important”) is negative (r = -0.45) and from the second matrix we retrieve the approximate P-value, unadjusted for the multiple comparisons problem, of p = 0.0024. We quickly move past this matrix to the adjusted P-values and confirm that this particular correlation is statistically significant even after correcting for multiple comparisons. Thus, there is a moderately strong negative correlation between those who reported that religion was very important to them and the difference between registered Democrats and Republicans in the 48 states. Because it is a partial correlation, we can conclude that this correlation is independent of all of the other included variables.
And what about our original question: Do Democrats prefer cats over dogs? The partial correlation after adjusting for all of the other correlated variables is small (r = 0.05) and not statistically different from zero (P-value greater than 5%).
Are there any interesting associations involving pet ownership in this data set? See if you can find it (hint: the correlation you are looking for is also in red).
Partial correlations:
         ASDEMS  ASRELIG LGCAT   LGDOG   LGIPC   LGPOP
ASDEMS   0.0000 -0.4460  0.0487  0.0605  0.1231 -0.0044
ASRELIG -0.4460  0.0000 -0.2291 -0.0132 -0.4685  0.2659
LGCAT    0.0487 -0.2291  0.0000  0.2225 -0.1451  0.6348
LGDOG    0.0605 -0.0132  0.2225  0.0000 -0.6299  0.5953
LGIPC    0.1231 -0.4685 -0.1451 -0.6299  0.0000  0.6270
LGPOP   -0.0044  0.2659  0.6348  0.5953  0.6270  0.0000
Raw P-values, Pairwise two-sided p-values:
         ASDEMS ASRELIG  LGCAT   LGDOG   LGIPC   LGPOP
ASDEMS           0.0024  0.7534  0.6965  0.4259  0.9772
ASRELIG  0.0024          0.1347  0.9325  0.0013  0.0810
LGCAT    0.7534  0.1347          0.1465  0.3473  <.0001
LGDOG    0.6965  0.9325  0.1465          <.0001  <.0001
LGIPC    0.4259  0.0013  0.3473  <.0001          <.0001
LGPOP    0.9772  0.0810  <.0001  <.0001  <.0001
Adjusted P-values, Holm’s method (Benjamini and Hochberg 1995)
         ASDEMS ASRELIG  LGCAT   LGDOG   LGIPC   LGPOP
ASDEMS           0.0241  1.0000  1.0000  1.0000  1.0000
ASRELIG  0.0241          1.0000  1.0000  0.0147  0.7293
LGCAT    1.0000  1.0000          1.0000  1.0000  <.0001
LGDOG    1.0000  1.0000  1.0000          <.0001  0.0002
LGIPC    1.0000  0.0147  1.0000  <.0001          <.0001
LGPOP    1.0000  0.7293  <.0001  0.0002  <.0001
A graph (Fig 6) to summarize the partial correlations: green lines indicate positive correlation, red lines show negative correlations; Strength of association indicated by the line thickness, with thicker lines corresponding to greater correlation.
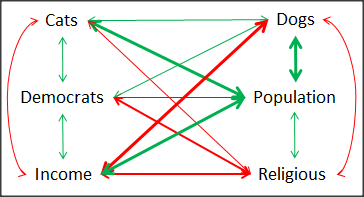
Figure 6. Causal paths among variables.
As you can see, partial correlation analysis is good for a few variables, but as the numbers increase it is difficult to make heads or tails out of the analysis. Better methods for working with these highly correlated data in what we call multivariate data analysis, for example Structural Equation Modeling or Path Analysis.
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- Spurious correlations can be challenging to recognize, and, sometimes, they become part of a challenge to medicine to explain away. A classic spurious correlation is the correlation between rates of MMR vaccination and autism prevalence. Here’s a table of numbers for you
| Year | Herb Supplement Revenue, millions $ | Fertility rate per 1000 births, women age 35 and older+ | MMR per 100K children age 0 -5 | UFC revenue, millions $ | Autism Prevalence per 1000 |
|---|---|---|---|---|---|
| 2000 | 4225 | 47.7 | 179 | 6.7 | |
| 2001 | 4361 | 48.6 | 183 | 4.5 | |
| 2002 | 4275 | 49.9 | 190 | 8.7 | 6.6 |
| 2003 | 4146 | 52.6 | 196 | 7.5 | |
| 2004 | 4288 | 54.5 | 199 | 14.3 | 8 |
| 2005 | 4378 | 55.5 | 197 | 48.3 | |
| 2006 | 4558 | 56.9 | 198 | 180 | 9 |
| 2007 | 4756 | 57.6 | 204 | 226 | |
| 2008 | 4800 | 56.7 | 202 | 275 | 11.3 |
| 2009 | 5037 | 56.1 | 201 | 336 | |
| 2010 | 5049 | 56.1 | 209 | 441 | 14.4 |
| 2011 | 5302 | 57.5 | 212 | 437 | |
| 2012 | 5593 | 58.7 | 216 | 446 | 14.5 |
| 2013 | 6033 | 59.7 | 220 | 516 | |
| 2014 | 6441 | 61.6 | 224 | 450 | 16.8 |
| 2015 | 6922 | 62.8 | 222 | 609 | |
| 2016 | 7452 | 64.1 | 219 | 666 | 18.5 |
| 2017 | 8085 | 63.9 | 213 | 735 | |
| 2018 | 65.3 | 220 | 800 | 25 |
- Make scatterplots of autism prevalence vs
- Herb supplement revenue
- Fertility rate
- MMR vaccination
- UFC revenue
- Calculate and test correlations between autism prevalence vs
- Herb supplement revenue
- Fertility rate
- MMR vaccination
- UFC revenue
- Interpret the correlations — is there any clear case for autism vs MMR?
- What additional information is missing from Table 2? Add that missing variable and calculate partial correlations for autism prevalence vs
- Herb supplement revenue
- Fertility rate
- MMR vaccination
- UFC revenue
- Do a little research: What are some reasons for increase in autism prevalence? What is the consensus view about MMR vaccine and risk of autism?
Quiz Chapter 16.2
Causation and Partial correlation
Data sets
Data used in this page, 100 meter running times since 1900.
| Year | Men | Women |
|---|---|---|
| 1912 | 10.6 | |
| 1913 | ||
| 1914 | ||
| 1915 | ||
| 1916 | ||
| 1917 | ||
| 1918 | ||
| 1919 | ||
| 1920 | ||
| 1921 | 10.4 | |
| 1922 | 13.6 | |
| 1923 | 12.7 | |
| 1924 | ||
| 1925 | 12.4 | |
| 1926 | 12.2 | |
| 1927 | 12.1 | |
| 1928 | 12 | |
| 1929 | ||
| 1930 | 10.3 | |
| 1931 | 12 | |
| 1932 | 11.9 | |
| 1933 | 11.8 | |
| 1934 | 11.9 | |
| 1935 | 11.9 | |
| 1936 | 10.2 | 11.5 |
| 1937 | 11.6 | |
| 1938 | ||
| 1939 | 11.5 | |
| 1940 | ||
| 1941 | ||
| 1942 | ||
| 1943 | 11.5 | |
| 1944 | ||
| 1945 | ||
| 1946 | ||
| 1947 | ||
| 1948 | 11.5 | |
| 1949 | ||
| 1950 | ||
| 1951 | ||
| 1952 | 11.4 | |
| 1953 | ||
| 1954 | ||
| 1955 | 11.3 | |
| 1956 | 10.1 | |
| 1957 | ||
| 1958 | 11.3 | |
| 1959 | ||
| 1960 | 10 | 11.3 |
| 1961 | 11.2 | |
| 1962 | ||
| 1963 | ||
| 1964 | 10.06 | 11.2 |
| 1965 | 11.1 | |
| 1966 | ||
| 1967 | 11.1 | |
| 1968 | 9.9 | 11 |
| 1969 | ||
| 1970 | 11 | |
| 1972 | 10.07 | 11 |
| 1973 | 10.15 | 10.9 |
| 1976 | 10.06 | 11.01 |
| 1977 | 9.98 | 10.88 |
| 1978 | 10.07 | 10.94 |
| 1979 | 10.01 | 10.97 |
| 1980 | 10.02 | 10.93 |
| 1981 | 10 | 10.9 |
| 1982 | 10 | 10.88 |
| 1983 | 9.93 | 10.79 |
| 1984 | 9.96 | 10.76 |
| 1987 | 9.83 | 10.86 |
| 1988 | 9.92 | 10.49 |
| 1989 | 9.94 | 10.78 |
| 1990 | 9.96 | 10.82 |
| 1991 | 9.86 | 10.79 |
| 1992 | 9.93 | 10.82 |
| 1993 | 9.87 | 10.82 |
| 1994 | 9.85 | 10.77 |
| 1995 | 9.91 | 10.84 |
| 1996 | 9.84 | 10.82 |
| 1997 | 9.86 | 10.76 |
| 1998 | 9.86 | 10.65 |
| 1999 | 9.79 | 10.7 |
| 2000 | 9.86 | 10.78 |
| 2001 | 9.88 | 10.82 |
| 2002 | 9.78 | 10.91 |
| 2003 | 9.93 | 10.86 |
| 2004 | 9.85 | 10.77 |
| 2005 | 9.77 | 10.84 |
| 2006 | 9.77 | 10.82 |
| 2007 | 9.74 | 10.89 |
| 2008 | 9.69 | 10.78 |
| 2009 | 9.58 | 10.64 |
| 2010 | 9.78 | 10.78 |
| 2011 | 9.76 | 10.7 |
| 2012 | 9.63 | 10.7 |
| 2013 | 9.77 | 10.71 |
| 2014 | 9.77 | 10.8 |
| 2015 | 9.74 | 10.74 |
| 2016 | 9.8 | 10.7 |
| 2017 | 9.82 | 10.71 |
| 2018 | 9.79 | 10.85 |
| 2019 | 9.76 | 10.71 |
| 2020 | 9.86 | 10.85 |
| 2021 | 9.77 | 10.54 |
| 2022 | 9.76 | 10.62 |
| 2023 | 9.83 | 10.65 |
| 2024 | 9.77 | 10.72 |
Data used in this page, birth weight by lead exposure
| CityTown | Core | Population | NTested | HiLead | Births | LowBirthWeight | InfantDeaths |
|---|---|---|---|---|---|---|---|
| Barrington | n | 16819 | 237 | 13 | 785 | 54 | 1 |
| Bristol | n | 22649 | 308 | 24 | 1180 | 77 | 5 |
| Burrillville | n | 15796 | 177 | 29 | 824 | 44 | 8 |
| Central Falls | y | 18928 | 416 | 109 | 1641 | 141 | 11 |
| Charlestown | n | 7859 | 93 | 7 | 408 | 22 | 1 |
| Coventry | n | 33668 | 387 | 20 | 1946 | 111 | 7 |
| Cranston | n | 79269 | 891 | 82 | 4203 | 298 | 20 |
| Cumberland | n | 31840 | 381 | 16 | 1669 | 98 | 8 |
| East Greenwich | n | 12948 | 158 | 3 | 598 | 41 | 3 |
| East Providence | n | 48688 | 583 | 51 | 2688 | 183 | 11 |
| Exeter | n | 6045 | 73 | 2 | 362 | 6 | 1 |
| Foster | n | 4274 | 55 | 1 | 208 | 9 | 0 |
| Glocester | n | 9948 | 80 | 3 | 508 | 32 | 5 |
| Hopkintown | n | 7836 | 82 | 5 | 484 | 34 | 3 |
| Jamestown | n | 5622 | 51 | 14 | 215 | 13 | 0 |
| Johnston | n | 28195 | 333 | 15 | 1582 | 102 | 6 |
| Lincoln | n | 20898 | 238 | 20 | 962 | 52 | 4 |
| Little Compton | n | 3593 | 48 | 3 | 134 | 7 | 0 |
| Middletown | n | 17334 | 204 | 12 | 1147 | 52 | 7 |
| Narragansett | n | 16361 | 173 | 10 | 728 | 42 | 3 |
| Newport | y | 26475 | 356 | 49 | 1713 | 113 | 7 |
| New Shoreham | n | 1010 | 11 | 0 | 69 | 4 | 1 |
| North Kingstown | n | 26326 | 378 | 20 | 1486 | 76 | 7 |
| North Providence | n | 32411 | 311 | 18 | 1679 | 145 | 13 |
| North Smithfield | n | 10618 | 106 | 5 | 472 | 37 | 3 |
| Pawtucket | y | 72958 | 1125 | 165 | 5086 | 398 | 36 |
| Portsmouth | n | 17149 | 206 | 9 | 940 | 41 | 6 |
| Providence | y | 173618 | 3082 | 770 | 13439 | 1160 | 128 |
| Richmond | n | 7222 | 102 | 6 | 480 | 19 | 2 |
| Scituate | n | 10324 | 133 | 6 | 508 | 39 | 2 |
| Smithfield | n | 20613 | 211 | 5 | 865 | 40 | 4 |
| South Kingstown | n | 27921 | 379 | 35 | 1330 | 72 | 10 |
| Tiverton | n | 15260 | 174 | 14 | 516 | 29 | 3 |
| Warren | n | 11360 | 134 | 17 | 604 | 42 | 1 |
| Warwick | n | 85808 | 973 | 60 | 4671 | 286 | 26 |
| Westerly | n | 22966 | 140 | 11 | 1431 | 85 | 7 |
| West Greenwich | n | 5085 | 68 | 1 | 316 | 15 | 0 |
| West Warwick | n | 29581 | 426 | 34 | 2058 | 162 | 17 |
| Woonsoket | y | 43224 | 794 | 119 | 2872 | 213 | 22 |
Data in this page, Do Democrats prefer cats?
Chapter 16 contents
- Introduction
- Product moment correlation
- Causation and Partial correlation
- Data aggregation and correlation
- Spearman and other correlations
- Instrument reliability and validity
- Similarity and Distance
- References and suggested readings
17 – Linear Regression
Introduction
Regression is a toolkit for developing models of cause and effect between one ratio scale data type dependent response variables, and one (simple linear regression) or more or more (multiple linear regression) ratio scale data type independent predictor variables. By convention the dependent variable(s) is denoted by Y, the independent variable(s) represented by X1, X2,  Xn for n independent variables. Like ANOVA, linear regression is simply a special case of the general linear model, first introduced in Chapter 12.7.
Components of a statistical model
Regression statistical methods return model estimates of the intercept and slope coefficients, plus statistics of regression fit (eg, R2, aka “R-squared,” the coefficient of determination).
Chapter 17.1 – 17.9 cover the simple linear model
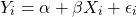
Chapter 18.1 – 18.5 cover the multiple regression linear model
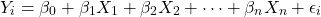
where α or β0 represent the Y-intercept and β or β1, β2, … βn represent the regression slopes.
Regression and correlation test linear hypotheses
We state that the relationship between two variables is linear (the alternative hypothesis) or it is not (the null hypothesis). The difference? Correlation is a test of linear association (are variables correlated, we ask?), imply possible causation, but are not sufficient evidence for causation: we do not imply that one variable causes another to vary, even if the correlation between the two variables is large and positive, for example. Correlations are used in statistics on data sets not collected from explicit experimental designs incorporated to test specific hypotheses of cause and effect.
Linear regression, however, is to cause and effect as correlation is to association. With regression and ANOVA, we are indeed making a case for a particular understanding of the cause of variation in a response variable: modeling cause and effect is the goal. Regression, ANOVA, and other general linear models are designed to permit the statistician to control for the effects of confounding variables provided the causal variables themselves are uncorrelated.
When to use correlation and when to apply linear regression to data set? For two ratio scale variables, one can always apply either approach. Correlation is always appropriate if both variables are measured in the course of the study whereas a regression modeling approach would be implied where one variable was the result of manipulation by the researcher.
Assumptions of linear regression
The key assumption in linear regression is that a straight line indeed is the best fit of the relationship between dependent and independent variables. The additional assumptions of parametric tests (Chapter 13) also hold. In Chapter 18 we conclude with an extension of regression from one to many predictor variables and the special and important topic of correlated predictor variables or multicollinearity.
Build a statistical model, make predictions
In our exploration of linear regression we begin with simple linear regression, also called ordinary least squares regression, starting with one predictor variable. Practical aspects of model diagnostics are presented. Regression may be used to describe or to provide a predictive statistical framework. In Chapter 18 we conclude with an extension of regression from one to many predictor variables. We conclude with a discussion of model selection. Throughout, use of Rcmdr and R have multiple ways to analyze linear regression models are presented; we will continue to emphasize the general linear model approach, but note that use of linear model in Rcmdr provides a number of default features that are conveniently available.
Questions
1. Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
Suggested homework
Homework 11: Simple linear regression.
Quiz
In addition to the quiz on this page, a total of 81 questions among the several subchapters, a mix of true or false and multiple choice question format.
Quiz Chapter 17
Linear Regression
References
Linear regression is a huge topic; references I include are among my favorite on the subject, but are only a small and incomplete sampling. For simplicity, I merged references for Chapter 17 and Chapter 18 into one page at References and suggested readings (Ch17 & 18)
Chapter 17 contains
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)
14 – ANOVA designs, multiple factors
Introduction
In our previous discussions about t-tests and ANOVA we focused on procedures with one dependent (response) variable and a single independent (predictor) factor variable that may cause variation in the response variable. In this chapter we extend our discussions about the general linear model by reviewing
- One-way ANOVA and provided a few examples of the one-way design.
- To review and set the stage for adding a second independent variable to the model.
Additional one-way ANOVA examples
1. In a plants, we may have a response variable like height and one factor variable (location: sun vs. shade) thought to influence plant height (eg, Aphalo et al 1999).
2. Pulmonary macrophage phagocytosis behavior (response variable) after exposure of toads to clean air or ozone (factor with 2 levels) (Dohm et al. 2005).
3. Monitor weight change on subjects after 6 weeks eating different diet (DASH, control) (Elmer et al. 2006).
All three of the examples are based on the same statistical model which may be written as:
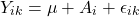
where μ is the grand mean, Y is the response variable and A is the independent variable, or factor, with k = 1, 2, …. K levels, groups, or treatments. The total number of experimental units (eg, subjects) is given by i = 1, 2, 3, … n. Note that in the first and third examples, because there were only two groups (example 1: k = location, shade; example 3: k = DASH, control) note that this problem could have been evaluated as an independent sample t-test. For the second example, there were three groups so k = clean air, first ozone level, second ozone level).
Two-way ANOVA with replication
As useful as the one-way ANOVA design can be, it is a “one-factor-at-a-time” approach (Radzilani et al 2025), experiments are typically more complicated than a single t-test or one-way ANOVA design can handle; rarely would we conduct an experiment that reflects only one source of variation. Looking only at variability for one factor at a time while while keeping all other factors constant ignores interactions between factors, resulting in potentially serious model bias (eg, discussed in Vatcheva et al 2015).
For example, while diet has a profound effect on weight, clearly, activity levels are also important. At a minimum, when considering a weight loss program, we would want to control or monitor activity of the subjects. This is a two-factor model, and the main effects, the two factors, were diet (factor A) and activity, (factor B). Both are expected to affect weight loss, and, perhaps, they may do so in complicated ways — an interaction (eg, on DASH diet, weight loss is accelerated when subjects exercise regularly).
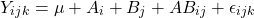
The subject of this chapter is the introduction to two-way ANOVA designs. In fact, to many, ANOVA design is practically synonymous to a statistician when they think about experimental design (Lindman 1992; Quinn and Keough 2002). As noted by Quinn and Keough (2002) in the preface to their book, “… many biological hypotheses, even deceptively simple ones, are matched by complex statistical models” (p. xv). Once you start adding factor variables there becomes a number of ways in which the groups and experimental units can be distributed, and thus impact the inferences one can make from the ANOVA results. The first statistical model we introduced was the one-way ANOVA. Next, we begin the two-way ANOVA with the crossed, balanced, fully replicated design. Along the way we introduce model symbols to help us communicate the design structure and implications of the statistical models.
Quizzes in this chapter
A total of 71 questions among the several subchapters, a mix of true or false and multiple choice question format.
Chapter 14 contents
12.7 – Many tests one model
Introduction
In our introduction to parametric tests we so far have covered one and two sample t-tests and now the multiple sample or one-way analysis of variance (ANOVA). In subsequent sections we will cover additional tests, each with their own name. It is time to let you in on a little secret. All of these tests, t-tests, ANOVA, and linear and multiple regression we will work on later in the book belong to one family of statistical models. That model is called the general Linear Model (LM), not to be confused with the Generalized Linear Model (GLM) (Burton et al 1998; Guisan et al 2002). This greatly simplifies our approach to learning how to implement statistical tests in R (or other statistical programs) — you only need to learn one approach: the general Linear Model (LM) function lm().
Brief overview of linear models
With the inventions of correlation, linear regression, t-tests, and analysis of variance in the period between 1890 and 1920, subsequent work led to the realization that these tests (and many others!) were special cases of a general model, the general linear model, or LM. The LM itself is a special case of the generalized linear model, or GLM; among the differences between LM and GLM, in LM, the dependent variable is ratio scale and errors in the response (dependent) variable(s) are assumed to come from a Gaussian (normal) distribution. In contrast, for GLM, the response variable may be categorical or continuous, and error distributions other than normal (Gaussian), may be applied. The GLM user must specify both the error distribution family (eg, Gaussian) and the link function, which specifies the relationship among the response and predictor variables. While we will use the GLM functions when we attempt to model growth functions and calculate EC50 in dose-response problems, we will not cover GLM this semester.
The general Linear Model, LM
In matrix form, the LM can be written as

where  is a matrix of response variables predicted by independent variables contained in matrix
 and weighted by linear coefficients in the vector b. Basically, all of the predictor variables are combined to produce a single linear predictor
 . By adding an error component we have the complete linear model.

In the linear model, the error distribution is assumed to be normally distributed, or “Gaussian.”
R code
The bad news is that LM in R (and in any statistical package, actually) is a fairly involved set of commands; the good news is that once you understand how to use this command, and can work with the Options, you will be able to conduct virtually all of the tests we will use this semester, from two-sample t-tests to multiple linear regression. In the end, all you need is the one Rcmdr command to perform all of these tests.
We begin with a data set, ohia.ch12. Scroll down this page or click here to get the R code.
I found a nice report on a common garden experiment with o`hia (Corn and Hiesey 1973). O`hia (Metrosideros polymorpha) is an endemic, but wide-spread tree in the Hawaiian islands (Fig 1). O`hia exhibits pronounced intraspecific variation: individuals differ from each other. O`hia grows over wide range of environments, from low elevations along the ocean right up the sides of the volcanoes, and takes on many different growth forms, from shrubs to trees. Substantial areas of o`hia trees on the Big Island are dying, attributed to two exotic fungal species of the genus Ceratocystis (Asner et al., 2018).
Figure 1. O’hia, Metrosideros polymorpha. Public domain image from Wikipedia.
The Biology. Individuals from distinct populations may differ because the populations differ genetically, or because the environments differ, or, and this is more realistic, both. Phenotypic plasticity is the ability of one genotype to produce more than one phenotype when exposed to different environments. Environmental differences are inevitable when populations are from different geographic areas. Thus, in population comparisons, genetic and environmental differences are confounded. A common garden experiment is a crucial genetic experiment to separate variation in phenotypes, P, among populations into causal genetic or environmental components.
If you recall from your genetics course, 
where G stands for genetic (alleles) differences among individuals and E stands for environmental differences among individuals. In brief, the common garden experiment begins with individuals from the different populations are brought to the same location to control environmental differences. If the individuals sampled from the populations continue to differ despite the common environment, then the original differences between the populations must have a genetic basis, although the actual genetic scenario may be complicated (the short answer is that if “genotype by environment interaction exists, then results from a common garden experiment cannot be generalized back to the natural populations/locations — this will make more sense when we talk about two-way ANOVA). For more about common garden experiments, see de Villemereuil et al (2016). Nuismer and Gandon (2008) discuss statistical aspects of the common garden approach to studying local adaptation of populations and the more powerful “reciprocal translocation” experimental design.
Managing data for linear models
First, your data must be stacked in the worksheet. That means one column is for group labels (independent variable), the other column is for the response (dependent) variable.
If you have not already downloaded the data set, ohia.ch12, do so now. Scroll down this page or click here to get the R code.
Confirm that the worksheet is stacked. If it is not, then you would rearrange your data set using Rcmdr: Data → Active data set → Stack variables in data set…
The data set contains one factor, “Site” with three levels (M-1, 2, 3). M stands for Maui, and collection sites were noted in Figure 2 of Corn and Hiesey (1973). Once the dataset is in Rcmdr, click on View to see the data (Fig 2). There are two response variables, Height (shown in red below) and Width (shown in blue below).
Figure 2. The o`hia dataset as viewed in R Commander.
The data are from Table 5 of Corn and Hiesey 1973. (I simulated data based on their mean/SD reported in Table 5). This was a very cool experiment: they collected o`hia seeds from three elevations on Maui, then grew the seeds in a common garden in Honolulu. Thus, the researchers controlled the environment; what varied, then were the genotypes.
As always, you should look at the data. Box plots are good to compare central tendency (Fig 3).
Figure 3. Box plots of growth responses of o`hia seedlings collected from three Maui sites, M-1 (elevation 750 ft), M-2 (elevation 1100 ft), and M-3 (elevation 6600 ft). Data adapted from Table 5 of Corn and Hiersey 1973.
R code to make Figure 4 plots
par(mfrow=c(1,2))
Boxplot(Height ~ Site, data = ohia, id = list(method = "y"))
Boxplot(Width ~ Site, data = ohia, id = list(method = "y"))
This dataset would typically be described as a one-way ANOVA problem. There was one treatment variable (population source) with three levels (M-1, M-2, M-3). From Rcmdr we select the one-way ANOVA: Statistics → Means → One-way ANOVA… and after selecting the Groups (from the Site variable) and the Response variable (eg, Height), we have
AnovaModel.1 <- aov(Height ~ Site, data = ohia.ch12)
summary(AnovaModel.1)
           Df Sum Sq   Mean Sq  F value          Pr(>F)
Site        2   4070    2034.8    22.63 0.000000131 ***
Residuals  47   4227      89.9
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Let us proceed to test the null hypothesis (what was it???) using instead the lm() function. Four steps in all.
Step 1. Rcmdr: Statistics → Fit models → Linear model … (Fig 4).
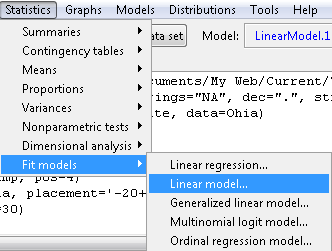
Figure 4. R Commander, select to fit a Linear model.
Step 2. The pop up menu below (Fig 5) follows.
First, What is our response (dependent) variable? What is our predictor (independent) variable? We then input our model. In this case, with only the one predictor variable, Sites, our model formula is simple to enter (Fig 5): Height ~ Site.
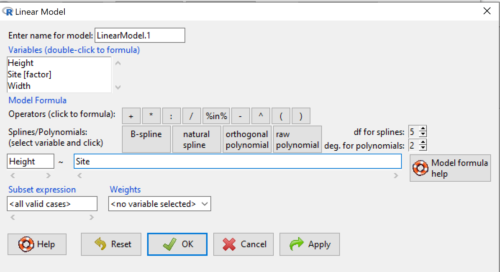
Figure 5. Input linear model formula, Height ~ Site.
Step 3. Click OK to carry out the command.
Here is the R output and the statistical results from the application of the linear model.
LinearModel.1 <- lm(Height ~ Site, data=ohia.ch12)
summary(LinearModel.1)

Call:
lm(formula = Height ~ Site, data = ohia.ch12)

Residuals:
    Min     1Q   Median     3Q     Max
-18.808 -4.761   -1.755  4.758  29.257

Coefficients:
             Estimate  Std. Error  t value      Pr(>|t|)
(Intercept)    15.314       2.121    7.222 0.00000000377 ***
Site[T.M-2]    19.261       2.999    6.423 0.00000006153 ***
Site[T.M-3]     2.924       3.673    0.796          0.43
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Residual standard error: 9.483 on 47 degrees of freedom
Multiple R-squared:  0.4905,	Adjusted R-squared:  0.4688
F-statistic: 22.63 on 2 and 47 DF,  p-value: 0.0000001311
End R output
The linear model has produced a series of estimates of coefficients for the linear model, statistical tests of the significance of each component of the model, and the coefficient of determination, R2, which is a descriptive statistic of how well model fits the data. Instead of our single factor variable for Source Population like in ANOVA we have a series of what are called dummy variables or contrasts between the populations. Thus, there is a coefficient for the difference between M-1 and M-2. “Site[T.M-2]” in the output, between M-1 and M-3, and between M-2 and M-3.
Note 1: Brief description of linear model output; these will be discussed fuller in Chapter 17 and Chapter 18. The residual standard error is a measure of how well a model fits the data. The Adjusted R-squared is calculated by dividing the residual mean square error by the total mean square error. The result is then subtracted from 1.
It also produced our first statistic that assesses how well the model fits the data called the coefficient of determination, R2. An of of 1.0 would indicate that all variation in the data set can be explained by the predictor variable(s) in the model with no residual error remaining. Our value of 49% indicates that nearly 50% of the variation in height of the seedlings grown under common environments are due to the source population (= genetics).
Step 4. But we are not quite there — we want the traditional ANOVA results (recall the ANOVA table).
To get the ANOVA Table we have to ask Rcmdr (and therefore R) to give us this. Select
Rcmdr: Models → Hypothesis tests → ANOVA table … (Fig 6).
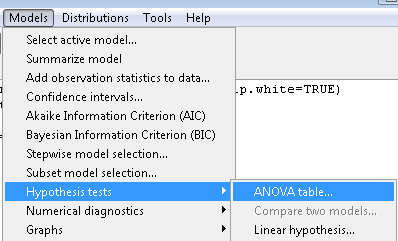
Figure 6. To retrieve an ANOVA table, select Models, Hypothesis tests, then ANOVA table…
Here’s the type of tests for the ANOVA table, select the default (Fig 7).
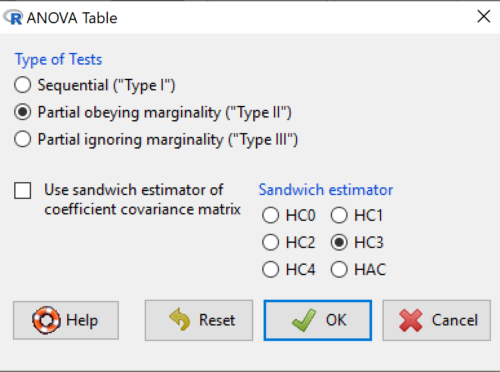
Figure 7. Options for types of tests.
Now, in the future when we work with more complicated experimental designs, we will also need to tell R how to conduct the test. For now, we will accept the default Type II type of test and ignore sandwich estimators. You should confirm that for a one-way ANOVA, Type I and Type II choices give you the same results.
The reason they do is because there is only one factor — when there are more than one factors, and if one or both of the factors are random effects, then Type I, II, and III will give you different answers. We will discuss this more as needed, but see the note below about default choices.
Note 2: Marginal or partial effects are slopes (or first derivatives): they quantify the change in one variable given change in one or more independent variables. Type I tests are sequential: sums of squares are calculated in the order the predictor variables are entered into the model. Type II tests the sums of squares are calculated after adjusting for some of the variables in the model. Type III, every sum of square calculation is adjusted for all other variables in the model. Sandwich estimator refers to algorithms for calculating the structure of errors or residuals remaining after the predictor variables are fitted to the data. The assumption for ordinary least square estimation (See Chapter 17) is that errors across the predictors are equal, ie, equal variances assumption. HC refers to “heteroscedasticity consistent” (Hayes and Chai 2007), which infers fitting of a model does not assume equal error variance across all observations.
By default, Rcmdr makes Type II. In most of the situations we will find ourselves this semester, this is the correct choice.
Below is the output from the ANOVA table request. Confirm that the information is identical to the output from the call to aov() function.
Anova(LinearModel.1, type = "II")
Anova Table (Type II tests)
Response: Height
          Sum Sq  Df   F value        Pr(>F)
Site      4069.7   2    22.626  0.0000001311 ***
Residuals 4226.9  47
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
And the other stuff we got from the linear model command? Ignore for now but make note that this is a hint that regression and ANOVA are special cases of the same model, the linear model.
We do have some more work to do with ANOVA, but this is a good start.
Why use the linear model approach?
Chief among the reasons to use the lm() approach is to emphasize that a model approach is in use. One purpose of developing a model is to provide a formula to predict new values. Prediction from linear models is more fully developed in Chapter 17 and Chapter 18, but for now, we introduce the predict() function with our O`hia example.
myModel <- predict(LinearModel.1, interval = "confidence")
head(myModel, 3)    #print out first 3 rows
#Add the output to the data set
ohiaPred <- data.frame(ohia,myModel)
with(ohiaPred, tapply(fit, list(Site), mean, na.rm = TRUE))   #print out predicted values for the three sites
Output from R
myModel <- predict(LinearModel.1, interval = "confidence")
head(myModel, 3)
       fit      lwr      upr
1 15.31374 11.04775 19.57974
2 15.31374 11.04775 19.57974
3 15.31374 11.04775 19.57974
with(myModel, tapply(fit, list(Site), mean, na.rm = TRUE))
     M-1      M-2      M-3
15.31374 34.57474 18.23796
Questions
1. Revisit ANOVA problems in homework and questions from early parts of this chapter and apply lm() followed by Hypothesis testing (Rcmdr: Models → Hypothesis tests → ANOVA table) approach instead of one-way ANOVA command. Compare results using lm() to results from One-way ANOVA and other ANOVA problems.
Quiz Chapter 12.7
Many tests one model
Data set and R code used in this page
Corn and Hiesey (1973)
| Site | Height | Width |
|---|---|---|
| M-1 | 12.5567 | 19.1264 |
| M-1 | 13.2019 | 13.1547 |
| M-1 | 8.0699 | 16.032 |
| M-1 | 6.0952 | 22.8586 |
| M-1 | 11.3879 | 11.0105 |
| M-1 | 12.2242 | 21.8102 |
| M-1 | 16.0147 | 11.0488 |
| M-1 | 19.7403 | 25.9756 |
| M-1 | 36.4824 | 25.2867 |
| M-1 | 13.1233 | 20.0487 |
| M-1 | 21.7725 | 24.8511 |
| M-1 | 14.2013 | 43.7679 |
| M-1 | 37.7629 | 37.3438 |
| M-1 | 2.8652 | 2.5549 |
| M-1 | 0.6456 | 22.8013 |
| M-1 | 29.623 | 20.0194 |
| M-1 | 10.5812 | 29.0328 |
| M-1 | 18.3046 | 22.2867 |
| M-1 | 19.0528 | 24.684 |
| M-1 | 2.5693 | 35.74 |
| M-2 | 45.0162 | 14.3878 |
| M-2 | 40.8404 | 18.8396 |
| M-2 | 27.1032 | 21.0547 |
| M-2 | 29.8036 | 16.9327 |
| M-2 | 63.8316 | 30.7037 |
| M-2 | 42.107 | 3.2491 |
| M-2 | 30.0322 | 47.4412 |
| M-2 | 34.0516 | 42.239 |
| M-2 | 15.7664 | 32.8354 |
| M-2 | 35.1262 | 50.9698 |
| M-2 | 43.6988 | 19.3897 |
| M-2 | 26.7585 | 13.8168 |
| M-2 | 36.7895 | 0.5817 |
| M-2 | 30.9458 | 53.7757 |
| M-2 | 26.8465 | 15.4137 |
| M-2 | 40.3883 | 9.2161 |
| M-2 | 30.6555 | 56.8456 |
| M-2 | 19.9736 | 44.9411 |
| M-2 | 27.676 | 36.8543 |
| M-2 | 44.084 | 24.3396 |
| M-3 | 15.2646 | 11.4999 |
| M-3 | 19.6745 | 9.7757 |
| M-3 | 23.275 | 12.7825 |
| M-3 | 16.1161 | 2.4065 |
| M-3 | 16.8393 | 1.1253 |
| M-3 | 23.107 | 3.7349 |
| M-3 | 21.5322 | 6.9725 |
| M-3 | 13.4191 | 12.2867 |
| M-3 | 14.7273 | 11.4841 |
| M-3 | 18.4245 | 11.9078 |