16.5 – Instrument reliability and validity
Introduction
What’s in a measure? We’ve talked about measurement extensively, eg, Chapter 3.3 . As review, a measure is simply the result of some process used to quantify an object or item of interest. Instead of a number, a measure may return a classification: for a given sample unit, the unit may be categorized as meeting the definition and therefore given a “yes” or it does not (“no”), a dichotomous response. The method used to obtain the measurement is called the instrument. An instrument may indeed be an instrument like a sphygmomanometer or a thermocycler equipped with fluorescent optics. Instrument in this context however also includes questionnaires or surveys intended.
In biology and biomedical research, there are thousands of kinds of measurements one has to choose among depending on the question at hand. In many cases choices are straightforward: in morphometrics, the instruments of choice will be lengths and areas and shapes quantified by rulers and application of well-defined geometry equations. Where multiple measurement approaches apply, reliability analysis can help decide which method to use, or, importantly, whether the different approaches agree. For example, Kruse et al (2017) compared ultra sound and magnetic resonance imaging measurements of Achilles tendon cross-sectional area; they found that although both methods were internally consistent, the methods consistently yielded different results.
In other arenas, the choice of instrument will be less clear. For example, doctors use a questionnaire to rank cardiac patients for attention in perioperative care, the care a surgical patient receives from admittance to release from the hospital, to improve patient outcomes. The questionnaire will include a number of questions intended to provide a summary picture of each patient so that if resources are limited, the most at risk patients may get priority. To the extent the questionnaire in fact is a useful discriminant, then the instrument may benefit both hospital and patients.
In conducting measures one selects instruments that provide valid results. That is, provided the instruments are maintained and well-calibrated, use of a sphygmomanometer by a trained technician will return accurate and valid measures of a subject’s blood pressure. Survey questions also can be evaluated for validity although the extent to which survey questions measure what is intended may be more complex. For example, if the intent is to ascertain a subject’s chance (ie, risk) of graduating from college in the next year, how useful would the following question be if administered to a room filled with first-year students?
Survey question: How old are you now?
Simple enough question, but immediately, several questions come to mind. Do we want our responses in years, months, days, hours, minutes, or seconds? What about for those individuals that know only approximately when they were born, ie, in many parts of the world, registration of birth is irregular. So, we may even wonder about how necessary it is we ask this question of college students in the first place, eg, do we really want to trigger our subjects for a case in which most of our subjects are about the same age?
Perhaps we decide this is important information to ask. When do you start counting? Most Western cultures start the clock at zero when the baby is born. In China and many other Eastern Asian countries, people are born at one. In India, once a person reaches a year plus six months, the person would be considered two years old, whereas in the USA, the person would still be considered one until the second birthday. Thus, depending on the person’s culture identity, responses to this simple question may differ by as much as a year.
Types of reliability
Regardless of instrument, all measures contain error. Hence, even a valid instrument may not return an accurate measure for each subject. The concept of instrument reliability is concerned with error of measurement. Reliability may be defined in at least four contexts:
- internal consistency
- inter-rater (also called inter-observer reliability)
- parallel-forms
- test-retest
For an instrument to show internal consistency, this implies that the survey has multiple questions that pertain to the same concept or topic, but written in different ways to reveal effects of word choice, for example. Inter-rater reliability refers to an instrument that when used by different observers (eg, science fair judges), the observers give the same or at least consistent scores for the same test. Parallel forms reliability implies that two surveys on, perhaps scientific literacy in high school students, yield the same conclusions even though each survey has different questions. Test-retest reliability is a straight-forward concept — if the instrument is repeated, are the same scores achieved?
Split-half reliability
Split-half reliability is a method for assessing a measurement tool’s internal consistency by determining if different parts of it produce consistent results. This is done by splitting a single measure (eg, a test or a set of behavioral observations) into two comparable halves, calculating a score for each half, and then finding the correlation between the two sets of scores. For example, the ManyDogs research consortium used split-half design to investigate whether or not dogs consistently interpret human pointing instructions (Espinoza et al 2023). Alternatives to split-half reliability include test-retest reliability, parallel-forms reliability, and inter-rater reliability — see Chapter 12.3, Chapter 14.3 — (Cook and Beckman 2006). These methods assess different aspects of consistency, such as stability over time (test-retest), consistency between two different but equivalent tests (parallel-forms), or agreement between observers (inter-rater). Both ICC and split-half reliability address consistency. The primary distinction is that split-half reliability is a method for assessing the internal consistency of a single test administration, while the Intraclass Correlation Coefficient (ICC) is a more flexible statistical measure used to assess absolute agreement or consistency across different measures, time points, or, most commonly, between multiple raters.
For split-half reliability, a product moment correlation is first calculated between the score of the two halves. A high correlation indicates that all items or observations within the measure are likely assessing the same underlying construct, while a low correlation suggests inconsistency. The correlation coefficient is typically adjusted using the Spearman-Brown prediction formula to estimate the reliability of the original full-length measure.
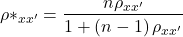
Equation of the Spearman-Brown prediction (or prophecy) formula.
Reliability estimators
In general, correlation-type measures can be used to quantify the extent of reliability (also termed reproducibility or repeatability). The product moment correlation is used to quantify the relationship between two measures where there is clear distinction between the two variables. For example, to quantify the association between body weight and height, the proper correlation to calculate would be the product moment correlation because it is clear that a measure of weight goes with the variable weight whereas height measures goes with the variable height.
But it is less clear which variable should go first in the calculation when you have repeat measures of essentially the same thing. Which goes first, the first observation of sprint running speed over a 100 meters of the second measure of the same person’s performance? Logically, we may say take the first as the X variable and the second as the Y variable, but there is no mathematical justification.
For a more challenging example, consider measures of body mass on male and female birds that are mated, and the researcher wants to assess whether there is a correlation between male and female weight — which variable goes first in the analysis, male weight or female weight? In such cases the intraclass correlation coefficient may be used (Chapter 12.3, Chapter 16.4). The intraclass correlation can be estimated as the ratio of the variance of interest over the sum of the variance of interest plus the variance error. Interest in the case of sprint running would be the two (or more) trials or for the bird weights the variable of interest is weights of male and female birds within a mated pair. The formula for ICC in this context is given by
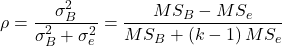
where k is the number of repeat measures and MS refers to the mean squares from the one-way ANOVA and B and e refer to between (among) subjects and e is the error or within subjects variability.
Cronbach’s alpha is a reliability measure that quantifies the internal consistency of items in a survey or instrument by calculating the average among these items. Cronbach’s alpha will tend to increase as the intercorrelations among test items increase, and in this sense can be taken as an internal consistency estimate of the reliability of test scores.
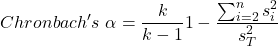
where k is the number of items, si2 is the variance of the i-th item, and sT2 is the variance of the total score after summing all items.
Cronbach’s alpha is one of the oldest measures, and at least in part because of how long ago it was introduced, is very common as a measure of reliability. However, there are other estimators and in some aspects these perform better than Cronbach’s alpha.
Reliability statistics like Cronbach’s alpha are available in the R package psych. See also R package agRee.
Example. Judging of posters
library(psych)
alpha(myJudge)
Output from R
Reliability analysis
Call: alpha(x = myJudge)

raw_alpha std.alpha G6(smc) average_r S/N   ase  mean   sd median_r
     0.74      0.74   0.59       0.59 2.9  0.21   2.8  1.1     0.59

lower alpha upper 95% confidence boundaries
0.33 0.74 1.15
Questions
1. Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
2. A team of behavioral ecologists designs a new test to measure problem-solving ability in domestic dogs. Each dog is given a puzzle box, and the experimenters record the time taken to retrieve a treat and number of errors made. They want to ensure that their measurement instrument is reliable before drawing conclusions about individual differences in cognition.
Question: Describe how you would test the reliability of this instrument. Which type(s) of reliability would be most appropriate (split-half, test–retest, parallel-forms, inter-rater), and why?
Quiz Chapter 16.5
Instrument reliability and validity
Chapter 16 contents
16.4 – Spearman and other correlations
Introduction
Pearson product moment correlation is used to describe the level of linear association between two variables. There are many types of correlation estimators in addition to the familiar Product Moment Correlation, r.
Spearman rank correlation
If you take the ranks for X 1 and the ranks for X 2, the correlation of ranks is called Spearman rank correlation, rs. Spearman correlation is a nonparametric statistic. Like the product moment correlation, it can take values between -1 and +1.
For variables X 1 and X 2, the rank order correlation may be calculated on the ranks as
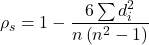
where di is the difference between the ranks of X 1 and X 2 for each experimental unit. This formula assumes that there are no tied ranks; if there are, use the equation for the product moment correlation instead (but on the ranks).
R commander has an option to calculate the Spearman rank correlation simply by selecting the check box in the correlation sub menu. However, if the data set is small, it may be easier to just run the correlation in the script window.
Our example for the product moment correlation was between Drosophila fly wing length and wing area (Table 1).
Table 1. Fly wing lengths and area, units mm and mm2, respectively (Dohm pers obs.)
| Obs | Student | Length | Area |
|---|---|---|---|
| 1 | S01 | 1.524 | 0.446 |
| 2 | S01 | 2.202 | 0.876 |
| 3 | S01 | 1.52 | 0.39 |
| 4 | S01 | 1.62 | 0.51 |
| 5 | S01 | 1.71 | 0.736 |
| 6 | S03 | 1.551 | 0.453 |
| 7 | S03 | 2.228 | 0.882 |
| 8 | S03 | 1.46 | 0.394 |
| 9 | S03 | 1.659 | 0.503 |
| 10 | S03 | 1.719 | 0.535 |
| 11 | S05 | 1.534 | 0.441 |
| 12 | S05 | 2.223 | 0.889 |
| 13 | S05 | 1.49 | 0.391 |
| 14 | S05 | 1.633 | 0.514 |
| 15 | S05 | 1.704 | 0.546 |
| 16 | S08 | 1.551 | 0.453 |
| 17 | S08 | 2.228 | 0.882 |
| 18 | S08 | 1.468 | 0.394 |
| 19 | S08 | 1.659 | 0.503 |
| 20 | S08 | 1.719 | 0.535 |
Repeated observations by image analysis (ImageJ) were collected by four students (S01, S03, So5, S08) from fixed wings to glass slides.
Here’s the scatterplot of the ranks of fly wing length and fly wing area (Fig 1).
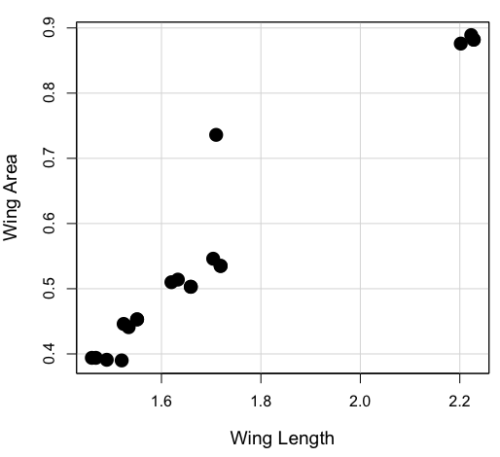
Figure 1. Drosophila wing area (mm2) by wing length (mm).
A nonparametric alternative to the product moment correlation, the Spearman Rank correlation can be obtained directly. The Spearman correlation involves ranking the data, ie, converting data types, from ratio scale data to ordinal scale, then applying the same formula used for the Product moment correlation to the ranked data. The Spearman correlation would be the choice for testing linear association between two ordinal type variables. It is also appropriate in lieu of the parametric product moment correlation when the statistical assumptions are not met, eg, normality assumption.
R code
For the Spearman rank correlation, at the R prompt type
cor.test(Area, Length, alternative="two.sided", method="spearman")

R returns with
    Spearman's rank correlation rho

data:  Area and Length
S = 58.699, p-value = 5.139e-11
alternative hypothesis: true rho is not equal to 0
sample estimates:
      rho
0.9558658
Alternatively, to calculate either correlation, use R Commander.
Rcmdr: Statistics → Summaries→ Correlation test
Example
BM=c(29,29,29,32,32,35,36,38,38,38,40)
Matings=c(0,2,4,4,2,6,3,3,5,8,6)

cor.test(BM,Matings, method="spearman")
Warning in cor.test.default(BM, Matings, method = "spearman") :
  Cannot compute exact p-value with ties

        Spearman's rank correlation rho

data:  BM and Matings
S = 77.7888, p-value = 0.03163
alternative hypothesis: true rho is not equal to 0
sample estimates:
      rho
0.6464143
cor.test(BM,Matings, method="pearson")

        Pearson's product-moment correlation

data:  BM and Matings
t = 2.6728, df = 9, p-value = 0.02551
alternative hypothesis: true correlation is not equal to 0
95 percent confidence interval:
 0.1087245 0.9042515
sample estimates:
      cor
0.6652136
Other correlations
Kendall’s tau
Another nonparametric correlation is Kendall’s tau (τ). Rank the X 1 values, then rank the X 2 values. Count the number of X 1, X 2 pairs that have the same rank (concordant pairs) and the number of X 1, X 2 pairs that do not have the same rank (discordant pairs), Kendall’s tau is then
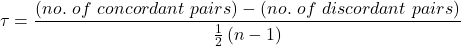
where n is the number of pairs.
Note 1: The denominator is our familiar number of pairwise comparisons if we take k = n
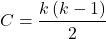
We introduced concordant and discordant pairs when we presented McNemar’s test and cross-classified experimental design in Chapter 9.6.
Example: Judging of Science Fair posters
What is the agreement between two judges, A and B, who evaluated the same science fair posters? Posters were evaluated on if the student’s project was hypothesis-based and judges used a Likert-like scale Strongly disagree (1), Somewhat disagree (2), Neutral (3), Somewhat agree (4), Strongly agree (5).
Table 2. Two judges evaluated six posters for evidence of hypothesis-based project
| Poster | Judge.A | Judge.B |
| 1 | 5 | 4 |
| 2 | 2 | 3 |
| 3 | 4 | 2 |
| 4 | 3 | 1 |
| 5 | 2 | 1 |
| 6 | 4 | 3 |
A concordant pair represents a poster ranked higher by both judges, while a discordant pair is a poster ranked high by one judge but low by another judge. Poster 1 and poster 5 were concordant pairs,
In R, it is simple to get this correlation directly by invoking the cor.test function and specifying the method equal to kendall. The cor.test assumes that the data are in a matrix, so use the cbind function to bind two vectors together – note the vectors need to have the same number of observations. If the data set is small, it is easier to just enter the data directly in the script window of R commander.
A = c(2,2,3,4,4,5)
B = c(1,3,1,2,3,4)
m = cbind(A,B)
cor.test(A,B, method="kendall")

  Cannot compute exact p-value with ties

        Kendall's rank correlation tau

data:  A and B
z = 1.4113, p-value = 0.1581
alternative hypothesis: true tau is not equal to 0
sample estimates:
      tau
0.5384615
End of R output
There were no ties in this data set, but we can run the product moment correlation just for comparison
cor.test(A,B, method="pearson")

        Pearson's product-moment correlation

data:  A and B
t = 1.4649, df = 4, p-value = 0.2168
alternative hypothesis: true correlation is not equal to 0
95 percent confidence interval:
 -0.4239715  0.9478976
sample estimates:
      cor
0.5909091
End R output
Tetrachoric and Polychoric correlation
Tetrachoric correlations used for binomial outcomes (yes, no), polychoric correlation used for ordinal categorical data like the Likert scale. Introduced by Karl Pearson, commonly applied correlation estimate for Item Analysis in psychometric research. Pyschometrics, a sub-discipline within psychology and now a significant part of education research, is about evaluating assessment tools.
R package psych.
R code: Tetrachoric correlation
tetrachoric(x,y=NULL,correct=.5,smooth=TRUE,global=TRUE,weight=NULL,na.rm=TRUE,
     delete=TRUE)
R code: Polychoric correlation
polychoric(x,smooth=TRUE,global=TRUE,polycor=FALSE,ML=FALSE, std.err=FALSE,
     weight=NULL,correct=.5,progress=TRUE,na.rm=TRUE,  delete=TRUE)
Polyserial correlation
R package polychor. Used to estimate linear association between a ratio scale variable and an ordinal variable.
R code: Polyserial correlation
polyserial(x,y)
Biserial correlation would be a special case of the polyserial correlation, where ordinal variable is replaced by a dichotomous (binomial) variable.
R code: Polyserial correlation
biserial(x,y)
Intra-class correlation coefficient
Both the ICC and the product moment correlation, r, which we introduced in Chapter 16.1, are measures of strength of linear association between two ratio scale variables (Jinyuan et al 2016). But ICC is more appropriate for association between repeat measures of the same thing, eg, repeat measures of running speed. In contrast, the product moment correlation can be used to describe association between any two variables, eg, between repeat measures of running speed, but also between say running speed and maximum jumping height. ICC is used when quantitative measures are organized into paired groups, eg, before and after on same subjects, or cross-classified designs. ICC was introduced in Chapter 12.3 as part of discussion of repeated measures and random effects. ICC is used extensively to assess reliability of a measurement instrument (Shrout and Fleiss 1979; McGraw and Wong 1996).
Example. Data from Table 2
library(psych)
ICC(myJudge, lmer=FALSE)
R output follows
Intraclass correlation coefficients
                         type  ICC   F df1 df2      p lower bound upper bound
Single_raters_absolute   ICC1 0.40 2.3   5   6  0.166      -0.306        0.84
Single_random_raters     ICC2 0.46 3.9   5   5  0.081      -0.093        0.85
Single_fixed_raters      ICC3 0.59 3.9   5   5  0.081      -0.130        0.90
Average_raters_absolute ICC1k 0.57 2.3   5   6  0.166      -0.880        0.91
Average_random_raters   ICC2k 0.63 3.9   5   5  0.081      -0.205        0.92
Average_fixed_raters    ICC3k 0.74 3.9   5   5  0.081      -0.299        0.95

Number of subjects = 6 Number of Judges = 2
See the help file for a discussion of the other 4 McGraw and Wong estimates
Lots of output, lots of “ICC”. However, rather than explaining each entry, reflect on the type and review the data. Were the posters evaluated repeatedly? Posters were evaluated twice, but only once per judge, so there is a repeated design with respect to the posters. Had the judges been randomly selected from a population of all possible judges? No evidence was provided to suggest this, so judges were a fixed factor (see Chapter 12.3 and Chapter 14.3).
The six ICC estimates reported by R follow discussion in Shrout and Fliess (1979), and our description fits their Case 3: “Each target is rated by each of the same k judges, who are the only judges of interest (p. 421)” Thus, we find ICC for single fixed rater, ICC = 0.59. Note that we would fail to reject the hypothesis that the judges evaluations were associated.
Questions
1. Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
2. See Homework 10, Mike’s Workbook for biostatistics
Quiz Chapter 16.4
Spearman and other correlations
Chapter 16 contents
12.3 – Fixed effects, random effects, and agreement
Introduction
Within discussions of one-way ANOVA models the distinction between two general classes of models needs to be made clear by the researcher. The distinction lies in how the levels of the factor are selected. If the researcher selects the levels, then the model is a Fixed Effects Model, also called a Model I ANOVA. On the other hand, if the levels of the factor were selected by random sampling from all possible levels of the factor, then the model is a Random Effects Model, also called a Model II ANOVA. This page is about such models and I’ll introduce the intraclass correlation coefficient, abbreviated as ICC, as a way to illustrate applications of Model II ANOVA.
Here’s an example to help the distinction. Consider an experiment to see if over the counter painkillers are as good as prescription pain relievers at reducing numbers of migraines over a six week period. The researcher selects Tylenol®, Advil®, Bayer® Aspirin, and Sumatriptan (Imitrex®), the latter an example of a medicine only available by prescription. This is clearly an example of fixed effects; the researcher selected the particular medicines for use.
Random effects, in contrast, implies that the researcher draws up a list of all over the counter pain relievers and draws at random three medicines; the researcher would also randomly select from a list of all available prescription medicines.
Fixed effects are probably the more common experimental approaches. To be complete, there is a third class of ANOVA called a Mixed Model or Model III ANOVA, but this type of model only applies to multidimensional ANOVA (eg, two-way ANOVA or higher), and we reserve our discussion of the Model III until we discuss multidimensional ANOVA (Table 1).
Table 1. ANOVA models
| ANOVA model | Treatments are |
| I | Fixed effects |
| II | Random effects |
| III | Mixed, both fixed & random effects |
Although the calculations for the one-way ANOVA under Model I or Model II are the same, the interpretation of the statistical significance is different between the two.
In Model I ANOVA, any statistical difference applies to the differences among the levels selected, but cannot be generalized back to the population. In contrast, statistical significance of the Factor variable in Model II ANOVA cannot be interpreted as specific differences among the levels of the treatment factor, but instead, apply to the population of levels of the factor. In short, Model I ANOVA results apply only to the study, whereas Model II ANOVA results may be interpreted as general effects, applicable to the population.
This distinction between fixed effects and random effects can be confusing, but it has broad implications for how we interpret our results in the short-term. This conceptual distinction between how the levels of the factor are selected also has general implications for our ability to acquire generalizable knowledge by meta-analysis techniques (Hunter and Schmidt 2000). Often we wish to generalize our results: we can do so only if the levels of the factor were randomly selected in the first place from all possible levels of the factor. In reality, this may not often be the case. It is not difficult to find examples in the published literature in which the experimental design is clearly fixed effects (ie, the researcher selected the treatment levels for a reason), and yet in the discussion of the statistical results, the researcher will lapse into generalizations.
Random Effects Models and agreement
Model II ANOVA is common in settings in which individuals are measured more than once. For example, in behavioral science or in sports science, subjects are typically measured for the response variable more than once over a course of several trials. Another common setting of Model II ANOVA is where more than one raters are judging an event or even a science project. In all of these cases what we are asking is about whether or not the subjects are consistent, in other words, we are asking about the precision of the instrument or measure.
In the assessment of learning by students, for example, different approaches may be tried and the instructor may wish to investigate whether the interventions can explain changes in test scores. To assess instrument validity — an item score from a grading rubric (Goertzen and Klaus 2023), tumor budding as biomarker for colorectal cancer (Bokhorst et al 2020) — agreement or concordance among two or more raters or judges (inter-rater reliability) needs to be established (same citations and references therein). For binomial data, we would be tempted to use the phi coefficient, Is it actually reliable Cohen’s kappa (two judges) or Fleiss Kappa (two or more judges) is a better tool. Phi coefficient and both assessment scores were introduced in Chapter 9.2.
For ratio scale data, agreement among scores of two or more scores from judges There is an enormous number of articles on reliability measures in the social sciences and you should be aware of a classical paper on reliability by Shrout and Fleiss (1979) (see also McGraw and Wong, 1996). Both the ICC and the Pearson product moment correlation, r, which we will introduce in Chapter 16, are measures of strength of linear association between two ratio scale variables (Jinyuan et al 2016). But ICC is more appropriate for association between repeat measures of the same thing, eg, repeat measures of running speed or agreement between judges. In contrast, the product moment correlation can be used to describe association between any two variables, eg, between repeat measures of running speed, but also between say running speed and maximum jumping height. The concept of repeatability of individual behavior or other characteristics is also a common theme in genetics and so you should not be surprised to learn that the concept actually traces to RA Fisher and his invention of ANOVA. Just as in the case of the sociology literature, there are many papers on the use and interpretation of repeatability in the evolutionary biology literature (eg, Lessels and Boag 1987; Boake 1989; Falconer and Mackay 1996; Dohm 2002; Wolak et al 2012).
Agreement and repeatability are Model II (random effects) because the subjects, items, or raters being studied are treated as a random sample from a larger population rather than specific, fixed levels of interest. In reliability studies, subjects are not chosen for their specific characteristics but as representatives of the population variability. The goal is to infer whether a measurement tool works for any future subject or rater, not just the ones tested in the study. These factors are designed to estimate variance components and generalize results beyond the specific sample used. Put another way, the goal of Model II is often to estimate how much variance is due to differences between subjects versus within subjects (repeatability), which requires treating the subject effect as random.
There are many ways to analyze these kinds of data but a good way is to treat this problem as a one-way ANOVA with Random Effects. Thus, the Random Effects model permits the partitioning of the variation in the study into two portions: the amount that is due to differences among the subjects or judges or intervention versus the amount that is due to variation within the subjects themselves. The Factor is the Subjects and the levels of the factor are how ever many subjects are measured twice or more for the response variable.
If the subjects performance is repeatable, then the Mean Square Between (Among) Subjects,  , component will be greater than the Mean Square Error component,
 , of the model. There are many measures of repeatability or reliability, but the intraclass correlation coefficient or ICC is one of the most common. The ICC may be calculated from the Mean Squares gathered from a Random Effects one-way ANOVA. ICC can take any value between zero and one.
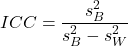
where
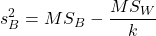
and

B and W refers to the among group (between or among groups mean square) and the within group components of variation (error mean square), respectively, from the ANOVA, MS refers to the Mean Squares, and k is the number of repeat measures for each experimental unit. In this formulation k is assumed to be the same for each subject.
By example, when a collection of sprinters run a race, if they ran it again, would the outcome be the same, or at least predictable? If the race is run over and over again and the runners cross the finish lines at different times each race, then much of the variation in performance times will be due to race differences largely independent of any performance abilities of the runners themselves and the Mean Square Error term will be large and the Between subjects Mean Square will be small. In contrast, if the race order is preserved race after race: Jenny is 1st, Ellen is 2nd, Michael is third, and so on, race after race, then differences in performance are largely due to individual differences. In this case, the Between-subjects Mean Square will be large as will the ICC, whereas the Mean Square for Error will be small, and so will the ICC.
Can the intraclass correlation be negative?
In theory, no. Values for ICC range between zero and one. The familiar Pearson product moment correlation, Chapter 16, takes any value between -1 and +1. However, in practice, negative values for ICC will result if 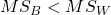 .
In other words, if the within group variability is greater than the among group variability, then negative ICC are possible. The question is whether negative estimates are ever biologically relevant or, simply result of limitations of the estimation procedure. Small ICC values and few repeats increases the risk of negative ICC estimates. Thus, a negative ICC would be “simply a(n) “unfortunate” estimate (Liljequist et al 2019). However, there may be situations in which negative ICC is more than unfortunate. For example, repeatability, a quantitative genetics concept (Falconer and Mackay 1996), can be negative (Nakagawa and Schielzeth 2010).
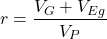
Repeatability reflects the consistency of individual traits over time (or spatially, eg, scales on on a snake), is defined as the ratio of within individual differences and among individuals differences. Thus, within individual variance is attributed to general environmental effects,  , whereas variance among individuals is both genetic and environmental. Scenarios for which repeated measures on the same individual may occur under environmental conditions, termed specific environmental effects or
 by Falconer and Mackay (1996), that negatively affect performance are not hard to imagine — it remains to be determined how common these conditions are and whether or not estimates of repeatability are negative.
ICC Example
I extracted 15 data points from a figure about nitrogen metabolism in kidney patients following treatment with antibiotics (Figure 1, Mitch et al 1977). I used a web application called WebPlot Digitizer (https://apps.automeris.io/wpd/), but you can also accomplish this task within R via the digitize package. I was concerned about how steady my hand was using my laptop’s small touch screen, a problem that very much can be answered by thinking statistically, and taking advantage of the ICC. So, rather than taking just one estimate of each point I repeated the protocol for extracting the points from the figure three times generating a total of three points for each of the 15 data points or 45 points in all. How consistent was I?
Let’s look at the results just for three points, #1, 2, and 3.
In the R script window enter
points = c(1,2,3,1,2,3,1,2,3)
Change points to character so that the ANOVA command will treat the numbers as factor levels.
points = as.character(points)
extracts = c(2.0478, 12.2555, 16.0489, 2.0478, 11.9637, 16.0489, 2.0478, 12.2555, 16.0489)
Make a data frame, assign to an object, eg, “digitizer”
digitizer = data.frame(points, extracts)
The dataset “digitizer” should now be attached and available to you within Rcmdr. Select digitizer data set and proceed with the one-way ANOVA.
Output from oneway ANOVA command
Model.1 <- aov(extracts ~ points, data=digitizer)

 summary(Model.1)
            Df    Sum Sq   Mean Sq  F value     Pr(>F)
points       2 313.38895 156.69448 16562.49 5.9395e-12 ***
Residuals    6   0.05676   0.00946
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

numSummary(extracts , groups = points,
+   statistics=c("mean", "sd"))
         mean           sd data:n
1  2.04780000 0.0000000000      3
2 12.15823333 0.1684708085      3
3 16.04890000 0.0000000000      3
End R output. We need to calculate the ICC
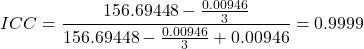
I’d say that’s pretty repeatable and highly precise measurement!
But is it accurate? You should be able to disentangle accuracy from precision based on our previous discussion (Chapter 3.5), but now in the context of a practical way to quantify precision.
ICC calculations in R
We could continue to calculate the ICC by hand, but better to have a function. Here’s a crack at the function to calculate ICC along with a 95% confidence interval.
myICC <- function(m, k, dfN, dfD) {
 testMe <- anova(m)
 MSB <- testMe$"Mean Sq"[1]
 MSE <- testMe$"Mean Sq"[2]
 varB <- MSB - MSE/k
 ICC <- varB/(varB+MSE)
 fval <- qf(c(.025), df1=dfN, df2=dfD, lower.tail=TRUE)
 CI = (k*MSE*fval)/(MSB+MSE*(k-1)*fval)
 LCIR = ICC-CI
 UCIR = ICC+CI
 myList = c(ICC, LCIR, UCIR)
 return(myList)
}
The user supplies the ANOVA model object (eg, Model.1 from our example), k, which is the number of repeats per unit, and degrees of freedom for the among groups comparison (2 in this example), and the error mean square (6 in this case). Our example, run the function
m2ICC = myICC(Model.1, 3, 2,6); m2ICC
and R returns
[1] 0.9999396 0.9999350 0.9999442
with the ICC reported first, 0.9999396, followed by the lower limit (0.9999350) and the upper limit (0.9999442) of the 95% confidence interval.
Instead of writing your own function, several R packages can calculate the intraclass correlation coefficient (ICC) and its variants. These packages include: irr, psy, psych, and rptR. For complex experiments involving multiple predictor variables, these packages are helpful for obtaining the correct ICC calculation (cf Shrout and Fleiss 1979; McGraw and Wong 1996). For the one-way ANOVA it is easier to just extract the information you need from the ANOVA table and run the calculation directly. We do so for a couple of examples.
Example: Are marathon runners consistent more consistent than my commute times?
Figure 1.Honolulu Marathon 2024 participant. Image credit: Pdubs.94, licensed under CC BY 4.0 (Creative Commons Attribution 4.0 International License), via Wikipedia.
A marathon is 26 miles, 385 yards (42.195 kilometers) long (World Athletics.org). And yet, tens of thousands of people choose to run in these events. For many, running a marathon is a one-off, the culmination of a personal fitness goal. For others, it’s a passion and a few are simply extraordinary, elite runners who can complete the courses in 2 to 3 hours (Table 3). That’s about 12.5 miles per hour. For comparison, my 20 mile commute on the H1 freeway on Oahu typically takes about 40 minutes to complete, or 27 miles per hour (Table 2, yes, I keep track of my commute times, per Galton’s famous maxim: “Whenever you can, count”).
Figure 2. View west along Interstate H-1 (Lunalilo Freeway) at 6:30AM on a weekday, Honolulu, Oahu, Hawaii. Image used with permission, credit: S. Dohm.
Table 2. A sampling of average commute speeds, miles per hour (mph), on the H1 freeway during DrD’s morning commute (distance about 19.3 miles).
| Week | Monday | Tuesday | Wednesday | Thursday | Friday |
|---|---|---|---|---|---|
| 1 | 28.5 | 23.8 | 28.5 | 30.2 | 26.9 |
| 2 | 25.8 | 22.4 | 29.3 | 26.2 | 27.7 |
| 3 | 26.2 | 22.6 | 24.9 | 24.2 | 34.3 |
| 4 | 23.3 | 26.9 | 31.3 | 26.2 | 30.2 |
Try on your own.
Calculate the ICC for my commute speeds.
Run the one-way ANOVA to get the necessary mean squares and input the values into our ICC function. We have
require(psych)
m2ICC = myICC(AnovaModel.1, 4, 4,11); m2ICC
[1] 0.7390535 0.6061784 0.8719286
Repeatability, as estimated by the ICC, was 0.74 (95% CI 0.606, 0.872), for repeat measures of commute times.
We can ask the same about marathon runners — how consistent from race to race are these runners? The following data are race times drawn from a sample of runners who completed the Honolulu Marathon in both 2016 and 2017 in 2 to 3 hours (times recorded in minutes). In other words, are elite runners consistent?
Table 3. Honolulu marathon running times (min) for eleven repeat, elite runners.
| ID | Time |
|---|---|
| P1 | 179.9 |
| P1 | 192.0 |
| P2 | 129.9 |
| P2 | 130.8 |
| P3 | 128.5 |
| P3 | 129.6 |
| P4 | 179.4 |
| P4 | 179.7 |
| P5 | 174.3 |
| P5 | 181.7 |
| P6 | 177.2 |
| P6 | 176.2 |
| P7 | 169.0 |
| P7 | 173.4 |
| P8 | 174.1 |
| P8 | 175.2 |
| P9 | 175.1 |
| P9 | 174.2 |
| P10 | 163.9 |
| P10 | 175.9 |
| P11 | 179.3 |
| P11 | 179.8 |
Stacked worksheet, P refers to person, therefore P1 is person ID 1, P2 is person ID 2, and so on.
After running a one-way ANOVA, here are results for the marathon runners
m2ICC = myICC(Model.1, 2, 10,11); m2ICC
[1] 0.9780464 0.9660059 0.9900868
Repeatability, as estimated by the ICC, was 0.98 (95% CI 0.966, 0.990), for repeat measures of marathon performance. Put more simply, knowing what a runner did in 2016 I would be able to predict their 2017 race performance with high confidence, 98%!
And now, we compare: the runners are more consistent!
Clearly this is an apples-to-oranges comparison, but it gives us a chance to think about how we might make such comparisons. The ICC will change because of differences among individuals. For example, if individuals are not variable, if everyone finishes the race at the same time, then the ICC will be low (or even zero). Because there is no variance to be attributed to individual differences, the proportion of total variance explained by those differences will be being minimal.
Visualizing repeated measures.
Waterfall plot.
If just two measures, then a profile plot will do. We introduced profile plots in the paired t-test chapter (Ch10.3). For more than two repeated measures, a line graph will do (see question 9 below). Another graphic increasingly used is the waterfall plot (waterfall chart), particularly for before and after measures or other comparisons against a baseline. For example, it’s a natural question for our eleven marathon runners — how much did they improve on the second attempt of the same course? Figure 3 shows my effort to provide a visual.
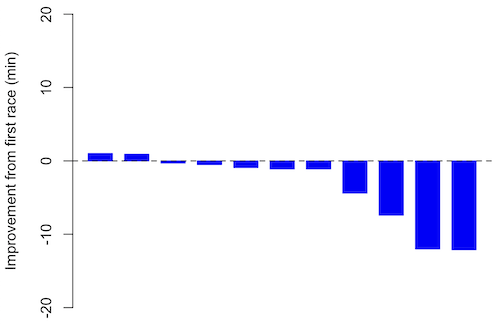
Figure 3. Simple waterfall plot of race improvement for Table 3 data. Dashed horizontal line at zero.
R code
Data wrangling: Create a new variable, eg, race21, by subtracting the first time from the second time. Multiply by -1 so that improvement (faster time in second race) is positive. Finally, apply descending sort so that improvement is on the left and increasingly poorer times are on the right.
df <- data.frame(
ID = rep(paste0("P", 1:11), each = 2),
Time = c(179.9,192.0,
129.9,130.8,
128.5,129.6,
179.4,179.7,
174.3,181.7,
177.2,176.2,
169.0,173.4,
174.1,175.2,
175.1,174.2,
163.9,175.9,
179.3,179.8)
)

# Convert to wide format
df_wide <- reshape(df, idvar = "ID", timevar = "ID",
direction = "wide")

# Extract first and second times manually
time_matrix <- matrix(df$Time, ncol = 2, byrow = TRUE)
colnames(time_matrix) <- c("Time1", "Time2")

# Calculate improvement (second - first)
base21 <- time_matrix[,2] - time_matrix[,1]

# Sort for waterfall display
base21 <- sort(base21, decreasing = TRUE)

# Waterfall plot
barplot(base21, col="blue", border="blue", space=0.5,
ylim=c(-20,20),
ylab="Improvement from first race (min)")
abline(h=0, lty=2)
Interpretation.
From the graph (Fig 3) we see that few of the racers improved their times the second time around — a few had decreased times.
Spaghetti plots.
Spaghetti plots, which display individual trajectories over time or multiple measurements, is a specialized line plot effective for visualizing the consistency of performance. The vertical thickness or spread of a single subject’s line across measurements indicates their level of repeatability. A “flat” line indicates high repeatability, while a volatile, zig-zagging line indicates low repeatability. Spaghetti plots are useful to visualize growth, decline, or stability over time for a single performance measure.
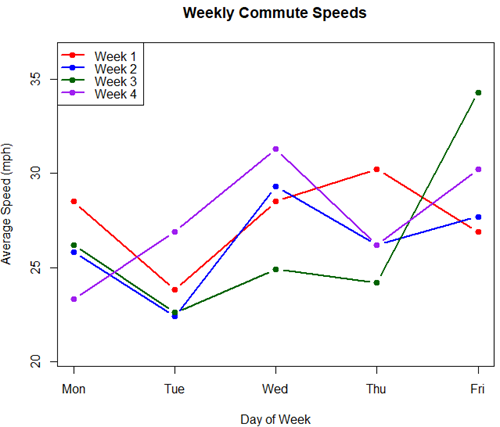
Figure 4. A spaghetti plot of average commute speeds from Table 2 data.
R code
# 1. Enter the data from Table 2.
commute <- data.frame(
Week = 1:4,
Monday = c(28.5, 25.8, 26.2, 23.3),
Tuesday = c(23.8, 22.4, 22.6, 26.9),
Wednesday = c(28.5, 29.3, 24.9, 31.3),
Thursday = c(30.2, 26.2, 24.2, 26.2),
Friday = c(26.9, 27.7, 34.3, 30.2)
)

head(commute)

# 2. Set the X-axis points
days <- 1:5
day_names <- c("Mon", "Tue", "Wed", "Thu", "Fri")

# 3. Create empty plot
# Find range of Y to ensure all data fits
ymin <- min(commute[, 2:6]) - 2
ymax <- max(commute[, 2:6]) + 2

plot(NA, xlim = c(1, 5), ylim = c(ymin, ymax),
xlab = "Day of Week", ylab = "Average Speed (mph)",
main = "Weekly Commute Speeds", xaxt = "n")

# Add X-axis labels
axis(1, at = 1:5, labels = day_names)

# 4. Add lines for each week (spaghetti)
colors <- c("red", "blue", "darkgreen", "purple")
for (i in 1:nrow(commute)) {
# Plot lines
lines(days, commute[i, 2:6], col = colors[i], lwd = 2, type = "b", pch = 19)
}

# 5. Add legend
legend("topleft", legend = paste("Week", 1:4), col = colors, lwd = 2, pch = 19)
Parallel coordinates plots.
Parallel coordinates plot allows each entity to be represented by a unique, continuous line traced across several vertical axes (each representing a different measurement or variable). High repeatability is indicated when a line remains roughly horizontal across all axes, while poor repeatability is visualized as lines that zig-zag or change direction between measurements.
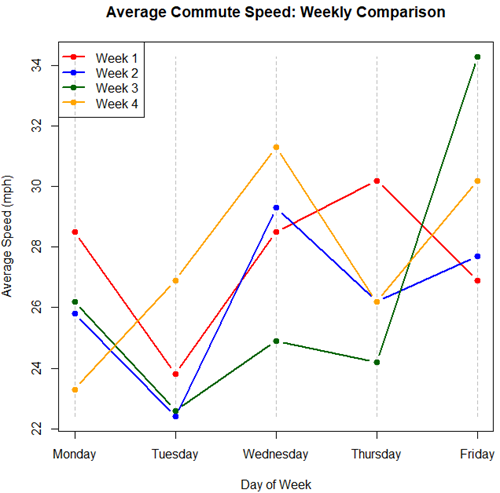
Figure 5. A parallel coordinates plot of average commute speeds from Table 2 data.
Both spaghetti plots and parallel coordinate plots can be used to visualize consistency of performance over multiple measures, but they differ significantly in their handling of data, scale, and context. Spaghetti plots are best for tracking within-subject variability over time, but quickly become a mess — like pasta tossed and sticking to a wall — when subject count increases. Parallel coordinate plots are a multivariate generalization — each line represents an individual’s profile across different tests, eg, accuracy, speed, VO2max.
R code.
# 1. Create the data frame
# see above

# 2. Extract only the numerical commute data for plotting
commute_data <- commute[, 2:6]

# 3. Setup the plot area
# Define range for y-axis
y_range <- range(commute_data)
# Define number of days (5)
num_days <- ncol(commute_data)

# Create empty plot
plot(NA, xlim = c(1, num_days), ylim = y_range,
xaxt = "n", xlab = "Day of Week", ylab = "Average Speed (mph)",
main = "Average Commute Speed: Weekly Comparison")

# Add x-axis labels
axis(1, at = 1:num_days, labels = colnames(commute_data))

# 4. Draw vertical lines for each day
for (i in 1:num_days) {
lines(c(i, i), y_range, col = "grey", lty = 2)
}

# 5. Add lines for each week (repeated measures)
colors <- c("red", "blue", "darkgreen", "orange")
for (i in 1:nrow(commute_data)) {
lines(1:num_days, commute_data[i, ], col = colors[i], lwd = 2, type = "b", pch = 19)
}

# 6. Add legend
legend("topleft", legend = paste("Week", commute$Week), col = colors, lwd = 2, pch = 19)
Heat map.
Heat map quickly identify patterns, such as an individual’s performance improving, degrading, or remaining stable over time. For example, uniform, solid colors across rows (individuals) or columns (time/trials) indicate high consistency, while varied colors indicate poor repeatability.
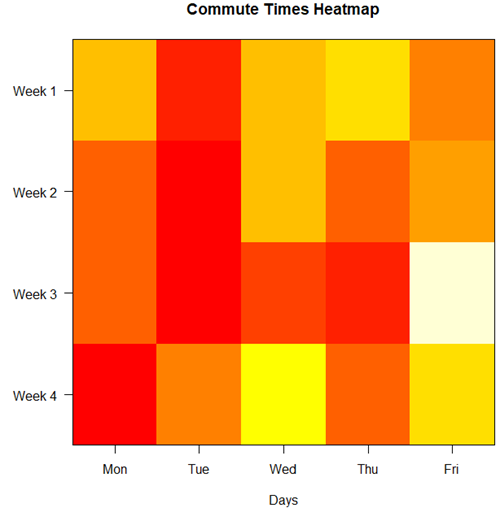
Figure 6. A heat map of the commute speeds data set.
R code.
# 1. Create the data
# Week is excluded from matrix to only include numerical commute times
commute_data <- matrix(c(
28.5, 23.8, 28.5, 30.2, 26.9,
25.8, 22.4, 29.3, 26.2, 27.7,
26.2, 22.6, 24.9, 24.2, 34.3,
23.3, 26.9, 31.3, 26.2, 30.2
), nrow = 4, byrow = TRUE)

# 2. Add row and column names
rownames(commute_data) <- c("Week 1", "Week 2", "Week 3", "Week 4")
colnames(commute_data) <- c("Mon", "Tue", "Wed", "Thu", "Fri")

# 3. Create the heatmap
# Use t() to transpose so weeks are rows and days are columns
# Use rev() on rows to have Week 1 at the top
image_data <- t(apply(commute_data, 2, rev))

# Set up the plotting area (margins for labels)
par(mar = c(5, 6, 4, 2))

# Plot the matrix
# Option 1
image(1:nrow(image_data), 1:ncol(image_data), image_data,
col = heat.colors(12),
axes = FALSE, xlab = "Days", ylab = "",
main = "Commute Times Heatmap")

# Add axes labels
axis(1, at = 1:5, labels = colnames(commute_data))
axis(2, at = 1:4, labels = rev(rownames(commute_data)), las = 1)
box()
Interpretation.
The graphs (Fig 4 – 6) show a lack of trends in consistency of drive speeds. The heat map suggests more consistency on Monday — low speeds (Fig 4 & Fig 5), but that’s a stretch.
An example for you to work, from our Measurement Day
If you recall, we had you calculate length and width measures on shells from samples of gastropod and bivalve species. In the table are repeated measures of shell length, by caliper in mm, for a sample of Conus shells (Fig 7 and Table 4).
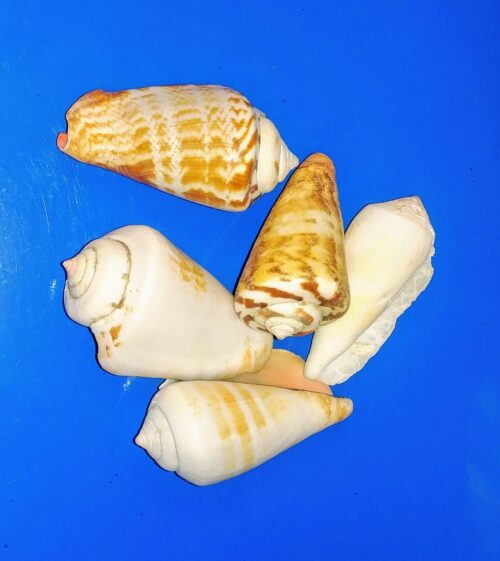
Figure 7. Conus shells, image by M. Dohm.
Repeated measures of the same 12 Conus shells.
Table 4. Unstacked dataset of repeated length measures on 12 shells
| Sample | Measure1 | Measure2 | Measure3 |
|---|---|---|---|
| 1 | 45.74 | 46.44 | 46.79 |
| 2 | 48.79 | 49.41 | 49.67 |
| 3 | 52.79 | 53.45 | 53.36 |
| 4 | 52.74 | 53.14 | 53.14 |
| 5 | 53.25 | 53.45 | 53.15 |
| 6 | 53.25 | 53.64 | 53.65 |
| 7 | 31.18 | 31.59 | 31.44 |
| 8 | 40.73 | 41.03 | 41.11 |
| 9 | 43.18 | 43.23 | 43.2 |
| 10 | 47.1 | 47.64 | 47.64 |
| 11 | 49.53 | 50.32 | 50.24 |
| 12 | 53.96 | 54.5 | 54.56 |
Maximum length from from anterior end to apex with calipers. Repeated measures were conducted blind to shell id, sampling was random over three separate time periods.
Questions
- Consider data in Table 2, Table 3, and Table 4. True or False: The arithmetic mean is an appropriate measure of central tendency. Explain your answer.
- Enter the shell data into R; Best to copy and stack the data in your spreadsheet, then import into R or R Commander. Once imported, don’t forget to change Sample to character, otherwise R will treat Sample as ratio scale data type. Run your one-way ANOVA and calculate the intraclass correlation (ICC) for the dataset. Is the shell length measure repeatable?
- The marathon results in Table 2 are paired data, results of two races run by the same individuals. Make a profile plot for the data (see Ch10.3 for help).
- A profile plot is used to show paired data; for two or more repeat measures, use a line graph instead.
A. Produce a line graph for data in Table 4. The line graph is an option in R Commander (Rcmdr: Graphs Line graph…), and can be generated with the following simple R code:
lineplot(Sample, Measure1, Measure2, Measure3)
B. What trends, if any, do you see? Report your observations.
C. Make another line plot for data in Table 2. Report any trend and include your observations.
Quiz Chapter 12.3
Fixed effects, random effects, and agreement
Chapter 12 contents
- Introduction
- The need for ANOVA
- One way ANOVA
- Fixed effects, random effects, and agreement
- ANOVA from “sufficient statistics”
- Effect size for ANOVA
- ANOVA posthoc tests
- Many tests one model
- References and suggested readings
9.2 – Chi-square contingency tables
 from a, b, c, and d 2X2 table format formula
 effect size
Introduction
This page covers a lot of ground to extend our discussion of implementations of the chi-square test to experimental data and introduces several related statistics, including a correlation coefficient for categorical data and an introduction to agreement and reliability measurement statistics.
We begin with contingency tables.
We just completed a discussion about goodness of fit tests, inferences on categorical traits for which a theoretical distribution or expectation is available. We offered Mendelian ratios as an example in which theory provides clear-cut expectations for the distribution of phenotypes in the F2 offspring generation. This is an extrinsic model — theory external to the study guides in the calculation of expected values — and it reflects a common analytical task in epidemiology.
But for many other kinds of categorical outcomes, no theory is available. Today, most of us accept the link between tobacco cigarette smoking and lung cancer. The evidence for this link was reported in many studies, some better designed than others.
Consider the famous Doll and Hill (1950) report on smoking and lung cancer. They reported (Table IV Doll and Hill 1950), for men with lung cancer, only two out of 649 were non-smokers. In comparison, 27 case-control patients (ie, patients in the hospital but with other ailments, not lung cancer) were nonsmokers, but 622 were smokers (Table 1).
Table 1. Doll and Hill (1950).
| Smokers | Non-smokers | |
| Lung cancer | 647 | 2 |
| Case controls, no lung cancer | 622 | 27 |
A more recent example from the study of the efficacy of St John’s Wort (Hypericum perforatum) as a treatment for major depression (Shelton et al 2001, Apaydin et al. 2016). Of patients who received St. John’s Wort over 8 weeks, 14 were deemed improved while 98 did not improve. In contrast 5 patients who received the placebo were deemed improved while 102 did not improve (Table 2).
Table 2. St. John’s Wort and depression
| Improved | Not improved | |
| St. John’s Wort | 14 | 98 |
| Placebo | 5 | 102 |
Note 1: The St. John’s Wort problem is precisely a the time to remind any reader of Mike’s Biostatistics Book: under no circumstances is medical advice implied from my presentation. From the National Center for Complementary and Integrative Medicine: “It has been clearly shown that St. John’s wort can interact in dangerous, sometimes life-threatening ways with a variety of medicines.”
These kinds of problems are direct extensions of our risk analysis work in Chapter 7. Now, instead of simply describing the differences between case and control groups by Relative Risk Reduction or odds ratios, we instruct how to do inference on the risk analysis problems.
Thus, faced with absence of coherent theory as guide, the data themselves can be used (intrinsic model), and at least for now, we can employ the  test.
Note 2: The preferred analysis is to use a logistic regression approach, Chapter 18.3, because additional covariates can be included in the model.
In this lesson we will learn how to extend the analyses of categorical data to cases where we do not have a prior expectation — we use the data to generate the tests of hypotheses. This would be an intrinsic model. One of the most common two-variable categorical analysis involves 2X2 contingency tables. We may have one variable that is the treatment variable and the second variable is the outcome variable. Some examples provided in Table 3.
Table 3. Some examples of treatment and outcome variables suitable for contingency table analysis.
| Treatment Variable and Levels | Outcome Variable(s) | Reference |
| Lead exposure
Levels: Low, Medium, High |
Intelligence and development | Bellinger et al 1987 |
| Wood preservatives
Levels: Borates vs. Chromated Copper Arsenate |
Effectiveness as fungicide | Hrastnik et al 2013 |
| Antidepressants
Levels: St. John’s Wort, conventional antidepressants, placebo |
Depression relief | Linde et al 2008 |
| Coral reefs
Levels: Protected vs Unprotected |
Fish community structure | Guidetti 2006 |
| Aspirin therapy
Levels: low dose vs none |
Cancer incidence in women | Cook et al 2013 |
| Aspirin therapy
Levels: low dose vs none |
Cancer mortality in women | Cook et al 2013 |
Table 4 were examples of published studies returned from a quick PubMed search; there are many examples (meta-analysis opportunities!). However, while they all can be analyzed by contingency tables analysis, they are not exactly the same. In some cases, the treatments are fixed effects, where the researcher selects the levels of the treatments (see Ch12.3 and Ch14.3 for discussion about fixed vs random effects in experimental design).
In other cases, each of these treatment variables need not be actual treatments (in the sense that an experiment was conducted), but it may be easier to think about these as types of experiments. These types of experiments can be distinguished by how the sampling from the reference population were conducted. Before we move on to our main purpose, to discuss how to calculate contingency tables, I wanted to provide some experimental design context by introducing two kinds of sampling (Chapter 5.5).
Our first kind of sampling scheme is called unrestricted sampling. In unrestricted sampling, you collect as many subjects (observations) as possible, then assign subjects to groups. A common approach would be to sample with a grand total in mind; for example, your grant is limited and so you only have enough money to make 1000 copies of your survey and you therefore approach 1000 people. If you categorize the subjects into just two categories (eg, Liberal, Conservative), then you have a binomial sample. If instead you classify the subjects a number of variables, eg, Liberal or Conservative, Education levels, income levels, homeowners or renters, etc., then this approach is called multinomial sampling. The point in either case is that you have just utilized a multinomial sampling approach. The aim is to classify your subjects to their appropriate groups after you have collected the sample.
Logically what must follow unrestricted sampling would be restricted sampling. Sampling would be conducted with one set of “marginal totals” fixed. Margins refers to either the row totals or to the column totals. The sampling scheme is referred to as compound multinomial. The important distinction from the other two types is that the number of individuals in one of the categories is fixed ahead of time. For example, in order to determine if smoking influences respiratory health, you approach as many people as possible to obtain 100 smokers.
The contingency table analysis
We introduced the 2×2 contingency table (Table 4) in Chapter 7.
Table 4. 2X2 contingency table
| Outcome |
|||
| Exposure or Treatment group | Yes | No | Marginal total |
| Exposure (Treatment) | a | b | Row1 = a + b |
| Nonexposure (Control) | c | d | Row2 = c + d |
| Marginal total | Column1 = a + c |
Column2 = a + c |
N |
Contingency tables are all of the form (Table 5)
Table 5. Basic format of a 2X2 table
| Outcome 1 | Outcome 2 | |
| Treatment 1 | Yes | No |
| Treatment 2 | Yes | No |
Regardless of how the sampling occurred, the analysis of the contingency table is the same; mechanically, we have a chi-square type of problem. In both contingency table and the “goodness of fit” Chi-Square analyses the data types are discrete categories. The difference between GOF and contingency table problems is that we have no theory or external model to tell us about what to expect. Thus, we calculate expected values and the degrees of freedom differently in contingency table problems. To learn about how to perform contingency tables we will work through an example, first the long way, and then using a formula and the a, b, c, and d 2X2 table format. Of course, R can easily do contingency tables calculations for us.
Doctors noticed that a new form of Hepatitis (HG, now referred to as GB virus C), was common in some HIV+ populations (Xiang et al 2001). Accompanying the co-infection, doctors also observed an inverse relationship between HG loads and HIV viral loads: patients with high HG titers often had low HIV levels. Thus, the question was whether co-infection alters the outcome of patients with HIV — do HIV patients co-infected with this HG progress to AIDS and mortality at rates different from non-infected HIV patients? I’ve represented the Xiang et al (2001) data in Table 6.
Table 6. Progression of AIDS for patients co-infected with HG [GB virus C], Xiang et al data (2001)
| Lived | Died | Row totals | |
| HG+ | 103 | 41 | 144 |
| HG- | 95 | 123 | 218 |
| Column totals | 198 | 164 | 362 |
Note 3: HG virus is no longer called a hepatitis virus, but instead is referred to as GB virus C, which, like hepatitis viruses, is in the Flaviviridae virus family. For more about the GB virus C, see review article by Bhattarai and Stapleton (2012).
Our question was: Do HIV patients co-infected with this HG progress to AIDS and mortality at rates different from non-infected HIV patients? A typical approach to analyze such data sets is to view the data as discrete categories and analyze with a contingency table. So we proceed.
Setup the table for analysis
Rules of contingency tables (see Kroonenberg and Verbeek 2018). What follows is a detailed walk through setting up and interpreting a 2X2 table. Note that I maintain our a, b, c, d cell order, with row 1 referencing subjects exposed or part of treatment group and row 2 referencing subjects not exposed (or part of the control group), as introduced in Chapter 7.
The Hepatitis G data from Xiang et al 2001 data, arranged in 2X2 format (Table 7).
Table 7. Format of 2X2 table Xiang et al (2001) dataset.
| Lived | Died | Row totals | |
| HG+ | a | b | a + b |
| HG- | c | d | c + d |
| Column totals | a + c | b + d | N |
The data are placed into the cells labeled a, b, c, and d.
Cell a : The number of HIV+ individuals infected with HG that lived beyond the end of the study.
Cell b : The number of HIV+ individuals infected with HG that died during the study.
Cell c : The number of HIV+ individuals not infected with HG that lived.
Cell d : The number of HIV+ individuals not infected with HG that died.
This is a contingency table because the probability of living or dying for these patients may have been contingent on coinfection with hepatitis G.
State the examined hypotheses
HO: There is NO association between the probability of living and coinfection with hepatitis G.
For a contingency table this means that there should be the same proportion of individuals with and without hepatitis G that either lived or died (1:1:1:1).
Now, compute the Expected Values in the Four cells (a, b, c, d)
- Calculate the Expected Proportion of Individuals that lived in Entire Sample:
Column 1 Total / Total = Expected Proportion of those that lived beyond the study. - Calculate Expected Proportion of Individuals that died in Entire Sample:
Column 2 Total / Total = Expected Proportion that died during the study. - Calculate the Expected Proportion of Individuals that lived and were HG+
Expected Proportion of living (step 1 above) x Row 1 Total = Expected For Cell A. - Calculate the Expected Proportion of Individuals that died and were HG+
Expected Proportion died x Row 1 Total = Expected For Cell B - Calculate the Expected Proportion of surviving individuals that were HG-
Expected Proportion lived x Row 2 Total = Expected For Cell C - Calculate the Expected Proportion of individuals that died that were HG-
Expected Proportion that died x Row 2 Total = Expected For Cell D
Yes, this can get a bit repetitive! But, we are now done — remember, we’re working through this to review how the intrinsic model is applied to obtain expected values.
To summarize what we’ve done so far, we now have
Observations arranged in a 2X2 table
Calculated the expected proportions, ie, the Expected values under the Null Hypothesis.
Now, we proceed to conduct the chi-square test of the null hypothesis — The observed values may differ from these expected values, meaning that the Null Hypothesis is False.
Table 8. Copy Table 6 data set
| Lived | Died | Row totals | |
| HG+ | 103 | 41 | 144 |
| HG- | 95 | 123 | 218 |
| Column totals | 198 | 164 | 362 |
Get the Expected Values
- Calculate the Expected Proportion of Individuals that lived in Entire Sample:
Column 1 Total (198) / Total (362) = 0.5470 - Calculate Expected Proportion of Individuals that died in Entire Sample:
Column 2 Total (164) / Total (362) = 0.4530 - Calculate the Expected Proportion of Individuals that lived and were HG+
Expected Proportion of living (0.547) x Row 1 Total (218) = Cell A = 119.25 - Calculate the Expected Proportion of Individuals that died and were HG+
Expected Proportion died (0.453) x Row 1 Total (218) = Cell B = 98.75. - Calculate the Expected Proportion of surviving individuals that were HG-
Expected Proportion lived (0.547) x Row 2 Total (144) = Cell C = 78.768 - Calculate the Expected Proportion of individuals that died that were HG-
Expected Proportion that died 0(.453) X Row 2 Total = Cell D = 65.232
Thus, we have (Table 9)
Table 9. Expected values for Xiang et al (2001) data set (Table 6 and Table 8)
| Lived | Died | Row totals | |
| HG+ | 78.768 | 65.232 | 144 |
| HG- | 119.25 | 98.75 | 218 |
| Column totals | 198 | 164 | 362 |
Now we are ready to calculate the Chi-Square Value
Recall the formula for the chi-square test
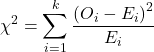
Table 10. Worked contingency table for Xiang et al (2001) data set (Table 6 and Table 8)
| Cell |  |
|
| a | (103 – 87.768)2 = 78.768 | 7.4547 |
| b | (41 – 65.232)2 = 65.232 | 9.002 |
| c | (95 – 119.25)2 = 119.25 | 4.93134 |
| d | (123 – 98.75)2 = 98.75 | 5.95506 |
 |
27.3452 |
Adding all the parts we have the chi-square test statistic 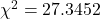 . To proceed with the inference, we test using the chi-square distribution.
Determine the Critical Value of  test and evaluate the null hypothesis
Now recall that we can get the critical value of this test in one of two (related!) ways. One, we could run this through our statistical software and get the p-value, the probability of our result and the null hypothesis is true. Second, we look up the critical value from an appropriate statistical table. Here, we present option 2.
We need the Type I error rate α and calculate the degrees of freedom for the problem. By convention, we set α = 0.05. Degrees of freedom for contingency table is calculated as
Degrees of Freedom = (# rows – 1) x (# columns – 1)
and for our example → DF = (2 – 1) x (2 – 1) = 1.
Note. How did we get the 1 degree of freedom? Aren’t there 4 categories and shouldn’t we therefore have k – 1 = 3 df? We do have four categories, yes, but the categories are not independent. We need to take this into account when we evaluate the test and this lack of independence is accounted for by the loss of degrees of freedom.
What exactly is not independent about our study?
-
- The total number of observations is set in advance from the data collection.
- We also have the column and row totals set in advance. The number of HIV individuals with or without Hepatitis G infection was determined at the beginning of the experiment. The number of individuals that lived or died was also determined before we we conducted the test.
- Then the first cell (let us make that cell A) can still vary anywhere from 0 to N i (sample size of the first drug).
- Once the first cell (A) is determined then the next cell in that row (B) will have to add up to N i.
- Also the other cell in the same column as the first cell (C) must add up to the Column 1 Total.
- Lastly, the last cell (D) must have the Row 1 Total add up to the correct number.
All this translates into there being only one cell that is FREE TO VARY, hence, only one degree of freedom.
Get the Critical Value from a chi-square distribution table: For our example, look up the critical value for DF = 1, α = 0.05, you should get 3.841. The 3.841 is the value of the chi-square we would expect at 5% and the null hypothesis is in fact true condition in the population.
Once we obtain the critical value we simply use the previous statement regarding the probability of the Null Hypothesis being TRUE. We Reject the Null Hypothesis when the calculated test statistic is greater than the Critical Value. We Accept the Null Hypothesis when the calculated is less than the Critical Value. In our example we got 27.3452 for our calculated test statistic, thus we reject the null hypothesis and conclude, that, at least for the sample in this study, there was an association between the probability of patients living past the study period and the presence of hepatitis G.
from a, b, c, and d 2X2 table format formula
If a hand calculation is required, a simpler formula to use is
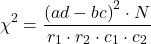
where N is the sum of all observations in the table, r1 and r2 are the marginal row totals, and c1 and c2 are the marginal column totals from the 2×2 contingency table (eg, Table 4). If you are tempted to try this in a spreadsheet, and assuming your entries for a, b, c, d, and N look like Table 11, then a straightforward interpretation requires referencing five spreadsheet cells no less than 13 times! Not to mention a separate call to the distribution to calculate the p-value (one tailed test).
Note 4: This formulation was provided as equation 1 in Yates 1984 (referred to in Serra 2018), but is likely found in the earlier papers on dating back to Pearson.
Table 11. Example spreadsheet with formulas for odds ratio (OR), Pearson’s , and p-value from distribution.
| A | B | C | D | E | F | G | |
| 1 | |||||||
| 2 | a | 103 | OR | =( 2*5)/(3*4) |
|||
| 3 | b | 41 | |||||
| 4 | c | 95 | |||||
| 5 | d | 123 | chisq, p | =(((2*5-3*4)^2)*6)/ (SUM( 2:3)*SUM(4:5)*SUM( 2,4)*SUM(3,5)) |
=CHIDIST(F5,1) | ||
| 6 | N | 632 |
Now, let’s see how easy this is to do in R.
effect size
Inference on hypotheses about association, there’s statistical significance — evaluate p-value compared to Type I error, eg, 5% — and then there’s biological importance, the strength of the association. The concept of effect size is an attempt to communicate the likely importance of a result. Several statistics are available to communicate effect size: for that’s φ, phi for the φ (phi) coefficient.

where N is the total. Phi for our example is
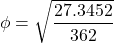
R code
sqrt(27.3452/362)
and R returns
[1] 0.274844
Effect size statistics typically range from 0 to 1; Cohen (1992) suggested the following interpretation
Table 12. Cohen’s interpretation of d values.
| Effect size | Interpretation |
| < 0.2 | Small, weak effect |
| 0.5 | Moderate effect |
| > 0.8 | Large effect |
For our example,  effect size of the association between co-infection with GB virus C and mortality was weak in the patients with HIV infection. The function
phi() in psych package will calculate phi coefficient from a 2X2 table.
Agreement, kappa, and inter-rater reliability
I imagine by now you have made the leap — can we use the contingency table to assess agreement between (inter-) two judges (raters) who evaluate the same object? A naive approach would be to calculate simple agreement, the percent of objects in the list of items evaluated for which both judges agree (concur). For a binomial Yes or No, then agreement (concordance) occurs when both judges report “Yes,” or both report “No,” displayed on the main diagonal of the 2X2 table. The other possible combinations (Yes vs No and No vs Yes) are disagreement (discordance) and would be displayed on the off-diagonal of the 2X2 matrix.
Unfortunately, simple agreement, while intuitive, cannot discriminate between true agreement and agreement by chance. Cohen’s kappa (Cohen 1960, McHugh 2012) is used to assess agreement, aka inter-rater reliability, for binomial and nominal data types for two judges (raters). Cohen’s 1960 paper has been enormously impactful, with more than 53K citations (Google Scholar, Fall 2024), and spawned a number of additional measures of agreement, eg, weighted kappa for more than binomial levels, Fleiss kappa for three or more raters, ICC for ratio scale, discussed in Ch12.3). It’s beyond the scope of this text to review the context of such terms as agreement, and reliability, for just two terms used to evaluate results from two independent observers of the “same” event or object, and leave that to the reader to confirm how to report such endeavors.
Off we go. Cohen’s kappa is defined as

where po is the proportion in agreement and pc is proportion of agreement expected by chance. Essentially, then, interpretable kappa values fall between 0 and 1 (0% to 100%); negative kappa estimates are possible. Cohen (1960) noted that for kappa to equal 1, the off diagonal elements would all have to be zero.
Cohen provided an estimate of the standard error for kappa as
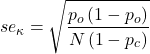
and 95% confidence intervals are then  .
Here, we review calculation of simple agreement and Cohen’s kappa, with just the two levels. Both simple agreement and Cohen’s kappa (κ), are available in R via the icc package. Cohen’s kappa is also available in the psych package, with the cohen.kappa() function providing a confidence interval estimate directly.
Note 5: Base R includes the function kappa(), but that returns an estimate for the condition number of the matrix, or how close to singular the matrix solution may be, ie, determinant is zero and its inverse is unavailable.
Use of both is illustrated here with a simulated coin toss example modified from a nice 2018 summary of Cohen’s kappa at r-bloggers. The R code
library(irr)
# simulate some data
N = 24
flips1 <- rbinom(n = N, size = 1, prob = 0.5)
flips2 <- rbinom(n = N, size = 1, prob = 0.5)
coins<-cbind(flips1, flips2)
Confirm the data set.
head(coins)
flips1 flips2
[1,] 0 1
[2,] 1 0
[3,] 1 0
[4,] 1 1
[5,] 0 0
[6,] 1 0
and create a 2X2 table.
I stacked the data
head(StackedCoin)
Side Coins    HT
1 0 flips1 tails
2 1 flips1 heads
3 1 flips1 heads
4 1 flips1 heads
5 0 flips1 tails
6 1 flips1 heads
then created a simple 2×2 table (see Note 6 below for a simple explanation for why “.Table” as a named object).
.Table <- xtabs(~Coins+HT, data=StackedCoin)
Table 13. coins as 2X2 table.
| tails | heads | |
| flips1 | 10 | 14 |
| flips2 | 14 | 10 |
We can calculate the phi coefficient for Table 13.
phi(.Table, digits = 3)
[1] -0.167
and would conclude no correlation between the two sets of coin tosses.
Now, agreement statistics. Both agree() and kappa2() expect an unstacked (wide) data format. It’s not necessary, but we’ll call a value of 1 as “heads up” and a value of 0 as “tails up” of the tossed coin.
Next, simple agreement.
agree(coins, tolerance=0)
R returns
Subjects = 24
Raters = 2
%-agree = 41.7
Now, a proper agreement statistic.
kappa2(coins)
and R returns
Subjects = 24
Kappa = -0.135
z = -0.7
p-value = 0.484
Results with psych:cohen.kappa, which provides the 95% confidence interval as default output.
Cohen Kappa and Weighted Kappa correlation coefficients and confidence boundaries
                 lower estimate upper
unweighted kappa -0.51    -0.14  0.24
weighted kappa   -0.51    -0.14  0.24
Number of subjects = 24
By chance, the two independent toss of 24 coins had 10 rows of “agreement” (H:H or T:T), simply due to chance. However, results of kappa find no agreement between the two sets of coin tosses.
In summary, we see that simple agreement and the kappa statistic don’t return similar results. Percent agreement reported 41%, whereas kappa was zero. We know percent agreement can’t reflect anything in the coin toss case because each toss is independent from the next. We’ll have you explore repeated trials of coin tosses to help convince you that simple agreement is not a reliable measure of agreement (see question 6 below).
Interpreting agreement values is not straightforward, and some argue agreement statistics should be avoided in favor of disagreement measures (for example, see discussion in Pontius and Millones 2011). Cohen suggested (Table 14)
Table 14. Landis and Koch’s (1977) interpretation of Cohen’s kappa.
| Cohen’s kappa | Agreement? |
| < 0 | none |
| 0.01 — 0.20 | slight |
| 0.21 — 0.40 | fair |
| 0.41 — 0.60 | moderate |
| 0.61 — 0.80 | substantial |
| 0.81 — 1 | nearly perfect |
Note 6: Wikipedia page for Cohen’s kappa suggests that this interpretation began with the Landis and Koch 1997 paper in the journal Biometrics. I haven’t confirmed this — regardless, this paper is also highly influential, with more than 89K citations (Fall 2024).
Even a cursory look at Table 14 should lead to questions about scenarios in which a range of agreement “substantial” would provide little comfort about the agreement between the judges or the reliability of the instrument used, for example forensic cases or histology of tissue biopsies.
Contingency table analyses in Rcmdr
Assuming you have already summarized the data, you can enter the data directly in the Rcmdr contingency table form. If your data are not summarized, then you would use Rcmdr's Two-way table… for this. We will proceed under the assumption that you have already obtained the frequencies for each cell in the table.
Rcmdr: Statistics → Contingency tables → Enter and analyze two-way table…
Here you can tell R how many rows and how many columns (Fig 1).
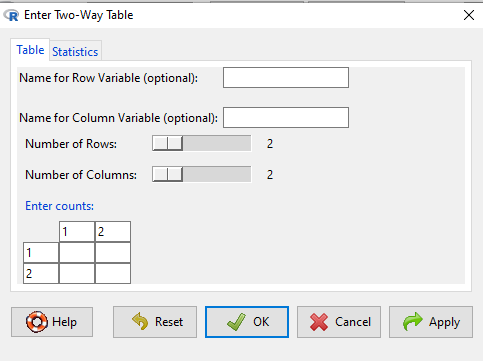
Figure 1. Screenshot R Commander menu for 2X2 data entry with counts.
The default is a 2X2 table. For larger tables, use the sliders to increase the number of rows, columns, or both.
Next, enter the counts. You can edit every cell in this table, including the headers. In the next panel, I will show you the data entry and options. The actual calculation of the test statistic is done when you select the “Chi-square test of independence” check-box (Fig 2).
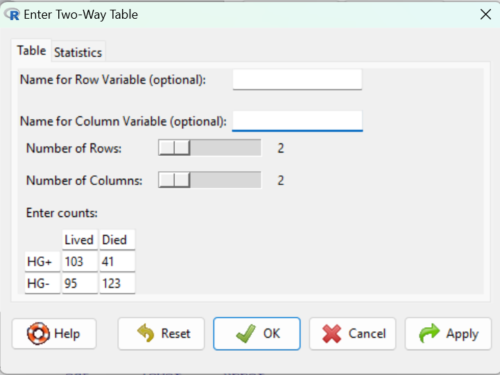
Figure 2. Display of Xiang et al data entered into R Commander menu.
After entering the data, click on the Statistics tab (Fig 3).
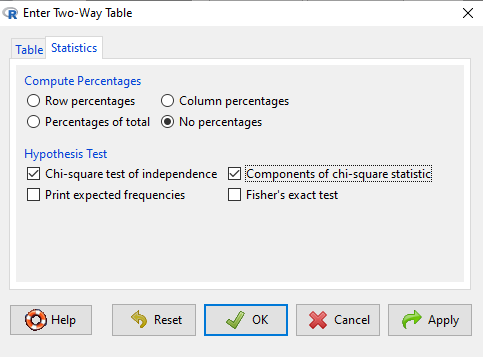
Figure 3. Screenshot Statistics options for contingency table.
If you also select “Components of chi-square statistic” option, then R will show you the contributions of each cell (O-E) towards the chi-square test statistic value. This is helpful to determine if rejection of the null is due to a subset of the categories, and it also forms the basis of the heterogeneity tests, a subject we will pick up in the next section.
Here’s the R output from R Commander. Note the “2, 2, byrow=TRUE” instructions (check out R help to confirm what
.Table <- matrix(c(103,41,95,123), 2, 2, byrow=TRUE)
dimnames(.Table) <- list("rows"=c("HG+", "HG-"), "columns"=c("Lived", "Died"))

.Table # Counts
     columns
rows Lived Died
 HG+   103   41
 HG-   95   123

.Test <- chisq.test(.Table, correct=FALSE)
.Test

Pearson's Chi-squared test

data: .Table
X-squared = 27.339, df = 1, p-value = 0.0000001708

round(.Test$residuals^2, 2) # Chi-square Components
    columns
rows Lived Died
HG+   7.46 9.00
HG-   4.93 5.95

remove(.Test)
remove(.Table)
end R output.
Note 7: R Commander often cleans up after itself by removing objects like .Test and .Table. This is not necessary for the code to work, but does make it easier for you to go back and modify the code without worrying about confusing objects.
Lots of output, take a deep breath and remember… The minimum output we need to look at is… (Table 15)?
Table 15. Minimally expected outcome for report from a statistical test.
| Value of the test statistic | 27.339 |
| Degrees of freedom | 1 |
| p-value | 0.0000001708 |
We can see that the p-value 1.7-7 is much less than Type 1 α = 0.05, thus, by our decision criterion we reject the null hypothesis (provisionally of course, as science goes).
Note 7: Simple enough to get R to report numbers as you need. For example, R code
myNumber = 0.0000001708
format(myNumber, scientific = TRUE, digits=2)
returns
[1] "1.7e-07"
Questions
- Instead of R Commander, try the contingency table problem in R directly.
myData <- matrix(c(103,41,95,123))
chisq.test(myData)
Is this the correct
contingency table analysis? Why or why not? - For many years National Football League games that ended in ties went to “sudden death,” where the winner was determined by the first score in the extra period of play, regardless of whether or not the other team got an opportunity to possess the ball on offense. Thus, in more than 100 games (140), the team that won the coin toss and therefore got the ball first in overtime, won the game following either a kicked field goal or after a touchdown was scored. In 337 other games under this system, the outcome was not determined by who got the ball first. Many complained that the “sudden death” format was unfair and in 2013 the NFL changed its overtime rules. Beginning 2014 season, both teams got a chance to possess the ball in overtime, unless the team that won the coin toss also went on to score a touchdown at which time that team would be declared the winner. In this new era of over-time rules ten teams that won the coin toss went on to score a touchdown in their first possession and therefore win the game, whereas in 54 other overtime games, the outcome was decided after both teams had a chance on offense (data as of 1 December 2015). These data may be summarized in the table
First possession win? Yes No Coin flip years 140 337 New era 10 54 A. What is the null hypothesis?
B. Which is more appropriate: to calculate an odds ratio or to calculate an RRR?
C. This is a contingency table problem. Explain why
D. Conduct the test of the null hypothesis.
E. What is the value of the test statistic? Degrees of freedom? P-value?
F. Evaluate the results of your analysis — do you accept or reject the null hypothesis? - Return to the Doll and Hill (1950) data: 2 men with lung cancer were nonsmokers, 647 men with lung cancer were cigarette smokers. In comparison, 27 case-control patients (ie, patients in the hospital but with other ailments, not lung cancer) were nonsmokers, but 622 were cigarette smokers.
A. What is the null hypothesis?
B. Which is more appropriate: to calculate an odds ratio or to calculate an RRR?
C. This is a contingency table problem. Explain why
D. Conduct the test of the null hypothesis.
E. What is the value of the test statistic? Degrees of freedom? P-value?
F. Evaluate the results of your analysis — do you accept or reject the null hypothesis? - A more recent example from the study of the efficacy of St John’s Wort as a treatment for major depression (Shelton et al 2001). Of patients who received St. John’s Wort over 8 weeks, 14 were deemed improved while 98 did not improve. In contrast 5 patients who received the placebo were deemed improved while 102 did not improve.
A. What is the null hypothesis?
B. Which is more appropriate: to calculate an odds ratio or to calculate an RRR?
C. This is a contingency table problem. Explain why
D. Conduct the test of the null hypothesis.
E. What is the value of the test statistic? Degrees of freedom? P-value?
F. Evaluate the results of your analysis — do you accept or reject the null hypothesis? - Return to the coin toss simulation and repeat comparisons between simple agreement and Cohen’s kappa for different values of N. Do you see any trend(s) for the two measures as sample size increases or decreases?
- Repeat the coin toss simulation for N = 24 up to five times, each time calculate simple agreement and Cohen’s kappa. Provide a table of your five results plus the example, and generalize simple agreement vs Cohen’s kappa as a reliable measure of agreement. Hint: you may want to use Descriptive statistics to help make your case.
Quiz Chapter 9.2
Chi-square contingency tables