19.3 — Monte Carlo methods
edits: — under construction —
Introduction
Statistical method that employ Monte Carlo methods use repeated random sampling to estimate properties of a frequency distribution. These distributions may be well-known, e.g., gamma-distribution, normal distribution, or t-distribution, or . The simulation is based on generation of a set of random numbers on the open interval (0,1) — the set of real numbers between zero and one (all numbers greater than 0 and less than 1).
If the set included 0 and 1, then it would be called a closed set, i.e., the set includes the boundary points zero and one.
Markov chain Monte Carlo (MCMC) sampling approach used to solve large scale problems. The Markov chain refers to how the sample is drawn from a specified probability distribution. It can be drawn by discrete time steps (DTMC) or by a continuous process (CTMC). The Markov process is “memoryless:” predictions of future events are derived solely from their present state — the future and past states are independent.
Gibbs sampling is a common MCMC algorithm.
ccc
R code
R’s uniform generator is runif function. Examples of the samples generated over different values (100, 1000, 10000, 100000) with output displayed as histograms (Fig. 1). Note that as sample size increases, the simulated distributions resemble more and more the uniform distribution. Use set.seed() to reproduce the same set and sequence of numbers
require(RcmdrMisc)
par(mfrow = c(2, 2))
myUniformH <- data.frame(runif(100))
with(myUniformH, Hist(runif.100., scale="frequency", ylim=c(0,20), breaks="Sturges", col="red", xlab="100 samples", ylab="Count"))
myUniform1K <- data.frame(runif(1000))
with(myUniform1K, Hist(runif.1000., scale="frequency", ylim=c(0,150), breaks="Sturges", col="green", xlab="1K samples", ylab="Count"))
myUniform10K <- data.frame(runif(10000))
with(myUniform10K, Hist(runif.10000., scale="frequency", ylim=c(0,600), breaks="Sturges", col="lightblue", xlab="10K samples", ylab="Count"))
myUniform100K <- data.frame(runif(100000))
with(myUniform100K, Hist(runif.100000., scale="frequency", ylim=c(0,5000),breaks="Sturges", col="blue", xlab="100K samples", ylab="Count"))
#reset par()
dev.off()
Yes, a nice repeating function would be more elegant code, but we move on. As a suggestion, you should create one! Use sapply() or a basic for loop.
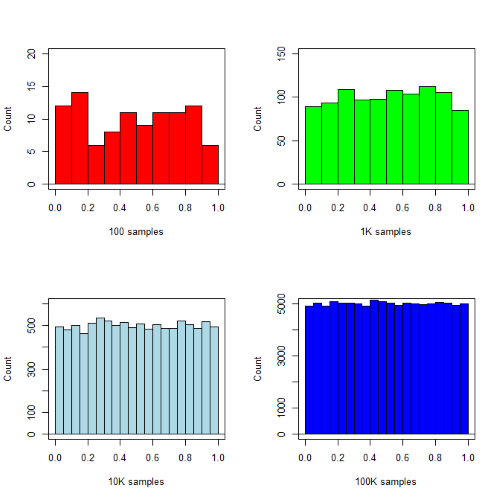
Figure 1. Histograms of runif results with 100, 1K, 10K, and 100K numbers of values to be generated
Looks pretty uniform. A property of random numbers is that history should not influence the future, i.e., no autocorrelation. We can check using the acf() function (Fig. 2).
par(mfrow = c(2, 2))
acf(myUniformH, main="100")
acf(myUniform1K, main="1K")
acf(myUniform10K, main="10K")
acf(myUniform100K, main="100K"
dev.off()
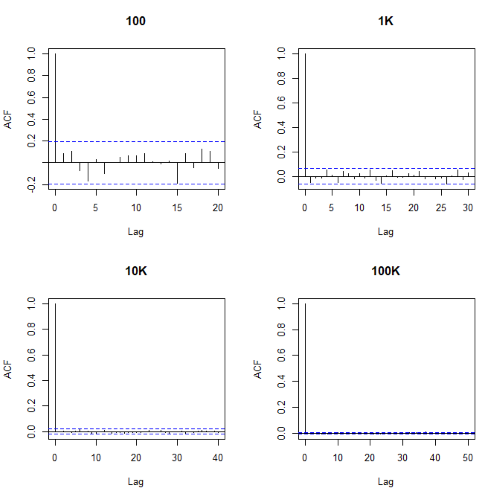
Figure 2. Autocorrelation plots of runif results with 100, 1K, 10K, and 100K numbers of values
Correlations among points are plotted versus lag, where lag refers to the number of points between adjacent points, e.g., lag = 10 reflects the correlation among points 1 and 11, 2 and 12, and so forth. The band defined by two parallel blue dashed lines
Questions
- Use
set.seed(123)and repeatrunif(10)twice. Confirm that the two sets are different (do not set seed) or the same whenset.seedis used. R hint: use functionidentical(x,y), where x and y are the two generated samples. This function tests whether the values and sequence of elements are the same between the two vectors.
Chapter 19 contents
- Introduction
- Jackknife sampling
- Bootstrap sampling
- Monte Carlo methods
- Ch19 References and suggested readings
19.2 – Bootstrap sampling
Introduction
Bootstrapping is a general approach to estimation or statistical inference that utilizes random sampling with replacement (Kulesa et al. 2015). In classic frequentist approach, a sample is drawn at random from the population and assumptions about the population distribution are made in order to conduct statistical inference. By resampling with replacement from the sample many times, the bootstrap samples can be viewed as if we drew from the population many times without invoking a theoretical distribution. A clear advantage of the bootstrap is that it allows estimation of confidence intervals without assuming a particular theoretical distribution and thus avoids the burden of repeating the experiment.
Base install of R includes the boot package. The boot package allows R users to work with most functions, and many authors have provided helpful packages. I highlight a couple packages
install packages lmboot, confintr
Example data set, Tadpoles from Chapter 14, copied to end of this page for convenience (scroll down or click here).
Bootstrapped 95% Confidence interval of population mean
Recall classic frequentist (large-sample) approach to confidence interval estimates of mean by R
x = round(mean(Tadpole$Body.mass),2); x
n = length(Tadpole$Body.mass); n
s = sd(Tadpole$Body.mass); s
error = qt(0.975,df=n-1)*(s/sqrt(n)); error
lower_ci = round(x-error,3)
upper_ci = round(x+error,3)
paste("95% CI of ", x, " between:", lower_ci, "&", upper_ci)
Output results are
> n = length(Tadpole$Body.mass); n
[1] 13
> s = sd(Tadpole$Body.mass); s
[1] 0.6366207
> error = qt(0.975,df=n-1)*(s/sqrt(n)); error
[1] 0.384706
> paste("95% CI of ", x, " between:", lower_ci, "&", upper_ci)
[1] "95% CI of 2.41 between: 2.025 & 2.795"
We used the t-distribution because both  the population mean and
 the population standard deviation were unknown. Thus, 95 out of 100 confidence intervals would be expected to include the true value.
Bootstrap equivalent
library(confintr)
ci_mean(Tadpole$Body.mass, type=c("bootstrap"), boot_type=c("stud"), R=999, probs=c(0.025, 0.975), seed=1)
Output results are
Two-sided 95% bootstrap confidence interval for the population mean based on 999 bootstrap replications
and the student method

Sample estimate: 2.412308
Confidence interval:
    2.5%    97.5%
2.075808 2.880144
where stud is short for student t distribution (another common option is the percentile method — replace stud with perc), R = 999 directs the function to resample 999 times. We set seed=1 to initialize the pseudorandom number generator so that if we run the command again, we would get the same result. Any integer number can be used. For example, I set seed = 1 for output below
Confidence interval:
    2.5%    97.5%
2.075808 2.880144
compared to repeated runs without initializing the pseudorandom number generator:
Confidence interval:
    2.5%    97.5%
2.067558 2.934055
and again
Confidence interval:
    2.5%    97.5%
2.067616 2.863158
Note that the classic confidence interval is narrower than the bootstrap estimate, in part because of the small sample size (i.e., not as accurate, does not actually achieve the nominal 95% coverage). Which to use? The sample size was small, just 13 tadpoles. Bootstrap samples were drawn from the original data set, thus it cannot make a small study more robust. The 999 samples can be thought as estimating the sampling distribution. If the assumptions of the t-distribution hold, then the classic approach would be preferred. For the Tadpole data set, Body.mass was approximately normally distributed (Anderson-Darling test = 0.21179, p-value = 0.8163). For cases where assumption of a particular distribution is unwarranted (e.g., what is the appropriate distribution when we compare medians among samples?), bootstrap may be preferred (and for small data sets, percentile bootstrap may be better). To complete the analysis, percentile bootstrap estimate of confidence interval are presented.
The R code
ci_mean(Tadpole$Body.mass, type=c("bootstrap"), boot_type=c("perc"), R=999, probs=c(0.025, 0.975), seed=1)
and the output
Two-sided 95% bootstrap confidence interval for the population mean based on 999 bootstrap replications
and the percent method
Sample estimate: 2.412308
Confidence interval:
    2.5%    97.5%
2.076923 2.749231
In this case, the bootstrap percentile confidence interval is narrower than the frequentist approach.
Model coefficients by bootstrap
R code
Enter the model, then set B, the number of samples with replacement.
myBoot <- residual.boot(VO2~Body.mass, B = 1000, data = Tadpoles)
R returns two values:
bootEstParam, which are the bootstrap parameter estimates. Each column in the matrix lists the values for a coefficient. For this model,bootEstParam$[,1]is the intercept andbootEstParam$[,2]is the slope.origEstParam, a vector with the original parameter estimates for the model coefficients.seed, numerical value for the seed; use seed number to get reproducible results. If you don’t specify the seed, then seed is set to pick any random number.
While you can list the $bootEstParam, not advisable because it will be a list of 1000 numbers (the value set with B)!
Get necessary statistics and plots
#95% CI slope
quantile(myBoot$bootEstParam[,2], probs=c(.025, .975))
R returns
    2.5%    97.5%
335.0000 562.6228
#95% CI intercept
quantile(myBoot$bootEstParam[,1], probs=c(.025, .975))
R returns
     2.5%     97.5%
-881.3893 -310.8209
Slope
#plot the sampling distribution of the slope coefficient
par(mar=c(5,5,5,5)) #setting margins to my preferred values
hist(myBoot$bootEstParam[,2], col="blue", main="Bootstrap Sampling Distribution",
xlab="Slope Estimate")
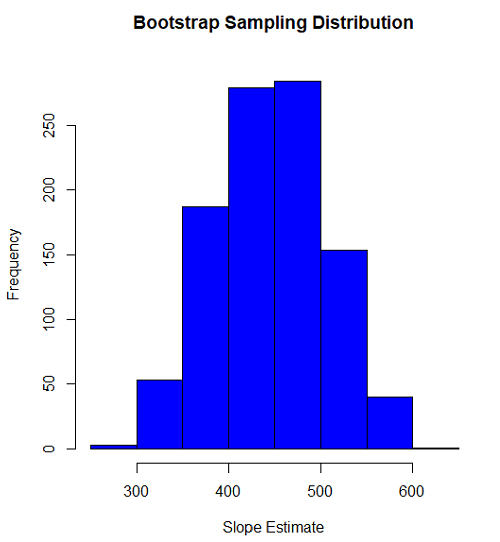
Figure 1. histogram of bootstrap estimates for slope
Intercept
#95% CI intercept
quantile(myBoot$bootEstParam[,1], probs=c(.025, .975))
par(mar=c(5,5,5,5))
hist(myBoot$bootEstParam[,1], col="blue", main="Bootstrap Sampling Distribution",
xlab="Intercept Estimate")
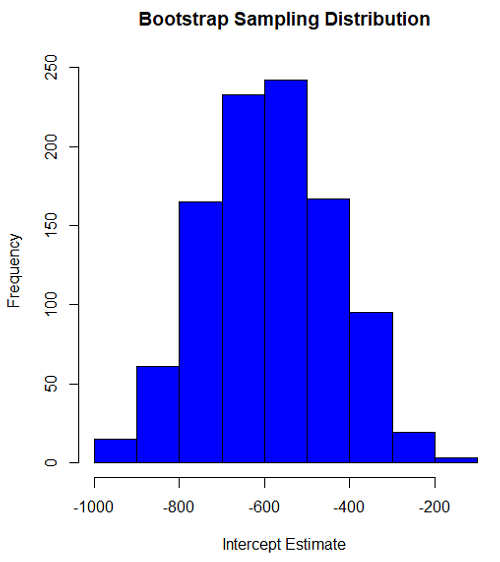
Figure 2. Histogram of bootstrap estimates for intercept.
Questions
edits: pending
Data set used this page (sorted)
| Gosner | Body mass | VO2 |
| I | 1.76 | 109.41 |
| I | 1.88 | 329.06 |
| I | 1.95 | 82.35 |
| I | 2.13 | 198 |
| I | 2.26 | 607.7 |
| II | 2.28 | 362.71 |
| II | 2.35 | 556.6 |
| II | 2.62 | 612.93 |
| II | 2.77 | 514.02 |
| II | 2.97 | 961.01 |
| II | 3.14 | 892.41 |
| II | 3.79 | 976.97 |
| NA | 1.46 | 170.91 |
Chapter 19 contents
- Introduction
- Jackknife sampling
- Bootstrap sampling
- Monte Carlo methods
- Ch19 References and suggested readings
10.3 – Paired t-test
Introduction
Good experiments include controls. Interested in a new treatment for weight loss? Define a control group to compare the weight loss by a group using the new product. In many cases, the best control is the individual.
Consider now a basic experimental design, the randomized crossover trial (Fig 1), introduced in Chapter 2.4.
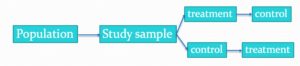
Figure 1. A two group Randomized Crossover Trial.
Subjects randomly selected from population of interest, then again once recruited into one of two treatment arms: arm 1, subjects first receive the experimental treatment, then some time later the subjects receive the control treatment; arm 2, subjects first receive the control treatment, then some time later the subjects receive the experimental treatment. Note the difference between this paired or repeated measures design and the independent sample design (see Chapter 10.1). Repeated measures designs have many advantages; we discuss them further in Chapter 14.6. At the start, repeated measures designs have greater statistical power compared to cross-sectional (independent) sample designs.
Many experiments are designed so that subjects receive all treatments and responses are gauged against the initial values recorded on the subjects. Repeated measures statistical tests, like the paired t-test, are needed however to analyze the data. These types of statistical procedures are similar to the two sample independent t-test that we discussed earlier.
However, there is an important difference between these two types of statistical procedures. For the two independent sample t-test the samples are unpaired: we observed one variable on some individuals assigned to two different groups. These groups might be
- Two locations where we measure plants or animals
- A treatment (or experimental) group with a control group.
- Expression of cytokeratin genes (eg, ΔΔCT, fold-change) from breast cancer patients compared to healthy donor subjects (Andergassen et al 2016).
The point is that samples in one group are not the same samples in the second group.
In the paired t-test we have two groups but the observations in these two groups are paired. Paired means that there is some relationship between one observation in the first sample and one observation in the second sample (every observation in one sample must be paired with one observation in another sample).
For example, weight change in humans before and after a change in diet could be performed as a paired analysis. Each subject’s weight before the diet was “paired” with the same subject’s weight after the diet.
Another example comes from genetics. Siblings or Monozygotic twins or clones, strains or varieties of plants or animals can be Paired in an experiment.
- You can give one of the twins a particular diet, or the plant or animal clones or strains can be raised in a particular environment (nutrient)
- The other twin or plant or animal clone or variety can serve as a type of control by providing a normal diet or normal environment.
Another example is a study of environmental pollution on cancer rates in many different communities.
- The researchers selects pairs of communities with similar characteristics for many socioeconomic factors.
- Each pair of communities differed with respect to the proximity to a known source of pollution: one of the pair was close to a source of pollution and one of the pair was far from a source of pollution.
The purpose of pairing in this example is to attempt to “control” for all the socioeconomic factors that might contribute to cancer but they did not want to directly measure. These other factors should be similar for each member of the pair.
Example: How repeatable is human running performance?
The subheading is misleading — we leave “repeatability” or, do individuals perform consistently to another time (see Chapter 12.3 – Fixed effects, random effects, and agreement). Here, we focus on a different question — we test whether mean performance differs across repeated trials. This may seem a subtle difference, but consistency asks the question if performance, whether it is answering questions on an exam or running times for a race, is stable across trials. Testing the means of first and second trials asks a different question: we test for a trend in performance, which may reflect learning.
Here’s an example in which a measure was taken twice for the same individuals. The data are running speed or pace during 5K race held annually on Oahu for a selected sample of female runners with repeat race times (20 – 29 years old). The race was run annually on Oahu, and the data reported are the pace for the first race and the second race, which occurred a year later (Jamba Juice – Banana Man Chase, Ala Moana Beach Park, data extracted from source, https://timelinehawaii.com).
Table 1. 5K pace times (kph) for 15 women (20 – 29 years)
| ID | First race | Second race |
|---|---|---|
| 1 | 15.28 | 15.61 |
| 2 | 11.22 | 11.19 |
| 3 | 8.80 | 9.14 |
| 4 | 8.88 | 5.46 |
| 5 | 9.81 | 10.50 |
| 6 | 6.12 | 5.69 |
| 7 | 8.31 | 8.71 |
| 8 | 6.26 | 7.42 |
| 9 | 17.16 | 16.41 |
| 10 | 16.23 | 15.82 |
| 11 | 5.90 | 7.12 |
| 12 | 8.31 | 10.48 |
| 13 | 5.93 | 8.64 |
| 14 | 10.54 | 5.99 |
| 15 | 9.53 | 8.69 |
Note 1: We’ll return to this data set in Chapter 15.3
Load the data into R as an unstacked data set. Data available at end of this page or click here.
Begin with description and exploration of the data. Start with histograms to get a sense of the sample distributions (hint: we’re looking to see if the data looks like it could come from a normal distribution, see Chapter 13.3 Assumptions) (Fig 2).
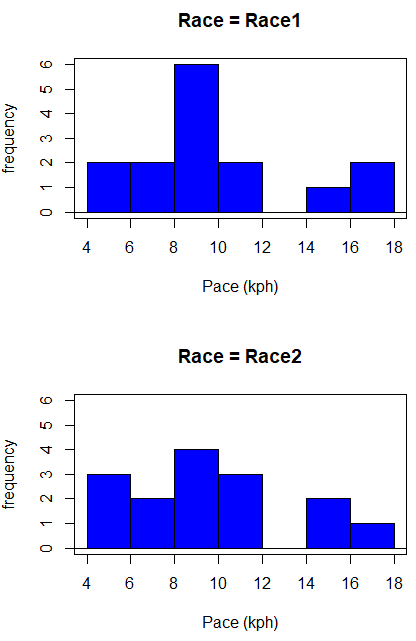
Figure 2. Histograms shows the distribution of 5K running times of 15 women who ran the race twice.
R code (stacked data set, then used defaults R Commander to make the histogram, then modified the code and submitted modified code to make Fig 1)
with(stackExCh10.3, Hist(obs, groups=Race, scale="frequency", breaks="Sturges", col="blue",
xlab="Time (min)", ylab="Frequency")))
Conclusion? The histograms don’t look normally distributed so we keep this in mind as we proceed. (See Chapter 13 – Assumptions of parametric tests for additional information about assumptions.)
A box plot comparing the first and second pace times (Fig 3).
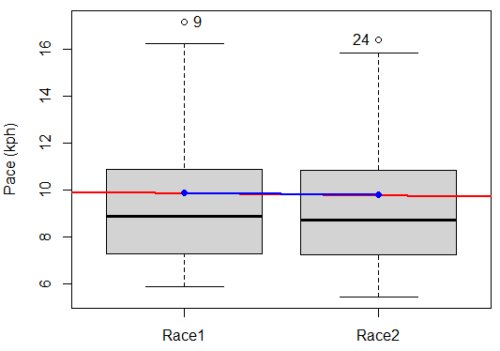
Figure 3. Box plot of race speed (kph) for 15 women 5K in two successive years.
I added a trend line (linear regression, see Chapter 17, red line) and connected the averages (blue line) for visual emphasis — no differences between the means — but note that one wouldn’t do this as part of an analysis (see Chapter 4 discussion).
R code for Fig 2
Boxplot(obs~Race, data=stackExCh10.3, id=list(method="y"), xlab="", ylab="Pace (kph)") #boxplot was made in Rcmdr
abline(lm(obs ~ as.numeric(Race), data=stackExCh10.3), col="red", lwd=2)
means <- tapply(obs, Race, mean)
points(1:2, means, pch=7, col="blue")
lines(1:2, means, col="blue", lwd=2)
The box plot works to show the median difference, but loses the paired information. A nice package called PairedData has several functions that work well with paired data, for example a profile plot (Fig 4). A profile plot is useful for showing an association between paired data.
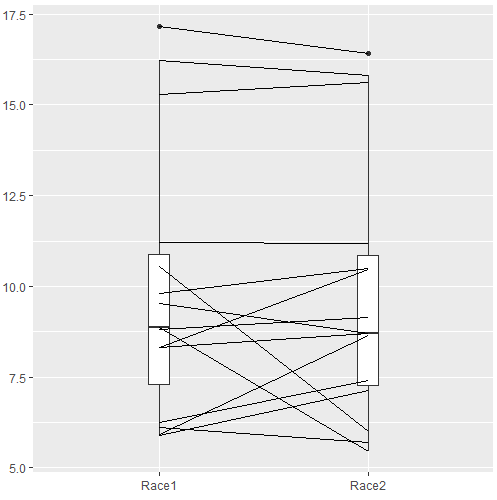
Figure 4. Profile plot, PairedData package.
R commands for Figure 4.
require(PairedData)
attach(example.ch10.3) # remember to attach dataframe so you don't have to call variables like example.ch10.3$Race1
races <- paired(Race1, Race2)
plot(races, type = "profile")
Paired t-test calculation
The paired t-test is a straight-forward extension of the independent sample t-test; the key concept is that the two samples are no longer independent, they are paired. Thus, instead of mean of group 1 minus mean of group two, we test the differences between sample 1 and sample 2 for each paired observation.

- Compute the differences between the Paired Samples (as in tables above)
- Calculate the MEAN difference score,
 : in the previous example = -0.094 kmh
- Calculate the degrees of freedom df = # pairs – 1 = n – 1, where n is the number of pairs
- Calculate the standard error of the mean of d.
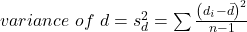
where

- Calculate the test statistic for paired data

- Compare to the Critical Value in Table C. 4 (Appendix Table 2)
- Find the Critical Value = t α (2), df
Try as difference instead of paired
Before you answer, take a look at the box plot of the mean difference between the repeat measures of 5K pace for the 15 women (Fig 5).
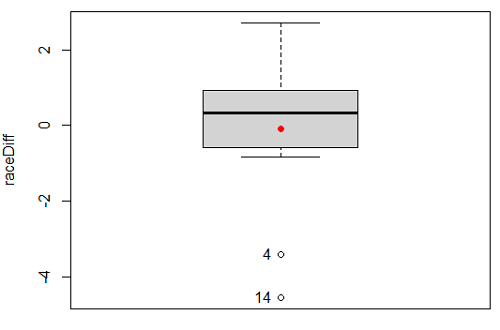
Figure 5. Box plot of differences, Red dotted lines shows the null hypothesis.
Note 2: Figure 5 is appropriate for diagnostics, but not for publication, per our discussions in Chapter 4.
Create a new variable, raceDiff, equal to Race2 minus Race1. Then, use the one sample T-test on raceDiff. I’ll leave you to complete the work (Question 2).
R code
t.test(Race1, Race2, paired = TRUE, alternative = "two.sided")
R output
Paired t-test

data: Race.1 and Race.2
t = 0.19389, df = 14, p-value = 0.849
alternative hypothesis: true difference in means is not equal to 0
95 percent confidence interval:
-0.9491017 1.1377521
sample estimates:
mean of the differences
0.09432517
Rcmdr, paired t-test
Rcmdr: Statistics → Means → Paired t-test…
Note: your two groups must be in two different columns (unstacked!) to run this version of the test.
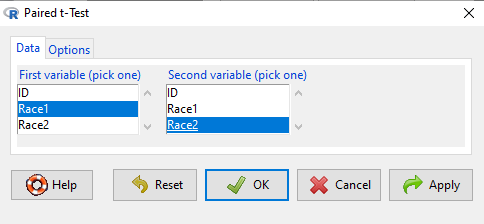
Figure 6. R Commander Paired t-test menu, Rcmdr version 2.7.
After selecting the variables, set null hypothesis after clicking on Options tab (Fig 6).
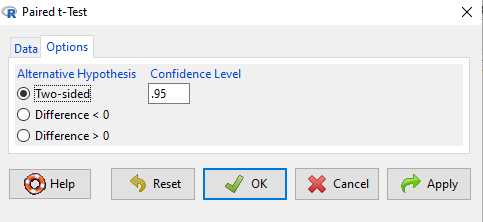
Figure 7. R Commander Paired t-Test options, select null hypothesis.
Click OK to proceed. Results will be the same as the output listed above.
the following text needs to be updated
Interpret the results.
So, what can we conclude about the null hypothesis? Interpret the 95% CI, the T-test statistic, and the P-value.
Do not ignore sample dependence
What if we ignored the repeated measures design and treated the first and second races as independent? The important concept here is to ask, what would have happened if we had done a two independent sample t-test instead?
Let’s run the analysis again, this time incorrectly using the independent sample t-test. We need to manipulate the data set before we do.
Manage your data: Stack the data
This is a good time to share how to Stack data in R. If you look at our active data set, the results of the two trials are in two different columns. In order to run the independent sample t-test we need the data in one column (with a label column).
stackExCh10.3 <- stack(example.ch10.3[, c("Race1","Race2")])
names(stackExCh10.3) <- c("obs", "Race")
Rcmdr: Data → Active data set → Stack variables in data set…
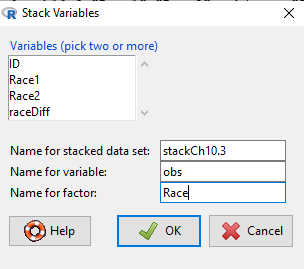
Figure 8. R Commander: Stack worksheet. Select the two variables, Race1 and Race2.
I entered values for name of the new data set, the new variable, and the name for the factor (label) column.
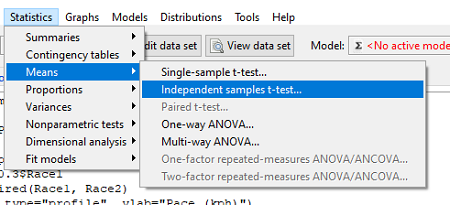
Figure 9. R Commander, select independent sample t-Test …
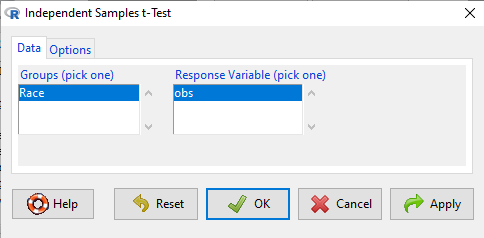
Figure 10. R commander, independent sample t test menu.
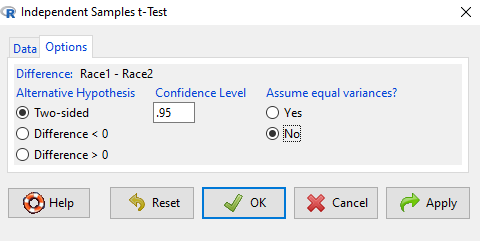
Figure 11. R Commander, select options for independent sample t-Test (assume equal variance).
Here are the results of the independent sample t-test from R.
t.test(obs~Race, alternative='two.sided', conf.level=.95, var.equal=TRUE, + data=stackCh10.3)

Two Sample t-test
data: obs by Race
t = 0.070645, df = 28, p-value = 0.9442
alternative hypothesis: true difference in means is not equal to 0
95 percent confidence interval:
 -2.640719 2.829369
sample estimates:
mean in group Race1 mean in group Race2
 9.886342 9.792017
End R output
In this case, we would have reached the same general conclusion, but the p-values are different. The p-value from the paired t-test was about 0.85 whereas the p-value from the independent sample t-test was higher, nearly 0.95, suggesting little difference between the two trials.
While the general conclusion holds, this time, that there were no statistically significant difference between the means for first and second trials. However, it won’t always work out that way. And besides, if you treated the paired data as independent, you’ve clearly violated one of the assumptions of the test.
Take a look at the degrees of freedom for the two analyses. By ignoring the pairing of samples we gain twice the number of degrees of freedom … that can’t both be right. The way to distinguish between the two is to go back to the experimental units.
Question: What are the sampling units in the case of repeat measures on individuals: the individuals themselves? the pairs of burst speed trials? something else?
it is important to note that the paired t-test is still the best for this situation because it accurately reflects the experiment — individuals were measured twice, therefore the two groups (trial 1 and trial 2) are not independent! Thus, the p-value from the paired t-test correctly reflect our best analyses of the test of the null hypothesis because the correct degrees of freedom were 14 and not 28.
In the case of the independent sample t-test we necessarily make the assumption that the two groups are independent — that is, that they are measured on different sampling units (eg, different individuals or subjects). In statistical terms, that means that you assume that the correlation between trial results is equal to zero. By incorrectly choosing an independent sample test in these repeated measures cases, I would make two null hypotheses: (1) that the means are the same and (2) that the correlation between repeat measures is zero. The problem? The t-test only evaluates the first hypothesis (means).
Questions
- Refer to Figure 6 again and related data set. Were runners faster the second year or the first year running the 5k? What about the points labeled 4 and 14? What was the average difference between first and second races?
- Complete the test of the null hypothesis of no difference between race 1 and race 2 (
raceDiff) with the one sample t-test. Set up a table to compare the test statistic, df, and p-values for results from paired t test, one sample t-test, and independent sample t-test. How do these results compare? - I’ve called the observed value “pace,” but runners would know that pace is actually amount of time per kilometer, not the total time over 5k, which is what I called pace.
- Create a new variable and report average pace for Race1 and Race2.
- Redo the paired analysis, including box plot, on your new variable.
- What is the null hypothesis for your new variable?
- Summarize your results and add to the table you created for question 2.
- Redo the two plots in Figure 2 so that the two histograms are on the sample plot. Instructions and examples were provided in Chapter 4.2.
Quiz Chapter 10.3
Paired t-test
Data set
example.ch10.3 <- read.table(header=TRUE, text = "
ID Race1 Race2
1 15.28 15.61
2 11.22 11.19
3 8.80 9.14
4 8.88 5.46
5 9.81 10.50
6 6.12 5.69
7 8.31 8.71
8 6.26 7.42
9 17.16 16.41
10 16.23 15.82
11 5.90 7.12
12 8.31 10.48
13 5.93 8.64
14 10.54 5.99
15 9.53 8.69
")
Chapter 10 contents
6.7 – Normal distribution and the normal deviate (Z)
Introduction
In chapter 3.3 we introduced the normal distribution and the Z score, aka normal deviate, as part of a discussion about how some knowledge about characteristics of the dispersion of our data sampled from a population could be used to calculate how many samples we need (the empirical rule). We introduced Chebyshev’s inequality as a general approach to this problem, where little is known about the distribution of the population and contrasted it with the Z score, for cases where the distribution is known to be Gaussian or the normal distribution. The normal distribution is one of the most important distributions in classical statistics. All normal distributions are bell-shaped and symmetric about the mean. To describe a normal distribution only two parameters are needed: the population mean, μ, and the population standard deviation, σ. The normal distribution with mean equal to zero and standard deviation equal to one is called the standard normal, or Z distribution. With use of the Z score any normal distribution can be quickly converted to the standard normal distribution.
Proportions of a Normal Distribution
This concept will become increasingly important for the many statistical tests we will learn over the next few weeks. What is the proportion of the populations that is greater than some specific value? Below (Fig 1), again, I have generated a large data set, now with population mean µ = 5 and σ = 2. The red line corresponds to the equation of the normal curve using our values of µ = 5 and σ = 2.

Figure 1. Frequency of observations expected to be greater than 7 (red bars) from a large population with mean µ = 5 and σ = 2.
R code for Fig 1.
set.seed(123)
myData <- rnorm(1000, mean = 5, sd = 2)
h <- hist(myData, breaks = 20, plot = FALSE)
threshold <- 7
# Bars with midpoints greater than threshold will be "red",
# and others will be "white."
bar_colors <- ifelse(h$mids > threshold, "red", "white")
plot(h, col = bar_colors, xlab = "Value", ylab = "Frequency")
Note that this is a crucial step! We assume that our sample distribution is really a sample from a population density (= “area under the curve”) function (= “an equation”) for a normal random (= “population”) variable.
Once I (you) make this assumption, then we have powerful and easy to use tools at our command to answer questions like
Question: What proportion of the population is greater than 7 (Fig 1, colored in red)?
This gets to the heart of the often-asked question, How many samples should I measure? If we know something about the mean and the variability, then we can predict how many samples will be of a particular kind. Let’s solve the problem.
The Z score
We could use the formula for the normal curve (and a lot of repetitions), but fortunately, some folks have provided tables that short-cut this procedure. R and other programs also can find these numbers because the formulas are “built in” to the base packages. First, let’s introduce a simple formula that lets us standardize our population numbers so that we can use established tables of probabilities for the normal distribution.
Below, we will see how to use Rcmdr for these kinds of problems.
However, it’s one of the basic tasks in statistics that you should be able to do by hand. We’ll use the Z score as a way to take advantage of known properties of the standard normal curve.
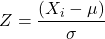
Z = 1 (with the mean and SD). Z (say “Z-score”) is called the normal deviate (aka “standard normal score”; it is also called the “Z-score”); it gives us a shortcut for finding the proportion of data greater than 7 in this case).
We use the normal deviate to do a couple of things; one use is to standardize a sample of observations so that they have a mean of zero and a standard deviation of one (the Z distribution). The data would then said to have been normalized.
The second use is to make predictions about how often a particular observation is likely to be encountered. As you can imagine, this last use is very helpful for designing an experiment — if we need to see a specified difference, we can conduct a pilot study (or refer to the literature) to determine a mean and level of variability for our observation of choice, plug these back into the normal equation and predict how likely we can expect to see a particular difference. In other words, this is one way to answer that question — how many observations need I make for my experiment to be valid?
Table of normal distribution
A portion of the table of the normal curve is provided at our web site and in your workbook. For our discussions, here’s another copy to look at (Fig 2).
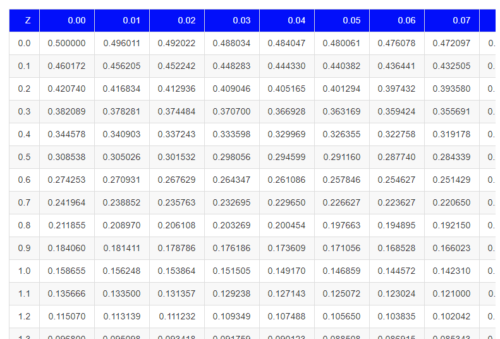
Figure 2. Portion of the table of the normal distribution. Only values equal to or greater than Z = 0 are visible.
See Table 1 in the Appendix for a full version of the normal table.
We read values of Z from the first column and the first row. For Z = 0.23 we would scan the top row, scoot over to fourth column, then trace to where the row and column intersect (Fig 3); the frequency of occurrence of values at Z = 0.23 is 0.409046 or 40.9% (Fig 3).
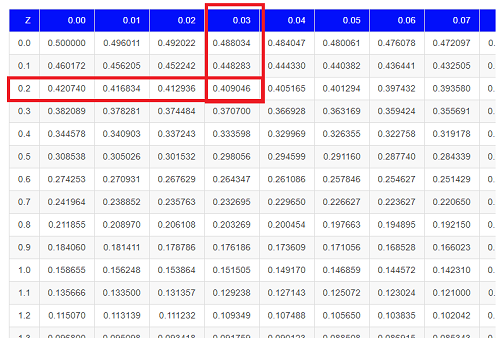
Figure 3. Highlight Z = 0.23, frequency is 0.409046.
Z on the standard normal table is going to range between -4 and +4, with Z = 0 corresponding to 0.500. The Normal table values are symmetrical about the mean of zero.
What to make of the values of Z, from -4, -3, … +2, +3, up to +4 and beyond? These are the standard deviations! Recall that using the Z score you corrected to mean of zero (got it!), and a standard deviation of one! A Z of 2 is twice the standard deviation; a Z = 3 is therefore three times the standard deviation, and so forth. The distribution is symmetrical: you get the same frequency for negative as for positive values. So on the “X” axis on a standard normal distribution, we have units of standard deviation plus (greater) or minus (less) than the mean. In Figure 4, area less than -1 standard deviations is highlighted (Fig 4).
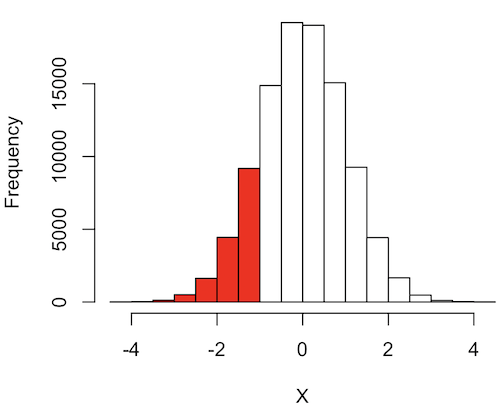
Figure 4. Plot of standard normal distribution; area less than -1 σ.
R code for Fig 4.
set.seed(123)
myData2 <- rnorm(100000, mean = 0, sd = 1)
threshold <- -1
bar_colors <- ifelse(h$mids < threshold, "red", "white")
# Additional code used, same as Figure 1.
Question. How many multiples of standard deviations would you have for a Z score of Z = 1.75?
Answer = 1.75 times
Examples
See Table 1 in the Appendix for a full version of the normal table as you read this section.
What proportion of the data set will have values greater than 7? After applying our Z score equation, I get Z = 1.0 and for a Z of 1.0 = 0.1587 or 15.87% of the observations are greater than 7.
What proportion of the data set will have values less than -7? After applying our Z score equation, I get Z = -1.0. Taking advantage of symmetry argument, I just take my Z = -1.0 and make it positive — instead of values smaller than -1.0 we now have values greater than +1.0. And for a Z of 1.0 = 0.1587 or 15.87% of the observations are greater than 7, which means that 15.87% will be -7 or smaller.
What proportion of the data set will have values greater than 8? Again, apply the Z score equation I get Z of 1.5 = 0.0668 or 6.68% of the observations are greater than Z.
What proportion of the population is between 5 and 7 ? (colored in red). Draw the problem (example shown in Fig 5).
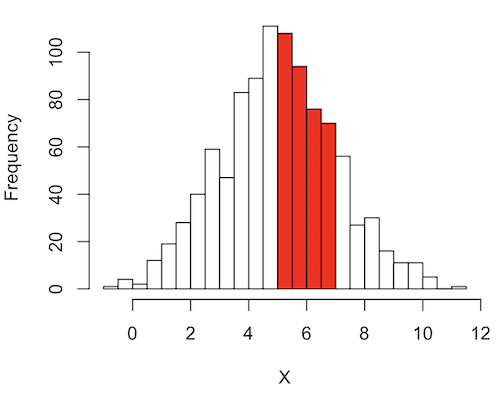
Figure 5. Proportion of the population is between 5 and 7.
R code for Fig 5.
# Used myData from Fig 1 code.
highlight_start <- 5
highlight_end <- 7
bar_colors <- rep("white", length(h$counts))
bar_colors[h$breaks[-length(h$breaks)] >= highlight_start & h$breaks[-1] <= highlight_end] <- "red"
# Additional code used, same as Figure 1.
Note 1: h$breaks[-length(h$breaks)] gives the left edges of the bins, and h$breaks[-1] gives the right edges.
Worked problem
1 – (proportion beyond 7) – (proportion less than 5)
1 – (0.1587) – (proportion less than 5)
And the proportion less than 5?
Use Z-score equation again. Now we find that
Z = 0
And look up Z of 0 from the table = 0.5 proportion or 50.0%
Therefore, the proportion between 5 & 7 equals
1 -0.1587 – 0.50 = 0.3413
Answer = 34.13 % of the observations are between 5 and 7 when the mean µ = 5 and s = 2.
Questions
Several questions were asked in the text.
1. Proportion of observations greater than 7 from a large population with mean µ = 5 and σ = 2.
2. How many multiples of standard deviations would you have for a Z score of Z = 1.75?
3.
Quiz Chapter 6.7
Normal distribution questions
Chapter 6 contents
- Introduction
- Some preliminaries
- Ratios and probabilities
- Combinations and permutations
- Types of probability
- Discrete probability distributions
- Continuous distributions
- Normal distribution and the normal deviate (Z)
- Moments
- Chi-square (Χ2) distribution
- t distribution
- F distribution
- References and suggested readings