5.6 – Sampling from Populations
Introduction
Researchers generally can’t study an entire population. More generally, striving to study each member of a population is not necessary to arrive at answers about the population. For example, consider the question, does taking a multivitamin daily improve health? What are our options? Do we really need to follow every single individual in the United States of America, monitoring their health and noting whether or not the person takes vitamins daily in order to test (inference) this hypothesis? Or, can we get at the same answer by careful experimental design (see Schatzkin et al 2002; Dawsey et al 2014)? Supplement use is wide-spread in the United States, but both health and vitamin use differ by demographics. Young people tend to be healthier than older people and older people tend to take supplements more than younger people.
A subset of the population is measured for some trait or characteristic. From the sample, we hope to refer back to the population. We want to move from anecdote (case histories) to possible generalizations of use to the reference population (all patients with these symptoms). How we sample from the reference population limits our ability to generalize. We need a representative sample: simple to define, hard to achieve.
Statistics becomes necessary if we want to infer something about the entire populations. (Which is usually the point of doing a study!!) Typically tens to thousands of individuals are measured. But in addition, HOW we obtain the sample of individuals from the reference population is CRITICAL.
Kinds of sampling include (adapted from Box 1, Tyrer and Heyman 2016; see also McGarvey et al 2016)
Probability sampling
- random
- stratified
- blocking
- clustered
- systematic
Nonprobability sampling
- convenience, haphazard
- judgement
- quota
- snowball
For an exhaustive, authoritative look at sampling, see Thompson (2012).
How can samples be obtained?
Sampling from a population may be convenient. For one famous example, consider the Bumpus data set. (We introduced this data set in Question 5, Chapter 5.) So the legend goes, Professor Bumpus was walking across the campus of Brown University, the day after a severe winter storm, and came across a number of motionless house sparrows on the ground. Bumpus collected the birds and brought them to his lab. Seventy-two birds recovered; 64 did not (Table1).
Table 1. A subset of Bumpus data set, summarized by sex of birds.
| House sparrows | Lived | Died |
|---|---|---|
| Female | 21 | 28 |
| Male | 51 | 36 |
Bumpus reported differences in body size that correlated with survival (Bumpus 1899), and this report is often taken as an example of Natural Selection (cf. Johnston et al 1972). The Bumpus dataset is clearly convenience sampling. It’s also a case study: a report of a single incident. But given that is is a large sample (n = 136), it is tempting to use the data to inform about about possible characteristics of the birds that survived compared with those that perished.
Another way we collect samples from populations is best termed haphazard. In graduate school I got the opportunity to study locomotor performance of whiptail lizards (Aspidoscelis tigris, A. marmoratus, genus formerly Cnemidophorus**) across a hybrid zone in the Southwest United States (Dohm et al. 1998). During the day we would walk in areas where the lizards were known to occur and capture any individual we saw by hand. (This would sometimes mean sticking our hands down into burrows, which was always exciting — you never really knew if you were going to find your lizard or if you were going to find a scorpion, venomous spider, or …) Lizards collected were returned to the lab for subsequent measures. Clearly, this was not convenience sampling; it involved a lot of work under the hot sun. But just as clearly, we could only catch what we could see and even the best of us would occasionally lose a lizard that had been spotted. Moreover, one suspects we missed many lizards that were present, but not in our view. Lizards that were underground at the time we visited a spot would not be seen nor captured by us; individual lizards that were especially wary of people (Bulova 1994) would also escape us. In other words, we caught the lizards that were catchable and can only assume (hope?) that they were representative of all of these lizards. Applying a grid or quadrant system to the area and then randomly visiting plots within the grid or quadrant might help, but still would not eliminate the potential for biased sampling we faced in this study.
Quota sampling implies selection of subjects by some specific criteria, weighted by the proportions represented in the population. It’s different from stratified sampling because there is no random selection scheme: subjects are selected based on matching some criteria, and collection for that group stops when the sample number matches the proportion in the population. Consider our vitamin supplement survey. If student population at Chaminade University was the reference population, and we have enough money to survey 100 students, then we would want a sample of 70 women students and 30 male students, representing the proportions of the student population.
Snowball sampling implies that you rely on word-of-mouth to complete sampling. After initial recruitment of subjects, sample size for the study increases because early participants refer others to the researchers. This can be a powerful tool for reaching underrepresented communities (eg, Valerio et al 2016).
Types of Probability sampling
Random sampling is an example of probability sampling. As we defined earlier, simple random sampling requires that you know how many subjects are in the population (N) and then each subject has an equal chance of being selected

Examples of nonprobability sampling include
- convenience sampling
- volunteer sampling
- judgement sampling
Convenience sampling (the first 20 people you meet at the library lanai); volunteer sampling (you stand in front of a room of strangers and ask for any ten people to come forward and take your survey — or more seriously, persons with a terminal disease calling a clinic reportedly known to cure the disease with a radical new, experimental treatment), and judgement sampling (to study tastes in fashion, you decide that only persons over six feet tall should be included because .…).
Random in statistics has a very important, strict meaning. As opposed to our day-to-day usage, random sampling from a population means that the probability that any one individual is chosen to be included in a sample is equal. Formally, this is called simple random sampling to distinguish it from more complex schemes. For a sampling procedure to be random requires a formal procedure for sampling a population with known size (N).
For example, at the end of the semester, I may select the order for student presentations at random. Thus, students in the classroom would be considered the population (groups of students are my sample unit, not individual students!). What is the probability that your group will be called first? Second? We need to know how many groups there are to conduct simple random sampling. Let’s take an extreme and say that all groups have a size of one; there are 26 students in this room, so

or

of being selected first.
Now to determine the probability of your group being selected second, we need to distinguish between two kinds of sampling:
- Sampling with replacement — after I select the first group, the first group is returned to the pool of groups that have not been selected. In other words, with replacement, your group could be selected first and selected second! The probability of being selected second then remains

.
- Sampling without replacement — after I select the first group, then I have

groups left to select the second group, so probability that your group will be second is

. The first group has already been selected and is not available.
Random sampling refers to how subjects are selected from the target, reference population. Random assignment, however, describes the process by which subjects are assigned to treatment groups of an experiment. Random sampling applies to the external validity of the experiment: to the extent that a truly random sample was drawn, then results may be generalized to the study population. Random assignment of subjects to treatment however makes the experiment internally valid: results from the experiment may be interpreted in terms of causality.
R code, sample without replacement
sample(26)
[1] 1 10 11 23 17 13 8 6 19 20 21 16 14 15 5 2 12 4 26 22 9 7 25 18 3 24
R code, sample with replacement
mySample <- sample(26, replace = TRUE); mySample
[1] 9 26 24 9 3 1 23 14 26 6 5 19 17 23 11 12 3 8 7 19 2 16 3 11 1 1
How many elements duplicated?
out <- duplicated(mySample); table(out)
out
FALSE TRUE
17 9
More on sampling in R discussed in Sampling with computers below.
Additional sampling schemes
Simple random sampling is not the only option, but in many cases it is the most desirable. Consider our multivitamin study again. Perhaps studying the entire USA population is a bit extreme. How about working from a list of AARP members, sending out questionnaires to millions of persons on this list, getting back about 20% of the questionnaires, sorting through the responses and identifying the respondent to diet categories and multivitamin use. The researchers had nearly 500,000 persons willing and able to participate in their prospective study (Schatzkin et al 2001; Dawsey et al 2014; Lim et al 2021). It’s an enormous study. But is this really much better than our described lizard experiment? Let’s count the ways: Not all older people are members of AARP (that 500,000? That’s less than 1% of the 50 and older persons in the USA); A large majority of AARP members did not return surveys; Some fraction of the returned surveys were not usable; How representative of diverse aged populations in the United States is AARP?
Simple random sampling may not be practical, particularly if sub-populations, or strata, are present and members of the different sub-populations are not available to the researcher in the same numbers. In ecology, habitat-use studies routinely need to account for the patchiness of the environment in space and time (Wiens 1976; Summerville and Crisp 2021). Thus, samples are drawn in such a way to represent the frequency within each sub-population.
For a simple example, researchers conducting a controlled breeding program of mice don’t use simple random sampling to choose pairs of mates; after all, random sampling without regard of sex of the mice would lead to some pairings of males only, or females only (Fig 1).
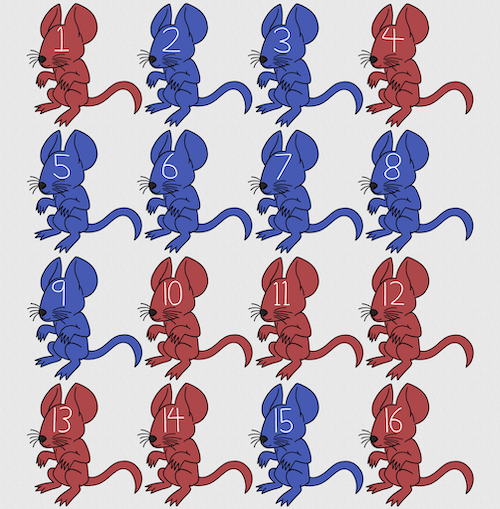
Figure 1. Sixteen mice, eight red and eight blue. Image © 2024 Mia D Graphics
R code
pairs <- c(rep("red", 8), rep("blue", 8))
replicate(2, sample(pairs, 8), simplify = FALSE)
[[1]]
[1] "blue" "blue" "blue" "red" "blue" "red" "blue" "red"

[[2]]
[1] "blue" "blue" "red" "red" "red" "red" "red" "blue"
Oops. If we interpret the output blue = male and red = female, then four out of the eight pairs were same sex pairings.
Thus, the breeding strategy is to random sample from female mice and from male mice and the stratification is sex of the mouse. Alternatively, breeders may select mice to form breeding pairs systematically: From a large colony with dozens of cages, the breeder may select one mouse from every third cage.
Stratified Random Sampling: Individuals in the population are classified into strata or sub-groups: age, economic class, ethnicity, gender, sex …, as many as needed. Then choose a simple random sample from each group, typically in proportion to the size of the sub-groups in the population. Combine those into the overall sample. For example, when I wanted a random sample of mice for my work, I called the supplier and requested that a total of 100 male and female mice be randomly selected from the five colonies they maintained. The reference population is the entire supply of mice at that company (at that time), but I wished to make sure that I got unrelated mice, so I needed to divide the population into groups (the five colonies) before my sample was constructed.
Note 1: The size of the population must be known in advance, just like in simplified random sampling. A more interesting example, the Social Security Administration conducts surveys of popular baby names by year. They post the top ten most popular names based on 1% or 5% (first strata), then by male/female (second strata).
For a simple example of the need for stratified sampling, consider our 16 blue and red mice again. If mice were randomly assigned to treatment group, then by chance unequal samples within strata may be assigned to a treatment group, potentially biasing our conclusions (Fig 2).
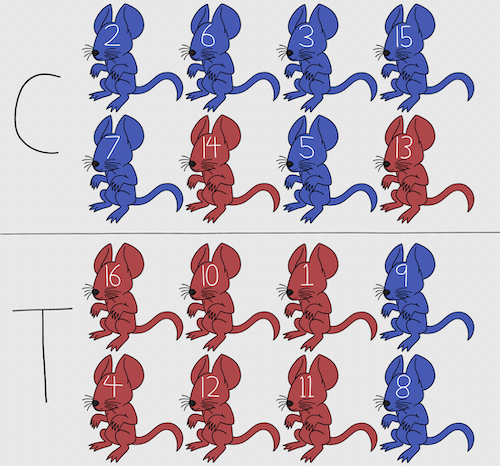
Figure 2. Sixteen mice, randomly assigned to treatment groups C and T; by chance, 75% blue in C and just 25% in T. If color was a confounding factor then our conclusions about the effectiveness of the treatment would be associated with color. Image © 2024 Mia D Graphics
Block sampling: superficially resembles stratified sampling, but refers to how experimental units are assigned to treatment groups. Blocks in experimental design refers to potentially confounding factors for which we wish to control, but are otherwise not interested in. For our example described in Figure 2, mouse color may not be of specific interest for our study and therefore would be considered a blocking effect.
Agricultural research provides a host of other blocking situations: plots distributed across an elevation or hydration gradient (Fig 3), soil types, and many others.
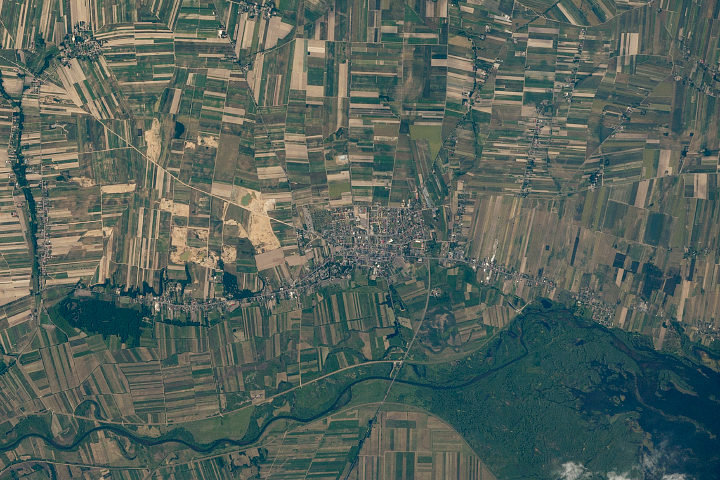
Figure 3. Agricultural fields in Central Poland. NASA https://visibleearth.nasa.gov/images/146593/agriculture-fields-in-central-poland/146595w
For a microbiology example, edge effects of heated culture plates. For a growth experiment it’s unlikely we are specifically interested in the plate layout on the growth characteristics of treated cells. However, it’s also unlikely we can assume placement has no influence on growth (eg, Mansoury et al 2021). A 96-well microplate has 60 inner wells and 36 edge wells (A1 – H1, A12-H12, plus 1st and 12th wells of columns B – H, for a total of 36 wells, Fig 4). Thus, analysis of growth effects should include a block effect for well position.
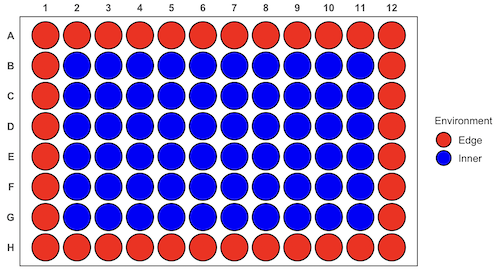
Figure 4. Format of 96-well plate. Red cells = “edge” wells; blue cells = “inner” wells. Plotted with ggplate package.
For long incubation periods it’s not unexpected that edge wells and inner wells may evaporate at different rates, potentially confounding interpretation of treatment effects if, by chance, treatment samples are more commonly assigned to edge wells. Block sampling implies subjects from treatment groups are randomly assigned to each block, in equal numbers if possible.
Cluster Sampling: In many situations, the population is far too large or too dispersed and scattered for a list of the entire population to be known. And, a random approach ignores that there is a natural grouping — people live next to each other, so there is going to be things in common. A multi-stage approach to sampling will be better than simply taking a random sample approach. Most surveys of opinion (when conducted reputably) use a multi-stage method. For example, if a senator wishes to poll his constituents about an issue, he may his pollster will randomly select a few of the counties from his state (first stage), then randomly select among towns or cities (second stage), to obtain a list of 1000 people to call. In some instances, they might use even more stages. At each stage, they might do a stratified random sample on sex, race, income level, or any other useful variable on which they could get information before sampling. If you are interested in this kind of work, for starters, see Couper and Miller (2009).
There are more types of sampling, and entire books written about the best way to conduct sampling. One important thing to keep in mind is that as long as the sample is large relative to the size of the population, each of the above methods generally will get the same answers (= the statistics generated from the samples will be representative of the population).
As long as some attempt is made to randomize, then you can say that the procedure is probability sampling. Nonprobability, or haphazard sampling, describes the other possibility, that is, each element is selected arbitrarily by a non-formal selecting of individual. … all the fish or birds that you catch may not be a random sample of those present in a population. For example,
- wild Pacific salmon do not feed on the surface, hatchery salmon feed on the surface. …
- all the individuals who respond to a survey.
- Phone surveys, web surveys, person on the street surveys… how random, how representative?
Sampling with computers
Now to determine the probability of your group being selected second, we need to distinguish between two kinds of sampling:
Sampling with replacement — after I select the first group, the first group is returned to the pool of groups that have not been selected. In other words, with replacement, your group could be selected first and selected second! The probability of being selected second then remains
Sampling without replacement — after I select the first group, then I have

groups left to select the second group, so probability that your group will be second is

. The first group has already been selected and is not available, and so on.
Sampling is usually easiest if a computer is used. Computers use algorithms to generate pseudo-random numbers. We call the resulting numbers pseudo-random to distinguish them from truly random physical processes (eg, radioactive decay). For more information about random numbers, please see random.org.
If all you wish to do is select a few observations or you need to use a random procedure to select subjects prior to observations, then these websites can provide a very quick, useful tool.
Sampling in Microsoft Excel or LibreOffice Calc
Microsoft’s Excel is pretty good at sampling, but requires knowledge of included functions. Here are the steps to generate random numbers and select with and without replacement in Excel. I’ll give you two cases.
1. For random numbers, enter the function =rand() in a cell, then drag the cell handle to fill in cells to N (in our case = 26, so A1 to A26). This function generates a random (more or less!) number between 0 and 1. We want digits between 1 and 26, not fractions between 0 and 1, so combine INT function with RAND function
=INT(27*RAND())
Note 2: To get between 1 and 9, multiply by 10 instead of 27; to get between 1 and 100, multiply by 101, etc.
In Excel to sample with replacement, simply pick the first two cells (the algorithm Excel used already has conducted sample with replacement. See next item for method to sample without replacement in Excel. You have to have installed the Data Analysis Tool Pak. Here’s instructions for Office 2010.
If you have a Mac and Office 2008, there is no Data Analysis Tool Pak, so to get this function in your Excel, install a third-party add-in program (eg, StatPlus, a free add-in, really nice, adds a lot of function to your Excel). If you have the 2011 version of Office for Mac, then the Data Analysis Tool Pak is included, but like your Windows counterparts, you have to install it (click here for instructions).
2. Let’s say that we have already given each group a number between 1 and 26 and we enter those numbers in sequence in column A.
To sample without replacement, select Tools → Data Analysis… (if this option is not available, you’ll have to add it — see Excel help for instructions, Fig 5).
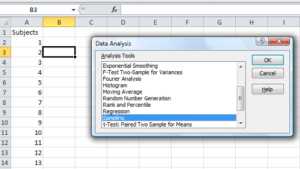
Figure 5. Screenshot of Sampling in Data Analysis menu, Microsoft Excel
Enter the cells with the numbers you wish to select from. In our example, column A has the numbers 1 through 26 representing each group in our class. I entered A:A as the Input Range.
Next, select “Random” and enter the number of samples. I want two.
Click OK and the output will be placed into cell B3 (my choice); I could have just as easily had Excel put the answer into a new worksheet.
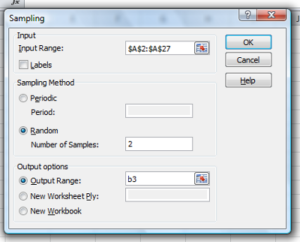
Figure 6. Screenshot of input required for Sampling in Data Analysis menu, Microsoft Excel
To sample with replacement from column A (with our 1 through 26), type in the formula B1
=INT(27*RAND())and the formula C1
=INDEX(A:A,RANK(B1,B:B))then drag the cell handles to fill in the columns (first column B, then column C).
That’ll do it for MS Excel or LibreOffice Calc.
Sampling with R (Rcmdr)
It’s much easier with much more control to get sampling in Rcmdr (R) than in Excel. Sampling in R is based on the function called sample() and sample.int(). I will present just the sample() command here.
sample(x, size, replace = FALSE, prob = NULL)Example
You want to sample ten integers between 1 and 10
sample(10)R output
sample(10)
[1]  5  1 10  8  7  3  4  9  2  6
You have a list of subjects, A1 through A10
subjects = c("A1","A2","A3","A4","A5","A6","A7","A8","A9","A10")
sample(subjects, 3, replace = FALSE, prob = NULL)
R output
sample(subjects, 3, replace = FALSE, prob = NULL)
[1] "A5" "A2" "A9"
Could use this to arrange random order for ten subjects
sample(subjects, 10, replace = FALSE, prob = NULL)
[1] "A9" "A3" "A8" "A2" "A1" "A4" "A10" "A7" "A5" "A6"
Try with replacement; To sample with replacement, type in TRUE after replace in the sample() function. The R output follows
sample(x, 10, replace = TRUE, prob = NULL)
[1]  5  5  3  5  3  7  3  5 10  6
R’s randomness is based on pseudonumbers and is, therefore, not truly random (actually, this is true of just about all computer-based algorithms unless they are based on some chaotic process). We can use this pseudo part to our advantage: if we want to reproduce our “random” process, we can seed the random number algorithm to a value (eg, 100), with the command in the Script Window
set.seed(100)For 10 random integers (eg, observations), type in the Script window
sample(10)R returns the following in the Output Window
sample(10)
[1] 4 5 7 3 10 9 2 1 6 8
Sampling was done without replacement. Here’s another selection round,
First without setting a seed value
sample(10)
[1] 10 4 7 3 8 1 2 9 6 5
Try again to see if get the same 10
sample(10)
[1]  1  4  8  2  9  6  5 10  3  7
Now to demonstrate how setting the seed allows you to draw repeated samples that are the same.
Note 3: If I need to precede the sample command with a set.seed() call, then sampling is repeatable.
set.seed(100)
sample(10)
[1] 4 3 5 1 9 6 10 2 8 7
and try again
set.seed(100)
sample(10)
[1] 4 3 5 1 9 6 10 2 8 7
Additional R packages that help with sampling schemes include: sampling() and spatialsample, which is part of the BiodiversityR package, which is available as a plugin for R Commander.
Quiz Chapter 5.6
Sampling from populations
Questions
- For our two descriptions of experiments in section 6.1 (the sample of patients; the sample of frogs), which sampling technique was used?
- What purpose is served by
set.seed()in a sampling trial? - Consider our question, Does taking a multivitamin daily improve health? Imagine you have a grant willing to support a long-term prospective study to follow up to one thousand people for ten years. List at least three concerns with proposed solutions about how sampling of subjects for the study.
- Imagine you wish to conduct a detailed survey to learn about student preferences. Your survey will include many questions, so you decide to ask just ten students. Student population is 70% female, 30% male.
- Assuming you select at random (simple random sampling), what is the chance that no male students will be included in your survey?
- You are able to increase the number of surveys to 20, 30, 40, or 50. What is the chance that no male students will be included in your survey for each of these increased sample numbers?
- What can you conclude about the effects of increasing survey sample size on representativeness of students for the survey?
- Discuss how you could apply a stratified sampling scheme to this survey and whether or not this approach improves representativeness.
- Why are random numbers generated by a computer called pseudo random numbers?
Chapter 5 contents
5.3 – Replication, Bias, and Nuisance Variables
Introduction
This page describes additional elements of experimental design, replication and bias, which can impact the validity of a study.
Replication in science refers to repeating an experiment under identical conditions multiple times. To the extent the same conclusions are achieved, we can say the outcome is reproducible (Simmons 2014) and, therefore, likely to be objectively true (Earp 2011). Replication of experimental and sampling units is an essential component of good experimental design. Confusing technical replicates for biological replicates is called pseudoreplication.
Bias refers to any of a number of sociological and cognitive errors which may influence conclusions in science (Ionnidis 2005). In a meta-analysis, Fanelli et al (2017) reported that while the size of effect from identifiable biases were small, some disciplines were more prone to these sources of error. That researchers testing similar hypotheses reach different conclusions may result from bias. One such bias is positive outcome bias, where reports of null hypotheses are more often rejected than they should be based on sample size and other concerns of statistical power (see Chapter 11 – Power analysis).
The page concludes with a discussion of nuisance variables, variables that may be causally associated with the outcome of interest, but themselves are either of no interest in the study, or may not be known in advance (Meehl 1970; see also discussion of spurious correlations in Chapter 16.3 – Data aggregation and correlation).
Technical vs. biological replicates.
A laboratory technician retrieves a vial of an immortalized cell line from cryostorage and initiate propagation of the cells for the week’s work. After a couple of days of subculturing, the technician has grown millions of cells and is ready to set up an assay. After washing the cells in PBS (phosphate buffered saline), the technician adjusts the concentration of cells to 10,000 per mL media, places the tube on ice, and proceeds to set up a 48 well microplate. To each well, the technician adds media, one or more agents (Table 1), plus cells, total volume each well at one mL, three replicates per treatment.
Table 1. In our example there were four treatments plus a control (media only)
- DMSO only (D)
- DMSO + Cytokine (DC)
- DMSO + Small molecule Inhibitor (DS)
- DMSO + Cytokine + Small molecule Inhibitor (DCS)
- Media only (M)
The plate table might look something like Figure 1.

Figure 1. Schematics of a set up for a hypothetical 48 well microplate (plate_plot() from ggplate package).
The technician has done a lot of work; but, from a statistician’s point of view, effectively the technician has but one sampling unit to show for his efforts; one biological sampling unit because as far as we can tell, the cells were all related. Biological replication refers to repeat measures (eg, same conditions) on biologically distinct entities (Blainey et al 2014). Technical replication, in contrast, refers to repeat measures on the same entity, eg, the same individual (Blainey et al 2014).
However, there were more than one technical samples in the experimental design, twelve in all because there were twelve wells. Many of you will recognize this as the distinction between technical and biological replicates. In thinking about experimental design replicates pertain to the number of sampling units that are treated the same way. In our example cells may be “treated the same way” in at least two distinct ways. Biologically, the cells may be the same: derived from the same clonal cell, all at the same passage (generation) number, each cell genetically, morphologically, physiologically (etc.,) identical to the next cell. Technical replication on the other hand pertains to the levels of the treatments.
Within each of these treatments we had three wells, and that’s at the level of the technical replication.
A final note on this experiment. We as molecular biologists call each of these treatment groups, but statisticians thinking of this design would recognize only one treatment (called in statistics a factor), with four levels of the treatment. We will discuss this beginning in chapter 12 when we introduce analysis of variance.
Types of bias.
When we make decisions, we like to think we are rational; that we make decisions based on an evaluation of evidence. And yet, an increasing body of literature suggests that our decisions often made in a manner that falls short of rational processing. We outlined some sources of bias in Chapter 2.6. Deviance from rational decision making is due to any number of cognitive biases we may have. Researchers and medical doctors make many decisions and, unfortunately, are just as susceptible to cognitive biases as the rest of us. One kind of bias that is bedeviling to research is confirmatory bias. Confirmatory bias refers to a researcher in effect seeking evidence in a way that confirms a prior conclusion (Kaptchuck 2003). Confirmatory bias would be exhibited if we report positive effects of aspirin to relieve migraines in subjects, but exclude cases where the subjects report no improvement. Medical doctors may be risk averse and therefore tend to over-prescribe, or they may be risk-takers (eg, rise and fall of high-dose chemotherapy, cf, discussion in Howard et al. 2011).
The concept of bias was first introduced in Chapter 3 and will be returned to in subsequent chapters. In general, bias refers to the objectivity of measurement and inferences about such measurements. Bias implies that a series of measurements consistently fail to return the true value of the variable. Bias is systematic error and may be associated with a poorly calibrated instrument or even the use of improper sets of rules for measurement given the nature of the characteristic. Bias can be captured by the concept of accuracy.
Bias is challenging to eliminate; the best way is to design the experiment so that the observer, the researcher, is unaware of the specific questions to be tested. The research is conducted “blind.” Clinical research provides the easiest examples. A trial can be blind in a couple of ways:
- The subjects do not know which treatment they receive, but the researcher does know
- The researcher does not know which treatment subjects receive, but the subjects know
- Neither the researcher nor the subjects know which treatment they receive.
- The other possibility is that both the researcher and the subjects know treatments received — this would be a poor design.
Bias can enter a research project at multiple levels. A partial list of sources of bias in research includes (modified after Pannucci and Wikins 2010):
Bias that occurs before the experiment
- Inadequate planning of the experiment, flawed design
- Bias in selection of subjects from the reference population
- Surveillance bias, where one group is studied more closely than another group.
Surveillance bias, also called detection bias or ascertainment bias, a type of information bias. Characterized as “the more you look, the more you find (Sackett 1979),” differences in outcome counts varies with differences in effort to detect. Recently, cases of myocarditis in young people were reported following Covid-19 mRNA vaccination (eg, Bozkurt et al 2021. Marshall et al 2021). However, myocarditis reports following vaccination occur at the rates expected in the population, and the reports lack important context (eg, other respiratory viruses known to cause myocarditis not ruled out), suggesting the putative link between Covid-19 vaccines and this heart condition may be result of us looking hard for signs of adverse effects of the vaccine (cf, discussion in O’Leary and Maldonado 2021).
Bias during the experiment
- Interviewer bias
- Chronology bias
- Recall bias
- Transfer bias
- Misclassification of exposure or outcome
- Performance bias
Performance bias refers to conditions of an experiment that introduce unintended differences between groups. For example, subjects enrolled in a weight-loss study randomly assigned to the control group may react poorly when they realize they are not receiving the experimental intervention. This leads to potential for a systematic bias — participants in the control group may behave differently, counteracting the point of randomization (McCambridge et al 2014).
Another well-known performance bias is associated with eliciting maximal performance from animals, such as running stamina or maximum sprint running speed (Losos et al 2002). For example, spring running speed of lizards may be measured by placing lizards onto a high-speed treadmill, then increasing belt speed to match the individual’s burst performance (eg, Dohm et al 1998). Clearly, not all individuals will perform to maximum physiological capabilities under these conditions.
Bias after the experiment
- Citation bias
- Confounding
Another way to view sources of bias is that, at least from the perspective of the researcher, the bias is likely to be unconscious bias. After all, if we knew about the sources of bias we would work our experiments in such a way to minimize known error producing sources (Holman et al 2015). Selecting subjects at random and keeping record keeping blind with respect to treatments are among the best tools we have to avoid this kind of bias.
Nuisance variables
A key quality of experimental design is the opportunity afforded the researcher to apply control. In a classic view of the experiment, one allows only one aspect to vary, the treatment applied, all else is controlled. Thus, any difference in outcome may be attributed to the treatment. However, it is likely impossible to control for all possible variables that may affect our outcome; confounding clear interpretation of results (see Chapter 16.2 and 16.3). Consider, for example, the effects of age on running performance (Fig. 2).
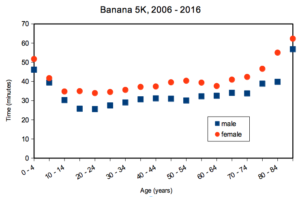
Figure 2. Mean 5K running times (minutes) by age and gender (2006 – 2016, Jamba Juice Banana 5K race, Honolulu, HI).
If we are interested in gender differences, we must also deal with the change in performance with age: older runners regardless of gender tend to run slower than younger runners. Thus, in the comparison of genders, age is a nuisance variable. In the literature, you may see “lurking variable,” or other such names. The concept is that these variables may be causal, but are either of no interest in the study, or may not be known in advance. Therefore, age must be accounted for before we can address gender differences, if any. Age, in this case, is considered a nuisance variable because we are not primarily interested in age effects, but age clearly covaries (is associated) with running performance. How best to handle nuisance variables? One approach is to match by age (blocking effect, see Chapter 14.4); another approach would be to randomly select with respect to age when compiling female and male times.
Another example of confounding. Results from ecological experiments intended to test for presence of competition for resources by plant species by removing plants may alter herbivory levels; thus, survivorship not the result of reduced plant-plant competition but because of changes in herbivore behavior (Reader 1992).
Questions
- I cite a number of articles in Mike’s Biostatistics Book. If you’re paying attention, you’ll have noticed that all of my citations, at least for articles, link to a source that you can either download or read online. What kind of error am I committing by following this approach?
- In large part because of the tendency for overuse of antibiotics, doctors are less likely today to prescribe antibiotics for patients with upper respiratory tract infections than in the past (Zoorob et al 2012). URTI are mostly caused by rhinovirus infections (Calderaro et al 2022) and, therefore, the course of infection in a patient should be unaffected by addition of antibiotic. However, although rare compared to URTI, life-threatening illness like acute epiglottitis caused by bacteria infection can sometimes develop or accompany URTI. Thus, not prescribing antibiotics at a diagnosis of URTI may risk a worsening condition for the patients. This sets the doctor up for a potential cognitive bias – to prescribe or not to prescribe antibiotics prophylactically? Discuss this decision in the context of potential sources of cognitive biases and possible outcomes of the decision.
Quiz Chapter 5.3
Replication, bias, and nuisance variables
Chapter 5 contents
- The basics explained
- Experiments
- Experimental and Sampling units
- Replication, Bias, and Nuisance Variables
- Clinical trials
- Importance of randomization in experimental design
- Sampling from Populations
- References and suggested readings
5.2 – Experimental units, Sampling units
Introduction.
Sampling units refer to the measured items, the focus of data collection; samples are selected from populations. Often, sampling units are the same thing as individuals. For example, if we are interested in the knowing whether men are more obese than women in Hawai’i, we would select individuals from the population; we would measure individuals. Thus, the sampling unit would be individuals, and the measurement unit would be percent body fat recorded for each individual. The data set would be the collection of all body fat measures for all individuals in the study, and we would then make inferences (draw conclusions) about the differences, if any, between adult males and females for body fat.
But sampling units can also refer to something more restrictive than the individual. For example, we may be interested in how stable, or consistent, is a person’s body fat over time. If we take a body fat measure once per year over a decade on the same group of adults, then the sampling unit refers to each observation of body fat recorded (once per year, ten times for an individual), and the population we are most likely to be referring to is the collection of all such readings (ten is arbitrary — we could have potentially measured the same individual thousands of times).
In some cases the researcher may wish to compare groups of individuals and not the individuals themselves. For example, a 2001 study sought to see if family structure influenced the metabolic (glycemic) control of children with diabetes (Thompson et al 2001). The researchers compared how well metabolic control was achieved in children of single parents and two-parent families. Thus, the sampling units would be families and not the individual children.
Experimental units.
Experimental units refers to the level at which treatments are independently applied in a study. Often, but not always, treatments are applied directly to individuals and therefore the sampling units and experimental units in these cases would be the same.
Question 1: What is the sampling unit in the following cell experiment?
A technician thaws a cryo tube containing about ½ million A549 cells (Foster et al 1998) and grows the cells in a T-75 culture flask (the 75 corresponds to 75 cm2 growing area) in a CO2 incubator at 37 °C. After the cells reach about 70% confluency, which may represent hundreds of thousands of cells, the technician aliquots 1000 cells into twelve wells of a plate for a total of 12000 cells. To three wells the technician adds a cytokine, to another three wells he adds a cytokine inhibitor, and to another three wells he adds both the cytokine and it’s inhibitor, and to the last three wells he adds DMSO, which was the solvent for both the cytokine and the inhibitor. He then returns the plate to the incubator and 24 hours later extracts all of the cells and performs a multiplex quantitative PCR to determine gene expression of several target genes known to be relevant to cell proliferation.
The described experiment would be an example of a routine, but not trivial procedure the technician would do in the course of working on the project in a molecular biology laboratory.
The choices for numbers provided in the description we may consider for the number of sampling units are:
- 1000 cells
- 12,000 cells
- ½ million cells
- 3 wells
- 12 wells
- The target genes
- None of the above
The correct answer is G, None of the above.
“None of the above” because the correct answer is … there was just one sampling unit! All cells trace back to that single cryo tube.
To answer the question, start from the end and work your way back. What we are looking for is independence of samples and at what level in the experiment we find independence. Our basic choice is between numbers of cells and numbers of wells. Clearly, cells are contained in the wells, so all of the cells in one well share the same medium, being treated the same way, including all the way back to the cryo tube — all of the cells came from that one tube so this lack of independence traces all the way back to the source of the cells. Thus, the answer can’t be related to cell number. How many wells did the technician set up? Twelve total. So, the maximum number of sampling units would be twelve, unless the samples are not independent. And clearly the wells (samples) are not independent because, again, all cells in the twelve wells trace back to a single cryo tube. Thus, from both perspectives, wells and cells, the answer is actually just one sampling unit! (Cumming et al 2007; Lazic 2010). Finally, the genes themselves are the targets of our study — they are the variables, not the samples. Moreover, the same logic applies — all copies of the genes are in effect descended from the few cells used to start the population.
Experimental and sampling units often, but not always the same.
Question 2: What is the experimental unit in the described cell experiment?
- 1000 cells
- 12,000 cells
- ½ million cells
- 3 wells
- 12 wells
- The target genes
- None of the above
The correct answer is E, 12 wells. Noted above, the technician applied treatments to 12 wells. DMSO was added to all wells. There were three treatments, cytokine, inhibitor, and cytokine-inhibitor (Table 1).
Table 1. Translate experiment description to a table to better visualize the design
| Wells | Treatment |
|---|---|
| A1 | Cytokine |
| A2 | Cytokine |
| A3 | Cytokine |
| A4 | DMSO |
| B1 | Inhibitor |
| B2 | Inhibitor |
| B3 | Inhibitor |
| B4 | DMSO |
| C1 | Cytokine+Inhibitor |
| C2 | Cytokine+Inhibitor |
| C4 | Cytokine+Inhibitor |
| C4 | DMSO |
Note 1: Use package ggplate to create a simple graphic to visualize a culture plate.
table01.ch05.2 <- data.frame(
     well = c("A1", "A2", "A3", "B1", "B2", "B3", "C1",
              "C2", "C3", "A4", "B4", "C4", "D4"),
     treatment = c(rep("Cytokine", 3), rep("Inhibitor", 3),
              rep("Cytokine + Inhibitor", 3), rep("DMSO", 4))
     )
plate_plot(data = table01.ch05.2,
     position = Well,
     value = Treatment,
     plate_size = 12,
     plate_type = "round")
which results in this nice plate layout (Fig 1)

Figure 1. Plate layout for Table 1. Plot made with plate_plot() function from R package ggplate.
If observations were made, then the same function can display values. Add a column of values to the dataset (eg, “Values”), then add another value = line, eg, value = Values to the R code.
Replication: Groups and individuals as sampling units.
The correct identification of levels at which sampling independence occurs is crucial to successful interpretation of inferential statistics.
Note 2:replication in Table 1: three cytokine, three cytokine-inhibitor, three with both.
Sampling error rate is evaluated at the level of the sampling units. Technical replication of sampling units allows one to evaluate errors of measurement (eg, instrument noise) (Blainey et al 2014) and other sources of technical sources of noise.
Note 3: Data noise refers to random or irrelevant information that corrupts the “true” signal in a dataset, introducing variability and potential errors. A nuisance variable is a specific type of noise that is fundamental to the data collection process but not of interest to the researcher, and its effect must be accounted for or removed via pre-processing steps. For approaches to control for noise, see Chapter 17.4 and Chapter 20.3 for more.
Replication of sampling units increases statistical power, the ability to correctly reject hypotheses. If the correct design reflects sampling units are groups and not individuals, then by counting the individuals as the independent sampling units would lead the researcher to think his design has more replication than it actually does. The consequence on the inferential statistics is that he will more likely reject a correct null hypothesis, in other words, the risk of elevated type I error occurs (Chapter 8 – Inferential statistics). This error, confusing individual and group sampling units, is called pseudoreplication (Lazic 2010).
Consider a simpler experimental design scenario depicted in Figure 2: Three different water treatments (eg, concentrations of synthetic progestins, Zeilinger et al. 2009) in bowls A, B, and C; three fish in bowl A, three fish in bowl B, and three fish in bowl C. The outcome variable might be a stress indicator, eg, plasma cortisol (Luz et al 2008).
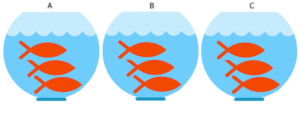
Figure 2. Three aquariums, three fish. Image modified from https://www.pngrepo.com/svg/153528/aquarium
Question 3: What were the experimental units for the fish in the bowl experiment (Fig 2)?
- Three bowls
- Nine fish
- Three water treatments
The correct answer is A, 3 bowls. The treatments were allocated to the bowls, not to individual fish. The three fish in each bowl provides technical replication for the effects of bowl A, bowl B, and bowl C, but does not provide replication for the effects of the water treatments. Adding three bowls for each water treatment, each with three fish, would be the simplest correction of the design, but may not be available to the researcher because of space or cost limitations. The design would then include nine bowls and 27 fish. If resources are not available to simply scale up the design, then the researcher could repeat the study several times, taking care to control nuisance variables (Chapter 5.3). Alternatively, if the treatments were applied to the individual fish, then the experimental units become the individual fish and the bowls reduced to a blocking effect (Chapter 14.4), where differences may exist among the bowls, but they are no longer the level by which measurements are made.
Note 4: If pseudoreplication is present in a study, then this may be accounted for by specifying the error structure in a linear mixed model (eg, random effects, blocking effects, etc., see Chapter 14 and Chapter 18).
Question 4: What were the sampling units for the fish in the bowl experiment (Fig 2)?
- Three bowls
- Nine fish
- Three water treatments
The correct answer is B, the individual fish. If instead of aqueous application of synthetic progestin, treatments were applied directly to each fish via injection, what would be the answers to Question 3 and Question 4?
Choices like these clearly involve additional compromises and assumptions about experimental design and inference about hypotheses.
Conclusion.
Sampling units, experimental units, and the concept of level at which units are independent within an experiment were introduced. Lack of independence yields the problem of pseudoreplication in an experiment, which will increase the chance that we will detect differences between our treatment groups, when no such difference exists!
Questions.

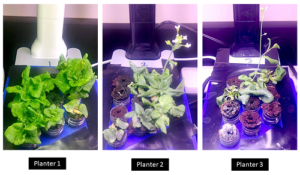
Figure 3. Three Miracle-Gro AeroGarden planters®, each with nine seedlings of an Arabidopsis thaliana strain.
Nine seeds each of three strains of Arabidopsis thaliana were germinated in three Miracle-Grow AeroGarden® hydroponic planters (Fig 3). Each planter had nine or ten vials with sphagnum peat. All seeds from a strain were planted in the same apparatus, one seed per vial. With respect to this experimental design
1. Define experimental units and sampling units.
2. Provide design examples where the experimental units are the same as the sampling units.
3. With respect to the independent and dependent (outcome) variables, discuss impacts of nuisance variables.
Quiz Chapter 5.2
Experimental units, Sampling units