19.2 – Bootstrap sampling
Introduction
Bootstrapping is a general approach to estimation or statistical inference that utilizes random sampling with replacement (Kulesa et al. 2015). In classic frequentist approach, a sample is drawn at random from the population and assumptions about the population distribution are made in order to conduct statistical inference. By resampling with replacement from the sample many times, the bootstrap samples can be viewed as if we drew from the population many times without invoking a theoretical distribution. A clear advantage of the bootstrap is that it allows estimation of confidence intervals without assuming a particular theoretical distribution and thus avoids the burden of repeating the experiment.
Base install of R includes the boot package. The boot package allows R users to work with most functions, and many authors have provided helpful packages. I highlight a couple packages
install packages lmboot, confintr
Example data set, Tadpoles from Chapter 14, copied to end of this page for convenience (scroll down or click here).
Bootstrapped 95% Confidence interval of population mean
Recall classic frequentist (large-sample) approach to confidence interval estimates of mean by R
x = round(mean(Tadpole$Body.mass),2); x
n = length(Tadpole$Body.mass); n
s = sd(Tadpole$Body.mass); s
error = qt(0.975,df=n-1)*(s/sqrt(n)); error
lower_ci = round(x-error,3)
upper_ci = round(x+error,3)
paste("95% CI of ", x, " between:", lower_ci, "&", upper_ci)
Output results are
> n = length(Tadpole$Body.mass); n
[1] 13
> s = sd(Tadpole$Body.mass); s
[1] 0.6366207
> error = qt(0.975,df=n-1)*(s/sqrt(n)); error
[1] 0.384706
> paste("95% CI of ", x, " between:", lower_ci, "&", upper_ci)
[1] "95% CI of 2.41 between: 2.025 & 2.795"
We used the t-distribution because both  the population mean and
 the population standard deviation were unknown. Thus, 95 out of 100 confidence intervals would be expected to include the true value.
Bootstrap equivalent
library(confintr)
ci_mean(Tadpole$Body.mass, type=c("bootstrap"), boot_type=c("stud"), R=999, probs=c(0.025, 0.975), seed=1)
Output results are
Two-sided 95% bootstrap confidence interval for the population mean based on 999 bootstrap replications
and the student method

Sample estimate: 2.412308
Confidence interval:
    2.5%    97.5%
2.075808 2.880144
where stud is short for student t distribution (another common option is the percentile method — replace stud with perc), R = 999 directs the function to resample 999 times. We set seed=1 to initialize the pseudorandom number generator so that if we run the command again, we would get the same result. Any integer number can be used. For example, I set seed = 1 for output below
Confidence interval:
    2.5%    97.5%
2.075808 2.880144
compared to repeated runs without initializing the pseudorandom number generator:
Confidence interval:
    2.5%    97.5%
2.067558 2.934055
and again
Confidence interval:
    2.5%    97.5%
2.067616 2.863158
Note that the classic confidence interval is narrower than the bootstrap estimate, in part because of the small sample size (i.e., not as accurate, does not actually achieve the nominal 95% coverage). Which to use? The sample size was small, just 13 tadpoles. Bootstrap samples were drawn from the original data set, thus it cannot make a small study more robust. The 999 samples can be thought as estimating the sampling distribution. If the assumptions of the t-distribution hold, then the classic approach would be preferred. For the Tadpole data set, Body.mass was approximately normally distributed (Anderson-Darling test = 0.21179, p-value = 0.8163). For cases where assumption of a particular distribution is unwarranted (e.g., what is the appropriate distribution when we compare medians among samples?), bootstrap may be preferred (and for small data sets, percentile bootstrap may be better). To complete the analysis, percentile bootstrap estimate of confidence interval are presented.
The R code
ci_mean(Tadpole$Body.mass, type=c("bootstrap"), boot_type=c("perc"), R=999, probs=c(0.025, 0.975), seed=1)
and the output
Two-sided 95% bootstrap confidence interval for the population mean based on 999 bootstrap replications
and the percent method
Sample estimate: 2.412308
Confidence interval:
    2.5%    97.5%
2.076923 2.749231
In this case, the bootstrap percentile confidence interval is narrower than the frequentist approach.
Model coefficients by bootstrap
R code
Enter the model, then set B, the number of samples with replacement.
myBoot <- residual.boot(VO2~Body.mass, B = 1000, data = Tadpoles)
R returns two values:
bootEstParam, which are the bootstrap parameter estimates. Each column in the matrix lists the values for a coefficient. For this model,bootEstParam$[,1]is the intercept andbootEstParam$[,2]is the slope.origEstParam, a vector with the original parameter estimates for the model coefficients.seed, numerical value for the seed; use seed number to get reproducible results. If you don’t specify the seed, then seed is set to pick any random number.
While you can list the $bootEstParam, not advisable because it will be a list of 1000 numbers (the value set with B)!
Get necessary statistics and plots
#95% CI slope
quantile(myBoot$bootEstParam[,2], probs=c(.025, .975))
R returns
    2.5%    97.5%
335.0000 562.6228
#95% CI intercept
quantile(myBoot$bootEstParam[,1], probs=c(.025, .975))
R returns
     2.5%     97.5%
-881.3893 -310.8209
Slope
#plot the sampling distribution of the slope coefficient
par(mar=c(5,5,5,5)) #setting margins to my preferred values
hist(myBoot$bootEstParam[,2], col="blue", main="Bootstrap Sampling Distribution",
xlab="Slope Estimate")
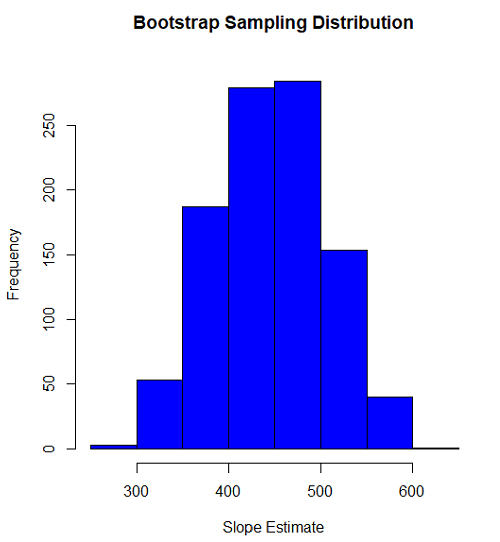
Figure 1. histogram of bootstrap estimates for slope
Intercept
#95% CI intercept
quantile(myBoot$bootEstParam[,1], probs=c(.025, .975))
par(mar=c(5,5,5,5))
hist(myBoot$bootEstParam[,1], col="blue", main="Bootstrap Sampling Distribution",
xlab="Intercept Estimate")
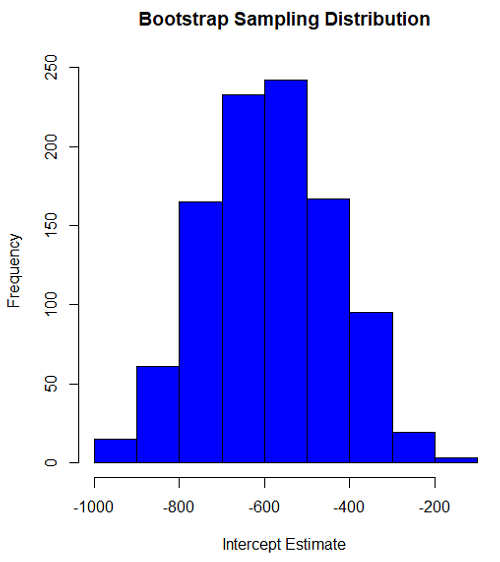
Figure 2. Histogram of bootstrap estimates for intercept.
Questions
edits: pending
Data set used this page (sorted)
| Gosner | Body mass | VO2 |
| I | 1.76 | 109.41 |
| I | 1.88 | 329.06 |
| I | 1.95 | 82.35 |
| I | 2.13 | 198 |
| I | 2.26 | 607.7 |
| II | 2.28 | 362.71 |
| II | 2.35 | 556.6 |
| II | 2.62 | 612.93 |
| II | 2.77 | 514.02 |
| II | 2.97 | 961.01 |
| II | 3.14 | 892.41 |
| II | 3.79 | 976.97 |
| NA | 1.46 | 170.91 |
Chapter 19 contents
- Introduction
- Jackknife sampling
- Bootstrap sampling
- Monte Carlo methods
- Ch19 References and suggested readings
17.6 – ANCOVA – analysis of covariance
Introduction
Analysis of covariance (ANCOVA) is intended to help with analysis of designs with categorical treatment variables on some response (dependent) variable, but a known confounding variable is also present. Thus, the researcher is also likely to know of additional ratio scale variables that covary with the response variable and, moreover, must be included in the experimental design in some way.
Take for example the well-known relationship between body size and whole-animal metabolic rate as measured by rates of carbon dioxide production or rates of oxygen consumption for aerobic organisms. We may be interested in how addition or blocking of stress hormones affects resting metabolism; we may be interested in comparing men and women for activity metabolism, and so on. We’d like to know if the regressions were the same (eg, metabolic rate covaried with body mass in the same way — that is, the slope of the relationship was the same).
This situation arises frequently in biology. For example, we might want to know if male and female birds have different mean field metabolic rates, in which case we might be tempted to use a one-way ANOVA or t-test (since one factor with two levels). However, if males and females also differ for body size, then any differences we might see in metabolic rate could be due to differences in metabolic rate are confounded by differences in the covariable body size. We already discussed one approach to correction: calculate a ratio. Thus, a logical approach to correcting or normalizing for the covariation would be to divide body mass (units of kilograms) into metabolic rate (eg, volume of oxygen, O2, consumed), and make comparisons, say, among different species, on mass-specific trait ( ). However, because the regression between mass and metabolic rate is allometric, i.e., not equal to one, the ratio does not, in fact normalize for body mass. We made this point in Chapter 6.2, and remarked that analysis of covariance ANCOVA was a solution.
ANCOVA allows you to test for mean differences in traits like metabolic rate between two or more groups, but only after first accounting for covariation due to another variable (eg, body size). However, ANCOVA makes the assumption that relationship between the covariable and the response variable is the same in the two groups. This is the same as saying that the regression slopes are the same. We discussed how to use t-test to test hypothesis of equal slopes between regression models in Chapter 17.5, but a more elegant way is to include this in your model.
Example
We return to our sample of 13 tadpoles (Rana pipiens), hatched in the laboratory. I’ve repeated the data set in this page, scroll or click here.
Our linear model was 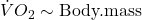 and a scatterplot of the data set is shown in Figure 1 (a repeat of Figure 3 from Chapter 17.5, but now points identified to developmental group).
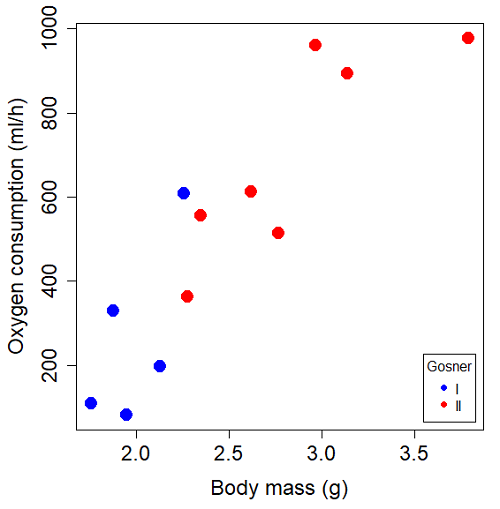
Figure 1. Scatterplot of oxygen consumption by R. pipiens tadpoles vs body mass (g) by developmental group (Gosner stages I or II).
The project looked at whether metabolism as measured by oxygen consumption was consistent across two developmental stages. Metamorphosis in frogs and other amphibians represents profound reorganization of the organism as the tadpole moves from water to air. Thus, we would predict some cost as evidenced by change in metabolism associated with later stages of development. Figure 2 shows a box plot of tadpole oxygen consumption by Gosner (1960) developmental stage (Figure 2 is a repeat of Figure 4 Chapter 17.5).
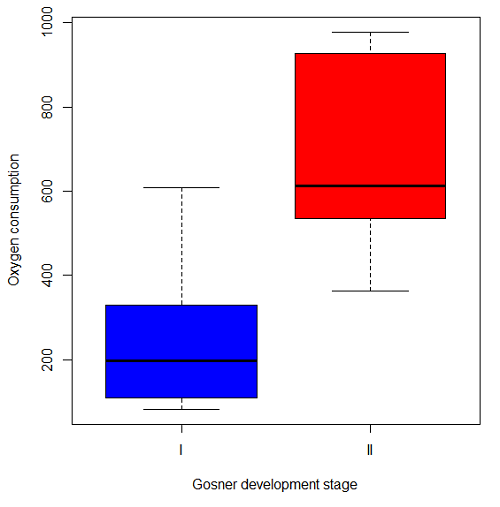
Figure 2. Copy of Figure 4, Chapter 17.5; boxplot of oxygen consumption of R. pipiens tadpoles by Gosner developmental stages.
Looking at Figure 2 we see a trend consistent with our prediction; developmental stage may be associated with increased metabolism. However, older tadpoles also tend to be larger, and the plot in Figure 2 does not account for that. Thus, body mass is a confounding variable in this example. There are several options for analysis here (eg, ANCOVA), but one way to view this is to compare the slopes for the two developmental stages. While this test does not compare the means, it does ask a related question: is there evidence of change in rate of oxygen consumption relative to body size between the two developmental stages? The assumption that the slopes are equal is a necessary step for conducting the ANCOVA.
So, divide the data set (Table 1) into two groups by developmental stage (12 tadpoles could be assigned to one of two developmental stages; one was at a lower Gosner stage than the others and so is dropped from the subset.
Table 1.  and
 of 12 R. pipiens tadpole larvae by Gosner developmental stage.
Gosner stage I
|
|
| 1.76 | 109.41 |
| 1.88 | 329.06 |
| 1.95 | 82.35 |
| 2.13 | 198 |
| 2.26 | 607.7 |
Gosner stage II
| Body mass | |
| 2.28 | 362.71 |
| 2.35 | 556.6 |
| 2.62 | 612.93 |
| 2.77 | 514.02 |
| 2.97 | 961.01 |
| 3.14 | 892.41 |
| 3.79 | 976.97 |
The slopes and standard errors we obtained in Chapter 17.5 were
| Gosner Stage I | Gosner stage II | |
| slope | 750.0 | 399.9 |
| standard error of slope | 444.6 | 111.2 |
Make a plot (Figure 3).
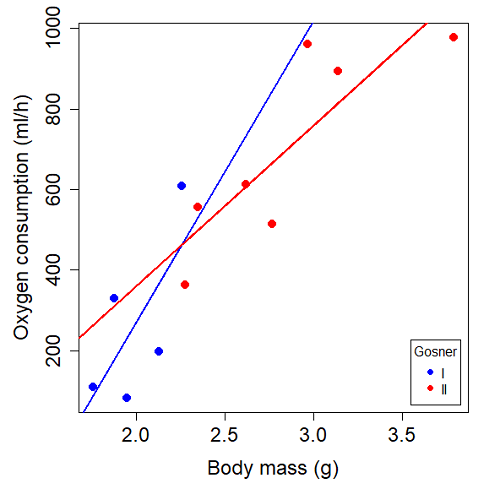
Figure 3. Scatterplot with best-fit regression lines of by for Gosner State I (closed circle, solid line) and Gosner Stage II (open circle, dashed line) R. pipiens tadpoles.
R code for plot in Figure 3.
#Used Rcmdr scatterplot(), then modified code
scatterplot(VO2~Body.mass | Gosner, regLine=FALSE, smooth=FALSE,
boxplots=FALSE, xlab="Body mass (g)", ylab="Oxygen consumption (ml/h)",
main="", cex=1.4, cex.axis=1.5, cex.lab=1.5, pch=c(19,19), by.groups=TRUE,
col=c("blue","red"), grid=FALSE,
legend=list(coords="bottomright"), data=Tadpoles)
#Get regression equations for groups, subset by Gosner
abline(lm(VO2~Body.mass, data=Stage01), lty=1, lwd=2, col="blue")
abline(lm(VO2~Body.mass, data=Stage02), lty=1, lwd=2, col="red")
Returning to the important question, are the two slopes statistically indistinguishable (Ho: bI = bII), where bI is the slope for the Gosner Stage I subset and bII is the slope for the Gosner Stage II subset? We look at the plot, and since the lines cross, we tend to see a difference. Of course, we need to consider that our perception of slope differences may simply be chance, especially because the sample size is small. Proceed to test.
R code
The ANCOVA is a new ANOVA model where the factor variables are adjusted or corrected for the effects of the continuous variable.
R code for ANCOVA example, crossed or interaction model.
tadpole.1 <- lm(VO2 ~ Body.mass*Gosner, data=example.Tadpole)
summary(tadpole.1)
Anova(tadpole.1, type="II")
Output
summary(tadpole.1)

Call:
lm(formula = VO2 ~ Body.mass * Gosner, data = example.Tadpole)

Residuals:
    Min      1Q   Median      3Q      Max
-167.80 -117.93    13.81   94.66   214.65

Coefficients:
                       Estimate   Std. Error   t value    Pr(>|t|)
(Intercept)             -1231.6       783.0     -1.573    0.1544
Body.mass                 750.0       390.7      1.919    0.0912 .
Gosner[T.II]              790.4       859.2      0.920    0.3845
Body.mass:Gosner[T.II]   -350.1       409.5     -0.855    0.4174
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 155.8 on 8 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.821, Adjusted R-squared: 0.7539
F-statistic: 12.23 on 3 and 8 DF, p-value: 0.002336
The coefficients for the first factor (GII) and then the differences in the coefficient for the second factor. You can just add the second coefficient to the first so they’re on the same scale.
Anova Table (Type II tests)

Response: VO2
                  Sum Sq   Df    F value     Pr(>F)
Body.mass         330046    1    13.6030   0.006146 **
Gosner              5630    1     0.2321   0.642908
Body.mass:Gosner   17736    1     0.7310   0.417423
Residuals 194102 8
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Suggests interaction is not significant, i.e., the slopes are not different.
We can then proceed to check to see if the intercepts are different, now that we’ve confirmed no significant difference in slope.
R code for ANCOVA as additive model
tadpole.2 <- lm(VO2 ~ Body.mass + Gosner, data=example.Tadpole)
summary(tadpole.2)
Anova(tadpole.2, type="II")
Output
> summary(tadpole.2)

Call:
lm(formula = VO2 ~ Body.mass + Gosner, data = example.Tadpole)

Residuals:
    Min       1Q    Median      3Q      Max
-163.12  -125.53    -20.27   83.71   228.56

Coefficients:
                   Estimate   Std. Error     t value    Pr(>|t|)
(Intercept)         -595.37       239.87      -2.482     0.03487 *
Body.mass            431.20       115.15       3.745     0.00459 **
Gosner[T.II]          64.96       132.83       0.489     0.63648
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 153.4 on 9 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.8047, Adjusted R-squared: 0.7613
F-statistic: 18.54 on 2 and 9 DF, p-value: 0.0006432

Anova(tadpole.2, type="II")
Anova Table (Type II tests)

Response: VO2
              Sum Sq    Df    F value      Pr(>F)
Body.mass     330046     1    14.0221   0.004593 **
Gosner          5630     1     0.2392   0.636482
Residuals     211839     9
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Note 1. There is no test of interaction in the added model. This model would be appropriate IF the slopes are equal.
Instead of the interaction, or as added, try a nested model, with body mass nested within stage.
tadpole.3 <- lm(VO2 ~ Body.mass/Gosner, data=example.Tadpole)

summary(tadpole.3)

Call:
lm(formula = VO2 ~ Body.mass/Gosner, data = example.Tadpole)

Residuals:
    Min       1Q    Median      3Q      Max
-168.66  -131.14    -20.28   90.33   225.36

Coefficients:
                 Estimate      Std. Error    t value Pr(>|t|)
(Intercept)           -575.10      319.51     -1.800   0.1054
Body.mass              423.65      162.50      2.607   0.0284 *
Body.mass:Gosner[T.II]  21.95       63.73      0.344   0.7384
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 154.4 on 9 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.8021, Adjusted R-squared: 0.7581
F-statistic: 18.24 on 2 and 9 DF, p-value: 0.0006823
Gets the true coefficient (nested lm() version).
The two test different hypotheses.
lm(VO2 ~ Body.mass * Gosner) tests whether or not the regression has a nonzero slope.
lm(VO2 ~ Body.mass */Gosner) test whether or not the slopes and intercepts from different factors are statistically significant.
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- An OLS approach was used for the analysis of tadpole oxygen consumption body mass. Consider the RMA approach — would that be a more appropriate regression model? Explain why or why not.
- Consider an experiment in which you plan to administer a treatment that has a carry-over effect. For example, Compare and contrast “crossed” and “nested” designs.
- True or False. The nested design option for the ANCOVA assumes the slopes for the two groups of tadpoles for the regression line of by are equal. Explain your choice.
- Metabolic rates like oxygen consumption over time are well-known examples of allometric relationships. That is, many biological variables (eg, is related as aMb, where M is body mass, slope b is scaling exponent), and best evaluated on log-log scale. Repeat the analysis above on log10-transformed and for
- crossed design (eg, tadpole.1 model)
- added design (eg, tadpole.2 model)
- nested design (eg, tadpole.3 model)
- Create the plot and add the fitted lines from crossed design to the plot.
Note 2. About log-transform of a variable. The most straight-forward tact is to create two new variables. For example,
lgVO2 <- log10(VO2)
Another option is to transform the variables within the call to lm() function. For example, try
lm(log10(VO2) ~ log10(Body.mass ), data=example.Tadpole)
Hint: don’t forget to attach your data set to avoid having to call the variable as, for example, example.Tadpole$VO2
Quiz Chapter 17.6
ANCOVA - analysis of covariance
Data sets
Oxygen consumption,  , of Anuran tadpoles, dataset=
example.Tadpole
| Gosner | Body mass | VO2 |
|---|---|---|
| NA | 1.46 | 170.91 |
| I | 1.76 | 109.41 |
| I | 1.88 | 329.06 |
| I | 1.95 | 82.35 |
| I | 2.13 | 198 |
| II | 2.28 | 362.71 |
| I | 2.26 | 607.7 |
| II | 2.35 | 556.6 |
| II | 2.62 | 612.93 |
| II | 2.77 | 514.02 |
| II | 2.97 | 961.01 |
| II | 3.14 | 892.41 |
Gosner refers to Gosner (1960), who developed a criteria for judging metamorphosis staging.
Chapter 17 contents
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – Analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)
17.7 – Regression model fit
Introduction
In Chapter 17.5 and 17.6 we introduced the example of tadpoles body size and oxygen consumption. We ran a simple linear regression, with the following output from R
RegModel.1 <- lm(VO2~Body.mass, data=example.Tadpole)

summary(RegModel.1)

Call:
lm(formula = VO2 ~ Body.mass, data = example.Tadpole)

Residuals:
    Min      1Q    Median       3Q       Max
-202.26 -126.35     30.20    94.01    222.55

Coefficients:
                Estimate     Std. Error    t value    Pr(>|t|)
(Intercept)      -583.05         163.97     -3.556     0.00451 **
Body.mass         444.95          65.89      6.753   0.0000314 ***
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 145.3 on 11 degrees of freedom
Multiple R-squared: 0.8057, Adjusted R-squared: 0.788
F-statistic: 45.61 on 1 and 11 DF, p-value: 0.00003144
You should be able to pick out the estimates of slope and intercept from the table (intercept was -583 and slope was 445). Additionally, as part of your interpretation of the model, you should be able to report how much variation in VO2 was explained by tadpole body mass (coefficient of determination,  , was 0.81, which means about 81% of variation in oxygen consumption by tadpoles is explained by knowing the body mass of the tadpole.
What’s left to do? We need to evaluate how well our model fits the data, i.e., we evaluate regression model fit. By fit we mean, how well does our model agree to the raw data? A poor fit and the model predictions are far from the raw data; a good fit, the model accurately predicts the raw data. In other words, if we draw a line through the raw data, a good fit line crosses through most of the points — a poor fit the line rarely passes through the cloud of points.
How to judge fit? This we can do by evaluating the error components relative to the portion of the model that explains the data. Additionally, we can perform a number of diagnostics of the model relative to the assumptions we made to perform linear regression. These diagnostics form the subject of Chapter 17.8. Here, we ask how well does the model,
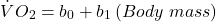
fit the data?
Model fit statistics
The second part of fitting a model is to report how well the model fits the data. The next sections apply to this aspect of model fitting. The first area to focus on is the magnitude of the residuals: the greater the spread of residuals, the less well a fitted line explains the data.
In addition to the output from lm() function, which focuses on the coefficients, we typically generate the ANOVA table also.
Anova(RegModel.1, type="II")
Anova Table (Type II tests)

Response: VO2
                Sum Sq   Df    F value       Pr(>F)
Body.mass       962870    1     45.605   0.00003144 ***
Residuals       232245   11
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Standard error of regression
S, the Residual Standard Error (aka Standard error of regression), is an overall measure to indicate the accuracy of the fitted line: it tells us how good the regression is in predicting the dependence of response variable on the independent variable. A large value for S indicates a poor fit. One equation for S is given by
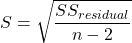
In the above example, S = 145.3 (underlined, bold in regression output above). We can see how if  is large, S will be large indicating poor fit of the linear model to the data. However, by itself S is not of much value as a diagnostic as it is difficult to know what to make of 145.3, for example. Is this a large value for S? Is it small? We don’t have any context to judge S, so additional diagnostics have been developed.
Coefficient of determination
, the coefficient of determination, is also used to describe model fit. can take on values between 0 and 1 (0% to 100%). A good model fit has a high value. In our example above,  or 80.57%. One equation for is given by
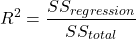
A value of close to 1 means that the regression “explains” nearly all of the variation in the response variable, and would indicate the model is a good fit to the data. As we mentioned in Chapter 17.2, the coefficient of determination, , is the squared value of r, the product moment correlation.
Adjusted R-squared
Before moving on we need to remark on the difference between and adjusted . For Simple Linear Regression there is but one predictor variable, X; for multiple regression there can be many additional predictor variables. Without some correction, will increase with each additional predictor variables. This doesn’t mean the model is more useful, however, and in particular, one cannot compare between models with different numbers of predictors. Therefore, an adjustment is used so that the coefficient of determination remains a useful way to assess how reliable a model is and to permit comparisons of models. Thus, we have the Adjusted  , which is calculated as
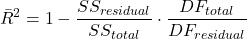
In our example above, Adjusted R 2 = 0.3806 or 38.06%.
Which should you report? Adjusted ,because it is independent of the number of parameters in the model.
Both and S are useful for regression diagnostics, a topic which we will discuss next (Chapter 17.8).
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- As you may know, the US census is used to reapportion congress and also to determine the number of electoral college votes. In honor of the election for US President that’s just days away, in the next series of questions in this Chapter and subsequent sections of Chapter 17 and 18, I’ll ask you to conduct a regression analysis on the electoral college. For starters, make the regression of Electoral votes on 2010 census population. (Ignore for now the other columns, just focus on POP_2019 and Electoral.) Report the
- regression coefficients (slope, intercept)
- percent of the variation in electoral college votes explained by the regression ( ).
- Make a scatterplot and add the regression line to the plot
Quiz Chapter 17.7
Regression model fit
Data set
USA population year 2010 and year 2019 with Electoral College counts
| State | Region | Division | POP_2010 | POP_2019 | Electoral |
|---|---|---|---|---|---|
| Alabama | South | East South Central | 4779736 | 4903185 | 9 |
| Alaska | West | Pacific | 710231 | 731545 | 3 |
| Arizona | West | Mountain | 6392017 | 7278717 | 11 |
| Arkansas | South | West South Central | 2915918 | 3017804 | 6 |
| California | West | Pacific | 37253956 | 39512223 | 55 |
| Colorado | West | Mountain | 5029196 | 5758736 | 9 |
| Connecticut | Northeast | New England | 3574097 | 3565287 | 7 |
| Delaware | South | South Atlantic | 897934 | 982895 | 3 |
| District of Columbia | South | South Atlantic | 601723 | 705749 | 3 |
| Florida | South | South Atlantic | 18801310 | 21477737 | 29 |
| Georgia | South | South Atlantic | 9687653 | 10617423 | 16 |
| Hawaii | West | Pacific | 1360301 | 1415872 | 4 |
| Idaho | West | Mountain | 1567582 | 1787065 | 4 |
| Illinois | Midwest | East North Central | 12830632 | 12671821 | 20 |
| Indiana | Midwest | East North Central | 6483802 | 6732219 | 11 |
| Iowa | Midwest | West North Central | 3046355 | 3155070 | 6 |
| Kansas | Midwest | West North Central | 2853118 | 2913314 | 6 |
| Kentucky | South | East South Central | 4339367 | 4467673 | 8 |
| Louisiana | South | West South Central | 4533372 | 4648794 | 8 |
| Maine | Northeast | New England | 1328361 | 1344212 | 4 |
| Maryland | South | South Atlantic | 5773552 | 6045680 | 10 |
| Massachusetts | Northeast | New England | 6547629 | 6892503 | 11 |
| Michigan | Midwest | East North Central | 9883640 | 9883635 | 16 |
| Minnesota | Midwest | West North Central | 5303925 | 5639632 | 10 |
| Mississippi | South | East South Central | 2967297 | 2976149 | 6 |
| Missouri | Midwest | West North Central | 5988927 | 6137428 | 10 |
| Montana | West | Mountain | 989415 | 1068778 | 3 |
| Nebraska | Midwest | West North Central | 1826341 | 1934408 | 5 |
| Nevada | West | Mountain | 2700551 | 3080156 | 6 |
| New Hampshire | Northeast | New England | 1316470 | 1359711 | 4 |
| New Jersey | Northeast | Mid-Atlantic | 8791894 | 8882190 | 14 |
| New Mexico | West | Mountain | 2059179 | 2096829 | 5 |
| New York | Northeast | Mid-Atlantic | 19378102 | 19453561 | 29 |
| North Carolina | South | South Atlantic | 9535483 | 10488084 | 15 |
| North Dakota | Midwest | West North Central | 672591 | 762062 | 3 |
| Ohio | Midwest | East North Central | 11536504 | 11689100 | 18 |
| Oklahoma | South | West South Central | 3751351 | 3956971 | 7 |
| Oregon | West | Pacific | 3831074 | 4217737 | 7 |
| Pennsylvania | Northeast | Mid-Atlantic | 12702379 | 12801989 | 20 |
| Rhode Island | Northeast | New-England | 1052567 | 1059361 | 4 |
| South Carolina | South | South-Atlantic | 4625364 | 5148714 | 9 |
| South Dakota | Midwest | West-North-Central | 814180 | 884659 | 3 |
| Tennessee | South | East-South-Central | 6346105 | 6829174 | 11 |
| Texas | South | West-South-Central | 25145561 | 28995881 | 38 |
| Utah | West | Mountain | 2763885 | 3205958 | 6 |
| Vermont | Northeast | New-England | 625741 | 623989 | 3 |
| Virginia | South | South-Atlantic | 8001024 | 8535519 | 13 |
| Washington | West | Pacific | 6724540 | 7614893 | 12 |
| West Virginia | South | South-Atlantic | 1852994 | 1792147 | 5 |
| Wisconsin | Midwest | East-North-Central | 5686986 | 5822434 | 10 |
| Wyoming | West | Mountain | 563626 | 578759 | 3 |
Chapter 17 contents
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – Analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)