17.6 – ANCOVA – analysis of covariance
Introduction
Analysis of covariance (ANCOVA) is intended to help with analysis of designs with categorical treatment variables on some response (dependent) variable, but a known confounding variable is also present. Thus, the researcher is also likely to know of additional ratio scale variables that covary with the response variable and, moreover, must be included in the experimental design in some way.
Take for example the well-known relationship between body size and whole-animal metabolic rate as measured by rates of carbon dioxide production or rates of oxygen consumption for aerobic organisms. We may be interested in how addition or blocking of stress hormones affects resting metabolism; we may be interested in comparing men and women for activity metabolism, and so on. We’d like to know if the regressions were the same (eg, metabolic rate covaried with body mass in the same way — that is, the slope of the relationship was the same).
This situation arises frequently in biology. For example, we might want to know if male and female birds have different mean field metabolic rates, in which case we might be tempted to use a one-way ANOVA or t-test (since one factor with two levels). However, if males and females also differ for body size, then any differences we might see in metabolic rate could be due to differences in metabolic rate are confounded by differences in the covariable body size. We already discussed one approach to correction: calculate a ratio. Thus, a logical approach to correcting or normalizing for the covariation would be to divide body mass (units of kilograms) into metabolic rate (eg, volume of oxygen, O2, consumed), and make comparisons, say, among different species, on mass-specific trait ( ). However, because the regression between mass and metabolic rate is allometric, i.e., not equal to one, the ratio does not, in fact normalize for body mass. We made this point in Chapter 6.2, and remarked that analysis of covariance ANCOVA was a solution.
ANCOVA allows you to test for mean differences in traits like metabolic rate between two or more groups, but only after first accounting for covariation due to another variable (eg, body size). However, ANCOVA makes the assumption that relationship between the covariable and the response variable is the same in the two groups. This is the same as saying that the regression slopes are the same. We discussed how to use t-test to test hypothesis of equal slopes between regression models in Chapter 17.5, but a more elegant way is to include this in your model.
Example
We return to our sample of 13 tadpoles (Rana pipiens), hatched in the laboratory. I’ve repeated the data set in this page, scroll or click here.
Our linear model was 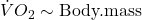 and a scatterplot of the data set is shown in Figure 1 (a repeat of Figure 3 from Chapter 17.5, but now points identified to developmental group).
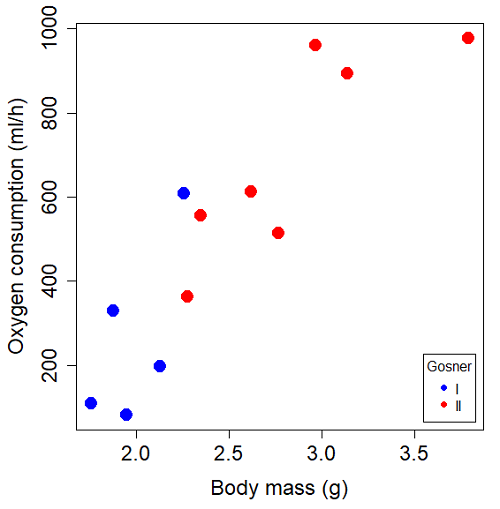
Figure 1. Scatterplot of oxygen consumption by R. pipiens tadpoles vs body mass (g) by developmental group (Gosner stages I or II).
The project looked at whether metabolism as measured by oxygen consumption was consistent across two developmental stages. Metamorphosis in frogs and other amphibians represents profound reorganization of the organism as the tadpole moves from water to air. Thus, we would predict some cost as evidenced by change in metabolism associated with later stages of development. Figure 2 shows a box plot of tadpole oxygen consumption by Gosner (1960) developmental stage (Figure 2 is a repeat of Figure 4 Chapter 17.5).
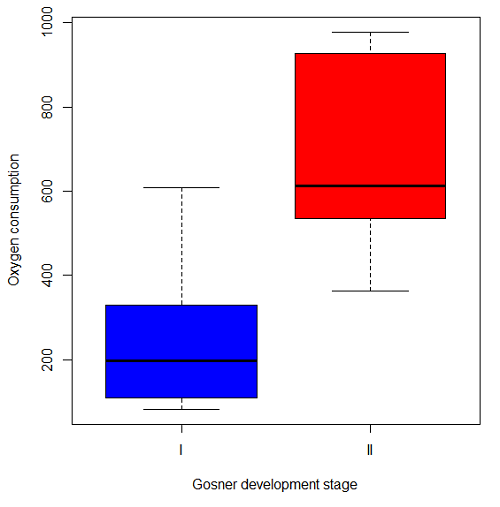
Figure 2. Copy of Figure 4, Chapter 17.5; boxplot of oxygen consumption of R. pipiens tadpoles by Gosner developmental stages.
Looking at Figure 2 we see a trend consistent with our prediction; developmental stage may be associated with increased metabolism. However, older tadpoles also tend to be larger, and the plot in Figure 2 does not account for that. Thus, body mass is a confounding variable in this example. There are several options for analysis here (eg, ANCOVA), but one way to view this is to compare the slopes for the two developmental stages. While this test does not compare the means, it does ask a related question: is there evidence of change in rate of oxygen consumption relative to body size between the two developmental stages? The assumption that the slopes are equal is a necessary step for conducting the ANCOVA.
So, divide the data set (Table 1) into two groups by developmental stage (12 tadpoles could be assigned to one of two developmental stages; one was at a lower Gosner stage than the others and so is dropped from the subset.
Table 1.  and
 of 12 R. pipiens tadpole larvae by Gosner developmental stage.
Gosner stage I
|
|
| 1.76 | 109.41 |
| 1.88 | 329.06 |
| 1.95 | 82.35 |
| 2.13 | 198 |
| 2.26 | 607.7 |
Gosner stage II
| Body mass | |
| 2.28 | 362.71 |
| 2.35 | 556.6 |
| 2.62 | 612.93 |
| 2.77 | 514.02 |
| 2.97 | 961.01 |
| 3.14 | 892.41 |
| 3.79 | 976.97 |
The slopes and standard errors we obtained in Chapter 17.5 were
| Gosner Stage I | Gosner stage II | |
| slope | 750.0 | 399.9 |
| standard error of slope | 444.6 | 111.2 |
Make a plot (Figure 3).
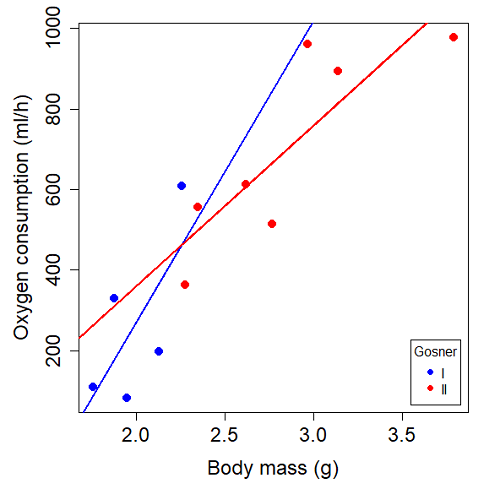
Figure 3. Scatterplot with best-fit regression lines of by for Gosner State I (closed circle, solid line) and Gosner Stage II (open circle, dashed line) R. pipiens tadpoles.
R code for plot in Figure 3.
#Used Rcmdr scatterplot(), then modified code
scatterplot(VO2~Body.mass | Gosner, regLine=FALSE, smooth=FALSE,
boxplots=FALSE, xlab="Body mass (g)", ylab="Oxygen consumption (ml/h)",
main="", cex=1.4, cex.axis=1.5, cex.lab=1.5, pch=c(19,19), by.groups=TRUE,
col=c("blue","red"), grid=FALSE,
legend=list(coords="bottomright"), data=Tadpoles)
#Get regression equations for groups, subset by Gosner
abline(lm(VO2~Body.mass, data=Stage01), lty=1, lwd=2, col="blue")
abline(lm(VO2~Body.mass, data=Stage02), lty=1, lwd=2, col="red")
Returning to the important question, are the two slopes statistically indistinguishable (Ho: bI = bII), where bI is the slope for the Gosner Stage I subset and bII is the slope for the Gosner Stage II subset? We look at the plot, and since the lines cross, we tend to see a difference. Of course, we need to consider that our perception of slope differences may simply be chance, especially because the sample size is small. Proceed to test.
R code
The ANCOVA is a new ANOVA model where the factor variables are adjusted or corrected for the effects of the continuous variable.
R code for ANCOVA example, crossed or interaction model.
tadpole.1 <- lm(VO2 ~ Body.mass*Gosner, data=example.Tadpole)
summary(tadpole.1)
Anova(tadpole.1, type="II")
Output
summary(tadpole.1)

Call:
lm(formula = VO2 ~ Body.mass * Gosner, data = example.Tadpole)

Residuals:
    Min      1Q   Median      3Q      Max
-167.80 -117.93    13.81   94.66   214.65

Coefficients:
                       Estimate   Std. Error   t value    Pr(>|t|)
(Intercept)             -1231.6       783.0     -1.573    0.1544
Body.mass                 750.0       390.7      1.919    0.0912 .
Gosner[T.II]              790.4       859.2      0.920    0.3845
Body.mass:Gosner[T.II]   -350.1       409.5     -0.855    0.4174
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 155.8 on 8 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.821, Adjusted R-squared: 0.7539
F-statistic: 12.23 on 3 and 8 DF, p-value: 0.002336
The coefficients for the first factor (GII) and then the differences in the coefficient for the second factor. You can just add the second coefficient to the first so they’re on the same scale.
Anova Table (Type II tests)

Response: VO2
                  Sum Sq   Df    F value     Pr(>F)
Body.mass         330046    1    13.6030   0.006146 **
Gosner              5630    1     0.2321   0.642908
Body.mass:Gosner   17736    1     0.7310   0.417423
Residuals 194102 8
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Suggests interaction is not significant, i.e., the slopes are not different.
We can then proceed to check to see if the intercepts are different, now that we’ve confirmed no significant difference in slope.
R code for ANCOVA as additive model
tadpole.2 <- lm(VO2 ~ Body.mass + Gosner, data=example.Tadpole)
summary(tadpole.2)
Anova(tadpole.2, type="II")
Output
> summary(tadpole.2)

Call:
lm(formula = VO2 ~ Body.mass + Gosner, data = example.Tadpole)

Residuals:
    Min       1Q    Median      3Q      Max
-163.12  -125.53    -20.27   83.71   228.56

Coefficients:
                   Estimate   Std. Error     t value    Pr(>|t|)
(Intercept)         -595.37       239.87      -2.482     0.03487 *
Body.mass            431.20       115.15       3.745     0.00459 **
Gosner[T.II]          64.96       132.83       0.489     0.63648
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 153.4 on 9 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.8047, Adjusted R-squared: 0.7613
F-statistic: 18.54 on 2 and 9 DF, p-value: 0.0006432

Anova(tadpole.2, type="II")
Anova Table (Type II tests)

Response: VO2
              Sum Sq    Df    F value      Pr(>F)
Body.mass     330046     1    14.0221   0.004593 **
Gosner          5630     1     0.2392   0.636482
Residuals     211839     9
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Note 1. There is no test of interaction in the added model. This model would be appropriate IF the slopes are equal.
Instead of the interaction, or as added, try a nested model, with body mass nested within stage.
tadpole.3 <- lm(VO2 ~ Body.mass/Gosner, data=example.Tadpole)

summary(tadpole.3)

Call:
lm(formula = VO2 ~ Body.mass/Gosner, data = example.Tadpole)

Residuals:
    Min       1Q    Median      3Q      Max
-168.66  -131.14    -20.28   90.33   225.36

Coefficients:
                 Estimate      Std. Error    t value Pr(>|t|)
(Intercept)           -575.10      319.51     -1.800   0.1054
Body.mass              423.65      162.50      2.607   0.0284 *
Body.mass:Gosner[T.II]  21.95       63.73      0.344   0.7384
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 154.4 on 9 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.8021, Adjusted R-squared: 0.7581
F-statistic: 18.24 on 2 and 9 DF, p-value: 0.0006823
Gets the true coefficient (nested lm() version).
The two test different hypotheses.
lm(VO2 ~ Body.mass * Gosner) tests whether or not the regression has a nonzero slope.
lm(VO2 ~ Body.mass */Gosner) test whether or not the slopes and intercepts from different factors are statistically significant.
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- An OLS approach was used for the analysis of tadpole oxygen consumption body mass. Consider the RMA approach — would that be a more appropriate regression model? Explain why or why not.
- Consider an experiment in which you plan to administer a treatment that has a carry-over effect. For example, Compare and contrast “crossed” and “nested” designs.
- True or False. The nested design option for the ANCOVA assumes the slopes for the two groups of tadpoles for the regression line of by are equal. Explain your choice.
- Metabolic rates like oxygen consumption over time are well-known examples of allometric relationships. That is, many biological variables (eg, is related as aMb, where M is body mass, slope b is scaling exponent), and best evaluated on log-log scale. Repeat the analysis above on log10-transformed and for
- crossed design (eg, tadpole.1 model)
- added design (eg, tadpole.2 model)
- nested design (eg, tadpole.3 model)
- Create the plot and add the fitted lines from crossed design to the plot.
Note 2. About log-transform of a variable. The most straight-forward tact is to create two new variables. For example,
lgVO2 <- log10(VO2)
Another option is to transform the variables within the call to lm() function. For example, try
lm(log10(VO2) ~ log10(Body.mass ), data=example.Tadpole)
Hint: don’t forget to attach your data set to avoid having to call the variable as, for example, example.Tadpole$VO2
Quiz Chapter 17.6
ANCOVA - analysis of covariance
Data sets
Oxygen consumption,  , of Anuran tadpoles, dataset=
example.Tadpole
| Gosner | Body mass | VO2 |
|---|---|---|
| NA | 1.46 | 170.91 |
| I | 1.76 | 109.41 |
| I | 1.88 | 329.06 |
| I | 1.95 | 82.35 |
| I | 2.13 | 198 |
| II | 2.28 | 362.71 |
| I | 2.26 | 607.7 |
| II | 2.35 | 556.6 |
| II | 2.62 | 612.93 |
| II | 2.77 | 514.02 |
| II | 2.97 | 961.01 |
| II | 3.14 | 892.41 |
Gosner refers to Gosner (1960), who developed a criteria for judging metamorphosis staging.
Chapter 17 contents
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – Analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)
16.2 – Causation and Partial correlation
Introduction
Science driven by statistical inference and model building is largely motivated by the the drive to identify pathways of cause and effect linking events and phenomena observed all around us. (We first defined cause and effect in Chapter 2.4) The history of philosophy, from the works of Ancient Greece, China, Middle East and so on is rich in the language of cause and effect. From these traditions we have a number of ways to think of cause and effect, but for us it will be enough to review the logical distinction among three kinds of cause-effect associations:
- Necessary cause
- Sufficient cause
- Contributory cause
Here’s how the logic works. If A is a necessary cause of B, then the mere fact that B is present implies that A must also be present. However, that the presence of A does not imply that B will occur. If A is a sufficient cause of B, then the presence of A necessarily implies the presence of B. However, another cause C may alternatively cause B. Enter the contributory or related cause: A cause may be contributory if the presumed cause A (1) occurs before the effect B, and (2) changing A also changes B. A contributory cause does not need to be necessary nor must it be sufficient; contributory causes play a role in cause and effect.
Thus, following this long tradition of thinking about causality we have the mantra, “Correlation does not imply causation.” The exact phrase was written as early as emphasized by Karl Pearson who invented the statistic back in the late 1800s. This well-worn slogan deserves to be on T-shirts and bumper stickers*, and perhaps to be viewed as the single most important concept you can take from a course in philosophy/statistics. But in practice, we will always be tempted to stray from this guidance. The developments in genome-wide-association studies, or GWAS, are designed to look for correlations, as evidenced by statistical linkage analysis, between variation at one DNA base pair and presence/absence of disease or condition in humans and animal models. These are costly studies to do and in the end, the results are just that, evidence of associations (correlations), not proof of genetic cause and effect. We are less likely to be swayed by a correlation that is weak, but what about correlations that are large, even close to one? Is not the implication of high, statistically significant correlation evidence of causation? No, necessary, but not sufficient.
Note 1. A helpful review on causation in epidemiology is available from Parascandola and Weed (2001); see also Kleinberg and Hripcsak (2011). For more on “correlation does not imply causation”, try the Wikipedia entry. Obviously, researchers who engage in genome wide association studies are aware of these issues: see for example discussion by Hu et al (2018) on causal inference and GWAS.
Causal inference (Pearl 2009; Pearl and Mackenzie 2018), in brief, employs a model to explain the association between dependent and multiple, likely interrelated candidate causal variable, which is then subject to testing — is the model stable when the predictor variables are manipulated, when additional connections are considered (eg, predictor variable 1 covaries with one or more other predictor variables in the model). Wright’s path analysis, now included as one approach to Structural Equation Modeling, is used to relate equations (models) of variation in observed variables attributed to direct and indirect effects from predictor variables.
* And yes, a quick Google search reveals lots of bumper stickers and T-shirts available with the causation  sentiment.
Spurious correlations
Correlation estimates should be viewed as hypotheses in the scientific sense of the meaning of hypotheses for putative cause-effect pairings. To drive the point home, explore the web site “Spurious Correlations” at https://www.tylervigen.com/spurious-correlations , which allows you to generate X-Y plots and estimate correlations among many different variables. Some of my favorite correlations from “Spurious Correlations” include (Table 1):
Table 1. Spurious correlations, https://www.tylervigen.com/spurious-correlations
| First variable | Second variable | Correlation |
| Divorce rate in Maine, USA | Per capita USA consumption of margarine | +0.993 |
| Honey producing bee colonies USA | Juvenile arrests for marijuana possession | -0.933 |
| Per capita USA consumption of mozzarella cheese | Civil engineering PhD awarded USA | +0.959 |
| Total number of ABA lawyers USA | Cost of red delicious apples | +0.879 |
These are some pretty strong correlations (cf. effect size discussion, Ch11.4 and 16.1), about as close to +1 as you can get. But really, do you think the amount of cheese that is consumed in the USA has anything to do with the number of PhD degrees awarded in engineering or that apple prices are largely set by the number of lawyers in the USA? Cause and effect implies there must also be some plausible mechanism, not just a strong correlation.
But that does NOT ALSO mean that a high correlation is meaningless. The primary reason a correlation cannot tell about causation is because of the problem (potentially) of an UNMEASURED variable (a confounding variable) being the real driving force (Fig 1).
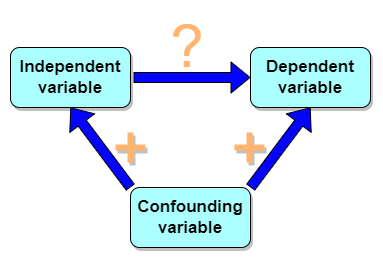
Figure 1. Unmeasured confounding variables influence association between independent and dependent variables, the characters or traits we are interested in.
Here’s a plot of running times for the best, fastest men and women runners for the 100-meter sprint. Running times over 100 meters of top athletes since the 1920s. The data are collated for you and presented at end of this page (scroll or click here).
Here’s a scatterplot (Fig 2).
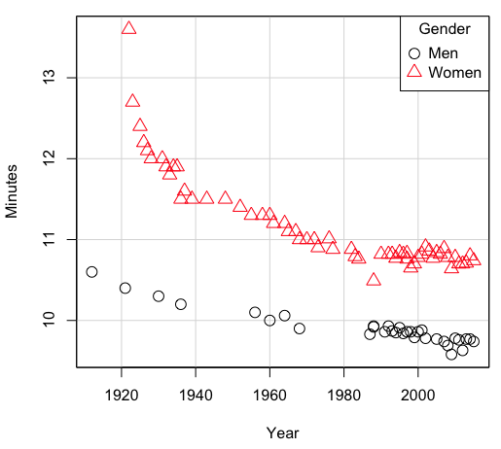
Figure 2. Running times over 100 meters of top athletes since the 1920s.
There’s clearly a negative correlation between years and running times. Is the rate of improvement in running times the same for men and women? Is the improvement linear? What, if any, are the possible confounding variables? Height? weight? Biomechanical differences? Society? Training? Genetics? … Performance enhancing drugs…?
If we measure potential confounding factors, we may be able to determine the strength of correlation between two variables that share variation with a third variable.
The partial correlation
There are several ways to work this problem. The partial correlation is a useful way to handle this problem, i.e., where a measured third variable is positively correlated with the two variable you are interested in.
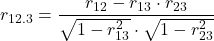
Without formal mathematical proof presented, r12.3 is the correlation between variables 1 and 2 INDEPENDENT of any covariation with variable 3.
For our running data set, we have the correlation between women’s time for 100m over 9 decades, (r13 = -0.876), between men’s time for 100m over 9 decades (r23 = -0.952), and finally, the correlation we’re interested in, whether men’s and women’s times are correlated (r12 = +0.71). When we use the partial correlation, however, I get r12.3 = -0.819… much less than 0 and significantly different from zero. In other words, men’s and women’s times are not positively correlated independent of the correlation both share with the passage of time (decades)! The interpretation is that men are getting faster at a rate faster than women.
In conclusion, keep your head about you when you are doing analyses. You may not have the skills or knowledge to handle some problems (partial correlation), but you can think simply — why are two variables correlated? One causes the other to increase (or decrease) OR the two are both correlated with another variable.
Testing the partial correlation
Like our simple correlation, the partial correlation may be tested by a t-test, although modified to account for the number of pairwise correlations (Wetzels and Wagenmakers 2012). The equation for the t test statistic is now
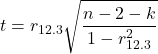
with k equal to the number of pairwise correlations and n – 2 – k degrees of freedom.
Examples
Lead exposure and low birth weigh. The data set is numbers of low birth weight births (< 2,500 g regardless of gestational age) and numbers of children with high levels of lead (10 or more micrograms of lead in a deciliter of blood) measured from their blood. Data used for 42 cities and towns of Rhode Island, United States of America (data at end of this page, scroll or click here to access the data).
A scatterplot of number of children with high lead is shown below (Fig 3).
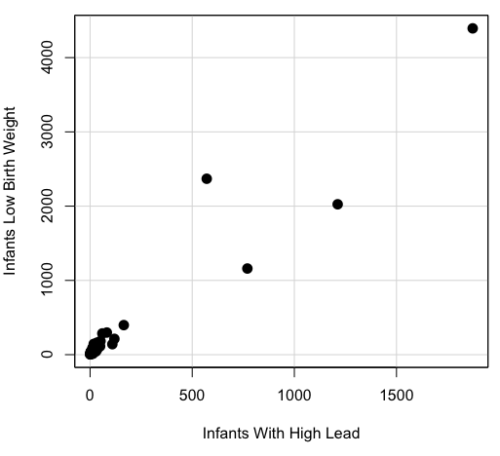
Figure 3. Scatterplot birth weight by lead exposure.
The product moment correlation was r = 0.961, t = 21.862, df = 40, p < 2.2e-16. So, at first blush looking at the scatterplot and the correlation coefficient, we conclude that there is a significant relationship between lead and low birth weight, right?
However, by the description of the data you should recall that counts were reported, not rates (eg, per 100,000 people). Clearly, population size varies among the cities and towns of Rhode Island. West Greenwich had 5085 people whereas Providence had 173,618. We should suspect that there is also a positive correlation between number of children born with low birth weight and numbers of children with high levels of lead. Indeed there are.
Correlation between Low Birth Weight and Population, r = 0.982
Correlation between High Lead levels and Population, r = 0.891
The question becomes, after removing the covariation with population size is there a linear association between high lead and low birth weight? One option is to calculate the partial correlation. To get partial correlations in Rcmdr, select
Statistics → Summaries → Correlation matrix
then select “partial” and select all three variables (select + Ctrl key; (Windows or macOS) (Fig 4).
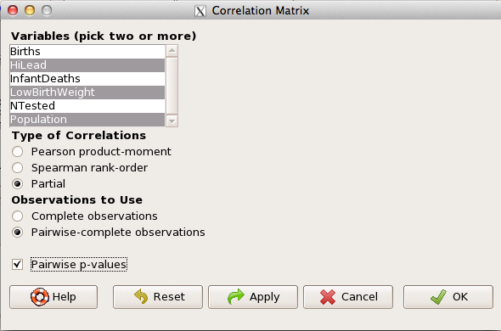
Figure 4. Screenshot Rcmdr partial correlation menu
Results are shown below.
partial.cor(leadBirthWeight[,c("HiLead","LowBirthWeight","Population")], tests=TRUE, use="complete")

Partial correlations:
                 HiLead LowBirthWeight Population
HiLead          0.00000        0.99181   -0.97804
LowBirthWeight  0.99181        0.00000    0.99616
Population     -0.97804        0.99616    0.00000
Thus, after removing the covariation we conclude there is indeed a strong correlation between lead and low birth weights.
Note 2. Some verbiage about correlation tables (matrices). The matrix is symmetric and the information is repeated. I highlighted the diagonal in green. The upper triangle (red) is identical to the lower triangle (blue). When you publish such matrices, don’t publish both the upper and lower triangles; it’s also not necessary to publish the on-diagonal numbers, which are generally not of interest. Thus, the publishable matrix would be
Partial correlations:
                LowBirthWeight Population
HiLead                 0.99181   -0.97804
LowBirthWeight                    0.99616
Another example
Do Democrats prefer cats? The question I was interested in, Do liberals really prefer cats, was inspired by a Time magazine 18 February 2014 article. I collated data on a separate but related question: Do states with more registered Democrats have more cat owners? The data set was compiled from three sources: 2010 USA Census, a 2011 Gallup poll about religious preferences, and from a data book on survey results of USA pet owners (data at end of this page, scroll or click here to access the data).
Note 3: This type of data set involves questions about groups, not individuals. We have access to aggregate statistics for groups (city, county, state, region), but not individuals. Thus, our conclusions are about groups and cannot be used to predict individual behavior, eg, knowing a person votes Green Party does not mean they necessarily share their home with a cat). See ecological fallacy.
This data set also demonstrates use of transformations of the data to improve fit of the data to statistical assumptions (normality, homoscedacity).
The variables, and their definitions, were:
ASDEMS = DEMOCRATS. Democrat advantage: the difference in registered Democrats compared to registered Republicans as a percentage; to improve the distribution qualities the arcsine transform was applied..
ASRELIG = RELIGION. Percent Religious from a Gallup poll who reported that Religion was “Very Important” to them. Also arcsine-transformed to improve normality and homoescedasticity (there you go, throwing $3 words around 🤠 ).
LGCAT = Number of pet cats, log10-transformed, estimated for USA states by survey, except Alaska and Hawaiʻi (not included in the survey by the American Veterinary Association).
LGDOG = Estimated number of pet dogs, log10-transformed for states, except Alaska and Hawaiʻi (not included in the survey by the American Veterinary Association).
LGIPC = Per capita income, log10-transformed.
LGPOP = Population size of each state, log10 transformed.
As always, begin with data exploration. All of the variables were right-skewed, so I applied data transformation functions as appropriate: log10 for the quantitative data and arc sine transform for the frequency variables. Because Democrat Advantage and Percent Religious variables were in percentages, the values were first divided by 100 to make frequencies, then the R function asin() was applied. All analyses were conducted on the transformed data, therefore conclusions apply to the transformed data.
Note 4: As we’ve discussed before, to relate the results to the original scales, back transformations would need to be run on any predictions. Back transformation for log10 would be power of ten; for the arcsine-transform the inverse of the arcsine would be used.
A scatter plot matrix (KMggplo2) plus histograms of the variables along the diagonals shows the results of the transforms and hints at the associations among the variables. A graphic like this one is called a trellis plot; a layout of smaller plots in a grid with the same (preferred) or at least similar axes. Trellis plots (Fig 5) are useful for finding the structure and patterns in complex data. Scanning across a row shows relationships between one variable with all of the others. For example, the first row Y-axis is for the ASDEMS variable; from left to right along the row we have, after the histogram, what look to be weak associations between ASDEMS and ASRELIG, LGCAT, LGDOG, and LGDOG.
Figure 5. Trellis plot, correlations among variables.
A matrix of partial correlations was produced from the Rcmdr correlation call. Thus, to pick just one partial correlation, the association between DEMOCRATS and RELIGION (reported as “very important”) is negative (r = -0.45) and from the second matrix we retrieve the approximate P-value, unadjusted for the multiple comparisons problem, of p = 0.0024. We quickly move past this matrix to the adjusted P-values and confirm that this particular correlation is statistically significant even after correcting for multiple comparisons. Thus, there is a moderately strong negative correlation between those who reported that religion was very important to them and the difference between registered Democrats and Republicans in the 48 states. Because it is a partial correlation, we can conclude that this correlation is independent of all of the other included variables.
And what about our original question: Do Democrats prefer cats over dogs? The partial correlation after adjusting for all of the other correlated variables is small (r = 0.05) and not statistically different from zero (P-value greater than 5%).
Are there any interesting associations involving pet ownership in this data set? See if you can find it (hint: the correlation you are looking for is also in red).
Partial correlations:
         ASDEMS  ASRELIG LGCAT   LGDOG   LGIPC   LGPOP
ASDEMS   0.0000 -0.4460  0.0487  0.0605  0.1231 -0.0044
ASRELIG -0.4460  0.0000 -0.2291 -0.0132 -0.4685  0.2659
LGCAT    0.0487 -0.2291  0.0000  0.2225 -0.1451  0.6348
LGDOG    0.0605 -0.0132  0.2225  0.0000 -0.6299  0.5953
LGIPC    0.1231 -0.4685 -0.1451 -0.6299  0.0000  0.6270
LGPOP   -0.0044  0.2659  0.6348  0.5953  0.6270  0.0000
Raw P-values, Pairwise two-sided p-values:
         ASDEMS ASRELIG  LGCAT   LGDOG   LGIPC   LGPOP
ASDEMS           0.0024  0.7534  0.6965  0.4259  0.9772
ASRELIG  0.0024          0.1347  0.9325  0.0013  0.0810
LGCAT    0.7534  0.1347          0.1465  0.3473  <.0001
LGDOG    0.6965  0.9325  0.1465          <.0001  <.0001
LGIPC    0.4259  0.0013  0.3473  <.0001          <.0001
LGPOP    0.9772  0.0810  <.0001  <.0001  <.0001
Adjusted P-values, Holm’s method (Benjamini and Hochberg 1995)
         ASDEMS ASRELIG  LGCAT   LGDOG   LGIPC   LGPOP
ASDEMS           0.0241  1.0000  1.0000  1.0000  1.0000
ASRELIG  0.0241          1.0000  1.0000  0.0147  0.7293
LGCAT    1.0000  1.0000          1.0000  1.0000  <.0001
LGDOG    1.0000  1.0000  1.0000          <.0001  0.0002
LGIPC    1.0000  0.0147  1.0000  <.0001          <.0001
LGPOP    1.0000  0.7293  <.0001  0.0002  <.0001
A graph (Fig 6) to summarize the partial correlations: green lines indicate positive correlation, red lines show negative correlations; Strength of association indicated by the line thickness, with thicker lines corresponding to greater correlation.
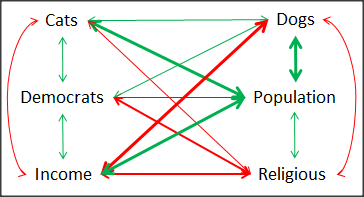
Figure 6. Causal paths among variables.
As you can see, partial correlation analysis is good for a few variables, but as the numbers increase it is difficult to make heads or tails out of the analysis. Better methods for working with these highly correlated data in what we call multivariate data analysis, for example Structural Equation Modeling or Path Analysis.
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- Spurious correlations can be challenging to recognize, and, sometimes, they become part of a challenge to medicine to explain away. A classic spurious correlation is the correlation between rates of MMR vaccination and autism prevalence. Here’s a table of numbers for you
| Year | Herb Supplement Revenue, millions $ | Fertility rate per 1000 births, women age 35 and older+ | MMR per 100K children age 0 -5 | UFC revenue, millions $ | Autism Prevalence per 1000 |
|---|---|---|---|---|---|
| 2000 | 4225 | 47.7 | 179 | 6.7 | |
| 2001 | 4361 | 48.6 | 183 | 4.5 | |
| 2002 | 4275 | 49.9 | 190 | 8.7 | 6.6 |
| 2003 | 4146 | 52.6 | 196 | 7.5 | |
| 2004 | 4288 | 54.5 | 199 | 14.3 | 8 |
| 2005 | 4378 | 55.5 | 197 | 48.3 | |
| 2006 | 4558 | 56.9 | 198 | 180 | 9 |
| 2007 | 4756 | 57.6 | 204 | 226 | |
| 2008 | 4800 | 56.7 | 202 | 275 | 11.3 |
| 2009 | 5037 | 56.1 | 201 | 336 | |
| 2010 | 5049 | 56.1 | 209 | 441 | 14.4 |
| 2011 | 5302 | 57.5 | 212 | 437 | |
| 2012 | 5593 | 58.7 | 216 | 446 | 14.5 |
| 2013 | 6033 | 59.7 | 220 | 516 | |
| 2014 | 6441 | 61.6 | 224 | 450 | 16.8 |
| 2015 | 6922 | 62.8 | 222 | 609 | |
| 2016 | 7452 | 64.1 | 219 | 666 | 18.5 |
| 2017 | 8085 | 63.9 | 213 | 735 | |
| 2018 | 65.3 | 220 | 800 | 25 |
- Make scatterplots of autism prevalence vs
- Herb supplement revenue
- Fertility rate
- MMR vaccination
- UFC revenue
- Calculate and test correlations between autism prevalence vs
- Herb supplement revenue
- Fertility rate
- MMR vaccination
- UFC revenue
- Interpret the correlations — is there any clear case for autism vs MMR?
- What additional information is missing from Table 2? Add that missing variable and calculate partial correlations for autism prevalence vs
- Herb supplement revenue
- Fertility rate
- MMR vaccination
- UFC revenue
- Do a little research: What are some reasons for increase in autism prevalence? What is the consensus view about MMR vaccine and risk of autism?
Quiz Chapter 16.2
Causation and Partial correlation
Data sets
Data used in this page, 100 meter running times since 1900.
| Year | Men | Women |
|---|---|---|
| 1912 | 10.6 | |
| 1913 | ||
| 1914 | ||
| 1915 | ||
| 1916 | ||
| 1917 | ||
| 1918 | ||
| 1919 | ||
| 1920 | ||
| 1921 | 10.4 | |
| 1922 | 13.6 | |
| 1923 | 12.7 | |
| 1924 | ||
| 1925 | 12.4 | |
| 1926 | 12.2 | |
| 1927 | 12.1 | |
| 1928 | 12 | |
| 1929 | ||
| 1930 | 10.3 | |
| 1931 | 12 | |
| 1932 | 11.9 | |
| 1933 | 11.8 | |
| 1934 | 11.9 | |
| 1935 | 11.9 | |
| 1936 | 10.2 | 11.5 |
| 1937 | 11.6 | |
| 1938 | ||
| 1939 | 11.5 | |
| 1940 | ||
| 1941 | ||
| 1942 | ||
| 1943 | 11.5 | |
| 1944 | ||
| 1945 | ||
| 1946 | ||
| 1947 | ||
| 1948 | 11.5 | |
| 1949 | ||
| 1950 | ||
| 1951 | ||
| 1952 | 11.4 | |
| 1953 | ||
| 1954 | ||
| 1955 | 11.3 | |
| 1956 | 10.1 | |
| 1957 | ||
| 1958 | 11.3 | |
| 1959 | ||
| 1960 | 10 | 11.3 |
| 1961 | 11.2 | |
| 1962 | ||
| 1963 | ||
| 1964 | 10.06 | 11.2 |
| 1965 | 11.1 | |
| 1966 | ||
| 1967 | 11.1 | |
| 1968 | 9.9 | 11 |
| 1969 | ||
| 1970 | 11 | |
| 1972 | 10.07 | 11 |
| 1973 | 10.15 | 10.9 |
| 1976 | 10.06 | 11.01 |
| 1977 | 9.98 | 10.88 |
| 1978 | 10.07 | 10.94 |
| 1979 | 10.01 | 10.97 |
| 1980 | 10.02 | 10.93 |
| 1981 | 10 | 10.9 |
| 1982 | 10 | 10.88 |
| 1983 | 9.93 | 10.79 |
| 1984 | 9.96 | 10.76 |
| 1987 | 9.83 | 10.86 |
| 1988 | 9.92 | 10.49 |
| 1989 | 9.94 | 10.78 |
| 1990 | 9.96 | 10.82 |
| 1991 | 9.86 | 10.79 |
| 1992 | 9.93 | 10.82 |
| 1993 | 9.87 | 10.82 |
| 1994 | 9.85 | 10.77 |
| 1995 | 9.91 | 10.84 |
| 1996 | 9.84 | 10.82 |
| 1997 | 9.86 | 10.76 |
| 1998 | 9.86 | 10.65 |
| 1999 | 9.79 | 10.7 |
| 2000 | 9.86 | 10.78 |
| 2001 | 9.88 | 10.82 |
| 2002 | 9.78 | 10.91 |
| 2003 | 9.93 | 10.86 |
| 2004 | 9.85 | 10.77 |
| 2005 | 9.77 | 10.84 |
| 2006 | 9.77 | 10.82 |
| 2007 | 9.74 | 10.89 |
| 2008 | 9.69 | 10.78 |
| 2009 | 9.58 | 10.64 |
| 2010 | 9.78 | 10.78 |
| 2011 | 9.76 | 10.7 |
| 2012 | 9.63 | 10.7 |
| 2013 | 9.77 | 10.71 |
| 2014 | 9.77 | 10.8 |
| 2015 | 9.74 | 10.74 |
| 2016 | 9.8 | 10.7 |
| 2017 | 9.82 | 10.71 |
| 2018 | 9.79 | 10.85 |
| 2019 | 9.76 | 10.71 |
| 2020 | 9.86 | 10.85 |
| 2021 | 9.77 | 10.54 |
| 2022 | 9.76 | 10.62 |
| 2023 | 9.83 | 10.65 |
| 2024 | 9.77 | 10.72 |
Data used in this page, birth weight by lead exposure
| CityTown | Core | Population | NTested | HiLead | Births | LowBirthWeight | InfantDeaths |
|---|---|---|---|---|---|---|---|
| Barrington | n | 16819 | 237 | 13 | 785 | 54 | 1 |
| Bristol | n | 22649 | 308 | 24 | 1180 | 77 | 5 |
| Burrillville | n | 15796 | 177 | 29 | 824 | 44 | 8 |
| Central Falls | y | 18928 | 416 | 109 | 1641 | 141 | 11 |
| Charlestown | n | 7859 | 93 | 7 | 408 | 22 | 1 |
| Coventry | n | 33668 | 387 | 20 | 1946 | 111 | 7 |
| Cranston | n | 79269 | 891 | 82 | 4203 | 298 | 20 |
| Cumberland | n | 31840 | 381 | 16 | 1669 | 98 | 8 |
| East Greenwich | n | 12948 | 158 | 3 | 598 | 41 | 3 |
| East Providence | n | 48688 | 583 | 51 | 2688 | 183 | 11 |
| Exeter | n | 6045 | 73 | 2 | 362 | 6 | 1 |
| Foster | n | 4274 | 55 | 1 | 208 | 9 | 0 |
| Glocester | n | 9948 | 80 | 3 | 508 | 32 | 5 |
| Hopkintown | n | 7836 | 82 | 5 | 484 | 34 | 3 |
| Jamestown | n | 5622 | 51 | 14 | 215 | 13 | 0 |
| Johnston | n | 28195 | 333 | 15 | 1582 | 102 | 6 |
| Lincoln | n | 20898 | 238 | 20 | 962 | 52 | 4 |
| Little Compton | n | 3593 | 48 | 3 | 134 | 7 | 0 |
| Middletown | n | 17334 | 204 | 12 | 1147 | 52 | 7 |
| Narragansett | n | 16361 | 173 | 10 | 728 | 42 | 3 |
| Newport | y | 26475 | 356 | 49 | 1713 | 113 | 7 |
| New Shoreham | n | 1010 | 11 | 0 | 69 | 4 | 1 |
| North Kingstown | n | 26326 | 378 | 20 | 1486 | 76 | 7 |
| North Providence | n | 32411 | 311 | 18 | 1679 | 145 | 13 |
| North Smithfield | n | 10618 | 106 | 5 | 472 | 37 | 3 |
| Pawtucket | y | 72958 | 1125 | 165 | 5086 | 398 | 36 |
| Portsmouth | n | 17149 | 206 | 9 | 940 | 41 | 6 |
| Providence | y | 173618 | 3082 | 770 | 13439 | 1160 | 128 |
| Richmond | n | 7222 | 102 | 6 | 480 | 19 | 2 |
| Scituate | n | 10324 | 133 | 6 | 508 | 39 | 2 |
| Smithfield | n | 20613 | 211 | 5 | 865 | 40 | 4 |
| South Kingstown | n | 27921 | 379 | 35 | 1330 | 72 | 10 |
| Tiverton | n | 15260 | 174 | 14 | 516 | 29 | 3 |
| Warren | n | 11360 | 134 | 17 | 604 | 42 | 1 |
| Warwick | n | 85808 | 973 | 60 | 4671 | 286 | 26 |
| Westerly | n | 22966 | 140 | 11 | 1431 | 85 | 7 |
| West Greenwich | n | 5085 | 68 | 1 | 316 | 15 | 0 |
| West Warwick | n | 29581 | 426 | 34 | 2058 | 162 | 17 |
| Woonsoket | y | 43224 | 794 | 119 | 2872 | 213 | 22 |
Data in this page, Do Democrats prefer cats?
Chapter 16 contents
- Introduction
- Product moment correlation
- Causation and Partial correlation
- Data aggregation and correlation
- Spearman and other correlations
- Instrument reliability and validity
- Similarity and Distance
- References and suggested readings
5.5 – Importance of randomization in experimental design
Introduction
If the goal of the research is to make general, evidenced-based statements about causes of disease or other conditions of concern to the researcher, then how the subjects are selected for study directly impacts our ability to make generalizable conclusions. The most important concept to learn about inference in statistical science is that your sample of subjects upon which all measurements and treatments are conducted, ideally should be a random selection of individuals from a well-defined reference population.
The primary benefit of random sampling is that it strengthens our confidence in the links between cause and effect. Often after an intervention trial is complete, differences among the treatment groups will be observed. Groups of subjects who participated in sixteen weeks of “vigorous” aerobic exercise training show reduced systolic blood pressure compared to those subjects who engaged in light exercise for the same period of time (Cox et al 1996). But how do we know that exercise training caused the difference in blood pressure between the two treatment groups? Couldn’t the differences be explained by chance differences in the subjects? Age, body mass index (BMI), overall health, family history, etc?
How can we account for these additional differences among the subjects? If you are thinking like an experimental biologist, then the word “control” is likely coming to the foreground. Why not design a study in which all 60 subjects are the same age, the same BMI, the same general health, the same family … history…? Hmm. That does not work. Even if you decide to control age, BMI, and general health categories, you can imagine the increased effort and cost to the project in trying to recruit subjects based on such narrow criteria. So, control per se is not the general answer.
If done properly, random sampling makes these alternative explanations less likely. Random sampling implies that other factors that may causally contribute to differences in the measured outcome, but themselves are not measured or included as a focus of the research study, should be the same, on average, among our different treatment groups. The practical benefits of proper random sampling is that recruiting subjects gets easier — fewer subjects will be needed because you are not trying to control dozens of factors that may (or may not!) contribute to differences in your outcome variable. The downside to random sampling is that the variability of the outcomes within your treatment groups will tends to increase. As we will see when we get to statistical inference, large variability within groups will make it less likely that any statistical difference between the treatment groups will be observed.
Demonstrate the benefits of random sampling as a method to control for extraneous factors.
The study reported by Cox et al included 60 obese men between the ages of 20 and 50. A reasonable experimental design decision would suggest that the 60 subjects be split into the two treatment groups such that both groups had 30 subjects for a balanced design. Subjects who met all of the research criteria and who had signed the informed consent agreement are to be placed into the treatment groups and there are many ways that group assignment could be accomplished. One possibility, the researchers could assign the first 30 people that came into the lab to the Vigorous exercise group and the remaining 30 then would be assigned to the Light exercise group. Intuitively I think we would all agree that this is a suspect way to design an experiment, but more importantly, why shouldn’t you use this convenient method?
Just for argument’s sake, imagine that their subjects came in one at a time, and, coincidentally, they did so by age. The first person was age 21, the second was 22, and so on up to the 30th person who was 50. Then, the next group came in, again, coincidentally in order of ascending age. If you calculate the simple average age for each group you will find that they are identical (35.5 years). On the surface, this looks like we have controlled for age: both treatment groups have subjects that are the same age. A second option is to sort the subjects into the two treatment groups so that a 21 year old is in Group A, and the other 21 year old is in Group B, and so on. Again, the average age of Group A subjects and of Group B subjects would be the same and therefore controlled with respect to any covariation between age and change in blood pressure. However, there are other variables that may covary with blood pressure, and by controlling one, we would need to control the others. Randomization provides a better way.
I will demonstrate how randomization tends to distribute the values in such a way that the groups will not differ appreciably for the nuisance variables like age and BMI differences and, by extension, any other covariable. The R work is attached following the Reading list. The take-home message: After randomly selecting subjects for assignment to the treatment groups, the apparent differences between Group A and Group B for both age and BMI are substantially diminished. No attempt to match by age and by BMI is necessary. The numbers are shown in the table and then in two graphics (Fig 1, Fig 2) derived from the table.
Table 1. Mean age and BMI for subjects in two treatment groups A and B where subjects were assigned randomly or by convenience to treatment groups.
| Group | Random assignment of subjects to treatment groups | Convenience assignment of subjects to treatment groups |
|---|---|---|
| A | 35.2 | 28 |
| B | 35.8 | 43 |
| A | 32.49 | 28.99 |
| B | 32.87 | 37.37 |
Just for emphasis, the means from Table 1 are presented in the next two figures (Fig 1 and Fig 2).
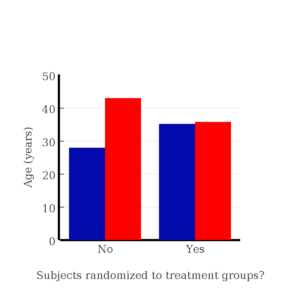
Figure 1. Age of subjects by groups (A = blue, B = red) with and without randomized assignment of subjects to treatment groups.
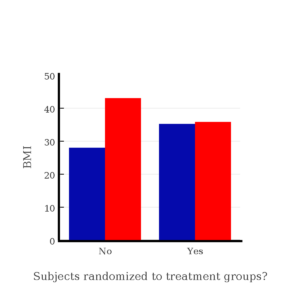
Figure 2. BMI of subjects by groups (A = blue, B = red) with and without randomized assignment of subjects to treatment groups.
Note that the apparent difference between A and B for BMI disappear once proper randomization of subjects was accomplished. In conclusion, a random sample is an approach to experimental design that helps to reduce the influence other factors may have on the outcome variable (eg, change in blood pressure after 16 weeks of exercise). In principle, randomization should protect a project because, on average, these influences will be represented randomly for the two groups of individuals. This reasoning extends to unmeasured and unknown causal factors as well.
This discussion was illustrated by random assignment of subjects to treatment groups. The same logic applies to how to select subjects from a population. If the sampling is large enough, then a random sample of subjects will tend to be representative of the variability of the outcome variable for the population and representative also of the additional and unmeasured cofactors that may contribute to the variability of the outcome variable.
What about observational studies? How does randomization work?
However, if you do cannot obtain a random sample, then conclusions reached may be sample-specific, biased. …perhaps the group of individuals that likes to exercise on treadmills just happens to have a higher cardiac output because they are larger than the individuals that like to exercise on bicycles. This nonrandom sample, an example of confounding where an extraneous or nuisance variable, body size, is associated with both the independent variable (exercise preference) and the dependent variable (cardiac output), will bias your results and can lead to incorrect interpretation of results.
Alternatively, perhaps a researcher elects to study the cardiac output of treadmill users versus bicycle users. The researcher sets up their testing station inside a gym’s powerlifting zone, where the largest individuals in the gym hang out. Inevitably because of this choice, the researcher over recruits larger individuals into the treadmill group, leading to a falsely elevated average cardiac output for treadmill users. This is an example of ascertainment bias — the sample is not representative of all treadmill users at the gym.
Random sampling is CRUCIAL in epidemiology, opinion survey work, most aspects of health, drug studies, medical work with human subjects. It’s difficult and very costly to do… so most surveys you hear about, especially polls reported from Internet sites, are NOT conducted using random sampling (included in the catch-all term “probability sampling“)!! As an aside, most opinion survey work involves complex sample designs involving some form of geographic clustering (eg, all phone numbers in a city, random sample among neighborhoods).
Random sampling is the ideal if generalizations are to be made about data, but strictly random sampling is not appropriate for all kinds of studies. Consider the question of whether or not EMF exposure is a risk factor for developing cancer (Pool 1990). These kinds of studies are observational: at least in principle, we wouldn’t expect that housing and therefore exposure to EMF is manipulated (cf. discussion Walker 2009). Thus, epidemiologists will look for patterns: if EMF exposure is linked to cancer, then more cases of cancer should occur near EMF sources compared to areas distant from EMF sources. Thus, the hypothesis is that an association between EMF exposure and cancer occurs non-randomly, whereas cancers occurring in people not exposed to EMF are random. Unfortunately, clusters can occur even if the process that generates the data is random.
Compare Graph A and Graph B (Fig 3). One of the graphs resulted from a random process and the other was generated by a non-random process. Note that the claim can be rephrased about the probability that each grid has a point, eg, it’s like Heads/Tails of 16 tosses of a coin. We can see clusters of points in Graph B; Graph A lacks obvious clusters of points — there is a point in each of the 16 cells of the grid. Although both patterns could be random, the correct answer in this case is Graph B.
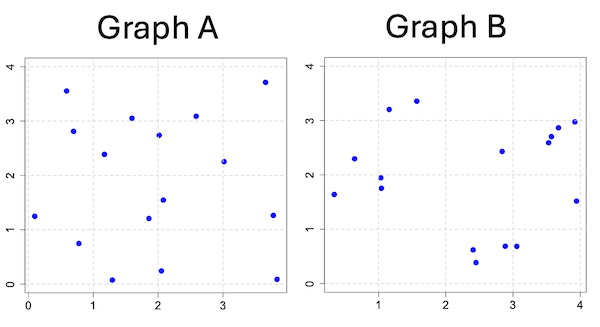
Figure 3. An example of clustering resulting from a random sampling process (Graph B). In contrast, Graph A was generated so that a point was located within each grid.
Hard to tell — and truth be told, random process could generate either one. To convince you, Figure 4 reveals the grouping that was done for Group A, in contrast with Group B which was drawn with the truly random process.
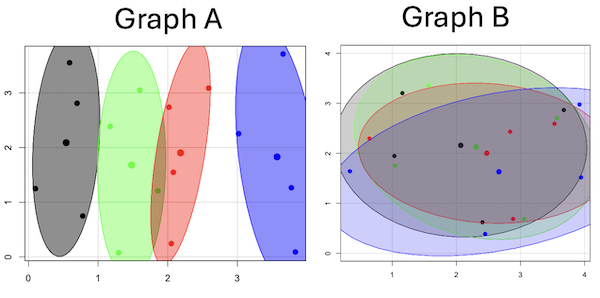
Figure 4. Same graphs as Figure 3, but with ellipses around the grouped data (hard to tell, but the centroids are the larger points).
Implications for sampling
The graphic below shows the transmission grid in the continental United States (Fig 5). How would one design a random sampling scheme overlaid against the obviously heterogeneous distribution of the grid itself? If a random sample was drawn, chances are good that no population would be near a grid in many of the western states, but in contrast, the likelihood would increase in the eastern portion of the United States where the population and therefore transmission grid is more densely placed.
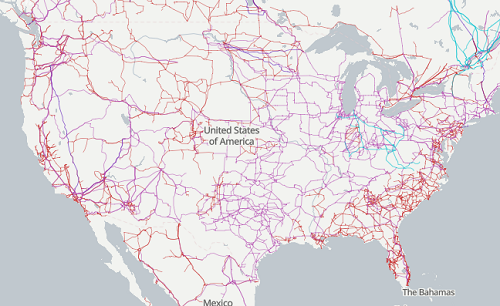
Figure 5. Map of electrical transmission grid for continental United States of America. Image source https://openinframap.org/#3/24.61/-101.16
For example, you want to test whether or not EMF affects human health, and your particular interest is in whether or not there exists a relationship between living close to high voltage towers or transfer stations and brain cancer. How does one design a study, keeping in mind the importance of randomization for our ability to generalize and assign causation? This is a part of epidemiology which strives to detect whether clusters of disease are related to some environmental source. It is an extremely difficult challenge. For the record, no clear link to EMF and cancer has been found, but reports do appear from time to time (eg, report on a cluster of breast cancer in men working in office adjacent to high EMF, Milham 2004).
Questions
1. Use the sample() with and without replacement on the object (see help with R below)
fruit <- c("apple", "banana", "grape", "kiwi", "pear", "pineapple", "tomato")a) set of 3
b) set of 4
2. Confirm the claim by calculating the probability of Graph A result vs Graph B result (see R script below).
Quiz Chapter 5.5
Importance of randomization in experimental design
R code!
Code you type is shown in red; responses or output from R are shown in blue. Recall that statements preceded by the hash # are comments and are not read by R (ie, no need for you to type them).
First, create some variables. Vectors aa and bb contain my two age sequences.
 aa = seq(21,50)
 bb = seq(21,50)
Second, append vector bb to the end of vector aa
 age = append(aa,bb)
 age           #submit the vector (variable) name to print the records for verification - looks good!
  [1] 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37
 [48] 38 39 40 41 42 43 44 45 46 47 48 49 50
Third, get the average age for the first group (the aa sequence) and for the second group (the bb sequence). Lots of ways to do this, I made a two subsets from the combined age variable; could have just as easily taken the mean of aa and the mean of bb (same thing!).
 A = age[1:30]
 mean(A)
 [1] 35.5
 B = age[31:60]
 mean(B)
 [1] 35.5
Fourth, start building a data frame, then sort it by age. Will be adding additional variables to this data frame
 ex.random = data.frame(age)
 AO.all = sort(ex.random$age)
 AO.age           #submit the vector (variable) name to print the records for verification - looks good!
  [1] 21 21 22 22 23 23 24 24 25 25 26 26 27 27 28 28 29 29 30 30 31 31 32 32 33 33 34 34 35 35 36 36 37 37 38 38 39 39 40 40 41 41 42 42 43 43 44
 [48] 44 45 45 46 46 47 47 48 48 49 49 50 50
Fifth, divide the variable again into two subsets of 30 and get the averages
 AO = AO.age[1:30]
 AO
  [1] 21 21 22 22 23 23 24 24 25 25 26 26 27 27 28 28 29 29 30 30 31 31 32 32 33 33 34 34 35 35
 mean(AO)
 [1] 28
 BO = AO.age[31:60]
 BO
  [1] 36 36 37 37 38 38 39 39 40 40 41 41 42 42 43 43 44 44 45 45 46 46 47 47 48 48 49 49 50 50
 mean(BO)
 [1] 43
Sixth, create an index variable, random order without replacement
rand.index = sample(1:60,60,replace=F)Add the new variable to our existing data frame, then print it to check that all is well
 ex.random$rand = rand.index
 ex.random
    age rand
 1   21   43
 2   22   15
 3   23   17
 4   24   35
 5   25   19
 6   26   18
 7   27   22
 8   28   31
 9   29   12
 10  30   44
 11  31   24
 12  32    5
 13  33    2
 14  34   50
 15  35   23
 16  36   20
 17  37   41
 18  38   56
 19  39   36
 20  40    8
 21  41   45
 22  42   38
 23  43   42
 24  44   46
 25  45   16
 26  46   21
 27  47   28
 28  48   10
 29  49   32
 30  50   54
 31  21   57
 32  22   51
 33  23   27
 34  24   40
 35  25   14
 36  26   48
 37  27   26
 38  28   58
 39  29    9
 40  30   11
 41  31    4
 42  32   52
 43  33   37
 44  34   53
 45  35    6
 46  36   34
 47  37   39
 48  38    7
 49  39    1
 50  40   47
 51  41   33
 52  42   60
 53  43   49
 54  44   30
 55  45   29
 56  46   55
 57  47   13
 58  48    3
 59  49   25
 60  50   59
Seventh, select for our first treatment group the first 30 subjects from the randomized index. There are again other ways to do this, but sorting on the index variable means that the subject order will be change too.
AR.age = ex.random[order(ex.random$rand),] #created a new data frame to distinguish it from the presorted version "ex.random"Print the new data frame to confirm that the sorting worked. It did. we can see that the rows have been sorted by ascending order based on the index variable.
 AR.age
    age rand
 49  39    1
 13  33    2
 58  48    3
 41  31    4
 12  32    5
 45  35    6
 48  38    7
 20  40    8
 39  29    9
 28  48   10
 40  30   11
 9   29   12
 57  47   13
 35  25   14
 2   22   15
 25  45   16
 3   23   17
 6   26   18
 5   25   19
 16  36   20
 26  46   21
 7   27   22
 15  35   23
 11  31   24
 59  49   25
 37  27   26
 33  23   27
 27  47   28
 55  45   29
 54  44   30
 8   28   31
 29  49   32
 51  41   33
 46  36   34
 4   24   35
 19  39   36
 43  33   37
 22  42   38
 47  37   39
 34  24   40
 17  37   41
 23  43   42
 1   21   43
 10  30   44
 21  41   45
 24  44   46
 50  40   47
 36  26   48
 53  43   49
 14  34   50
 32  22   51
 42  32   52
 44  34   53
 30  50   54
 56  46   55
 18  38   56
 31  21   57
 38  28   58
 60  50   59
 52  42   60
Eighth, create our new treatment groups, again of n = 30 each, then get the means ages for each group.
 AR = AR.age$age[1:30]
 mean(AR)
 [1] 35.16667
 AR2 = AR.all$all[31:60]
 mean(AR2)
 [1] 35.83333
Get the minimum and maximum values for the groups
 min(AR)
 [1] 22
 min(AR2)
 [1] 21
 max(AR)
 [1] 49
 max(AR2)
 [1] 50
Ninth, create a BMI variable drawn from a normal distribution with coefficient of variation equal to 20%. The first group with we will call cc
cc = rnorm(n=30,m=27.5, sd=5.5) #mean was 27.5 for this group with standard deviation of 5.5The second group called dd
dd = rnorm(n=30,m=37.5, sd=7.5) #mean was 37.5 for this group with standard deviation of 7.5Create a new variable called BMI by joining cc and dd
 BMI=append(cc,dd)
 BMI            #print out BMI to confirm. Looks good!
  [1] 27.87528 27.83250 31.88703 34.99041 24.06751 23.50952 22.57779 31.48394 31.04321 25.60258 25.41081 22.34619 34.62213 36.41348 41.17740
 [16] 20.56529 27.25238 21.85205 32.11690 32.37168 23.11314 33.29110 34.99106 38.22016 18.72105 26.22030 25.13412 27.50475 34.79361 32.81267
 [31] 47.57872 27.58428 40.17211 38.22195 26.91893 37.02784 53.72671 34.94727 30.35245 38.32571 40.52111 36.15627 30.36592 36.20397 47.63142
 [46] 40.30846 36.47643 50.86804 43.63741 37.84994 42.82665 41.71008 28.44976 24.57906 42.37762 38.38512 35.22879 31.34063 34.02996 27.28038
Add the BMI variable to our data frame.
 ex.random$BMI = BMI
 ex.random              #Print out the revised data frame. Looks good. We now have three variables: age, the index "rand," and now BMI
    age rand      BMI
 1   21   43 27.87528
 2   22   15 27.83250
 3   23   17 31.88703
 4   24   35 34.99041
 5   25   19 24.06751
 6   26   18 23.50952
 7   27   22 22.57779
 8   28   31 31.48394
 9   29   12 31.04321
 10  30   44 25.60258
 11  31   24 25.41081
 12  32    5 22.34619
 13  33    2 34.62213
 14  34   50 36.41348
 15  35   23 41.17740
 16  36   20 20.56529
 17  37   41 27.25238
 18  38   56 21.85205
 19  39   36 32.11690
 20  40    8 32.37168
 21  41   45 23.11314
 22  42   38 33.29110
 23  43   42 34.99106
 24  44   46 38.22016
 25  45   16 18.72105
 26  46   21 26.22030
 27  47   28 25.13412
 28  48   10 27.50475
 29  49   32 34.79361
 30  50   54 32.81267
 31  21   57 47.57872
 32  22   51 27.58428
 33  23   27 40.17211
 34  24   40 38.22195
 35  25   14 26.91893
 36  26   48 37.02784
 37  27   26 53.72671
 38  28   58 34.94727
 39  29    9 30.35245
 40  30   11 38.32571
 41  31    4 40.52111
 42  32   52 36.15627
 43  33   37 30.36592
 44  34   53 36.20397
 45  35    6 47.63142
 46  36   34 40.30846
 47  37   39 36.47643
 48  38    7 50.86804
 49  39    1 43.63741
 50  40   47 37.84994
 51  41   33 42.82665
 52  42   60 41.71008
 53  43   49 28.44976
 54  44   30 24.57906
 55  45   29 42.37762
 56  46   55 38.38512
 57  47   13 35.22879
 58  48    3 31.34063
 59  49   25 34.02996
 60  50   59 27.28038
Tenth, repeat our protocol from before: Set up two groups each with 30 subjects, calculate the means for the variables and then sort by the random index and get the new group means.
 AO = ex.random$BMI[1:30]
 mean(AO)
 [1] 28.99333
 BO = ex.random$BMI[31:60]
 mean(BO)
 [1] 37.36943
All we did was confirm that the unsorted groups had mean BMI of around 27.5 and 37.5 respectively. Now, proceed to sort by the random index variable. Go ahead and create a new data frame
 AR.age = ex.random[order(ex.random$rand),]
 AR.age                 #Print out the new data frame to confirm. Looks good.
    age rand      BMI
 49  39    1 43.63741
 13  33    2 34.62213
 58  48    3 31.34063
 41  31    4 40.52111
 12  32    5 22.34619
 45  35    6 47.63142
 48  38    7 50.86804
 20  40    8 32.37168
 39  29    9 30.35245
 28  48   10 27.50475
 40  30   11 38.32571
 9   29   12 31.04321
 57  47   13 35.22879
 35  25   14 26.91893
 2   22   15 27.83250
 25  45   16 18.72105
 3   23   17 31.88703
 6   26   18 23.50952
 5   25   19 24.06751
 16  36   20 20.56529
 26  46   21 26.22030
 7   27   22 22.57779
 15  35   23 41.17740
 11  31   24 25.41081
 59  49   25 34.02996
 37  27   26 53.72671
 33  23   27 40.17211
 27  47   28 25.13412
 55  45   29 42.37762
 54  44   30 24.57906
 8   28   31 31.48394
 29  49   32 34.79361
 51  41   33 42.82665
 46  36   34 40.30846
 4   24   35 34.99041
 19  39   36 32.11690
 43  33   37 30.36592
 22  42   38 33.29110
 47  37   39 36.47643
 34  24   40 38.22195
 17  37   41 27.25238
 23  43   42 34.99106
 1   21   43 27.87528
 10  30   44 25.60258
 21  41   45 23.11314
 24  44   46 38.22016
 50  40   47 37.84994
 36  26   48 37.02784
 53  43   49 28.44976
 14  34   50 36.41348
 32  22   51 27.58428
 42  32   52 36.15627
 44  34   53 36.20397
 30  50   54 32.81267
 56  46   55 38.38512
 18  38   56 21.85205
 31  21   57 47.57872
 38  28   58 34.94727
 60  50   59 27.28038
 52  42   60 41.71008
Get the means of the new groups
 AR = AR.age$BMI[1:30]
 mean(AR)
 [1] 32.49004
 min(AR)
 [1] 18.72105
 max(AR)
 [1] 53.72671
 AR2 = AR.all$BMI[31:60]
 mean(AR2)
 [1] 33.87273
 min(AR2)
 [1] 21.85205
 max(AR2)
 [1] 47.57872
That’s all of the work!
Data set
nonrandom
| X | Y |
| 0.779 | 0.747 |
| 0.098 | 1.248 |
| 0.697 | 2.811 |
| 0.59 | 3.553 |
| 1.295 | 0.075 |
| 1.858 | 1.207 |
| 1.172 | 2.388 |
| 1.597 | 3.051 |
| 2.051 | 0.242 |
| 2.081 | 1.546 |
| 2.016 | 2.738 |
| 2.587 | 3.088 |
| 3.833 | 0.088 |
| 3.776 | 1.264 |
| 3.017 | 2.254 |
| 3.657 | 3.712 |
random
| X1 | Y1 |
| 1.157 | 3.203 |
| 2.407 | 0.62 |
| 1.033 | 1.946 |
| 3.676 | 2.866 |
| 3.57 | 2.703 |
| 3.056 | 0.685 |
| 1.568 | 3.355 |
| 1.041 | 1.753 |
| 0.643 | 2.295 |
| 2.884 | 0.687 |
| 3.53 | 2.591 |
| 2.838 | 2.431 |
| 3.945 | 1.518 |
| 0.34 | 1.64 |
| 2.45 | 0.386 |
| 3.921 | 2.976 |
Chapter 5 contents
- The basics explained
- Experiments
- Experimental and Sampling units
- Replication, Bias, and Nuisance Variables
- Clinical trials
- Importance of randomization in experimental design
- Sampling from Populations
- References and suggested readings