2.6 – Statistical reasoning
How statistical reasoning helps us spot and reduce bias.
.
So far in the course we have talked about statistical reasoning. Statistical reasoning as part of the critical thinking tool kit. What this should mean for you in practice is that we will be developing and enhancing your critical thinking skill set. Here, we’ll define our terms and place statistical reasoning in context.
Critical thinking.
.
What do I mean by critical thinking? You’ll find various definitions and discussions, but the Wikipedia entry on the subject seems as good a start as anything else I have heard or read:
“Critical thinking is a way of deciding whether a claim is always true, sometimes true, partly true, or false” (5 August 2013, http://en.wikipedia.org/wiki/Critical_thinking).
Which raises the question, what is truth (false)? And what about the frequency qualifiers “always,” “sometimes,” “partly”? This hints at one of the strengths of science; “Truth in science … is never final, and what is accepted as fact today may be modified or even discarded tomorrow” (p. 2, National Academy of Science 1999). Scientists extend and even correct the work of their predecessors.
Critical thinking has many definitions, but they coalesce broadly as the search for rational justification — arguments and decisions based on reason not emotion — given sets of facts. We’ll define facts as assertions about the world that are verifiably true. Related to facts, we define evidence as collection of facts used to infer an assertion or belief is objectively true. Objectivity holds independently of the observer. In practice, critical thinking can be improved by identifying and developing certain skill sets, from deductive reasoning to use of a statistical toolkit, although skills alone do not necessarily lead to sound critical thinking (Bailin 2002). Emphasis on the importance of statistical reasoning, for example in the Evidence-Based Medicine (EBM) approach, is now well established. EBM is an expansive concept, but includes the philosophy that decisions in medicine and health care should be based on evidence (results) from well designed and executed research. More generally, much has been written on the subject. My purpose here is to sell you just a bit that you will learn more than formulas and statistical tests in this course; if we do this right you will improve your critical thinking skills.
And the tool kit for critical thinking? Science has the scientific method to offer. In turn, by adopting statistical reasoning approaches you will be more cognizant of whether or not you are indeed engaged in critical thinking about your work.
A working checklist for critical evaluation of a project
- “All sides” of the problem are fairly represented
- Authority is not synonymous with empirical truth: trust, but verify
- Correlation (association) may or may not infer causation
- Do conflicts of interest compromise conclusions?
In other words, identify and rigorously consider assumptions made to reach conclusions, evidence given in support of conclusions, and considerations of bias held by the researcher. The “all sides” part requires judgement — not all sides of a research question are equally valid; the point about “fair” representation requires that opposing arguments are actually held by others and not simply a “”straw man” characterization of of a position held by no one.
Rigid adherence to “how to do science checklist” is likely to be wanting and thus practicing and successful scientists show more flexibility. And, the list is certainly incomplete because it presumes observations and data collection are from a reliable, unbiased source. Before proceeding with how statistics informs our critical thinking in science, let’s illustrate bias.
Bias everywhere.
.
Bias is defined as any tendency that may hamper our ability to answer a question without prejudice (Pannucci and Wilkins 2010). Although we tend to think of ourselves as highly rational (Note 1), psychologists have documented, named numerous, and in some cases, highly specific kinds of cognitive biases we may have about “real world data” that may impair our judgment about results of experiments.
Note 1. A handful of Nobel prizes were awarded over evidence and theory on just how unrational we are, see Simon (1978), Kahneman (2002), and Thaler (2017, whose views were immortalized in the movie The Big Short).
At its best, application of the scientific method is our best tool kit to help protect our conclusions against bias (Nuzzo 2015), by proper experimental design and possible study biases. A couple of comics from xkcd illustrate.
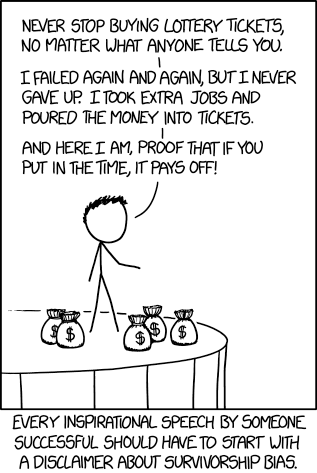
Figure 1. “Survivorship bias,” https://www.xkcd.com/1827/ .
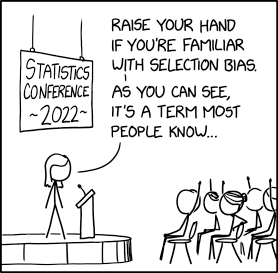
Figure 2. “Selection bias,” https://xkcd.com/2618/ .
Wikipedia lists dozens of named biases which may influence our ability to interpret science:
- confirmation bias, eg, given extraneous information about ancestry or sex, forensic investigators were more likely to assign ancestry or sex of skeletal evidence to group that confirmed the contextual information (Nakhaeizadeh et al 2014).
- congruence bias, a type of confirmation bias, the tendency to test only a favorite or initial hypothesis over consideration of alternative hypotheses.
- observer-expectancy bias, eg, randomized controlled trials of acupuncture often find equivalent responses to real and placebo acupuncture despite both appearing superior to no treatment (Colagiuri and Smith 2012).
- selection bias, the selection of individuals, groups, or data for analysis in such a way that proper randomization is not achieved, eg, mitotic counts (Cree et al 2021) and cell differentials and Figure 2. Selection bias, where the study population is not well-defined or if is, the method by which subjects are recruited favors one kind of subject over another.
- surveillance bias, eg, association between myocarditis and COVID-19 vaccines may be due to increased focus to identify myocarditis (Husby et al 2021).
- survivorship bias, focusing on subjects that passed a selection process as if they represent an entire group, eg, from ecology: rare species more likely to go extinct than abundant species (Lockwood 2003) and Figure 1.
Bias in research may occur at any level, from study design to analysis and publication of results. Bias leads to systematic errors that may favor one outcome over others. Clearly then, bias is something one wants to avoid in science, and most scientists would probably agree strongly that bias is unacceptable. However, bias can creep into projects in many forms.
Particularly pernicious causes of bias are conflicts of interest, with the notable case of a 1990’s set of trials in gene therapy (Wilson 2010). Biased research may be more harmful to science than deliberate misconduct, at least in part because there are, or should be, mechanisms to detect fraud (eg, Marusic et al 2007). If errors in data analysis or management are rare, we can trust the results; if errors are common, systematic, or deliberate falsification, then any conclusions drawn from such work deserves retraction at the very least (cf. discussion in Baggerly and Coombs 2009; see StatCheck project, Nuijten et al 12016).
Bias in research.
.
Bias is not limited to obvious profit seeking or even defense of one’s ideas or reputation. Bias can enter research in subtle ways. Prior to 2000, many post-menopausal women could expect to be placed on hormone replacement therapy (HRT) to manage post-menopausal symptoms and to reduce likelihood of osteoporosis later in life. Moreover, HRT was believed based on research to show protective benefits against heart disease (eg, Nabulsi et al 1993; Grodstein et al 2000). However, other prospective studies that were designed to reduce many sources of bias in patient recruitment (Women’s Health Initiative Study Group 1998), found the opposite: HRT may increase risk of heart disease as well as other diseases (Rossouw et al 2002). Since the 2002 Women’s Health Initiative study report, the costs and benefits of HRT have been furiously debated (Lukes 2008).
The purpose of this chapter, however, is not to exhaustively review sources of bias. Instead, we leave you with a partial list of kinds of bias in clinical trials (from a review by Pannucci and Wilkins 2010).
- Bias during study design, eg, use of subjective measures or poorly designed questionnaires.
- Interviewer bias, for example, if the interviewer is aware of the subject’s condition
- Chronology bias, where the control subjects may not be observed in the same time frame as the treatment subjects
- Citation (reporting) bias, where negative results are not reported
- Confounding, where results may be due to factors not properly controlled that also affect the outcome. An example provided was link between income and health status, which would be confounded by access to health care.
These are but a few of the kinds of bias that even proper research may be influenced by. Solutions are to randomize, to double-blind, and to avoid reporting bias. Controls of sources of bias increase the validity of the research. How experimental design may control for bias is discussed further in Chapter 5.3.
A case study.
.
Stories we hear from the news or from our friends about health or the environment are anecdotal. A basic rule in critical thinking is to distinguish between argument that is built on anecdotal evidence and argument based on scientific evidence. Let’s evaluate the following real-world example.
Airborne® is a leading dietary supplement. Here’s what their website has to say about the product.
“Scientific research confirms that Airborne proprietary formulation with 13 vitamins and minerals plus a blend of health-promoting herbs, does indeed enhance immunity (5 August 2013, http://www.airbornehealth.com/our-story).
This next statement appears in smaller text near the bottom of the page.
“These statements have not been evaluated by the Food and Drug Administration. These products are not intended to diagnose, treat, cure or prevent disease” (5 August 2013, http://www.airbornehealth.com/our-story).
So, in short, how do you evaluate Airborne? The claim is that “scientific research confirms that Airborne … enhance immunity,” and yet, there is a statement that follows that suggests that the claim has not been evaluated by the agency legally responsible in the USA for determining the efficacy of medicine and treatments.
Note 2. “enhance” immunity is a vacuous phrase. Immunity is not a single object. If by immunity we mean resistant to a particular pathogen, this cannot be what the makers literally mean because that would be in violation of the FDA. Yes, deficiencies of vitamin C and other nutrients impair immune function (Carr and Maggini 2017), but there is no evidence to support the claim that Vitamin C supplementation above RDA, recommended dietary allowances, improves resistance. See 2013 Cochrane Review.
Are not these in contradiction? In the USA, supplement manufactures’ need not seek FDA approval. In fact, the U.S. Congress, in it’s passing of the The Dietary Supplement Health and Education Act of 1994 (DSHEA), specified what needs to be reported to the FDA; statements of “enhancing immunity” are lawful, but do not require the supplement manufacture to show evidence that their product provides this support, only that ingredients in the supplement may do so.
Returning to the statements from Airborne Health, how may these statements be interpreted?
- peer-reviewed articles testing Airborne are available
- that experiments were conducted without bias
- and that to “enhance immunity” is something one could measure
Let’s look at #3 first. A search of PubMed (December 2013) for the phrase “enhance immunity” returned 9171 hits. I didn’t look through the more than 9000 articles, but a quick look shows that the term is indeed used in research, but carries a wide range of interpretations. For one paper “enhance immune” response was the result of genetic modifications to T-cells and how they responded to a virus (PMID:24324159).
Adding “vitamin” to the search resulted in just 158 hits in PubMed; none of these are about Airborne (see claim #1 and #2). However, to be fair, go back and look at their statement — notice they are not saying exactly that anyone has studied Airborne (otherwise they’d probably list the papers), just that vitamins and minerals and herbs that are in Airborne have been studied.
Indeed, vitamins A, C, E and minerals like zinc and selenium that are in Airborne are among the 158 papers. To be additionally fair to Airborne, there are indeed many papers investigating benefits (harm) of supplemental vitamins and minerals — and again, being charitable here, what we can say is that results are at best inconsistent (Bjelakovic et al 2014; Comerford 2013).
The manufacturer of Airborne ran into some trouble with the FTC and ended up paying over $20 million US dollars to settle the lawsuit. The one study, not peer-reviewed, of Airborne’s effectiveness cited during these proceedings apparently was sponsored by Airborne’s manufacturer. Airborne was acquired by Schiff Vitamins March 2012 (Bloomberg News). Click here for additional reading about Airborne.
About peer-review.
.
Evaluation of claims made, research reported, and ideas in science are generally expected to be subject to peer-review by knowledgeable persons in the field. Effective peer-review is an important “gatekeeper” in science (Siler et al 2015, Tennant 2018). Proper peer review gives legitimacy to research (Siler et al 2015). The traditional peer review system is a closed system, which includes elements controlled by journal editors and is based on reviewer identify remaining anonymous. The closed peer-review system is not the only option: many have argued for an open review process (eg, Pöschl 2012, Ho et al 2013).
Does the Airborne story meet your definition of bias?
.
Airborne made health claims I about their product; these claims were found by the federal government to be misleading but does not fit into our discussion of bias. Instead, Airborne story fits more with critical thinking: I think it is rather a casual position to say that we should, and do, think critically of news source or the stories our friends tell us about health.
But bias in science occurs too, and can be very difficult to control or completely eliminate.
Learning statistical reasoning will help develop critical thinking skills.
.
In addition to considering sources of bias, ie, can you trust the messenger, thinking about the sets of facts offered to bolster a claim, it helps to evaluate each fact to see if
- The author is really talking about correlation and has not in fact provided evidence of causation
- vs. experiment, which tests “cause” manipulate
X, doesYchange?
- vs. experiment, which tests “cause” manipulate
- Measurement appropriate?
- Direct or indirect
- Unmeasured important (co)variable
Questions.
.
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- The xkcd comic in Figure 1 titles calls it survivorship bias. Provide a definition for this kind of bias and describe the effects on conclusions if it is not accounted for.
- Doctors are encouraged to engage in “evidence based medicine,” that is, decisions about care should be based on data. How may confirmatory bias (from the patient’s point of view, from the doctor’s point of view) influence a discussion of “facts” when deciding on a course of medication therapy — between a well-established medication with many known side-effects and a new, recently approved medicine reported to be as effective as the standard treatment.
Quiz Chapter 2.6
Statistical reasoning
Chapter 2 contents
.
Preface
Overview.
.
The following pages, loosely called Mike’s Biostatistics Book, contain the extended versions of my lectures for BI311 Biostatistics, a biology course I teach at Chaminade University.
The companion site, Mike’s Workbook for Biostatistics, provides homework, problems and projects to learn-by-doing biostatistics, and several R tutorials. (I’ve also put together a number of handouts, background, and bioinformatics support at Mike’s Genetics & Genomics Workbook, consisting of materials used to support my lab classes these past 20 years.)
The Biology department faculty require biology majors to take this course. Class standing of students range from sophomores to first year graduate students.
We use and rely heavily on R, the open source “language and environment for statistical computing” (R-project [dot] org), and the R Commander package by J Fox (Fox 2005; Fox 2016). R Commander allows students to gain confidence with R commands by use of drop down menus to access functions. Increasingly, we also use Google CoLab to run simple R sessions.
The lecture notes are written from my perspective on what matters in a semester-long, first course in Biostatistics: concepts, context and practical advice along with a generous introduction to general linear models. The focus is on applied statistics with reference to other data science skill sets as needed. Concepts are illustrated by examples and multiple choice questions to “test” reader comprehension. Examples in Mike’s Biostatistics Book are generally from real data sets in biological or biomedical research. Therefore, context and practice comes from data sets we will work on throughout the semester. The data sets are presented in the accompanying workbook, body titled Mike’s Workbook for Biostatistics.
The material presented in Mike’s Biostatistics Book provide background and the examples needed to complete the problems presented in the course workbook.
- Chapter 2: Statistical reasoning.
- Workbook: Homework 1: Project data life cycle.
- Chapter 3 and 4: Exploring data.
- Workbook: Homework 2A: Descriptive statistics.
- Workbook: Homework 2B: Graphs.
- Chapter 5: Experimental design.
- Chapter 6: Probability.
- Workbook: Homework 3: Distributions & Probability.
- Chapter 7: Risk analysis.
- Workbook: Homework 4: Risk.
- Chapter 8: Inferential statistics.
- Workbook: Homework 5: Inference.
- Chapter 9: Qualitative (categorical) analyses.
- Workbook: Homework 6: Chi-square problems.
- Chapter 10 – 19: Quantitative (continuous) analyses.
- Chapter 10, 12, 13 – Workbook: Homework 7: t-tests and ANOVA.
- Workbook: Homework 8: Multiway ANOVA.
- Workbook: Homework 10: Correlation.
- Workbook: Homework 10: Multiple linear regression.
- Chapter 11: Power analysis.
- Chapter 15: Nonparametric tests.
- Chapter 19: Distribution-free methods.
- Chapter 20: Additional topics (partial listing).
- growth curves, dose response.
- logistic regression.
- others.
- Statistical tables.
- Appendix
While the intention is to downplay lists of statistical tests in favor of developing statistical reasoning, many of the kinds of tests one comes across are introduced and discussed in this book. The intent is to introduce these tests as special cases of general (or generalized) models from a data analyst’s point of view. Think of “k-means clustering“, “independent sample t-test“, “ANOVA“, “linear regression“, and the other tests as vocabulary. We understand biology best when we can talk the talk, and the same holds for learning statistics.
The book does not include machine learning — systems that can learn and help make decisions from data — and as of September 2023, includes only a short discourse on clustering and dimensionality reduction of data sets.
About this book (and website).
.
This textbook is an eBook and will undergo updates to correct errors, improve clarity, and even new content, throughout the semester. Although in spirit I welcome comments, corrections, and suggestions to improve coverage and content, I have closed comments at this site to minimize spam. As the book has a modest readership from multiple countries, I’m always happy to try and answer student questions — A little judicious search on the part of the reader likely will find a relevant email address.
Typesetting.
.
The manuscript was type set from a mix of html and Markup language — See Part 09: Making a report at Mike’s Biostatistics Book — and Ghostwriter (version 2 [dot] 1 [dot] 1), and the eBook (pdf version coming soon!) was generated and edited with Calibre (version 5 [dot] 35 [dot] 0).
Text to speech considerations.
Text to speech apps can get confused when a period appears within text and not just at the end of a sentence. Therefore, I’ve dropped periods from “Fig. 1” and the “e.g.” and “i.e.” Latin abbreviations. Periods appear in R commands, for example, data.frame(), and those remain as is. Similarly, I generally add a period after a subheading to encourage a break by text to speech apps.
Hosting.
Both books, Mike’s Biostatistics Book and Mike’s Workbook for Biostatistics, are hosted on my website. This site, Mike’s Biostatistics Book, is solely supported by me and I don’t monetize the site. As of Fall 2023, the site cookie only stores temporary session information during a users visit.
Equations.
.
Equations in the eBook were created with LaTeX — a software system used to prepare and format documents — and saved as PNG images, or embedded in text (QuickLaTeX WordPress plug-in). Pages with many images or equations may be slow to load in your browser: in general, to improve browsing experience reduce the number of open tabs and use of additional apps.
References and citations.
.
Introductory textbooks often lack in-line citations. The absence of in-line citations improves readability, but at the very real expense of giving credit to the original and to providing the reader the opportunity to verify facts and opinions presented. I have tried a balance: first, I included in-line citations to references. One of many remaining tasks for me to improve the book is to complete linkage of in-page citations to reference lists. I have, however, refrained from an exhaustive, dissertation-like reference listing for each point raised in the book. Second, most citations are to open access articles (or articles with pdfs available by judicious search), with the justification of the reader has access to the original material. However, this approach is a form of citation bias. Thus, I refer to reference pages as References and Suggested Readings, and don’t claim Mike’s Biostatistics Book as an authoritative voice on the subject (cf. discussion in Greenberg 2009 Bmj 339).
A note about me.
.
I’m an Associate Professor of Biology at Chaminade University. My PhD was not in statistics, I trained in evolutionary physiology and quantitative genetics. Quantitative genetics is an applied field that depends heavily on use of mathematics and statistics, particularly linear models. I took courses in applied statistics while at the University of Wisconsin, but I would not call my training in statistics thorough or complete. Much of what I know comes from self-study. My strengths in biostatistics, I believe, are in translation of sometimes dense mathematics to direct use and application. Thus, I have developed a direct style to the material that I hope you will find helpful as you work on the material. It also means we won’t spend a lot of time with proofs, not because these are unimportant, but because they can side-track from developing your statistical thinking when it comes to data analysis — but primarily because this is not my strength. References are presented in the book to support the algorithms and mathematical foundations of biostatistics and to back claims I make about applied statistics.
Thus, I don’t claim that I have all of the answers, nor am I saying that the mathematical foundations are unimportant, far from it. But we have to start somewhere and I elect to spend our time on the concepts in statistics, the why do we do it this way, as opposed to the mechanics of the mathematics, the how do we do it.
What I have learned about statistics comes from publications from many real statisticians; Mike’s Biostatistics Book, such as it is, stands on on their work. I apologize in advance to any author whose work has not been given proper credit. Mistakes or mischaracterizations are, of course, mine alone.
Other sources of expertise.
.
Mike’s Biostatistics Book of lecture notes is intended to provide students with a foundation in biostatistics: the concepts of assumptions, probability, sampling, description, and modeling that support a researcher’s ability to advance knowledge in biology. But you will very much benefit from other opinions, other voices. And, as much as I have adopted the online presence, it is hard to beat a book in hand as a guide. Good statistics books retain their value well passed their publication date. Some of the textbooks I have found useful over the years include the following:
Introduction and general statistics.
.
Chaterjee S, Price B (1977) Regression analysis by example. Wiley Interscience (5th edition now published in 2006)
Glover T, Mitchell K (2008) Introduction to biostatistics, 2nd edition. Waveland Press
Norman GR, Streiner DL (2003) PDQ Statistics, 3rd edition. BC Decker
Snedecor GW, Cochran WG (1989) Statistical methods, 8th edition. Iowa State University Press
Sokal RR, Rohlf (1981) Biometry, 2nd edition. WH Freeman (4th edition published in 2011)
Whitlock MC, Schluter D (2008) The analysis of biological data. Roberts and Company
Zar J (1999) Biostatistical analysis, 4th edition. Prentice Hall (5th edition published in 2011)
Intermediate and advanced books.
Abelson RP (1995) Statistics as principled argument. Taylor & Francis (epub available)
Bulmer MG (1967) Principles of statistics. Dover Publications (epub available)
Davidson AC, Hinkley DV (1997) Bootstrap methods and their application. Cambridge University Press (epub available)
Edwards AWF (1992) Likelihood, expanded edition. Johns Hopkins University Press
Fisher RA (1934) Statistical methods for research workers, 5th edition. Oliver and Boyd (The last edition was the 14th)
Härdle W, Simar L (2003) Applied multivariate statistical analysis. Springer-Verlag
Lee PM (1989) Bayesian statistics: An introduction. Oxford University Press – McCullagh P, Nelder JA (1989) Generalized linear models, 2nd edition. Chapman and Hall
Montgomery DC, Peck EA (1992) Introduction to linear regression analysis, 2nd edition. John Wiley & Sons (5th edition published in 2013)
Neter J, Wasserman W, Kutner MH (1989) Applied linear regression models, 2nd edition. Robert D Irwin (4th edition published in 2003)
Quinn GP, Keough MJ (2002) Experimental design and data analysis for biologists. Cambridge University Press.
Shao J (2003) Mathematical statistics, 2nd ed. Springer Science
Wei WWS (1990) Time series analysis. Addison-Wesley (2nd edition published in 2005)
Some of these titles are old!
.
One of the good things about statistics is that many of the standard statistical applications were developed a long time ago, so “old textbooks” in statistics retain their value. A quick search online will result in many options to purchase one or more of these books for under $10. In addition, most of the books listed above have new editions; where appropriate I have listed the most recent available edition.
What about books on R?
None of the listed books teach R. Between Mike’s Biostatistics Book and the companion Mike’s Workbook for Biostatistics, several tutorial and lots of worked examples are provided to help you learn how to use R to help statistical work. A quick Google search, e.g., “free online books learn R,” returns thousands of suggested titles. Search “R tutorials,” for millions more. Chances are, if you have a question about how to do some task in R, someone has already solved the task and published code examples for you to borrow (always cite your sources!).
Concluding remarks about these lecture notes.
.
These collected lecture notes will serve as your official textbook – I have tried to make them accurate, informative, and yet balanced between providing too much detail while still providing depth to the presentation. In class, lecture slides will be provided as outline to these more extensive notes. Homework and quizzes support the progress through the notes.
The lecture notes contained in Mike’s Biostatistics Book are very much a work in progress, with some areas more developed than others. If you find areas that make no sense, seem abrupt, or you would like more examples, please do let me know. Your input is important to improve this textbook; the Discussion Forum on the course website is a good place to do lend your critiques and suggestions.
Like most subjects one voice is not enough; you will benefit from acquiring a second opinion, either from one or more of the books listed above or from the many online sites on statistics you will find. The good news is that you will find substantial overlap between what I write and other sources you may acquire because the topics we will cover are foundational and my take is mainstream.
However, you will also find some differences in detail. For one example, I have included much more on risk analysis and an epidemiology tilt as compared to many of the the titles listed under the Introduction and General statistics category. For a second example, I give a different perspective on how to work with probability calculations, emphasizing use of natural numbers over frequency calculations. Many examples provided in the book are drawn from data sets created in lab classes or as preliminary and pilot projects from my research at Chaminade University: growth curves, dose-response, working with RT-PCR traces, multi-well plate assays and more.
Preface contents
.
Preface