7.5 – Odds ratio
What are the odds.
We introduced the concept of odds 7.1 — Epidemiology definitions. As a reminder, odds are a way to communicate the chance (likelihood) that a particular event will take place. Odds are calculated as the number of individuals with the event divided by the number of individuals without the event.
Odds ratio definition: is a measure of effect size for the association between two binary (yes/no) variables. It is the ratio of the odds of an event occurring in one group to the odds of the same event happening in another group. The odds ratio (OR) is a way to quantify the strength of association between one condition and another.
Note 1: Effect size — the size of the difference between groups — is discussed further in Chapter 9.2 and Chapter 11.4.
And note, it’s association, not correlation. In statistics, correlation is a specific kind of relationship (linear) among the variables, whereas “association” means there is some relationship between the variables without specifying the shape of the relationship.
How are odds ratios calculated? The probabilities are conditional; recall that conditional probability of some event A, given the occurrence of some other event B.
Let  equal probability of the event occurring (y = Yes) in A,
 equal probability of the event not occurring (n = No) in A,
 equal probability of the event occurring in B, and
 equal probability of the event not occurring in B.
| A | |||
| Yes | No | ||
| B | Yes | |
|
| No | |
|
|
These sum to one: 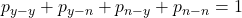
The conditional probabilities are
| A | |||
| Yes | No | ||
| B | Yes |  |
 |
| No |  |
 |
|
and finally then, the odds ratio (OR) is
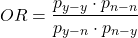
If you have the raw numbers you can calculate the odds ratio directly, too.
| A | |||
| Yes | No | ||
| B | Yes | a | b |
| No | c | d | |
and the odds ratio is then

or, equivalently

Example.
Comparing proportions is a frequent need in court. Gray (2002) provided an example from Title IX of the Education Act of 1972 case Cohen v. Brown University. Under the Act, discrimination based on gender is prohibited. The case concerned participation in collegiate athletics by women. The case data were that of the 5722 undergraduate students, 51% were women, but of the 987 athletes, only 38% were women. A mosaic plot shows graphically these proportions (Fig 1, males in red bars, females in yellow bars).
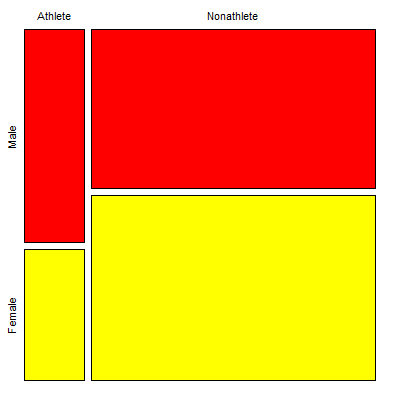
Figure 1. Mosaic plot of athletes to non-athletes in college. Males red, females yellow, data from Gray 2002.
Alternatively, use a Venn diagram to describe the distribution (Fig 2). Circles that overlap show regions of commonality.
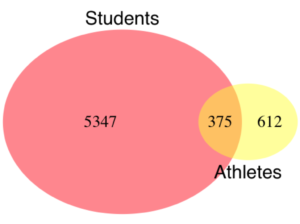
Figure 2. Venn Diagram of athletes to non-athletes in college. Female athletes (n = 375), male athletes (n = 612), data from Gray 2002.
where the orange region
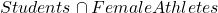
R code for the Venn diagram was
library(VennDiagram)
area1 = 5722
area2 = 987
cross.area = 375
draw.pairwise.venn(area1,area2,cross.area,category=c("Students","Athletes"),
euler.d = TRUE, scaled = TRUE, inverted = FALSE, print.mode = "percent",
fill=c("Red","Yellow"),cex = 1.5, lty="blank", cat.fontfamily = rep("sans", 2),
cat.cex = 1.7, cat.pos = c(0, 180), ext.pos=0)
The question raised before the court was whether these proportions meet the demand of “substantially proportionate.” What exactly the law means by “substantially proportionate” was left to the courts and the lawyers to work out (Gray 2002). Title IX suggests that “substantially proportionate” is a statistical problem and the two sides of the argument must address the question from that perspective.
What is the chance that an undergraduate student was an athlete and female? 38% And the chance that an undergraduate student was an athlete and male? 62% Clearly 38% is not 62%; did the plaintiffs have a case?
Graphs like Figure 1 and Figure 2 help communicate but can’t provide a sense of whether the differences are important. Let’s start by looking at the numbers. Working with the proportions we have the following break down for numbers of students (Table 1) or as proportions (Table 2).
Table 1. Gray’s raw data displayed in a 2 x 2 format.
| Athletes | |||
| Yes | No | ||
| Undergraduates | Male | 612 | 2192 |
| Female | 375 | 2543 | |
Together, the numbers total 5,722.
The Odds Ratio (OR) would be
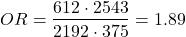
Or from the proportions (Table 2)
Table 2. Data from Table 1 as proportions.
| Athletes | |||
| Yes | No | ||
| Undergraduates | Male | 0.107 | 0.383 |
| Female | 0.066 | 0.444 | |
adding all of these frequencies together equal 1. Carry out the calculation of odds (Table 3), the conditional probabilities (in bold).
Table 3. Odds calculated from Table 2 inputs.
| Athletes | |||
| Yes | No | ||
| Undergraduates | Male | 0.218
|
0.782
|
| Female | 0.129
|
0.871
|
|
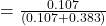
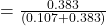
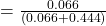
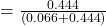
Calculate the odds ratio
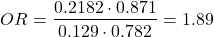
Thankfully, whether we use the raw number format or the proportion format, we got the same results!
Odds ratio interpretation.
Because the Odds Ratio (OR) was greater than 1, males students were more likely to be athletes than female students. If there was no difference in proportion of male and female athletes, the odds ratio would be close to one. That is a test of statistical inference (eg, a contingency table), but for now, if one is included in the confidence interval, then this would be evidence that there was no difference between the proportions.
And in R? Simple enough, just create a matrix then apply the Fisher test. which we will discuss further in Chapter 9.5.
title9 <- matrix(c(612, 2192, 375, 2543), nrow=2))
fisher.test(title9)
and results
p-value < 2.2e-16
alternative hypothesis: true odds ratio is not equal to 1
95 percent confidence interval:
1.641245 2.185576
sample estimates:
odds ratio
1.893143
Thankfully, they agree. But note, we now have confidence intervals and a p-value, which we use to conduct inference: were the odds “significantly different from 1?” We would conclude, yes! Between the lower limit (1.64) and the upper limit (2.19), the value “1” was excluded. Moreover, the p-value at 2.2e-16 was much less than the standard type I error cut-off of 5% (see Chapter 8).
Before we leave the interpretation, sometimes a calculated odds-ratio is less than one. If our calculated odds ratio for the Title IX case described in Table 1 was less than 1, (say, the numbers were flipped, Table 4) we then the interpretation would be females were more likely to be athletes on college campus.
Table 4. Table 1 data, but order of entry changed.
| Athletes | |||
| Yes | No | ||
| Undergraduates | Female | 375 | 2543 |
| Male | 612 | 2192 | |
Now, calculating the odds via Fisher exact test, the odds ratio is less than one (0.53):
Fisher's Exact Test for Count Data
p-value < 2.2e-16
alternative hypothesis: true odds ratio is not equal to 1
95 percent confidence interval:
0.4575452 0.6092936
sample estimates:
odds ratio
0.5282222
Note this result is for the same data (Table 1 vs Table 4), just the order by which the groups are specified changed. Of course they are related to each other mathematically, and in a simple way. Note that taking the inverse (reciprocal) odds ratio.
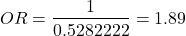
will return the comparison we wanted in the first place — the odds a student athlete was male. As long as you keep track of the comparison, of the groups, it may be easier to communicate results when the reported odds ratio is greater than one.
Relative risk v. odds ratio.
We introduced another way to quantify this association as the Relative Risk (RR) and Absolute Risk Reductions in the previous section. Both can be used to describe the risk of the treatment (exposed) group relative to the control (nonexposed) group. RR is the ratio the treated to control group. OR is the ratio between odds of treated (exposed) and control (nonexposed). What’s the difference? OR is more general — it can be used in situations in which the researcher chooses the number of affected individuals in the groups and, therefore, the base rate or prevalence of the condition in the population is not known or is not representative of the population, whereas RR is appropriate when prevalence is known (this is a general point, but see Schechtman 2002 for a nice discussion).
The odds ratio is related to relative risk, but not over the entire range of possible risk. Odds of an event is simply the number of individuals with the event divided by the number without the event. Odds of an event therefore can range from zero (event cannot occur) to infinity (event must occur). For example, odds of eight (1.89:1) means that nearly two male students were student athletes at Brown University for every one female student.
In contrast, the risk of an event occurring is the number of individuals with the event divided by the total number of people at risk of having that event. Risk is expressed as a percentage (Davies et al 1998). Thus, for our example, odds of 1.89:1 correspond to a risk of 1.89 divided by (1 + 1.89) equals 65%.
To get the relative risk we can use

or 1.7% for our example.
In this example we could use either odds or relative risk; the key distinction is that we knew how many events happened in both groups. If this information is missing for one group (eg, control group of the case-control design), then only the odds ratio would be appropriate.
From cumulative wisdom in the literature (eg, Tamhane et al 2107), if prevalence is less than ten percent, OR ≈ RR. We can relate RR and OR as
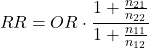
where n11 and n21 are the frequency with the condition for group 1 and group 2, respectively, and n12 and n22 are the frequency without the condition for group 1 and group 2, respectively. For the examples on this page group 1 is the treatment group and group 2 is the control group.
Hazard ratio
The hazard ratio is the ratio of hazard rates. Hazard rates are like the relative risk rates, but are specific to a period of time. Hazard rates come from a technique called Survival Analysis (introduced in Chapter 20.9). Survival analysis can be thought of as following a group of subjects over time until something (the event) happens. By following two groups, perhaps one group exposed to a suspected carcinogen vs. another group matched in other respects except the exposure, at the end of the trial, we’ll have two hazard rates: the rate for the exposed group and the rate for the control group. If there is no difference, then the hazard ratio will be one.
Hazard ratios are more appropriate for clinical trials; relative risk is more appropriate for observational studies.
For a hazard ratio, it is often easier to think of it as a probability (between 0 to 1). To translate a hazard ratio to a probability use the following equation
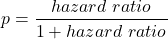
Questions
- Distinguish between odds ratio, relative risk, and hazard ratio.
- Refer to problem 1 introduced in 7.4 – Epidemiology: Relative risk and absolute risk, explained.
Quiz Chapter 7.5
Odds ratio
Chapter 7 contents
4.6 – Adding a second Y axis
Introduction
Scatter plots are used to show association between two continuous variables. However, it is not uncommon to have a third variable for which association between the same X variable is expected. Thus, a common scatter plot includes a second Y axis. These graphs are a bit more involved to make regardless of which application used. The purpose of this short section is to provide a way to create a plot with two Y axes against a common X axis. Additional plotting options are also provided and explained.
The data set
The first draft of this post was written in September 4, 2019, peak time for hurricanes. Hurricane Dorian passed the Bahamas as a category 4 storm heading for Florida. For context I include a screenshot of imagery from NOAA; you can see Dorian along the Florida coastline as well as four additional storms lined up from the coast of Africa across the Atlantic Ocean (Fig 1).
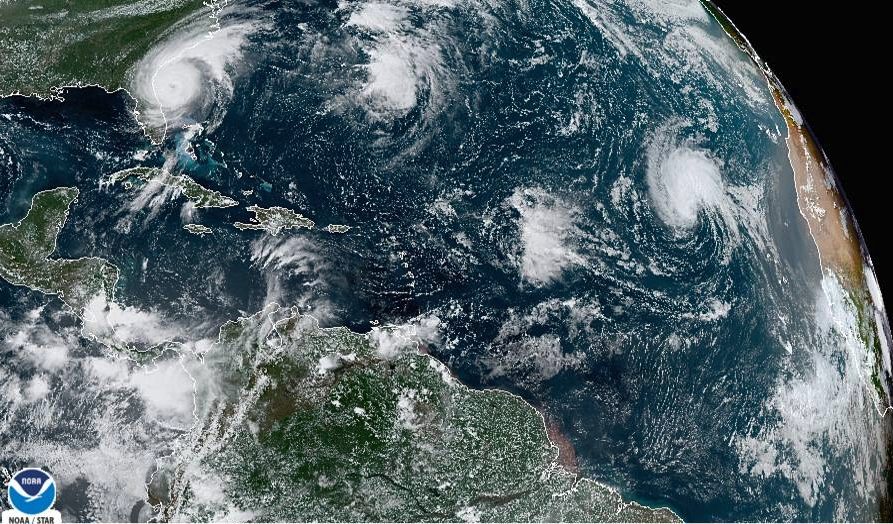
Figure 1. Screenshot from NOAA GOES-East – Sector view: Tropical Atlantic – GeoColor, 4 September 2019. Click image to view full sized image.
The data set here is the number of Atlantic Ocean Category 1, 2, 3, 4, or 5 storms since 1900, tabulated by decade. Storms are categorized by wind speed according to the Saffir-Simpson Hurricane Wind Scale, or SSHWS.
Note 1: Since September 2019 there have been 36 major hurricanes: 2019, October – December = 3; 2020 = 13; 2021 = 3; 2022 = 3; 2023 = 2; 2024 = 12.
Additional data, average levels of carbon dioxide (CO2), a greenhouse gas, measured at Mauna Loa and average global temperature index from NOAA were also acquired for the same period. (The temperature index is called anomaly data as it is the difference of temperature between the average temperatures between 1950 and 1980).
#Create the time data, 12 decades, with 2010 based on 8 years only -- up to 2018
decade <- seq(1900,2010, by = 10)
#Saffir-Simpson Hurricane Wind Scale; compiled from Wikipedia, checked against NOAA
cat01 <- c(2,0,1,3,0,9,4,11,18,11,27,46)
cat02 <- c(2,0,1,3,10,4,5,4,3,13,9,8)
cat03 <- c(7,2,3,1,4,10,9,5,4,12,11,7)
cat04 <- c(1,6,5,8,9,10,9,5,5,10,15,8)
cat05 <- c(0,0,2,6,0,2,4,3,3,2,9,4)
#land ocean anomaly temperature index, NOAA
tempIndex <- c(-0.317,-0.329,-0.241,-0.123,0.042,-0.048,-0.028,0.034,0.247,0.387,0.591,0.791)
#mauna kea CO2, mean by decade, record starts 1958
co2 <- c(NA,NA,NA,NA,NA,316.0,320.3,330.9,345.5,360.5,378.6,399.0)
Note 2: Corresponding temperature anomalies and CO2 data: cc
Combine all of the variables into a single data frame.
storms <- data.frame(decade,tempIndex,cat01,cat02,cat03,cat04,cat05,co2)
head(storms)
Output from R should look like
  decade tempIndex cat01 cat02 cat03 cat04 cat05 co2
1   1900    -0.317     2     2     7     1     0  NA
2   1910    -0.329     0     0     2     6     0  NA
3   1920    -0.241     1     1     3     5     2  NA
4   1930    -0.123     3     3     1     8     6  NA
5   1940     0.042     0    10     4     9     0  NA
6   1950    -0.048     9     4    10    10     2 316
Create a new variable with all categories of storms summed by decade.
#Sum all of the storms
allHur <- cat01+cat02+cat03+cat04+cat05
#Add new variable to the data frame
storms$allHur <- allHur
#Attach the data frame so you don't have to keep referring to the data frame when you call variables.
attach(storms)
Now, create a simple scatter plot, number of hurricanes by decade (Fig 2).
plot(decade,allHur,pch=16)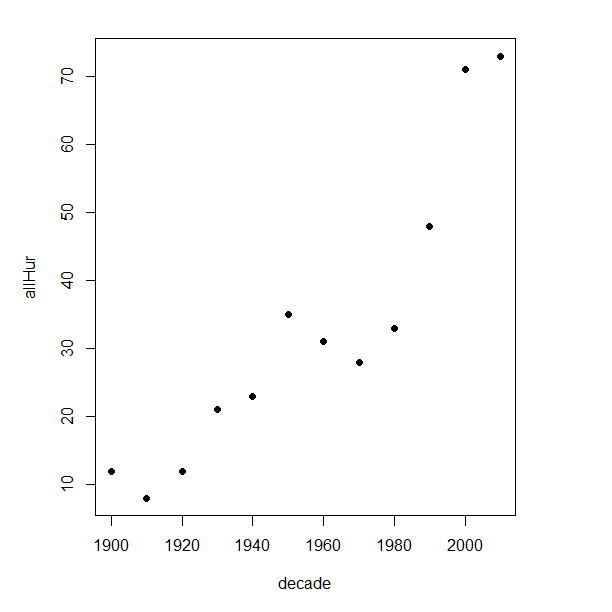
Figure 2. Plot of hurricanes from 1900 to present by decade.
Note 3: Best data come from the satellites, which means use of data since the 1980s would be more appropriate. IPCC reports climate change is projected to increase the intensity of hurricanes, with higher wind speeds and more rainfall. While there is not a consensus on the frequency of storms, the proportion of the most intense storms (Category 4 and 5) is expected to increase, and rapid intensification is also likely to become more common (Masson-Delmotte, et al (2021), IPCC Sixth Assessment Report (AR6) – The Physical Science Basis).
A note on data management
This note is not needed for the plots. However, it’s as good a place as any to comment about how to work with your data in R. For the hurricane data, I set the data frame storms as an unstacked (wide) worksheet. The code that follows shows how to use the reshape2 package, part of the tidyverse set of packages for data manipulation, to convert the data frame from unstacked (wide) to stacked (long).
#code modified from examples presented by Thomas Eisfeld
library(reshape2)
library(dplyr)
tryMe <- melt(storms, id.vars=c("decade", "tempIndex", "co2"), variable.name = "SSHWS", value.name = "hurricanes")
head(tryMe)
You can also take a stacked (long) worksheet and convert it to unstacked (wide) with dcast().
tryAgain <- dcast(tryMe, decade + tempIndex + co2 ~ SSHWS)Make the plots
At last, here’s the code for adding a second Y axis. Code modified from https://www.r-bloggers.com/r-single-plot-with-two-different-y-axes/. The work flow begins by setting parameters of the plotting window, creating the first plot, followed up by adding the second plot (par=TRUE), setting graphing elements, then adding labels and a legend.
First plot example: Total number of hurricanes by decades, with Temperature Index by decades. Number of hurricanes represented on first (left) axis and Temperature Index represented on second (right) axis (Fig 3).
par(mar = c(5,5,2,5))
#Create the first plot
plot(tryAgain$decade, tryAgain$allHur, pch=16, cex=1.5, col="black", xlab="Decades", ylab="Hurricanes", main="Atlantic Hurricanes by Decade")
the syntax par(mar = c(bottom, left, top, right))
#Add the second plot
par(new=T)
plot(tryAgain$decade, tryAgain$tempIndex, type="l", lty="dashed", lwd=2, col="red3", axes=F, xlab=NA, ylab=NA)
axis(side=4)
mtext(side=4,line=3,"Temperature Index")

#Add a legend
legend("topleft",legend=c("Hurricanes", "Temperature Index"),lty=c(0,2), pch=c(16,NA), col=c("black", "red3"))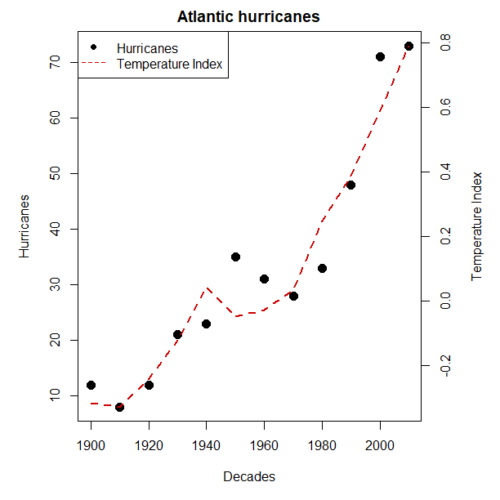
Figure 3. Total number of hurricanes by decades, with Temperature Index by decades. Number of hurricanes represented on first (left) axis and Temperature Index represented on second (right) axis.
Next plot example: Total number of hurricanes by decades, with Atmospheric CO2 measured at Mauna Loa by decades. Number of hurricanes represented on first (left) axis and Atmospheric CO2 represented on second (right) axis (Fig 4).
par(mar = c(5,5,2,5))
plot(tryAgain$decade, tryAgain$allHur, pch=16, cex=1.5, col="black", xlab="Decades", ylab="Hurricanes", main="Atlantic Hurricanes by Decade")
Create space for the second plot in the same frame (use T or TRUE, both work).
par(new=T)Code for the second plot. Note that axes=F (“F” or “FALSE” works) is used to suppress printing axes — Recall that lines were already created by the first plot; if you do not add this, then additional lines are added to the plot.”NA” is used to suppress adding labels; if you do not add this code, then labels will be printed over the existing labels created for the first plot. The code axis=4 sets the right-hand Y axis to active. The next code, mtext() is used to place the axis label for the second Y axis.
plot(tryAgain$decade, tryAgain$co2, type="l", lty="dashed", lwd=2, col="red3", axes=F, xlab=NA, ylab=NA)
axis(side=4)
mtext(side=4,line=3,"Mean CO2, ppm")
Add the legend.
legend("topleft",legend=c("Hurricanes", "CO2"),lty=c(0,2), pch=c(16,NA), col=c("black", "blue"))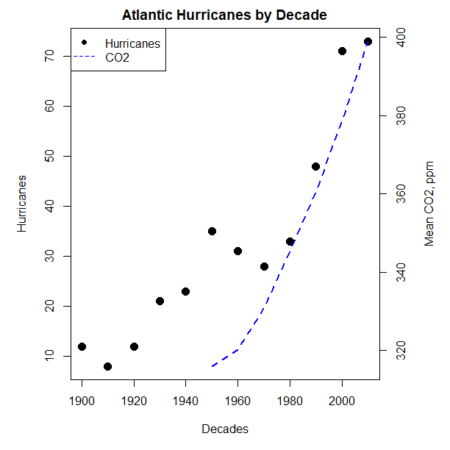
Figure 4. Total number of hurricanes by decades, with Atmospheric CO2 measured at Mauna Kea by decades. Number of hurricanes represented on first (left) axis and Atmospheric CO2 represented on second (right) axis.
Go ahead and try these plots. Change the settings (e.g., lty, pch, cex, col), and note how the graphs look.
Bubble (chart) plot
From the basic scatter plot a variety of variants have been developed to convey additional information about ratio scale variables. The bubble chart is one common example and can be used as an alternative to adding a second Y-axis in some cases. A bubble plot uses the area of a bubble to represent a third variable, while a second y-axis is used to display a second set of data with its own scale on the same chart.
In brief, a third variable is added, mapped to circle size. Spreadsheet apps also include options to make bubble charts and the wonderful plot.ly library provides a vehicle to produce sophisticated graphs including bubble charts online or as a package in R — and it works well with the ggplot2 package. A nice bubble chart introduction is available at Atlassian.
Examples of bubble charts with R code are provided in Ch16.3. That said, what’s one more? Here’s example R code:
ggplot(storms, aes(x = decade, y = tempIndex, size = total_storms)) +
  geom_point(alpha = 0.7, color = "lightgreen") + # Added color = "lightgreen"
  scale_size_continuous(range = c(3, 15)) +
  labs(title = "Temperature Index vs. Decade with Total Storms",
       x = "Decade",
       y = "Land Ocean Anomaly Temperature Index",
       size = "Total Storms") +
  theme_classic()
and the plot, Figure 4.
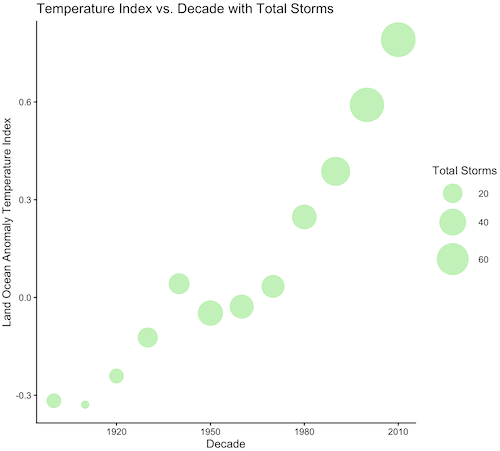
Figure 4. Bubble plot of association between total hurricanes and Land-Ocean Temperature Anomalies by Decade.
If you are interested in trying yourself, a bubble chart yourself, CO2 datas with the hurricane data set is a good candidate for a bubble plot.
Questions
-
Using the
plot()command, make the following graphs- One scatter plot for each category of storm by decade
- Explore the kinds of graph elements available by changing
pchvalues. Create your own - Change point size by changing valued for
cex
- Create a new plot with Decade on X axis, Temperature Index on first Y axis, and CO2 on the second Y axis.
- Include a legend for the plot.
- What is a Q-Q plot used for in statistics?
- Looking at the plot in Figure 5, explain why the confidence lines get further and further away from the straight line.
- What are some advantages and disadvantages of heat map for communicating data.
- What color pallet is considered “color-friendly” for accessible visualization?
- Create a table with three columns.
- In column 1, list the name for each graph type discussed in Chapter 5.
- In column 2, state the kind of data appropriate for each graph.
- In column 3, enter the name of a function in the base R package you can use to make the graph
- In column 4, enter the name of a function from the ggplot2 package you can use to make the graph
Quiz Chapter 4.6
Adding a second Y axis
Chapter 4 contents
4.5 – Scatter plots
Introduction
Scatter plots, also called scatter diagrams, scatterplots, or XY plots, display associations between two quantitative, ratio-scaled variables. Each point in the graph is identified by two values: its X value and its Y value. The horizontal axis is used to display the dispersion of the X variable, while the vertical axis displays the dispersion of the Y variable.
The graphs we just looked at with Tufte’s examples Anscombe’s quartet data were scatter plots (Chapter 4 – How to report statistics).
Here’s another example of a scatter plot, data from Francis Galton, data contained in the R package HistData.
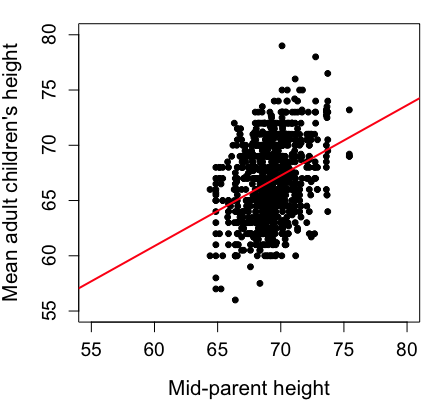
Figure 1. Scatterplot of mid-parent (vertical axis) and their adult children’s (horizontal axis) height, in inches. data from Galton’s 1885 paper, “Regression towards mediocrity in hereditary stature.” The red line is the linear regression fitted line, or “trend” line, which is interpreted in this case as the heritability of height.
Note 1. Sorry about that title — being rather short of stature myself, not sure I’m keen to learn further what Galton was implying with that “mediocrity” quip.
The commands I used to make the plot in Figure 1 were
library(HistData)
data(GaltonFamilies, package="HistData")
attach(GaltonFamilies)

plot(childHeight~midparentHeight, xlab="Mid-parent height", ylab="Mean adult children's height", xlim=c(55, 80), ylim=c(55,80), cex=0.8, cex.axis=1.2, cex.lab=1.3, pch=c(19), data=GaltonFamilies)
abline(lm(childHeight~midparentHeight), col="red", lwd=2)
I forced the plot function to use the same range of values, set by providing values for xlim and ylim; the default values of the plot command picks a range of data that fits each variable independently. Thus, the default X axis values ranged from 64 to 76 and the Y variable values ranged from 55 to 80. This has the effect of shifting the data, reducing the amount of white space, which a naïve reading of Tufte would suggest is a good idea, but at the expense of allowing the reader to see what would be the main point of the graph: that the children are, on average, shorter than the parents, mean height = 67 vs. 69 inches, respectively. Therefore, Galton’s title begins with the word “regression,” as in the definition of regression as a “return to a former … state” (Oxford Dictionary).
For completeness, cex sets the size of the points (default = 1), and therefore cex.axis and cex.lab apply size changes to the axes and labels, respectively; pch refers to the graph elements or plotting characters, further discussed below (see Fig 8); lm() is a call to the linear model function; col refers to color.
Figure 2 shows the same plot, but without attention to the axis scales, and, more in keeping with Tufte’s principle of maximize data, minimize white space.
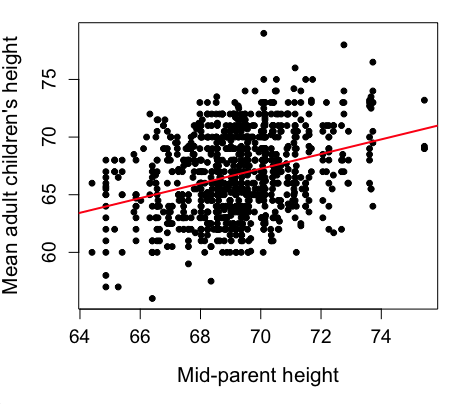
Figure 2. Same plot as Figure 1, but with default settings for axis scales.
Take a moment to compare the graphs in Figure 1 and 2. Setting the scales equal allows you to see that the mid-parent heights were less variable, between 65 and 75 inches, than the mean children height, which ranged from 55 to 80 inches.
And another example, Figure 3. This plot is from the ggplot2() function and was generated from within R Commander’s KMggplot2 plug-in.
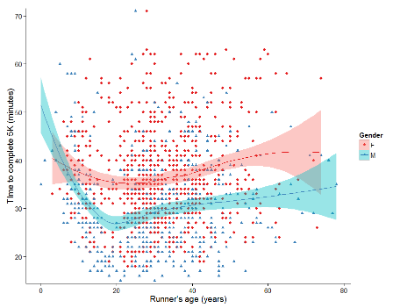
Figure 3. Finishing times in minutes of 1278 runners by age and gender at the 2013 Jamba Juice Banana 5K in Honolulu, Hawaiʻi. Loess smoothing functions by groups of female (red) and male (blue) runners are plotted along with 95% confidence intervals.
Figure 3 is a busy plot. Because there were so many data points, it is challenging to view any discernible pattern, unlike Figure 1 and 2 plots, which featured less data. Use of the loess smoothing function, a transformation of the data to reduce data “noise” to reveal a continuous function, helps reveal patterns in the data:
- across most ages, men completed 5K faster than did females and
- there was an inverse, nonlinear association between runner’s age and time to complete the 5K race.
Take a look at the X-axis. Some runners ages were reported as less than 5 years old (trace the points down to the axis to confirm), and yet many of these youngsters were completing the 5K race in less than 30 minutes. That’s 6-minute mile pace! What might be some explanations for how pre-schoolers could be running so fast?
Design criteria
As in all plotting, maximize information to background. Keep white space minimal and avoid distorting relationships. Some things to consider:
- keep axes same length
- do not connect the dots UNLESS you have a continuous function
- do not draw a trend line UNLESS you are implying causation
Scatter plots in R
We have many options in R to generate scatter plots. We have already demonstrated use of plot() to make scatter plots. Here we introduce how to generate the plot in R Commander.
Rcmdr: Graphs → Scatterplot…
Rcmdr uses the scatterplot function from the car package. In recent versions of R Commander the available options for the scatterplot command are divided into two menu tabs, Data and Options, shown in Figure 4 and Figure 5.
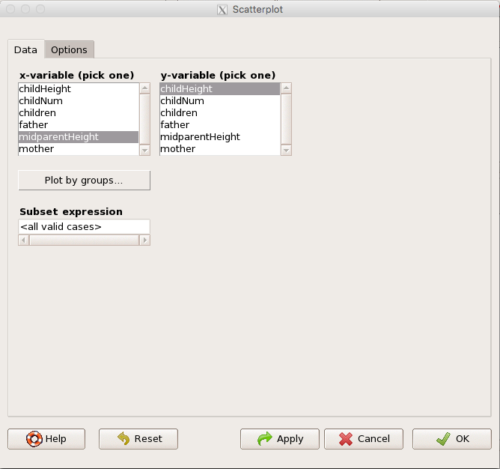
Figure 4. First menu popup in R Commander Scatterplot command, Rcmdr ver. 2.2-3.
Select X and Y variables, choose Plot by groups if multiple grounds are included, eg, male, female, then click Options tab to complete.
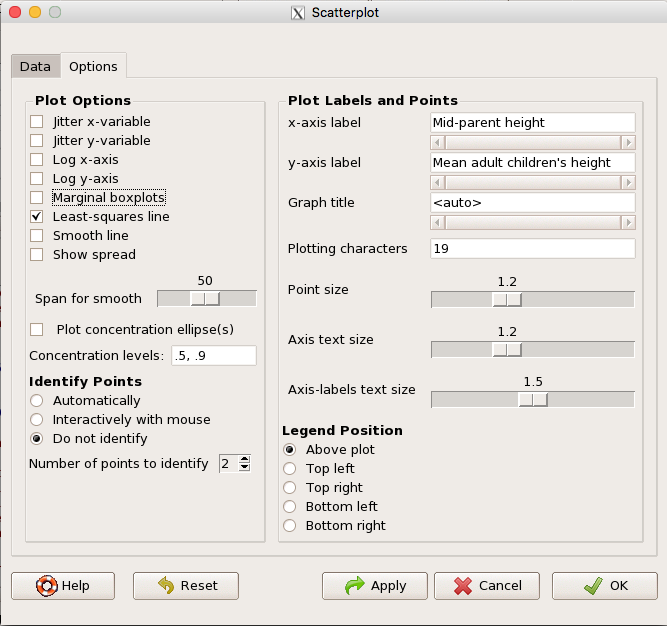
Figure 5. Second menu popup in R Commander scatterplot command., Rcmdr ver. 2.2-3
Set graph options including axes labels and size of the points.
Note 2. Lots of boxes to check and uncheck. Start by unchecking all of the Options and do update the axes labels (see red arrow in image). You can also manipulate the plot “points,” which R refers to as plotting characters (abbreviated pch in plotting commands). The “Plotting characters” box is shown as <auto>, which is an open circle. You can change this to one of 26 different characters by typing in a number between 0 and 25. The default used in Rcmdr scatterplot is “1” for open circle. I typically use “19” for a solid circle.
Here is another example using the default settings in scatterplot() function in the car package, now the default scatter plot command via R Commander (Fig. 4), along with the same graph, but modified to improve the look and usefulness of the graph (Fig. 6). The data set was Puromycin in the package datasets.
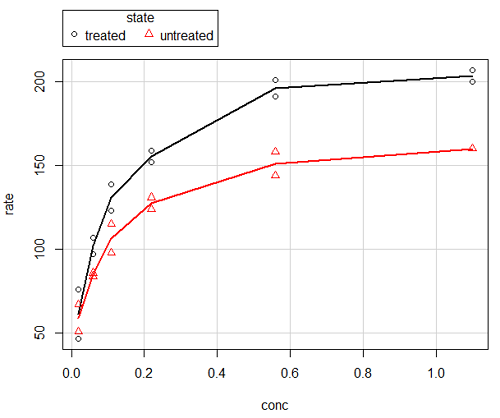
Figure 6. Default scatterplot, package car, from R Commander, version 2.2-4.
Grid lines in graphs should be avoided unless you intend to draw attention to values of particular data points. I prefer to position the figure legend within the frame of the graph, eg, the open are at the bottom right of the graph. Modified graph shown in Figure 7.
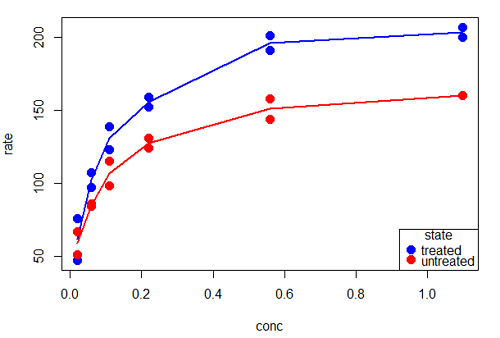
Figure 7. Modified scatterplot, same data from Figure 6
R commands used to make the scatter plot in Figure 7 were
scatterplot(rate~conc|state, col=c("blue", "red"), cex=1.5, pch=c(19,19),
bty="n", reg=FALSE, grid=FALSE, legend.coords="bottomright")
A comment about graph elements in R
In some ways R is too rich in options for making graphs. There are the plot functions in the base package, there’s lattice and ggplot2 which provide many options for graphics, and more. The advice is to start slowly, for example taking advantage of the Figure 8 displays R’s plotting characters and the number you would invoke to retrieve that plotting character.
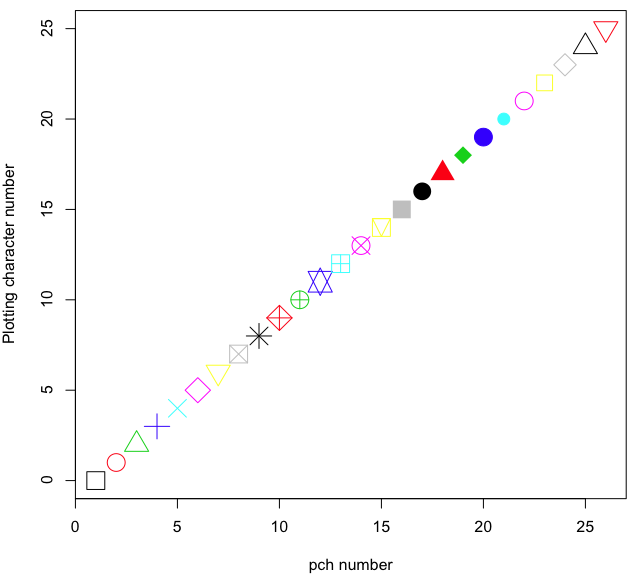
Figure 8. R plotting characters pch = 1 – 25 along with examples of color.
Note 3. To see available colors at the R prompt type
colors()
which returns 667 different colors by name, from
[1] "white" "aliceblue" "antiquewhite"
to
[655] "yellow3" "yellow4" "yellowgreen" There’s a lot more to R plotting. For example, you are not limited to just 25 possible characters. R can print any of the ASCII characters 32:127 or from the extended ASCII code 128:255. See Wikipedia to see the listing of ASCII characters.
In addition to pch, you can change the size of the plotting character with cex, color of the character with col for lines or outlines, and bg to change background color. lwd is used to set the character’s border thickness.
Here’s the R code used to generate the graph in Figure 8. Remember, any line beginning with # is a comment line, not an R command.
#create a vector with 26 numbers, from 0 to 25
stuff <-c(0:25)
plot(stuff, pch=c(32:58), cex = 2.5, col = c(1:26), 'xlab' = "pch number", 'ylab' = "Plotting character number")
Is it “scatter plot” or “scatterplot”?
Spelling matters, of course, and yet there are many words for which the correct spelling seems to be like “beauty,” it is “in the eye of the beholder” (Molly Bawn, 1878, by Margaret Hungerford). Scatter plot is one of these — is it one word or two, or is it something else entirely?
Scatter plot is one of these terms: you’ll find it spelled as “scatterplot” or as “scatter plot,” in the dictionary (eg, Oxford English dictionary), with no guidance to choose between them. And I’m not just talking about the differences between British and American English spelling traditions.
Note 4. The spell checkers in Microsoft Office and Google Docs do not flag “scatterplot” as incorrect, but the spell checker in LibreOffice Writer does (per obs).
Thus, in these situations as an author, you can turn to which of the spellings is in common use. I first looked at some of the statistics books on my shelves. I selected 14 (bio)statistics textbooks and checked the index and if present, chapters on graphics for term usage.
Table 1. Frequency of use of different terms for scatter plot in 14 (bio)statistics books currently on Mike’s shelves.
| spelling | number of statistical texts | frequency |
|---|---|---|
| scatter diagram | 2 | 0.144 |
| scatter plot | 5 | 0.357 |
| scattergram | 1 | 0.071 |
| scatterplot | 5 | 0.357 |
| XY plot | 0 | 0.071 |
Not much help, basically, it is a tie between “scatter plot” and “scatterplot.”
Next, I searched six journals for the interval 1990 – 2016 for use of these terms. Results presented in Table 6 along with journal impact factor for 2014 and number of issues (Table 2).
Table 2. Impact factor and number of issues 1990 – 2016 for six science journals.
| Journal | Impact factor | Issues |
|---|---|---|
| BMJ | 17.445 | 1374 |
| Ecology | 5.175 | 271 |
| J. Exp. Biol | 2.897 | 540 |
| Nature | 41.456 | 1454 |
| NEJM | 55.873 | 1377 |
| Science | 33.611 | 1347 |
My methods? I used the journal’s online search functions for the various usage for scatter plot and the results are shown in Figure 9.
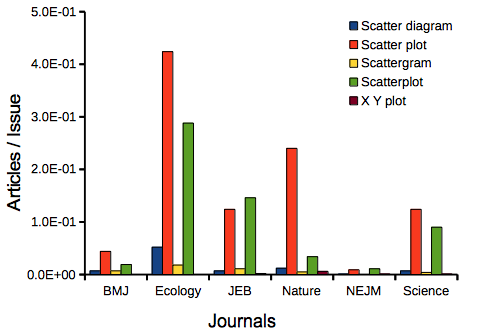
Figure 9. Usage of terms for X Y plots in research articles normalized to number of issues in six journals between 1990 and 2016.
The journals have different numbers of articles; I partially corrected for this by calculating the ratio number of articles with one of the terms divided by the number of issues for the interval 1990 – 2016. It would have been better to count all of the articles, but even I found that to be an excessive effort given the point I’m trying to make here.
Not much help there, although we can see a trend favoring “scatter plot” over any of the other options.
And finally, to completely work over the issue I present results from use of Google’s Ngram Viewer. Ngram Viewer allows you to search words in all of the texts that Google’s folks have scanned into digital form. I searched on the terms in texts between 1950 and 2015, and results are displayed in Figure 10 and Figure 11.
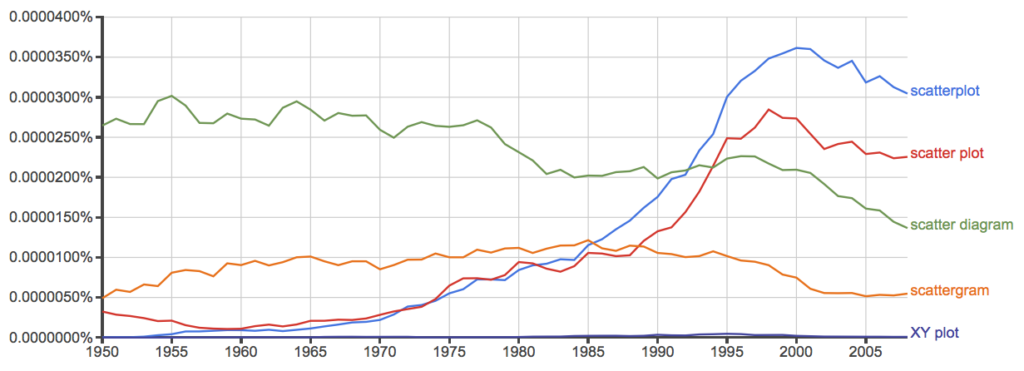
Figure 10. Results from Ngram Viewer for American English, “scatterplot” (blue), “scatter plot” (red), “scatter diagram” (green), “scattergram” (orange), and “XY plot” (purple).
And the same plot, but this time for British sources
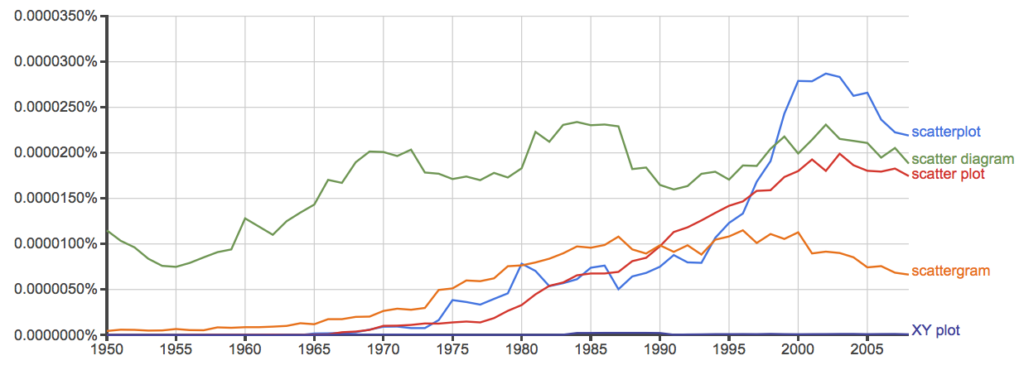
Figure 11. Results from Ngram Viewer for British English. See Figure 10 for key.
Conclusion? It looks like “scatterplot” (blue line) is the preferred usage, but it is close. Except for “scattergram” and “XY plot,” which, apparently, are rarely used. After all of this, it looks like you’re free to make your choice between “scatterplot” or “scatter plot.” I will continue to use “scatter plot.”
Bland-Altman plot
Also known as Tukey mean-difference plot, the Bland-Altman plot is used to describe agreement between two ratio scale variables (Bland and Altman 1986, Giavarina 2015), for example agreement between two different methods used to measure the same samples.
Note 6. Agreement — aka concordance or reproducibility — in the statistical sense is consistent with our everyday conception — consistency among sets of observations on the same object, sample, or unit. We introduce and develop additional agreement statistics in Chapter 9.2 and Chapter 12.3. Additional note for my students — note that I didn’t define agreement by including the term “agree”, thereby avoiding a circular definition (for an amusing clarification on the phrase, see Logically Fallacious). It’s a common short-fall I’ve seen thus far in AI-tools.
Consider use of imageJ by two different observers to record number of pixels of a unit measure (1 cm) on a series of digital images — there’s subjectivity in drawing the lines (where to start, where to end) — do they agree? Data set below. blandr package, blandr.draw function.
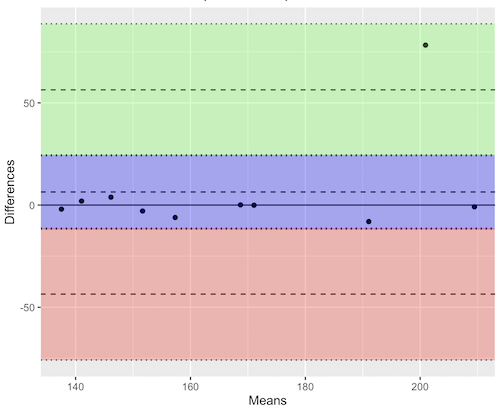
Figure 12. Bland-Altman plot of 1 cm unit measure in pixel number by imageJ from digital images by two independent observers. Purple central region is 95% CI. Lower and upper dashed horizontal lines represent bounds of “acceptable” agreement.
blandr.draw(Obs1, Obs2)
The plot makes it easy to identify questionable points, for example, the one point in upper right quadrant looks suspect.
Visualizing large data sets
Since the early 2000s, size of data sets in biology have increased dramatically, leaving many statistical graphics solutions ill-equipped to tell stories. The data scientists involved with the genomics and health care communities have introduced a number of useful visualizations. We introduce just two, the volcano plot (Fig 13) and the Manhattan-style plot (Fig 14).
Volcano plot
The volcano plot (Fig 13) is a common way to show events that differ between two groups of subjects (eg, p-values), and is common often provides to help visualize gene expression studies of an exposed group vs a control group (eg, fold changes). For the volcano plot, fold changes are reflected on horizontal axis, indicating how much the gene expression level has increased or decreased. The vertical axis typically represents the negative logarithm of the p-value (-logP), which indicates the statistical significance of the change.
Below is R code — with assistance from Gemini AI (Fall 2026) — for a set of five replicate simulated gene expression fold change data sets on stress test (NaCl, H2O2) on yeast grown on YPDA plates. Gene expression profiles were simulated for a set of 100 genes (oxidative pathway, DNA repair pathway); as noted, such studies typically include many more genes.
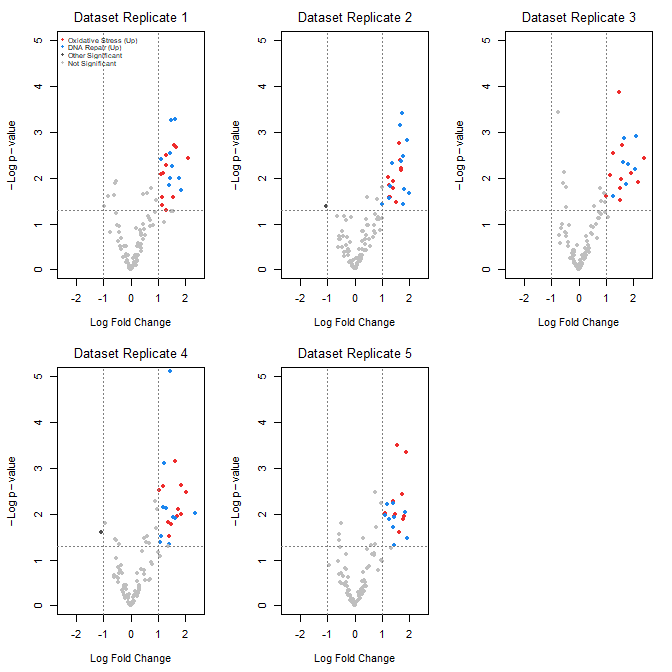
Figure 13. Volcano plot, gene expression fold change on simulated stress test (NaCl, H2O2) yeast data sets, 100 genes (oxidative pathway, DNA repair pathway).
Inspecting the plots (Fig 13), we see a symmetric distribution: The overall distribution of genes is cleanly centered around a Log2 Fold Change (LFC) of zero. This mirrors a realistic transcriptomic profile where the vast majority of the background genome (shown in grey) remains stable, displaying only technical and biological noise. There is a distinct, asymmetrical shift toward positive fold changes among specific gene pathways (targeted activation). Genes belonging to the Oxidative Stress pathway (red) and DNA Repair pathway (blue) consistently surpass both the statistical threshold (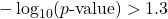 ) and the biological threshold (
 ). Additionally, we see evidence of synergistic effects: The simultaneous application of both stressors (“Both”) drives these pathways to their highest expression levels, pushing them into the top-right quadrant of the plots as highly significant, upregulated features.
R code — with assistance from Gemini AI (Fall 2026) — for yeast gene expression and volcano plots; graphs by base package only.
# ==============================================================================
# 1. SIMULATE 5 REASONABLE DATASETS WITH BIOLOGICAL & TECHNICAL NOISE
# ==============================================================================
set.seed(123) # New seed for realistic distribution

n_genes <- 100
n_datasets <- 5
groups <- c("Control", "Salt", "H2O2", "Both")
n_groups <- length(groups)

# Real-world experiment: each dataset has 3 biological replicates per group
n_reps_per_group <- 3

# Define gene pathways (15 oxidative stress, 15 DNA repair, 70 background/unchanged)
gene_ids <- paste0("Gene_", 1:n_genes)
pathways <- c(rep("Oxidative_Stress", 15), rep("DNA_Repair", 15), rep("Background", 70))

# Initialize a list to hold the 5 realistic datasets
datasets <- list()

for (d in 1:n_datasets) {

# 1. Establish a realistic base expression distribution across 100 genes
# Real data has high-expressing and low-expressing genes
base_expression <- rnorm(n_genes, mean = 7, sd = 2)

# Create a blank sample matrix: 100 genes x 12 samples (4 groups x 3 replicates)
sample_names <- paste0(rep(groups, each = n_reps_per_group), "_R", 1:n_reps_per_group)
expr_matrix <- matrix(0, nrow = n_genes, ncol = length(sample_names))
rownames(expr_matrix) <- gene_ids
colnames(expr_matrix) <- sample_names

# 2. Add realistic baseline biological variation to every sample
for (col_idx in 1:ncol(expr_matrix)) {
expr_matrix[, col_idx] <- base_expression + rnorm(n_genes, mean = 0, sd = 0.4)
}

# 3. Inject subtle, realistic treatment effects (not over-exaggerated)
for (i in 1:n_genes) {
# Every gene gets a tiny bit of random directional drift across groups (real-world noise)
drift <- rnorm(n_groups, mean = 0, sd = 0.15)

if (pathways[i] == "Oxidative_Stress") {
# Subtle upregulation in H2O2 and Both (mean fold change ~ 1.0 to 1.3)
drift[3] <- drift[3] + rnorm(1, mean = 1.1, sd = 0.2) # H2O2
drift[4] <- drift[4] + rnorm(1, mean = 1.3, sd = 0.2) # Both
} else if (pathways[i] == "DNA_Repair") {
# Subtle upregulation in Salt and Both (mean fold change ~ 0.8 to 1.2)
drift[2] <- drift[2] + rnorm(1, mean = 0.9, sd = 0.2) # Salt
drift[4] <- drift[4] + rnorm(1, mean = 1.2, sd = 0.2) # Both
}

# Apply the group drifts to the respective sample columns
for (g_idx in 1:n_groups) {
start_col <- (g_idx - 1) * n_reps_per_group + 1
end_col <- g_idx * n_reps_per_group
expr_matrix[i, start_col:end_col] <- expr_matrix[i, start_col:end_col] + drift[g_idx]
}
}

datasets[[d]] <- expr_matrix
}

# ==============================================================================
# 2. STATISTICAL ANALYSIS (Calculated directly from replicates)
# ==============================================================================
# We will compare the double stressor 'Both' vs 'Control' using real t-tests.
all_lfc <- matrix(0, nrow = n_genes, ncol = n_datasets)
all_pvals <- matrix(0, nrow = n_genes, ncol = n_datasets)
rownames(all_lfc) <- rownames(all_pvals) <- gene_ids

for (d in 1:n_datasets) {
mat <- datasets[[d]]

# Identify the columns for each group
control_cols <- grep("^Control_", colnames(mat))
both_cols <- grep("^Both_", colnames(mat))

for (i in 1:n_genes) {
control_vals <- mat[i, control_cols]
both_vals <- mat[i, both_cols]

# Real Log2 Fold Change (Difference of means since data is on log scale)
all_lfc[i, d] <- mean(both_vals) - mean(control_vals)

# Real Student's t-test
ttest_res <- t.test(both_vals, control_vals, var.equal = TRUE)
all_pvals[i, d] <- ttest_res$p.value
}
}

# ==============================================================================
# 3. GENERATE REALISTIC VOLCANO PLOTS
# ==============================================================================
par(mfrow = c(2, 3), mar = c(4.5, 4.5, 2.5, 1.5))

lfc_threshold <- 1.0
p_threshold <- 0.05

for (d in 1:n_datasets) {
lfc <- all_lfc[, d]
neg_log10_p <- -log10(all_pvals[, d])

col_vector <- rep("grey75", n_genes)

is_sig_up <- (lfc >= lfc_threshold) & (all_pvals[, d] <= p_threshold)
is_sig_down <- (lfc <= -lfc_threshold) & (all_pvals[, d] <= p_threshold)

col_vector[is_sig_up & pathways == "Oxidative_Stress"] <- "firebrick2"
col_vector[is_sig_up & pathways == "DNA_Repair"] <- "dodgerblue2"
col_vector[(is_sig_up | is_sig_down) & col_vector == "grey75"] <- "grey30"

plot(lfc, neg_log10_p,
col = col_vector,
pch = 19,
cex = 0.9,
xlab = expression(Log ~ Fold ~ Change),
ylab = expression(-Log ~ p - value),
main = paste("Dataset Replicate", d),
xlim = c(-2.5, 2.5),
ylim = c(0, 5),
font.main = 1)

abline(v = c(-lfc_threshold, lfc_threshold), col = "grey50", lty = 3)
abline(h = -log10(p_threshold), col = "grey50", lty = 3)

# Set the legend.
if (d == 1) {
legend("topleft",
legend = c("Oxidative Stress (Up)", "DNA Repair (Up)", "Other Significant", "Not Significant"),
col = c("firebrick2", "dodgerblue2", "grey30", "grey75"),
pch = 19,
cex = 0.6,
box.lty = 0,
bg = "transparent")
}
}

# Reset layout parameters
par(mfrow = c(1, 1))
End R code.
About the simulation
- Symmetric, Balanced Center: Most of the 100 genes (the 70 background genes) are strictly driven by standard biological and technical noise. This distributes them evenly around 0 on the X-axis, meaning you will naturally see negative fold changes alongside positive ones.
- Realistic Effect Scales: True upregulations are dialed down to max out around
 to

 Fold Changes, mirroring standard biological responses on YPDA plates.
- True T-Tests: Instead of faking p-values, each simulated dataset now contains 3 biological samples per group. The p-values are calculated dynamically using t.test(), generating a mathematically sound distribution pattern on the Y-axis.
Manhattan plot
A Manhattan plot (Fig 14) is a type of scatter plot used to display the statistical significance of large sets of data points simultaneously. Some feature of the experiment, for example location in the genome or sequential test identifiers, is displayed on the horizontal axis. Like the volcano plot (Fig 13), the vertical axis displays the statistical significance (eg, -log10(p-value)).
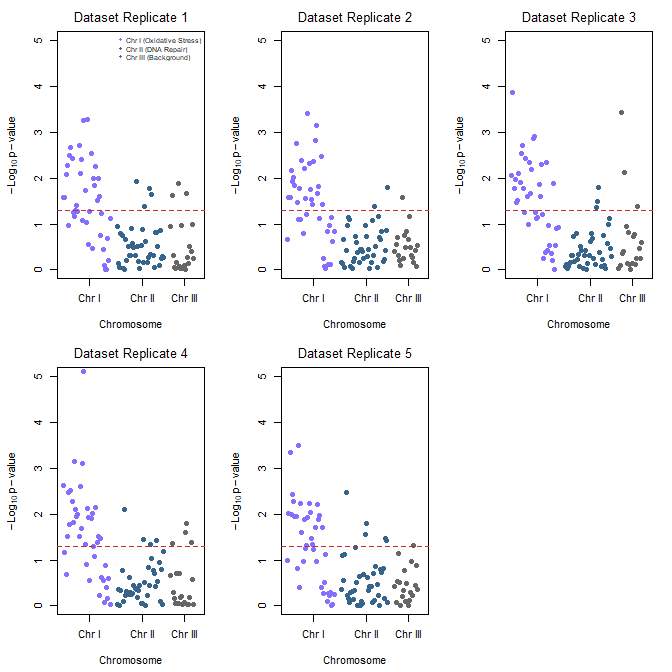
Figure 14. Manhattan plot, gene expression fold change on simulated stress test (NaCl, H2O2) yeast data sets, 100 genes (oxidative pathway, DNA repair pathway).
Looking over the plots (Fig 14) we see evidence of pathway clustering: By arranging the 100 genes sequentially across three chromosomes, we see distinct localized peaks rather than a random distribution of significant points. We also see chromosome hotspots: Chromosome I (Oxidative Stress genes) and Chromosome II (DNA Repair genes) display pronounced vertical clusters that reliably break through the red significance line across all five experimental replicates. This simulates a real-world genomic architecture where functionally related gene clusters or operon-like structures respond in unison to environmental shifts.
Conversely, Chromosome III (Background genes, ie, baseline Control) remained entirely flat and well below the significance threshold, validating that the observed stress responses are highly specific and not an artifact of global transcriptional runaway.
R code — with assistance from Gemini AI (Fall 2026) — for Manhattan plot.
# ==============================================================================
# 1. ASSIGN GEOMETRIC CHROMOSOME POSITIONS TO SIMULATED GENES
# ==============================================================================
# We will use the exact same 5 datasets generated in the previous step.
# To plot a Manhattan plot, every gene needs a Chromosome and a Base Pair (BP) position.

# Assign chromosomes:
# Chromosome 1: Genes 1-40 (Oxidative Stress pathway)
# Chromosome 2: Genes 41-80 (DNA Repair pathway)
# Chromosome 3: Genes 81-100 (Background/Control pathway)
chroms <- c(rep(1, 40), rep(2, 40), rep(3, 20))

# Assign incremental Base Pair positions along each chromosome
bp_positions <- c(seq(1000, 40000, length.out = 40),
seq(1000, 40000, length.out = 40),
seq(1000, 20000, length.out = 20))

# To make a continuous X-axis across multiple chromosomes, we calculate cumulative positions
chr_lengths <- c(45000, 45000, 25000)
chr_offsets <- c(0, cumsum(chr_lengths)[1:2])
coord_x <- bp_positions + chr_offsets[chroms]

# Calculate where the chromosome tick marks should sit on the X-axis (the midpoints)
chr_midpoints <- chr_offsets + (chr_lengths / 2)

# ==============================================================================
# 2. GENERATE MANHATTAN PLOTS FOR ALL 5 REPLICATES
# ==============================================================================
# Set up a clean 2x3 plotting grid to display all 5 replicates together
par(mfrow = c(2, 3), mar = c(4.5, 4.5, 2.5, 1.5))

# Standard scientific significance line (-log10(0.05) is ~1.3)
p_threshold <- 0.05
suggestive_line <- -log10(p_threshold)

for (d in 1:n_datasets) {
neg_log10_p <- -log10(all_pvals[, d])

# Alternating color scheme per chromosome to differentiate boundaries
# Chromosome 1 = Slate Blue, Chromosome 2 = Deep Blue, Chromosome 3 = Dark Grey
chr_colors <- c("lightslateblue", "steelblue4", "grey40")
col_vector <- chr_colors[chroms]

# Create the Manhattan plot grid
plot(coord_x, neg_log10_p,
col = col_vector,
pch = 19,
cex = 1.0,
xaxt = "n", # Suppress the standard numeric X-axis to draw custom Chromosome ticks
xlab = "Chromosome",
ylab = expression(-Log[10] ~ p - value),
main = paste("Dataset Replicate", d),
xlim = c(0, sum(chr_lengths)),
ylim = c(0, 5),
font.main = 1)

# Add the standard genome-wide significance horizontal threshold line
abline(h = suggestive_line, col = "firebrick3", lty = 2, lwd = 1.2)

# Draw the custom structural X-axis labeling the specific chromosomes
axis(1, at = chr_midpoints, labels = c("Chr I", "Chr II", "Chr III"))

# Add an explanatory legend to the first plot panel to map pathways to locations
if (d == 1) {
legend("topright",
legend = c("Chr I (Oxidative Stress)", "Chr II (DNA Repair)", "Chr III (Background)"),
col = c("lightslateblue", "steelblue4", "grey40"),
pch = 19,
cex = 0.65,
box.lty = 0,
bg = "transparent")
}
}

# Reset layout parameters back to default single screen layout
par(mfrow = c(1, 1))
About the R code.
The Genomic Peaks: Because these simulated Oxidative Stress genes sit together on Chromosome I and DNA Repair genes sit on Chromosome II, we see pronounced, beautiful vertical clusters extending upwards over the red significance line.
The Noise Flatline: Chromosome III hosts the background genes, creating a realistically flat landscape where points rarely cross the significance threshold.
Alternating Chromosome Tracks: Using the standard coordinate offset method, the data points stay organized left-to-right without overlapping.
Questions
- Using our Comet assay data set (Table 1, Chapter 4.2), create scatter plots to show associations between tail length, tail percent, and olive moment.
- Explore different settings including size of points, amount of white area, and scale of the axes. Evaluate how these changes change the “story” told by the graph.
Quiz Chapter 4.5
Scatter plots
Data sets
Number of pixels of 1 cm length from unit measure on ten digital images. Recorded by two independent observers, Obs1 and Obs2.
 Obs1, Obs2
171.026, 171.105
136.528, 138.521
148.084, 144.222
142.014, 140.057
150.213, 153.118
187.011, 195.092
168.760, 168.668
154.302 ,160.381
209.022, 209.876
240.067, 161.805
Gene expression
ccc
Chapter 4 contents