6.5 – Discrete probability distributions
Binomial distribution
Discrete refers to particular outcomes — data that take on only specific separate values. Discrete data types include all of the categorical types we introduced earlier, including binary, ordinal, and nominal.
The binomial probability distribution is a discrete distribution for the number of successes, k, in a sequence of n independent trials, where the outcome of each trial can take on only one of two possible outcomes. For cases of 0 or 1, yes or no, “heads” or “tails,” male or female, pass or fail, we talk about the binomial distribution, because the outcomes are discrete and there can be only two possible (binary) outcomes.
Note 1: The biological definition of sex is binary — whether sexually reproducing organism produces male (sperm) or female (ovum) gametes (cf discussion in Goymann et al 2022). For the argument that sex is a continuum held by some biomedical and social scientists, see Ainsworth 2015.
The mathematical function of the binomial is written as
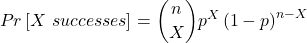
where the binomial coefficient is given by
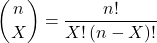
and X refers to the number of ways to choose “success” from n observations.
Consider an example.
We have to define what we mean by success. For coin toss, this might be the number of heads.
The mean for the binomial this is given simply as

where X is “Heads” (the category of successes for our example), and p corresponds to the probability the selected event occurs, in this case, “Heads.”
The variance of the binomial distribution is given by
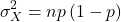
Here’s a density plot of two trials with success 2% with n (x) equal to 20 (Fig 1).
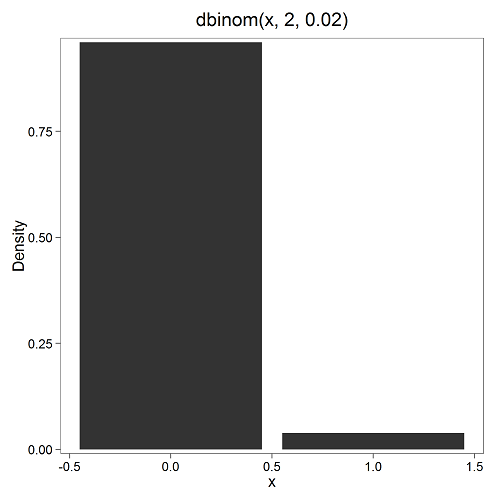
Figure 1. Plot generated with KMggplot2 Rcmdr plugin.
Here’s the R code
Create the trials, 1 through 20, then create an object to hold the number of trials
nSize=1:20
Size <- length(nSize); Size
R returns
[1] 20
Assign the probability value to an object
prob <- 0.02
Next, calculate the mean, mu, and the variance, var, for the binomial with prob = 0.02 and number of trials Size = 20
mu <- Size*prob
var <- Size*prob*(1-prob)
Print the mean and variance; lets assign them to an object then print the object
stats <- c(mu, var); stats
And R returns
[1] 0.400 0.392
And here’s a real-world example. Twinning in humans is rare. In Hawaiʻi in the 1990’s the rate of twin births (monozygotic and dizygotic) was about 20 for every 1000 births or 2%. “Success” here then is twin births.
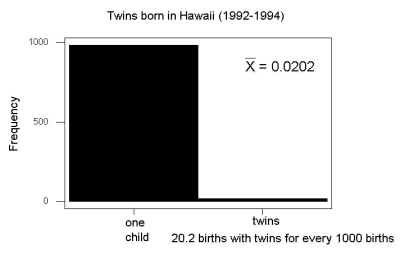
Figure 2. Example of binomial-like distribution: reported twins born in Hawaiʻi.
Interestingly, rates of twins have since increased in Hawaiʻi (31 out of 1000 births) and in the United States overall (33 out of 1000 births) (Table 2, NCHS Data Brief No. 80, 2012). Data for Fig 2 were for year 2009.
Out of ten births, what is the probability of two twin births in Hawaiʻi?

You can solve this with your calculator (yikes!), or take advantage of online calculators (GraphPad QuickCalcs), or use R and Rcmdr.
In R, simply type at the prompt
dbinom(2,10,0.031)
[1] 0.03361446
Try in R Commander.
Rcmdr → Distributions → Discrete distributions → Binomial distribution → Binomial probabilities …
Figure 3. Rcmdr menu to get binomial probability.
Note I used p = 0.033 the rate for entire USA. Here’s the output
> .Table <- data.frame(Pr=dbinom(0:10, size=10, prob=0.033))
> rownames(.Table) <- 0:10
> .Table
Pr
0  7.149320e-01
1  2.439789e-01
2  3.746728e-02 ← Answer, 0.0375 or 3.75%
3  3.409639e-03
4  2.036263e-04
5  8.338782e-06
6  2.371422e-07
7  4.624430e-09
8  5.918028e-11
9  4.487991e-13
10 1.531579e-15
And here is the output for our example from Hawaiʻi (p = 0.031).
> .Table <- data.frame(Pr=dbinom(0:10, size=10, prob=0.031))
> rownames(.Table) <- 0:10
> .Table
Pr
0  7.298570e-01
1  2.334940e-01
2  3.361446e-02 ← Answer, 0.0336 or 3.36%
3  2.867694e-03
4  1.605494e-04
5  6.163507e-06
6  1.643178e-07
7  3.003893e-09
8  3.603741e-11
9  2.561999e-13
10 8.196283e-16
We use the binomial distribution as the foundation for the binomial test, ie, the test of an observed proportion against an expected population level proportion in a Bernoulli trial.
Hypergeometric distribution
The binomial distribution is used for cases of sampling with replacement from a population. When sampling without replacement is done, the hypergeometric distribution is used. It is the number of successes, k, in a sequence of n independent trials drawn from a fixed population.
Note 2: A fixed population in epidemiology refers to a group of individuals, defined by set of characteristics. Examples include individuals selected because they all share a common life event, eg, giving birth. The population is “fixed” because, once an individual is included in the population, they remain a member of the population even if their characteristics change during the duration of the study. The opposite of a fixed population is an dynamic or open population. Definitions from Chapter 2 in Aschengrau and Seage (2003).
This sampling scheme means that each draw is no longer independent — with each draw you decrease the remaining number of observations and thus change the proportion.
The P-value from the hypergeometric distribution is often used to study if genes from a list of Gene Ontology (eg, biological process functional terms like “cell cycle,” or “apoptosis”) are enriched in the sets of genes with expression differences across the treatment groups (cf, discussion in Cao and Zhang 2014). The R package gprofiler2, which links to a Cloud service at g:Profiler, the can be used to do gene enrichment analyses with stunning visualizations (eg, Manhattan plot) suitable for publication.
The mathematical function of the hypergeometric is written as

where N is the population size, K is the number of successes in that population, and n and k are defined as above. Lets look apply this to the twinning problem.
In 2009, 2200 women gave birth in Hawaiʻi County, Hawaiʻi. Out of 10 births, what is the probability of 2 twin births in Hawaiʻi?
Assuming “risk” of twinning is the same rate as in rest of USA, then we have expected 72 successes in this population (0.033 * 2200).
Here’s the graph (Fig 4).
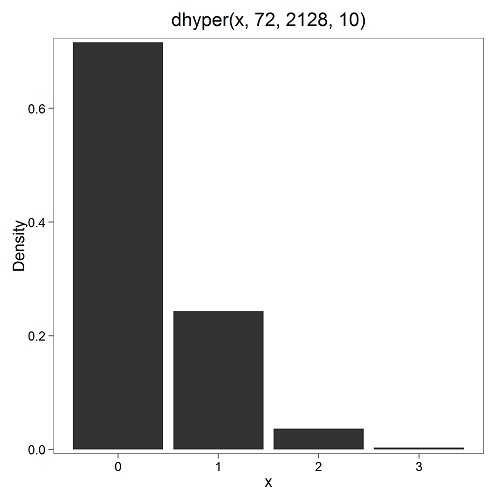
Figure 4. Plot of hypergeometric distribution twinning Hawaiʻi.
where the X axis values shows the number of events with successes (twin births). Taking the bin 2 (we wanted to know about probability of 2 out of ten), we can draw a line back to the Y-axis to get our probability — looks like about 5% roughly. Plot drawn with KMggplot2
To get the actual probability,
Rcmdr → Distributions → Discrete distributions → Hypergeometric distribution → Hypergeometric probabilities …
Figure 5. Rcmdr menu to get hypergeometric probability.
where m is the number of successes, n is the number of “failures,” and k is the number of trials.
> .Table
Pr
0 0.716453457
1 0.243438645
2 0.036688041 ← Answer, 0.0367 or 3.67%
3 0.003228871
The reference to white and black balls and urns is a device described by Bernoulli himself and has been used by others ever since to discuss probability problems (called the urn problem) and so I apply it here to be consistent. The urn contains a number of white (x) and a number of black (y) balls mixed together. One ball is drawn randomly from the urn — what color is it? The ball is then is either returned into the urn (replacement) or it is left out (without replacement) as in the hypergeometric problem, and the selection process is repeated.
Besides applications in gambling and balls-in-urns problems, this distribution is the basis for many tests of gene enrichment from microarray analyses. The hypergeometric forms the basis of the Fisher Exact test (see Chapter 9.5).
Discrete uniform distribution
For discrete cases of “1,” “2,” “3,” “4,” “5,” or “6,” on the single toss of fair dice, we can talk about the discrete uniform distribution because all possible outcomes are equally likely. If you are branded as a “card-counter” in Las Vegas, all you’ve done is reached an understanding of the uniform distribution of card suits!
One biological example would be the fate of a random primary oocyte in the human (mammal) female — three out of four will become polar bodies, eventually reabsorbed, whereas one in four will develop into a secondary oocyte (egg); the uniform distribution has to do with the counts of the products — each of the four primary oocytes has the same (apparently) chance (25%) of becoming the egg (Edwards and Beard 1997).
Analyses in biological research often use a uniform distribution as a baseline or null model (Gotelli and Ulrich 2011). For DNA sequencing, the uniform distribution provides a baseline for assessing coverage bias, eg, GC bias (Ross et al 2013). The uniform distribution underlies the Jukes–Cantor evolutionary model. The Jukes–Cantor model assumes equal substitution rates among all four nucleotides (A, T, C, G) and equal base frequencies (Felsenstein 2003).
The uniform distribution exists also for continuous data types, where every value within a specified interval has equal probability density. For example, DNA shearing — by endonucleases, proteases, or tansposases — during initial library prep for sequencing reactions, breakpoints may be modeled as uniformly distributed along fragment length. Non-uniform distributions reveal cleavage bias. Sequence-dependent cleavage bias is concluded when certain DNA fragments or sequences are generated or detected more (or less) frequently than would be expected by chance (Meyer and Liu 2014). This generates many false positives — that is, identifying a biological signal or molecule that isn’t actually there (Nix et a; 2008).
Poisson distribution
An extension from the binomial case is that, rather than following success or failure, you may have the following scenario. Consider a wind-dispersed seed released from a plant. If we markup the area around the plant in grids, we could then count the number of seeds within each grid. Most grids will have no seeds, some grids will have one seed, a few grids may have two seeds, etc. Multiple seeds in grids is a rare event. The graph might look like
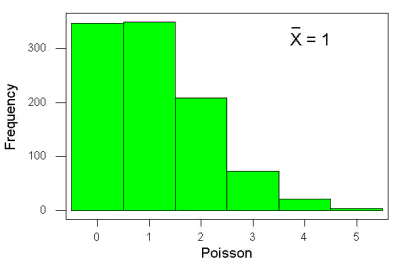
Figure 6. Example, poisson-like graph: the number of wind-dispersed seeds within each grid.
In molecular biology, use of Poisson distribution is common. In digital PCR for example, a DNA sample is diluted and divided into thousands of small reaction volumes or partitions. Thus, each partition contains either zero molecules, one molecule, or more than one molecule, where the loading of molecules into partitions is assumed to be independent, random, and rare per partition. In sequencing, Poisson models are used to describe random sampling of molecules and reads, especially when coverage is generated by non-deterministic processes like shotgun sequencing.
The Poisson has interesting properties, one being that the expected mean, λ, is equal to the variance. Lambda is, with respect to the Poisson distribution, the average number of times an event happens over a specific period or area.
An equation is

where μ is the mean (or could substitute with variance!), e is the natural logarithm, and X is number of successes you are interested in. For example, if μ = 1, what is the probability of observing a grid with five seeds? Simple enough to do this by hand, but let’s use Rcmdr instead. Here’s the graph (Fig 7) from Rcmdr (KMggplot2 plugin).
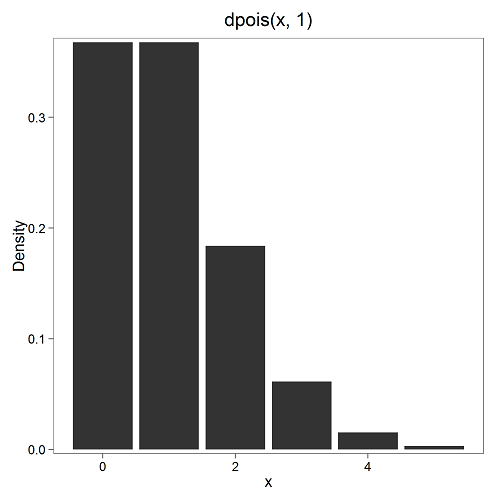
Figure 7. The probability of observing a grid with five seeds, poisson μ = 1 (ggplot2).
and for the actual probability we have from R
dpois(5, lambda = 1)
[1] 0.003065662
Rcmdr → Distributions → Discrete distributions → Poisson distribution → Poisson probabilities … (Fig 8)
The only thing to enter is the mean (some call μ lambda with symbol λ).
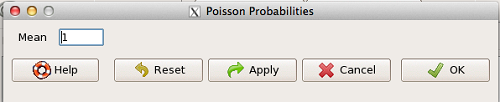
Figure 8. Rcmdr menu, poisson probability.
Here’s the output from R. For intervals 0, 1, 2, 3, …, 6 (Rcmdr just enters this range for you!
> .Table <- data.fram(Pr=dpois(0:6, lambda = 1))
> rownames(.Table) <- 0:6
> .Table
Pr
0 0.3678794412
1 0.3678794412
2 0.1839397206
3 0.0613132402
4 0.0153283100
5 0.0030656620 ← Answer, 0.0307 or 3.07%
6 0.0005109437
Next — Continuous distributions
And finally, for ratio (continuous) scale data, which can take on any value, we can express the chance that probability of a given point as a continuous function, with the normal distribution being one of the most important examples (there are others, like the F-distribution). Many statistical procedures assume that the data we use can be viewed as having come from a “normally distributed population.” See Chapter 6.6.
Questions
1.2. Quarterback sacks by game for the NFL team Seahawks, years 2011 through 2022 are summarized below (data extracted from https://www.pro-football-reference.com/ ).
| Sacks | How many games? |
| 0 | 25 |
| 1 | 46 |
| 2 | 49 |
| 3 | 39 |
| 4 | 25 |
| 5 | 14 |
| 6 | 8 |
| 7 | 2 |
| 8 | 1 |
| 9 | 0 |
a) Assuming a Poisson distribution, what are the mean (lambda) and variance?
b) The table covers a total of 112 games. How many sacks (events) were observed?
c) What is the probability of the Seahawks getting zero sacks in a game (in 2022, a season was 17 games; prior years a season was 16 games)?
Quiz Chapter 6.5
Discrete probability
Chapter 6 contents
- Introduction
- Some preliminaries
- Ratios and proportions
- Combinations and permutations
- Types of probability
- Discrete probability distributions
- Continuous distributions
- Normal distribution and the normal deviate
- Moments
- Chi-square distribution
- t distribution
- F distribution
- References and suggested readings
5.5 – Importance of randomization in experimental design
Introduction
If the goal of the research is to make general, evidenced-based statements about causes of disease or other conditions of concern to the researcher, then how the subjects are selected for study directly impacts our ability to make generalizable conclusions. The most important concept to learn about inference in statistical science is that your sample of subjects upon which all measurements and treatments are conducted, ideally should be a random selection of individuals from a well-defined reference population.
The primary benefit of random sampling is that it strengthens our confidence in the links between cause and effect. Often after an intervention trial is complete, differences among the treatment groups will be observed. Groups of subjects who participated in sixteen weeks of “vigorous” aerobic exercise training show reduced systolic blood pressure compared to those subjects who engaged in light exercise for the same period of time (Cox et al 1996). But how do we know that exercise training caused the difference in blood pressure between the two treatment groups? Couldn’t the differences be explained by chance differences in the subjects? Age, body mass index (BMI), overall health, family history, etc?
How can we account for these additional differences among the subjects? If you are thinking like an experimental biologist, then the word “control” is likely coming to the foreground. Why not design a study in which all 60 subjects are the same age, the same BMI, the same general health, the same family … history…? Hmm. That does not work. Even if you decide to control age, BMI, and general health categories, you can imagine the increased effort and cost to the project in trying to recruit subjects based on such narrow criteria. So, control per se is not the general answer.
If done properly, random sampling makes these alternative explanations less likely. Random sampling implies that other factors that may causally contribute to differences in the measured outcome, but themselves are not measured or included as a focus of the research study, should be the same, on average, among our different treatment groups. The practical benefits of proper random sampling is that recruiting subjects gets easier — fewer subjects will be needed because you are not trying to control dozens of factors that may (or may not!) contribute to differences in your outcome variable. The downside to random sampling is that the variability of the outcomes within your treatment groups will tends to increase. As we will see when we get to statistical inference, large variability within groups will make it less likely that any statistical difference between the treatment groups will be observed.
Demonstrate the benefits of random sampling as a method to control for extraneous factors.
The study reported by Cox et al included 60 obese men between the ages of 20 and 50. A reasonable experimental design decision would suggest that the 60 subjects be split into the two treatment groups such that both groups had 30 subjects for a balanced design. Subjects who met all of the research criteria and who had signed the informed consent agreement are to be placed into the treatment groups and there are many ways that group assignment could be accomplished. One possibility, the researchers could assign the first 30 people that came into the lab to the Vigorous exercise group and the remaining 30 then would be assigned to the Light exercise group. Intuitively I think we would all agree that this is a suspect way to design an experiment, but more importantly, why shouldn’t you use this convenient method?
Just for argument’s sake, imagine that their subjects came in one at a time, and, coincidentally, they did so by age. The first person was age 21, the second was 22, and so on up to the 30th person who was 50. Then, the next group came in, again, coincidentally in order of ascending age. If you calculate the simple average age for each group you will find that they are identical (35.5 years). On the surface, this looks like we have controlled for age: both treatment groups have subjects that are the same age. A second option is to sort the subjects into the two treatment groups so that a 21 year old is in Group A, and the other 21 year old is in Group B, and so on. Again, the average age of Group A subjects and of Group B subjects would be the same and therefore controlled with respect to any covariation between age and change in blood pressure. However, there are other variables that may covary with blood pressure, and by controlling one, we would need to control the others. Randomization provides a better way.
I will demonstrate how randomization tends to distribute the values in such a way that the groups will not differ appreciably for the nuisance variables like age and BMI differences and, by extension, any other covariable. The R work is attached following the Reading list. The take-home message: After randomly selecting subjects for assignment to the treatment groups, the apparent differences between Group A and Group B for both age and BMI are substantially diminished. No attempt to match by age and by BMI is necessary. The numbers are shown in the table and then in two graphics (Fig 1, Fig 2) derived from the table.
Table 1. Mean age and BMI for subjects in two treatment groups A and B where subjects were assigned randomly or by convenience to treatment groups.
| Group | Random assignment of subjects to treatment groups | Convenience assignment of subjects to treatment groups |
|---|---|---|
| A | 35.2 | 28 |
| B | 35.8 | 43 |
| A | 32.49 | 28.99 |
| B | 32.87 | 37.37 |
Just for emphasis, the means from Table 1 are presented in the next two figures (Fig 1 and Fig 2).
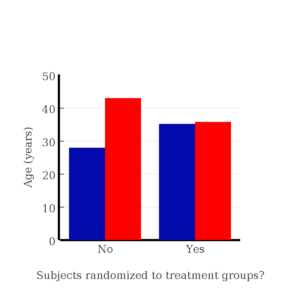
Figure 1. Age of subjects by groups (A = blue, B = red) with and without randomized assignment of subjects to treatment groups.
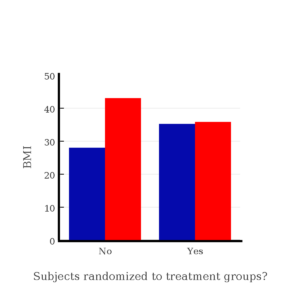
Figure 2. BMI of subjects by groups (A = blue, B = red) with and without randomized assignment of subjects to treatment groups.
Note that the apparent difference between A and B for BMI disappear once proper randomization of subjects was accomplished. In conclusion, a random sample is an approach to experimental design that helps to reduce the influence other factors may have on the outcome variable (eg, change in blood pressure after 16 weeks of exercise). In principle, randomization should protect a project because, on average, these influences will be represented randomly for the two groups of individuals. This reasoning extends to unmeasured and unknown causal factors as well.
This discussion was illustrated by random assignment of subjects to treatment groups. The same logic applies to how to select subjects from a population. If the sampling is large enough, then a random sample of subjects will tend to be representative of the variability of the outcome variable for the population and representative also of the additional and unmeasured cofactors that may contribute to the variability of the outcome variable.
What about observational studies? How does randomization work?
However, if you do cannot obtain a random sample, then conclusions reached may be sample-specific, biased. …perhaps the group of individuals that likes to exercise on treadmills just happens to have a higher cardiac output because they are larger than the individuals that like to exercise on bicycles. This nonrandom sample, an example of confounding where an extraneous or nuisance variable, body size, is associated with both the independent variable (exercise preference) and the dependent variable (cardiac output), will bias your results and can lead to incorrect interpretation of results.
Alternatively, perhaps a researcher elects to study the cardiac output of treadmill users versus bicycle users. The researcher sets up their testing station inside a gym’s powerlifting zone, where the largest individuals in the gym hang out. Inevitably because of this choice, the researcher over recruits larger individuals into the treadmill group, leading to a falsely elevated average cardiac output for treadmill users. This is an example of ascertainment bias — the sample is not representative of all treadmill users at the gym.
Random sampling is CRUCIAL in epidemiology, opinion survey work, most aspects of health, drug studies, medical work with human subjects. It’s difficult and very costly to do… so most surveys you hear about, especially polls reported from Internet sites, are NOT conducted using random sampling (included in the catch-all term “probability sampling“)!! As an aside, most opinion survey work involves complex sample designs involving some form of geographic clustering (eg, all phone numbers in a city, random sample among neighborhoods).
Random sampling is the ideal if generalizations are to be made about data, but strictly random sampling is not appropriate for all kinds of studies. Consider the question of whether or not EMF exposure is a risk factor for developing cancer (Pool 1990). These kinds of studies are observational: at least in principle, we wouldn’t expect that housing and therefore exposure to EMF is manipulated (cf. discussion Walker 2009). Thus, epidemiologists will look for patterns: if EMF exposure is linked to cancer, then more cases of cancer should occur near EMF sources compared to areas distant from EMF sources. Thus, the hypothesis is that an association between EMF exposure and cancer occurs non-randomly, whereas cancers occurring in people not exposed to EMF are random. Unfortunately, clusters can occur even if the process that generates the data is random.
Compare Graph A and Graph B (Fig 3). One of the graphs resulted from a random process and the other was generated by a non-random process. Note that the claim can be rephrased about the probability that each grid has a point, eg, it’s like Heads/Tails of 16 tosses of a coin. We can see clusters of points in Graph B; Graph A lacks obvious clusters of points — there is a point in each of the 16 cells of the grid. Although both patterns could be random, the correct answer in this case is Graph B.
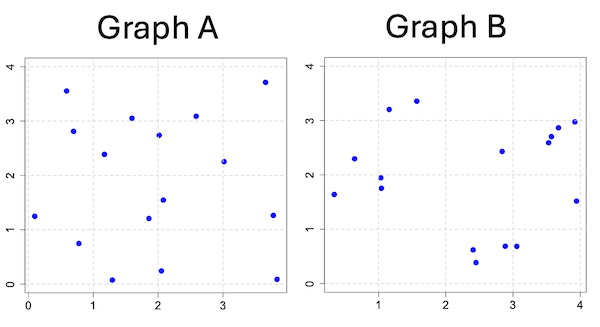
Figure 3. An example of clustering resulting from a random sampling process (Graph B). In contrast, Graph A was generated so that a point was located within each grid.
Hard to tell — and truth be told, random process could generate either one. To convince you, Figure 4 reveals the grouping that was done for Group A, in contrast with Group B which was drawn with the truly random process.
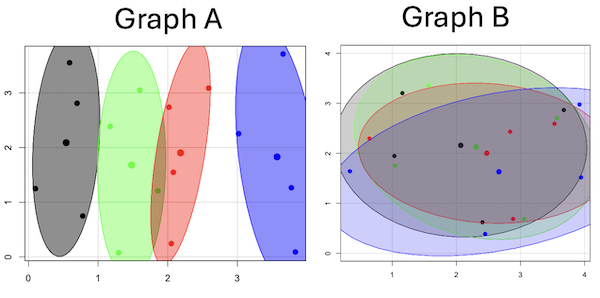
Figure 4. Same graphs as Figure 3, but with ellipses around the grouped data (hard to tell, but the centroids are the larger points).
Implications for sampling
The graphic below shows the transmission grid in the continental United States (Fig 5). How would one design a random sampling scheme overlaid against the obviously heterogeneous distribution of the grid itself? If a random sample was drawn, chances are good that no population would be near a grid in many of the western states, but in contrast, the likelihood would increase in the eastern portion of the United States where the population and therefore transmission grid is more densely placed.
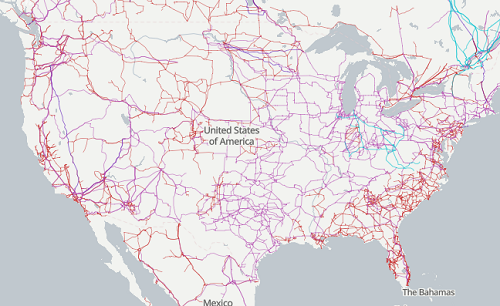
Figure 5. Map of electrical transmission grid for continental United States of America. Image source https://openinframap.org/#3/24.61/-101.16
For example, you want to test whether or not EMF affects human health, and your particular interest is in whether or not there exists a relationship between living close to high voltage towers or transfer stations and brain cancer. How does one design a study, keeping in mind the importance of randomization for our ability to generalize and assign causation? This is a part of epidemiology which strives to detect whether clusters of disease are related to some environmental source. It is an extremely difficult challenge. For the record, no clear link to EMF and cancer has been found, but reports do appear from time to time (eg, report on a cluster of breast cancer in men working in office adjacent to high EMF, Milham 2004).
Questions
1. Use the sample() with and without replacement on the object (see help with R below)
fruit <- c("apple", "banana", "grape", "kiwi", "pear", "pineapple", "tomato")a) set of 3
b) set of 4
2. Confirm the claim by calculating the probability of Graph A result vs Graph B result (see R script below).
Quiz Chapter 5.5
Importance of randomization in experimental design
R code!
Code you type is shown in red; responses or output from R are shown in blue. Recall that statements preceded by the hash # are comments and are not read by R (ie, no need for you to type them).
First, create some variables. Vectors aa and bb contain my two age sequences.
 aa = seq(21,50)
 bb = seq(21,50)
Second, append vector bb to the end of vector aa
 age = append(aa,bb)
 age           #submit the vector (variable) name to print the records for verification - looks good!
  [1] 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37
 [48] 38 39 40 41 42 43 44 45 46 47 48 49 50
Third, get the average age for the first group (the aa sequence) and for the second group (the bb sequence). Lots of ways to do this, I made a two subsets from the combined age variable; could have just as easily taken the mean of aa and the mean of bb (same thing!).
 A = age[1:30]
 mean(A)
 [1] 35.5
 B = age[31:60]
 mean(B)
 [1] 35.5
Fourth, start building a data frame, then sort it by age. Will be adding additional variables to this data frame
 ex.random = data.frame(age)
 AO.all = sort(ex.random$age)
 AO.age           #submit the vector (variable) name to print the records for verification - looks good!
  [1] 21 21 22 22 23 23 24 24 25 25 26 26 27 27 28 28 29 29 30 30 31 31 32 32 33 33 34 34 35 35 36 36 37 37 38 38 39 39 40 40 41 41 42 42 43 43 44
 [48] 44 45 45 46 46 47 47 48 48 49 49 50 50
Fifth, divide the variable again into two subsets of 30 and get the averages
 AO = AO.age[1:30]
 AO
  [1] 21 21 22 22 23 23 24 24 25 25 26 26 27 27 28 28 29 29 30 30 31 31 32 32 33 33 34 34 35 35
 mean(AO)
 [1] 28
 BO = AO.age[31:60]
 BO
  [1] 36 36 37 37 38 38 39 39 40 40 41 41 42 42 43 43 44 44 45 45 46 46 47 47 48 48 49 49 50 50
 mean(BO)
 [1] 43
Sixth, create an index variable, random order without replacement
rand.index = sample(1:60,60,replace=F)Add the new variable to our existing data frame, then print it to check that all is well
 ex.random$rand = rand.index
 ex.random
    age rand
 1   21   43
 2   22   15
 3   23   17
 4   24   35
 5   25   19
 6   26   18
 7   27   22
 8   28   31
 9   29   12
 10  30   44
 11  31   24
 12  32    5
 13  33    2
 14  34   50
 15  35   23
 16  36   20
 17  37   41
 18  38   56
 19  39   36
 20  40    8
 21  41   45
 22  42   38
 23  43   42
 24  44   46
 25  45   16
 26  46   21
 27  47   28
 28  48   10
 29  49   32
 30  50   54
 31  21   57
 32  22   51
 33  23   27
 34  24   40
 35  25   14
 36  26   48
 37  27   26
 38  28   58
 39  29    9
 40  30   11
 41  31    4
 42  32   52
 43  33   37
 44  34   53
 45  35    6
 46  36   34
 47  37   39
 48  38    7
 49  39    1
 50  40   47
 51  41   33
 52  42   60
 53  43   49
 54  44   30
 55  45   29
 56  46   55
 57  47   13
 58  48    3
 59  49   25
 60  50   59
Seventh, select for our first treatment group the first 30 subjects from the randomized index. There are again other ways to do this, but sorting on the index variable means that the subject order will be change too.
AR.age = ex.random[order(ex.random$rand),] #created a new data frame to distinguish it from the presorted version "ex.random"Print the new data frame to confirm that the sorting worked. It did. we can see that the rows have been sorted by ascending order based on the index variable.
 AR.age
    age rand
 49  39    1
 13  33    2
 58  48    3
 41  31    4
 12  32    5
 45  35    6
 48  38    7
 20  40    8
 39  29    9
 28  48   10
 40  30   11
 9   29   12
 57  47   13
 35  25   14
 2   22   15
 25  45   16
 3   23   17
 6   26   18
 5   25   19
 16  36   20
 26  46   21
 7   27   22
 15  35   23
 11  31   24
 59  49   25
 37  27   26
 33  23   27
 27  47   28
 55  45   29
 54  44   30
 8   28   31
 29  49   32
 51  41   33
 46  36   34
 4   24   35
 19  39   36
 43  33   37
 22  42   38
 47  37   39
 34  24   40
 17  37   41
 23  43   42
 1   21   43
 10  30   44
 21  41   45
 24  44   46
 50  40   47
 36  26   48
 53  43   49
 14  34   50
 32  22   51
 42  32   52
 44  34   53
 30  50   54
 56  46   55
 18  38   56
 31  21   57
 38  28   58
 60  50   59
 52  42   60
Eighth, create our new treatment groups, again of n = 30 each, then get the means ages for each group.
 AR = AR.age$age[1:30]
 mean(AR)
 [1] 35.16667
 AR2 = AR.all$all[31:60]
 mean(AR2)
 [1] 35.83333
Get the minimum and maximum values for the groups
 min(AR)
 [1] 22
 min(AR2)
 [1] 21
 max(AR)
 [1] 49
 max(AR2)
 [1] 50
Ninth, create a BMI variable drawn from a normal distribution with coefficient of variation equal to 20%. The first group with we will call cc
cc = rnorm(n=30,m=27.5, sd=5.5) #mean was 27.5 for this group with standard deviation of 5.5The second group called dd
dd = rnorm(n=30,m=37.5, sd=7.5) #mean was 37.5 for this group with standard deviation of 7.5Create a new variable called BMI by joining cc and dd
 BMI=append(cc,dd)
 BMI            #print out BMI to confirm. Looks good!
  [1] 27.87528 27.83250 31.88703 34.99041 24.06751 23.50952 22.57779 31.48394 31.04321 25.60258 25.41081 22.34619 34.62213 36.41348 41.17740
 [16] 20.56529 27.25238 21.85205 32.11690 32.37168 23.11314 33.29110 34.99106 38.22016 18.72105 26.22030 25.13412 27.50475 34.79361 32.81267
 [31] 47.57872 27.58428 40.17211 38.22195 26.91893 37.02784 53.72671 34.94727 30.35245 38.32571 40.52111 36.15627 30.36592 36.20397 47.63142
 [46] 40.30846 36.47643 50.86804 43.63741 37.84994 42.82665 41.71008 28.44976 24.57906 42.37762 38.38512 35.22879 31.34063 34.02996 27.28038
Add the BMI variable to our data frame.
 ex.random$BMI = BMI
 ex.random              #Print out the revised data frame. Looks good. We now have three variables: age, the index "rand," and now BMI
    age rand      BMI
 1   21   43 27.87528
 2   22   15 27.83250
 3   23   17 31.88703
 4   24   35 34.99041
 5   25   19 24.06751
 6   26   18 23.50952
 7   27   22 22.57779
 8   28   31 31.48394
 9   29   12 31.04321
 10  30   44 25.60258
 11  31   24 25.41081
 12  32    5 22.34619
 13  33    2 34.62213
 14  34   50 36.41348
 15  35   23 41.17740
 16  36   20 20.56529
 17  37   41 27.25238
 18  38   56 21.85205
 19  39   36 32.11690
 20  40    8 32.37168
 21  41   45 23.11314
 22  42   38 33.29110
 23  43   42 34.99106
 24  44   46 38.22016
 25  45   16 18.72105
 26  46   21 26.22030
 27  47   28 25.13412
 28  48   10 27.50475
 29  49   32 34.79361
 30  50   54 32.81267
 31  21   57 47.57872
 32  22   51 27.58428
 33  23   27 40.17211
 34  24   40 38.22195
 35  25   14 26.91893
 36  26   48 37.02784
 37  27   26 53.72671
 38  28   58 34.94727
 39  29    9 30.35245
 40  30   11 38.32571
 41  31    4 40.52111
 42  32   52 36.15627
 43  33   37 30.36592
 44  34   53 36.20397
 45  35    6 47.63142
 46  36   34 40.30846
 47  37   39 36.47643
 48  38    7 50.86804
 49  39    1 43.63741
 50  40   47 37.84994
 51  41   33 42.82665
 52  42   60 41.71008
 53  43   49 28.44976
 54  44   30 24.57906
 55  45   29 42.37762
 56  46   55 38.38512
 57  47   13 35.22879
 58  48    3 31.34063
 59  49   25 34.02996
 60  50   59 27.28038
Tenth, repeat our protocol from before: Set up two groups each with 30 subjects, calculate the means for the variables and then sort by the random index and get the new group means.
 AO = ex.random$BMI[1:30]
 mean(AO)
 [1] 28.99333
 BO = ex.random$BMI[31:60]
 mean(BO)
 [1] 37.36943
All we did was confirm that the unsorted groups had mean BMI of around 27.5 and 37.5 respectively. Now, proceed to sort by the random index variable. Go ahead and create a new data frame
 AR.age = ex.random[order(ex.random$rand),]
 AR.age                 #Print out the new data frame to confirm. Looks good.
    age rand      BMI
 49  39    1 43.63741
 13  33    2 34.62213
 58  48    3 31.34063
 41  31    4 40.52111
 12  32    5 22.34619
 45  35    6 47.63142
 48  38    7 50.86804
 20  40    8 32.37168
 39  29    9 30.35245
 28  48   10 27.50475
 40  30   11 38.32571
 9   29   12 31.04321
 57  47   13 35.22879
 35  25   14 26.91893
 2   22   15 27.83250
 25  45   16 18.72105
 3   23   17 31.88703
 6   26   18 23.50952
 5   25   19 24.06751
 16  36   20 20.56529
 26  46   21 26.22030
 7   27   22 22.57779
 15  35   23 41.17740
 11  31   24 25.41081
 59  49   25 34.02996
 37  27   26 53.72671
 33  23   27 40.17211
 27  47   28 25.13412
 55  45   29 42.37762
 54  44   30 24.57906
 8   28   31 31.48394
 29  49   32 34.79361
 51  41   33 42.82665
 46  36   34 40.30846
 4   24   35 34.99041
 19  39   36 32.11690
 43  33   37 30.36592
 22  42   38 33.29110
 47  37   39 36.47643
 34  24   40 38.22195
 17  37   41 27.25238
 23  43   42 34.99106
 1   21   43 27.87528
 10  30   44 25.60258
 21  41   45 23.11314
 24  44   46 38.22016
 50  40   47 37.84994
 36  26   48 37.02784
 53  43   49 28.44976
 14  34   50 36.41348
 32  22   51 27.58428
 42  32   52 36.15627
 44  34   53 36.20397
 30  50   54 32.81267
 56  46   55 38.38512
 18  38   56 21.85205
 31  21   57 47.57872
 38  28   58 34.94727
 60  50   59 27.28038
 52  42   60 41.71008
Get the means of the new groups
 AR = AR.age$BMI[1:30]
 mean(AR)
 [1] 32.49004
 min(AR)
 [1] 18.72105
 max(AR)
 [1] 53.72671
 AR2 = AR.all$BMI[31:60]
 mean(AR2)
 [1] 33.87273
 min(AR2)
 [1] 21.85205
 max(AR2)
 [1] 47.57872
That’s all of the work!
Data set
nonrandom
| X | Y |
| 0.779 | 0.747 |
| 0.098 | 1.248 |
| 0.697 | 2.811 |
| 0.59 | 3.553 |
| 1.295 | 0.075 |
| 1.858 | 1.207 |
| 1.172 | 2.388 |
| 1.597 | 3.051 |
| 2.051 | 0.242 |
| 2.081 | 1.546 |
| 2.016 | 2.738 |
| 2.587 | 3.088 |
| 3.833 | 0.088 |
| 3.776 | 1.264 |
| 3.017 | 2.254 |
| 3.657 | 3.712 |
random
| X1 | Y1 |
| 1.157 | 3.203 |
| 2.407 | 0.62 |
| 1.033 | 1.946 |
| 3.676 | 2.866 |
| 3.57 | 2.703 |
| 3.056 | 0.685 |
| 1.568 | 3.355 |
| 1.041 | 1.753 |
| 0.643 | 2.295 |
| 2.884 | 0.687 |
| 3.53 | 2.591 |
| 2.838 | 2.431 |
| 3.945 | 1.518 |
| 0.34 | 1.64 |
| 2.45 | 0.386 |
| 3.921 | 2.976 |
Chapter 5 contents
- The basics explained
- Experiments
- Experimental and Sampling units
- Replication, Bias, and Nuisance Variables
- Clinical trials
- Importance of randomization in experimental design
- Sampling from Populations
- References and suggested readings
4.6 – Adding a second Y axis
Introduction
Scatter plots are used to show association between two continuous variables. However, it is not uncommon to have a third variable for which association between the same X variable is expected. Thus, a common scatter plot includes a second Y axis. These graphs are a bit more involved to make regardless of which application used. The purpose of this short section is to provide a way to create a plot with two Y axes against a common X axis. Additional plotting options are also provided and explained.
The data set
The first draft of this post was written in September 4, 2019, peak time for hurricanes. Hurricane Dorian passed the Bahamas as a category 4 storm heading for Florida. For context I include a screenshot of imagery from NOAA; you can see Dorian along the Florida coastline as well as four additional storms lined up from the coast of Africa across the Atlantic Ocean (Fig 1).
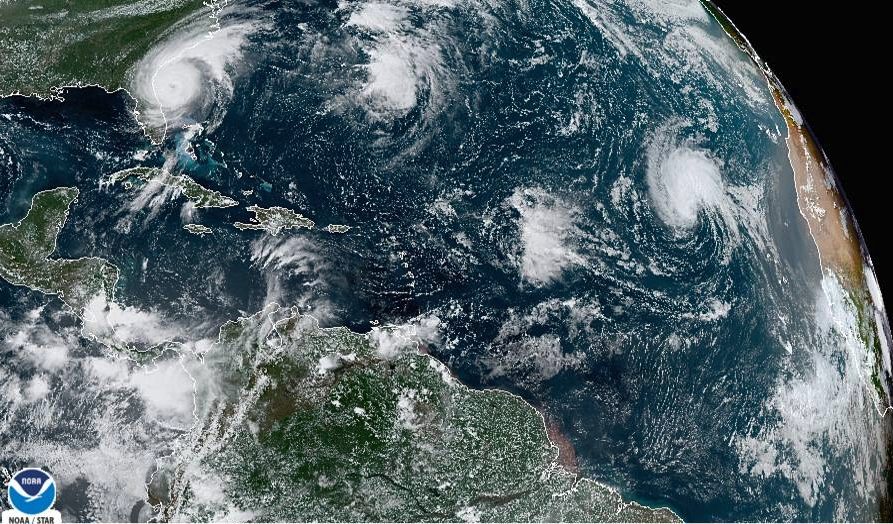
Figure 1. Screenshot from NOAA GOES-East – Sector view: Tropical Atlantic – GeoColor, 4 September 2019. Click image to view full sized image.
The data set here is the number of Atlantic Ocean Category 1, 2, 3, 4, or 5 storms since 1900, tabulated by decade. Storms are categorized by wind speed according to the Saffir-Simpson Hurricane Wind Scale, or SSHWS.
Note 1: Since September 2019 there have been 36 major hurricanes: 2019, October – December = 3; 2020 = 13; 2021 = 3; 2022 = 3; 2023 = 2; 2024 = 12.
Additional data, average levels of carbon dioxide (CO2), a greenhouse gas, measured at Mauna Loa and average global temperature index from NOAA were also acquired for the same period. (The temperature index is called anomaly data as it is the difference of temperature between the average temperatures between 1950 and 1980).
#Create the time data, 12 decades, with 2010 based on 8 years only -- up to 2018
decade <- seq(1900,2010, by = 10)
#Saffir-Simpson Hurricane Wind Scale; compiled from Wikipedia, checked against NOAA
cat01 <- c(2,0,1,3,0,9,4,11,18,11,27,46)
cat02 <- c(2,0,1,3,10,4,5,4,3,13,9,8)
cat03 <- c(7,2,3,1,4,10,9,5,4,12,11,7)
cat04 <- c(1,6,5,8,9,10,9,5,5,10,15,8)
cat05 <- c(0,0,2,6,0,2,4,3,3,2,9,4)
#land ocean anomaly temperature index, NOAA
tempIndex <- c(-0.317,-0.329,-0.241,-0.123,0.042,-0.048,-0.028,0.034,0.247,0.387,0.591,0.791)
#mauna kea CO2, mean by decade, record starts 1958
co2 <- c(NA,NA,NA,NA,NA,316.0,320.3,330.9,345.5,360.5,378.6,399.0)
Note 2: Corresponding temperature anomalies and CO2 data: cc
Combine all of the variables into a single data frame.
storms <- data.frame(decade,tempIndex,cat01,cat02,cat03,cat04,cat05,co2)
head(storms)
Output from R should look like
  decade tempIndex cat01 cat02 cat03 cat04 cat05 co2
1   1900    -0.317     2     2     7     1     0  NA
2   1910    -0.329     0     0     2     6     0  NA
3   1920    -0.241     1     1     3     5     2  NA
4   1930    -0.123     3     3     1     8     6  NA
5   1940     0.042     0    10     4     9     0  NA
6   1950    -0.048     9     4    10    10     2 316
Create a new variable with all categories of storms summed by decade.
#Sum all of the storms
allHur <- cat01+cat02+cat03+cat04+cat05
#Add new variable to the data frame
storms$allHur <- allHur
#Attach the data frame so you don't have to keep referring to the data frame when you call variables.
attach(storms)
Now, create a simple scatter plot, number of hurricanes by decade (Fig 2).
plot(decade,allHur,pch=16)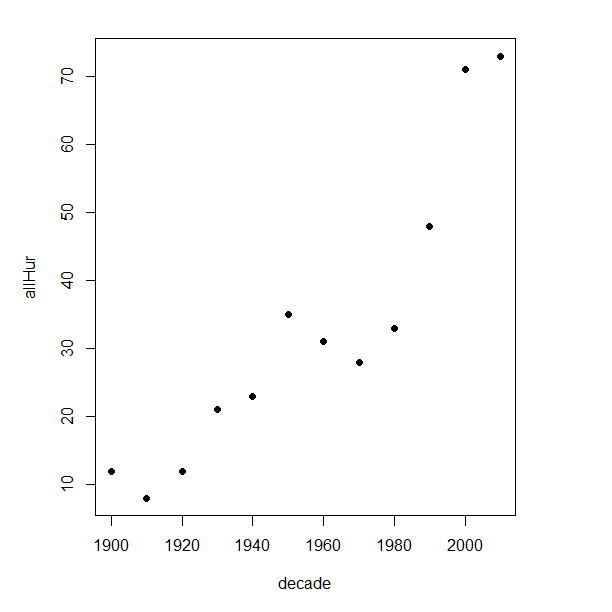
Figure 2. Plot of hurricanes from 1900 to present by decade.
Note 3: Best data come from the satellites, which means use of data since the 1980s would be more appropriate. IPCC reports climate change is projected to increase the intensity of hurricanes, with higher wind speeds and more rainfall. While there is not a consensus on the frequency of storms, the proportion of the most intense storms (Category 4 and 5) is expected to increase, and rapid intensification is also likely to become more common (Masson-Delmotte, et al (2021), IPCC Sixth Assessment Report (AR6) – The Physical Science Basis).
A note on data management
This note is not needed for the plots. However, it’s as good a place as any to comment about how to work with your data in R. For the hurricane data, I set the data frame storms as an unstacked (wide) worksheet. The code that follows shows how to use the reshape2 package, part of the tidyverse set of packages for data manipulation, to convert the data frame from unstacked (wide) to stacked (long).
#code modified from examples presented by Thomas Eisfeld
library(reshape2)
library(dplyr)
tryMe <- melt(storms, id.vars=c("decade", "tempIndex", "co2"), variable.name = "SSHWS", value.name = "hurricanes")
head(tryMe)
You can also take a stacked (long) worksheet and convert it to unstacked (wide) with dcast().
tryAgain <- dcast(tryMe, decade + tempIndex + co2 ~ SSHWS)Make the plots
At last, here’s the code for adding a second Y axis. Code modified from https://www.r-bloggers.com/r-single-plot-with-two-different-y-axes/. The work flow begins by setting parameters of the plotting window, creating the first plot, followed up by adding the second plot (par=TRUE), setting graphing elements, then adding labels and a legend.
First plot example: Total number of hurricanes by decades, with Temperature Index by decades. Number of hurricanes represented on first (left) axis and Temperature Index represented on second (right) axis (Fig 3).
par(mar = c(5,5,2,5))
#Create the first plot
plot(tryAgain$decade, tryAgain$allHur, pch=16, cex=1.5, col="black", xlab="Decades", ylab="Hurricanes", main="Atlantic Hurricanes by Decade")
the syntax par(mar = c(bottom, left, top, right))
#Add the second plot
par(new=T)
plot(tryAgain$decade, tryAgain$tempIndex, type="l", lty="dashed", lwd=2, col="red3", axes=F, xlab=NA, ylab=NA)
axis(side=4)
mtext(side=4,line=3,"Temperature Index")

#Add a legend
legend("topleft",legend=c("Hurricanes", "Temperature Index"),lty=c(0,2), pch=c(16,NA), col=c("black", "red3"))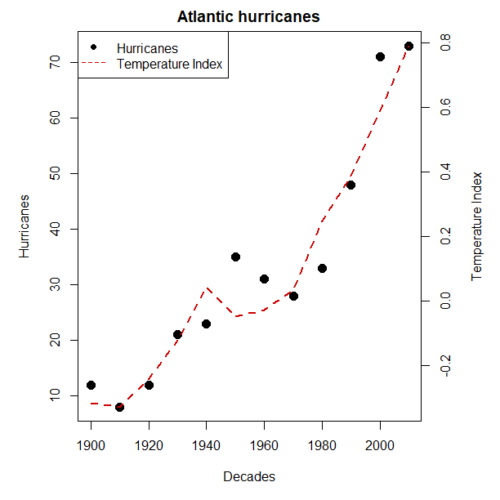
Figure 3. Total number of hurricanes by decades, with Temperature Index by decades. Number of hurricanes represented on first (left) axis and Temperature Index represented on second (right) axis.
Next plot example: Total number of hurricanes by decades, with Atmospheric CO2 measured at Mauna Loa by decades. Number of hurricanes represented on first (left) axis and Atmospheric CO2 represented on second (right) axis (Fig 4).
par(mar = c(5,5,2,5))
plot(tryAgain$decade, tryAgain$allHur, pch=16, cex=1.5, col="black", xlab="Decades", ylab="Hurricanes", main="Atlantic Hurricanes by Decade")
Create space for the second plot in the same frame (use T or TRUE, both work).
par(new=T)Code for the second plot. Note that axes=F (“F” or “FALSE” works) is used to suppress printing axes — Recall that lines were already created by the first plot; if you do not add this, then additional lines are added to the plot.”NA” is used to suppress adding labels; if you do not add this code, then labels will be printed over the existing labels created for the first plot. The code axis=4 sets the right-hand Y axis to active. The next code, mtext() is used to place the axis label for the second Y axis.
plot(tryAgain$decade, tryAgain$co2, type="l", lty="dashed", lwd=2, col="red3", axes=F, xlab=NA, ylab=NA)
axis(side=4)
mtext(side=4,line=3,"Mean CO2, ppm")
Add the legend.
legend("topleft",legend=c("Hurricanes", "CO2"),lty=c(0,2), pch=c(16,NA), col=c("black", "blue"))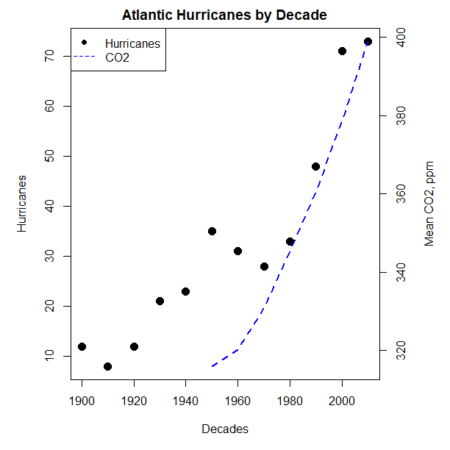
Figure 4. Total number of hurricanes by decades, with Atmospheric CO2 measured at Mauna Kea by decades. Number of hurricanes represented on first (left) axis and Atmospheric CO2 represented on second (right) axis.
Go ahead and try these plots. Change the settings (e.g., lty, pch, cex, col), and note how the graphs look.
Bubble (chart) plot
From the basic scatter plot a variety of variants have been developed to convey additional information about ratio scale variables. The bubble chart is one common example and can be used as an alternative to adding a second Y-axis in some cases. A bubble plot uses the area of a bubble to represent a third variable, while a second y-axis is used to display a second set of data with its own scale on the same chart.
In brief, a third variable is added, mapped to circle size. Spreadsheet apps also include options to make bubble charts and the wonderful plot.ly library provides a vehicle to produce sophisticated graphs including bubble charts online or as a package in R — and it works well with the ggplot2 package. A nice bubble chart introduction is available at Atlassian.
Examples of bubble charts with R code are provided in Ch16.3. That said, what’s one more? Here’s example R code:
ggplot(storms, aes(x = decade, y = tempIndex, size = total_storms)) +
  geom_point(alpha = 0.7, color = "lightgreen") + # Added color = "lightgreen"
  scale_size_continuous(range = c(3, 15)) +
  labs(title = "Temperature Index vs. Decade with Total Storms",
       x = "Decade",
       y = "Land Ocean Anomaly Temperature Index",
       size = "Total Storms") +
  theme_classic()
and the plot, Figure 4.
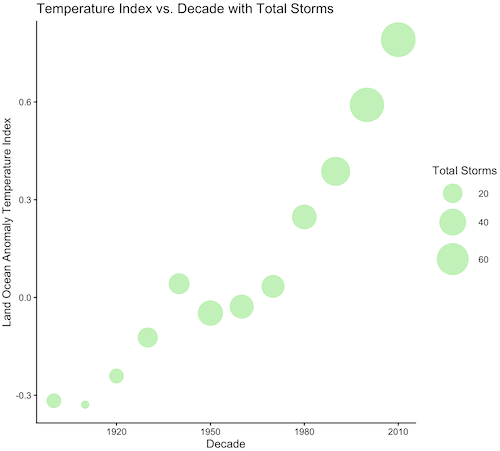
Figure 4. Bubble plot of association between total hurricanes and Land-Ocean Temperature Anomalies by Decade.
If you are interested in trying yourself, a bubble chart yourself, CO2 datas with the hurricane data set is a good candidate for a bubble plot.
Questions
-
Using the
plot()command, make the following graphs- One scatter plot for each category of storm by decade
- Explore the kinds of graph elements available by changing
pchvalues. Create your own - Change point size by changing valued for
cex
- Create a new plot with Decade on X axis, Temperature Index on first Y axis, and CO2 on the second Y axis.
- Include a legend for the plot.
- What is a Q-Q plot used for in statistics?
- Looking at the plot in Figure 5, explain why the confidence lines get further and further away from the straight line.
- What are some advantages and disadvantages of heat map for communicating data.
- What color pallet is considered “color-friendly” for accessible visualization?
- Create a table with three columns.
- In column 1, list the name for each graph type discussed in Chapter 5.
- In column 2, state the kind of data appropriate for each graph.
- In column 3, enter the name of a function in the base R package you can use to make the graph
- In column 4, enter the name of a function from the ggplot2 package you can use to make the graph
Quiz Chapter 4.6
Adding a second Y axis
Chapter 4 contents
4.5 – Scatter plots
Introduction
Scatter plots, also called scatter diagrams, scatterplots, or XY plots, display associations between two quantitative, ratio-scaled variables. Each point in the graph is identified by two values: its X value and its Y value. The horizontal axis is used to display the dispersion of the X variable, while the vertical axis displays the dispersion of the Y variable.
The graphs we just looked at with Tufte’s examples Anscombe’s quartet data were scatter plots (Chapter 4 – How to report statistics).
Here’s another example of a scatter plot, data from Francis Galton, data contained in the R package HistData.
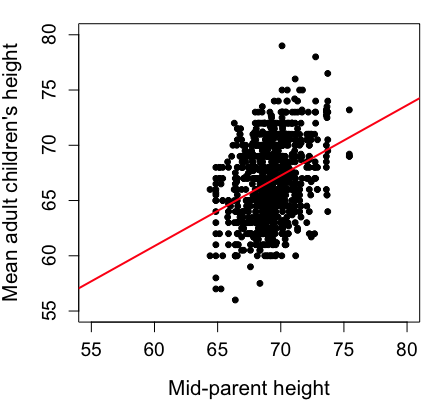
Figure 1. Scatterplot of mid-parent (vertical axis) and their adult children’s (horizontal axis) height, in inches. data from Galton’s 1885 paper, “Regression towards mediocrity in hereditary stature.” The red line is the linear regression fitted line, or “trend” line, which is interpreted in this case as the heritability of height.
Note 1. Sorry about that title — being rather short of stature myself, not sure I’m keen to learn further what Galton was implying with that “mediocrity” quip.
The commands I used to make the plot in Figure 1 were
library(HistData)
data(GaltonFamilies, package="HistData")
attach(GaltonFamilies)

plot(childHeight~midparentHeight, xlab="Mid-parent height", ylab="Mean adult children's height", xlim=c(55, 80), ylim=c(55,80), cex=0.8, cex.axis=1.2, cex.lab=1.3, pch=c(19), data=GaltonFamilies)
abline(lm(childHeight~midparentHeight), col="red", lwd=2)
I forced the plot function to use the same range of values, set by providing values for xlim and ylim; the default values of the plot command picks a range of data that fits each variable independently. Thus, the default X axis values ranged from 64 to 76 and the Y variable values ranged from 55 to 80. This has the effect of shifting the data, reducing the amount of white space, which a naïve reading of Tufte would suggest is a good idea, but at the expense of allowing the reader to see what would be the main point of the graph: that the children are, on average, shorter than the parents, mean height = 67 vs. 69 inches, respectively. Therefore, Galton’s title begins with the word “regression,” as in the definition of regression as a “return to a former … state” (Oxford Dictionary).
For completeness, cex sets the size of the points (default = 1), and therefore cex.axis and cex.lab apply size changes to the axes and labels, respectively; pch refers to the graph elements or plotting characters, further discussed below (see Fig 8); lm() is a call to the linear model function; col refers to color.
Figure 2 shows the same plot, but without attention to the axis scales, and, more in keeping with Tufte’s principle of maximize data, minimize white space.
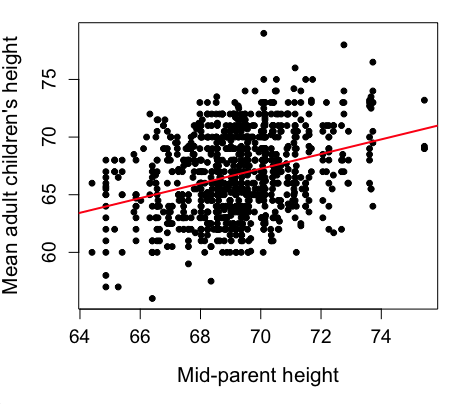
Figure 2. Same plot as Figure 1, but with default settings for axis scales.
Take a moment to compare the graphs in Figure 1 and 2. Setting the scales equal allows you to see that the mid-parent heights were less variable, between 65 and 75 inches, than the mean children height, which ranged from 55 to 80 inches.
And another example, Figure 3. This plot is from the ggplot2() function and was generated from within R Commander’s KMggplot2 plug-in.
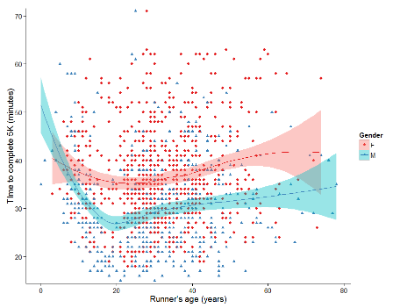
Figure 3. Finishing times in minutes of 1278 runners by age and gender at the 2013 Jamba Juice Banana 5K in Honolulu, Hawaiʻi. Loess smoothing functions by groups of female (red) and male (blue) runners are plotted along with 95% confidence intervals.
Figure 3 is a busy plot. Because there were so many data points, it is challenging to view any discernible pattern, unlike Figure 1 and 2 plots, which featured less data. Use of the loess smoothing function, a transformation of the data to reduce data “noise” to reveal a continuous function, helps reveal patterns in the data:
- across most ages, men completed 5K faster than did females and
- there was an inverse, nonlinear association between runner’s age and time to complete the 5K race.
Take a look at the X-axis. Some runners ages were reported as less than 5 years old (trace the points down to the axis to confirm), and yet many of these youngsters were completing the 5K race in less than 30 minutes. That’s 6-minute mile pace! What might be some explanations for how pre-schoolers could be running so fast?
Design criteria
As in all plotting, maximize information to background. Keep white space minimal and avoid distorting relationships. Some things to consider:
- keep axes same length
- do not connect the dots UNLESS you have a continuous function
- do not draw a trend line UNLESS you are implying causation
Scatter plots in R
We have many options in R to generate scatter plots. We have already demonstrated use of plot() to make scatter plots. Here we introduce how to generate the plot in R Commander.
Rcmdr: Graphs → Scatterplot…
Rcmdr uses the scatterplot function from the car package. In recent versions of R Commander the available options for the scatterplot command are divided into two menu tabs, Data and Options, shown in Figure 4 and Figure 5.
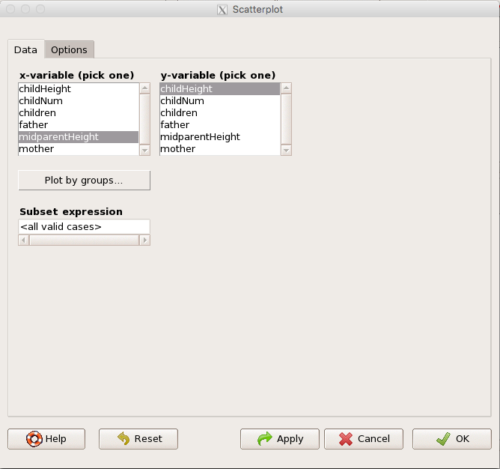
Figure 4. First menu popup in R Commander Scatterplot command, Rcmdr ver. 2.2-3.
Select X and Y variables, choose Plot by groups if multiple grounds are included, eg, male, female, then click Options tab to complete.
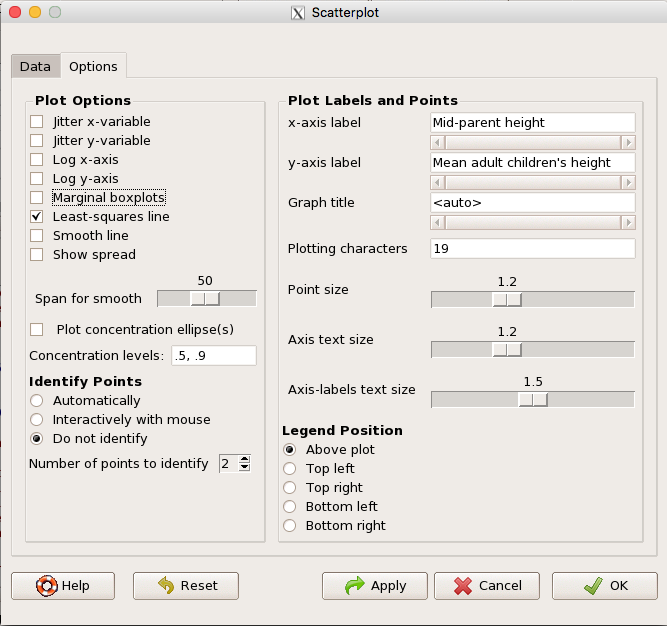
Figure 5. Second menu popup in R Commander scatterplot command., Rcmdr ver. 2.2-3
Set graph options including axes labels and size of the points.
Note 2. Lots of boxes to check and uncheck. Start by unchecking all of the Options and do update the axes labels (see red arrow in image). You can also manipulate the plot “points,” which R refers to as plotting characters (abbreviated pch in plotting commands). The “Plotting characters” box is shown as <auto>, which is an open circle. You can change this to one of 26 different characters by typing in a number between 0 and 25. The default used in Rcmdr scatterplot is “1” for open circle. I typically use “19” for a solid circle.
Here is another example using the default settings in scatterplot() function in the car package, now the default scatter plot command via R Commander (Fig. 4), along with the same graph, but modified to improve the look and usefulness of the graph (Fig. 6). The data set was Puromycin in the package datasets.
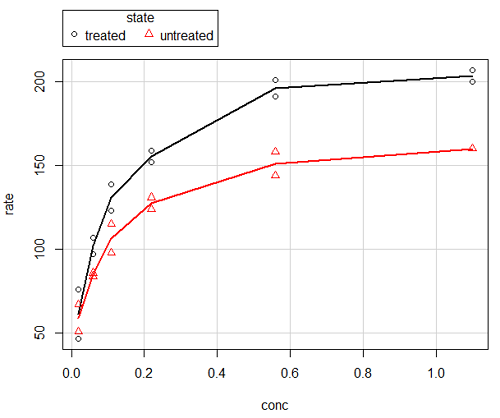
Figure 6. Default scatterplot, package car, from R Commander, version 2.2-4.
Grid lines in graphs should be avoided unless you intend to draw attention to values of particular data points. I prefer to position the figure legend within the frame of the graph, eg, the open are at the bottom right of the graph. Modified graph shown in Figure 7.
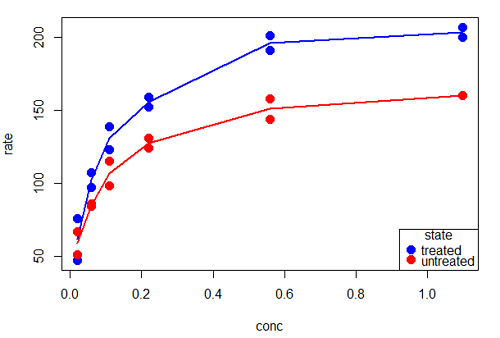
Figure 7. Modified scatterplot, same data from Figure 6
R commands used to make the scatter plot in Figure 7 were
scatterplot(rate~conc|state, col=c("blue", "red"), cex=1.5, pch=c(19,19),
bty="n", reg=FALSE, grid=FALSE, legend.coords="bottomright")
A comment about graph elements in R
In some ways R is too rich in options for making graphs. There are the plot functions in the base package, there’s lattice and ggplot2 which provide many options for graphics, and more. The advice is to start slowly, for example taking advantage of the Figure 8 displays R’s plotting characters and the number you would invoke to retrieve that plotting character.
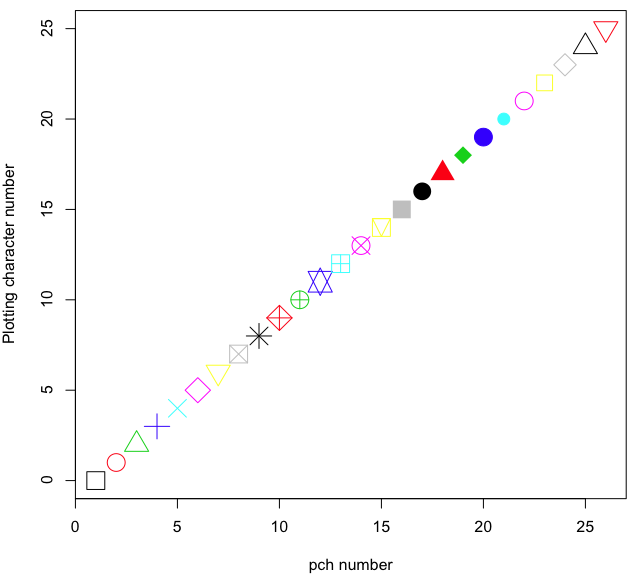
Figure 8. R plotting characters pch = 1 – 25 along with examples of color.
Note 3. To see available colors at the R prompt type
colors()
which returns 667 different colors by name, from
[1] "white" "aliceblue" "antiquewhite"
to
[655] "yellow3" "yellow4" "yellowgreen" There’s a lot more to R plotting. For example, you are not limited to just 25 possible characters. R can print any of the ASCII characters 32:127 or from the extended ASCII code 128:255. See Wikipedia to see the listing of ASCII characters.
In addition to pch, you can change the size of the plotting character with cex, color of the character with col for lines or outlines, and bg to change background color. lwd is used to set the character’s border thickness.
Here’s the R code used to generate the graph in Figure 8. Remember, any line beginning with # is a comment line, not an R command.
#create a vector with 26 numbers, from 0 to 25
stuff <-c(0:25)
plot(stuff, pch=c(32:58), cex = 2.5, col = c(1:26), 'xlab' = "pch number", 'ylab' = "Plotting character number")
Is it “scatter plot” or “scatterplot”?
Spelling matters, of course, and yet there are many words for which the correct spelling seems to be like “beauty,” it is “in the eye of the beholder” (Molly Bawn, 1878, by Margaret Hungerford). Scatter plot is one of these — is it one word or two, or is it something else entirely?
Scatter plot is one of these terms: you’ll find it spelled as “scatterplot” or as “scatter plot,” in the dictionary (eg, Oxford English dictionary), with no guidance to choose between them. And I’m not just talking about the differences between British and American English spelling traditions.
Note 4. The spell checkers in Microsoft Office and Google Docs do not flag “scatterplot” as incorrect, but the spell checker in LibreOffice Writer does (per obs).
Thus, in these situations as an author, you can turn to which of the spellings is in common use. I first looked at some of the statistics books on my shelves. I selected 14 (bio)statistics textbooks and checked the index and if present, chapters on graphics for term usage.
Table 1. Frequency of use of different terms for scatter plot in 14 (bio)statistics books currently on Mike’s shelves.
| spelling | number of statistical texts | frequency |
|---|---|---|
| scatter diagram | 2 | 0.144 |
| scatter plot | 5 | 0.357 |
| scattergram | 1 | 0.071 |
| scatterplot | 5 | 0.357 |
| XY plot | 0 | 0.071 |
Not much help, basically, it is a tie between “scatter plot” and “scatterplot.”
Next, I searched six journals for the interval 1990 – 2016 for use of these terms. Results presented in Table 6 along with journal impact factor for 2014 and number of issues (Table 2).
Table 2. Impact factor and number of issues 1990 – 2016 for six science journals.
| Journal | Impact factor | Issues |
|---|---|---|
| BMJ | 17.445 | 1374 |
| Ecology | 5.175 | 271 |
| J. Exp. Biol | 2.897 | 540 |
| Nature | 41.456 | 1454 |
| NEJM | 55.873 | 1377 |
| Science | 33.611 | 1347 |
My methods? I used the journal’s online search functions for the various usage for scatter plot and the results are shown in Figure 9.
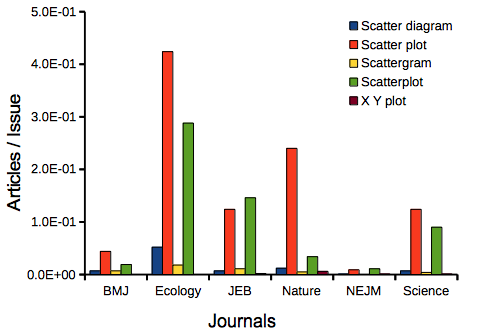
Figure 9. Usage of terms for X Y plots in research articles normalized to number of issues in six journals between 1990 and 2016.
The journals have different numbers of articles; I partially corrected for this by calculating the ratio number of articles with one of the terms divided by the number of issues for the interval 1990 – 2016. It would have been better to count all of the articles, but even I found that to be an excessive effort given the point I’m trying to make here.
Not much help there, although we can see a trend favoring “scatter plot” over any of the other options.
And finally, to completely work over the issue I present results from use of Google’s Ngram Viewer. Ngram Viewer allows you to search words in all of the texts that Google’s folks have scanned into digital form. I searched on the terms in texts between 1950 and 2015, and results are displayed in Figure 10 and Figure 11.
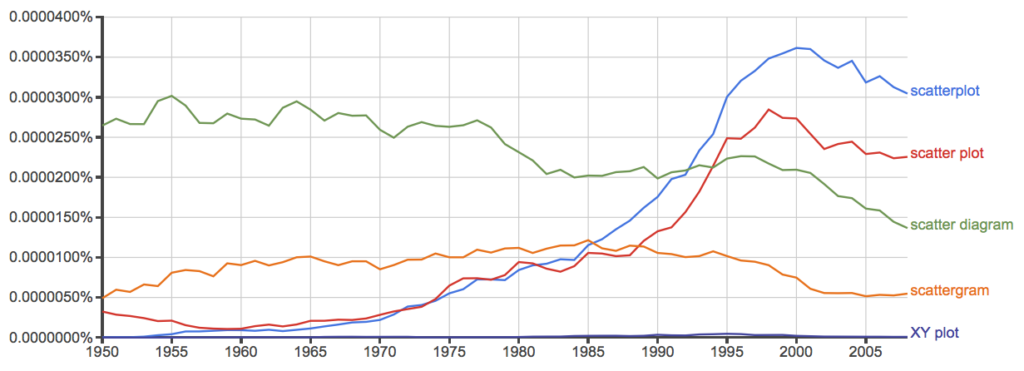
Figure 10. Results from Ngram Viewer for American English, “scatterplot” (blue), “scatter plot” (red), “scatter diagram” (green), “scattergram” (orange), and “XY plot” (purple).
And the same plot, but this time for British sources
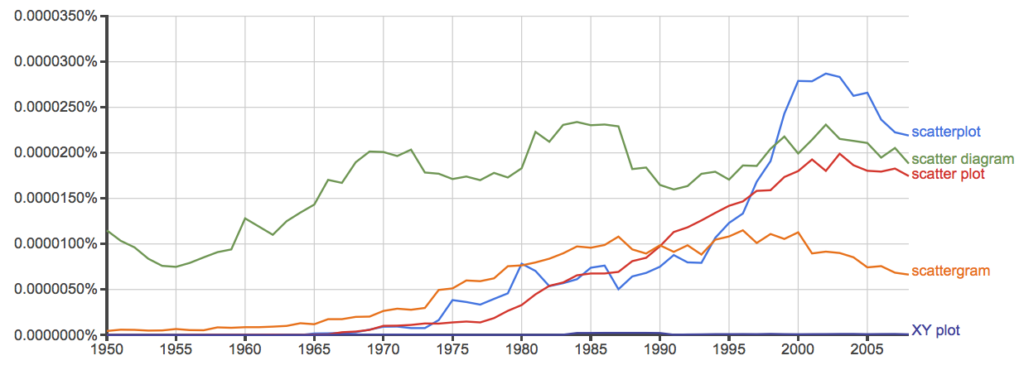
Figure 11. Results from Ngram Viewer for British English. See Figure 10 for key.
Conclusion? It looks like “scatterplot” (blue line) is the preferred usage, but it is close. Except for “scattergram” and “XY plot,” which, apparently, are rarely used. After all of this, it looks like you’re free to make your choice between “scatterplot” or “scatter plot.” I will continue to use “scatter plot.”
Bland-Altman plot
Also known as Tukey mean-difference plot, the Bland-Altman plot is used to describe agreement between two ratio scale variables (Bland and Altman 1986, Giavarina 2015), for example agreement between two different methods used to measure the same samples.
Note 6. Agreement — aka concordance or reproducibility — in the statistical sense is consistent with our everyday conception — consistency among sets of observations on the same object, sample, or unit. We introduce and develop additional agreement statistics in Chapter 9.2 and Chapter 12.3. Additional note for my students — note that I didn’t define agreement by including the term “agree”, thereby avoiding a circular definition (for an amusing clarification on the phrase, see Logically Fallacious). It’s a common short-fall I’ve seen thus far in AI-tools.
Consider use of imageJ by two different observers to record number of pixels of a unit measure (1 cm) on a series of digital images — there’s subjectivity in drawing the lines (where to start, where to end) — do they agree? Data set below. blandr package, blandr.draw function.
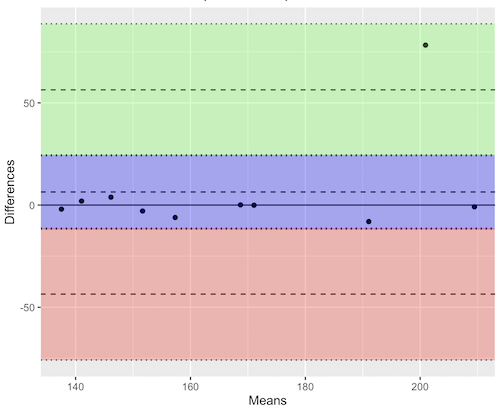
Figure 12. Bland-Altman plot of 1 cm unit measure in pixel number by imageJ from digital images by two independent observers. Purple central region is 95% CI. Lower and upper dashed horizontal lines represent bounds of “acceptable” agreement.
blandr.draw(Obs1, Obs2)
The plot makes it easy to identify questionable points, for example, the one point in upper right quadrant looks suspect.
Visualizing large data sets
Since the early 2000s, size of data sets in biology have increased dramatically, leaving many statistical graphics solutions ill-equipped to tell stories. The data scientists involved with the genomics and health care communities have introduced a number of useful visualizations. We introduce just two, the volcano plot (Fig 13) and the Manhattan-style plot (Fig 14).
Volcano plot
The volcano plot (Fig 13) is a common way to show events that differ between two groups of subjects (eg, p-values), and is common often provides to help visualize gene expression studies of an exposed group vs a control group (eg, fold changes). For the volcano plot, fold changes are reflected on horizontal axis, indicating how much the gene expression level has increased or decreased. The vertical axis typically represents the negative logarithm of the p-value (-logP), which indicates the statistical significance of the change.
Below is R code — with assistance from Gemini AI (Fall 2026) — for a set of five replicate simulated gene expression fold change data sets on stress test (NaCl, H2O2) on yeast grown on YPDA plates. Gene expression profiles were simulated for a set of 100 genes (oxidative pathway, DNA repair pathway); as noted, such studies typically include many more genes.
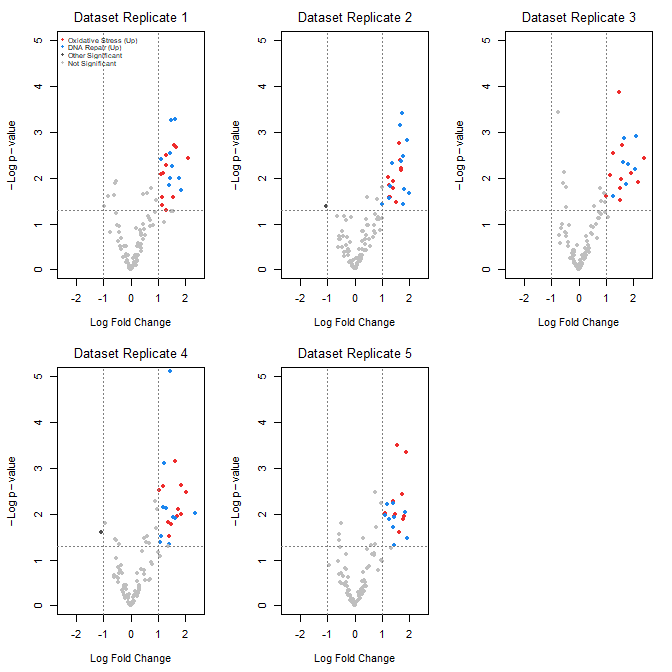
Figure 13. Volcano plot, gene expression fold change on simulated stress test (NaCl, H2O2) yeast data sets, 100 genes (oxidative pathway, DNA repair pathway).
Inspecting the plots (Fig 13), we see a symmetric distribution: The overall distribution of genes is cleanly centered around a Log2 Fold Change (LFC) of zero. This mirrors a realistic transcriptomic profile where the vast majority of the background genome (shown in grey) remains stable, displaying only technical and biological noise. There is a distinct, asymmetrical shift toward positive fold changes among specific gene pathways (targeted activation). Genes belonging to the Oxidative Stress pathway (red) and DNA Repair pathway (blue) consistently surpass both the statistical threshold (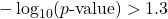 ) and the biological threshold (
 ). Additionally, we see evidence of synergistic effects: The simultaneous application of both stressors (“Both”) drives these pathways to their highest expression levels, pushing them into the top-right quadrant of the plots as highly significant, upregulated features.
R code — with assistance from Gemini AI (Fall 2026) — for yeast gene expression and volcano plots; graphs by base package only.
# ==============================================================================
# 1. SIMULATE 5 REASONABLE DATASETS WITH BIOLOGICAL & TECHNICAL NOISE
# ==============================================================================
set.seed(123) # New seed for realistic distribution

n_genes <- 100
n_datasets <- 5
groups <- c("Control", "Salt", "H2O2", "Both")
n_groups <- length(groups)

# Real-world experiment: each dataset has 3 biological replicates per group
n_reps_per_group <- 3

# Define gene pathways (15 oxidative stress, 15 DNA repair, 70 background/unchanged)
gene_ids <- paste0("Gene_", 1:n_genes)
pathways <- c(rep("Oxidative_Stress", 15), rep("DNA_Repair", 15), rep("Background", 70))

# Initialize a list to hold the 5 realistic datasets
datasets <- list()

for (d in 1:n_datasets) {

# 1. Establish a realistic base expression distribution across 100 genes
# Real data has high-expressing and low-expressing genes
base_expression <- rnorm(n_genes, mean = 7, sd = 2)

# Create a blank sample matrix: 100 genes x 12 samples (4 groups x 3 replicates)
sample_names <- paste0(rep(groups, each = n_reps_per_group), "_R", 1:n_reps_per_group)
expr_matrix <- matrix(0, nrow = n_genes, ncol = length(sample_names))
rownames(expr_matrix) <- gene_ids
colnames(expr_matrix) <- sample_names

# 2. Add realistic baseline biological variation to every sample
for (col_idx in 1:ncol(expr_matrix)) {
expr_matrix[, col_idx] <- base_expression + rnorm(n_genes, mean = 0, sd = 0.4)
}

# 3. Inject subtle, realistic treatment effects (not over-exaggerated)
for (i in 1:n_genes) {
# Every gene gets a tiny bit of random directional drift across groups (real-world noise)
drift <- rnorm(n_groups, mean = 0, sd = 0.15)

if (pathways[i] == "Oxidative_Stress") {
# Subtle upregulation in H2O2 and Both (mean fold change ~ 1.0 to 1.3)
drift[3] <- drift[3] + rnorm(1, mean = 1.1, sd = 0.2) # H2O2
drift[4] <- drift[4] + rnorm(1, mean = 1.3, sd = 0.2) # Both
} else if (pathways[i] == "DNA_Repair") {
# Subtle upregulation in Salt and Both (mean fold change ~ 0.8 to 1.2)
drift[2] <- drift[2] + rnorm(1, mean = 0.9, sd = 0.2) # Salt
drift[4] <- drift[4] + rnorm(1, mean = 1.2, sd = 0.2) # Both
}

# Apply the group drifts to the respective sample columns
for (g_idx in 1:n_groups) {
start_col <- (g_idx - 1) * n_reps_per_group + 1
end_col <- g_idx * n_reps_per_group
expr_matrix[i, start_col:end_col] <- expr_matrix[i, start_col:end_col] + drift[g_idx]
}
}

datasets[[d]] <- expr_matrix
}

# ==============================================================================
# 2. STATISTICAL ANALYSIS (Calculated directly from replicates)
# ==============================================================================
# We will compare the double stressor 'Both' vs 'Control' using real t-tests.
all_lfc <- matrix(0, nrow = n_genes, ncol = n_datasets)
all_pvals <- matrix(0, nrow = n_genes, ncol = n_datasets)
rownames(all_lfc) <- rownames(all_pvals) <- gene_ids

for (d in 1:n_datasets) {
mat <- datasets[[d]]

# Identify the columns for each group
control_cols <- grep("^Control_", colnames(mat))
both_cols <- grep("^Both_", colnames(mat))

for (i in 1:n_genes) {
control_vals <- mat[i, control_cols]
both_vals <- mat[i, both_cols]

# Real Log2 Fold Change (Difference of means since data is on log scale)
all_lfc[i, d] <- mean(both_vals) - mean(control_vals)

# Real Student's t-test
ttest_res <- t.test(both_vals, control_vals, var.equal = TRUE)
all_pvals[i, d] <- ttest_res$p.value
}
}

# ==============================================================================
# 3. GENERATE REALISTIC VOLCANO PLOTS
# ==============================================================================
par(mfrow = c(2, 3), mar = c(4.5, 4.5, 2.5, 1.5))

lfc_threshold <- 1.0
p_threshold <- 0.05

for (d in 1:n_datasets) {
lfc <- all_lfc[, d]
neg_log10_p <- -log10(all_pvals[, d])

col_vector <- rep("grey75", n_genes)

is_sig_up <- (lfc >= lfc_threshold) & (all_pvals[, d] <= p_threshold)
is_sig_down <- (lfc <= -lfc_threshold) & (all_pvals[, d] <= p_threshold)

col_vector[is_sig_up & pathways == "Oxidative_Stress"] <- "firebrick2"
col_vector[is_sig_up & pathways == "DNA_Repair"] <- "dodgerblue2"
col_vector[(is_sig_up | is_sig_down) & col_vector == "grey75"] <- "grey30"

plot(lfc, neg_log10_p,
col = col_vector,
pch = 19,
cex = 0.9,
xlab = expression(Log ~ Fold ~ Change),
ylab = expression(-Log ~ p - value),
main = paste("Dataset Replicate", d),
xlim = c(-2.5, 2.5),
ylim = c(0, 5),
font.main = 1)

abline(v = c(-lfc_threshold, lfc_threshold), col = "grey50", lty = 3)
abline(h = -log10(p_threshold), col = "grey50", lty = 3)

# Set the legend.
if (d == 1) {
legend("topleft",
legend = c("Oxidative Stress (Up)", "DNA Repair (Up)", "Other Significant", "Not Significant"),
col = c("firebrick2", "dodgerblue2", "grey30", "grey75"),
pch = 19,
cex = 0.6,
box.lty = 0,
bg = "transparent")
}
}

# Reset layout parameters
par(mfrow = c(1, 1))
End R code.
About the simulation
- Symmetric, Balanced Center: Most of the 100 genes (the 70 background genes) are strictly driven by standard biological and technical noise. This distributes them evenly around 0 on the X-axis, meaning you will naturally see negative fold changes alongside positive ones.
- Realistic Effect Scales: True upregulations are dialed down to max out around
 to

 Fold Changes, mirroring standard biological responses on YPDA plates.
- True T-Tests: Instead of faking p-values, each simulated dataset now contains 3 biological samples per group. The p-values are calculated dynamically using t.test(), generating a mathematically sound distribution pattern on the Y-axis.
Manhattan plot
A Manhattan plot (Fig 14) is a type of scatter plot used to display the statistical significance of large sets of data points simultaneously. Some feature of the experiment, for example location in the genome or sequential test identifiers, is displayed on the horizontal axis. Like the volcano plot (Fig 13), the vertical axis displays the statistical significance (eg, -log10(p-value)).
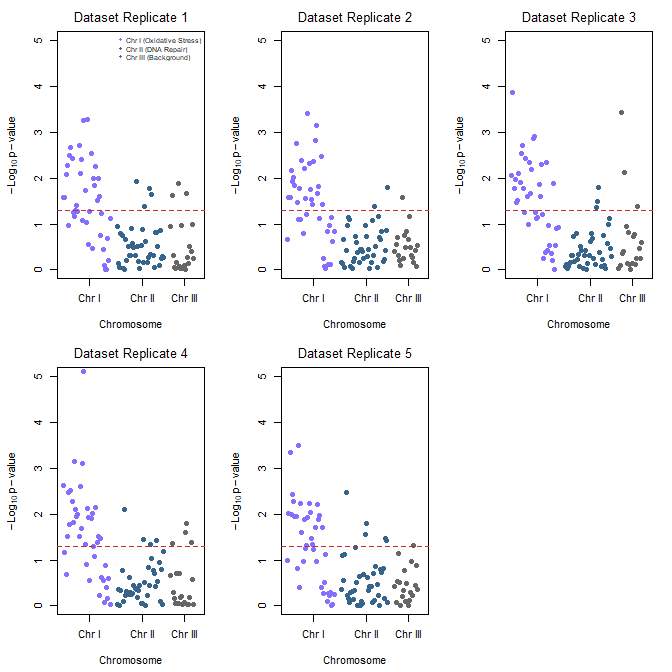
Figure 14. Manhattan plot, gene expression fold change on simulated stress test (NaCl, H2O2) yeast data sets, 100 genes (oxidative pathway, DNA repair pathway).
Looking over the plots (Fig 14) we see evidence of pathway clustering: By arranging the 100 genes sequentially across three chromosomes, we see distinct localized peaks rather than a random distribution of significant points. We also see chromosome hotspots: Chromosome I (Oxidative Stress genes) and Chromosome II (DNA Repair genes) display pronounced vertical clusters that reliably break through the red significance line across all five experimental replicates. This simulates a real-world genomic architecture where functionally related gene clusters or operon-like structures respond in unison to environmental shifts.
Conversely, Chromosome III (Background genes, ie, baseline Control) remained entirely flat and well below the significance threshold, validating that the observed stress responses are highly specific and not an artifact of global transcriptional runaway.
R code — with assistance from Gemini AI (Fall 2026) — for Manhattan plot.
# ==============================================================================
# 1. ASSIGN GEOMETRIC CHROMOSOME POSITIONS TO SIMULATED GENES
# ==============================================================================
# We will use the exact same 5 datasets generated in the previous step.
# To plot a Manhattan plot, every gene needs a Chromosome and a Base Pair (BP) position.

# Assign chromosomes:
# Chromosome 1: Genes 1-40 (Oxidative Stress pathway)
# Chromosome 2: Genes 41-80 (DNA Repair pathway)
# Chromosome 3: Genes 81-100 (Background/Control pathway)
chroms <- c(rep(1, 40), rep(2, 40), rep(3, 20))

# Assign incremental Base Pair positions along each chromosome
bp_positions <- c(seq(1000, 40000, length.out = 40),
seq(1000, 40000, length.out = 40),
seq(1000, 20000, length.out = 20))

# To make a continuous X-axis across multiple chromosomes, we calculate cumulative positions
chr_lengths <- c(45000, 45000, 25000)
chr_offsets <- c(0, cumsum(chr_lengths)[1:2])
coord_x <- bp_positions + chr_offsets[chroms]

# Calculate where the chromosome tick marks should sit on the X-axis (the midpoints)
chr_midpoints <- chr_offsets + (chr_lengths / 2)

# ==============================================================================
# 2. GENERATE MANHATTAN PLOTS FOR ALL 5 REPLICATES
# ==============================================================================
# Set up a clean 2x3 plotting grid to display all 5 replicates together
par(mfrow = c(2, 3), mar = c(4.5, 4.5, 2.5, 1.5))

# Standard scientific significance line (-log10(0.05) is ~1.3)
p_threshold <- 0.05
suggestive_line <- -log10(p_threshold)

for (d in 1:n_datasets) {
neg_log10_p <- -log10(all_pvals[, d])

# Alternating color scheme per chromosome to differentiate boundaries
# Chromosome 1 = Slate Blue, Chromosome 2 = Deep Blue, Chromosome 3 = Dark Grey
chr_colors <- c("lightslateblue", "steelblue4", "grey40")
col_vector <- chr_colors[chroms]

# Create the Manhattan plot grid
plot(coord_x, neg_log10_p,
col = col_vector,
pch = 19,
cex = 1.0,
xaxt = "n", # Suppress the standard numeric X-axis to draw custom Chromosome ticks
xlab = "Chromosome",
ylab = expression(-Log[10] ~ p - value),
main = paste("Dataset Replicate", d),
xlim = c(0, sum(chr_lengths)),
ylim = c(0, 5),
font.main = 1)

# Add the standard genome-wide significance horizontal threshold line
abline(h = suggestive_line, col = "firebrick3", lty = 2, lwd = 1.2)

# Draw the custom structural X-axis labeling the specific chromosomes
axis(1, at = chr_midpoints, labels = c("Chr I", "Chr II", "Chr III"))

# Add an explanatory legend to the first plot panel to map pathways to locations
if (d == 1) {
legend("topright",
legend = c("Chr I (Oxidative Stress)", "Chr II (DNA Repair)", "Chr III (Background)"),
col = c("lightslateblue", "steelblue4", "grey40"),
pch = 19,
cex = 0.65,
box.lty = 0,
bg = "transparent")
}
}

# Reset layout parameters back to default single screen layout
par(mfrow = c(1, 1))
About the R code.
The Genomic Peaks: Because these simulated Oxidative Stress genes sit together on Chromosome I and DNA Repair genes sit on Chromosome II, we see pronounced, beautiful vertical clusters extending upwards over the red significance line.
The Noise Flatline: Chromosome III hosts the background genes, creating a realistically flat landscape where points rarely cross the significance threshold.
Alternating Chromosome Tracks: Using the standard coordinate offset method, the data points stay organized left-to-right without overlapping.
Questions
- Using our Comet assay data set (Table 1, Chapter 4.2), create scatter plots to show associations between tail length, tail percent, and olive moment.
- Explore different settings including size of points, amount of white area, and scale of the axes. Evaluate how these changes change the “story” told by the graph.
Quiz Chapter 4.5
Scatter plots
Data sets
Number of pixels of 1 cm length from unit measure on ten digital images. Recorded by two independent observers, Obs1 and Obs2.
 Obs1, Obs2
171.026, 171.105
136.528, 138.521
148.084, 144.222
142.014, 140.057
150.213, 153.118
187.011, 195.092
168.760, 168.668
154.302 ,160.381
209.022, 209.876
240.067, 161.805
Gene expression
ccc
Chapter 4 contents
2.4 – Experimental Design and rise of statistics in medical research
Experiments and observations: Finding answers.
.
How to identify cause and effect, and the kinds of evidence that can be inferred from the various approaches to study causes of disease has became a major source of disagreement in the news. In a fascinating study, Pew Research Center reported “half of U.S. adults under 50 say they get health and wellness information from social media influencers or podcasts,” and, only about 17% of these influencers report “conventional medicine” training (Report, May 7 2026). For our purposes, I made substantial updates to this page in the fifth month after WHO had declared the Covid-19 pandemic (CDC timeline), and continue to do so today.
The pandemic left many life-lessons, for scientists and public-health supporters, but also for everyone who lived through those times. One of the lessons was how to deal with the challenges of finding treatments in real time. If you followed the news early in the pandemic, you know of the appeal from some (including Donald Trump, the then-President of the United States, Boseley 2020), for use of an anti-parasite drug, hydroxychloroquine, as prophylactic or treatment for active Covid-19 infection (cf. Liu et al 2020). The FDA as well as other institutions rapidly advised against use, in part because experimental design concerns were raised for early studies (Kupferschmidt, 2020). The issue remains contentious for some (eg, Health and Human Services Secretary Robert F. Kennedy Jr., CNN August 2, 2026 interview).
Thus, job number one for students of biostatistics is to learn how to weigh arguments for or against therapies or treatments offered. The purpose of this page is to introduce these issues — how to judge whether a treatment is effective or not.
We will spend some time later on statistical aspects of experimental design (Chapter 5), but we begin with Randomized Control Trials, or RCT, as a model for our discussion of experimental studies. The RCT we recognize today owes its beginning to the 1948 studies on streptomycin use to treat tuberculosis (British Medical Research Council 1948), but of course, the foundations of RCT and experimental design in general, go back much earlier than that date (Chalmers 2011, Hairton and Locascio 2018). For a number of reasons the RCT — experimental, prospective, double-blind clinical trial with random selection of subjects from a reference population and random assignment of subjects to a treatment group or an appropriate placebo treatment control group — is considered the “gold standard” method for producing knowledge (Kaptchuk 2001, Hairton and Locascio 2018).
Note 1. I use the phrase “gold standard” associated with the RCT in the historical context intended by the authors cited. Unfortunately, in 2025, the phrase “gold standard science” has become political (Lewandowsky 2025, Mervis 2025). What we can agree on is characteristics of research as good science: “reproducible; transparent; communicative of error and uncertainty; collaborative and interdisciplinary; skeptical of its findings and assumptions; structured for falsifiability of hypotheses; subject to unbiased peer review; accepting of negative results as positive outcomes; and without conflicts of interest,” Sec. 3. Restoring Gold Standard Science, Presidential Executive Order, May 23, 2025. But even this list is not above scrutiny.
This discourse is way above my pay grade, but for starters, I would replace “without conflicts of interest” with “without disclosure of potential conflicts of interest.” The latter is practical, the former is likely not at all achievable. After all, even where a conflict exists, it does not immediately follow that the reported science is bad, that the conflict is evidence by itself of bias. Reporting conflicts warns the reader that results and conclusions may warrant further scrutiny, but outright dismissal is itself contrary to good science practice. Certainly, there are other aspects to defining what is and what is not good science. And, “gold standard” is just a metaphor (Love 2003), and, frankly, a very out-dated one. The United States and most other nations long ago gave up — for many good reasons — the gold standard as a monetary standard.
Technically, RCT are intervention trials, a specific application of the more general definition of an experiment. That is, the researchers tests a potential drug or therapy in people to observe its effect while holding other variables constant. Experimental studies imply that the researcher imposed treatments or controls onto subjects. The subjects are followed and outcomes are recorded. Thus, experiments by definition are also prospective studies — the outcome is recorded for subjects after some period of time. With a well-designed experiment, the researcher may have evidence to support the claim that, for example, Treatment A causes the outcome.
RCT applied to human health can have profound impact on lives.
The ALLHAT-LLT (JAMA, 2002) trial tested whether adding the cholesterol-lowering drug pravastatin to standard care would reduce heart attacks and deaths in people with high blood pressure and moderately high cholesterol. The study found no significant benefit compared to usual care, suggesting that statin therapy may not always provide extra protection in this group. Its results helped refine how doctors balance blood pressure and cholesterol treatment in heart disease prevention.
The Women’s Health Initiative (JAMA, 2002) trial tested the effects of combined estrogen and progestin therapy in healthy postmenopausal women. It found that while the therapy slightly reduced the risk of fractures and colon cancer, it increased the risk of heart disease, stroke, and breast cancer. These results transformed medical guidance by showing that hormone therapy should not be routinely used to prevent chronic disease in postmenopausal women.
The Du Toit et al. (NEJM, 2015) study showed that introducing peanut-containing foods early in life — rather than avoiding them — greatly reduced the risk of developing peanut allergies in high-risk infants. This landmark randomized trial changed how doctors think about food allergies, leading to new guidelines that encourage early introduction instead of avoidance.
And more recently, we have study reported by Deanfield et al (Lancet, 2025), which found that semaglutide reduced the risk of major adverse cardiovascular events (MACE) in adults with overweight or obesity and established cardiovascular disease—even if they did not lose much weight or had lower baseline adiposity.
In contrast, observational studies are those in which treatments arise by acts of nature. In both experiments and observational studies, there can be treatment and control groups; the distinction between the types of studies is how assignment of subjects to treatments were affected. Observational studies generally are retrospective studies — the outcome has already occurred, the researcher follows up to identify differences among the groups that may account for different outcomes. Examples of observational, retrospective study designs include cross-sectional and case control; cohort studies are prospective studies. Observational studies are discussed further in Chapter 5.4 – Clinical trials.
Compared to observational studies, in principle, experiments can establish cause and effect. Cause and effect refers to an explanation about relationship between two events or objects. In biology, Ernst Mayr (1904 – 2005) distinguished between two levels of explanation, proximate (how) explanations and ultimate (why) explanations (Mayr 1961, cf. Laland et al. 2011). As you know, our mechanism for identifying cause and effect is application of the Scientific Method (Chapter 2.5). Discussions of how to detect cause and effect are provided throughout this book, but emphasized in a few sections (Chapter 16.2 and 16.3).
Good experiments.
The principles of good experiments include many steps beyond simply choosing treatments and controls. In Chapter 5 we’ll go into more depth, but I wished to list for you some of the key principles of good experimental design. With respect to human-subject research, the researcher needs to protect against many sources of potential bias.
- Randomization of subjects assigned to treatment groups controls for individual differences.
- Controls (eg, Placebos) are a means to establish controls in a study so that effects may be attributed to the active treatment.
- Single-blind implies that the subject does not know what treatment was given.
- Double-blind implies that not only is the subject unaware of the treatment received, but, crucially, neither does the researcher.
- The double-blind design — neither the patient-subject nor the researchers know who received the placebo or the treatment — controls for subtle biases.
Note 2. Experimental control implies researcher imposes conditions to remove possibly confounding effects on the dependent variable — outcome of the experiment. Placebo, derived from Latin placere, to please (but see Aronson 1999). Placebo refers to an inert substance (“sugar pill”), or to a substance with known activity but without effect on the target condition or “wrong indication” (eg, antibiotics administered for viral infection), given to research subjects in lieu of the active treatment of interest (the hypothesis). Thus, placebos are examples of treatment controls.
The placebo effect is improvement of subjects who received the placebo and not active treatment (Pardo-Cabello et al 2022). In contrast, nocebo effects are adverse effects attributed to placebo treatment. Under most circumstances, placebo applies to humans only because placebo effects are thought to be product of psychological factors, although mechanisms of action are in dispute. Is sentience necessary for a placebo effect (cf. McMillan 1999)?
The experimenter may influence the outcome of the experiment if knowledge about who received the placebo or the new drug; the subject may respond differently with knowledge that they received the placebo and not the new drug. The key intent in this experimental design is to avoid systematic error, errors in studies that may occur because of our conscious and unconscious beliefs and biases. Placebos are used as treatments because people (and animals!) sometimes get better (or worse) with or without treatment; thus, to be effective, subjects receiving a new drug must get better more frequently than do subjects on placebo. Importantly, the well-designed placebo allows the researcher to gain insight into the mechanism of action by the new drug.
A case to consider: Comparing migraine treatments.
.
Consider the following experiment (Diener et al 2006; see also Liu et al 2018): subjects who had several migraines per month were treated with acupuncture, sham-acupuncture, or standard treatments including beta blockers, calcium channel blockers, or antiepileptic drugs. After 26 weeks the reductions in reported migraines was compared. The authors reported that there was no difference in numbers of migraines among patients who received the different therapy treatments. The authors conclude that because acupuncture lacks side-effects that may occur with standard therapies acupuncture may be a good choice for patients seeking relief from migraine. This is a classic experiment — subjects were assigned to treatments by the researchers. At least in principle, if one treatment group showed better outcomes, the improvement could be attributed to the treatment.
Another case to consider: When the cause isn’t clear.
.
Consider the following example. My dad was diagnosed with lung cancer in his late 70s; his left lung showed many spots when imaged and biopsy confirmed. Surgeons removed half of the lung and after several years he was considered cancer free. Why did he develop cancer in the first place? If you immediately think, “He’s a smoker,” that’s not a good explanation — and shame on you, you’re first instinct was to blame the patient (see discussion in Huff 2013). Dad last smoked tobacco in his early thirties (latency smoking-lung cancer link about 20 years, Lipfert et al 2019).
Tobacco smoking is not the only environmental trigger for lung cancer. Cancer of the lung in non-smokers is the seventh leading cause of cancer mortality worldwide (Field and Withers 2012). Long term exposure to radon gas, a naturally occurring, radioactive noble gas has been linked to lung cancer (EPA). I grew up on Vashon Island, Washington, in a non-smoking home environment. Radon levels on Vashon Island and other areas around Puget Sound are low (source: Washington State Department of Health). Radon is out as an explanation.
What other environmental sources may be linked to cancer? Vashon Island is rural, but, as it turned out, within range of effluent from a copper smelter located in nearby Ruston, Pierce County (Fig 1; my home was 17 km distance from the smelter).
Figure 1. Left: ASARCO smelter, Ruston, Washington, image from Department of Ecology, State of Washington. Direction of smoke from the stack is north, toward Vashon Island. Right: Voronoi map of arsenic and lead affected areas. image from kingcounty.gov. Darker regions correspond to heavier arsenic and lead contamination of soils.
The smelter was last in operation in 1986 and was torn down in 1993 (EPA publication number 910R94001). The smelter stack rose more than 500 feet dispersing smoke laden with heavy metals, notably inorganic arsenic and lead, into the air (Bromenshenk et al. 1985). Over the smelter’s 68 years of service, winds carried away the smoke to my island and to other areas known now as the “Ruston-Vashon Island Exposure Pathway” (Kalman et al 1990). The former smelter site was among the first listed Superfund sites (1983) in the United States by the EPA. Thus, tens of thousands of people were (and continue to be) exposed to the heavy metals deposited into the soils, forming a distinct exposure group (Milham & Strong 1974; Kalman et al 1990; EPA 2000). Arsenic exposure can be via inhalation, skin, or in drinking water — areas of Vashon-Maury island continue to have high levels of arsenic in both the soil and in any domestic water wells (PublicationNo. 14-09-044, Department of Ecology State of Washington).
Note 3: A personal comment — I stumbled onto the article by Bromenshenk and colleagues by accident. Instead of attending lecture, as I often did at the time, I was looking through journals in the research library. I was shocked at this article, because for the first time, I connected the smelter to the island I grew up on. The contamination on the island just wasn’t a conversation.
Is arsenic exposure by inhalation a plausible mechanism for my Dad’s lung cancer? As shown in Fig 1, the soils on Vashon near my home were heavily impacted by the smelter. Exposure could have come about from exposure during routine yard work — I have memories of clouds of dust kicked up by the lawn mower during spring and summers. Thus, an exposure route is possible. What evidence can we come up with?
Figure 2A shows negative association between lung and bronchial cancer incidence rates per 100L persons, adjusted for age, for several Washington state counties between 2000 and 2020 and distance from the smelter in Ruston. For comparison, Figure 2B shows no association between bladder cancer incidence rates per 100K for the same counties and time period and distance from the smelter. Workers exposed to arsenic have higher rates of lung cancer (Sullivan 2007, Wei et al 2019; see Enterline et al 1987 for a study a study based on cancer of workers at the smelter). Cultured lung cells exposed to arsenic associated with changes in gene expression (Clancy et al 2012). Coincidently, two of the family dogs developed and died of cancer as did one female goat. Perhaps my dad’s lung cancer was attributed to long exposure to arsenic (a decade after the cancer, and long after he stopped with yard work, his blood readings for arsenic were in the range of a modest 11 μg/L).
Figure 2. County cancer rates (A, lung and bronchial; B, bladder) from 2000 – 2020 vs distance in kilometers from ASARCO smelter, Ruston, WA. Data compiled from Washington Tracking Network (WTN). The counties were King (55 km), Kitsap (39.28 km), Pierce (38.48 km), San Juan ( 141.43 km), Snohomish (100.73 km), and Spokane (385.34 km).
If this scenario seems plausible, I hope you immediately recognize it as a case of confirmation bias (see Chapter 2.6). Putting aside for a moment the different arsenic species, each with different LD50 (the lethal dose needed to kill half the population — see Chapter 20.10), the difficulty ascribing arsenic as a causal agent for my Dad’s cancer is that many other exposures happened simultaneously. For example, indoor carpets are a primary source of several volatile organic compounds (Haines et al 2020). Prior to 1980 carpets may have included formaldehyde and other known carcinogenic agents. Dad commuted by car between work and home — with a ferry ride between — for decades (until the early 1990s), routinely traveling heavily congested roadways, this during the years prior to and the early years of the Clean Air Act of Environmental Protection Agency of the United States (it wasn’t until 1981 that new cars met EPA emission standards: Clean Air Act timeline here). Thus, all commuters including my Dad were exposed to gasoline combustion emissions, many known to be carcinogenic (Parent et al 2007). Moreover, a limited study by Public Health of Seattle and King County (2001) found rates of cancer on Vashon between 1980 and 1988 were similar to other areas in King County.
Summary.
It’s easy to fall into the trap that experiments — and by extension meta-analysis and systematic reviews — are the best tools offered by science for developing knowledge about the world, and other approaches suffer by comparison. But after even a bit of reflection, we should recognize that it can’t be that simple. While we now “know” tobacco cigarette smoking increases lung cancer risk, and many experiments with animal models convincingly show the link (eg, Hutt et al 2005), no human experiment in the strict sense, ie, prospective, randomized control trial, has ever been conducted (hint: it would be unethical, see discussion in Allmark and Tod 2016). Instead, the accumulated evidence from observational studies on exposures of different populations over the years overwhelmingly points to smoking as a leading risk factor (cause) of lung and other cancers — an example of Hill’s guidelines of causality. We end with a quote:
RCTs can play a role in building scientific knowledge and useful predictions but they can only do so as part of a cumulative program, combining with other methods, including conceptual and theoretical development, to discover not ‘what works’, but ‘why things work’ (p 2, Deaton and Cartwright 2017).
Questions.
.
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- Was my Dad’s lung cancer attributable to his 40 years plus exposure to soil arsenic (he’s a non-smoker)? How should we approach this question?
- In Diener et al (2006), the authors concluded that because acupuncture lacks side-effects that may occur with standard therapies acupuncture may be a good choice for patients seeking relief from migraine. Do you agree with the authors?
- Ethical standards evolve with time. An ongoing debate in research is whether and how placebos are to be used in human subjects research. Placebos are a means to establish controls in a study so that effects may be attributed to the active treatment. The “gold standard” of clinical trials is considered to be the randomized double-blind design — neither the patient-subject nor the researchers know who receives the placebo or the treatment. Following review of the WHO report on Use of Placebos in Vaccine Trials, pick one study and evaluate whether or not the decision to use placebos was warranted in your opinion.
- I searched PUBMED for “double-blind” by decade and found the following results (August 2018) (Table 1). Open R and/or R Commander and create two variables, then generate a scatter plot. Describe the shape of the relationship between number of publications citing “double-blind” and time (eg, 1950 – 1959, 1960 – 1969, and so on).
| Decade | Publications |
|---|---|
| 1950 | 60 |
| 1960 | 995 |
| 1970 | 7184 |
| 1980 | 24737 |
| 1990 | 39643 |
| 2000 | 53965 |
| 2010 | 69265 |
- Here’s one way to enter this data into R. At the R prompt (or in the R Script window of R Commander), create two variables,
DecadeandPubsDecade <- c(seq(1950, 2020, by=10))Pubs <- c(59,995,7161,24728,39670,54011,57043)Make an XY scatter plotplot(Decade,Pubs) - Repeat the PUBMED search as above but search for “placebo”. Make a table like the one above and provide a scatterplot of your results.
- Is the concept of a placebo relevant if the subjects in your experiment are yeast cells, not humans?
- Similarly, if your subjects are yeast cells, how does the concept of performing experiments “blind” apply?
- Ethical standards change with time. An ongoing debate in research is whether and how placebos are to be used in human subjects research.
- If placebos are so important, why is their use a concern in clinical trials?
- Following review of the WHO report on Use of Placebos in Vaccine Trials (see Readings below), pick one study and evaluate whether or not the decision to use placebos was warranted in your opinion.
R notes for question 5:
<-is an assignment operator (assignOP); everything to the right of<-is assigned to the object named to the left of the<-operator. You can instead use=in place of<-, but because=is also used in other contexts besides assignment, a quick look at blogs by data scientists will find a preference to use<-for clarity and consistency.c()“combines” arguments into a vector.seq()is used to generate a sequence of numbers between a lower and an upper limit; ifby = nis included, the sequence will be increased by the value n. If omitted, then the sequence is increased by 1.
Quiz Chapter 2.4
Chapter 2 contents.
.
- Introduction
- Why biostatistics?
- Why do we use R Software?
- A brief history of (bio)statistics
- Experimental Design and rise of statistics in medical research
- Scientific method and where statistics fits
- Statistical reasoning
- Chapter 2 – References and suggested reading
2.2 – Why do we use R Software?
- Why R? The case for using R in biostatistics education.
- How to get started with R .
- Why R Commander, why not RStudio? .
- Wait! Why don’t we use Microsoft Excel? .
- Statistics comparisons between R and MS Excel .
- Graphics comparison between R and MS Excel .
- So, you’re telling me I don’t need a spreadsheet application? .
- Still not convinced? .
- Why install R on your computer?.
- Help with R?.
- Questions .
- Quiz .
- Chapter 2 contents.
If this page is TL;DR, and you’re in a rush, then instructions to install R onto your macOS or Windows PC are provided in Install R. To run in the cloud only, see Use R in the cloud.
Why R? The case for using R in biostatistics education.
.
Why do we use R Software? Or put another way: DrD, Why are you making me use R?
Truth? You can use just about any acceptable statistical application to get the work done and achieve the learning objectives we have for beginning biostatistics. However, we will use the R statistical language as our primary statistical software in this course. Part of the justification is that all statistical software applications come with a learning curve, so you’d start at zero regardless of which application I used for the course.
In selecting software for statistics I have several criteria. The software should be:
- if not exactly easy, the software should have a reasonable learning curve
- widely accessible and compatible with
allmost personal computers - well-respected and widely used by professionals
- free software
- open source
- well-supported for the purposes of data analysis and data processing
- really good for making graphics, from the basics to advanced
- capable to handle diverse kinds of statistical tests
R meets all of these criteria. R history began back in 1993 and has always been available as free software under the terms of the Free Software Foundation’s GNU General Public License in source code form. R compiles and runs on a wide variety of UNIX platforms and similar systems, including GNU/LINUX, FreeBSD, and various Linux distros like the popular Ubuntu®, in addition to their more famous Microsoft Windows® and Apple macOS® distributions. To facilitate access to the software, numerous mirror sites are available from sites around the world, with cloud.r-project.org supported by RStudio perhaps the most widely used. From January 2024 to December 2024, more than 8.5 million downloads of base R were made from the RStudio CRAN mirror site (CRAN stands for Comprehensive R Archive Network.
changelog file, which allow one to track numbers of downloads for any package from their mirror site — https://cloud.r-project.org/. Here’s the code and recent counts for downloads of R itself over a four week period .
install.packages("cranlogs")
library(cranlogs)
# How many downloads of base R around start of Fall semester?
 out <- cran_downloads("R", from = "2025-08-01", to = "2025-08-31")
sum(out$count)
R output
[1] 582524
An iterative function returning number of downloads over multiple years is provided at Part05 of Mike’s Workbook for Biostatistics.
R is straightforward to use once you learn how to work with the language, but has a steep learning curve; after all, it’s a programming language. I recommend installing the program onto your computer, but ready to go R is also available at multiple cloud services, including Google CoLab and Posit Cloud. The remainder of this page is directed at users who choose to install R to their computer, although much of the discussion holds regardless of the R environment choice, local or Cloud.
For local installs of R, I also recommend use of the GUI R Commander. Use of R Commander helps with the learning curve, and eventually, your use of code will become second nature. We don’t use RStudio, but as your skills improve, I recommend transitioning to the IDE RStudio; after the initial growing pains are behind you, RStudio likely will be a better solution over R Commander.
This discussion implies learning R programming. However, while we need statistical software to do statistics, students in my BI311 course must keep in mind that learning objectives for a biostatistics course is about the concepts and interpretation of statistics, not just use of the software. In other words, learning how to use R is not the focus of BI311 nor will you likely achieve R programming competency by the end of the semester. I certainly encourage students to strive for competency and I give frequent bonus opportunities to demonstrate coding skills during the semester.
Why R and not some other statistics software?
Thus, you might ask if the purpose of the course isn’t to learn R, why work with R instead of a more familiar app or software, eg, Microsoft Excel® (hereafter simply referred to as Excel), or Google Sheets, or even my favorite open-source office alternative, LibreOffice Calc? Or, perhaps even just one of the many online calculators, if the course learning objective is to “just” learn about statistics?
First, I believe that real data derived from real biology or biomedical problems are essential elements to a first course in biostatistics. That’s not a particularly unique perspective although I don’t have survey results of other statistics instructors to back up the claim. Real problems involve observations on multiple subjects, many variables — large data sets; this alone precludes use of hand calculations and calculators. As a corollary, we will not spend a great deal of time learning the in’s and out’s of the algorithms that form particular statistical tests. Now, do understand that there is a tremendous benefit to understanding statistics by working through the equations, by looking at the algorithms, and there’s no escaping the need for understanding that probability provides the foundation of statistics inference (Chapter 8). Thus, for most of us, the statistical software available to us provides an appropriate framework for applying correct statistical tests to our projects. Therefore, the decision is about which statistical package we should use.
Second, R is perhaps the choice in academia for statistical software. A PUBMED search found more than 1500 citations of R. Visit Robert A. Muenchen’s web page (The popularity of data analysis software, r4stats.com) to see updated statistics on statistical software use. Those of you continuing on to graduate school or to professional schools will find that many of your statistically literate colleagues use R and not one of the commercial programs. While there are many excellent commercial packages (Table 1), and in some cases you can make spreadsheet programs do statistics (typically add-ins are required), all statistical software come with steep learning curves. Thus, part of my selling point to you is that learning to use R is at the cutting-edge in your field and, given that all of the software you could use can have have their challenges, it is best to work with something that will be around and is in wide use, without the burden of a financial investment.
Table 1. A selective list of statistical software.
| Software | Student license? | Limited or full function version | macOS | Windows 11 | Fee* | Academic license type |
|---|---|---|---|---|---|---|
| GraphPad Prism | Subscription, $142 per year | Full | Yes | Yes | $202 | annual subscription |
| JMP | Yes, but with purchase of selected textbook | Limited | Yes | Yes | $100 | monthly subscription |
| Minitab | Subscription, $54.99 per year | Full | Yes | Yes | $1610 | annual subscription |
| IBM SPSS | Rental, $76 per year | Full | Yes | Yes | $260 | annual rental |
| SigmaSTAT | No | NA | No | Yes | $299 | perpetual |
| MySTAT | Yes, free | Limited | No | Yes | NA | |
| SYSTAT | No | NA | No | Yes | $739 | perpetual |
| Stata | Subscription, $94 per year | Full | Yes | Yes | $325 | annual subscription |
see Wikipedia for list of additional software
Third, what about online sites like plot.ly where, for free, you can plot and, in some cases, calculate statistics? What about the web application at Brightstat, which claims to provide an SPSS-like experience online (Stricker 2008)? While it is true that there are many wonderful websites that can perform many of the statistical tests we will use this semester, these sites are not suitable for more than occasional use.
How to get started with R.
.
A few words about my approach to the software in my biostatistics course. I note to students during the semester that our course is not a programming course, but rather, programming skills are acquired along the way. Our focus is how to do statistical analysis, how to design experiments, etc. Coding skills without understanding of the why we’re doing it is not unlike learning to cook by following a great recipe as opposed to learning about the art and science of flavor (NPR Science Friday, March 15, 2024) — the homework is solved but the why we can support our conclusions may be obscure.
We set aside the first couple of class meetings simply to setup student’s Windows PC or Apple macOS computers to do data science; for students with access to Chromebooks or iPad tablets, we need to set them up to run R in the Cloud (eg., Google Colaboratory) — in other words, there’s a lot of pre-work that can present barriers to actual doing statistics in R (or other software). Once we have the environment set up for the students, we utilize a “tell-show-do” approach to learning how to code. The “tell” part includes sharing script; the “do” part is mostly done by students outside of class as part of completing homework.
First work with the language can be frustrating, so I also encourage a “five minute” rule — if it ain’t working, stop. So, by all means when Run through a troubleshooting checklist, but please don’t continue to struggle — the gap is between the instructions and where the student is with the material — it’s a me-as-instructor problem, not a student must work harder problem!
All statistics work follows a similar workflow.
The basic workflow for a data project, using R as the primary statistical programming tool, looks like that illustrated in Figure 1.

Figure 1. A basic workflow with R.
The workflow begins with the assumption that a data set already exists. Getting the data into an R session depends on the source of the data, for example stored in spreadsheet file or from a table on a webpage. Data cleaning and processing of the data may be in order — for small and modest-sized data sets, my own preference is to do most of the data cleaning in my spreadsheet app, but R has full capabilities to handle or “wrangle” data. Next, the raw data should be stored in R session in a data frame object. Once the data frame object is available, exploratory data analysis, including summary statistics and data visualization can proceed. Higher order analytics, including statistical inference and modeling, can then begin.
The R statistical language, accompanied by additional packages to extend its capabilities beyond basic math and statistical functions, provided a complete statistical environment. R is best viewed as a programming language for statistics (data analysis), and data processing. Power users of R learn how to write scripts that do t-tests, ANOVA, regression, etc. The scripts are just lines of code that R understands and it provides the user tremendous control over analysis and inference of data sets. Because of this flexibility and power, however, R can be intimidating at first. So, we’ll start slowly with scripts, introducing just what we need to get started and build from there. We’ll be addressing R issues in more depth over the next several weeks, but for the first week, our goal(s) should be to make sure each of you knows how to start/exit R, how to create and utilize a working directory, and how to use R as a calculator. You obtain your copy of R from the R Project for Statistical Computing, available at https://www.r-project.org. Instructions to install R are provided in Install R. A ten-part tutorial to get started using R is provided in Mike’s Workbook for Biostatistics.
Note 2. A working directory or working folder is something you create on your computer to contain the files and sub-directories of a project. It sets the default location for files you may need to have R read. For example, all of your work for a course (data files, script files, Markdown files), may be stored in a folder called BI311 on your Desktop. For example, on a macOS, the path to the working folder would be
/Users/username/Desktop/BI311
Why R Commander, why not RStudio?
.
We utilize an R package that provides a menu-driven context to much of the typical statistics one needs to do biostatistics. The package is called R Commander (Rcmdr), which provides a graphic user interface or GUI. Rcmdr therefore significantly eases the learning curve for doing statistics with R. We use a package called R Commander, which provides drop down menus for most of the typical kinds of analyses. Rcmdr is in use in many courses across the world (more than 17K downloads in August 2025), and among the other GUI available for R, Rcmdr is among the best supported GUI available for R. R Commander function is extended by plug-ins; as of August 2025, there were 31 plugins that extend Rcmdr’s capabilities. Instructions to install R Commander are provided in Install R Commander.
Note 3. Other options to improve use of R include use of RStudio®, which is an integrated development environment or IDE. RStudio is really nice to use, and, happily, you can run R Commander within RStudio — but with windows popping up outside of the RStudio windowing framework if the default MDI environment to organize is set. (The solution? R Commander runs best when SDI option is selected during RStudio install.) I am also increasingly using shiny apps within the course to help with concept presentation; in the future, I plan to provide a complete shiny app which would allow BI311 students to work interactively with the statistics presented in this text, something like the radiant-rstats project. However, for use in our course, R Commander provides a familiar look as students develop knowledge in the course: simply point and click to access the statistical functions.
Wait! Why don’t we use Excel? My instructor in {insert course here} used Excel…
.
A very reasonable question for you to ask — why don’t we use Microsoft Excel or Google Sheets for statistics? Moreover, it is highly likely that you have gained at least some introduction to descriptive statistics and graphing with spreadsheets in former courses — shouldn’t we learn statistics within a software framework you are already familiar?
After all, “Can’t Microsoft Excel do statistics?” Mostly the answer is, no, not really (Fig 2).
Figure 2. “Spreadsheets,” xkcd.com no. 2180.
MS Excel, Google Sheets, Apple Numbers, and for that matter, Calc, the spreadsheet application in my favorite office app LibreOffice (LibreOffice is a free, open-source alternative to Microsoft Office), can be used to calculate many descriptive statistics. With some effort, these applications can be extended by use of either Analysis ToolPak or Solver Add-ins to do more complicated statistics like regression and analysis of variance, and curve fitting.
Note 4. Perhaps you’re thinking: I’m a data science student — it’s not whether we chose between use of spreadsheet apps or R, we should be using Python, shouldn’t we? DrD — this is an open question, and if you judge the job market as the arbiter, I’d say learn Python over R — if you are primarily aiming for a data science position. However, from the point of view of learning statistics, my vote would be R — far more packages developed to accomplish our tasks, and, at least for this course, we are not teaching coding: our focus is on using statistics to explore (describe) and ask questions about data collected by observation or experimentation.
While we’re on the subject in 2025, it looks like the job market is in Machine Learning, which means R or Python knowledge will be a given, but advantage will go to those who know Alteryx or it’s open source alternative KNIME for data science workflow design — from data collection to model development.
However, use of MS Excel for statistical analysis involves learning a number of commands, syntax, and developing workflows that are neither intuitive nor standard. Some publishers have provided add-ins that are reportedly designed to simplify this process (eg, XLStat, UNISTAT, Real Statistics using Excel). None of these options are free and none are in use in any major way by scientists (see Robert Muenchen’s The popularity of data analysis software). The free add-ins of Analysis ToolPak and Solver may work for you if you own a Windows PC, but only Solver is included for the Mac versions of Excel. MacOS users may download and install StatPlus:MacLE, which is a limited, but free alternative to the Analysis ToolPak add-in; for a complete package a Pro version is available (licenses started at $89, web site: www.analystsoft.com/en/products/statplusmacle/).
An additional caution: you should be aware that there have been reports over the years that algorithms selected by Microsoft for Excel have not always been to industry standards (eg, McCullogh and Wilson 2005). In short, the fit of Excel and other spreadsheet apps for use in statistics is not a simple one. To do the kinds of statistics we will use routinely in class, Excel would need to be modified with add-ins, and the add-ins would be the result of programming by someone. And you would still need to learn how to write the code.
What about graphics? You may like Microsoft Excel’s ability to do graphics. Indeed, Excel, Google Sheets, and LibreOffice Calc can be used to generate many typical kinds of statistical plots. But again, in comparison to R, spreadsheet app graphics are limited and require a deal of effort to generate acceptable plots. I think you’ll be surprised at how straight-forward R is. Here’s an example, first rendered in Microsoft Excel, then in base R. And importantly, the kinds of plots Excel does well at are not necessarily the plots suitable for research publication. For example, Excel allows you to make bar charts easily, but cannot do box plots. Box plots are preferred over bar (column) charts for ratio scale data.
Note 5. base R refers to the core R programming language along with many functions and graphics routines. We extend capabilities of base R by adding packages, like R Commander.
Statistics comparisons between R and MS Excel.
.
About that learning curve. Let’s compare R and MS Excel for basic functions common in data analysis. Similar conclusions hold for comparisons to Google Sheets and LibreOffice Calcs.
Note 6. If you search for variants of this question, you’ll find other’s making the argument that the learning curve for many data science tasks is, perhaps surprisingly, shorter for R than it is for Excel. For example, see Amieroh Abrahams 2023 article at https://www.jumpingrivers.com/blog/comparing-r-excel-data-wrangling/ .
Table 2 lists the observations we can use to conduct comparisons of the applications.
A simple data set
| varA |
|---|
| 12 |
| 14 |
| 20 |
| 25 |
| 28 |
| 29 |
| 32 |
| 34 |
| 35 |
| 39 |
| 47 |
| 47 |
| 50 |
| 53 |
| 54 |
| 71 |
| 79 |
| 87 |
| 89 |
| 96 |
| 105 |
| 122 |
| 130 |
| 132 |
One of the first steps in data analysis is to produce what are called descriptive statistics. Common descriptive statistics are the mean and the sample standard deviation. Let’s compare Excel and R for retrieving these two statistics.
With Excel, to calculate the arithmetic mean of 24 numbers, enter the values into a single column of 24 rows, then enter “=average(A2:A25)“, without the quotes, into a new cell of the spreadsheet. “A2:A25” refers to where data would be contained in column A rows 2 through 25. Typically the first row in a worksheet would contain the name of the variable, eg, “A.” Depending on the significant figures set, the estimate returned by Excel for the mean of A is 59.58333333.
Similarly, to obtain the standard deviation, type =stdev(A2:A25), into a new cell of the spreadsheet. Again, depending on the significant figures set, Excel returns a value of 37.05215674 for the standard deviation of A.
In contrast, to obtain the mean and standard deviation for a variable in an R data set, all you would type at the R prompt (>), or in the script window
Note 7. Always run your code as a script. Entering code at the R prompt means you are working at the command-line interface, and you work one line at a time. This is not an efficient way to interact with R. Instead, I recommend you always create and work from a script document. For beginners, that’s why I recommend R Commander, which includes a script window. Simply type your code in the script window, highlight the code you wish to run, and run by clicking submit button (or Ctrl+R Win11 or Cmd+Enter macOS). When you are ready to move on from R Commander, RStudio is the IDE of choice.
and then submit the code is:
myA <- c(12, 14, 20, 25, 28, 29, 32, 34, 35, 39, 47, 47, 50, 53, 54, 71, 79, 87, 89, 96, 105, 122, 130, 132)where the “c” is a function to combine arguments into a vector and saved to the object myA, followed at the new line by
mean(myA)Hit enter after entering the command) and R returns
[1] 59.58333For the standard deviation, write the R base function sd()
sd(myA)Hit enter after entering the command and R returns
[1] 37.05216It’s not much of a difference, but note that to get the mean (arithmetic average) I typed seven characters in R, but 16 characters in Excel; similarly, for the standard deviation I typed in 5 characters in R, but 13 characters in Excel. That’s a savings of 56% and 62%, respectively. Excel tries to help by using AutoComplete to anticipate what you want to enter, but AutoComplete doesn’t always work properly (eg, see gene name errors generated by use of default Microsoft Excel settings, Ziemann et al 2016).
Note 8. I use spreadsheets all of the time for data entry and data management. Make sure AutoComplete and AutoCorrect options are turned off and these problems are much less.
In conclusion, R is quicker for descriptive statistics.
Graphics comparison between R and MS Excel.
.
MS Excel is often cited for its graphics capabilities (Camões 2016). We can make the familiar scatter plots, bar charts, and pie charts in Excel. These plots and more are easily obtained in R. I won’t elaborate here about graphics, we talk at some length about graphics in Chapter 4. But here’s one example in R.
Let’s plot myB vs myA. We already provided the data for variable A, here’s the data for variable B.
17, 21, 21, 26, 27, 32, 28, 42, 40, 30, 71, 53, 56, 61, 55, 89, 82, 63, 116, 162, 116, 154, 137, 149Don’t recall how to assign a set of numbers to an object, B, in R? See above and look again at how we assigned the numbers to object myA.
To get a simple scatter plot (Fig 3), I may write at the R prompt.
plot(myA,myB)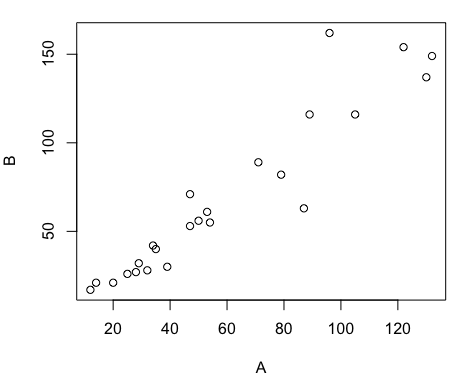
Figure 3. Basic scatter plot made in R, plot(myA,myB).
And here’s the comparable default plot (Fig 4) from Microsoft Excel, Office 365
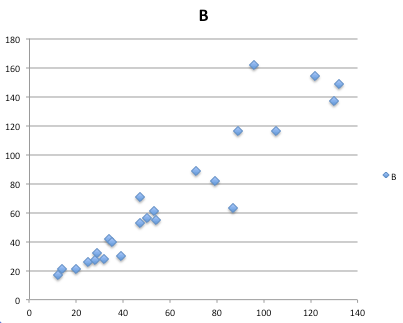
Figure 4. Basic scatterplot made in Microsoft Excel.
Now, both graphs need some work, and to be fair, these are just the defaults. With some effort, you can make an Excel graph look pretty good. But note — the defaults in Excel don’t generate axis labels, while R default plot does. Excel adds a useless title and legend; both need to be removed. Excel also adds grid lines where typically one would not include these in a scientific plot; for example, in the case of scatterplots, grid lines can distract the viewer from the data points and reduce the data-to-ink ratio Tufte 1984).
Count the steps to generate an acceptable scatter plot (Table 3). I’ve also added R Commander (Rcmdr) steps for comparisons (Rcmdr lets you use drop-down menus like Excel or Google Sheets or LibreOffice Calcs).
Table 3. Steps needed to make a simple scatterplot in R, R Commander, or Microsoft Excel.
| Steps | R | Rcmdr | Excel 365 |
| 1 | write the function | Select Graphs | Highlight columns |
| 2 | Select scatterplot | Select from Menu “Insert” | |
| 3 | Select variables | Select scatterplot | |
| 4 | Uncheck options | Select type of scatterplot | |
| 5 | Delete legend | ||
| 6 | Remove grids | ||
| 7 | Insert X-axis label | ||
| 8 | Insert Y-axis label |
Conclusion? R is quicker for routine statistical plots like a scatter plot. And I didn’t even count the steps needed to change MS Excel’s dreadful diamond icon points.
That’s one step in R, four steps in Rcmdr, but eight steps for Microsoft Excel. LibreOffice Calc is a little better at only four steps, but like MS Excel, you’d need to change several components to the graph (Fig 5).
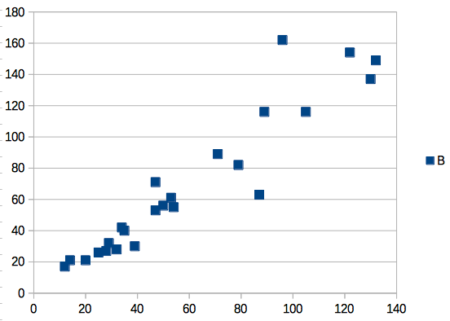
Figure 5. Basic scatterplot made in LibreOffice Calc.
Note 9. In R vernacular, these are referred to as pch, or point characters: pch = 23 returns a blue diamond character; for a blue square like Figure 5, add to the plot() command as
plot(myA,myB, pch = 22)
So, you’re telling me I don’t need a spreadsheet application?
.
No, not at all. We use spreadsheets, and more generally, databases, to store data. Spreadsheets apps are designed to make data entry and data management approachable and efficient. They remain an important tool for researchers (Browman and Woo 2017).
R is not that great of a spreadsheet; packages are available to seamlessly tie your spreadsheet and database data to R via ODBC. We will routinely enter and manipulate data in MS Excel, then import the data into R for analysis.
Spreadsheet apps like MS Excel and Google Sheets (see also LibreOffice Calc) are great at being a spreadsheet program, R is great at being a statistical software program. You should take advantage of what the tools do best.
Still not convinced?
.
R is in use all over the world, by students and professionals alike and if one is going to spend the time to learn how to use a statistics software program, you should learn a standard program, like R.
And it’s not just me. Read about R in this 2009 New York Times piece, “Data analysts captivated by R’s power.” Look who purchased (April 2015) Revolution Analytics, a major player in the development of the R programming language.
Note 10. The answer was Microsoft. For several years Microsoft supported R development via Microsoft Machine Learning Server & Microsoft R Open. However, as of July 2023, this service is no longer available. See Microsoft R application network retirement.
Why install R on your computer?
.
Convenience. Control. Offline.
At the Biology department of Chaminade University, we have installed and maintain R, Rcmdr, and RStudio along with all required packages on our Macbook Pro® Lab computers for your use during class and during optional, proctored biostatistics work sessions. Since 2018, R is increasingly available “in the cloud” (eg, RStudio Cloud), which would mean you could run R in your browser and avoid installation on your computer. You can run significant analysis with R in the cloud via the free Google Colaboratory and CoCalc are now available: I encourage you to look into these platforms. Unfortunately, these services are not quite ready for the classroom. For example, RStudio in the Cloud is free to use on a limited basis, but quickly requires a significant subscription cost with increasing use. Google Colab and GoCalcs require use of Jupyter notebooks, which add yet another layer to the learning curve without focusing on learning statistics. Second, although access to their servers is easy, running simultaneous connections via Chaminade’s single public IP address is likely to lead to problems for us. Third, I want you to use R Commander (Rcmdr) to assist in the learning curve — Rcmdr cannot be run in the Cloud (ie, RStudio in the Cloud, Google Colaboratory, or CoCalc).
Therefore, you are encouraged to install R, Rcmdr, and even RStudio, onto your own computers, in part because of the convenience, but also because R is not generally available to students on campus, ie, only the Biology department’s computers have the up-to-date R software installed.
To get started, go to your Canvas website and view How to install R on your own computer.
An additional benefit to installing a version of R on your computer, you’ll understand more about the software if you take the time to install and if need be, troubleshoot your installation of the software. Moreover, there’s a considerable amount of help out there for R. For example, a simple Google search(keywords: tutorial “install R”), returns more than 700K hits, and more than 40K January 2023 alone (add “after:2023-01-01” to Google search box). In fact, there’s so much out there that you’ll want to sample from several sites and select the voice that works best for you.
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- I listed several spreadsheet apps: Microsoft Excel, Google Sheets, Apple Numbers, LibreOffice Calc. Which of these are free to download and install to your computer? Which are freely available via the Cloud?
- What level of confidence do you have to this statement: I am confident in my ability to use spreadsheet apps for my BI-311 work this semester. Response options:
- Strongly disagree.
- Disagree.
- Agree.
- Strongly agree.
- What level of confidence do you have to this statement: I am confident in my ability to use the R programming software for my BI-311 work this semester. Response options:
- Strongly disagree.
- Disagree.
- Agree.
- Strongly agree.
.
Quiz Chapter 2.2
Why do we use R software?
Chapter 2 contents
.
1.1 – A quick look at R and R Commander
A first look at R.
R is a programming language for statistical computing (Venables et al 2009). R is an interpreted language — when you run (execute) an R program — the R interpreter intercepts and runs the code immediately through its command-line interface, one line at time. Python is another popular interpreted language common in data science. Interpreted languages are in contrast to compiled languages, like C++ and Rust, where program code is sent to a compiler to a machine language application. R is free to use and available via many platforms, from local installations on a person’s laptop to running on cloud servers (Fig 1). 
Figure 1. Choose how you will interact with R: on your computer (Blue box) or in the cloud (Red box). Users of Linux, macOS, and WinPC can either install R to their computer or choose to access R in the cloud (and/or, black arrow).
Before you begin, you have a choice: how do you want to work with R (Fig 1)? In part, the choice depends on your computing device. If you have a desktop or laptop computer, running Linux, Apple macOS, or Microsoft Windows, then R can be installed onto your computer (blue box, Fig 1). If, however, you have a ChromeBook, Apple iPad or iPhone, or any Android Tablet or Smartphone, you would go with the second option (red box, Fig 1).
For those going with installing R to their computer, the second choice is to pick the environment for creating and running scripts and managing file input and output during a session. Working environments for R in the cloud include RStudio and Jupyter Notebooks (eg, Google CoLab) (red box, Fig 1 — see Note 2 below). For installed R, two suggested environments are R Commander and RStudio, an Integrated Development Environment or IDE, RStudio (Fig 1). The choice depends on your needs — an IDE is helpful when you plan to write a lot of code, it’s a comprehensive programming environment, which includes many tools that support writing code from scratch.
For our course at Chaminade University, I recommend R Commander because of the drop-down menu approach to accessing statistical functions in R; R Commander is not a comprehensive environment, but it provides the necessary scripting window along with access to markdown editing. R Commander, Rcmdr, is an R package that provide a graphical user interface or GUI for R. It is based on the tcltk package. R must be installed first before installing the R Commander package. R Commander provides familiar menu functions, like many commercial statistical software. R Commander, like the IDE RStudio, is not necessary for R programming or conducting statistical analysis or even generating reports via markdown. R Commander, however, shrinks the learning curve with R programming basics so that students can focus on learning statistics, which is the chief objective of the Biostatistics course at Chaminade.
The following steps user through use of R and R Commander, from installation to writing and running commands. Mike’s Workbook for Biostatistics has a ten-part tutorial, A quick look at R and R Commander, which I recommend.
Note 1: Getting started? By all means rely on Mike’s Biostatistics Book (Appendix: Install R, Install R Commander, Use R in the cloud) and blogs or other online tutorials to point you in the right direction. You’ll also find many free and online books that may provide the right voice to get you working with R. However, the best way to learn is to go to the source. The R team has provided extensive documentation, all included as part of your installation of R. In R, run the command RShowDoc("doc name"). replace doc name with the name of the R manual or R user guide. For example, the Venables publication is accessed as RShowDoc("R-intro"). Similarly, the manual for installation is RShowDoc("R-admin") and the manual for R data import/export is RShowDoc("R-data").
Install R.
.
Full installation instructions are available at Install R, and for the R Commander package, at Install R Commander. Here, we provide a brief overview of the installation process.
Note 2: The instructions at Mike’s Biostatistics Book assume use of R on a personal computer running updated Microsoft Windows or Apple macOS operating systems. For Linux instructions, eg, Ubuntu distro, see How to install R on Ubuntu 22.04. For Chromebook users, if you can install a Linux subsystem, then you can also install and run R although it’s not a trivial installation. For instructions to install R see Levi’s excellent write up at levente.littvay.hu/chromebook/. (This works best with Intel-based CPUs — see my initial attempts with an inexpensive Chromebook at Install R.)
Another option is to run R in the cloud via service like Google’s Colab or CoCalc hosted by SageMath. Both support Jupyter Notebooks, a “web-based interactive computational environment.” Neither cloud-based service supports use of R Commander (because R Commander interacts with your local hardware). Colab is the route I’d choose if I don’t have access to a local installation of R. See Use R in the cloud for more details.
Download a copy of the R installation file appropriate for your computer from one of the Comprehensive R Archive Network (CRAN) mirror site of the r-project.org. For Hawaii, the most convenient mirror site is provided by the folks at RStudio (https://cloud.r-project.org/. In brief, Windows 11 users download and install the base distribution. MacOS users must first download and install XQuartz (https://Xquartz.org), which provides the X Window System needed by R’s GUI (graphic user interface). Once XQuartz is installed, proceed to install R to your computer. MacOS users — don’t forget to drag the R.app to your Applications folder!
Start R.
.
The following is a minimal look at how to use R and R Commander. Please refer to tutorials at Mike’s Workbook for Biostatistics (R work, part 1 – 10) to learn use of R and R Commander.
We’re just getting started, so the next thing to learn is how to set your working environment for your R sessions. Although we’ll discuss the R environment more as we proceed, it’s a good idea to start with a best practice action common in data science — always create and work from a working folder. This can be a local folder on your computer or pointed to a folder in your cloud storage. On my mac I usually create a folder on the desktop, example BI-311, and point to that as my working folder for a project. Now, we need to point R to use the working folder — we do this at start of each R session (or modify some code R needs during start up to always point to the folder — for now, we leave that for a later exercise).
Once R is installed on your computer, start R as you would any program on your computer. For example, the icon for the R.app as it appears in the dock on a MacBook is shown in Figure 2.
Figure 2. R.app icon shown on a MacBook dock.
To point R to our working folder, there are several options. For now, we’ll go with writing and submitting a simple function in R. Recall that R has a command-line. The R prompt appears on the command line in the RGUI as the greater-than typographical symbol “>” at the beginning of a line (Fig 2). The prompt is returned by R to indicate the interpreter is ready to accept the next line of code.
First, discover where R is pointing to by submitting (type the command exactly as written then select keyboard shortcuts on Windows enter, or on macOS return key) the function getwd() at the prompt.
Note 3: Unfamiliar with keyboard shortcuts? I created a page just for you at Keyboard shortcuts in Mike’s Workbook for Biostatistics.
Ready to
On my MacBook, R returns
> getwd()
[1] "/Users/[username]/Documents"
To point to my working folder, I submit setwd("/Users/[username]/Desktop/BI311". When I run getwd() again, R returns the update
> getwd()
[1] "/Users/[username]/Desktop/BI311"
Note 4: Windows users will recognize that, unlike macOS and Linux, they will need to write paths with the backslash, not the forward slash. This is discussed further in Mike’s Workbook.
[username] is just a placeholder here — no reason to share my actual user name!
Ready to do some work?
R coding practices in this book and in the companion workbook roughly follow guidance outlined in a September 2018 R-Bloggers post, “R Code — Best practices,” by The R Trader. Of note, naming conventions: variables are nouns, variable names are written in lowerCamelCase; functions are verbs, function names are period separated, eg, my.function; script file names all end with .R and are written snake_case.R. Comments, preceded by # and a single space, eg, # A brief comment, are sparingly included in code, but reserved for explanatory sentences in the text. We use <- and not = for assignment statements.
Where discussion requires reference to instructions on use of the R programming language, R code (instructions) the user needs to enter at the R prompt are shown in code blocks.
Courier New font within a “code block.”Until you write your own functions, the general idea is, you enter one set of commands at a time, one line at a time. For example, to create a new variable, curryPoints, containing points scored by the NBA’s Steph Curry during the 2016 playoffs, type the following code at the R prompt (displayed as >, the “greater than” sign)
curryPoints <- c(24,6,40,29,26,28,24,19,31,31,11,18,19).
and to obtain the mean, or arithmetic average, for curryPoints at the R prompt type and enter
.
mean(curryPoints).
Output from R function mean will look like the following
.
[1] 24.42857.
Functions in R, or any other data science programming language, are intended to automate a task.
Note 5: A good data management habit — store the variable as an R object called a data.frame.
df.curryPoints <- data.frame(curryPoints)
The R prompt appears in the RGUI as the greater-than typographical symbol “>” at the beginning of a line (Fig 3). The prompt is returned by R to indicate the interpreter is ready to accept the next line of code.
Figure 3. The R GUI on a macOS system; red arrow points to the R prompt.
Note 6: We just demonstrated one of several ways data can be brought into an R session, by creating a data.frame directly from a vector. Other methods include
- Reading a text file from your computer, eg, CSV, by
read.csv() - Importing a spreadsheet (Excel file) from your computer
using readxl::read_excel() - Entering small datasets directly using
read.table()with thetext= argument
Everything that exists is an object.
.
A brief programmer’s note — John M. Chambers, creator of the S programming language and a member of the R-project team, once wrote that sub-header phrase about R and objects. What that means for us: programming objects can be a combination of variables, functions, and data structures. During an R session the user creates and uses objects. The ls() function is a useful R command to list objects in memory. If you have been following along with your own installed R app, then how many objects are currently available in your session of R? Answer by submitting ls(). Hint: the answer should be one object.
A routine task during analysis is to calculate an estimate then use the result in subsequent work. For example, instead of simply printing the result of mean(curryPoints), we can assign the result to an object.
myResult <- mean(curryPoints)
.
To confirm the new object was created, try ls() again. And, of course, there’s no particular reason to use the object name, myResult, I provided! Like any programming language, creating good object names will make your code easier to understand.
When you submit the above code, R returns the prompt, and the result of the function call is not displayed. View the result by submitting the object’s name at the R prompt, in this case, myResult. Alternatively, a simple trick is to string commands on the same line by adding ; (semicolon) at the end of the first command. For example,
myResult <- mean(curryRoints); myResult
.
Objects created during an R session, like curryPoints, are stored in memory within the Global Environment. To remove an object, use the command rm(myVariable). Why remove objects during an R session? If you are attempting multiple tasks in a homework assignment, removing unneeded objects helps maintain a clean and organized workspace, improving code readability and reducing the chance of accidental errors.
Write your code as script.
.
While it is possible to submit code one line at a time, a much better approach is to create and manage code in a script file. A script file is just a text file with one command per line, but potentially containing many lines of code. Script files help automate R sessions. Once the code is ready, the user submits code to R from the script file.
Note 7: Working with scripts eliminates the R prompt, but code is still interpreted one line at a time. The user does not type the prompt in a script file.
Figure 4 shows how to create a new script file via the RGUI menu: File → New script.

Figure 4. Screenshot of drop down menu RGUI, create new script, Windows 11.
The default text editor opens (Fig 5).
Figure 5. Screenshot of portion of R Script editor, Windows 11. A simple R command is visible.
Submit code by placing cursor at start of the code or, if code consists of multiple lines, select all of the code, then hit keyboard keys Ctrl + R (Windows 11) or for macOS, Cmd + Enter.
I recommend starting with a clean environment, by using rm(list = ls()) at the beginning of a script.
By default, save R script files for reuse with the file extension .R, eg, my_script.R. Because the scripts are just text files you can use other editors that may make coding more enjoyable (see RStudio in particular, but there are many alternatives, some free to use. A good alternative is ESS).
Install R Commander package.
.
By now, you have installed the base package of the R statistical programming language (see for detailed instructions). The base package contains all of the components you would need to create and run data analysis and statistics on sets of data. However, you would quickly run into the need to develop functions, to write your own programs to facilitate your work. One of the great things about R is that a large community of programmers have written and contributed their own code; chances are high that someone has already written a function you would need. These functions are submitted in the form of packages. Throughout the semester we will install several R packages to extend R capabilities. R packages discussed in this book are listed at R packages of the Appendix.
Our first package to install is R Commander, Rcmdr for short. R Commander is a package that adds function to R; it provides a familiar point-and-click interface to R, which allows the user to access functions via a drop-down menu system (Fox 2017). Thus, instead of writing code to run a statistical test, Rcmdr provides a simple menu driven approach to help students select and apply the correct statistical test. R Commander also provides access to Rmarkdown and a menu approach to rendering reports.
install.packages("Rcmdr")
.
In addition, download and install the plugin
install.packages("RcmdrMisc")
See Install R Commander for detailed installation instructions.
Note 8: Plugins are additional software which add function to an existing application.
Start R Commander.
.
After installing Rcmdr, to start R Commander, type library(Rcmdr) at the R prompt and enter to load the library
library(Rcmdr).
On first run of R Commander you may see instructions for installing additional packages needed by R Commander. Accept the defaults and proceed to complete the installation of R Commander. Next time you start R commander the start up will be much faster since the additional packages needed by R Commander will already be present on your computer.
Note that you don’t type the R prompt and, indeed, in R Commander Script window you won’t see the prompt (Fig 6). Instead, you enter code in the R Script window, then click “Submit” button (or Win11: Ctrl+R or for macOS: Cmd+Enter), to send the command to the R interpreter. Results are sent to Output window (Fig 6).
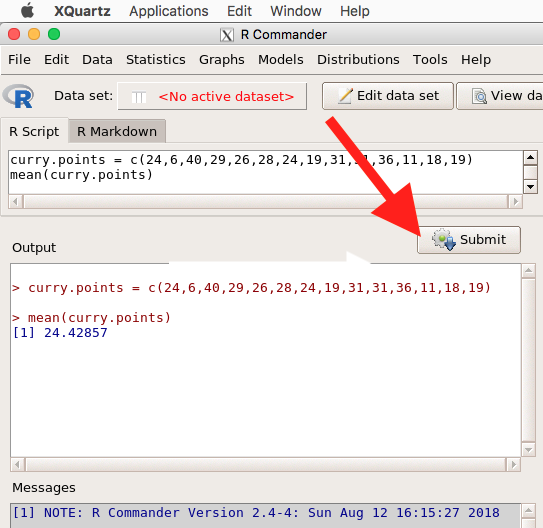
Figure 6. The windows of R Commander, macOS. From bottom to top: Messages, Output, Script (tab, Markdown) Rcmdr ver. 2.4-4.
Figure 6 shows how the R Commander GUI looks on a macOS computer. The look is similar on Microsoft Windows 11 machines (Fig 7).
Figure 7. The windows of R Commander, Win11. From bottom to top: Messages, Output, Script (tab, R Markdown) Rcmdr ver. 2.5-1.
We use R Commander because it gives us access to code from drop-down menus, which at least initially, helps learn R (Fox 2005, Fox 2016). Later, you’ll want to write the code yourself, and RStudio provides a nice environment to accomplish your data analysis.
Improve Rcmdr experience.
Windows users: R Commander works best in Windows if SDI option is set. This can be accomplished during R installation (“Startup options” popup, change from default “No” to “Yes” to customize), but you can also change after installing R. Win11 users should change from MDI to SDI — from one big window to separate windows — (see Do explore settings, WinPC see Fig 9; macOS see Fig 10). The downside of SDI is that while multiple Windows may appear during an R session, one or more windows may be hidden by an open window. For example, plots will popup in a new window and may be obscured by the Rcmdr window if full screen. A simple trick to view active windows on Win11 is to use the keyboard shortcut s Alt + Tab to view and cycle between windows. What about SDI and RStudio? RStudio experience will be similar whether MDI (default) or SDI was selected.
macOS users: To improve R Commander performance, turn off Apple’s app nap (see Do explore settings, Figures 6), which should improve a Mac user’s experience with R Commander and other X Window applications.
Complete R setup by installing LaTeX and pandoc for Markdown.
.
LaTeX is a system for document preparation. pandoc is a document converter system. Markdown is a language used to create formatted writing from simple text code. Once these supporting apps are installed, sophisticated reports can be generated from R sessions, by-passing copy and paste methods one might employ. See Install R Commander for instructions to add these apps.
Note 9: If you successfully installed R and are running R Commander, but may be having problems installing pandoc or LaTeX, then this note is for you. While there’s advantages to getting pandoc etc working, it is not essential for BI311 work.
Assuming you have Rcmdr and RcmdrMisc installed, and if you have started Rcmdr and have it up and running, then we can skip pandoc and LaTeX installation and use features of your browser to save to pdf.
R Markdown by default will print to a web page (an html document called RcmdrMarkdown.html) and display it in your default browser. To meet requirements of BI311 — you submit pdf files — we can print the html document generated from “Generate Report” in R Commander to a pdf.
- Chrome browser, right click in the web page, from the popup menu select Print, then change destination to Save as pdf.
- Safari browser, right click then select Print page (or if an option, Save page as pdf), then find at lower left find PDF and option to Save as PDF.
R Markdown.
.
Markdown is a syntax for plain text formatting and is really helpful for generating clean html (web) files. R Commander also helps us with our reporting. R Markdown is provided as a tab (Fig 6, Fig 7). Provided you have also installed pandoc on your computer, you can also convert or “render” the work into other formats including pdf and epub. Unsure if your computer has pandoc installed? If you are unsure than most likely it is not installed. 😁 Rcmdr provides a quick check — go to Tools and if you see Install auxiliary software, then click on it and a link to pandoc website to find and download installation file. You can also confirm install of pandoc by opening a terminal on your computer (eg, search “terminal” on macOS or “cmd” on Win11), then enter pandoc –version at the shell prompt. Figure 8 shows version pandoc is installed on my Win11 HP laptop.
Figure 8. Screenshot of terminal window (cmd) on win11 computer, checking for installed pandoc on a win10 pc.
Enter your R code in the script window, submit your code, and your results (code, output, graphs) are neatly formatted for you by Markdown. Once the Markdown file is created in R Commander, you can then export to an html file for a a web browser, an MS Word document, or other modes.
Do explore settings!
.
After installation, R and R Commander are ready to go. However, students are advised that a few settings may need to be changed to improve performance. For example, on Win11 PCs, R Commander recommends changing from the default MDI (Multiple Document Interface) to SDI (Single Document Interface). Check the SDI button via Edit menu, select GUI preferences menu. Click save, which will make changes to .RProfile, then exit and restart R. Check to make sure the changes have been made (Fig 9).
Figure 9. Screenshot of GUI preferences settings after changing from default MDI to SDI, win10
For macOS users, both R and Rcmdr will run better if you turn off Apple’s power saving feature called nap. From Rcmdr go to Tools and select Manage Mac OS X app nap for R.app… (Fig 10).
Figure 10. Screenshot Rcmdr Tools popup menu, macOS 10.15.6
A dialog box appears; select off to turn off app nap (Fig 11).
Figure 11. Screenshot Rcmdr Set app nap dialog box, macOS 10.15.6
Exit R Commander.
.
Click on Rcmdr: File → Exit, then choose to exit from just R Commander, or both R Commander and R.
If you exit just R Commander or both R and R Commander, you’ll receive a pop-up request to confirm you want to quit R Commander (click yes), and a second prompt asking if you want to save your script. In general, select yes and then you’ll be able to take up where you left off. Similarly, if asked to save your workspace, choose no. If you save workspace, this creates an .RProfile text file with settings for how R and R Commander will behave the next time you start R. The file will be saved to your current working folder, which R will use the next time R starts. At least while you are getting started, you should avoid creating these .RProfile files.
As long as the current session of R is active, then the library for Rcmdr, as well as any other library loaded during the R session, is in memory. To start R Commander again while R is running, at the R prompt, type and submit
Commander()
Questions.
- Biostatistics students should work through my ten R lessons, A quick look t R and R Commander, available in Mike’s Workbook for Biostatistics.
- Students should also search Internet for R tutorials and R Commander tutorials. Find recent tutorials and work through several of them. We get better when we practice.
Quiz Chapter 1.1
A quick look at R and R Commander
Chapter 1 contents
.
- Getting started
- A quick look at R and R Commander
- Chapter 1 – References