16.3 – Data aggregation and correlation
Introduction
Correlations are easy to calculate, but interpretation beyond a strict statistical interpretation, eg, two variables linearly associated, may be complicated — caution is recommended. With respect to interpreting a correlation, caution and temperance is warranted. As previously discussed, “correlation is not causation,” is well known, but identifying when this applies to a particular analysis is not straight-forward. We introduced the problem of two variables sharing a hidden covariation which drives the correlation. In this section we introduce how correlations among grouped (aggregated) data may be quite different from the underlining individual correlations (cf Robertson 1950, Greenland 2001, Portnov et. al 2006).
Perfect (+1 or -1) correlation?
What if an estimated correlation value between two ratio scale variables turns out to be +1 or -1, the limits of the possible range of the correlation coefficient? Trivially, the reported value of one for the coefficient may be the result of rounding, it was actually 0.97. But, for argument’s sake, let’s assume the coefficient value was 1.0 to as many significant figures as the calculator may report. Another trivial possibility: suspect you’re looking at a case for which the two variables are the same thing, but on different scale. For example, the correlation between a range of temperatures measured in degrees Fahrenheit and then converted to degrees Celsius trivially will be +1.
Less trivially, a correlation of +1 or -1 may reveal that two variables are simply restatements of the same measured variable. Additionally, perfect correlation may reflect construction of a composite variable. Composite variables are examples of indexes, and are constructed from related variables by the researcher in order to better predict multivariate outcomes (see also Latent variables). Refs to add Diamantopoulos and Winklhofer 2001; Bollen and Diamantopoulos 2015
Data aggregation
Data aggregation or grouping refers to processes to group data in a summary form. Considerable public health data is presented this way. For example, CDC reports table after table of data about morbidity and mortality of United States of America population. Data are grouped by age, cities, counties, ethnicities, gender, and states and reports are generated to convey the status of health peoples. Similarly, education statistics, economic statistics, and statistics about crime are commonly crafted from grouped data of what originally was data for individuals.
Correlations between groups may yield spurious conclusions
Researchers interested in testing hypotheses like BMI is correlated with mortality (Flegal et al 2013, Kltasky et al 2017), or health disparities and ethnicity (Portnov et. al 2006), may use grouped data. In 16.2 we introduced the concept of spurious correlation. Correlations between grouped data may also mislead.
Consider the hypothesis that religiosity may deter criminal behavior. This hypothesis has been tested many times dating back to at least the 1940s (reviewed in Salvatore and Rubin 2018). Conclusions about religious beliefs range from negative association with criminal behavior to, in some reports, holding religious beliefs makes one more likely to commit crime. Testing versions of the hypothesis — what causes criminality in some individuals — among a variety of putative causal agents pops up through the history of biology research, arguably beginning with Galton. I hope you appreciate how challenging this would be to actually resolve — defining criminal behavior itself is laden with all kinds of sociology traps — and for a biologist, reeks of eugenics lore (Horgan 1993).
that all said, let’s proceed to test the religion-criminality hypothesis with aggregated data. The null hypothesis would be no association between crime statistics and numbers of churches. We can also ask about association between crime and non-religious or secular beliefs. I added numbers of Catholic churches and secular humanists groups for cities larger than 100K population by Internet search (FBI for crime statistics, Wikipedia for cities). Figure 1 and Figure 2 report crimes statistics aggregated by cities in the United States and by number of Catholic churches (Fig 1), and by number of secular humanists groups (Fig 2) in the same cities.
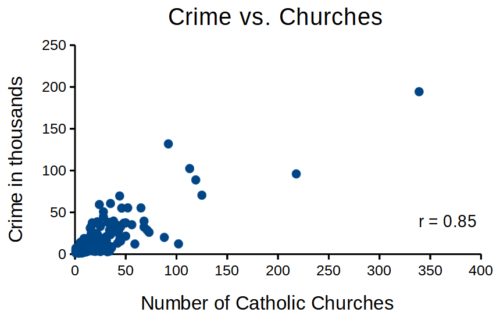
Figure 1. Scatterplot crime rates of cities by number of Catholic churches
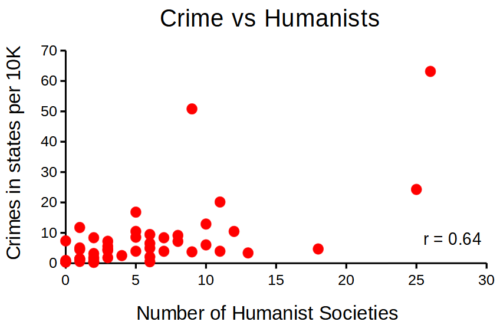
Figure 2. scatterplot crime rates of cities by number of secular humanist associations.
We’ll just take the numbers on faith (of course, we should think about the bunching around the origin — do we really think Internet search will get all of the secular groups, for example? Or is it really the case that several cities have no secular groups?). Both correlations were statistically different from zero, crime by churches (P < 0.001) and crime by secular groups (P < 0.001).
Now, having read Chapter 16.2 I trust you recognize immediately that there’s an important hidden covariate in common. Cities with small populations will have small numbers of crimes reported and smaller numbers of churches compared to large cities. Indeed, the correlation between population and crime for these cities was 0.89 and 0.97, respectively. However, after estimating the partial-correlations, we still have some explaining to do. For crime and churches, the partial correlation was +0.37 (p-value = 0.009); for crime and secular humanist groups, the partial correlation was -0.37 (p = 0.018). These results suggest that persons are more likely to commit crimes in cities with lots of Catholic churches whereas criminal behavior by individuals is less likely where secular humanist groups are numerous.
Before we start pointing fingers, the analysis presented here is a classic ecological fallacy. By grouping the data we lose information about the individuals, and it is the individuals to which the hypothesis applied. Thus, we are at risk of making incorrect conclusions by assuming that the individual is characterized by the group. The hypothesis remains challenging to test (how does one get a valid assessment of an individual’s religiosity? The hypothesis is challenging to test, but studies of individuals tend to find no association or a negative association between criminal behavior and religiosity (Salvatore and Rubin 2018). Crime statistics may underestimate criminal behavior, eg, embezzlement and other “white” crime), but a proper study would look to survey of individuals (Fig 3).
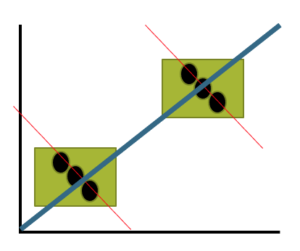
Figure 3. Illustration of ecological fallacy: positive association at level of groups (boxes, solid blue line), but negative association at level of individuals (black circles, red dashed lines).
Studies that use aggregate data test hypotheses about the groups, not about individuals in the groups. These studies are appropriate for comparing groups, eg, health disparities by ethnicity (Wang Kong et al 2022) or gender (Read and Gorman 2010; Cooper et al 2023), or comparisons among counties (eg, urban vs. rural) for medical resources (Anderson and Zimmerman 2024), or other “social determinates of health” (Crawfolrd 1977; Braveman and Gottlieb 2014), but one cannot conclude that the association is present for members of the group.
Bubble charts
Given we know about the covariation with population size, is there a better way to visualize the crime by number of churches and crime by number of humanist societies? One option is the bubble chart.
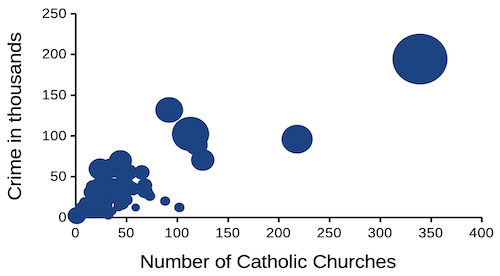
Figure 4. Bubble plot of data used to make Figure 1. Plot by LibreOffice Calc.
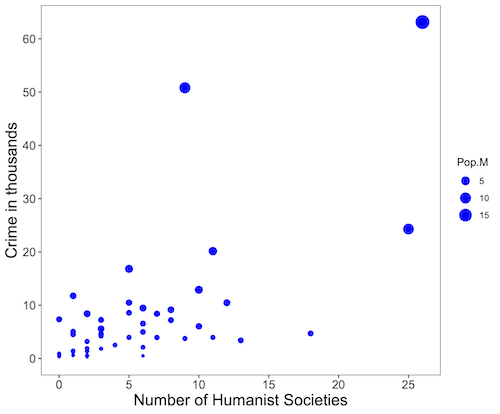
Figure 5. Bubble plot of data used to make Figure 2. Plot by ggplot2 package in R.
R code for Figure 5.
# STDHA site by Dr A. Kassambara https://www.sthda.com/english/

myPlot <- ggplot(humanists, aes(x = Humanist, y = Crime.K, size = Pop.M)) +
geom_point(color="blue", aes(size = Pop.M)) + theme_bw() + ylab("Crime in thousands") +
xlab("Number of Humanist Societies")

myPlot2 <- myPlot + theme(axis.title=element_text(size=16),
axis.text.x=element_text(size=12), axis.text.y=element_text(size=12),
panel.grid.major = element_blank(), panel.grid.minor = element_blank())

myPlot2 + scale_x_continuous(breaks=seq(0,30,5)) +
scale_y_continuous(breaks=seq(0,65,10))
Questions
1. Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
2. What’s the most likely statistical explanation for why there is an apparent correlation between rates of autism and childhood vaccination rates? See Davidson 2017.
3. For the following data set, calculate the Pearson product moment correlation and, separately, the Spearman rank correlation. Report the values of the coefficients and provide an interpretation of the results.
v1: 68, 72, 68, 69, 65, 76, 58, 62, 69, 67, 66, 71, 70
v2: 1.727, 1.829, 1.727, 1.753, 1.651, 1.93, 1.473, 1.575, 1.753, 1.702, 1.676, 1.803, 1.778
4. For a small data set on human males ages 24 to 59, the estimated correlation between weight and the calculated BMI index was 0.68. (BMI is an example of a composite variable.) Explain why the correlation between weight and BMI is not +1.
Quiz Chapter 16.3
Data aggregation and correlation
Chapter 16 contents
6.2 – Ratios and probabilities
Introduction
One common objective of a research project is comparison between quantities: one effective way to communicate a comparison is to construct a ratio. Ratios provide a standardized way to compare different data sets. The purpose of this page is introduce the wealth of types of ratios used for quantification of comparisons, from indexes to ratios.
Let’s review our definitions again. An event is some occurrence. As you know, a ratio is one number, the numerator, divided by another called the denominator. A proportion is a ratio where the numerator is a part of the whole. A rate is a ratio of the frequency of an event during a certain period of time. A rate may or may not be a proportion, and a ratio need not be a proportion, but proportions and rates are all kinds of ratios. If we combine ratios, proportions, and/or rates, we construct an index.
Ratios
Yes, data analysis can be complicated, but we start with this basic idea. Much of the statistics is based on frequency measures, eg, ratios, rates, proportions, indexes, and scales.
Ratios are the association between two numbers, one random variable divided by another. Ratios are used as descriptors and the numerator and denominator do not need to be of the same kind. Business and economics are full of ratios. For example, return on investment (ROI), eg, earnings equals net income divided by number of shares outstanding, the Price-Earnings, or P/E ratio, is the ratio of the price of a stock to the earnings per stock, as well as many others are used to summarize performance of a business, and to compare performance of one business against another.
Note 1: ROI also stands for region of interest — a sample in a data set identified by the analyst for a particular interest. Often refers to a specific area in an image.
Ratios are deceptively convenient way to standardize a variable for comparisons, ie, how many times one number contains another. For example, when estimating bird counts for different areas, or different birding effort (intensity, time searched), we may correct counts by accounting for area in which counts were made or the total time spent counting, for a per-unit ratio (Liermann et al 2004).
Practice: There were 1,326 day undergraduate students enrolled in 2014 at Chaminade University of Honolulu and the Sullivan Library added 8469 new items (ebooks, journals, etc,) to its collection during 2014. What is the ratio of new items per student?
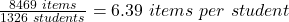
Data collected from Chaminade University website at www.chaminade.edu on 3 July 2014.
Practice: For another example, what is ratio of annual institutional aid a student at Chaminade University may expect to receive compared to a student at Hawaii Pacific University?
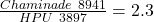
Thus, in 2014, Chaminade offered more than twice the institutional aid to its students then does HPU (both institutions are private universities, data from retrieved on 3 July 2014 from www.cappex.com).
Relative change, Fold-change and orders of magnitude
It’s common practice to report on the amount of change between two quantities recorded over time. Relative change (often percentage) describes change relative to an initial value. Relative change in root length b
To make percent increase (decrease), simply multiple 100%.
(1) 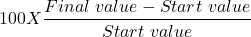
The ratio between two quantities, eg, to compare mRNA expression levels of genes from organisms exposed to different conditions, researchers may report fold-change. Fold change is often reported as log base 2 change.
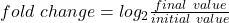
Why log base 2? Symmetry and ease of reporting. A doubling becomes +1 and a halving becomes -1. Without log transformation, doubling is +2, but having is +0.5.
Relative change is useful for reporting percent changes, fold change for ratios, although if the change is small in amount, then relative change can be misleading, eg, value goes from five to ten, then the relative change is 100%, but effectively, a very small change in absolute units. Similarly, fold change becomes a large, but likely meaningless comparison, if the denominator is close to zero.
An example of calculation of fold change. Rates of the expression from cells exposed to heavy metal divided by expression under basal conditions. Gene expression under different treatments may be evaluated by calculating fold-change as the log base2 of the ratio of expression of a gene for one treatment divided by expression of same gene from control conditions. Copper is an essential trace element, but excess exposure to copper is known to damage human health, including chronic obstructive pulmonary disease. One proposed mechanism is that cell injury promotes an epithelial-to-mesenchymal shift. In a pilot study (N.I.H. INBRE P20RR016467), we investigated gene expression changes by quantitative real-time polymerase chain reaction (qPCR) in a rat lung Type II alveolar cell line exposed to copper sulfate compared to unexposed cells. Record cycle threshold values, CT, for each gene, where CT is number of cycles required for the fluorescent signal to exceed background levels; CT is inversely proportional to amount of cDNA (mRNA) in the sample. Genes investigated were ECAD, FOXC2, NCAD, SMAD, SNAI1, TWIST, and VIM, with ATCB as reference gene. ECAD expression is marker of epithelial cells, whereas FOXC2, NCAD, SNAI1, TWIST, and VIM expression marker of mesenchymal cells. After calculating  values, geometric means of normalized values of three replicates each are shown in Table 1.
Note 2: The  is a relative change quantification that relates the PCR signal of the normalized gene of interest (GOI) transcript in a treatment group to another sample, eg, an untreated control. is now a widely applied method to analyze the relative changes in gene expression from real-time quantitative PCR experiments (relevant papers on the analysis method, Livak and Schmittgen (2001) and Schmittgen and Livak (2008) have been cited more than 230K times, Pubmed 2026. See also Rao et al (2013).)
Log-transform, introduced in Ch03.2, was used because gene expression levels vary widely on the original scale and any log-transform will reduce the variability. log-base 2 specifically was used for fold-change in particular because it is easy to interpret (eg, see discussion in Bergemann and Wilson 2011 and Corliss et al 2024), and provides symmetry (all log-transforms provide this symmetry). For example, log(1/2, 2) returns -1, while log(2/1, 2) returns +1. Thus, base 2, we see a decrease by half or doubling of original scale is a fold change of  . In contrast,
log(1/2, 10) returns -0.301, while log(2/1, 10) returns +0.301 — which is perfectly accurate, but deceptive to interpret.
log-base 2 is commonly employed to calculate the number of bits — binary digits — for a given number of values. For example, 8 bits (0 – 7), then log2(8-1), and R returns 2.807355. Round, add 1, and the number of bits is3. Related R code, if want to calculate and print te binary representation of of a number, eg, 8, try
myBits <- intToBits(8)
paste(as.character(myBits),collapse="")
On a more casual note, log-base 2 is useful to calculate number of rounds for a single-elimination playoff tournament, eg, NCAA men’s and women’s basketball tournament or March Madness (NCAA). As of 2025, 60 teams are invited, plus the four winning teams from four play-in games, for a total of 64 teams. The number of rounds is log2(64) and R returns 6. These six are referred to as First Round, Second Round, Sweet Sixteen, Elite Eight, Final Four, and the Championship Game. The play-in games are referred to as the”First Four.” The function draw_bracket() of R package SwimmeR can be used to plot a simple playoff bracket.
Table 1. Mean and fold change of gene expression values from qPCR for several genes from a rat lung cell line.*
| Control | Copper-sulfate | Fold change | |
| ECAD | 34.6 | 35.7 | 0.6 |
| NCAD | 28.5 | 24.0 | 27.2 |
| SMAD | 29.5 | 25.0 | 28.2 |
| SNAI1 | 25.5 | 28.1 | 0.2 |
| FOXC2 | 27.6 | 27.0 | 1.9 |
| VIM | 23.1 | 16.4 | 134.4 |
| TWIST | 25.1 | 22.9 | 5.6 |
* INBRE funding, P20RR016467.
At face value, following four hour exposure to copper sulfate in media, some evidence that the epithelial cell line adopted gene expression profile of mesenchyme-like cells. However, weakness of fold-change is clear from Table 1: the quantity is sensitive to small values. ECAD expression in the cell line is low, thus high numbers of PCR cycles (mean = 36) and treated cells not much fewer (mean = 34.4).
Note 3: Calculation of is included. Geomean CT were
| Control | CuSO4 | |
| ACTB | 32.2 | 32.5 |
| NCAD | 28.5 | 24.0 |
For control cells, 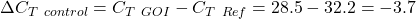
For treatment cells, 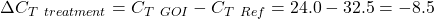
and 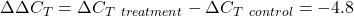
log2, 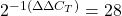
table value differs by rounding
Orders of magnitude
In addition to fold change, order of magnitude is another common way to compare quantities. While fold change returns the multiplier between two numbers, order of magnitude generally refers to differences in multiples of ten, logarithmic.
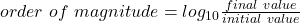
Thus, a difference of one order of magnitude is the number multiplied by 101, three orders of magnitude is the number multiplied by 103, and so on. A change from 10 to 100 is a one order of magnitude increase; the same change, 10 to 100, is a ten-fold change. It’s a difference of scale. If a person’s salary increases by 3%, from $49K to $50,470, reporting this as an “order of magnitude” increase is nonsensical as a communication device (magnitude of change is just 0.01). By contrast, fold change for the same increase would be 1.03 — also indicative of a negligible increase, but a cleaner representation.
Rates
Rates are a class of ratios in which the denominator is some measure of time. For example, the four year graduation rate of some Hawaii universities are shown in Table 2.
Table 2. Percent students graduation with bachelor’s degrees within four years or six years (cohort 2014, data source NCES.ed.gov)
| School | Private/Public | Four-year, Percent graduation |
Six-year, Percent graduation |
| Chaminade University | Private (non-profit) | 43 | 58 |
| Hawaii Pacific University | Private (non-profit) | 31 | 46 |
| University of Hawaii – Hilo | Public | 15 | 38 |
| University of Hawaii – Manoa | Public | 35 | 62 |
| University of Hawaii – West Oahu | Public | 16 | 39 |
| University of Phoenix | Private (for profit) | 0 | 19 |
Examples of rates
Rates are common in biology. To name just a few
- Basal metabolic rate (BMR), often measured by indirect calorimetry, reported in units kiloJoules per hour.
- Birth rates and mortality (death) rates, components of population growth rate.
- Extinction rate, how often over a given time species go extinct.
- Growth rate, which may refer to growth of the individual (somatic growth rate), or increase of number of individuals in a population per unit time.
- Molecular clock hypothesis, rate of amino acid (protein) or nucleotide (DNA) substitution is approximately constant per year over evolutionary time.
- Mutation rate, frequency of new mutations in a DNA sequence of an organism over time.
- Photosynthetic rate, convert light energy into chemical energy.
- Phred quality score, error rates of incorrectly called nucleotide bases by the sequencer.
Proportions
Proportions are also ratios, but they are used to describe one part to the whole. For example, 902 women (self-reported) day undergraduate students enrolled in 2014 at Chaminade University in Honolulu, Hawaii.
Practice: Given that the total enrollment for Chaminade in 2014 was of 1,326, calculate the proportion of female students to the total student body.

More practice: A common statistic in agriculture is germination percentage, count the number of seeds that sprout over a period of time divided by total number of seeds planted multiplied by 100. Figure 1 shows an example of a germination trial for five tomato seeds. Seed in position 3 (left to right 1 – 5) failed to germinate, whereas the other four seeds display range of seedling growth. (A seed coat is observed next to plant 2.)
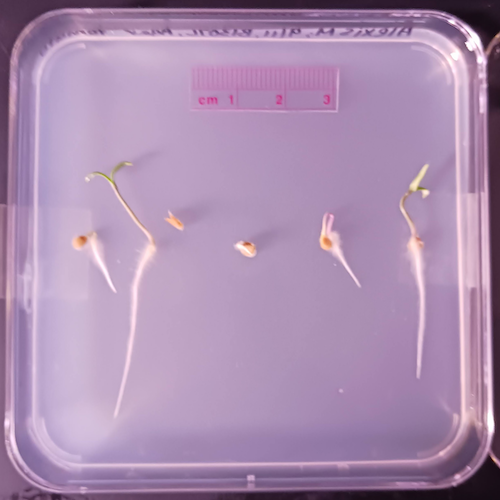
Figure 1. Example planting of five tomato seeds, day 5, on agar Petri dish (M. Dohm).
Observations conducted over 10 days. Germination defined as evidence of radicle by day 10. Data collected by student for biostatistics project. A random sample of results from three plates is presented in Table 3.
Table 3. Germination of tomato seeds on agar Petri dishes.
| Plate* | 1 | 2 | 3 | 4 | 5 |
| 18 | Yes | No | Yes | Yes | Yes |
| 13 | Yes | Yes | Yes | No | Yes |
| 20 | No | Yes | Yes | Yes | Yes |
* Random sample of three plates drawn from among 30 plates.
We calculate the percent germination for the 15 seeds planted as

Thus, for the sample of plates the germination percent was 80%, which, coincidently, is the same result if germination percent was calculated for the five seeds displayed in Figure 1.
Beginning in Chapter 7 – Probability, Risk Analysis, we introduce and use a number of proportions, for example incidence and prevalence are proportions, as is PPV — positive predictive value. Sensitivity and specificity are both proportions and also qualified as indexes.
Comparing proportions
In some cases you may wish to compare two proportions or two ratios. The hypothesis tested is the difference between the two ratios, and the test is if the confidence interval of the difference includes zero. If it does, then we would conclude there is no statistical difference between the two proportions. In R, use the prop.test function. For example, 63 women were on team sport rosters at Chaminade in 2014, a proportion of 59% of all student athletes (n = 106). Recall from the example above that women were 68% of all students at Chaminade University. Title IX compliance requires that a university “maintain policies, practices and programs that do not discriminate against anyone on the basis of gender” (NCAA, INCLUSION AND BELONGING Championing Women in Sports). In terms of athletic programs, then, universities are required to provide participation opportunities for women and men that are substantially proportionate to their respective rates of enrollment of full-time undergraduate students.
Consider Chaminade University: Is there a statistical difference between proportion of women athletes and their proportion of total enrollment? We introduce statistical inference in Chapter 8, but for now, this is a test of the null hypothesis that the difference between the two proportions is zero.
At the R prompt type (remember, anything after the # sign is a comment and ignored by R).
women = c(62,902)  #where 62 is the number of women athletes and 902 is the number of women students
students = c(106,1326)  #106 is the number of student athletes and 1326 is all students
prop.test(women,students)  #the default is a two-tailed test, ie, no group differences
And R returns
2-sample test for equality of proportions with continuity correction
 data: women out of students
X-squared = 3.6331, df = 1, p-value = 0.05664
alternative hypothesis: two.sided
95 percent confidence interval:
 -0.197532407 0.006861073
sample estimates:
 prop 1 prop 2
0.5849057 0.6802413
What is the conclusion of the test?
When you compare two groups, you’re asking whether the two groups are equal (the null hypothesis). Mathematically, that’s the same as saying the difference between the two groups is equal to zero.
First check the lower and upper limits of the confidence interval. A confidence interval is one way to report a range of plausible values for an estimate (see Ch 7.6 – Confidence intervals). It’s called a confidence interval because a probability is assigned to the range of values; a 95% confidence interval is interpreted as we’re 95% certain the true population value is somewhere between the reported limits. For our Chaminade University Title IX question, recall that we are asking whether the value of zero is included. The lower limit was -0.1975 and some change; the upper limit was 0.0068 and some change. Thus, zero is included and we would conclude that there was no statistical difference between the two proportions.
The second relevant output to look at is the p-value, or probability value. If the p-value is less than 5%, we typically reject the tested hypothesis. We will talk more about p-values and their relationship to inference testing in Chapter 8; for now, pay attention to the confidence interval (introduced in Chapter 3.4); if zero is included, then we conclude no substantial differences between the two proportions.
Indexes
Indexes are composite statistics that combine indicators. They condense complex diagnostic performance data into a single, universally understood numerical indicator.
Indexes are common in biology, and well-known business and economics indexes are reported on every day, eg, Dow Jones Industrial average combines stock prices from 30 companies listed on the New York Stock Exchange and the CPI, or Consumer Protection Index, constructed by the US Bureau of Labor Statistics from a “market basket of consumer goods and services, used by the government and other institutions to track inflation. The CPI itself is made up of numerous indexes to account for regional price differences and other factors.
Some indexes presented in this book include
- Grade point average
- Body Mass Index (BMI)
- Comet assay indexes (tail intensity, tail length, tail moment) are used to assess DNA damage among organisms exposed to environmental contaminants (eg, Mincarelli et al., 2019).
- Encephalization index, ratio of brain to body weight among species. Used to compare cognitive abilities.
- Sensitivity, specificity, NNT — number needed to treat, odds-ratio and RRR and related. See Chapter 7.1 – Probability, Risk Analysis.
- Species diversity indexes, measures of species richness and abundance. See Chapter 20.8.
Scales
Agreement scales for surveys, eg, Likert scale or sliding scale (Sullivan and Artino 2013). For example, after learning about Theranos, students were asked:
How serious is this violation in your opinion?
| Not serious
0 |
Slightly serious
0 |
Moderately serious
2 |
Serious
4 |
Very serious
19 |
a 5-point scale.
Although an intuitive measure, how fast can an individual run, challenging to determine whether individual’s performance is at physiological maximum. Particularly for measures of performance capacity that involves behavior (motivation), may apply a race quality scale (eg., binary scale “good” or “bad” Husak et al 2006).
These examples reflect ordinal scales. Many of the nonparametric tests discussed in Chapter 15 are suitable for analysis of scales.
Limitations of ratios
Although the indexes may be easy to communicate, statistically, indexes have many drawbacks. Chief among these, variation in ratios may be due to change in numerator or denominator. Ratios and any index calculated by combining ratios seem simple enough, but have complicated statistical properties. Over the years, several authors have made critical suggestions for use of ratios and indexes. Some key references are Packard and Boardman (1988), Jasienski and Oikos (1999), Nee et al (2005), and Karp et al (2012). For example, ratios, computing trait value by body weight, are often used to compare some trait among individuals or species that differ in body size. However, this normalization attempt only removes the covariation between size and the trait if there is a 1:1 relationship between size and the trait. More typically, relationship between the trait and body size is allometric, ie, the slope is not equal to one. Thus, ratio will over-correct for large size and under-correct for small size. The proper solution is to conduct the comparison as part of an analysis of covariance (ANCOVA, see Chapter 17.6).
Example
Which is the safer mode of travel: car or airplane?
The following discussion covers travel safety in the United States of America for a typical year, 2000*.
Note 4: *The following discussion excludes the 241 airline passenger deaths associated to the terrorist attacks of September 11 2001 in the USA; the NTSB also “…exclude(s illegal acts) for the purpose of accident rate computation. It also does not include considerations of 2020-2021 and effects of the COVID-19 pandemic on numbers of flights. The purpose of this discussion is not to convince you about the safety of modes of travel. Moreover, the following analysis is not necessarily the proper way to frame or analyze risk, but, rather, the purpose of this discussion is to highlight the impact of assumptions on estimating risk.
Between 2000 and 2023, there were 779 deaths associated with accidents of major air carriers in the USA. Year 2009 was the last multiple-casualty crash of a major U.S. carrier (Colgan Air Flight 3407); between 2010 and 2021, two fatal accidents, two fatalities were reported.
We’ve all heard the claim that it’s much safer to fly with a major airline than it is to travel by car (eg, Flying is getting scary. But is it still safe? CNN June 20, 2024). There are a variety of arguments, but one statistical argument goes as follows. In 2000 in the United States, 638,902,993 persons traveled by major air carrier, whereas there were 190,625,023 licensed drivers. In 2000, 92 persons died in air travel (again, major carriers only), whereas 37,526 persons died in vehicle crashes (includes drivers and passengers). Thus, the risk of dying in air travel is given as the proportion  , or 1.44e-07 (0.000014%), whereas the comparable proportion for death by motor vehicle is
 , or 1.97e-04 (0.0197%).
In other words, we can expect one death (actually 1.4) for every ten million airline passengers, but 20 deaths (actually 19.7) for every one hundred thousand licensed drivers. Thus, flying is a thousand times safer than driving (actual result 1,367 times; divide the rate of motor vehicle-caused deaths for licensed drivers by the rate for airlines). Proportions are hard to compare sometimes, especially when the per capita numbers differ (ten million vs. 100,000 in this case).
We can put the numbers onto a probability tree and get a sense of what we are looking at (Fig 2).
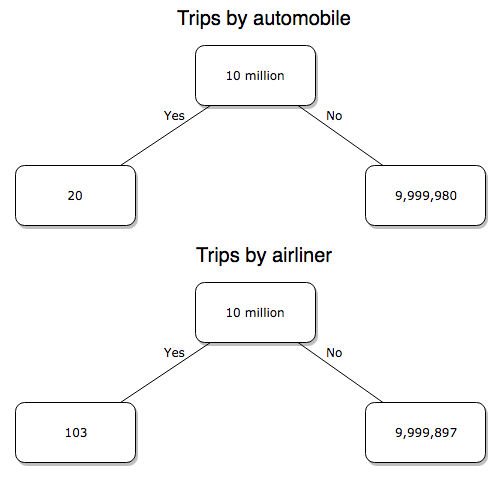
Figure 2. A probability tree to help visualize comparison of deaths (“yes”) by car travel and by airline travel in the United States for the year 2000.
Comparing rates and proportions
Without going into the details, we will do so in Chapter 9 Inferences on Categorical Data, comparing two rates is a chi-square, χ2, contingency table type of problem. More specifically, however, it is a binomial problem (Chapter 3.1, Chapter 6.5); there are two outcomes, death or no death, and we can describe how likely the event is to occur as a proportion. Because the numbers are large, we can use rely on the normal distribution for comparing the two proportions. We’ll explain this more in the next chapters, but for now it may be enough to present the equation for the comparison of two proportions under the assumption of normality, proportion z test.
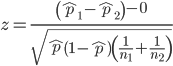
and the null hypothesis (see Chapter 8) tested as that the two proportions are equal. This may be written as
H0 : p1-p2=0
We can assign statistical significance to the differences in events for the two modes of travel under this set of assumptions. Rcmdr has a nice menu-driven system for comparing proportions, but for now I will simply list the R commands.
At the R prompt type each line then submit the command.
total = 100000000
prop.test(c(19700,14),c(total,total)))
And the R output
prop.test(c(19700,14),c(total,total))

    2-sample test for equality of proportions with continuity
    correction

data:  c(19700, 14) out of c(total, total)
X-squared = 19658, df = 1, p-value < 2.2e-16
alternative hypothesis: two.sided
95 percent confidence interval:
 0.0001940984 0.0001996216
sample estimates:
  prop 1   prop 2
1.97e-04 1.40e-07
There’s a bit to unpack here. R is consistent; when it reports results of a statistical test, it typically returns the value of the test statistic (χ2 = 19658), the degrees of freedom for the test (df = 1), and the p-value (< 2.2e-16).
prop.test() were calculated by the Wilson Score method not the Wald method. While both are parametric tests and therefore sensitive to departures from normality (see Chapter 13.3), formulation of Wilson score method makes fewer assumptions (involving approximations of the population proportions) and therefore is considered more accurate.By convention in statistics, if a p-value, where “p” stands for probability, is less than 5%, we would say that our results are statistically significant from the null hypothesis. Looks pretty convincing to me, the difference of 19,700 deaths compared to 14 deaths is clearly different by any criterion and by the results of the statistical test, the p-value is several orders of magnitude smaller than 5%.
Safer to fly. By far, not even close. And similar conclusions would be reached if we compare different years, or averages over many years, or if we used a different way to express the amount of travel (eg, miles/year) by these modes of transportation.
Are you convinced, really? Is it safer to fly?
Let’s try a little statistical reasoning — what assumptions did I make to do these calculations? We recognize immediately that many more people travel by car: that there are way more cars being driven then there are airline planes being flown. The question then is, have we properly adjusted for this difference? Here are a few considerations. My source for the numbers is the NTS 2001 book published by the U.S. Department of Transportation (U.S. Department of Transportation). We are conducting a risk analysis, and the first step is to make sure that we are comparing “apples with apples.” Here are two alternative solutions that at least compare, “Red Delicious” apples with “Macintosh” apples.
Option 1. There are many, many more licensed drivers than there are licensed commercial airline pilots. The standard comparison offered in the background above compared deaths per licensed car driver, but a different metric for air travel, the rate per passenger. This isn’t as bad of a comparison as it may seem — after all, the majority of deaths in car accidents are of the driver themselves. But it isn’t that hard to make the direct comparison — just find out how many commercial pilots there are — a direct comparison with licensed car drivers (stated above as 190,625,023). From the FAA we see that in 2009 there were 125,738 persons with commercial certificates. Since there are only 20 major airline carriers in the United States now (a few more were active in 2000, but we’ll put this aside), the number of licenses is an over estimate of the actual number we want — how many pilots of commercial airlines — but lets use this number for starters — after all, just because a person has a drivers license doesn’t mean they drive or ride in a car.
Number of deaths/yr: Let’s use 2000 data, a typical year prior to 9/11 (and excluding the Covid-19 pandemic). Airlines: 92 deaths; motor vehicles (includes passenger cars, trucks, etc, but not motorcycles): 37,526 deaths (drivers = 25,567; passengers = 10,695; 86 others).
Which mode of travel is riskier? I get a rate a rate of 7.3 X 10⁻⁴ deaths per commercial pilot, or
92125738
compared to a rate for car drivers of 1.97 X 10⁻⁴ deaths.
To summarize what we have so far, I get a result that suggests car travel is almost four times safer
7.3 x 10-41.97 x 10-4→7.31.97 = 3.7
then traveling by commercial airliner. In whole numbers, these results translate to seven deaths for every 10,000 commercial pilots compared to two deaths for every 10,000 licensed car drivers (Fig 3).
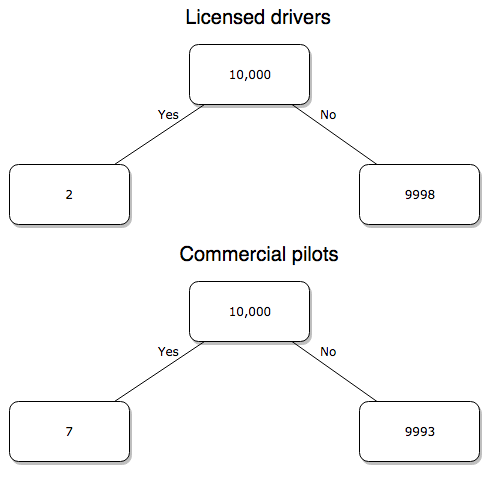
Figure 3. Comparing totals of deaths adjusted by numbers of licensed drivers and by licensed commercial airline pilots in the United States.
R work follows. Enter and submit each command on a separate line in the script window
total = 10000
prop.test(c(2,7),c(total,total))
And the R output
prop.test(c(2,7),c(total,total))

    2-sample test for equality of proportions with continuity
    correction

data:  c(2, 7) out of c(total, total)
X-squared = 1.7786, df = 1, p-value = 0.1823
alternative hypothesis: two.sided
95 percent confidence interval:
 -0.001187816  0.000187816
sample estimates:
prop 1 prop 2
 2e-04  7e-04
What’s happened? The p-value (0.1823) is not less than 5% and so we would conclude under this scenario that there is no difference between the proportions of deaths between the two modes of travel. Let’s keep going.
Option 2. There are many, many more cars on the road then there are airplanes flying commercial passengers. The standard comparison offered in the background information above identified death rates per individual driver, but used a different metric for airline travelers (number of deaths per passenger), which confuses individuals with travelers: what we need is the number of individuals that traveled by airliner, not the total number of passengers (which is many times higher, because of repeat flyers). How can we make a fair comparison for the two modes of travel? Most people never fly whereas most people drive (or ride in a car) frequently in the United States. To me, risk of travel might be better expressed in terms of a per trip rate. I want to know, what are my chances of dying each time I get into my car versus each time I fly on a commercial jet in the United States?
Number of trips/yr. For airlines, I use the number of departures (2000 = 8,951,773). But for cars, we need to decide how to get a similar number. It’s not available directly from the DOT (and would be difficult to get — studies with randomly selected drivers can yield as many as 5 trips per day for licensed drivers). I took the number of licensed drivers and bound the problem — at the low end, let’s say that only 2 trips per week (eg, 50 weeks) are taken by licensed drivers (100 trips); at the upper end, let’s take 2 trips per day per week, or 500 trips/year. Thus, at the low end, we have 1.91 X10¹⁰ trips per year; at the upper end, 9.53 X 10¹⁰ trips per year.
Which mode of travel is riskier? Using the number of deaths/yr listed above in Option 1, I get a rate of 1.03 X 10⁻⁵ deaths/trip for air carriers
928.95 x 10⁶
compared to a rate of 1.97 X 10⁻⁶ deaths/trip for cars (lower bound) or 3.9 X 10⁻⁷ deaths/trip for cars (upper bound). Here’s what the numbers look for in a tree (taking the lower number of trips per year for cars, Fig 4).
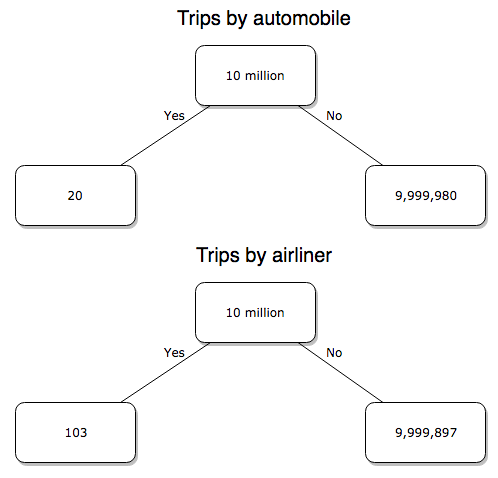
Figure 4. Comparing totals of deaths adjusted by numbers of car trips and by numbers of airline trips in the United States.
R work follow
total = 10000000
prop.test(c(20,103),c(total,total))
And the R output
prop.test(c(20,103),c(total,total))

    2-sample test for equality of proportions with continuity
    correction

data:  c(20, 103) out of c(total, total)
X-squared = 54.667, df = 1, p-value = 1.428e-13
alternative hypothesis: two.sided
95 percent confidence interval:
 -1.057370e-05 -6.026305e-06
sample estimates:
  prop 1   prop 2
2.00e-06 1.03e-05
Now we have another really small p-value (1.428e-13), which suggests a statistically significant difference between the modes of air travel, but the difference in deaths is switched. I now have a result that suggests car travel is much safer than traveling with a commercial airliner! These calculations suggest that you are as much as 26 (upper bounds, five times for lower bounds) times more likely to die from a plane crash then you are behind the wheel. In whole numbers, these results indicate one death for every 100,000 airline flights compared to 1 death for every 500,000 (lower estimate) or 2,500,000 car trips!
Do I have it right and the standard answer is wrong? As Lee Corso used to say on ESPN’s College GameDay program, “Not so fast, my friend!” (Wikipedia). Mark Twain was right to hold the skeptic’s view. Begin by listing the assumptions and by checking the logic of the comparisons (there are still holes in my logic!!). For one, if I am considering my risk of dying by mode of travel, it is far more likely that I will be in a car accident than I will an airline accident, simply because I don’t travel by airline that much. When we consider lifetime risk, we can see why the assertion that it is “safer to fly than drive” is true — we’re far more likely to belong to one of the reference populations involving automobiles (eg, those who drive frequently, for many years) than we are to be among the frequent flyers reference populations.
Questions
1. Review and provide your own examples for
- index
- rate
- ratio
- proportion
3. Like travel safety, we are often confronted by risk comparisons like the following: Which animal is more deadly to humans, dogs or sharks? Between the two, which lead to more hospitalizations in the United States? Work through your assumptions and use results from the International Shark Attack file.
- If a person lives in Nebraska, and never visits the ocean, how does a “shark attack” risk analysis apply? Is it a fair comparison to make between dog attacks and shark attacks? Why or why not.
4. Go to cappex.com/colleges and update institutional (gift) aid offered by Chaminade and HPU. Compare to University of Hawaii-Manoa.
5. Calculate percent increase for
- Annual atmospheric CO2 1980 and 2024.
Quiz Chapter 6.2
Ratios and probabilities
Chapter 6 content
- Introduction
- Some preliminaries
- Ratios and probabilities
- Combinations and permutations
- Types of probability
- Discrete probability distributions
- Continuous distributions
- Normal distribution and the normal deviate (Z)
- Moments
- Chi-square distribution
- t distribution
- F distribution
- References and suggested readings
5.5 – Importance of randomization in experimental design
Introduction
If the goal of the research is to make general, evidenced-based statements about causes of disease or other conditions of concern to the researcher, then how the subjects are selected for study directly impacts our ability to make generalizable conclusions. The most important concept to learn about inference in statistical science is that your sample of subjects upon which all measurements and treatments are conducted, ideally should be a random selection of individuals from a well-defined reference population.
The primary benefit of random sampling is that it strengthens our confidence in the links between cause and effect. Often after an intervention trial is complete, differences among the treatment groups will be observed. Groups of subjects who participated in sixteen weeks of “vigorous” aerobic exercise training show reduced systolic blood pressure compared to those subjects who engaged in light exercise for the same period of time (Cox et al 1996). But how do we know that exercise training caused the difference in blood pressure between the two treatment groups? Couldn’t the differences be explained by chance differences in the subjects? Age, body mass index (BMI), overall health, family history, etc?
How can we account for these additional differences among the subjects? If you are thinking like an experimental biologist, then the word “control” is likely coming to the foreground. Why not design a study in which all 60 subjects are the same age, the same BMI, the same general health, the same family … history…? Hmm. That does not work. Even if you decide to control age, BMI, and general health categories, you can imagine the increased effort and cost to the project in trying to recruit subjects based on such narrow criteria. So, control per se is not the general answer.
If done properly, random sampling makes these alternative explanations less likely. Random sampling implies that other factors that may causally contribute to differences in the measured outcome, but themselves are not measured or included as a focus of the research study, should be the same, on average, among our different treatment groups. The practical benefits of proper random sampling is that recruiting subjects gets easier — fewer subjects will be needed because you are not trying to control dozens of factors that may (or may not!) contribute to differences in your outcome variable. The downside to random sampling is that the variability of the outcomes within your treatment groups will tends to increase. As we will see when we get to statistical inference, large variability within groups will make it less likely that any statistical difference between the treatment groups will be observed.
Demonstrate the benefits of random sampling as a method to control for extraneous factors.
The study reported by Cox et al included 60 obese men between the ages of 20 and 50. A reasonable experimental design decision would suggest that the 60 subjects be split into the two treatment groups such that both groups had 30 subjects for a balanced design. Subjects who met all of the research criteria and who had signed the informed consent agreement are to be placed into the treatment groups and there are many ways that group assignment could be accomplished. One possibility, the researchers could assign the first 30 people that came into the lab to the Vigorous exercise group and the remaining 30 then would be assigned to the Light exercise group. Intuitively I think we would all agree that this is a suspect way to design an experiment, but more importantly, why shouldn’t you use this convenient method?
Just for argument’s sake, imagine that their subjects came in one at a time, and, coincidentally, they did so by age. The first person was age 21, the second was 22, and so on up to the 30th person who was 50. Then, the next group came in, again, coincidentally in order of ascending age. If you calculate the simple average age for each group you will find that they are identical (35.5 years). On the surface, this looks like we have controlled for age: both treatment groups have subjects that are the same age. A second option is to sort the subjects into the two treatment groups so that a 21 year old is in Group A, and the other 21 year old is in Group B, and so on. Again, the average age of Group A subjects and of Group B subjects would be the same and therefore controlled with respect to any covariation between age and change in blood pressure. However, there are other variables that may covary with blood pressure, and by controlling one, we would need to control the others. Randomization provides a better way.
I will demonstrate how randomization tends to distribute the values in such a way that the groups will not differ appreciably for the nuisance variables like age and BMI differences and, by extension, any other covariable. The R work is attached following the Reading list. The take-home message: After randomly selecting subjects for assignment to the treatment groups, the apparent differences between Group A and Group B for both age and BMI are substantially diminished. No attempt to match by age and by BMI is necessary. The numbers are shown in the table and then in two graphics (Fig 1, Fig 2) derived from the table.
Table 1. Mean age and BMI for subjects in two treatment groups A and B where subjects were assigned randomly or by convenience to treatment groups.
| Group | Random assignment of subjects to treatment groups | Convenience assignment of subjects to treatment groups |
|---|---|---|
| A | 35.2 | 28 |
| B | 35.8 | 43 |
| A | 32.49 | 28.99 |
| B | 32.87 | 37.37 |
Just for emphasis, the means from Table 1 are presented in the next two figures (Fig 1 and Fig 2).
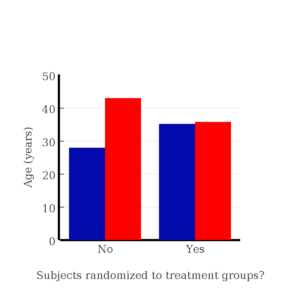
Figure 1. Age of subjects by groups (A = blue, B = red) with and without randomized assignment of subjects to treatment groups.
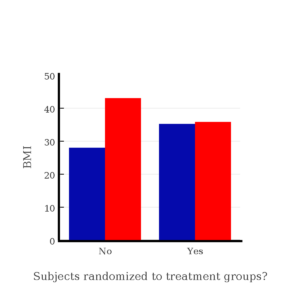
Figure 2. BMI of subjects by groups (A = blue, B = red) with and without randomized assignment of subjects to treatment groups.
Note that the apparent difference between A and B for BMI disappear once proper randomization of subjects was accomplished. In conclusion, a random sample is an approach to experimental design that helps to reduce the influence other factors may have on the outcome variable (eg, change in blood pressure after 16 weeks of exercise). In principle, randomization should protect a project because, on average, these influences will be represented randomly for the two groups of individuals. This reasoning extends to unmeasured and unknown causal factors as well.
This discussion was illustrated by random assignment of subjects to treatment groups. The same logic applies to how to select subjects from a population. If the sampling is large enough, then a random sample of subjects will tend to be representative of the variability of the outcome variable for the population and representative also of the additional and unmeasured cofactors that may contribute to the variability of the outcome variable.
What about observational studies? How does randomization work?
However, if you do cannot obtain a random sample, then conclusions reached may be sample-specific, biased. …perhaps the group of individuals that likes to exercise on treadmills just happens to have a higher cardiac output because they are larger than the individuals that like to exercise on bicycles. This nonrandom sample, an example of confounding where an extraneous or nuisance variable, body size, is associated with both the independent variable (exercise preference) and the dependent variable (cardiac output), will bias your results and can lead to incorrect interpretation of results.
Alternatively, perhaps a researcher elects to study the cardiac output of treadmill users versus bicycle users. The researcher sets up their testing station inside a gym’s powerlifting zone, where the largest individuals in the gym hang out. Inevitably because of this choice, the researcher over recruits larger individuals into the treadmill group, leading to a falsely elevated average cardiac output for treadmill users. This is an example of ascertainment bias — the sample is not representative of all treadmill users at the gym.
Random sampling is CRUCIAL in epidemiology, opinion survey work, most aspects of health, drug studies, medical work with human subjects. It’s difficult and very costly to do… so most surveys you hear about, especially polls reported from Internet sites, are NOT conducted using random sampling (included in the catch-all term “probability sampling“)!! As an aside, most opinion survey work involves complex sample designs involving some form of geographic clustering (eg, all phone numbers in a city, random sample among neighborhoods).
Random sampling is the ideal if generalizations are to be made about data, but strictly random sampling is not appropriate for all kinds of studies. Consider the question of whether or not EMF exposure is a risk factor for developing cancer (Pool 1990). These kinds of studies are observational: at least in principle, we wouldn’t expect that housing and therefore exposure to EMF is manipulated (cf. discussion Walker 2009). Thus, epidemiologists will look for patterns: if EMF exposure is linked to cancer, then more cases of cancer should occur near EMF sources compared to areas distant from EMF sources. Thus, the hypothesis is that an association between EMF exposure and cancer occurs non-randomly, whereas cancers occurring in people not exposed to EMF are random. Unfortunately, clusters can occur even if the process that generates the data is random.
Compare Graph A and Graph B (Fig 3). One of the graphs resulted from a random process and the other was generated by a non-random process. Note that the claim can be rephrased about the probability that each grid has a point, eg, it’s like Heads/Tails of 16 tosses of a coin. We can see clusters of points in Graph B; Graph A lacks obvious clusters of points — there is a point in each of the 16 cells of the grid. Although both patterns could be random, the correct answer in this case is Graph B.
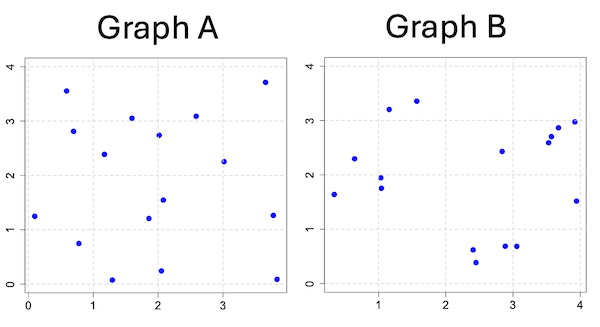
Figure 3. An example of clustering resulting from a random sampling process (Graph B). In contrast, Graph A was generated so that a point was located within each grid.
Hard to tell — and truth be told, random process could generate either one. To convince you, Figure 4 reveals the grouping that was done for Group A, in contrast with Group B which was drawn with the truly random process.
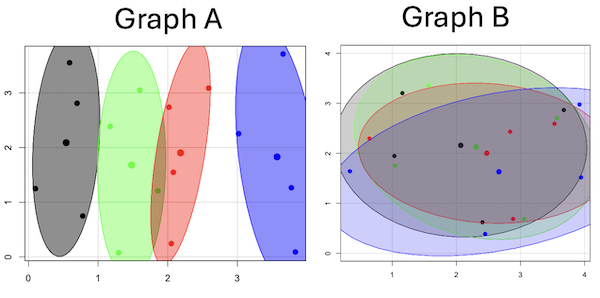
Figure 4. Same graphs as Figure 3, but with ellipses around the grouped data (hard to tell, but the centroids are the larger points).
Implications for sampling
The graphic below shows the transmission grid in the continental United States (Fig 5). How would one design a random sampling scheme overlaid against the obviously heterogeneous distribution of the grid itself? If a random sample was drawn, chances are good that no population would be near a grid in many of the western states, but in contrast, the likelihood would increase in the eastern portion of the United States where the population and therefore transmission grid is more densely placed.
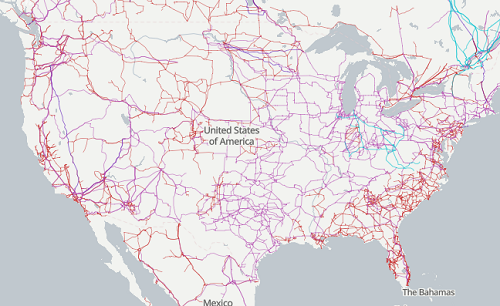
Figure 5. Map of electrical transmission grid for continental United States of America. Image source https://openinframap.org/#3/24.61/-101.16
For example, you want to test whether or not EMF affects human health, and your particular interest is in whether or not there exists a relationship between living close to high voltage towers or transfer stations and brain cancer. How does one design a study, keeping in mind the importance of randomization for our ability to generalize and assign causation? This is a part of epidemiology which strives to detect whether clusters of disease are related to some environmental source. It is an extremely difficult challenge. For the record, no clear link to EMF and cancer has been found, but reports do appear from time to time (eg, report on a cluster of breast cancer in men working in office adjacent to high EMF, Milham 2004).
Questions
1. Use the sample() with and without replacement on the object (see help with R below)
fruit <- c("apple", "banana", "grape", "kiwi", "pear", "pineapple", "tomato")a) set of 3
b) set of 4
2. Confirm the claim by calculating the probability of Graph A result vs Graph B result (see R script below).
Quiz Chapter 5.5
Importance of randomization in experimental design
R code!
Code you type is shown in red; responses or output from R are shown in blue. Recall that statements preceded by the hash # are comments and are not read by R (ie, no need for you to type them).
First, create some variables. Vectors aa and bb contain my two age sequences.
 aa = seq(21,50)
 bb = seq(21,50)
Second, append vector bb to the end of vector aa
 age = append(aa,bb)
 age           #submit the vector (variable) name to print the records for verification - looks good!
  [1] 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37
 [48] 38 39 40 41 42 43 44 45 46 47 48 49 50
Third, get the average age for the first group (the aa sequence) and for the second group (the bb sequence). Lots of ways to do this, I made a two subsets from the combined age variable; could have just as easily taken the mean of aa and the mean of bb (same thing!).
 A = age[1:30]
 mean(A)
 [1] 35.5
 B = age[31:60]
 mean(B)
 [1] 35.5
Fourth, start building a data frame, then sort it by age. Will be adding additional variables to this data frame
 ex.random = data.frame(age)
 AO.all = sort(ex.random$age)
 AO.age           #submit the vector (variable) name to print the records for verification - looks good!
  [1] 21 21 22 22 23 23 24 24 25 25 26 26 27 27 28 28 29 29 30 30 31 31 32 32 33 33 34 34 35 35 36 36 37 37 38 38 39 39 40 40 41 41 42 42 43 43 44
 [48] 44 45 45 46 46 47 47 48 48 49 49 50 50
Fifth, divide the variable again into two subsets of 30 and get the averages
 AO = AO.age[1:30]
 AO
  [1] 21 21 22 22 23 23 24 24 25 25 26 26 27 27 28 28 29 29 30 30 31 31 32 32 33 33 34 34 35 35
 mean(AO)
 [1] 28
 BO = AO.age[31:60]
 BO
  [1] 36 36 37 37 38 38 39 39 40 40 41 41 42 42 43 43 44 44 45 45 46 46 47 47 48 48 49 49 50 50
 mean(BO)
 [1] 43
Sixth, create an index variable, random order without replacement
rand.index = sample(1:60,60,replace=F)Add the new variable to our existing data frame, then print it to check that all is well
 ex.random$rand = rand.index
 ex.random
    age rand
 1   21   43
 2   22   15
 3   23   17
 4   24   35
 5   25   19
 6   26   18
 7   27   22
 8   28   31
 9   29   12
 10  30   44
 11  31   24
 12  32    5
 13  33    2
 14  34   50
 15  35   23
 16  36   20
 17  37   41
 18  38   56
 19  39   36
 20  40    8
 21  41   45
 22  42   38
 23  43   42
 24  44   46
 25  45   16
 26  46   21
 27  47   28
 28  48   10
 29  49   32
 30  50   54
 31  21   57
 32  22   51
 33  23   27
 34  24   40
 35  25   14
 36  26   48
 37  27   26
 38  28   58
 39  29    9
 40  30   11
 41  31    4
 42  32   52
 43  33   37
 44  34   53
 45  35    6
 46  36   34
 47  37   39
 48  38    7
 49  39    1
 50  40   47
 51  41   33
 52  42   60
 53  43   49
 54  44   30
 55  45   29
 56  46   55
 57  47   13
 58  48    3
 59  49   25
 60  50   59
Seventh, select for our first treatment group the first 30 subjects from the randomized index. There are again other ways to do this, but sorting on the index variable means that the subject order will be change too.
AR.age = ex.random[order(ex.random$rand),] #created a new data frame to distinguish it from the presorted version "ex.random"Print the new data frame to confirm that the sorting worked. It did. we can see that the rows have been sorted by ascending order based on the index variable.
 AR.age
    age rand
 49  39    1
 13  33    2
 58  48    3
 41  31    4
 12  32    5
 45  35    6
 48  38    7
 20  40    8
 39  29    9
 28  48   10
 40  30   11
 9   29   12
 57  47   13
 35  25   14
 2   22   15
 25  45   16
 3   23   17
 6   26   18
 5   25   19
 16  36   20
 26  46   21
 7   27   22
 15  35   23
 11  31   24
 59  49   25
 37  27   26
 33  23   27
 27  47   28
 55  45   29
 54  44   30
 8   28   31
 29  49   32
 51  41   33
 46  36   34
 4   24   35
 19  39   36
 43  33   37
 22  42   38
 47  37   39
 34  24   40
 17  37   41
 23  43   42
 1   21   43
 10  30   44
 21  41   45
 24  44   46
 50  40   47
 36  26   48
 53  43   49
 14  34   50
 32  22   51
 42  32   52
 44  34   53
 30  50   54
 56  46   55
 18  38   56
 31  21   57
 38  28   58
 60  50   59
 52  42   60
Eighth, create our new treatment groups, again of n = 30 each, then get the means ages for each group.
 AR = AR.age$age[1:30]
 mean(AR)
 [1] 35.16667
 AR2 = AR.all$all[31:60]
 mean(AR2)
 [1] 35.83333
Get the minimum and maximum values for the groups
 min(AR)
 [1] 22
 min(AR2)
 [1] 21
 max(AR)
 [1] 49
 max(AR2)
 [1] 50
Ninth, create a BMI variable drawn from a normal distribution with coefficient of variation equal to 20%. The first group with we will call cc
cc = rnorm(n=30,m=27.5, sd=5.5) #mean was 27.5 for this group with standard deviation of 5.5The second group called dd
dd = rnorm(n=30,m=37.5, sd=7.5) #mean was 37.5 for this group with standard deviation of 7.5Create a new variable called BMI by joining cc and dd
 BMI=append(cc,dd)
 BMI            #print out BMI to confirm. Looks good!
  [1] 27.87528 27.83250 31.88703 34.99041 24.06751 23.50952 22.57779 31.48394 31.04321 25.60258 25.41081 22.34619 34.62213 36.41348 41.17740
 [16] 20.56529 27.25238 21.85205 32.11690 32.37168 23.11314 33.29110 34.99106 38.22016 18.72105 26.22030 25.13412 27.50475 34.79361 32.81267
 [31] 47.57872 27.58428 40.17211 38.22195 26.91893 37.02784 53.72671 34.94727 30.35245 38.32571 40.52111 36.15627 30.36592 36.20397 47.63142
 [46] 40.30846 36.47643 50.86804 43.63741 37.84994 42.82665 41.71008 28.44976 24.57906 42.37762 38.38512 35.22879 31.34063 34.02996 27.28038
Add the BMI variable to our data frame.
 ex.random$BMI = BMI
 ex.random              #Print out the revised data frame. Looks good. We now have three variables: age, the index "rand," and now BMI
    age rand      BMI
 1   21   43 27.87528
 2   22   15 27.83250
 3   23   17 31.88703
 4   24   35 34.99041
 5   25   19 24.06751
 6   26   18 23.50952
 7   27   22 22.57779
 8   28   31 31.48394
 9   29   12 31.04321
 10  30   44 25.60258
 11  31   24 25.41081
 12  32    5 22.34619
 13  33    2 34.62213
 14  34   50 36.41348
 15  35   23 41.17740
 16  36   20 20.56529
 17  37   41 27.25238
 18  38   56 21.85205
 19  39   36 32.11690
 20  40    8 32.37168
 21  41   45 23.11314
 22  42   38 33.29110
 23  43   42 34.99106
 24  44   46 38.22016
 25  45   16 18.72105
 26  46   21 26.22030
 27  47   28 25.13412
 28  48   10 27.50475
 29  49   32 34.79361
 30  50   54 32.81267
 31  21   57 47.57872
 32  22   51 27.58428
 33  23   27 40.17211
 34  24   40 38.22195
 35  25   14 26.91893
 36  26   48 37.02784
 37  27   26 53.72671
 38  28   58 34.94727
 39  29    9 30.35245
 40  30   11 38.32571
 41  31    4 40.52111
 42  32   52 36.15627
 43  33   37 30.36592
 44  34   53 36.20397
 45  35    6 47.63142
 46  36   34 40.30846
 47  37   39 36.47643
 48  38    7 50.86804
 49  39    1 43.63741
 50  40   47 37.84994
 51  41   33 42.82665
 52  42   60 41.71008
 53  43   49 28.44976
 54  44   30 24.57906
 55  45   29 42.37762
 56  46   55 38.38512
 57  47   13 35.22879
 58  48    3 31.34063
 59  49   25 34.02996
 60  50   59 27.28038
Tenth, repeat our protocol from before: Set up two groups each with 30 subjects, calculate the means for the variables and then sort by the random index and get the new group means.
 AO = ex.random$BMI[1:30]
 mean(AO)
 [1] 28.99333
 BO = ex.random$BMI[31:60]
 mean(BO)
 [1] 37.36943
All we did was confirm that the unsorted groups had mean BMI of around 27.5 and 37.5 respectively. Now, proceed to sort by the random index variable. Go ahead and create a new data frame
 AR.age = ex.random[order(ex.random$rand),]
 AR.age                 #Print out the new data frame to confirm. Looks good.
    age rand      BMI
 49  39    1 43.63741
 13  33    2 34.62213
 58  48    3 31.34063
 41  31    4 40.52111
 12  32    5 22.34619
 45  35    6 47.63142
 48  38    7 50.86804
 20  40    8 32.37168
 39  29    9 30.35245
 28  48   10 27.50475
 40  30   11 38.32571
 9   29   12 31.04321
 57  47   13 35.22879
 35  25   14 26.91893
 2   22   15 27.83250
 25  45   16 18.72105
 3   23   17 31.88703
 6   26   18 23.50952
 5   25   19 24.06751
 16  36   20 20.56529
 26  46   21 26.22030
 7   27   22 22.57779
 15  35   23 41.17740
 11  31   24 25.41081
 59  49   25 34.02996
 37  27   26 53.72671
 33  23   27 40.17211
 27  47   28 25.13412
 55  45   29 42.37762
 54  44   30 24.57906
 8   28   31 31.48394
 29  49   32 34.79361
 51  41   33 42.82665
 46  36   34 40.30846
 4   24   35 34.99041
 19  39   36 32.11690
 43  33   37 30.36592
 22  42   38 33.29110
 47  37   39 36.47643
 34  24   40 38.22195
 17  37   41 27.25238
 23  43   42 34.99106
 1   21   43 27.87528
 10  30   44 25.60258
 21  41   45 23.11314
 24  44   46 38.22016
 50  40   47 37.84994
 36  26   48 37.02784
 53  43   49 28.44976
 14  34   50 36.41348
 32  22   51 27.58428
 42  32   52 36.15627
 44  34   53 36.20397
 30  50   54 32.81267
 56  46   55 38.38512
 18  38   56 21.85205
 31  21   57 47.57872
 38  28   58 34.94727
 60  50   59 27.28038
 52  42   60 41.71008
Get the means of the new groups
 AR = AR.age$BMI[1:30]
 mean(AR)
 [1] 32.49004
 min(AR)
 [1] 18.72105
 max(AR)
 [1] 53.72671
 AR2 = AR.all$BMI[31:60]
 mean(AR2)
 [1] 33.87273
 min(AR2)
 [1] 21.85205
 max(AR2)
 [1] 47.57872
That’s all of the work!
Data set
nonrandom
| X | Y |
| 0.779 | 0.747 |
| 0.098 | 1.248 |
| 0.697 | 2.811 |
| 0.59 | 3.553 |
| 1.295 | 0.075 |
| 1.858 | 1.207 |
| 1.172 | 2.388 |
| 1.597 | 3.051 |
| 2.051 | 0.242 |
| 2.081 | 1.546 |
| 2.016 | 2.738 |
| 2.587 | 3.088 |
| 3.833 | 0.088 |
| 3.776 | 1.264 |
| 3.017 | 2.254 |
| 3.657 | 3.712 |
random
| X1 | Y1 |
| 1.157 | 3.203 |
| 2.407 | 0.62 |
| 1.033 | 1.946 |
| 3.676 | 2.866 |
| 3.57 | 2.703 |
| 3.056 | 0.685 |
| 1.568 | 3.355 |
| 1.041 | 1.753 |
| 0.643 | 2.295 |
| 2.884 | 0.687 |
| 3.53 | 2.591 |
| 2.838 | 2.431 |
| 3.945 | 1.518 |
| 0.34 | 1.64 |
| 2.45 | 0.386 |
| 3.921 | 2.976 |
Chapter 5 contents
- The basics explained
- Experiments
- Experimental and Sampling units
- Replication, Bias, and Nuisance Variables
- Clinical trials
- Importance of randomization in experimental design
- Sampling from Populations
- References and suggested readings