14.8 – More on the linear model in Rcmdr
Introduction
During the last lectures, we could have used the Two-Way ANOVA command in R or Rcmdr
R code: How to analyze multifactorial ANOVA problems
Rcmdr: Statistics → Means → Multiway ANOVA
To analyze our two factor data sets. As long as the design meets the following conditions, by all means use this command because it is simple and precisely correct.
- Both factors are fixed, not random.
- Each level of first factor is crossed with each level of the second factor.
- No missing data (the design is fully replicated and balanced).
If any of the three points do not fit your two-way design, then you’ll need a different, more general and powerful ANOVA procedure in R and Rcmdr to analyze these types of designs. You’ll need the lm() function (Fig 1).
Rcmdr: Statistics → Fit models → Linear model…
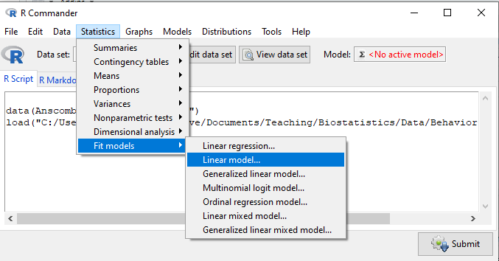
Figure 1. Linear model menu in Rcmdr, version 2.7.0
Some R basics with the lm() function, the general linear model.

Response  is specified by linear predictor(s), either factors or covariates (ratio-scale predictor variables). We communicate to R what the model is by using operators. The four more commonly used operators are
 the basic way to include the model terms, ie, the mode predictors
 which is interpreted as the interaction of all the variables and the factors in the term
 is interpreted as factor crossing
Not shown, but  indicates the term on the left is nested within the term on the right.
A few examples: we’ll have three factors, A, B, and C. For our one-way ANOVA, the model specification would be

For our crossed, balanced two-way ANOVA, the model specification would be
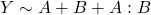
or equivalently

And for our block ANOVA problem?
Click here to get entire List of model commands in R.
How would we analyze our snake experiment?
Table 1. The snake data set
| Snake | Source | flick |
| 1 | dH2O | 3 |
| 2 | dH2O | 0 |
| 3 | dH2O | 0 |
| 4 | dH2O | 5 |
| 5 | dH2O | 1 |
| 6 | dH2O | 2 |
| 1 | fish | 6 |
| 2 | fish | 22 |
| 3 | fish | 12 |
| 4 | fish | 24 |
| 5 | fish | 16 |
| 6 | fish | 16 |
| 1 | worm | 6 |
| 2 | worm | 22 |
| 3 | worm | 12 |
| 4 | worm | 24 |
| 5 | worm | 16 |
| 6 | worm | 16 |
We have two factors, but one factor is a Block (repeated measures on individuals). We need to tell R and Rcmdr what our model is. We’ll return to talk about models next time, a very important topic!! For now, think of a model as adding the independent variables together to predict the response variable.
In our Snake example, it’s a two-way ANOVA, but one factor is individual snake, the other is a treatment, and we have repeat measures, so there cannot be an interaction.
We tell R and Rcmdr which columns contain the Response, and under Model, we enter the columns with the two factors.
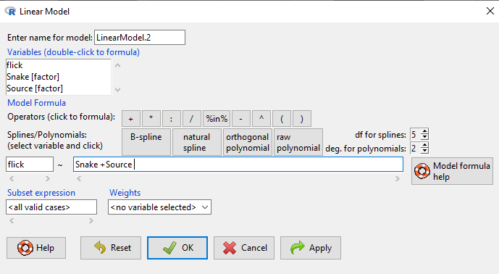
Figure 2. Menu of linear model with repeat measures model, Rcmdr, version 2.7.0.
You must also tell R and Rcmdr which factors in the model (if any) are random to get the correct F statistics. Almost without exception, blocking factors are always treated as Random
The output looks like this (see below). More complicated, true (which means more information!), but things marked in red we’ve seen before.
LinearModel.2 <- lm(flick ~ Snake +Source, data=L16SnakeTaste)

summary(LinearModel.2)

Call:
lm(formula = flick ~ Snake + Source, data = L16SnakeTaste)

Residuals:
Min 1Q Median 3Q Max
-5.2222 -0.7222 0.0278 1.5694 7.4444

Coefficients:
             Estimate Std. Error t value Pr(>|t|)
(Intercept)    -4.444      2.523  -1.762 0.10862
Snake[T.2]      9.667      3.090   3.128 0.01072 *
Snake[T.3]      3.000      3.090   0.971 0.35451
Snake[T.4]     12.667      3.090   4.099 0.00215 **
Snake[T.5]      6.000      3.090   1.942 0.08085 .
Snake[T.6]      6.333      3.090   2.050 0.06755 .
Source[T.fish] 14.167      2.185   6.484 0.0000704 ***
Source[T.worm] 14.167      2.185   6.484 0.0000704 ***
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 3.784 on 10 degrees of freedom
Multiple R-squared: 0.8858, Adjusted R-squared: 0.8058
F-statistic: 11.08 on 7 and 10 DF, p-value: 0.0005337
Contrast coding
When a factor (categorical variable) is used in a linear model (lm() or aov()), R must convert the factor into one or more numeric predictor variables. Contrast coding tells us how to represent the factor in the model, how to interpret the coefficients associated with the factor, how the hypothesis tests of the coefficients are handled, and whether or not Type III sums of squares tests are valid. R can handle contrast coding in a couple of ways, either as a dummy contrast (each group if the factor is contrasted to a baseline) or effects coding, where group means are compared to the grand mean. The command summary(lm()) reports contrast coding that was used in the linear model. Every kind of contrast leads to the same fitted values and same overall F-test, but coefficient estimates and t-tests change.
Note 1: Type I sums of squares tests are affected by the order of the predictors in the model, not by type of contrast coding used. R Commander defaults to Type II tests, which are generally unaffected by coding contrasts used. In contrast, Type III tests are affected by the type of coding contrasts used — Type III tests require sum-to-zero (effects) contrasts.
For the ANOVA table, we call up the command via
Rcmdr: Models → Hypothesis tests → ANOVA table… (Fig 3).
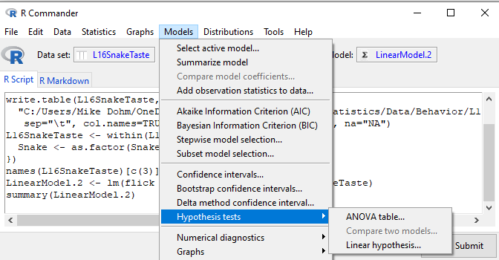
Figure 3. Rcmdr: Models → Hypothesis tests → ANOVA table… Rcmdr, version 2.7.0
Confirm that the model object is active (in this case, the object was LinearModel.2), accept the defaults about types of tests and marginality, and submit OK. The output is
Anova(LinearModel.2, type="II")
Anova Table (Type II tests)

Response: flick
          Sum Sq Df F value Pr(>F)
Snake     307.61  5  4.2956 0.02396 *
Source    802.78  2 28.0256 0.00007954 ***
Residuals 143.22 10
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
End R output
You do not need to know all of the output; all of that output is there for a reason, of course, but for now, here’s what R and Rcmdr has to say (from the help menu):
The sequential sums of squares is the added sums of squares given that prior terms are in the model. These values depend upon the model order. The adjusted sums of squares are the sums of squares given that all other terms are in the model. These values do not depend upon the model order.
You should try our snake example again, but this time, remove the tongue flick response to the dH2O for the first snake — a missing value. (just type into the cell NA).
How would you use GLM to analyze a simple two-way ANOVA, a fully crossed, fully replicated (“balanced”) design? We could use the Two-way ANOVA command in R and Rcmdr, or we could use lm(). Try it with the data set from random vs nonrandom lecture.
Another example
Below, you see how the model is entered. To let R know that I wish R and Rcmdr to test the interaction, I need to add a Model term for that source of variation. I accomplish this by typing “Diet*Drug” (without the quotes).

Figure 4. Crossed, balanced design. Linear model menu, Rcmdr, version 1.9.2
After clicking OK, the following output from the lm function is returned. How does this compare to output from the two-way ANOVA command in R and Rcmdr?
You should try both and compare!
Rcmdr: Models → Hypothesis tests → ANOVA table
Anova(LinearModel.17, type="II")
Anova Table (Type II tests)
Response: chol_randomized
             Sum Sq  Df F value   Pr(>F)
diet         141.08   2  1.3061 0.28745
drug         351.88   2  3.2577 0.05403 .
diet:drug    235.50   4  1.0901 0.38124
Residuals   1458.19  27
End R output
Nested ANOVA
The nested ANOVA may be analyzed in multiple ways in R and Rcmdr, but I prefer the lm() function because it is the most general. For Nested ANOVA, we can also use lm(). Here’s where it gets a little tricky. Put in the Response variable (Chol), then click in the box for model: Select both factors, then type in / after the factor that’s nesting factor. For our nested model example (14.5 – Nested designs), Manufacturer Source was nested within Drug.
Table 3. Nested design example data set from Chapter 14 – Nested design
| Drug | Source | Chol |
| 1 | 1 | 202.6 |
| 1 | 1 | 207.8 |
| 1 | 1 | 190.2 |
| 1 | 1 | 211.7 |
| 1 | 1 | 201.5 |
| 1 | 2 | 189.3 |
| 1 | 2 | 198.5 |
| 1 | 2 | 208.4 |
| 1 | 2 | 205.3 |
| 1 | 2 | 210 |
| 2 | 3 | 212.3 |
| 2 | 3 | 204.4 |
| 2 | 3 | 221.6 |
| 2 | 3 | 209.2 |
| 2 | 3 | 222.1 |
| 2 | 4 | 203.6 |
| 2 | 4 | 209.8 |
| 2 | 4 | 204.1 |
| 2 | 4 | 201.8 |
| 2 | 4 | 202.6 |
| 3 | 5 | 189.1 |
| 3 | 5 | 219.9 |
| 3 | 5 | 196 |
| 3 | 5 | 205.3 |
| 3 | 5 | 204 |
| 3 | 6 | 194.7 |
| 3 | 6 | 192.8 |
| 3 | 6 | 226.5 |
| 3 | 6 | 200.9 |
| 3 | 6 | 219.7 |
Note 2: If you were working with a CROSSED model, then you would enter the two factors and indicate the interaction by typing Drug*Source (if these are the two factors involved in the interaction).
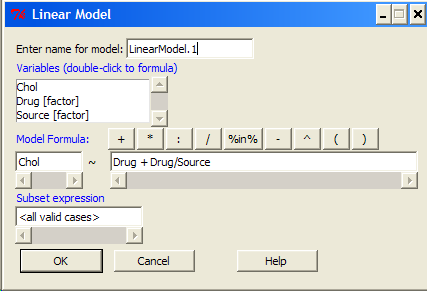
Figure 5. Nested design, linear model menu, Rcmdr, version 1.9.2
Fortunately, R and Rcmdr’s help system is quite extensive here, so when in doubt, check the help box…
Output from the linear model for the Nested Example looks like the one below.
The General Linear Model function in R and therefore Rcmdr returns information about our design plus Sums of Squares, Mean squares, and P-values. R and Rcmdr default’s to use of sequential evaluation of effects. Adjusted evaluation is useful for when you have a covariate (like body size or another confounding variable) that should be evaluated first before the factors are evaluated. We will use the sequential analysis.
Rcmdr: Models → Hypothesis tests → ANOVA table
Anova(LinearModel.15, type="II")
Anova Table (Type II tests)
Response: Chol
             Sum Sq Df F value Pr(>F)
Drug         225.14  2  1.1743 0.3262
Drug:Source  269.27  3  0.9363 0.4385
Residuals   2300.61 24
End R output
Repeatability and ANOVA
We need to tell Rcmdr how to structure the error term; you need the data frame to be arranged so
aovRes <- aov(dH2O ~ Source + Error(Source/Subject), data=SnakeTaste)
#Print the results
aovRes
Anova Table (Type II tests)
Response: dH2O
            Sum Sq Df F value   Pr(>F)
Subject     307.61  5  4.2956 0.02396 *
Source      802.78  2 28.0256 0.00007954 ***
Residuals   143.22 10
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
#What components are available in the aovRes object?
names(aovRes)
[1] "Sum Sq"  "Df"      "F value" "Pr(>F)"
How do I extract the “F value” for Subjects?
str(aovRes)
Questions
1. What are three learning objectives from this page?
2. Be able to distinguish use of lm() and aov() and the summary output with respect to testing of linear models.
Quiz Chapter 14.8
More on the linear model in Rcmdr
Data sets
Table 1. The snake data set
| Snake | Source | flick |
| 1 | dH2O | 3 |
| 2 | dH2O | 0 |
| 3 | dH2O | 0 |
| 4 | dH2O | 5 |
| 5 | dH2O | 1 |
| 6 | dH2O | 2 |
| 1 | fish | 6 |
| 2 | fish | 22 |
| 3 | fish | 12 |
| 4 | fish | 24 |
| 5 | fish | 16 |
| 6 | fish | 16 |
| 1 | worm | 6 |
| 2 | worm | 22 |
| 3 | worm | 12 |
| 4 | worm | 24 |
| 5 | worm | 16 |
| 6 | worm | 16 |
Chapter 14 contents
14.4 – Randomized block design
Introduction
Randomized Block Designs and Two-Factor ANOVA
In previous lectures, we have introduced you to the standard factorial ANOVA, which may be characterized as being crossed, balanced, and replicated. We expect additional factors (covariates) may contribute to differences among our experimental units, but rather than testing them — which would increase need for additional experimental units because of increased number of groups to test — we randomize our subjects. Randomization is intended to disrupt trends of confounding variables (aka covariates). If the resulting experiment has missing values (see Chapter 5), then we can say that the design is partially replicated; if only one observation is made per group, then the design is not replicated — and perhaps, not very useful!!
A special type of Two-factor ANOVA which includes a “blocking” factor and a treatment factor.
Randomization is one way to control for “uninteresting” confounding factors. Clearly, there will be scenarios in which randomization is impossible. For example, it is impossible to randomly assign subjects to The blocking factor is similar to the 10.3 – Paired t-test. In the paired t-test we had two individuals or groups that we paired (eg, twins). One specific design is called the Randomized Block Design and we can have more than 2 members in the group. We arrange the experimental units into similar groups, ie, the blocking factor. Examples of blocking factors may include day (experiments are run over different days), location (experiments may be run at different locations in the laboratory), nucleic acid kits (different vendors), operator (different assistants may work on the experiments), etcetera.
In general we may not be directly interested in the blocking factor. This blocking factor is used to control some factor(s) that we suspect might affect the response variable. Importantly, this has the effect of reducing the sums of squares by an amount equal to the sums of squares for the block. If variability removed by the blocking is significant, Mean Square Error (MSE) will be smaller, meaning that the F for treatment will be bigger — meaning we have a more powerful ANOVA than if we had ignored the blocking.
Statistical Testing in Randomized Block Designs
“Blocks” is a Random Factor because we are “sampling” a few blocks out of a larger possible number of blocks. Treatment is a Fixed Factor, usually.
The statistical model is
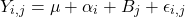
The Sources of Variation are simpler than the more typical Two-Factor ANOVA because we do not calculate all the sources of variation – the interaction is not tested! (Table 1).
Table 1. Sources of variation for a two-way ANOVA, randomized block design
|
Sources of Variation & Sum of Squares
|
DF
|
Mean Squares
|
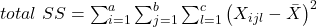 |
 |
 |
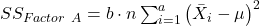 |
 |
 |
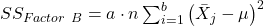 |
 |
 |
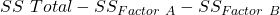 |
 |
 |
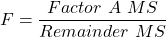
Critical Value F0.05(2), (a – 1), (Total DF – a – b)
In the exercise example above: Factor A = exercise or management plan.
Notice that we do not look at the interaction MS or the Blocking Factor (typically).
Learn by doing
Rather than me telling you, try on your own. We’ll begin with a worked example, then proceed to introduce you to three problems. Click here (Ch 14.8)for general discussion of Rcmdr and linear models for models other than the standard 2-way ANOVA (Chapter 14.8).
Worked example
Wheel running by mice is a standard measure of activity behavior. Even wild mice will use wheels (Meijer and Roberts 2014). For example, we conduct a study of family parity to see if offspring from the first, second, or third sets of births from wheel-running behavior in mice (total revs per 24 hr period). Each set of offspring from a female could be treated as a block. Data are for 3 female offspring from each pairing. This type of data set would look like this:
Table 2. Wheel running behavior by three offspring from each of three birth cohorts among four maternal sets (moms).
|
Revolutions of wheel per 24-hr period
|
||||
|
Block
|
Dam 1
|
Dam 2
|
Dam 3
|
Dam 4
|
|
b1
|
1100
|
1566
|
945
|
450
|
|
b1
|
1245
|
1478
|
877
|
501
|
|
b1
|
1115
|
1502
|
892
|
394
|
|
b2
|
999
|
451
|
644
|
605
|
|
b2
|
899
|
405
|
650
|
612
|
|
b2
|
745
|
344
|
605
|
700
|
|
b3
|
1245
|
702
|
1712
|
790
|
|
b3
|
1300
|
612
|
1745
|
850
|
|
b3
|
1750
|
508
|
1680
|
910
|
Thus, there were nine offspring for each female mouse (Dam1 – Dam4), three offspring per each of three litters of pups. The litters are the blocks. We need to get the data stacked to run in R. I’ve provided the full dataset for readers, scroll to end of this page or click here.
Question 1. Describe the problem and identify the treatment and blocking factors.
Answer. Each female has three litters. We’re primarily interested in genetics (and maternal environment) of wheel running behavior, which is associated with the moms (Treatment factor). The questions is whether there is an effect of birth parity on wheel running behavior. Offspring of a first-time mother may experience different environment than offspring of experienced mother. In this case, parity effects is an interesting question, nevertheless, blocking is the appropriate way to handle this type of problem.
Question 2. What is the statistical model?
Answer. Response variable, Y, is wheel running. Let α the effect of Dam and β the birth cohorts (ie, the blocking effect).
Question 3. Test the model.
Answer. We fit the main effects, Dam and Block Fig 1.
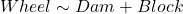
Rcmdr: Statistics → Fit models → Linear model
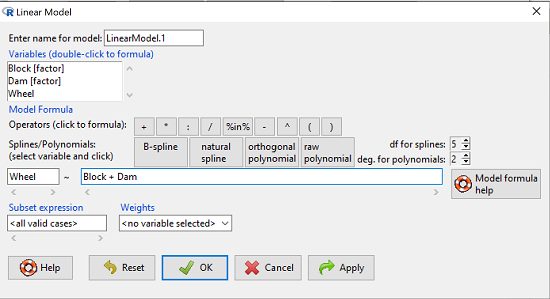
Figure 1. Screenshot Rcmdr Linear Model menu.
then run the ANOVA summary to get the ANOVA table. Rcmdr: Models → Hypothesis tests → ANOVA table.
R Output
Anova Table (Type II tests)

Response: Wheel
           Sum Sq  Df  F value    Pr(>F)
Dam       1467020   3   4.4732   0.01036 *
Block     1672166   2   7.6482   0.00207 **
Residuals 3279544  30
Question 4. Conclusions?
Answer 4. The null hypotheses are:
Treatment factor: Offspring of the different dams have same wheel running activity of offspring.
Blocking factor: No effect of litter parity on wheel running activity of offspring.
Both the treatment factor (p = 0.01036) and the blocking factor (p = 0.00207) were statistically significant.
Questions
Problem 1.
Or we might want to measure the Systolic Blood Pressure of individuals that are on different exercise regimens. However, we are not able to measure all the individuals on the same day at the same time. We suspect that time of day and the day of the year might effect an individuals blood pressure. Given this constraint, the best research design in this circumstance is to measure one individual on each exercise regime at the same time. These different individuals will then be in the same “block” because they share in common the time that their blood pressure was measured. This type of data set would look like this (Table 2):
Table 2. Simulated blood pressure of five subjects on three different exercise regimens.†
|
Subject
|
No
Exercise |
Moderate Exercise
|
Intense Exercise
|
|
1
|
120
|
115
|
114
|
|
2
|
135
|
130
|
131
|
|
3
|
115
|
110
|
109
|
|
4
|
112
|
107
|
106
|
|
5
|
108
|
103
|
102
|
Let’s make a line graph to help us visualize trends (Fig 2).
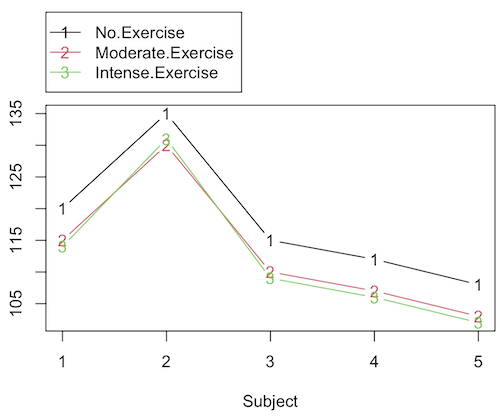
Figure 2. Line graph of data presented in Table 2.
Question 1. Describe the problem and identify the treatment and blocking factors.
Question 2. What is the statistical model?
Question 3. Test the model.
Question 4. Conclusions?
†You’ll need to arrange the data like the data set for the worked example.
Problem 2.
Another example in conservation biology or agriculture. There may be three different management strategies for promoting the recovery of a plant species. A good research design would be to choose many plots of land (blocks) and perform each treatment (management strategy) on a portion of each plot of land (block). A researcher would start with an equal number of plantings in the plots and see how many grew. The plots of land (blocks) share in common many other aspects of that particular plot of land that may effect the recovery of a species.
Table 3. Growth of plants in 5 different plots subjected to one of three management plans (simulated data set).†
|
Plot No.
|
No Management Used
|
Management
Plan 1 |
Management
Plan 2 |
|
1
|
0
|
11
|
14
|
|
2
|
2
|
13
|
15
|
|
3
|
3
|
11
|
19
|
|
4
|
4
|
10
|
16
|
|
5
|
5
|
15
|
12
|
†You’ll need to arrange the data the same arrangement as for the worked example.
These are examples of Two-Factor ANOVA but we are usually only interested in the treatment Factor. We recognize that the blocking factor may contribute to differences among groups and so wish to control for the fact that we carried out the experiments at different times (eg, seasons) or at different locations (eg, agriculture plots)
Question 5. Describe the problem and identify the treatment and blocking factors. Make a line graph to help visualize.
Question 6. What is the statistical model?
Question 7. Test the model.
Question 8. Conclusions?
Repeated-Measures Experimental Design
If multiple measures are taken on the same individual, then we have a repeated-measures experiment. This is a Randomized Block Design. In other words, each animal gets all levels of a treatment (assigned randomly). Thus, samples (individuals) are not independent and the analysis needs to take this into account. Just like for paired-T tests, one can imagine a number of experiments in biomedicine that would conform to this design.
Problem 3.
The data are total blood cholesterol levels for 7 individuals given 3 different drugs (from example given in Zar 1999, Ex 12.5, pp. 257-258).
Table 5. Repeated measures of blood cholesterol levels of seven subjects on three different drug regimens.†
|
Subjects
|
Drug1
|
Drug2
|
Drug3
|
|
1
|
164
|
152
|
178
|
|
2
|
202
|
181
|
222
|
|
3
|
143
|
136
|
132
|
|
4
|
210
|
194
|
216
|
|
5
|
228
|
219
|
245
|
|
6
|
173
|
159
|
182
|
|
7
|
161
|
157
|
165
|
†You’ll need to arrange the data like the data set for the worked example.
Question 9: Is there an interaction term in this design? Make a line graph to help visualize.
Question 10: Are individuals a fixed or a random effect?
Question 11. What is the statistical model?
Question 12. Test the model. Note that we could have done the experiment with 21 randomly selected subjects and a one-factor ANOVA. However, the repeated measures design is best IF there is some association (“correlation”) between the data in each row. The computations are identical to the randomized block analysis.
Question 13. Conclusions?
Problem 4.
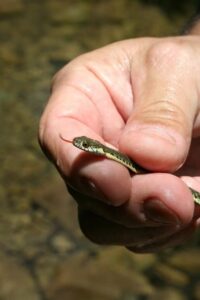
Figure 3. Juvenile garter snake, image from juvenile garter snake in hand, public domain.
Here is a second example of a repeated measures design experiment. Garter snakes (Fig 3) respond to odor cues to find prey. Snakes use their tongues to “taste” the air for chemicals, and flick their tongues rapidly when in contact with suitable prey items, less frequently for items not suitable for prey. In the laboratory, researchers can test how individual snakes respond to different chemical cues by presenting each snake with a swab containing a particular chemical. The researcher then counts how many times the snake flicks its tongue in a certain time period (data presented p. 301, Glover and Mitchell 2016).
Table 6. Tongue flick counts of naïve newborn snakes to extracts†
|
Snake
|
Control (dH2O)
|
Fish mucus
|
Worm mucus
|
|
1
|
3
|
6
|
6
|
|
2
|
0
|
22
|
22
|
|
3
|
0
|
12
|
12
|
|
4
|
5
|
24
|
24
|
|
5
|
1
|
16
|
16
|
|
6
|
2
|
16
|
16
|
†You’ll need to arrange the data like the data set for the worked example.
Question 14. Describe the problem and identify the treatment and blocking factors. Make a line graph to help visualize.
Question 15. What is the statistical model?
Question 16. Test the model.
Question 17. Conclusions?
Quiz Chapter 14.4
Randomized block design
Data sets used in this page
Problem 1 data set
| Block | Dam | Wheel |
|---|---|---|
| B1 | D1 | 1100 |
| B1 | D2 | 1566 |
| B1 | D3 | 945 |
| B1 | D4 | 450 |
| B1 | D1 | 1245 |
| B1 | D2 | 1478 |
| B1 | D3 | 877 |
| B1 | D4 | 501 |
| B1 | D1 | 1115 |
| B1 | D2 | 1502 |
| B1 | D3 | 892 |
| B1 | D4 | 394 |
| B2 | D1 | 999 |
| B2 | D2 | 451 |
| B2 | D3 | 644 |
| B2 | D4 | 605 |
| B2 | D1 | 899 |
| B2 | D2 | 405 |
| B2 | D3 | 650 |
| B2 | D4 | 612 |
| B2 | D1 | 745 |
| B2 | D2 | 344 |
| B2 | D3 | 605 |
| B2 | D4 | 700 |
| B3 | D1 | 1245 |
| B3 | D2 | 702 |
| B3 | D3 | 1712 |
| B3 | D4 | 790 |
| B3 | D1 | 1300 |
| B3 | D2 | 612 |
| B3 | D3 | 1745 |
| B3 | D4 | 850 |
| B3 | D1 | 1750 |
| B3 | D2 | 508 |
| B3 | D3 | 1680 |
| B3 | D4 | 910 |
Chapter 14 contents
14.2 – Sources of variation
Introduction
Sources of variation, or components of the two-way ANOVA include two factors, each with two or more levels (groups), and collectively, factors are often referred to as the main effects in these types of ANOVA. The other source of variation in a two-way ANOVA is the interaction between the two factors. Below, I have listed the important components, although I have not included how the sum of squares are calculated. You are expected to know the sources of variation for this most basic two-way ANOVA table (Fig 1). You should also be able to solve any missing elements in one of these tables by utilizing any included information.
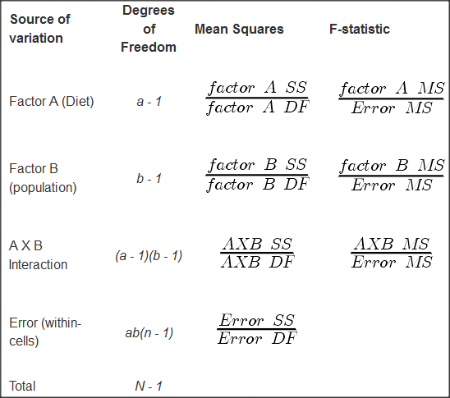
Figure 1. ANOVA table for two-way, balanced, replicated design.
Taking each row from Figure 1 one at a time we have
| Source | DF | Mean Squares | F-statistic |
| First Factor | |
 |
 |
where Source refers to the source of variation, DF refers to Degrees of Freedom, a is the number of levels (groups) of the first factor, SS refers to Sum of Squares, and MS refers to the Mean Squares.
Next is the second factor
| Source | DF | Mean Squares | F-statistic |
| First Factor | |
 |
 |
where b is the number of levels (groups) of the second factor. Next is the interaction between the first and second factors.
| Source | DF | Mean Squares | F-statistic |
| Interaction | 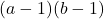 |
 |
 |
and lastly the Within-cell Error or residual source of variation
| Source | DF | Mean Squares | F-statistic |
| Error |  |
 |
 |
where n is the number of experimental units for each group. Note that if the sample size differs for one or more groups (levels),then the design would be unbalanced and this formula does not work to determine the degrees of freedom. The total degrees of freedom for the two-way ANOVA is simply N – 1, where N is the sample size for the entire problem; a little algebra shows that N may be calculated as

Unbalanced designs
An unbalanced design implies that observations are missing value for one or more groups. What to do if data are missing? Decision depends on how the data are missing (see Chapter 5). For example, if data are missing at random with respect to treatment, then this should not affect inference. If data are missing not at random, then inference, logically, must be impacted. Calculating the ANOVA, moreover, becomes a different matter. In the one-way ANOVA, no real problem arises although setting up contrasts among the levels requires a weighting term to be factored into the calculations. For higher-level ANOVA involving two or more factors the sums of squares for treatment effects are no longer simple partitioning into the different sources of variation. The sources overlap and the order by which the Factors enter into the statistical model now affects the calculations. Thus, while setting up the calculations for the balanced design is straight-forward, perhaps surprisingly, if group sizes differ, this simple relationship for calculating the degrees of freedom, sums of squares, and Mean squares become an unsolvable problem. This problem is largely solved by the general linear model.
Questions
- Based on the results of a two-way ANOVA, the error sums of squares (SSE) was computed to be 160. If we ignore one of the factors and perform a one-way ANOVA using the same data, will the SSE be the same as in the two-way ANOVA, or will it increase? Decrease? Explain your choice.
- While conducting a two-way ANOVA, you conclude that a statistically significant interaction exists between factor 1 and factor 2. What should be your next step? Do you drop the interaction term from the model and redo the analysis or do you report the results of factor effects including the non-significant interaction?
Quiz Chapter 14.2
Sources of variation