10.3 – Paired t-test
Introduction
Good experiments include controls. Interested in a new treatment for weight loss? Define a control group to compare the weight loss by a group using the new product. In many cases, the best control is the individual.
Consider now a basic experimental design, the randomized crossover trial (Fig 1), introduced in Chapter 2.4.
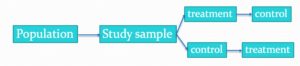
Figure 1. A two group Randomized Crossover Trial.
Subjects randomly selected from population of interest, then again once recruited into one of two treatment arms: arm 1, subjects first receive the experimental treatment, then some time later the subjects receive the control treatment; arm 2, subjects first receive the control treatment, then some time later the subjects receive the experimental treatment. Note the difference between this paired or repeated measures design and the independent sample design (see Chapter 10.1). Repeated measures designs have many advantages; we discuss them further in Chapter 14.6. At the start, repeated measures designs have greater statistical power compared to cross-sectional (independent) sample designs.
Many experiments are designed so that subjects receive all treatments and responses are gauged against the initial values recorded on the subjects. Repeated measures statistical tests, like the paired t-test, are needed however to analyze the data. These types of statistical procedures are similar to the two sample independent t-test that we discussed earlier.
However, there is an important difference between these two types of statistical procedures. For the two independent sample t-test the samples are unpaired: we observed one variable on some individuals assigned to two different groups. These groups might be
- Two locations where we measure plants or animals
- A treatment (or experimental) group with a control group.
- Expression of cytokeratin genes (eg, ΔΔCT, fold-change) from breast cancer patients compared to healthy donor subjects (Andergassen et al 2016).
The point is that samples in one group are not the same samples in the second group.
In the paired t-test we have two groups but the observations in these two groups are paired. Paired means that there is some relationship between one observation in the first sample and one observation in the second sample (every observation in one sample must be paired with one observation in another sample).
For example, weight change in humans before and after a change in diet could be performed as a paired analysis. Each subject’s weight before the diet was “paired” with the same subject’s weight after the diet.
Another example comes from genetics. Siblings or Monozygotic twins or clones, strains or varieties of plants or animals can be Paired in an experiment.
- You can give one of the twins a particular diet, or the plant or animal clones or strains can be raised in a particular environment (nutrient)
- The other twin or plant or animal clone or variety can serve as a type of control by providing a normal diet or normal environment.
Another example is a study of environmental pollution on cancer rates in many different communities.
- The researchers selects pairs of communities with similar characteristics for many socioeconomic factors.
- Each pair of communities differed with respect to the proximity to a known source of pollution: one of the pair was close to a source of pollution and one of the pair was far from a source of pollution.
The purpose of pairing in this example is to attempt to “control” for all the socioeconomic factors that might contribute to cancer but they did not want to directly measure. These other factors should be similar for each member of the pair.
Example: How repeatable is human running performance?
The subheading is misleading — we leave “repeatability” or, do individuals perform consistently to another time (see Chapter 12.3 – Fixed effects, random effects, and agreement). Here, we focus on a different question — we test whether mean performance differs across repeated trials. This may seem a subtle difference, but consistency asks the question if performance, whether it is answering questions on an exam or running times for a race, is stable across trials. Testing the means of first and second trials asks a different question: we test for a trend in performance, which may reflect learning.
Here’s an example in which a measure was taken twice for the same individuals. The data are running speed or pace during 5K race held annually on Oahu for a selected sample of female runners with repeat race times (20 – 29 years old). The race was run annually on Oahu, and the data reported are the pace for the first race and the second race, which occurred a year later (Jamba Juice – Banana Man Chase, Ala Moana Beach Park, data extracted from source, https://timelinehawaii.com).
Table 1. 5K pace times (kph) for 15 women (20 – 29 years)
| ID | First race | Second race |
|---|---|---|
| 1 | 15.28 | 15.61 |
| 2 | 11.22 | 11.19 |
| 3 | 8.80 | 9.14 |
| 4 | 8.88 | 5.46 |
| 5 | 9.81 | 10.50 |
| 6 | 6.12 | 5.69 |
| 7 | 8.31 | 8.71 |
| 8 | 6.26 | 7.42 |
| 9 | 17.16 | 16.41 |
| 10 | 16.23 | 15.82 |
| 11 | 5.90 | 7.12 |
| 12 | 8.31 | 10.48 |
| 13 | 5.93 | 8.64 |
| 14 | 10.54 | 5.99 |
| 15 | 9.53 | 8.69 |
Note 1: We’ll return to this data set in Chapter 15.3
Load the data into R as an unstacked data set. Data available at end of this page or click here.
Begin with description and exploration of the data. Start with histograms to get a sense of the sample distributions (hint: we’re looking to see if the data looks like it could come from a normal distribution, see Chapter 13.3 Assumptions) (Fig 2).
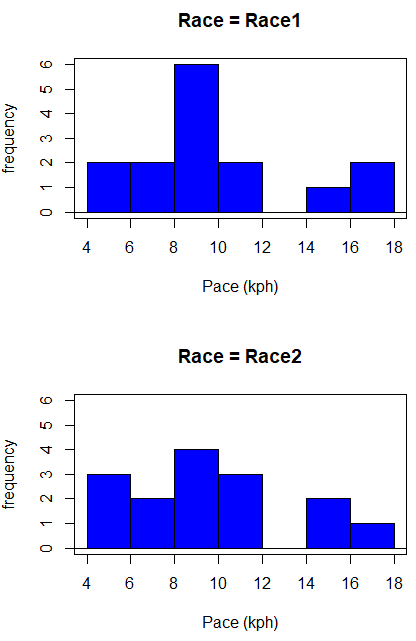
Figure 2. Histograms shows the distribution of 5K running times of 15 women who ran the race twice.
R code (stacked data set, then used defaults R Commander to make the histogram, then modified the code and submitted modified code to make Fig 1)
with(stackExCh10.3, Hist(obs, groups=Race, scale="frequency", breaks="Sturges", col="blue",
xlab="Time (min)", ylab="Frequency")))
Conclusion? The histograms don’t look normally distributed so we keep this in mind as we proceed. (See Chapter 13 – Assumptions of parametric tests for additional information about assumptions.)
A box plot comparing the first and second pace times (Fig 3).
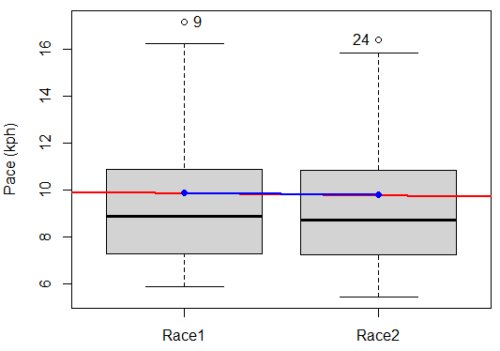
Figure 3. Box plot of race speed (kph) for 15 women 5K in two successive years.
I added a trend line (linear regression, see Chapter 17, red line) and connected the averages (blue line) for visual emphasis — no differences between the means — but note that one wouldn’t do this as part of an analysis (see Chapter 4 discussion).
R code for Fig 2
Boxplot(obs~Race, data=stackExCh10.3, id=list(method="y"), xlab="", ylab="Pace (kph)") #boxplot was made in Rcmdr
abline(lm(obs ~ as.numeric(Race), data=stackExCh10.3), col="red", lwd=2)
means <- tapply(obs, Race, mean)
points(1:2, means, pch=7, col="blue")
lines(1:2, means, col="blue", lwd=2)
The box plot works to show the median difference, but loses the paired information. A nice package called PairedData has several functions that work well with paired data, for example a profile plot (Fig 4). A profile plot is useful for showing an association between paired data.
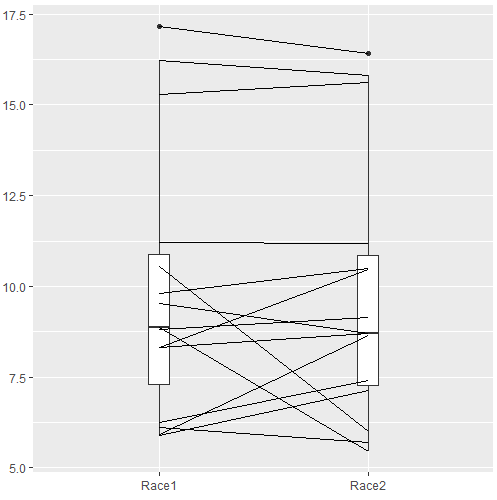
Figure 4. Profile plot, PairedData package.
R commands for Figure 4.
require(PairedData)
attach(example.ch10.3) # remember to attach dataframe so you don't have to call variables like example.ch10.3$Race1
races <- paired(Race1, Race2)
plot(races, type = "profile")
Paired t-test calculation
The paired t-test is a straight-forward extension of the independent sample t-test; the key concept is that the two samples are no longer independent, they are paired. Thus, instead of mean of group 1 minus mean of group two, we test the differences between sample 1 and sample 2 for each paired observation.

- Compute the differences between the Paired Samples (as in tables above)
- Calculate the MEAN difference score,
 : in the previous example = -0.094 kmh
- Calculate the degrees of freedom df = # pairs – 1 = n – 1, where n is the number of pairs
- Calculate the standard error of the mean of d.
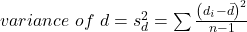
where

- Calculate the test statistic for paired data

- Compare to the Critical Value in Table C. 4 (Appendix Table 2)
- Find the Critical Value = t α (2), df
Try as difference instead of paired
Before you answer, take a look at the box plot of the mean difference between the repeat measures of 5K pace for the 15 women (Fig 5).
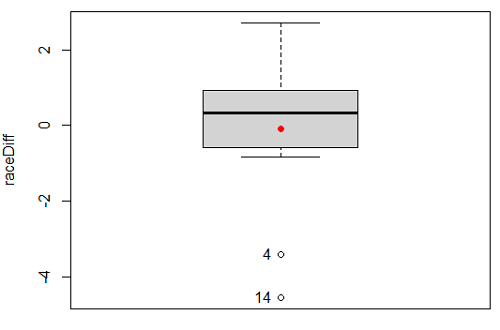
Figure 5. Box plot of differences, Red dotted lines shows the null hypothesis.
Note 2: Figure 5 is appropriate for diagnostics, but not for publication, per our discussions in Chapter 4.
Create a new variable, raceDiff, equal to Race2 minus Race1. Then, use the one sample T-test on raceDiff. I’ll leave you to complete the work (Question 2).
R code
t.test(Race1, Race2, paired = TRUE, alternative = "two.sided")
R output
Paired t-test

data: Race.1 and Race.2
t = 0.19389, df = 14, p-value = 0.849
alternative hypothesis: true difference in means is not equal to 0
95 percent confidence interval:
-0.9491017 1.1377521
sample estimates:
mean of the differences
0.09432517
Rcmdr, paired t-test
Rcmdr: Statistics → Means → Paired t-test…
Note: your two groups must be in two different columns (unstacked!) to run this version of the test.
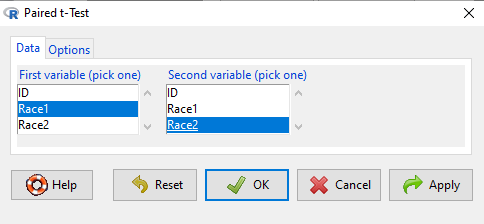
Figure 6. R Commander Paired t-test menu, Rcmdr version 2.7.
After selecting the variables, set null hypothesis after clicking on Options tab (Fig 6).
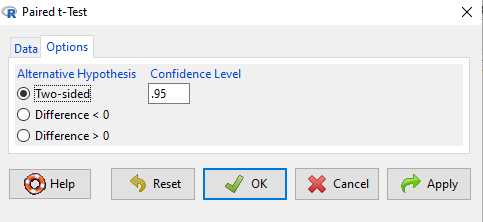
Figure 7. R Commander Paired t-Test options, select null hypothesis.
Click OK to proceed. Results will be the same as the output listed above.
the following text needs to be updated
Interpret the results.
So, what can we conclude about the null hypothesis? Interpret the 95% CI, the T-test statistic, and the P-value.
Do not ignore sample dependence
What if we ignored the repeated measures design and treated the first and second races as independent? The important concept here is to ask, what would have happened if we had done a two independent sample t-test instead?
Let’s run the analysis again, this time incorrectly using the independent sample t-test. We need to manipulate the data set before we do.
Manage your data: Stack the data
This is a good time to share how to Stack data in R. If you look at our active data set, the results of the two trials are in two different columns. In order to run the independent sample t-test we need the data in one column (with a label column).
stackExCh10.3 <- stack(example.ch10.3[, c("Race1","Race2")])
names(stackExCh10.3) <- c("obs", "Race")
Rcmdr: Data → Active data set → Stack variables in data set…
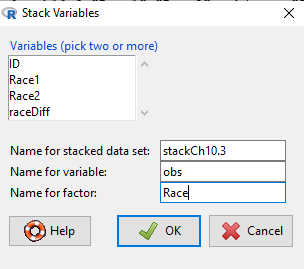
Figure 8. R Commander: Stack worksheet. Select the two variables, Race1 and Race2.
I entered values for name of the new data set, the new variable, and the name for the factor (label) column.
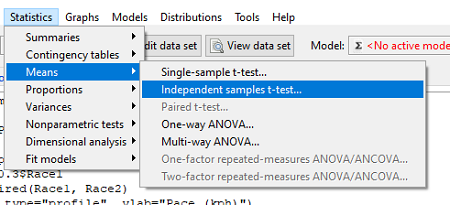
Figure 9. R Commander, select independent sample t-Test …
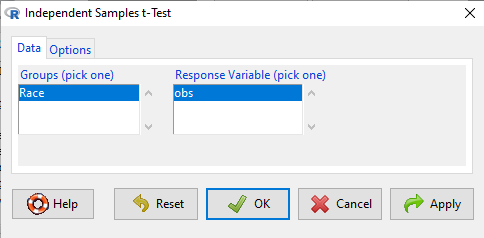
Figure 10. R commander, independent sample t test menu.
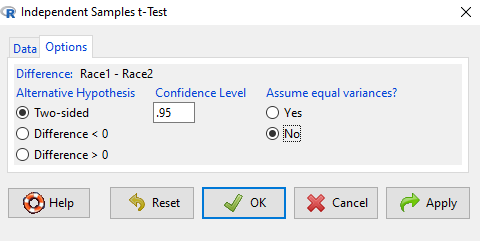
Figure 11. R Commander, select options for independent sample t-Test (assume equal variance).
Here are the results of the independent sample t-test from R.
t.test(obs~Race, alternative='two.sided', conf.level=.95, var.equal=TRUE, + data=stackCh10.3)

Two Sample t-test
data: obs by Race
t = 0.070645, df = 28, p-value = 0.9442
alternative hypothesis: true difference in means is not equal to 0
95 percent confidence interval:
 -2.640719 2.829369
sample estimates:
mean in group Race1 mean in group Race2
 9.886342 9.792017
End R output
In this case, we would have reached the same general conclusion, but the p-values are different. The p-value from the paired t-test was about 0.85 whereas the p-value from the independent sample t-test was higher, nearly 0.95, suggesting little difference between the two trials.
While the general conclusion holds, this time, that there were no statistically significant difference between the means for first and second trials. However, it won’t always work out that way. And besides, if you treated the paired data as independent, you’ve clearly violated one of the assumptions of the test.
Take a look at the degrees of freedom for the two analyses. By ignoring the pairing of samples we gain twice the number of degrees of freedom … that can’t both be right. The way to distinguish between the two is to go back to the experimental units.
Question: What are the sampling units in the case of repeat measures on individuals: the individuals themselves? the pairs of burst speed trials? something else?
it is important to note that the paired t-test is still the best for this situation because it accurately reflects the experiment — individuals were measured twice, therefore the two groups (trial 1 and trial 2) are not independent! Thus, the p-value from the paired t-test correctly reflect our best analyses of the test of the null hypothesis because the correct degrees of freedom were 14 and not 28.
In the case of the independent sample t-test we necessarily make the assumption that the two groups are independent — that is, that they are measured on different sampling units (eg, different individuals or subjects). In statistical terms, that means that you assume that the correlation between trial results is equal to zero. By incorrectly choosing an independent sample test in these repeated measures cases, I would make two null hypotheses: (1) that the means are the same and (2) that the correlation between repeat measures is zero. The problem? The t-test only evaluates the first hypothesis (means).
Questions
- Refer to Figure 6 again and related data set. Were runners faster the second year or the first year running the 5k? What about the points labeled 4 and 14? What was the average difference between first and second races?
- Complete the test of the null hypothesis of no difference between race 1 and race 2 (
raceDiff) with the one sample t-test. Set up a table to compare the test statistic, df, and p-values for results from paired t test, one sample t-test, and independent sample t-test. How do these results compare? - I’ve called the observed value “pace,” but runners would know that pace is actually amount of time per kilometer, not the total time over 5k, which is what I called pace.
- Create a new variable and report average pace for Race1 and Race2.
- Redo the paired analysis, including box plot, on your new variable.
- What is the null hypothesis for your new variable?
- Summarize your results and add to the table you created for question 2.
- Redo the two plots in Figure 2 so that the two histograms are on the sample plot. Instructions and examples were provided in Chapter 4.2.
Quiz Chapter 10.3
Paired t-test
Data set
example.ch10.3 <- read.table(header=TRUE, text = "
ID Race1 Race2
1 15.28 15.61
2 11.22 11.19
3 8.80 9.14
4 8.88 5.46
5 9.81 10.50
6 6.12 5.69
7 8.31 8.71
8 6.26 7.42
9 17.16 16.41
10 16.23 15.82
11 5.90 7.12
12 8.31 10.48
13 5.93 8.64
14 10.54 5.99
15 9.53 8.69
")
Chapter 10 contents
4 – How to report statistics
Introduction: Reporting your results.
While you are thinking about exploring data sets and descriptive statistics, please review our overview of data analysis (Chapter 2.4 and 2.5). While the scientific hypotheses come first, how experiments are designed should allow for straight-forward analysis: in other words, statistics can’t rescue poorly designed experiments, nor can it reveal new insight after the fact.
Once the experiments are completed, all projects will go through a similar process:
- Description: Describe and summarize the results.
- Check assumptions.
- Inference: conduct tests of hypotheses.
- Develop and evaluate statistical models.
Clearly this is a simplification, but there’s an expectation your readers will have about a project. Basic questions like how many subjects got better on the treatment? Is there an association between Body Mass Index (BMI) and the primary outcome? Did male and female subjects differ for response to the treatment? Undoubtedly these and related questions form the essence of the inferences, but providing graphs to show patterns may be as important to a reader as any p-value — a number which describes how likely it is that your data would have occurred by chance — eg, from an Analysis of variance.
Each project is unique — sorry, what a breathtakingly obvious statement — but what elements must be included in a results section?
Data visualization.
We describe data in three ways: graphs, tables, and in sentences. In this page we present the basics of when to choose a graph over presenting data in a table or as a series of sentences (ie, text). In the rest of this chapter we introduce the various graphics we will encounter in the course. Chapter 4 covers eight different graphics, but is by no means an exhaustive list of kinds of graphs. Phylogenetic network graphs are presented in Chapter 20.11. Although an important element of presentation in journal articles, we don’t discuss figure legends or table titles; guidelines are typically available by the journal of choice (eg, PLOS ONE journals guidelines).
A quick note about terminology. Data visualization encompasses charts, graphs and plots. Of the three terms, chart is the more generic. Graphs are used to display a function or mapping between two variables; plots are kinds of graphs for a finite set of points. There is a difference among the terms, but I confess, I won’t be consistent. Instead, I will refer to each type of data visualization by its descriptive name: bar chart, box plots, histograms, scatter plot, etc. Note that technically, a scatter plot can refer to a graph, eg, a line drawn to reflect a linear association between the two variables, whereas bar charts and box plots would not be a graph because no function is implied.
Why display data?
Do we just to show a graph to break the monotony of page after page of text or do we attempt to do more with graphs? After all, isn’t “a picture’s worth a thousand words?” In many cases, yes! Graphics allow us to see patterns. Data visualization is a key part of exploratory data analysis (Tukey 1977), or data mining in the parlance of big data (Keim 2001). Data visualization is also a crucial tool in the public health arena, and finding effective graphics to communicate, at times, complex data and information to both public and professional audiences can be challenging (see discussion in Meloncon and Warner 2017).
Graphics are complicated — all the interplay among pixels etc and rendering process — and expensive to do well. Text is much cheaper to publish, even in digital form. But the ability to visualize concepts, that is, to connect ideas to data through our eyes (see Wikipedia), seems to be more the cognitive goal of graphics. Lofty purpose, desirable goal. Yes, it is true that graphics can communicate concepts to the reader, but with some caution. Images distort, and default options in graphics programs are seldom acceptable for conveying messages without bias (Glazer 2011).
Here’s some tips from a book on graphical display (Tufte 1983; see also Camões 2016).
Your goal is to communicate complex ideas with clarity, precision, and efficiency. Graphical displays should:
- show the data
- avoid distorting the data
- present numbers in a small space
- help the viewer’s eye to compare different pieces of data
- serve a clear purpose (description, exploration, tabulation, decoration)
- be closely integrated with statistical and verbal descriptions of a data set.
We accomplish these tasks by following general principles involving scale and a commitment to avoiding bias in our presentation.
Importantly, graphs can show patterns not immediately evident in tables of numbers. See Table 1 for an example of a dataset, “Anscombe’s quartet,” (Anscombe 1973), where a picture is clearly helpful.
Anscombe’s quartet
| X | Y1 | Y2 | Y3 | Y4 |
|---|---|---|---|---|
| 10 | 8.04 | 9.14 | 7.46 | 6.58 |
| 8 | 6.95 | 8.14 | 6.77 | 5.76 |
| 13 | 7.58 | 8.74 | 12.74 | 7.71 |
| 9 | 8.81 | 8.77 | 7.11 | 8.84 |
| 11 | 8.33 | 9.26 | 7.81 | 8.47 |
| 14 | 9.96 | 8.10 | 8.84 | 7.04 |
| 6 | 7.24 | 6.13 | 6.08 | 5.25 |
| 4 | 4.26 | 3.10 | 5.39 | 12.50 |
| 12 | 10.84 | 9.13 | 8.15 | 5.56 |
| 7 | 4.82 | 7.26 | 6.42 | 7.91 |
| 5 | 5.68 | 4.74 | 5.73 | 6.89 |
| Mean (±SD) | 7.50 (2.032) | 7.50 (2.032) | 7.50 (2.032) | 7.50 (2.032) |
The Anscombe dataset is also available in R packages data(Anscombe, package="carData"), or you can copy/paste from Table 1 into a spreadsheet or text file, then load the data file into R (eg, Rcmdr → Load data set). Note that the data set does not include the column summary statistics shown in the last row of the table.
Before proceeding, look again at the table — See any patterns in the table?
Maybe.… Need to be careful as we humans are really good at perceiving patterns, even when no pattern exists.
Now, look just at the last row in the table, the row containing the descriptive statistics (the means and standard deviations). Any patterns?
The means and standard deviations are the same, so nothing really jumps out at you — does that mean that there are no differences among the columns then?
But let’s see what the scatter plots look like before we conclude that the columns of Y ’s are the same (Fig. 1). I’ll also introduce the R package clipr, which is useful for working with your computer’s clipboard.
Note 1: To show clipboard history, on Windows press + V; on macOS, open Finder and select Edit → Show Clipboard.
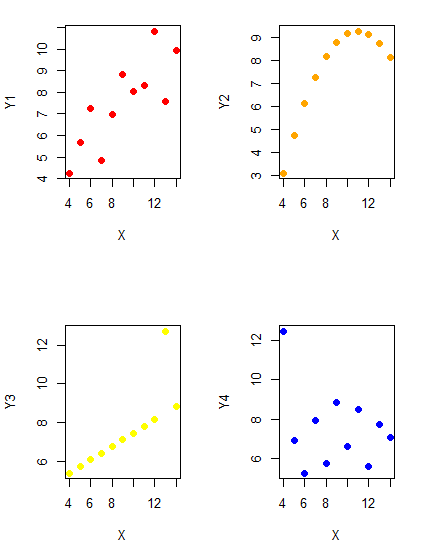
Figure 1. Scatter plot graphs of Anscombe’s quartet (Table 1)
#R code for Figure 1.

require(clipr)
#Copy from the Table and paste into spreadsheet (exclude last row). Highlight and copy data in spreadsheet
myTemp <- read_clip_tbl(read_clip(), header=TRUE, sep = "\t")
#Check that the data have been loaded correctly
head(myTemp)
#attach the data frame, so don't have to refer to variables as myTemp\$variable name
attach(myTemp)
#set the plot area for 4 graphs in 2X2 frame
par(mfrow=c(2,2))
plot(X, Y1, pch=19, col="red", cex=1.2)
plot(X, Y2, pch=19, col="orange",cex=1.2)
plot(X, Y3, pch=19, col="yellow",cex=1.2)
plot(X, Y4, pch=19, col="blue",cex=1.2)
And now we can see that the Y ‘s have different stories to tell. While the summary (descriptive) statistics are the same, the patterns of the association between Y values and the X variable are qualitatively different: Y1 is linear, but diffuse; Y2 is nonlinearly associated with X; Y3, like Y1, is linearly related to X, but one data point seems to be an outlier; and for Y4 we see a diffuse nonlinear trend and an outlier.
So, that’s the big picture here. In working with data, you must look at both ways to “see” data — you need to make graphs and you also need to calculate basic descriptive statistics.
And as to the reporting of these results, sometimes Tables are best (i.e., so others can try different statistical tests), but patterns can be quickly displayed with carefully designed graphs. Clearly, in this case, the graphs were very helpful to reveal trends in the data.
When to report numbers in a sentence? In a table? In a graph?
The choice depends on the message. Usually you want to make a comparison (or series of comparisons). If you are reporting one or two numbers in a comparison, a sentence is fine. “The two feral goat populations had similar mean numbers (120 vs. 125) of kids each breeding period.” If you have only a few comparisons to make, the text table is useful:
Table 2. Data from Kipahoehoe Natural Area Reserve, SW slope of Mauna Loa.
| Location | Number of kids |
|---|---|
| Outside fence | |
| kīpuka | 51 |
| other | 120 |
| Inside fence | |
| kīpuka | 3 |
To conclude, tables are the best way to show exact numbers and tables are preferred over graphs when many comparisons need to be made.
Note 2: A kīpuka is a land area surrounded by recent lava flows. This was a real data set, but I’ve misplaced the citation!
Couldn’t I use a pie chart for this?
Yes, but I will try and persuade you to not. Pie charts are used to show part-whole relationships. If there are just a few groups, and if we don’t care about precise comparisons, pie charts may be effective. Some good examples are Figure 1 O’Neill et al 2020,
Sometimes, people use pie charts for very small data sets (comparing two populations, or three categories, for example). These work well, but as we increase the number of categories, the graphic likely requires additional labels and remarks to clarify the message. The problem with pie charts is that they require interpretation of the angles that define the wedges, so we can’t be very precise about that. Bar charts are much better than pie charts — but can also suffer when many categories are used (Chapter 4.1).
To illustrate the problem, here’s a couple of pie charts from Microsoft Excel (a similar chart can be made with LibreOffice Calc) for our goat data set; compare this graph to the table and to the bar chart below (Fig 2).
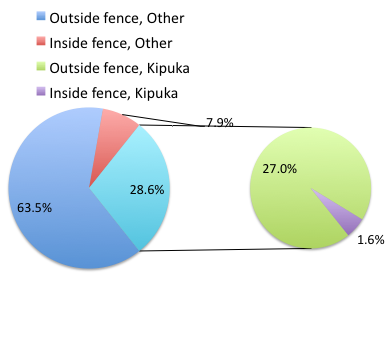
Figure 2. Excel pie chart of Table 2 data set.
A bar chart of the same data (Fig 3).
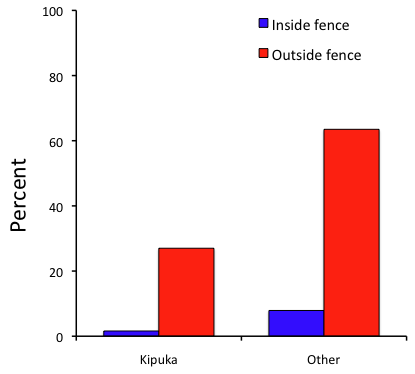
Figure 3. Bar chart of Table 2 data set
The bar chart (Fig 3) is easier to get the message across; more goat kids were found outside the fenced area then inside the fenced in areas. We can also see that more goat kids were found in the “other” areas compared to the kipuka. The pie chart (Fig 2) in my opinion fails to communicate these simple comparisons, conclusions about patterns in the data that clearly would be the take-home message from this project. Aesthetically the bar chart could be improved — a mosaic plot would work well to show the associations in the project results (See Ch 4.4 Mosaic plots). Furthermore, a strong case can be made that the bar chart is over kill — after all, there’s only the four points to show.
Note 3: A much better graph would include the actual counts, eg, a box plot as discussed in Chapter 4.3.
But we are not done with this argument, to use graphics or text to report results. Neither the bar chart (mosaic plot) or the pie chart really work. The reader has to interpret the graphics by extrapolating to the axes to get the numbers. While it may be boring — 1.5 million hits Google search “data tables” boring — tables can be used for comparisons and make the patterns more clear and informative to the reader. Here’s a different version of the table to emphasize the influence of fencing on the goat population.
Table 3. Revised Table 2 to emphasize comparisons between inside and outside the fence line on feral goat population on Mauna Loa.
| Location | Kīpuka | Other |
|---|---|---|
| Outside fence | 51 | 120 |
| Inside fence | 3 | 15 |
Table 3 would be my choice — over a sentence and over a graph. At a glance I can see that more goat kids were found outside of the fenced area, regardless of whether it was in a kipuka or some other area on the mountain side. Table 3 is an improvement over Table 2 because it presents the comparisons in a 2 X 2 format — especially useful when we have a conditional set.
For example, it’s useful to show the breakdown of voting results in tables (numbers of votes for different candidates by voters party affiliation, home district, sex, economic status, etc.). Interested readers can then scan through the table to identify the comparison they are most interested in. But often, a graph is the best choice to display information. One final point, by judiciously combining words, numbers, and images, you should be able to convey even the most complex information in a clear manner! We will not spend a lot of time on these issues, but you will want to pay some attention to these points as you work on your own projects.
Some final comments about how to present data.
What your graph looks like is up to you, lots of people have advice (eg, Klass 2012). But we all know poor graphs when we see them in talks or in papers; we know them when we struggle to make sense of the take-home message. We know them when we feel like we’re missing the take-home message.
Here’s my basic, very subjective take on communicating information with graphics — aka a grammar of graphics, sensu Tufte 2001, and Wilkinson 2005.
- Always include proper labeling: axes, units, legends, and captions.
- Minimize white space (for example, the scatter plots above could be improved simply by increasing the point size of the data points)
- Yes, minimize white space, but always respect the scale, particularly when comparisons are intended.
- Avoid bar charts for comparisons if you are trying to compare more than about three or four things.
- Use color sparingly and with intention: a consistent palette distinguishes groups.
- Avoid overly simple graphs with just a handful of points or bars. Just write it up!
- A graphic in a science report that is worth “a thousand words” probably is too complicated, too much information, and, very likely, whatever message you are trying to convey is better off in the text.
Clever graphics may be visually stunning and, perhaps, serve well to advertise the take home message, but likely they need to be accompanied by a sophisticated text as guide to those take home messages.
Homework to go with this topic.
Homework 2B: Graphs in Mike’s Workbook for biostatistics.
Quiz
In addition to ten general questions in quiz-form about this page contents, a total of 94 questions among the several subchapters, a mix of true or false and multiple choice question format.
Quiz Chapter 4
How to report statistics
Chapter 4 contents