14 – ANOVA designs, multiple factors
Introduction
In our previous discussions about t-tests and ANOVA we focused on procedures with one dependent (response) variable and a single independent (predictor) factor variable that may cause variation in the response variable. In this chapter we extend our discussions about the general linear model by reviewing
- One-way ANOVA and provided a few examples of the one-way design.
- To review and set the stage for adding a second independent variable to the model.
Additional one-way ANOVA examples
1. In a plants, we may have a response variable like height and one factor variable (location: sun vs. shade) thought to influence plant height (eg, Aphalo et al 1999).
2. Pulmonary macrophage phagocytosis behavior (response variable) after exposure of toads to clean air or ozone (factor with 2 levels) (Dohm et al. 2005).
3. Monitor weight change on subjects after 6 weeks eating different diet (DASH, control) (Elmer et al. 2006).
All three of the examples are based on the same statistical model which may be written as:
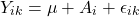
where μ is the grand mean, Y is the response variable and A is the independent variable, or factor, with k = 1, 2, …. K levels, groups, or treatments. The total number of experimental units (eg, subjects) is given by i = 1, 2, 3, … n. Note that in the first and third examples, because there were only two groups (example 1: k = location, shade; example 3: k = DASH, control) note that this problem could have been evaluated as an independent sample t-test. For the second example, there were three groups so k = clean air, first ozone level, second ozone level).
Two-way ANOVA with replication
As useful as the one-way ANOVA design can be, it is a “one-factor-at-a-time” approach (Radzilani et al 2025), experiments are typically more complicated than a single t-test or one-way ANOVA design can handle; rarely would we conduct an experiment that reflects only one source of variation. Looking only at variability for one factor at a time while while keeping all other factors constant ignores interactions between factors, resulting in potentially serious model bias (eg, discussed in Vatcheva et al 2015).
For example, while diet has a profound effect on weight, clearly, activity levels are also important. At a minimum, when considering a weight loss program, we would want to control or monitor activity of the subjects. This is a two-factor model, and the main effects, the two factors, were diet (factor A) and activity, (factor B). Both are expected to affect weight loss, and, perhaps, they may do so in complicated ways — an interaction (eg, on DASH diet, weight loss is accelerated when subjects exercise regularly).
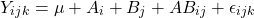
The subject of this chapter is the introduction to two-way ANOVA designs. In fact, to many, ANOVA design is practically synonymous to a statistician when they think about experimental design (Lindman 1992; Quinn and Keough 2002). As noted by Quinn and Keough (2002) in the preface to their book, “… many biological hypotheses, even deceptively simple ones, are matched by complex statistical models” (p. xv). Once you start adding factor variables there becomes a number of ways in which the groups and experimental units can be distributed, and thus impact the inferences one can make from the ANOVA results. The first statistical model we introduced was the one-way ANOVA. Next, we begin the two-way ANOVA with the crossed, balanced, fully replicated design. Along the way we introduce model symbols to help us communicate the design structure and implications of the statistical models.
Quizzes in this chapter
A total of 71 questions among the several subchapters, a mix of true or false and multiple choice question format.
Chapter 14 contents
13.1 – ANOVA Assumptions
Introduction
Like all parametric tests, assumptions are made about the data in order to justify and trust estimates and inferences drawn from ANOVA. While acknowledging the “experimental design” message suggested by the xkcd panel in Figure 1 — the presence of a large effect size between groups mitigates the technical necessities of inferential statistics — of course, not all of our projects will have such obvious results. Understanding the impact of assumptions on inference is a key concept in (bio)statistics: when the p-value is close to the Type I error rate, deviations from assumptions may reduce our confidence in the “statistical significance” of the result.

Figure 1. xkcd.com “Statistics,” https://xkcd.com/2400/.
ANOVA assumptions include:
- Data come from normal distributed population. View with a histogram or Q-Q plot. Test with Shapiro-Wilks or other appropriate goodness of fit test (see Question 1 below). Normality tests are the subject of Chapter 13.3.
- Sample size equal among groups.
- This is an example of a potentially confounding factor — If sample sizes differ, then any difference in means could be simply because of differences in sample size! This gets us into weighted versus unweighted means.
- You shouldn’t be surprised that modern implementations of ANOVA in software easily handle (adjust for) these known confounding factors. Depending on the program, you’ll see “Adjusted means,” “least squares means,” “Marginal means” etc. This just implies that the group means are compared after accounting for confounding factors.
- Importantly, as long as sample sizes among the groups are roughly equivalent, normality assumption is not a big deal (low impact on risk of Type I error).
- Independence of errors. One consequence of this assumption is that you would not view 100 repeated observations of a trait on the same subject as 100 independent data points. We’ll return to this concept more in the next two lectures. Some examples:
-
- Colorimetric assay where the signal changes over time, and you measure in order (eg, samples from group 1 first, samples from group 2 second, etc.) — this confounds group with time.
- The consequence is that you are far more likely to reject the null hypothesis, committing a Type I error.
- Let’s say you are observing running speeds of ten mongoose. However, it turns out that five of your subjects are actually from the same family, identical quintuplets! Do you really have ten subjects?
- Compare brain-body mass ratio among different species; this is a classic comparative method problem (Fig 3). Since 1985 (Felsenstein 1985), it was recognized that the hierarchical evolutionary relationships among the species must be accounted for to control for lack of independence among the taxa tested. See Phylogenetically independent contrasts, Chapter 20.12.
- Colorimetric assay where the signal changes over time, and you measure in order (eg, samples from group 1 first, samples from group 2 second, etc.) — this confounds group with time.
- Equal variances (homogeneity) among groups. See Chapter 13.4 for how to test this for multiple groups.
Impact of assumptions
R — and pretty much all statistics packages — will calculate the ANOVA table and the p-value, but it is up to you to recognize that the P-value is accurate only if the assumptions are met. Violation of the assumption of normality can lead to Type I errors occurring more often than the 5% level. What to do if the assumptions are violated?
If the violation is due to only a handful of the data, you might proceed anyway. But following a significant test for normality, we could avoid the ANOVA in favor of nonparametric alternatives (Chapter 15), or, we might try to transform the data.
Consider a histogram of brains weight measures in grams for a variety of mammals (Fig 2).
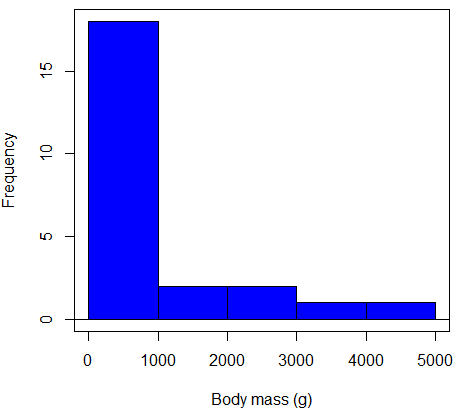
Figure 2. Histogram of body mass (g) for 24 mammals (data from Boddy et al 2012).
We will introduce a variety of statistical tests of the assumption of normality in Chapter 13.3, but looking at a histogram as part of our data exploration, we clearly see the data are right-skewed (Fig 2). Is this an example of normal distributed sample of observations? Clearly not. If we proceed with statistical tests on the raw data set, then we are more likely to commit a Type I error (ie, we will reject the null hypothesis more often than we should).
A comment on normality and biology. It is very possible that data may not be normally distributed or have equal variances on the original scale, but a simple mathematical manipulation may take care of that. In fact, in many case in biology that involve growth, many types of variables are expected to not be normal on the original scale. For example, while the relationship between body mass,  , and metabolic rate,
 , in many groups of organisms is allometric and increases positively, the relationship
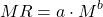
is not directly proportional (linear) on the original scale. By taking the logarithm of both body mass and metabolic rate, however, the relationship is linear
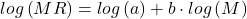
In fact, taking the logarithm (base 10, base 2, or base e) is often a common solution to both non-normal data (Fig 2) and unequal variances.
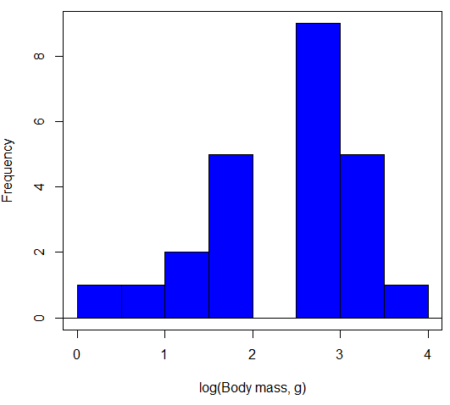
Figure 3. Histogram of log10-transformed body mass observations from Figure 2.
Other common transformations include taking the square root or the inverse of the square-root for skewed or kurtotic sample distributions, and the arcsine for frequencies (since frequencies can only be from 0 to 1 — need to “stretch the data” to make frequencies fit procedures like ANOVA). There are many issues about data transformation, but keep in mind three points. After completing the transformation, you should check the assumptions (normality, equal variances) again.
You may need to recode the data before applying a transform. For example, you cannot take the square root or logarithm of negative numbers. If you do not recode the data, then you will lose these observations in your subsequent analyses. In many cases, this problem is easily solved by adding 1 to all data points before making the transform. I prefer to make the minimum value 1 and go from there. The justification for data transformation is basically to realize that there is no necessity to use the common arithmetic or linear scale: many relationships are multiplicative or nonadditive (eg, rates in biology and medicine).
Note 1: Instead of transformations or other ad hoc manipulations of the data, modern statistical approaches favor modeling the error structure of the data within a Generalized Linear Model framework (St.-Pierre et al 2018). The advantage of the model approach is that parameter estimation occurs on the raw data. Use of transformations may, however, remain a better choice. While statistically justified, the generalized linear model approach may also tend to have higher rates of Type II error compared to simple transformations.
Statistical outlier
Another topic we should at least mention here is the concept of outliers. While most observations tend to cluster around the mean or middle of the sample distribution, occasionally one or more observations may differ substantially from the others. Such values are called outliers, and we note that there are two possible explanations for an outlier
- the value could be an error.
- it is a true value.
Note 2: “it is a true value,” and there may be an interesting biological explanation for its cause, ie, extraordinary individuals.
We encountered a clear outlier in the BMI homework. If the reason is (1), then we go back and either fix the error or delete it from the worksheet. If (2), however, then we have no objective reason to exclude the point from our analyses.
We worry if the outlier influences our conclusions — so it is a good idea to run your analyses with and without the outlier. If your conclusions remain the same, then no worries. If your conclusions change based on one observation, then this is problematic. For the most part you are then obligated to include the outlier and the more conservative interpretation of your statistical tests.
ANOVA is robust to modest deviations from assumptions
A comment about ANOVA assumptions ANOVA turns out to be robust to violations of item (1) or (2). That means unless the data are really skewed or the group sizes are very different, ANOVA will perform well (Type I error rate stays close to the specified 5% level). We worry about this however when p-value is very close to alpha!!
The third assumption is more important in ANOVA.
Like the t-test, ANOVA makes the assumption of equal variances among the groups, so it will be helpful to review why this assumption is important to both the t-test and ANOVA. In the two-sample independent t-test, the pooled sample variance,  , is taken as an estimate of the population variance,
 . If you recall,
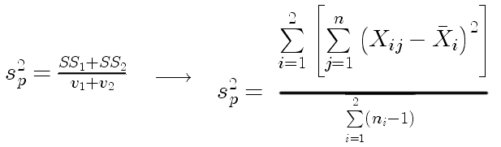
where  refers to the sum of squares for the first group and
 refers to the second group sum of squares (see our discussion on measures of dispersion) and
 refers to the degrees of freedom for the first group and
 refers to the second group degrees of freedom. We make a similar assumption in ANOVA. We assume that the variances for each sample are the same and therefore that they all estimate the population variance . To say it in another way, we are assuming that all of our samples have identical variability
Once we make this assumption, we may pool (or combine) all of the SSs and DFs for all groups as our best estimate of the population variance, . The trick to understanding ANOVA is to realize that there can be two types of variability: there is variability due to being part of a group (eg, even though ten human subjects receive the same calorie-restricted diet, not all ten will loose the same amount of weight) and there is variability among or between groups (eg, on average, all subjects who received the calorie-restricted diet lost more weight than did those subjects who were on the non-restricted diet).
Example
The encephalization index (or encephalization quotient) is defined as the ratio of size the brain compared to body size. While there is a well-recognized increase in brain size given increased body size, encephalization describes a shift of function to cortex (frontal, occipital, parietal, temporal) from noncortical parts of the brain (cerebellum, brainstem). Increased cortex is associated with increased complexity of brain function; for some researchers, the index is taken as a crude estimate of intelligence. Figure 4A shows plot of brain mass in grams versus body size (grams) for 24 mammal species (data sampled from Boddy et al 2012); Figure 4B shows the same data, but following log10-transform of both variables.
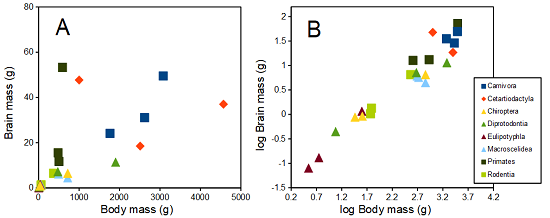
Figure 4. Plot of brain and body weights (A) and log10-log10 transform (B) for a variety of species (data from Boddy et al 2012). The ratio is called encephalization index.
Looking at the two figures the linear relationship between the two variables is obvious in Figure 4B, less so for Figure 4A. Thus, one biological justification for transformation of the raw data is exemplified with the brain-body mass dataset: the association is allometric not additive. The other reason to apply a transform is statistical; the log10-transform improves the normality of the variables. Take a look at the Q-Q plot for the raw data (Fig 5) and for the log10-transformed data (Fig 6).
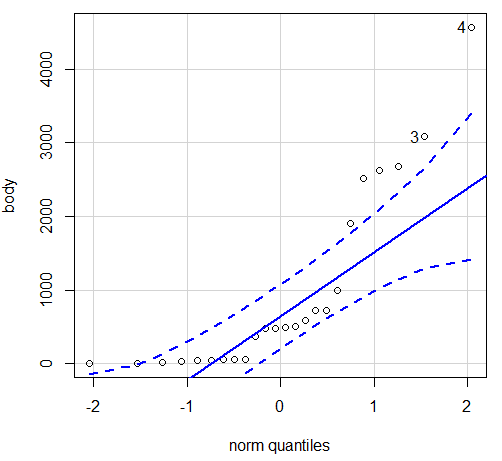
Figure 5. Q-Q plot, body mass, raw data. Compare to Figure 2.
Figure 5 is a good test of your observation skills — what are you supposed to look for in a Q-Q plot? Follow the dots — the data don’t fall on the straight line. A few even fall outside of the confidence interval (the curved dashed lines), which suggests the data were not normally distributed (see histogram, Fig 2). And for the transformed data, the Q-Q plot is shown in Figure 6.
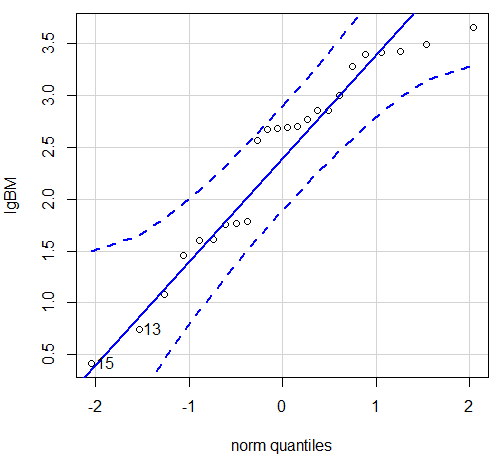
Figure 6. Q-Q plot same data, log10-transformed, compare to Figure 2.
Compared to the raw data, the transformed data now fall on the line and none are outside of the confidence interval. We would conclude that the transformed data are more normal, thus, better meeting the assumptions of our parametric tests.
Lack of independence among data
Species comparisons are common in evolutionary biology and related fields. As noted earlier, comparative data should not be treated as independent data points (discussed in 20.12 – Phylogenetically independent contrasts). For our 24 species, I plotted the estimate of the phylogeny (timetree.org), represented in Figure 7. Some species are closely related (eg the two elephant shrews, Rhynchocyon genus). Thus, because of the hierarchical, nested nature of evolution — first articulated by Charles Darwin — instead of 24 independent data points, we have eight clusters of points (see Question 4).
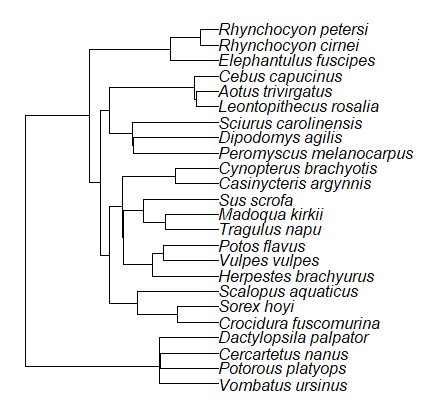
Figure 7. Phylogenetic tree of 24 species used in this report.
Note 3: The relevant quote from Charles Darwin: “… the inevitable result is that the modified descendants proceeding from one progenitor become broken up into groups subordinate to groups,” and was illustrated by the only figure in Origin of Species (both quote and illustration are in Chapter 4).
The conclusion? We don’t have 24 data points, more like 8 points. Because the species are more or less related, there are fewer than 24 independent data points. Statistically, this would mean that the errors are correlated. Various approaches to account for this lack of independence have been developed; perhaps the most common approach is to apply phylogenetically independent contrasts, a topic discussed in Chapter 20.12. (Boddy et al 2012 used this approach.)
Note 4: See 20.11 – Plot a Newick tree for how to plot phylogeny trees in R.
Questions
- Make a histogram for the brain mass data set.
- Shapiro-Wilks is one test of normality.
- Can you recall the name of the other normality tests we named?
- Run tests of normality on both body mass and brain mass data. Interpret the results, frame your response with keywords: “central tendency,” “outliers,” “shape,” and “symmetry.”
- Calculate moment statistics for the body mass and brain mass data set, both raw and log10-transformed data. Interpret your results, taking care to frame your answer with the following keywords: “shape,” “symmetry,” and “peakedness” (aka “tailedness”).
- We introduced the lack of independence for comparative data attributed to the evolutionary process. Statistically, the impact is on degrees of freedom; for example, if we ignore the lack of independence in the data set, df = 22 for the slope coefficient in a linear regression. However, given the degrees of freedom would be closer to six! What are the effects on Type I error rate of lack of independence?
Quiz Chapter 13.1
ANOVA assumptions
Data set and R code used in this page
species, order, body, brain
'Herpestes ichneumon', Carnivora, 1764, 24.1
'Potos flavus', Carnivora, 2620, 31.05
'Vulpes vulpes', Carnivora, 3080, 49.5
'Madoqua kirkii', Cetartiodactyla, 4570, 37
'Sus scrofa', Cetartiodactyla, 1000, 47.7
'Tragulus napu', Cetartiodactyla, 2510, 18.5
'Casinycteris argynnis', Chiroptera, 40.5, 0.92
'Cynopterus brachyotis', Chiroptera, 29, 0.88
'Potorous platyops', Chiroptera, 718, 6.5
'Cercartetus nanus', Diprotodontia, 12, 0.44548
'Dactylopsila palpator', Diprotodontia, 474, 7.15876
'Vombatus ursinus', Diprotodontia, 1902, 11.396
'Crocidura fuscomurina', Eulipotyphla, 5.6, 0.13
'Scalopus aquaticus', Eulipotyphla, 39.6, 1.48
'Sorex hoyi', Eulipotyphla, 2.6, 0.107
'Elephantulus fuscipes', Macroscelidea, 57, 1.33
'Rhynchocyon cirnei', Macroscelidea, 490, 6.1
'Rhynchocyon petersi', Macroscelidea, 717.3, 4.46
'Aotus trivirgatus', Primates, 480, 15.5
'Cebus capucinus', Primates, 590, 53.28
'Leontopithecus rosalia', Primates, 502.5, 11.7
'Dipodomys agilis', Rodentia, 61.4, 1.34
'Peromyscus melanocarpus', Rodentia, 58.8, 1.03
'Sciurus carolinensis', Rodentia, 367, 6.49
The Newick code for the tree in Figure 6.
((Vombatus_ursinus:48.94499077,((Potorous_platyops:47.59556667,Cercartetus_nanus:47.59556667)'14':0.66887333,Dactylopsila_palpator:48.26444000)'13':0.68055077)'11':109.65259681,(((((Crocidura_fuscomurina:33.74066667,Sorex_hoyi:33.74066667)'10':33.03022424,Scalopus_aquaticus:66.77089091)'19':22.55292749,(((Herpestes_brachyurus:54.32144118,(Vulpes_vulpes:45.52834967,Potos_flavus:45.52834967)'9':8.79309151)'22':23.43351523,((Tragulus_napu:43.96862857,Madoqua_kirkii:43.96862857)'8':17.99735995,Sus_scrofa:61.96598852)'6':15.78896789)'30':0.77378567,(Casinycteris_argynnis:35.20000000,Cynopterus_brachyotis:35.20000000)'29':43.32874208)'27':10.79507632)'35':7.13857077,(((Peromyscus_melanocarpus:69.89837667,Dipodomys_agilis:69.89837667)'43':0.64655123,Sciurus_carolinensis:70.54492789)'42':19.27825952,((Leontopithecus_rosalia:18.38385647,Aotus_trivirgatus:18.38385647)'40':1.29720005,Cebus_capucinus:19.68105652)'48':70.14213090)'51':6.63920175)'47':8.99739162,(Elephantulus_fuscipes:39.23366667,(Rhynchocyon_cirnei:15.34500000,Rhynchocyon_petersi:15.34500000)'39':23.88866667)'56':66.22611412)'55':53.13780679);
Chapter 13 contents
12.7 – Many tests one model
Introduction
In our introduction to parametric tests we so far have covered one and two sample t-tests and now the multiple sample or one-way analysis of variance (ANOVA). In subsequent sections we will cover additional tests, each with their own name. It is time to let you in on a little secret. All of these tests, t-tests, ANOVA, and linear and multiple regression we will work on later in the book belong to one family of statistical models. That model is called the general Linear Model (LM), not to be confused with the Generalized Linear Model (GLM) (Burton et al 1998; Guisan et al 2002). This greatly simplifies our approach to learning how to implement statistical tests in R (or other statistical programs) — you only need to learn one approach: the general Linear Model (LM) function lm().
Brief overview of linear models
With the inventions of correlation, linear regression, t-tests, and analysis of variance in the period between 1890 and 1920, subsequent work led to the realization that these tests (and many others!) were special cases of a general model, the general linear model, or LM. The LM itself is a special case of the generalized linear model, or GLM; among the differences between LM and GLM, in LM, the dependent variable is ratio scale and errors in the response (dependent) variable(s) are assumed to come from a Gaussian (normal) distribution. In contrast, for GLM, the response variable may be categorical or continuous, and error distributions other than normal (Gaussian), may be applied. The GLM user must specify both the error distribution family (eg, Gaussian) and the link function, which specifies the relationship among the response and predictor variables. While we will use the GLM functions when we attempt to model growth functions and calculate EC50 in dose-response problems, we will not cover GLM this semester.
The general Linear Model, LM
In matrix form, the LM can be written as

where  is a matrix of response variables predicted by independent variables contained in matrix
 and weighted by linear coefficients in the vector b. Basically, all of the predictor variables are combined to produce a single linear predictor
 . By adding an error component we have the complete linear model.

In the linear model, the error distribution is assumed to be normally distributed, or “Gaussian.”
R code
The bad news is that LM in R (and in any statistical package, actually) is a fairly involved set of commands; the good news is that once you understand how to use this command, and can work with the Options, you will be able to conduct virtually all of the tests we will use this semester, from two-sample t-tests to multiple linear regression. In the end, all you need is the one Rcmdr command to perform all of these tests.
We begin with a data set, ohia.ch12. Scroll down this page or click here to get the R code.
I found a nice report on a common garden experiment with o`hia (Corn and Hiesey 1973). O`hia (Metrosideros polymorpha) is an endemic, but wide-spread tree in the Hawaiian islands (Fig 1). O`hia exhibits pronounced intraspecific variation: individuals differ from each other. O`hia grows over wide range of environments, from low elevations along the ocean right up the sides of the volcanoes, and takes on many different growth forms, from shrubs to trees. Substantial areas of o`hia trees on the Big Island are dying, attributed to two exotic fungal species of the genus Ceratocystis (Asner et al., 2018).
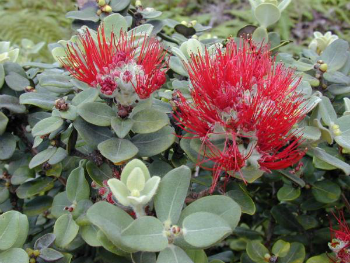
Figure 1. O’hia, Metrosideros polymorpha. Public domain image from Wikipedia.
The Biology. Individuals from distinct populations may differ because the populations differ genetically, or because the environments differ, or, and this is more realistic, both. Phenotypic plasticity is the ability of one genotype to produce more than one phenotype when exposed to different environments. Environmental differences are inevitable when populations are from different geographic areas. Thus, in population comparisons, genetic and environmental differences are confounded. A common garden experiment is a crucial genetic experiment to separate variation in phenotypes, P, among populations into causal genetic or environmental components.
If you recall from your genetics course, 
where G stands for genetic (alleles) differences among individuals and E stands for environmental differences among individuals. In brief, the common garden experiment begins with individuals from the different populations are brought to the same location to control environmental differences. If the individuals sampled from the populations continue to differ despite the common environment, then the original differences between the populations must have a genetic basis, although the actual genetic scenario may be complicated (the short answer is that if “genotype by environment interaction exists, then results from a common garden experiment cannot be generalized back to the natural populations/locations — this will make more sense when we talk about two-way ANOVA). For more about common garden experiments, see de Villemereuil et al (2016). Nuismer and Gandon (2008) discuss statistical aspects of the common garden approach to studying local adaptation of populations and the more powerful “reciprocal translocation” experimental design.
Managing data for linear models
First, your data must be stacked in the worksheet. That means one column is for group labels (independent variable), the other column is for the response (dependent) variable.
If you have not already downloaded the data set, ohia.ch12, do so now. Scroll down this page or click here to get the R code.
Confirm that the worksheet is stacked. If it is not, then you would rearrange your data set using Rcmdr: Data → Active data set → Stack variables in data set…
The data set contains one factor, “Site” with three levels (M-1, 2, 3). M stands for Maui, and collection sites were noted in Figure 2 of Corn and Hiesey (1973). Once the dataset is in Rcmdr, click on View to see the data (Fig 2). There are two response variables, Height (shown in red below) and Width (shown in blue below).
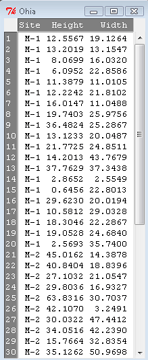
Figure 2. The o`hia dataset as viewed in R Commander.
The data are from Table 5 of Corn and Hiesey 1973. (I simulated data based on their mean/SD reported in Table 5). This was a very cool experiment: they collected o`hia seeds from three elevations on Maui, then grew the seeds in a common garden in Honolulu. Thus, the researchers controlled the environment; what varied, then were the genotypes.
As always, you should look at the data. Box plots are good to compare central tendency (Fig 3).
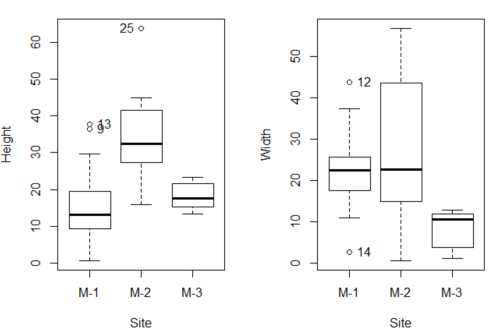
Figure 3. Box plots of growth responses of o`hia seedlings collected from three Maui sites, M-1 (elevation 750 ft), M-2 (elevation 1100 ft), and M-3 (elevation 6600 ft). Data adapted from Table 5 of Corn and Hiersey 1973.
R code to make Figure 4 plots
par(mfrow=c(1,2))
Boxplot(Height ~ Site, data = ohia, id = list(method = "y"))
Boxplot(Width ~ Site, data = ohia, id = list(method = "y"))
This dataset would typically be described as a one-way ANOVA problem. There was one treatment variable (population source) with three levels (M-1, M-2, M-3). From Rcmdr we select the one-way ANOVA: Statistics → Means → One-way ANOVA… and after selecting the Groups (from the Site variable) and the Response variable (eg, Height), we have
AnovaModel.1 <- aov(Height ~ Site, data = ohia.ch12)
summary(AnovaModel.1)
           Df Sum Sq   Mean Sq  F value          Pr(>F)
Site        2   4070    2034.8    22.63 0.000000131 ***
Residuals  47   4227      89.9
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Let us proceed to test the null hypothesis (what was it???) using instead the lm() function. Four steps in all.
Step 1. Rcmdr: Statistics → Fit models → Linear model … (Fig 4).
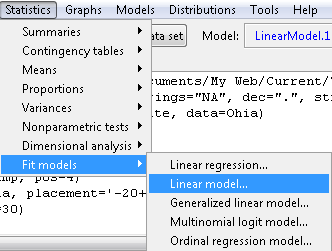
Figure 4. R Commander, select to fit a Linear model.
Step 2. The pop up menu below (Fig 5) follows.
First, What is our response (dependent) variable? What is our predictor (independent) variable? We then input our model. In this case, with only the one predictor variable, Sites, our model formula is simple to enter (Fig 5): Height ~ Site.
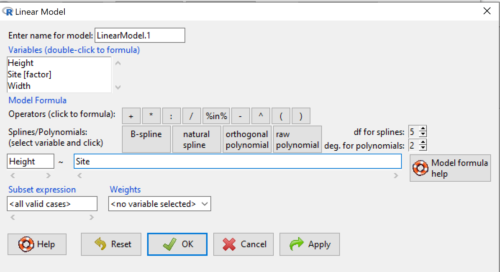
Figure 5. Input linear model formula, Height ~ Site.
Step 3. Click OK to carry out the command.
Here is the R output and the statistical results from the application of the linear model.
LinearModel.1 <- lm(Height ~ Site, data=ohia.ch12)
summary(LinearModel.1)

Call:
lm(formula = Height ~ Site, data = ohia.ch12)

Residuals:
    Min     1Q   Median     3Q     Max
-18.808 -4.761   -1.755  4.758  29.257

Coefficients:
             Estimate  Std. Error  t value      Pr(>|t|)
(Intercept)    15.314       2.121    7.222 0.00000000377 ***
Site[T.M-2]    19.261       2.999    6.423 0.00000006153 ***
Site[T.M-3]     2.924       3.673    0.796          0.43
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Residual standard error: 9.483 on 47 degrees of freedom
Multiple R-squared:  0.4905,	Adjusted R-squared:  0.4688
F-statistic: 22.63 on 2 and 47 DF,  p-value: 0.0000001311
End R output
The linear model has produced a series of estimates of coefficients for the linear model, statistical tests of the significance of each component of the model, and the coefficient of determination, R2, which is a descriptive statistic of how well model fits the data. Instead of our single factor variable for Source Population like in ANOVA we have a series of what are called dummy variables or contrasts between the populations. Thus, there is a coefficient for the difference between M-1 and M-2. “Site[T.M-2]” in the output, between M-1 and M-3, and between M-2 and M-3.
Note 1: Brief description of linear model output; these will be discussed fuller in Chapter 17 and Chapter 18. The residual standard error is a measure of how well a model fits the data. The Adjusted R-squared is calculated by dividing the residual mean square error by the total mean square error. The result is then subtracted from 1.
It also produced our first statistic that assesses how well the model fits the data called the coefficient of determination, R2. An of of 1.0 would indicate that all variation in the data set can be explained by the predictor variable(s) in the model with no residual error remaining. Our value of 49% indicates that nearly 50% of the variation in height of the seedlings grown under common environments are due to the source population (= genetics).
Step 4. But we are not quite there — we want the traditional ANOVA results (recall the ANOVA table).
To get the ANOVA Table we have to ask Rcmdr (and therefore R) to give us this. Select
Rcmdr: Models → Hypothesis tests → ANOVA table … (Fig 6).
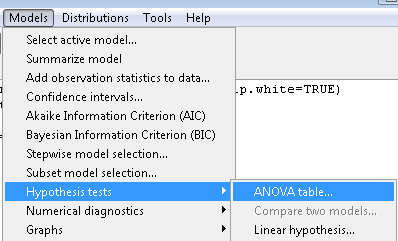
Figure 6. To retrieve an ANOVA table, select Models, Hypothesis tests, then ANOVA table…
Here’s the type of tests for the ANOVA table, select the default (Fig 7).
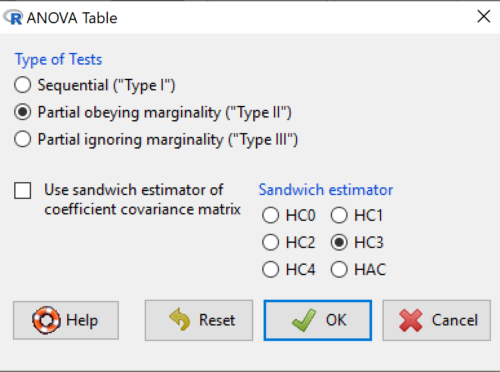
Figure 7. Options for types of tests.
Now, in the future when we work with more complicated experimental designs, we will also need to tell R how to conduct the test. For now, we will accept the default Type II type of test and ignore sandwich estimators. You should confirm that for a one-way ANOVA, Type I and Type II choices give you the same results.
The reason they do is because there is only one factor — when there are more than one factors, and if one or both of the factors are random effects, then Type I, II, and III will give you different answers. We will discuss this more as needed, but see the note below about default choices.
Note 2: Marginal or partial effects are slopes (or first derivatives): they quantify the change in one variable given change in one or more independent variables. Type I tests are sequential: sums of squares are calculated in the order the predictor variables are entered into the model. Type II tests the sums of squares are calculated after adjusting for some of the variables in the model. Type III, every sum of square calculation is adjusted for all other variables in the model. Sandwich estimator refers to algorithms for calculating the structure of errors or residuals remaining after the predictor variables are fitted to the data. The assumption for ordinary least square estimation (See Chapter 17) is that errors across the predictors are equal, ie, equal variances assumption. HC refers to “heteroscedasticity consistent” (Hayes and Chai 2007), which infers fitting of a model does not assume equal error variance across all observations.
By default, Rcmdr makes Type II. In most of the situations we will find ourselves this semester, this is the correct choice.
Below is the output from the ANOVA table request. Confirm that the information is identical to the output from the call to aov() function.
Anova(LinearModel.1, type = "II")
Anova Table (Type II tests)
Response: Height
          Sum Sq  Df   F value        Pr(>F)
Site      4069.7   2    22.626  0.0000001311 ***
Residuals 4226.9  47
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
And the other stuff we got from the linear model command? Ignore for now but make note that this is a hint that regression and ANOVA are special cases of the same model, the linear model.
We do have some more work to do with ANOVA, but this is a good start.
Why use the linear model approach?
Chief among the reasons to use the lm() approach is to emphasize that a model approach is in use. One purpose of developing a model is to provide a formula to predict new values. Prediction from linear models is more fully developed in Chapter 17 and Chapter 18, but for now, we introduce the predict() function with our O`hia example.
myModel <- predict(LinearModel.1, interval = "confidence")
head(myModel, 3)    #print out first 3 rows
#Add the output to the data set
ohiaPred <- data.frame(ohia,myModel)
with(ohiaPred, tapply(fit, list(Site), mean, na.rm = TRUE))   #print out predicted values for the three sites
Output from R
myModel <- predict(LinearModel.1, interval = "confidence")
head(myModel, 3)
       fit      lwr      upr
1 15.31374 11.04775 19.57974
2 15.31374 11.04775 19.57974
3 15.31374 11.04775 19.57974
with(myModel, tapply(fit, list(Site), mean, na.rm = TRUE))
     M-1      M-2      M-3
15.31374 34.57474 18.23796
Questions
1. Revisit ANOVA problems in homework and questions from early parts of this chapter and apply lm() followed by Hypothesis testing (Rcmdr: Models → Hypothesis tests → ANOVA table) approach instead of one-way ANOVA command. Compare results using lm() to results from One-way ANOVA and other ANOVA problems.
Quiz Chapter 12.7
Many tests one model
Data set and R code used in this page
Corn and Hiesey (1973)
| Site | Height | Width |
|---|---|---|
| M-1 | 12.5567 | 19.1264 |
| M-1 | 13.2019 | 13.1547 |
| M-1 | 8.0699 | 16.032 |
| M-1 | 6.0952 | 22.8586 |
| M-1 | 11.3879 | 11.0105 |
| M-1 | 12.2242 | 21.8102 |
| M-1 | 16.0147 | 11.0488 |
| M-1 | 19.7403 | 25.9756 |
| M-1 | 36.4824 | 25.2867 |
| M-1 | 13.1233 | 20.0487 |
| M-1 | 21.7725 | 24.8511 |
| M-1 | 14.2013 | 43.7679 |
| M-1 | 37.7629 | 37.3438 |
| M-1 | 2.8652 | 2.5549 |
| M-1 | 0.6456 | 22.8013 |
| M-1 | 29.623 | 20.0194 |
| M-1 | 10.5812 | 29.0328 |
| M-1 | 18.3046 | 22.2867 |
| M-1 | 19.0528 | 24.684 |
| M-1 | 2.5693 | 35.74 |
| M-2 | 45.0162 | 14.3878 |
| M-2 | 40.8404 | 18.8396 |
| M-2 | 27.1032 | 21.0547 |
| M-2 | 29.8036 | 16.9327 |
| M-2 | 63.8316 | 30.7037 |
| M-2 | 42.107 | 3.2491 |
| M-2 | 30.0322 | 47.4412 |
| M-2 | 34.0516 | 42.239 |
| M-2 | 15.7664 | 32.8354 |
| M-2 | 35.1262 | 50.9698 |
| M-2 | 43.6988 | 19.3897 |
| M-2 | 26.7585 | 13.8168 |
| M-2 | 36.7895 | 0.5817 |
| M-2 | 30.9458 | 53.7757 |
| M-2 | 26.8465 | 15.4137 |
| M-2 | 40.3883 | 9.2161 |
| M-2 | 30.6555 | 56.8456 |
| M-2 | 19.9736 | 44.9411 |
| M-2 | 27.676 | 36.8543 |
| M-2 | 44.084 | 24.3396 |
| M-3 | 15.2646 | 11.4999 |
| M-3 | 19.6745 | 9.7757 |
| M-3 | 23.275 | 12.7825 |
| M-3 | 16.1161 | 2.4065 |
| M-3 | 16.8393 | 1.1253 |
| M-3 | 23.107 | 3.7349 |
| M-3 | 21.5322 | 6.9725 |
| M-3 | 13.4191 | 12.2867 |
| M-3 | 14.7273 | 11.4841 |
| M-3 | 18.4245 | 11.9078 |
Chapter 12 contents
12.5 – Effect size for ANOVA
Introduction
As noted in the t-test chapter and our discussion of statistical power, an effect size is a measure of the strength of a phenomenon. An effect size calculated from data is a descriptive statistic that indicates how large (or small) the difference is between two or more samples. Effect size measures help to provide context between statistical significance, ie, p-values. Among other uses, effect size measures play an important role in meta-analysis studies biological significance (ie, importance of the measured difference).
Estimation of effect size
eta-squared (η2)

where SSB and SST are from the one-way ANOVA and refer to the sum of squared among (between) groups and the total sum of squares, respectively.  measures the proportion of the variation in the response variable that can be explained by membership in one of the groups.
For example, of 0.15 or 15% is interpreted to mean that just 15% of the variation in the response variable can be attributed to membership in the groups (ie, whether a subject was in control group or treatment group, only 15% of the differences between individuals can be attributed to having received control).
Note 1: η2 is just the unadjusted coefficient of determination, R2.
omega-squared (ω2)
A similar, but “less biased” effect size estimate is given by omega-squared (ω2) (Okada 2013). (The bias comes in because sample estimates were used.) Interpretation of  is the same as : measures the proportion of variation explained by membership in the groups. is given as
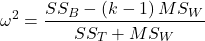
The bias for is more pronounced with small sample size, so omega-squared is preferred. will always be less than or equal to (Okada 2013).
R code
If you have not already done so, please install the package effectsize.
We’ll use the example one-way ANOVA problem from Chapter 12.2. I’ve added the data as example.ch12 and some R script to load the data, scroll to bottom of this page or click on the link).
Get 
First, get the ANOVA model. There are several ways to do this within R (and Rcmdr), the most general is to use the general linear model function, lm(),
#Get the model
AnovaModel.4 <- lm(Difference~Group, data=example.ch12)
#turn it into format that the next command needs
aov_fit <- anova(AnovaModel.4)
#get eta
effectsize(aov_fit)
R output
Parameter | Eta2 (partial) | 9e+01% CI
-----------------------------------------
Group | 0.95 | [0.88, 0.97]
is 0.95 for the Difference group.
Get
R code
omega_squared(aov_fit, partial = FALSE, ci = 0.95)
R output
Parameter | Omega2 | 1e+02% CI
---------------------------------
Group | 0.93 | [0.82, 0.97]
This is a case of a large effect due to group membership. The differences between A, B, and C means account for 93% of the variation. Note that both and  are close; note also that is greater than .
Questions
- In Chapter 7.4 we introduced the concept of number needed to treat, NNT. Discuss the concept of “important differences” between sample means of a control group and a treatment group to NNT.
- This question refers to hypothetical data presented in Chapter 12.2. For the “No difference” group, calculate and . Use the boxplots shown in Figure 1, together with effect size statistics to discuss the relationship between statistical significance (p-value) and important difference.
Quiz Chapter 12.5
Effect size for ANOVA
Data set
example.ch12 <- read.table(header=TRUE, sep=",",text="
Group, No.difference, Difference
A, 12.04822, 11.336161
A, 12.67584, 13.476142
A, 12.99568, 12.961210
A, 12.01745, 11.746712
A, 12.34854, 11.275492
B, 12.17643, 7.167262
B, 12.77201, 5.136788
B, 12.07137, 6.820242
B, 12.94258, 5.318743
B, 12.07670, 7.153992
C, 12.58212, 3.344218
C, 12.69263, 3.792337
C, 12.60226, 2.444438
C, 12.02534, 2.576014
C, 12.60420, 4.575672")
#check the dataframe
head(example.ch12)
Chapter 12 contents
12.3 – Fixed effects, random effects, and agreement
Introduction
Within discussions of one-way ANOVA models the distinction between two general classes of models needs to be made clear by the researcher. The distinction lies in how the levels of the factor are selected. If the researcher selects the levels, then the model is a Fixed Effects Model, also called a Model I ANOVA. On the other hand, if the levels of the factor were selected by random sampling from all possible levels of the factor, then the model is a Random Effects Model, also called a Model II ANOVA. This page is about such models and I’ll introduce the intraclass correlation coefficient, abbreviated as ICC, as a way to illustrate applications of Model II ANOVA.
Here’s an example to help the distinction. Consider an experiment to see if over the counter painkillers are as good as prescription pain relievers at reducing numbers of migraines over a six week period. The researcher selects Tylenol®, Advil®, Bayer® Aspirin, and Sumatriptan (Imitrex®), the latter an example of a medicine only available by prescription. This is clearly an example of fixed effects; the researcher selected the particular medicines for use.
Random effects, in contrast, implies that the researcher draws up a list of all over the counter pain relievers and draws at random three medicines; the researcher would also randomly select from a list of all available prescription medicines.
Fixed effects are probably the more common experimental approaches. To be complete, there is a third class of ANOVA called a Mixed Model or Model III ANOVA, but this type of model only applies to multidimensional ANOVA (eg, two-way ANOVA or higher), and we reserve our discussion of the Model III until we discuss multidimensional ANOVA (Table 1).
Table 1. ANOVA models
| ANOVA model | Treatments are |
| I | Fixed effects |
| II | Random effects |
| III | Mixed, both fixed & random effects |
Although the calculations for the one-way ANOVA under Model I or Model II are the same, the interpretation of the statistical significance is different between the two.
In Model I ANOVA, any statistical difference applies to the differences among the levels selected, but cannot be generalized back to the population. In contrast, statistical significance of the Factor variable in Model II ANOVA cannot be interpreted as specific differences among the levels of the treatment factor, but instead, apply to the population of levels of the factor. In short, Model I ANOVA results apply only to the study, whereas Model II ANOVA results may be interpreted as general effects, applicable to the population.
This distinction between fixed effects and random effects can be confusing, but it has broad implications for how we interpret our results in the short-term. This conceptual distinction between how the levels of the factor are selected also has general implications for our ability to acquire generalizable knowledge by meta-analysis techniques (Hunter and Schmidt 2000). Often we wish to generalize our results: we can do so only if the levels of the factor were randomly selected in the first place from all possible levels of the factor. In reality, this may not often be the case. It is not difficult to find examples in the published literature in which the experimental design is clearly fixed effects (ie, the researcher selected the treatment levels for a reason), and yet in the discussion of the statistical results, the researcher will lapse into generalizations.
Random Effects Models and agreement
Model II ANOVA is common in settings in which individuals are measured more than once. For example, in behavioral science or in sports science, subjects are typically measured for the response variable more than once over a course of several trials. Another common setting of Model II ANOVA is where more than one raters are judging an event or even a science project. In all of these cases what we are asking is about whether or not the subjects are consistent, in other words, we are asking about the precision of the instrument or measure.
In the assessment of learning by students, for example, different approaches may be tried and the instructor may wish to investigate whether the interventions can explain changes in test scores. To assess instrument validity — an item score from a grading rubric (Goertzen and Klaus 2023), tumor budding as biomarker for colorectal cancer (Bokhorst et al 2020) — agreement or concordance among two or more raters or judges (inter-rater reliability) needs to be established (same citations and references therein). For binomial data, we would be tempted to use the phi coefficient, Is it actually reliable Cohen’s kappa (two judges) or Fleiss Kappa (two or more judges) is a better tool. Phi coefficient and both assessment scores were introduced in Chapter 9.2.
For ratio scale data, agreement among scores of two or more scores from judges There is an enormous number of articles on reliability measures in the social sciences and you should be aware of a classical paper on reliability by Shrout and Fleiss (1979) (see also McGraw and Wong, 1996). Both the ICC and the Pearson product moment correlation, r, which we will introduce in Chapter 16, are measures of strength of linear association between two ratio scale variables (Jinyuan et al 2016). But ICC is more appropriate for association between repeat measures of the same thing, eg, repeat measures of running speed or agreement between judges. In contrast, the product moment correlation can be used to describe association between any two variables, eg, between repeat measures of running speed, but also between say running speed and maximum jumping height. The concept of repeatability of individual behavior or other characteristics is also a common theme in genetics and so you should not be surprised to learn that the concept actually traces to RA Fisher and his invention of ANOVA. Just as in the case of the sociology literature, there are many papers on the use and interpretation of repeatability in the evolutionary biology literature (eg, Lessels and Boag 1987; Boake 1989; Falconer and Mackay 1996; Dohm 2002; Wolak et al 2012).
Agreement and repeatability are Model II (random effects) because the subjects, items, or raters being studied are treated as a random sample from a larger population rather than specific, fixed levels of interest. In reliability studies, subjects are not chosen for their specific characteristics but as representatives of the population variability. The goal is to infer whether a measurement tool works for any future subject or rater, not just the ones tested in the study. These factors are designed to estimate variance components and generalize results beyond the specific sample used. Put another way, the goal of Model II is often to estimate how much variance is due to differences between subjects versus within subjects (repeatability), which requires treating the subject effect as random.
There are many ways to analyze these kinds of data but a good way is to treat this problem as a one-way ANOVA with Random Effects. Thus, the Random Effects model permits the partitioning of the variation in the study into two portions: the amount that is due to differences among the subjects or judges or intervention versus the amount that is due to variation within the subjects themselves. The Factor is the Subjects and the levels of the factor are how ever many subjects are measured twice or more for the response variable.
If the subjects performance is repeatable, then the Mean Square Between (Among) Subjects,  , component will be greater than the Mean Square Error component,
 , of the model. There are many measures of repeatability or reliability, but the intraclass correlation coefficient or ICC is one of the most common. The ICC may be calculated from the Mean Squares gathered from a Random Effects one-way ANOVA. ICC can take any value between zero and one.
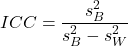
where
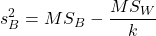
and

B and W refers to the among group (between or among groups mean square) and the within group components of variation (error mean square), respectively, from the ANOVA, MS refers to the Mean Squares, and k is the number of repeat measures for each experimental unit. In this formulation k is assumed to be the same for each subject.
By example, when a collection of sprinters run a race, if they ran it again, would the outcome be the same, or at least predictable? If the race is run over and over again and the runners cross the finish lines at different times each race, then much of the variation in performance times will be due to race differences largely independent of any performance abilities of the runners themselves and the Mean Square Error term will be large and the Between subjects Mean Square will be small. In contrast, if the race order is preserved race after race: Jenny is 1st, Ellen is 2nd, Michael is third, and so on, race after race, then differences in performance are largely due to individual differences. In this case, the Between-subjects Mean Square will be large as will the ICC, whereas the Mean Square for Error will be small, and so will the ICC.
Can the intraclass correlation be negative?
In theory, no. Values for ICC range between zero and one. The familiar Pearson product moment correlation, Chapter 16, takes any value between -1 and +1. However, in practice, negative values for ICC will result if 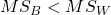 .
In other words, if the within group variability is greater than the among group variability, then negative ICC are possible. The question is whether negative estimates are ever biologically relevant or, simply result of limitations of the estimation procedure. Small ICC values and few repeats increases the risk of negative ICC estimates. Thus, a negative ICC would be “simply a(n) “unfortunate” estimate (Liljequist et al 2019). However, there may be situations in which negative ICC is more than unfortunate. For example, repeatability, a quantitative genetics concept (Falconer and Mackay 1996), can be negative (Nakagawa and Schielzeth 2010).
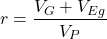
Repeatability reflects the consistency of individual traits over time (or spatially, eg, scales on on a snake), is defined as the ratio of within individual differences and among individuals differences. Thus, within individual variance is attributed to general environmental effects,  , whereas variance among individuals is both genetic and environmental. Scenarios for which repeated measures on the same individual may occur under environmental conditions, termed specific environmental effects or
 by Falconer and Mackay (1996), that negatively affect performance are not hard to imagine — it remains to be determined how common these conditions are and whether or not estimates of repeatability are negative.
ICC Example
I extracted 15 data points from a figure about nitrogen metabolism in kidney patients following treatment with antibiotics (Figure 1, Mitch et al 1977). I used a web application called WebPlot Digitizer (https://apps.automeris.io/wpd/), but you can also accomplish this task within R via the digitize package. I was concerned about how steady my hand was using my laptop’s small touch screen, a problem that very much can be answered by thinking statistically, and taking advantage of the ICC. So, rather than taking just one estimate of each point I repeated the protocol for extracting the points from the figure three times generating a total of three points for each of the 15 data points or 45 points in all. How consistent was I?
Let’s look at the results just for three points, #1, 2, and 3.
In the R script window enter
points = c(1,2,3,1,2,3,1,2,3)
Change points to character so that the ANOVA command will treat the numbers as factor levels.
points = as.character(points)
extracts = c(2.0478, 12.2555, 16.0489, 2.0478, 11.9637, 16.0489, 2.0478, 12.2555, 16.0489)
Make a data frame, assign to an object, eg, “digitizer”
digitizer = data.frame(points, extracts)
The dataset “digitizer” should now be attached and available to you within Rcmdr. Select digitizer data set and proceed with the one-way ANOVA.
Output from oneway ANOVA command
Model.1 <- aov(extracts ~ points, data=digitizer)

 summary(Model.1)
            Df    Sum Sq   Mean Sq  F value     Pr(>F)
points       2 313.38895 156.69448 16562.49 5.9395e-12 ***
Residuals    6   0.05676   0.00946
---
Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

numSummary(extracts , groups = points,
+   statistics=c("mean", "sd"))
         mean           sd data:n
1  2.04780000 0.0000000000      3
2 12.15823333 0.1684708085      3
3 16.04890000 0.0000000000      3
End R output. We need to calculate the ICC
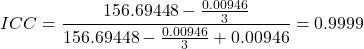
I’d say that’s pretty repeatable and highly precise measurement!
But is it accurate? You should be able to disentangle accuracy from precision based on our previous discussion (Chapter 3.5), but now in the context of a practical way to quantify precision.
ICC calculations in R
We could continue to calculate the ICC by hand, but better to have a function. Here’s a crack at the function to calculate ICC along with a 95% confidence interval.
myICC <- function(m, k, dfN, dfD) {
 testMe <- anova(m)
 MSB <- testMe$"Mean Sq"[1]
 MSE <- testMe$"Mean Sq"[2]
 varB <- MSB - MSE/k
 ICC <- varB/(varB+MSE)
 fval <- qf(c(.025), df1=dfN, df2=dfD, lower.tail=TRUE)
 CI = (k*MSE*fval)/(MSB+MSE*(k-1)*fval)
 LCIR = ICC-CI
 UCIR = ICC+CI
 myList = c(ICC, LCIR, UCIR)
 return(myList)
}
The user supplies the ANOVA model object (eg, Model.1 from our example), k, which is the number of repeats per unit, and degrees of freedom for the among groups comparison (2 in this example), and the error mean square (6 in this case). Our example, run the function
m2ICC = myICC(Model.1, 3, 2,6); m2ICC
and R returns
[1] 0.9999396 0.9999350 0.9999442
with the ICC reported first, 0.9999396, followed by the lower limit (0.9999350) and the upper limit (0.9999442) of the 95% confidence interval.
Instead of writing your own function, several R packages can calculate the intraclass correlation coefficient (ICC) and its variants. These packages include: irr, psy, psych, and rptR. For complex experiments involving multiple predictor variables, these packages are helpful for obtaining the correct ICC calculation (cf Shrout and Fleiss 1979; McGraw and Wong 1996). For the one-way ANOVA it is easier to just extract the information you need from the ANOVA table and run the calculation directly. We do so for a couple of examples.
Example: Are marathon runners consistent more consistent than my commute times?
Figure 1.Honolulu Marathon 2024 participant. Image credit: Pdubs.94, licensed under CC BY 4.0 (Creative Commons Attribution 4.0 International License), via Wikipedia.
A marathon is 26 miles, 385 yards (42.195 kilometers) long (World Athletics.org). And yet, tens of thousands of people choose to run in these events. For many, running a marathon is a one-off, the culmination of a personal fitness goal. For others, it’s a passion and a few are simply extraordinary, elite runners who can complete the courses in 2 to 3 hours (Table 3). That’s about 12.5 miles per hour. For comparison, my 20 mile commute on the H1 freeway on Oahu typically takes about 40 minutes to complete, or 27 miles per hour (Table 2, yes, I keep track of my commute times, per Galton’s famous maxim: “Whenever you can, count”).
Figure 2. View west along Interstate H-1 (Lunalilo Freeway) at 6:30AM on a weekday, Honolulu, Oahu, Hawaii. Image used with permission, credit: S. Dohm.
Table 2. A sampling of average commute speeds, miles per hour (mph), on the H1 freeway during DrD’s morning commute (distance about 19.3 miles).
| Week | Monday | Tuesday | Wednesday | Thursday | Friday |
|---|---|---|---|---|---|
| 1 | 28.5 | 23.8 | 28.5 | 30.2 | 26.9 |
| 2 | 25.8 | 22.4 | 29.3 | 26.2 | 27.7 |
| 3 | 26.2 | 22.6 | 24.9 | 24.2 | 34.3 |
| 4 | 23.3 | 26.9 | 31.3 | 26.2 | 30.2 |
Try on your own.
Calculate the ICC for my commute speeds.
Run the one-way ANOVA to get the necessary mean squares and input the values into our ICC function. We have
require(psych)
m2ICC = myICC(AnovaModel.1, 4, 4,11); m2ICC
[1] 0.7390535 0.6061784 0.8719286
Repeatability, as estimated by the ICC, was 0.74 (95% CI 0.606, 0.872), for repeat measures of commute times.
We can ask the same about marathon runners — how consistent from race to race are these runners? The following data are race times drawn from a sample of runners who completed the Honolulu Marathon in both 2016 and 2017 in 2 to 3 hours (times recorded in minutes). In other words, are elite runners consistent?
Table 3. Honolulu marathon running times (min) for eleven repeat, elite runners.
| ID | Time |
|---|---|
| P1 | 179.9 |
| P1 | 192.0 |
| P2 | 129.9 |
| P2 | 130.8 |
| P3 | 128.5 |
| P3 | 129.6 |
| P4 | 179.4 |
| P4 | 179.7 |
| P5 | 174.3 |
| P5 | 181.7 |
| P6 | 177.2 |
| P6 | 176.2 |
| P7 | 169.0 |
| P7 | 173.4 |
| P8 | 174.1 |
| P8 | 175.2 |
| P9 | 175.1 |
| P9 | 174.2 |
| P10 | 163.9 |
| P10 | 175.9 |
| P11 | 179.3 |
| P11 | 179.8 |
Stacked worksheet, P refers to person, therefore P1 is person ID 1, P2 is person ID 2, and so on.
After running a one-way ANOVA, here are results for the marathon runners
m2ICC = myICC(Model.1, 2, 10,11); m2ICC
[1] 0.9780464 0.9660059 0.9900868
Repeatability, as estimated by the ICC, was 0.98 (95% CI 0.966, 0.990), for repeat measures of marathon performance. Put more simply, knowing what a runner did in 2016 I would be able to predict their 2017 race performance with high confidence, 98%!
And now, we compare: the runners are more consistent!
Clearly this is an apples-to-oranges comparison, but it gives us a chance to think about how we might make such comparisons. The ICC will change because of differences among individuals. For example, if individuals are not variable, if everyone finishes the race at the same time, then the ICC will be low (or even zero). Because there is no variance to be attributed to individual differences, the proportion of total variance explained by those differences will be being minimal.
Visualizing repeated measures.
Waterfall plot.
If just two measures, then a profile plot will do. We introduced profile plots in the paired t-test chapter (Ch10.3). For more than two repeated measures, a line graph will do (see question 9 below). Another graphic increasingly used is the waterfall plot (waterfall chart), particularly for before and after measures or other comparisons against a baseline. For example, it’s a natural question for our eleven marathon runners — how much did they improve on the second attempt of the same course? Figure 3 shows my effort to provide a visual.
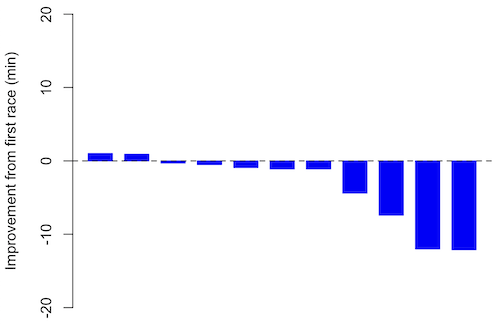
Figure 3. Simple waterfall plot of race improvement for Table 3 data. Dashed horizontal line at zero.
R code
Data wrangling: Create a new variable, eg, race21, by subtracting the first time from the second time. Multiply by -1 so that improvement (faster time in second race) is positive. Finally, apply descending sort so that improvement is on the left and increasingly poorer times are on the right.
df <- data.frame(
ID = rep(paste0("P", 1:11), each = 2),
Time = c(179.9,192.0,
129.9,130.8,
128.5,129.6,
179.4,179.7,
174.3,181.7,
177.2,176.2,
169.0,173.4,
174.1,175.2,
175.1,174.2,
163.9,175.9,
179.3,179.8)
)

# Convert to wide format
df_wide <- reshape(df, idvar = "ID", timevar = "ID",
direction = "wide")

# Extract first and second times manually
time_matrix <- matrix(df$Time, ncol = 2, byrow = TRUE)
colnames(time_matrix) <- c("Time1", "Time2")

# Calculate improvement (second - first)
base21 <- time_matrix[,2] - time_matrix[,1]

# Sort for waterfall display
base21 <- sort(base21, decreasing = TRUE)

# Waterfall plot
barplot(base21, col="blue", border="blue", space=0.5,
ylim=c(-20,20),
ylab="Improvement from first race (min)")
abline(h=0, lty=2)
Interpretation.
From the graph (Fig 3) we see that few of the racers improved their times the second time around — a few had decreased times.
Spaghetti plots.
Spaghetti plots, which display individual trajectories over time or multiple measurements, is a specialized line plot effective for visualizing the consistency of performance. The vertical thickness or spread of a single subject’s line across measurements indicates their level of repeatability. A “flat” line indicates high repeatability, while a volatile, zig-zagging line indicates low repeatability. Spaghetti plots are useful to visualize growth, decline, or stability over time for a single performance measure.
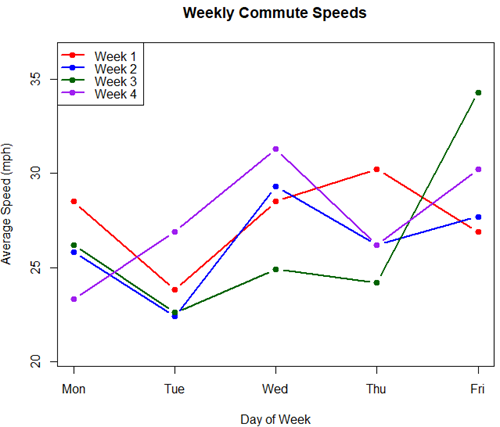
Figure 4. A spaghetti plot of average commute speeds from Table 2 data.
R code
# 1. Enter the data from Table 2.
commute <- data.frame(
Week = 1:4,
Monday = c(28.5, 25.8, 26.2, 23.3),
Tuesday = c(23.8, 22.4, 22.6, 26.9),
Wednesday = c(28.5, 29.3, 24.9, 31.3),
Thursday = c(30.2, 26.2, 24.2, 26.2),
Friday = c(26.9, 27.7, 34.3, 30.2)
)

head(commute)

# 2. Set the X-axis points
days <- 1:5
day_names <- c("Mon", "Tue", "Wed", "Thu", "Fri")

# 3. Create empty plot
# Find range of Y to ensure all data fits
ymin <- min(commute[, 2:6]) - 2
ymax <- max(commute[, 2:6]) + 2

plot(NA, xlim = c(1, 5), ylim = c(ymin, ymax),
xlab = "Day of Week", ylab = "Average Speed (mph)",
main = "Weekly Commute Speeds", xaxt = "n")

# Add X-axis labels
axis(1, at = 1:5, labels = day_names)

# 4. Add lines for each week (spaghetti)
colors <- c("red", "blue", "darkgreen", "purple")
for (i in 1:nrow(commute)) {
# Plot lines
lines(days, commute[i, 2:6], col = colors[i], lwd = 2, type = "b", pch = 19)
}

# 5. Add legend
legend("topleft", legend = paste("Week", 1:4), col = colors, lwd = 2, pch = 19)
Parallel coordinates plots.
Parallel coordinates plot allows each entity to be represented by a unique, continuous line traced across several vertical axes (each representing a different measurement or variable). High repeatability is indicated when a line remains roughly horizontal across all axes, while poor repeatability is visualized as lines that zig-zag or change direction between measurements.
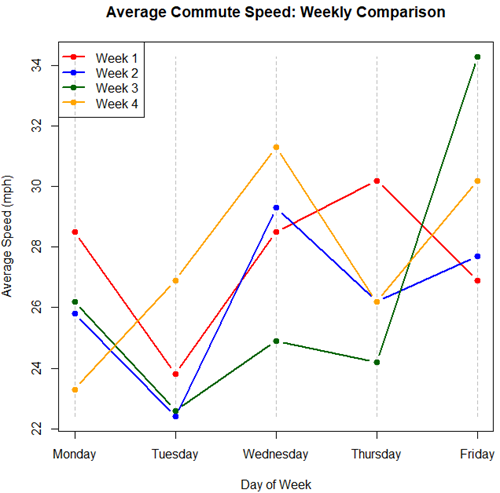
Figure 5. A parallel coordinates plot of average commute speeds from Table 2 data.
Both spaghetti plots and parallel coordinate plots can be used to visualize consistency of performance over multiple measures, but they differ significantly in their handling of data, scale, and context. Spaghetti plots are best for tracking within-subject variability over time, but quickly become a mess — like pasta tossed and sticking to a wall — when subject count increases. Parallel coordinate plots are a multivariate generalization — each line represents an individual’s profile across different tests, eg, accuracy, speed, VO2max.
R code.
# 1. Create the data frame
# see above

# 2. Extract only the numerical commute data for plotting
commute_data <- commute[, 2:6]

# 3. Setup the plot area
# Define range for y-axis
y_range <- range(commute_data)
# Define number of days (5)
num_days <- ncol(commute_data)

# Create empty plot
plot(NA, xlim = c(1, num_days), ylim = y_range,
xaxt = "n", xlab = "Day of Week", ylab = "Average Speed (mph)",
main = "Average Commute Speed: Weekly Comparison")

# Add x-axis labels
axis(1, at = 1:num_days, labels = colnames(commute_data))

# 4. Draw vertical lines for each day
for (i in 1:num_days) {
lines(c(i, i), y_range, col = "grey", lty = 2)
}

# 5. Add lines for each week (repeated measures)
colors <- c("red", "blue", "darkgreen", "orange")
for (i in 1:nrow(commute_data)) {
lines(1:num_days, commute_data[i, ], col = colors[i], lwd = 2, type = "b", pch = 19)
}

# 6. Add legend
legend("topleft", legend = paste("Week", commute$Week), col = colors, lwd = 2, pch = 19)
Heat map.
Heat map quickly identify patterns, such as an individual’s performance improving, degrading, or remaining stable over time. For example, uniform, solid colors across rows (individuals) or columns (time/trials) indicate high consistency, while varied colors indicate poor repeatability.
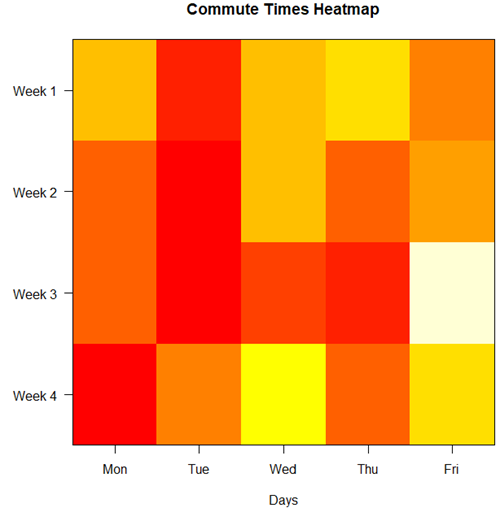
Figure 6. A heat map of the commute speeds data set.
R code.
# 1. Create the data
# Week is excluded from matrix to only include numerical commute times
commute_data <- matrix(c(
28.5, 23.8, 28.5, 30.2, 26.9,
25.8, 22.4, 29.3, 26.2, 27.7,
26.2, 22.6, 24.9, 24.2, 34.3,
23.3, 26.9, 31.3, 26.2, 30.2
), nrow = 4, byrow = TRUE)

# 2. Add row and column names
rownames(commute_data) <- c("Week 1", "Week 2", "Week 3", "Week 4")
colnames(commute_data) <- c("Mon", "Tue", "Wed", "Thu", "Fri")

# 3. Create the heatmap
# Use t() to transpose so weeks are rows and days are columns
# Use rev() on rows to have Week 1 at the top
image_data <- t(apply(commute_data, 2, rev))

# Set up the plotting area (margins for labels)
par(mar = c(5, 6, 4, 2))

# Plot the matrix
# Option 1
image(1:nrow(image_data), 1:ncol(image_data), image_data,
col = heat.colors(12),
axes = FALSE, xlab = "Days", ylab = "",
main = "Commute Times Heatmap")

# Add axes labels
axis(1, at = 1:5, labels = colnames(commute_data))
axis(2, at = 1:4, labels = rev(rownames(commute_data)), las = 1)
box()
Interpretation.
The graphs (Fig 4 – 6) show a lack of trends in consistency of drive speeds. The heat map suggests more consistency on Monday — low speeds (Fig 4 & Fig 5), but that’s a stretch.
An example for you to work, from our Measurement Day
If you recall, we had you calculate length and width measures on shells from samples of gastropod and bivalve species. In the table are repeated measures of shell length, by caliper in mm, for a sample of Conus shells (Fig 7 and Table 4).
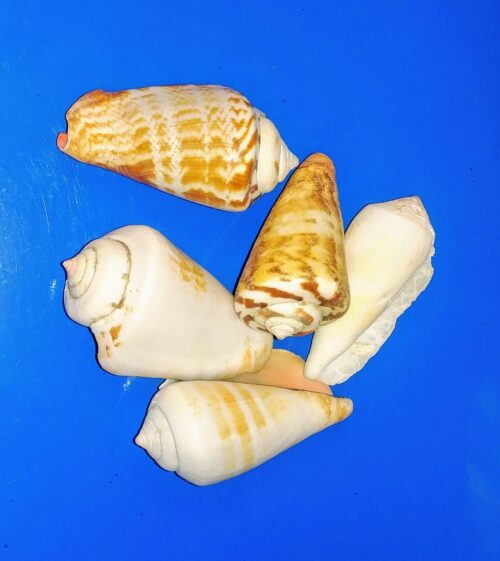
Figure 7. Conus shells, image by M. Dohm.
Repeated measures of the same 12 Conus shells.
Table 4. Unstacked dataset of repeated length measures on 12 shells
| Sample | Measure1 | Measure2 | Measure3 |
|---|---|---|---|
| 1 | 45.74 | 46.44 | 46.79 |
| 2 | 48.79 | 49.41 | 49.67 |
| 3 | 52.79 | 53.45 | 53.36 |
| 4 | 52.74 | 53.14 | 53.14 |
| 5 | 53.25 | 53.45 | 53.15 |
| 6 | 53.25 | 53.64 | 53.65 |
| 7 | 31.18 | 31.59 | 31.44 |
| 8 | 40.73 | 41.03 | 41.11 |
| 9 | 43.18 | 43.23 | 43.2 |
| 10 | 47.1 | 47.64 | 47.64 |
| 11 | 49.53 | 50.32 | 50.24 |
| 12 | 53.96 | 54.5 | 54.56 |
Maximum length from from anterior end to apex with calipers. Repeated measures were conducted blind to shell id, sampling was random over three separate time periods.
Questions
- Consider data in Table 2, Table 3, and Table 4. True or False: The arithmetic mean is an appropriate measure of central tendency. Explain your answer.
- Enter the shell data into R; Best to copy and stack the data in your spreadsheet, then import into R or R Commander. Once imported, don’t forget to change Sample to character, otherwise R will treat Sample as ratio scale data type. Run your one-way ANOVA and calculate the intraclass correlation (ICC) for the dataset. Is the shell length measure repeatable?
- The marathon results in Table 2 are paired data, results of two races run by the same individuals. Make a profile plot for the data (see Ch10.3 for help).
- A profile plot is used to show paired data; for two or more repeat measures, use a line graph instead.
A. Produce a line graph for data in Table 4. The line graph is an option in R Commander (Rcmdr: Graphs Line graph…), and can be generated with the following simple R code:
lineplot(Sample, Measure1, Measure2, Measure3)
B. What trends, if any, do you see? Report your observations.
C. Make another line plot for data in Table 2. Report any trend and include your observations.
Quiz Chapter 12.3
Fixed effects, random effects, and agreement
Chapter 12 contents
- Introduction
- The need for ANOVA
- One way ANOVA
- Fixed effects, random effects, and agreement
- ANOVA from “sufficient statistics”
- Effect size for ANOVA
- ANOVA posthoc tests
- Many tests one model
- References and suggested readings
12.2 – One way ANOVA
Introduction
In ANalysis Of VAriance, or ANOVA for short, we likewise have tools to test the null hypothesis of no difference between between categorical independent variables — often called factors when there’s just a few levels to keep track of — and a single, dependent response variable. But now, the response variable is quantitative, not qualitative like the  tests.
Analysis of variance, ANOVA, is such an important statistical test in biology that we will take the time to “build it” from scratch. We begin by reminding you of where you’ve been with the material.
We already saw an example of this null hypothesis. When there’s only one factor (but with two or more levels), we call the analysis of means and “one-way ANOVA.” In the independent sample t-test, we tested whether two groups had the same mean. We made the connection between the confidence interval of the difference between the sample means and whether or not it includes zero (ie, no difference between the means). In ANOVA, we extend this idea to a test of whether two or more groups have the same mean. In fact, if you perform an ANOVA on only two groups, you will get the exact same answer as the independent two-sample t-test, although they use different distributions of critical values (t for the t-test, F for the ANOVA — a nice little fact for you square the t-test statistic, you’ll get the F-test statistic:  ).
Let’s say we have an experiment where we’ve looked at the effect of different three different calorie levels on weight change in middle-aged men.
I’ve created a simulated dataset which we will use in our ANOVA discussions. The data set is available at the end of this page (scroll down or click here).
We might graph the mean weight changes ( SEM); Below are two possible outcomes of our experiment (Fig 1).
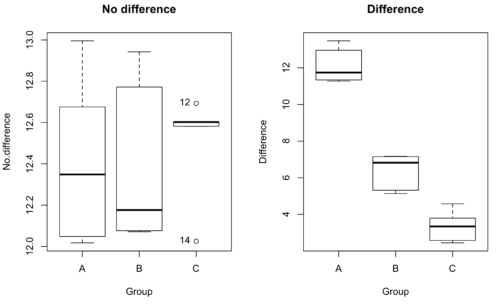
Figure 1. Hypothetical results of an experiment, box plots. Left, no difference among groups; Right, large differences among groups.
As statisticians and scientists, we would first calculate an overall or grand mean for the entire sample of observations; we know this as the sample mean whose symbol is  . But this overall mean is made up of the average of the sample means. If the null hypothesis is true, then the all of the sample means all estimate the overall mean. Put another way, being a member of a treatment group doesn’t matter, ie, there is no systematic effect, all differences among subjects are due to random chance.
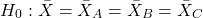
The hypotheses among are three groups or treatment levels then are:
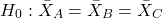
Null that there are no differences among the group means. And the alternative hypotheses include any (or all) of the following possibilities
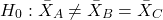
or maybe
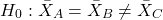
or… have we covered all possible alternate outcomes among three groups?
In either case, we could use one-way ANOVA to test for “statistically significant differences.”
Three important terms you’ll need for one-way ANOVA
FACTOR: We have one factor of interest. For example, a factor of interest might be
- Diet fed to hypertensive subjects (men and women)
- Distribution of coral reef sea cucumber species in archipelagos
- Antibiotic drug therapy for adolescents with Acne vulgaris (click see Webster 2002 for review).
Note 1: Character vs factor. In R programming, while it is true that a treatment variable can be a character vector like Gender*, such vectors are handled by R as string. In contrast, by claiming Gender as a factor, R handles the variable as a nominal data type. Hence, ANOVA and other GLM functions expect any treatment variable to be declared as a factor:
Gender <- c("Gender non-conforming", "Men", "Non-binary", "Transgender", "Women", "Declined"); Gender
[1] "Gender non-conforming" "Men" "Non-binary" "Transgender"
[5] "Women" "Declined"
# it’s a string vector, not a factor
is.factor(Gender)
[1] FALSE
Change string vector to a factor.
Gender <- as.factor(Gender); is.factor(Gender) [1] TRUE
* For discussions of ethics of language inclusivity and whether or not such information should be gathered, see Henrickson et al 2020.
LEVELS: We can have multiple levels (2 or more) within the single factor. Some examples of levels for the Factors listed:
- Three diets (DASH), diet rich in fruits & vegetables, control diet)
- Five archipelagos (Hawaiian Islands, Line Islands, Marshal Islands, Bonin Islands, and Ryukyu Islands)
- Five antibiotics (ciprofloxacin, cotrimoxazole, erythromycin, doxycycline, minocycline).
RESPONSE: There is one outcome or measurement variable. This variable must be quantitative (ie, on the ratio or interval scale). Continuing our examples then
- Reduction in systolic pressure
- Numbers of individual sea cucumbers in a plot
- number of microcomedo.
Note 2: A comedo is a clogged pore in the skin; a microcomedo refers to the small plug. Yes, I had to look that up, too.
The response variable can be just about anything we can measure, but because ANOVA is a parametric test, the response variable must be normally distributed!
Note on experimental design
As we discuss ANOVA, keep in mind we are talking about analyzing results from an experiment. Understanding statistics, and in particular ANOVA, informs how to plan an experiment. The basic experimental design is called a completely randomized experimental design, or CDR, where treatments are assigned to experimental units at random.
In this experimental design, subjects (experimental units) must be randomly assigned to each of these levels of the factor. That is, each individual should have had the same probability of being found in any one of the levels of the factor. The design is complete because randomization is conducted for all levels, all factors.
Thinking about how you would describe an experiment with three levels of some treatment, we would have
Table 1. Summary statistics of three levels for some ratio scale response variable.
| Level 1 |
sample mean1 |
sample standard deviation1 |
| Level 2 |
sample mean2 |
sample standard deviation2 |
| Level 3 |
sample mean3 |
sample standard deviation3 |


Note 3: Table 1 is the basis for creating the box plots in Figure 1.
ANOVA sources of variation
ANOVA works by partitioning total variability about the means (the grand mean, the group means). We will discuss the multiple samples and how the ANOVA works in terms of the sources of variation. There are two “sources” of variation that can occur:
- Within Group Variation
- Among Groups Variation
So let’s look first at the variability within groups, also called the Within Group Variation.
Consider and experiment to see if DASH diet reduces systolic blood pressure in USA middle-aged men and women with hypertension (Moore et al 2001). After eight weeks we have
We get the corrected sum of squares, SS, for within group

and the degrees of freedom, DF, for within groups
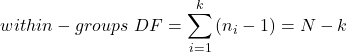
where i is the identity of the groups,  is the individual observations within group i,
 is the group i mean, ni is the sample size within each group, N is the total sample size of all subjects for all groups, and k is the number of groups.
Importantly, this value is also referred to as “error sums of squares” in ANOVA. It’s importance is as follows — In our example, the within group variability would be zero if and only if all subjects within the same diet lost exactly the same amount of weight. This is hardly ever the case of course in a real experiment. Because there are almost always some other unknown factors or measurement error that affect the response variable, there will be some unknown variation among individuals who received the same treatment (within the same group). Thus, the error variance will generally be larger than zero.
The first point to consider: your ANOVA will never result in statistical differences among the groups if the error variance is greater than the second type of variability, the variability between groups.
The second type of variability in ANOVA is that due to the groups or treatments. Individuals given a calorie-restricted diet will lose some weight; individuals allowed to eat a calorie-rich diet likely will gain weight, therefore there will be variability (a difference) due to the treatment. So we can calculate the variability among groups. We get the corrected sum of squares for among groups
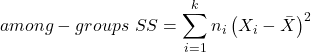
and the degrees of freedom for among groups
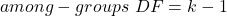
where i is the identity of the groups, is the grand mean as defined in Measures of Central Tendency (Chapter 3.1), is the group i mean, ni is the sample size within each group, N is the total sample size of all subjects for all groups, and k is the number of groups.
The sums of squares here is simply subtracting the mean of each population from the overall mean.
- If the Factor is not important in explaining the variation among individuals then all the population means will be similar and the sums of squares among populations would be small.
- If the Factor is important in explaining some of the variation among the individuals then all the population means will NOT be the same and the sums of squares among populations would be large.
Finally, we can identify the total variation in the entire experiment. We have the total sum of squares.
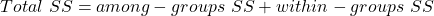
Thus, the insight of ANOVA is that variation in the dataset may be attributed to a portion explained by differences among the groups and differences among individual observations within each group. The inference comes from recognizing that if the among group effect is greater than the within group effect, then there will be a difference due to the treatment levels.
Mean squares
To decide whether the variation associated with the among group differences are greater than the within group variation, we calculate ratios of the sums of squares. These are called Mean Squares or MS for short. The ratio of the Mean Squares is called F, the test statistic for ANOVA.
For the one-way ANOVA we will have two Mean Squares and one F, tested with degrees of freedom for both the numerator  , and denominator
 ).
The Mean Square for (among) groups is
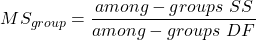
The Mean Square for error is
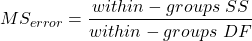
And finally, the value for F, the test statistic for ANOVA, is
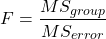
Worked example with R
A factor with three levels, A, B, and C
group <- c("A", "A", "A", "B", "B", "B", "C", "C", "C")
and their responses, simulated
response <- c(10.8, 11.8, 12.8, 6.5, 7, 8, 3.8, 2.8, 3)
We create a data frame
all <- data.frame(group, response)
Of course, you could place the data into a worksheet and then import the worksheet into R. Regardless, we now have our dataset.
Now, call the ANOVA function, aov, and assign the results to an object (eg, Model.1)
Model.1 <- aov(response ~ group, data=all)
Now, visualize the ANOVA table
summary(Model.1)
and the output from R, the ANOVA table, is shown below
Note 4: Rcmdr: Statistics → Means → One-way ANOVA… see figures 2 and 3 below
Table 2. Output from aov() command, the ANOVA table, for the “Difference” outcome variable.
           Df   Sum Sq    Mean Sq   F value       Pr(>F)
group       2   111.16      55.58     89.49    0.0000341 ***
Residuals   6     3.73       0.62
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Let’s take the ANOVA table one row at a time
- The first row has subject headers defining the columns.
- The second row of the table “groups” contains statistics due to group, and provides the comparisons among groups.
- The third row, “Residuals” is the error, or the differences within groups.
Moving across the columns, then, for each row, we have in turn,
- the degrees of freedom (there were 3 groups, therefore 2 DF for group),
- the Sums of Squares, the Mean Squares,
- the value of F, and finally,
- the P-value.
R provides a helpful guide on the last line of the ANOVA summary table, the “Signif[icance] codes,” which highlights the magnitude of the P-value.
Note 5: On the use of “error” and “residuals.” Error refers to the difference between an observed value and the true population value. Residual is the difference between an observed value and a value predicted by a model. In ANOVA, the “error variance” or “residual variance” is the variation within groups unexplained by the tested factor. It is what remains after the effects of the model are accounted for.
What to report? ANOVA problems can be much more complicated than the simple one-way ANOVA introduced here. For complex ANOVA problems, report the ANOVA table itself! But for the one-way ANOVA it would be sufficient to report the test statistic, the degrees of freedom, and the p-value, as we have in previous chapters (eg, t-test, chi-square, etc.). Thus, we would report:
F = 89.49, df = 2 and 6, p = 0.0000341
where F = 89.49 is the test statistic, df = 2 (degrees of freedom for the among group mean square) and 6 (degrees of freedom for the within group mean square), and p = 0.0000341 is the p-value.
In Rcmdr, the appropriate command for the one-way ANOVA is simply
Rcmdr: Statistics → Means
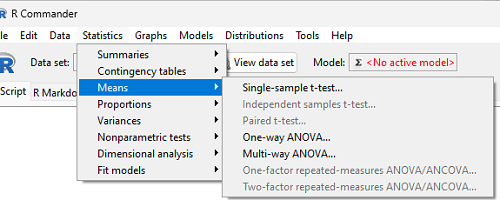
Figure 2. Screenshot Rcmdr select one-way ANOVA.
which brings up a simple dialog. R Commander anticipates factor (Groups) and Response variable. Optional, choose Pairwise comparisons of means for post-hoc test (Tukey’s) and, if you do not want to assume equal variances (see Chapter 13), select Welch F-test.
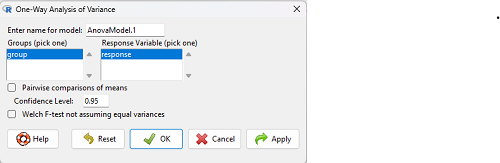
Figure 3. Screenshot Rcmdr select one-way ANOVA options.
Questions
1. Review the example ANOVA Table and confirm the following
- How many levels of the treatment were there?
- How many sampling units were there?
- Confirm the calculation of
 and using the formulas contained in the text.
- Confirm the calculation of F using the formula contained in the text.
- The degrees of freedom for the F statistic in this example were 2 and 6 (F2,6). Assuming a two-tailed test with Type I error rate of 5%, What is the critical value of the F distribution (see Appendix 20.4)
2. Repeat the one-way ANOVA using the simulated data, but this time, calculate the ANOVA problem for the “No.difference” response variable.
3. Leaf lengths from three strains of Arabidopsis thaliana plants grown in common garden are shown in Fig 2. Data are provided for you in the following R script.
arabid <- c("wt","wt","wt","AS1","AS1","AS1","AS2","AS2","AS2")
leaf <- c(4.909,5.736,5.108,6.956,5.809,6.888,4.768,4.209,4.065)
leaves <- data.frame(arabid,leaf)
- Write out a null and alternative hypotheses
- Conduct a test of the null hypothesis by one-way ANOVA
- Report the value of the test statistic, the degrees of freedom, and the P-value
- Do you accept or reject the null hypothesis? Explain your choice.
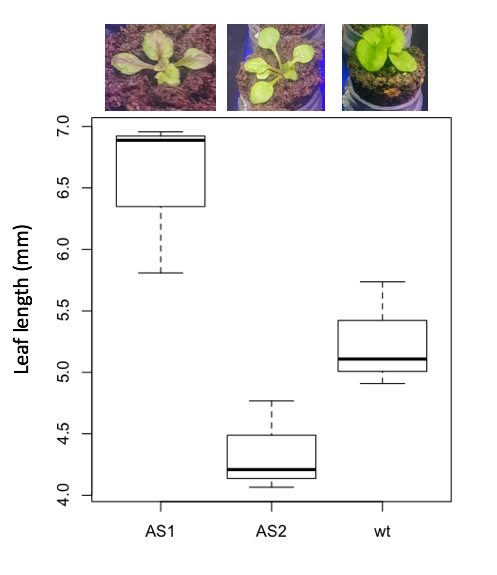
Figure 4. Box plot of lengths of leaves of a 10-day old plant from on of three strains of Arabidopsis thaliana.
4. Return to your answer to question 7 from Chapter 12.1 and review your answer and modify as appropriate to correct your language to that presented here about factors and levels.
5. Conduct the one-way ANOVA test on the Comet assay data presented question 7 from Chapter 12.1. Data are copied for your convenience to end of this page. Obtain the ANOVA table and report the value of the test statistics, degrees of freedom, and p-value.
a. Based on the ANOVA results, do you accept or reject the null hypothesis? Explain your choice.
Quiz Chapter 12.2
One-way ANOVA
Data used in this page
Difference, no difference
Table 12.2 Difference or No Difference
| Group | No.difference | Difference |
|---|---|---|
| A | 12.04822 | 11.336161 |
| A | 12.67584 | 13.476142 |
| A | 12.99568 | 12.96121 |
| A | 12.01745 | 11.746712 |
| A | 12.34854 | 11.275492 |
| B | 12.17643 | 7.167262 |
| B | 12.77201 | 5.136788 |
| B | 12.07137 | 6.820242 |
| B | 12.94258 | 5.318743 |
| B | 12.0767 | 7.153992 |
| C | 12.58212 | 3.344218 |
| C | 12.69263 | 3.792337 |
| C | 12.60226 | 2.444438 |
| C | 12.02534 | 2.576014 |
| C | 12.6042 | 4.575672 |
Comet assay, antioxidant properties of tea
Data presented in Chapter 12.1
Chapter 12 contents
12 – One-way Analysis of Variance
Introduction
We left off with two-group experiments in Chapter 10 where we introduced two-sample tests of the null hypothesis of no difference between the middles for each group (if means, t-tests; if medians, Wilcoxon test).
As review, please revisit what we mean by independent variables (statistical jargon for “different treatments, like a placebo vs. aspirin therapy”) and dependent variables (statistical jargon for “response or outcome of the experiment was recorded as number of living or dead subjects”).
Variables are independent in the sense that the values are not related to the experiment’s outcome — we select the levels of the variables. For example, we select to study green vs. red leaves (the variable is “leaf color”, and there are only two levels or states of the variable: green & red). In contrast, we denote the values of the response variable as dependent because the particular values that the variable will take depend on the experiment.
It’s rare that you, as a researcher, would only be interested in comparing two samples or two groups of data for which a treatment has been applied in an experiment or investigation. More often, inferences are drawn on multiple samples (more than two groups) and an experiment involves multiple groups (one or more controls plus one or more experimental treatments).
Previously, we have discussed data sets with only one or two samples or populations (eg, one and two-sample t-test, Mann-Whitney tests). Now we want to extend the discussion of statistics to situations where we may have more than two samples or populations. We introduce the ANalysis Of VAriance (ANOVA). ANOVA is an extremely popular statistical framework, with more than 500 thousand reports in PUBMED since 1936 (583,652 as of August 2025). It’s among the chief statistical approaches for comparing group means and, where groups are established by experimental design, ANOVA is used to identify which factors have a real impact and which do not.
Importantly, we will see that One and two-sample tests are just simple cases of ANOVA. Thus, use of ANOVA should be your preference, even if you have just two groups.
Suggested homework
Quizzes in this chapter
A total of 58 questions among the several subchapters, a mix of true or false and multiple choice question format.
Chapter 12 contents
- Introduction
- The need for ANOVA
- One way ANOVA
- Fixed effects, random effects, and agreement
- ANOVA from “sufficient statistics”
- Effect size for ANOVA
- ANOVA posthoc tests
- Many tests one model
- References and suggested readings
/MD