17.6 – ANCOVA – analysis of covariance
Introduction
Analysis of covariance (ANCOVA) is intended to help with analysis of designs with categorical treatment variables on some response (dependent) variable, but a known confounding variable is also present. Thus, the researcher is also likely to know of additional ratio scale variables that covary with the response variable and, moreover, must be included in the experimental design in some way.
Take for example the well-known relationship between body size and whole-animal metabolic rate as measured by rates of carbon dioxide production or rates of oxygen consumption for aerobic organisms. We may be interested in how addition or blocking of stress hormones affects resting metabolism; we may be interested in comparing men and women for activity metabolism, and so on. We’d like to know if the regressions were the same (eg, metabolic rate covaried with body mass in the same way — that is, the slope of the relationship was the same).
This situation arises frequently in biology. For example, we might want to know if male and female birds have different mean field metabolic rates, in which case we might be tempted to use a one-way ANOVA or t-test (since one factor with two levels). However, if males and females also differ for body size, then any differences we might see in metabolic rate could be due to differences in metabolic rate are confounded by differences in the covariable body size. We already discussed one approach to correction: calculate a ratio. Thus, a logical approach to correcting or normalizing for the covariation would be to divide body mass (units of kilograms) into metabolic rate (eg, volume of oxygen, O2, consumed), and make comparisons, say, among different species, on mass-specific trait ( ). However, because the regression between mass and metabolic rate is allometric, i.e., not equal to one, the ratio does not, in fact normalize for body mass. We made this point in Chapter 6.2, and remarked that analysis of covariance ANCOVA was a solution.
ANCOVA allows you to test for mean differences in traits like metabolic rate between two or more groups, but only after first accounting for covariation due to another variable (eg, body size). However, ANCOVA makes the assumption that relationship between the covariable and the response variable is the same in the two groups. This is the same as saying that the regression slopes are the same. We discussed how to use t-test to test hypothesis of equal slopes between regression models in Chapter 17.5, but a more elegant way is to include this in your model.
Example
We return to our sample of 13 tadpoles (Rana pipiens), hatched in the laboratory. I’ve repeated the data set in this page, scroll or click here.
Our linear model was 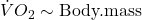 and a scatterplot of the data set is shown in Figure 1 (a repeat of Figure 3 from Chapter 17.5, but now points identified to developmental group).
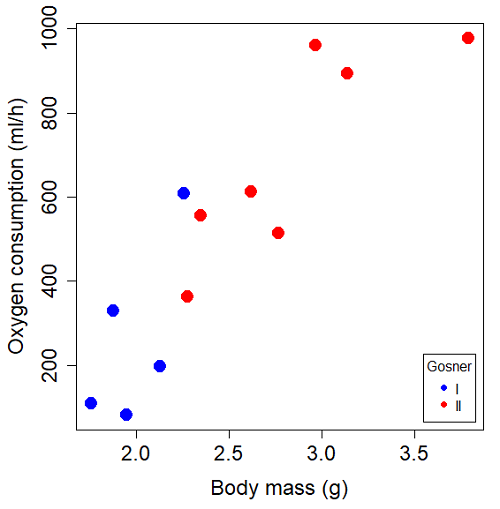
Figure 1. Scatterplot of oxygen consumption by R. pipiens tadpoles vs body mass (g) by developmental group (Gosner stages I or II).
The project looked at whether metabolism as measured by oxygen consumption was consistent across two developmental stages. Metamorphosis in frogs and other amphibians represents profound reorganization of the organism as the tadpole moves from water to air. Thus, we would predict some cost as evidenced by change in metabolism associated with later stages of development. Figure 2 shows a box plot of tadpole oxygen consumption by Gosner (1960) developmental stage (Figure 2 is a repeat of Figure 4 Chapter 17.5).
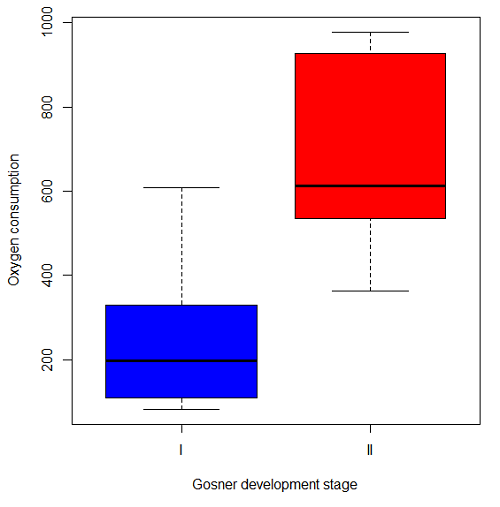
Figure 2. Copy of Figure 4, Chapter 17.5; boxplot of oxygen consumption of R. pipiens tadpoles by Gosner developmental stages.
Looking at Figure 2 we see a trend consistent with our prediction; developmental stage may be associated with increased metabolism. However, older tadpoles also tend to be larger, and the plot in Figure 2 does not account for that. Thus, body mass is a confounding variable in this example. There are several options for analysis here (eg, ANCOVA), but one way to view this is to compare the slopes for the two developmental stages. While this test does not compare the means, it does ask a related question: is there evidence of change in rate of oxygen consumption relative to body size between the two developmental stages? The assumption that the slopes are equal is a necessary step for conducting the ANCOVA.
So, divide the data set (Table 1) into two groups by developmental stage (12 tadpoles could be assigned to one of two developmental stages; one was at a lower Gosner stage than the others and so is dropped from the subset.
Table 1.  and
 of 12 R. pipiens tadpole larvae by Gosner developmental stage.
Gosner stage I
|
|
| 1.76 | 109.41 |
| 1.88 | 329.06 |
| 1.95 | 82.35 |
| 2.13 | 198 |
| 2.26 | 607.7 |
Gosner stage II
| Body mass | |
| 2.28 | 362.71 |
| 2.35 | 556.6 |
| 2.62 | 612.93 |
| 2.77 | 514.02 |
| 2.97 | 961.01 |
| 3.14 | 892.41 |
| 3.79 | 976.97 |
The slopes and standard errors we obtained in Chapter 17.5 were
| Gosner Stage I | Gosner stage II | |
| slope | 750.0 | 399.9 |
| standard error of slope | 444.6 | 111.2 |
Make a plot (Figure 3).
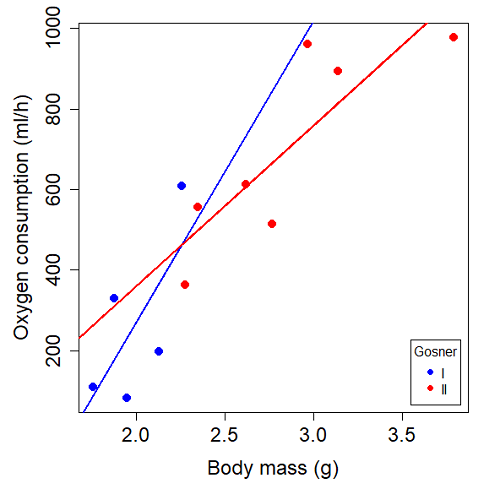
Figure 3. Scatterplot with best-fit regression lines of by for Gosner State I (closed circle, solid line) and Gosner Stage II (open circle, dashed line) R. pipiens tadpoles.
R code for plot in Figure 3.
#Used Rcmdr scatterplot(), then modified code
scatterplot(VO2~Body.mass | Gosner, regLine=FALSE, smooth=FALSE,
boxplots=FALSE, xlab="Body mass (g)", ylab="Oxygen consumption (ml/h)",
main="", cex=1.4, cex.axis=1.5, cex.lab=1.5, pch=c(19,19), by.groups=TRUE,
col=c("blue","red"), grid=FALSE,
legend=list(coords="bottomright"), data=Tadpoles)
#Get regression equations for groups, subset by Gosner
abline(lm(VO2~Body.mass, data=Stage01), lty=1, lwd=2, col="blue")
abline(lm(VO2~Body.mass, data=Stage02), lty=1, lwd=2, col="red")
Returning to the important question, are the two slopes statistically indistinguishable (Ho: bI = bII), where bI is the slope for the Gosner Stage I subset and bII is the slope for the Gosner Stage II subset? We look at the plot, and since the lines cross, we tend to see a difference. Of course, we need to consider that our perception of slope differences may simply be chance, especially because the sample size is small. Proceed to test.
R code
The ANCOVA is a new ANOVA model where the factor variables are adjusted or corrected for the effects of the continuous variable.
R code for ANCOVA example, crossed or interaction model.
tadpole.1 <- lm(VO2 ~ Body.mass*Gosner, data=example.Tadpole)
summary(tadpole.1)
Anova(tadpole.1, type="II")
Output
summary(tadpole.1)

Call:
lm(formula = VO2 ~ Body.mass * Gosner, data = example.Tadpole)

Residuals:
    Min      1Q   Median      3Q      Max
-167.80 -117.93    13.81   94.66   214.65

Coefficients:
                       Estimate   Std. Error   t value    Pr(>|t|)
(Intercept)             -1231.6       783.0     -1.573    0.1544
Body.mass                 750.0       390.7      1.919    0.0912 .
Gosner[T.II]              790.4       859.2      0.920    0.3845
Body.mass:Gosner[T.II]   -350.1       409.5     -0.855    0.4174
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 155.8 on 8 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.821, Adjusted R-squared: 0.7539
F-statistic: 12.23 on 3 and 8 DF, p-value: 0.002336
The coefficients for the first factor (GII) and then the differences in the coefficient for the second factor. You can just add the second coefficient to the first so they’re on the same scale.
Anova Table (Type II tests)

Response: VO2
                  Sum Sq   Df    F value     Pr(>F)
Body.mass         330046    1    13.6030   0.006146 **
Gosner              5630    1     0.2321   0.642908
Body.mass:Gosner   17736    1     0.7310   0.417423
Residuals 194102 8
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Suggests interaction is not significant, i.e., the slopes are not different.
We can then proceed to check to see if the intercepts are different, now that we’ve confirmed no significant difference in slope.
R code for ANCOVA as additive model
tadpole.2 <- lm(VO2 ~ Body.mass + Gosner, data=example.Tadpole)
summary(tadpole.2)
Anova(tadpole.2, type="II")
Output
> summary(tadpole.2)

Call:
lm(formula = VO2 ~ Body.mass + Gosner, data = example.Tadpole)

Residuals:
    Min       1Q    Median      3Q      Max
-163.12  -125.53    -20.27   83.71   228.56

Coefficients:
                   Estimate   Std. Error     t value    Pr(>|t|)
(Intercept)         -595.37       239.87      -2.482     0.03487 *
Body.mass            431.20       115.15       3.745     0.00459 **
Gosner[T.II]          64.96       132.83       0.489     0.63648
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 153.4 on 9 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.8047, Adjusted R-squared: 0.7613
F-statistic: 18.54 on 2 and 9 DF, p-value: 0.0006432

Anova(tadpole.2, type="II")
Anova Table (Type II tests)

Response: VO2
              Sum Sq    Df    F value      Pr(>F)
Body.mass     330046     1    14.0221   0.004593 **
Gosner          5630     1     0.2392   0.636482
Residuals     211839     9
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
Note 1. There is no test of interaction in the added model. This model would be appropriate IF the slopes are equal.
Instead of the interaction, or as added, try a nested model, with body mass nested within stage.
tadpole.3 <- lm(VO2 ~ Body.mass/Gosner, data=example.Tadpole)

summary(tadpole.3)

Call:
lm(formula = VO2 ~ Body.mass/Gosner, data = example.Tadpole)

Residuals:
    Min       1Q    Median      3Q      Max
-168.66  -131.14    -20.28   90.33   225.36

Coefficients:
                 Estimate      Std. Error    t value Pr(>|t|)
(Intercept)           -575.10      319.51     -1.800   0.1054
Body.mass              423.65      162.50      2.607   0.0284 *
Body.mass:Gosner[T.II]  21.95       63.73      0.344   0.7384
---
Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1

Residual standard error: 154.4 on 9 degrees of freedom
(1 observation deleted due to missingness)
Multiple R-squared: 0.8021, Adjusted R-squared: 0.7581
F-statistic: 18.24 on 2 and 9 DF, p-value: 0.0006823
Gets the true coefficient (nested lm() version).
The two test different hypotheses.
lm(VO2 ~ Body.mass * Gosner) tests whether or not the regression has a nonzero slope.
lm(VO2 ~ Body.mass */Gosner) test whether or not the slopes and intercepts from different factors are statistically significant.
Questions
- Write up three learning outcomes for this page. Hint: Point your favorite generative AI to this page and ask for help.
- An OLS approach was used for the analysis of tadpole oxygen consumption body mass. Consider the RMA approach — would that be a more appropriate regression model? Explain why or why not.
- Consider an experiment in which you plan to administer a treatment that has a carry-over effect. For example, Compare and contrast “crossed” and “nested” designs.
- True or False. The nested design option for the ANCOVA assumes the slopes for the two groups of tadpoles for the regression line of by are equal. Explain your choice.
- Metabolic rates like oxygen consumption over time are well-known examples of allometric relationships. That is, many biological variables (eg, is related as aMb, where M is body mass, slope b is scaling exponent), and best evaluated on log-log scale. Repeat the analysis above on log10-transformed and for
- crossed design (eg, tadpole.1 model)
- added design (eg, tadpole.2 model)
- nested design (eg, tadpole.3 model)
- Create the plot and add the fitted lines from crossed design to the plot.
Note 2. About log-transform of a variable. The most straight-forward tact is to create two new variables. For example,
lgVO2 <- log10(VO2)
Another option is to transform the variables within the call to lm() function. For example, try
lm(log10(VO2) ~ log10(Body.mass ), data=example.Tadpole)
Hint: don’t forget to attach your data set to avoid having to call the variable as, for example, example.Tadpole$VO2
Quiz Chapter 17.6
ANCOVA - analysis of covariance
Data sets
Oxygen consumption,  , of Anuran tadpoles, dataset=
example.Tadpole
| Gosner | Body mass | VO2 |
|---|---|---|
| NA | 1.46 | 170.91 |
| I | 1.76 | 109.41 |
| I | 1.88 | 329.06 |
| I | 1.95 | 82.35 |
| I | 2.13 | 198 |
| II | 2.28 | 362.71 |
| I | 2.26 | 607.7 |
| II | 2.35 | 556.6 |
| II | 2.62 | 612.93 |
| II | 2.77 | 514.02 |
| II | 2.97 | 961.01 |
| II | 3.14 | 892.41 |
Gosner refers to Gosner (1960), who developed a criteria for judging metamorphosis staging.
Chapter 17 contents
- Introduction
- Simple Linear Regression
- Relationship between the slope and the correlation
- Estimation of linear regression coefficients
- OLS, RMA, and smoothing functions
- Testing regression coefficients
- ANCOVA – Analysis of covariance
- Regression model fit
- Assumptions and model diagnostics for Simple Linear Regression
- References and suggested readings (Ch17 & 18)
4.1 – Bar (column) charts
Introduction
Bar chart, also called a bar graph, or column chart in many spreadsheet apps (e.g., Google Sheets, Microsoft Excel, Libreoffice Calc — “bar charts” is reserved for horizontal bar plots), are used to compare counts among two or more categories, i.e., an alternative to pie charts (Fig. 1).
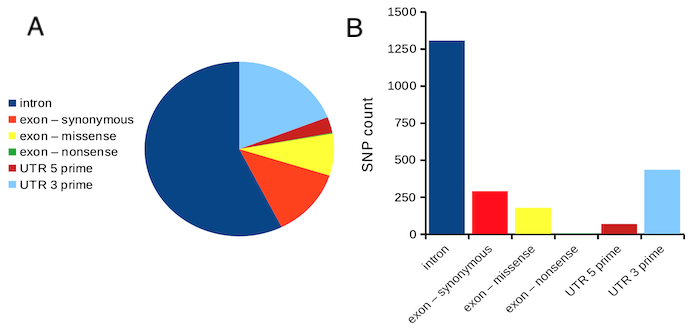
Figure 1. Single nucleotide variants for human gene ACTB by DNA and functional element (data collected 19 May 2022 from NCBI SNP database with Advanced search query). A. Pie chart. Note that slide for “exon – nonsense” is not visible. B. Bar chart – color coded bars to facilitate comparison with pie chart.
Although bar charts are common in the literature (Cumming et al 2007; Streit and Gehlenborg 2014), bar charts may not be a good choice for comparisons of ratio scale data (Streit and Gehlenbor 2014). Bar charts for ratio data are misleading. Parts of the range implied by the bar may never have been observed: the bars of the chart always start at zero. Box (whisker) plots are better for comparisons of ratio scale data and are presented in the next section of this chapter. That said, I will go ahead and present how to create bar charts for both count — generally considered acceptable — and ratio scale data, for which their use is controversial.
Purpose of the bar chart
Like all graphics, a bar chart should tell a story. The purpose of displaying data is to give your readers a quick impression of the general differences among two or more groups of the data. For counts, that’s where the bar chart comes in. The bar chart is preferred over the pie chart because differences are represented by lengths of the bars in the bar chart. Differences among categories in a pie chart are reflected by angles, and it seems that humans are much better at judging lengths than angles.
Bar chart with counts
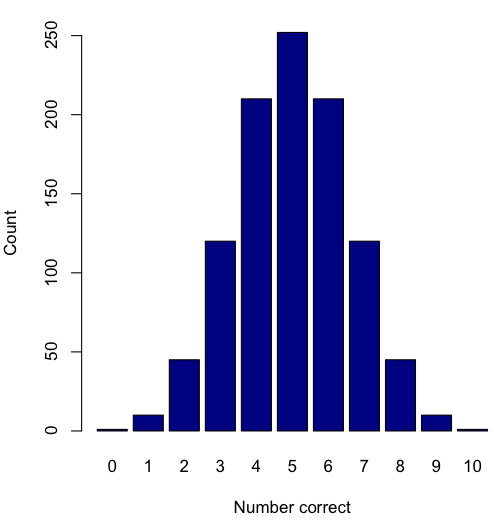
Figure 2. A simple bar chart
myCombo <- seq(0,10, by=1)
myCounts <- choose(10, myCombo)    #combinations
barplot(myCounts, names.arg = myCombo, xlab = "Number correct", ylab = "Count",col = "darkblue")
A stacked bar chart is used to
myCombo <- seq(0,10, by=1)
myCounts <- choose(10, myCombo)    #combinations
barplot(myCounts, names.arg = myCombo, xlab = "Number correct", ylab = "Count",col = "darkblue")
Figure 3. The luxury ship RMS Titanic, which sunk 15 April 1912, More than 1500 souls were lost. Public domain image, Wikipedia. Click image to view full sized image.
Stacked bar chart, data set TitanicSurvival in package carData.
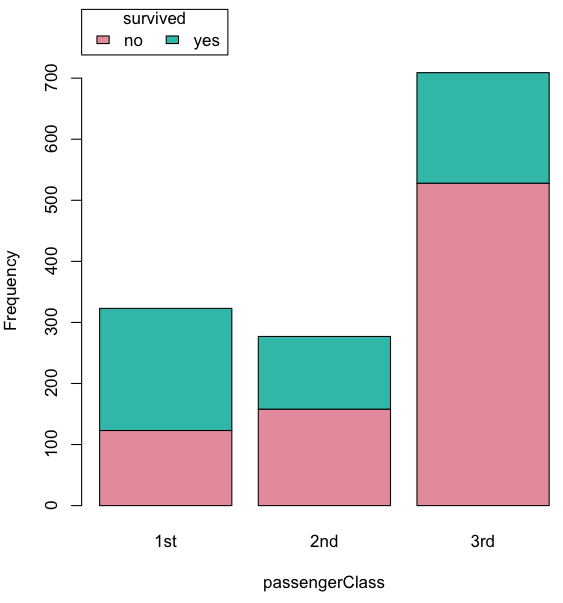
Figure 4. A stacked bar chart, survival Titanic
Barplot(passengerClass, by=survived, style="divided", legend.pos="above", xlab="passengerClass", ylab="Frequency")Bar charts with error bars
Although many data visualization specialists argue against the bar chart — they tend to obscure data — their use is well established. For the familiar bar chart with ratio scale data, the X (horizontal) axis displays the categories of one variable (e.g., location, or treatment group). You plot groups to emphasize comparisons. The Y (vertical) axis then is the mean for each group.
You need error bars with your bar chart to convey variability. A bar chart plus error bars is sometimes called (pejoratively) a dynamite plot. If the mean is displayed, some measure of precision should be (must be?) displayed (Cumming et al 2007). And, as you should recall by now, your choices are standard deviation (Chapter 3.2), standard error of the mean (SEM) (Chapters 3.2, 3.4), or confidence interval (see Chapter 3.4). It is strongly advised, that without a representation of precision, one should not interpret trends or group differences from representations of means (i.e., height of bars) alone.
The bar charts on this page are means plus or minus the standard error of the mean, + SEM. I’m not advocating here for the bar chart — box plots with efforts to show the actual data are better. However, bar charts remain common and may be more familiar to certain audiences. We’ll discuss which choice to make.
Examples
The Copper_rats_PMID3357063 dataset will be used for the next series of graphs (Data set). Refer to Mike’s Workbook for Biostatistics Part07 to review how to import the data.
A portion of the data set is shown below
head(Copper)
         Diet     Body    Heart    Liver
1 Adequate-Cu 320.1381 1.125037 10.259657
2 Adequate-Cu 329.6879 1.158982 9.843295
3 Adequate-Cu 327.9838 1.090374 9.855975
4 Adequate-Cu 334.6669 1.118183 9.942997
5 Adequate-Cu 338.3134 1.172636 9.860971
6 Adequate-Cu 345.4608 1.056183 8.885820
The data set consists of organ weights (heart, liver) from rats fed a diet adequate in copper, deficient in copper, and then a third group who received the adequate diet from perspective of amount of copper, but calorie restricted to match the decreased feeding rates of the rats fed the copper deficient diet. Copper is an essential trace element in our diet. The data set was simulated from descriptive statistics (means, standard deviation, number of subjects) of published data by sampling from a normal distribution. (Table 1, Ovecka et al 1988).
On we go with some graphs.
Note 1: R has many options to create bar charts, and especially ggplot2 can be used to great advantage, but there is a learning curve. One of the great things about R is that folks help each other by sharing code. For example, http://www.cookbook-r.com/Graphs/Plotting_means_and_error_bars_(ggplot2)/
But, I’m still learning about R graphics, and for bar charts with error bars, I find other packages more straight-forward. So, I’ll use this moment to point out that making a good graph is more about the end product then the particular tools. I have been using other tools for years to make my graphics, so I tend to default on these options first. Graphs presented here are mostly from Veusz software program (pronounced “views”). I like it because the software allows me to edit any of the elements of the graph.
Here’s a typical looking bar chart with ratio scale data: means ± SEM. Let’s look at them more critically.
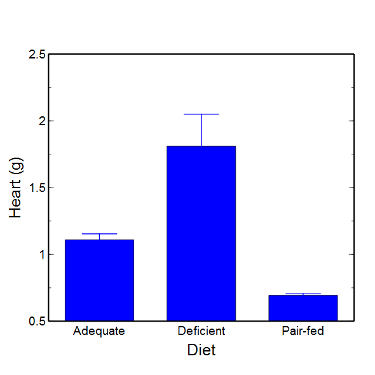
Figure 5. A bar chart with error bars (standard error of the mean).
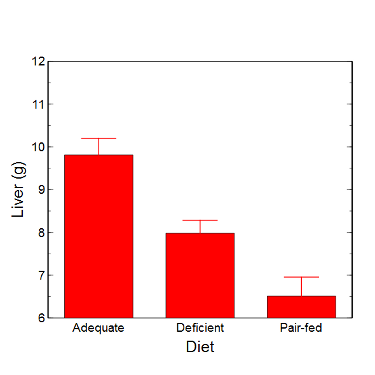
Figure 6. Another bar chart. with standard errors of mean
When making comparisons, make sure the axes have the same scale, or consider putting the graphs together.
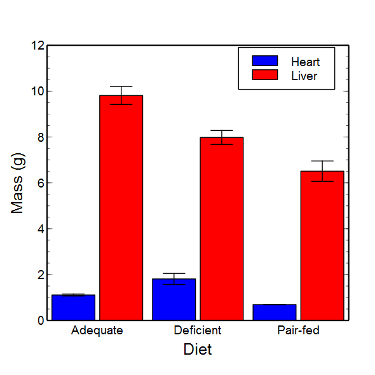
Figure 7. Bar chart that allows for a comparison among levels of a a factor (organs, liver vs. heart).
Analysis note: For variables that covary with body size (for example, on average, tall people generally are heavier too), is how to present (and analyze) the data in such a way that body size is accounted for. Here, the solution was to express organ weight as the ratio of organ weight to body weight for the mice. This may or may not be a good solution, and the answer is too complicated for us now (has to do with a thing called allometric scaling), but I wanted to at least present the issue and show how the graphics can be improved to handle some of these concerns.
Here’s the organ weights again, but taken as ratio of body mass.
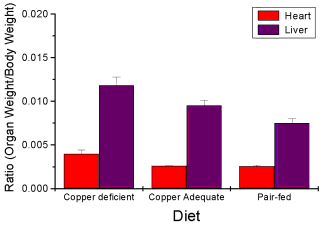
Figure 8. Same chart as in Figure 6, but on ratios.
Note 2. Lets be clear about expectations of you for statistics class. Now, R (and Rcmdr) do lots of graphics, pretty much anything you want, but it is not as friendly as it could be. For BI311 homework, the default graphics available via Rcmdr will generally be adequate for assignments. R and Rcmdr has many bar chart options, but there isn’t a straightforward way to get the error bars, unless you are willing to enter some code to the command line or learn a particular package (like gplots or ggplot2).
How to make a bar chart with error bars in R
Option 1. First, let’s try a work-around. Instead of an error bar option for bar chart menu, Rcmdr provides a plot of means that allows you to plot with error bars. These are equivalent graphs, the “bar chart” and the “plot of means”, though you should favor the bar chart format for publishing.
Rcmdr: Graphs → Plot of means…
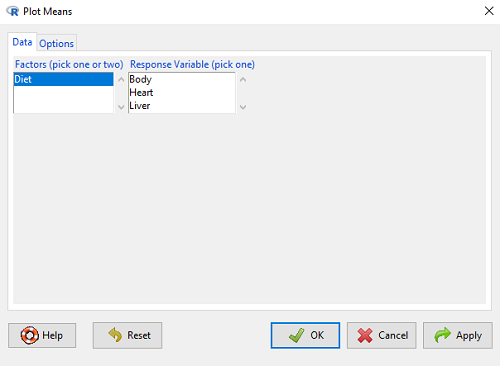
Figure 9. Rcmdr menu popup for Plots Means
Here, Rcmdr takes the data and calculates the mean and your choice of standard errors or deviations, confidence intervals, or no error bars. the resulting graph is below.
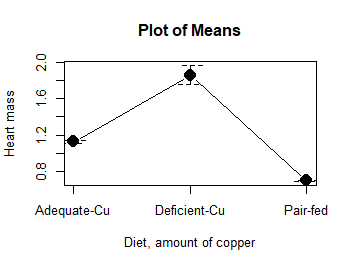
Figure 10. Plot of means
That’s an ugly graph (Fig. 10). Functional, good enough for data exploration and preliminary results, and certainly good enough for a Biostatistics homework or report. Additionally, connecting the dots here is a no-no. It implies that if we had measured categories between “adequate copper” and “deficient copper,” then the points would fall on those lines. That would be a complete guess. So, why did I include the connecting lines? That was the default setting for the command, and it makes the point — think before you click. One argument for connecting points in a graph is that it makes it easier for the reader to visualize trends.
This graph (Fig. 10) is fine for exploring data, but you will want to do better for publication.
Let’s make some better graphs with R
Once you are ready to go beyond the default settings available in Rcmdr, there is tremendous functionality in R for graphics. To access R’s potential, you’ll need to get into the commands a bit. I’m going to continue to try and shield you from the programming aspects of R, but from time to time you really need to see what is possible with R. Graphics is one such area. I use the package gplots, with 23 different graphing functions (type at R prompt ?gplots to call up the manual pages).
gplots should be among the packages on your R installation; if not, then install the package and run library(gplots) to complete the installation. We’ll try the barchart2 function.
But first, we need to get means for each of our groups.
At the R command prompt:
hrtWt <- tapply(Dataset$HeartWt, list(Group=Dataset$Group), mean, na.rm=TRUE) This code extracts means from our HeartWt variable for each Group, then stores the three (in this case, because our data set has 3 groups) in the place holder I had called hrtWt. To verify that the three means are there, type “hrtWt” without the quotes then enter.
You should see
hrtWt Group Cu adequate Cu deficient Pair-fed
               1.200000     1.566667 0.900000
R functions used: tapply, list, mean; na.rm was not needed but would be used to remove all missing values (recall during our import phase we were asked how missing observations were noted in our file; the default is NA).
Next, I want to apply standard error bars
stdDEV <- tapply(Dataset$HeartWt, list(Group=Dataset$Group), sd, na.rm=TRUE)
cil <- hrtWt-(stdDEV/sqrt(3))
ciu <- hrtWt+(stdDEV/sqrt(3))
I used cil and ciu to designate the lower cil and upper ciu values for my ± SEM (standard error of the mean). ciu stands for “confidence interval lower;” ciu stands for “confidence interval upper.”
Finally, here’s the plot command
barplot2(hrtWt, beside = TRUE, main=c("Mice fed different amounts of copper in diet"), col = c("blue", "red", "green"), xlab="Copper in diet", ylab="Heart mass (g)", ylim = c(0, 2), plot.ci=TRUE, ci.l=cil, ci.u=ciu)Now, draw a box around the graphic
box()Whew!
What does your new graph look like? My graph is below (Fig. 11).
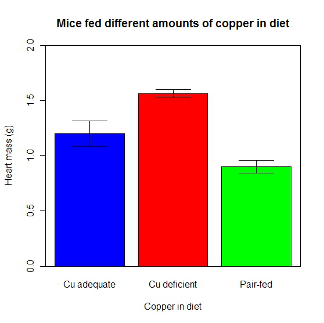
Figure 11. A bar chart using barplot2.
This works and the point is that once the script is written it easy to make small changes as you need in the future to make nice graphs.
If you are impatient like me, I like a GUI option, at least to start crafting the graph. The Rcmdr plugin KMggplot2 provides a good set of tools to make bar charts with error bars. An even better option I think is to use a software package that is designed for graphics, at least simple graphics like a bar chart. I use SciDAVis and Veusz for simple graphs like pie charts and bar charts; much easier to control.
ggplot2 bar charts with error bars
Nevertheless, here’s how to make a bar chart with error bars using ggplot2 (Fig. 11). First, we need to create a statistics summary. The script printed here was modified from scripts at R Graph Cookbook website.
require(plyr)
summarySE <- function(data=NULL, measurevar, groupvars=NULL, na.rm=FALSE,
     conf.interval=.95, .drop=TRUE) {
length2 <- function (x, na.rm=FALSE) {
     if (na.rm) sum(!is.na(x))
     else length(x)
}

#returns a vector with N, mean, and sd
datac <- ddply(data,groupvars, .drop=.drop,
    .fun = function(xx,col){
      c(N=length2(xx[[col]],na.rm=na.rm),
      mean=mean(xx[[col]],na.rm=na.rm),
      sd=sd(xx[[col]],na.rm=na.rm)
     )
    },
    measurevar
   )

#Rename the "mean" column
datac <- rename(datac,c("mean"=measurevar))

#Calculate the standard error of the mean
datac$se <- datac$sd/sqrt(datac$N)

#Get confidence interval
ciMult <- qt(conf.interval/2 + .5, datac$N-1)
datac$ci <- datac$se*ciMult

return(datac)
}
Applying this function to the BMI dataset yields the following output.
sumBMI <- summarySE(BMI, measurevar="BMI", groupvars=c("Sex", "Smoke"));sumBMI

   Sex Smoke   N      BMI       sd        se       ci
1    F    No  23 26.83567 7.610271 1.5868511 3.290928
2    F   Yes  14 25.76133 4.658625 1.2450698 2.689810
3    M    No  10 26.35731 3.363575 1.0636557 2.406156
4    M   Yes  27 26.71879 4.675631 0.8998256 1.849618
Now we are ready to make the bar chart with error bars
ggplot(tgc,aes(x=Smoke,y=BMI,fill=Sex)) +
 geom_bar(position=position_dodge(),stat="identity",color="black") +
 geom_errorbar(aes(ymin=BMI,ymax=BMI+se),width=.2,position=position_dodge(.9))
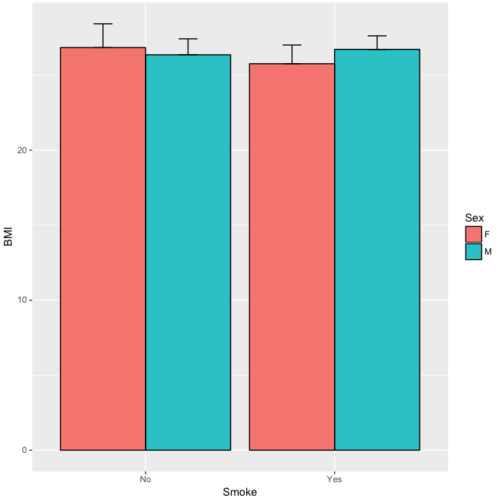
Figure 12. A barchart from ggplot2
Questions
1. Why should you use box plots and not bar charts to display comparisons for a ratio scale variable between categories? Obtain a copy of the article by Streit and Gehlenbor 2014 — it’s free! After reading, summarize the pro and cons for box plots over bar charts with error bars.
2. Enter the following data into R. The data are sulfate levels in water, parts per million.
type = c("Palolo Stream","Chaminade tap water", "Aquafina","Dasani")
sulfateppm =c(11, 14, 5, 12)
try = data.frame(type,sulfateppm)
byWater = tapply(try$sulfateppm,list(Group=try$type),mean)
Make a simple bar chart using the boxplot2 function in gplots package.
3. Change the range of values on the vertical axis to 0, 20
4. Change the color of the bars from gray to blue
5. Add a label to the vertical axis, “Sulfates, ppm” (without the quotes)
6. Add a box around the graph.
Quiz – Chapter 4.1
Bar charts
Data set
| Diet | Body | Heart | Liver |
|---|---|---|---|
| Adequate-Cu | 320.1381 | 1.125037 | 10.259657 |
| Adequate-Cu | 329.6879 | 1.158982 | 9.843295 |
| Adequate-Cu | 327.9838 | 1.090374 | 9.855975 |
| Adequate-Cu | 334.6669 | 1.118183 | 9.942997 |
| Adequate-Cu | 338.3134 | 1.172636 | 9.860971 |
| Adequate-Cu | 345.4608 | 1.056183 | 8.88582 |
| Adequate-Cu | 343.089 | 1.081261 | 10.166647 |
| Adequate-Cu | 328.3403 | 1.111278 | 10.124185 |
| Adequate-Cu | 324.9723 | 1.189194 | 10.158402 |
| Adequate-Cu | 325.2378 | 1.14715 | 9.939521 |
| Deficient-Cu | 195.5052 | 1.90973 | 7.907565 |
| Deficient-Cu | 182.7809 | 1.823672 | 8.430167 |
| Deficient-Cu | 184.3701 | 1.632249 | 7.619104 |
| Deficient-Cu | 193.7867 | 1.831765 | 8.742489 |
| Deficient-Cu | 180.0417 | 1.710367 | 7.975879 |
| Deficient-Cu | 208.5349 | 2.495623 | 8.652445 |
| Deficient-Cu | 182.3048 | 1.262053 | 7.257726 |
| Deficient-Cu | 203.0413 | 2.153639 | 8.081782 |
| Deficient-Cu | 193.3829 | 1.986028 | 7.807328 |
| Deficient-Cu | 195.0523 | 1.76975 | 8.297611 |
| Pair-fed | 211.0858 | 0.6911343 | 6.251177 |
| Pair-fed | 210.4041 | 0.6928067 | 7.696669 |
| Pair-fed | 208.5969 | 0.6911901 | 6.973803 |
| Pair-fed | 209.3333 | 0.7039211 | 6.629303 |
| Pair-fed | 208.8889 | 0.7077486 | 6.038704 |
| Pair-fed | 208.2994 | 0.7004535 | 6.606877 |
| Pair-fed | 209.4524 | 0.6915543 | 6.228888 |
| Pair-fed | 210.2699 | 0.6984497 | 6.638466 |
| Pair-fed | 208.8142 | 0.7214847 | 6.353705 |
| Pair-fed | 209.2977 | 0.6848656 | 6.536642 |